diff --git a/.claude/settings.json b/.claude/settings.json
index 7222d25..39b736a 100644
--- a/.claude/settings.json
+++ b/.claude/settings.json
@@ -8,11 +8,13 @@
"Edit(.obsidian/plugins/quickadd/data.json)",
"Edit(04_Archive/Projects/Airport/Chengdu/Office Test Env.md)",
"Bash(wc:*)",
- "Bash(cat > .replace_urls.py << 'PYEOF'\n#!/usr/bin/env python3\nimport re\n\n# Read the mapping\nmappings = []\nwith open\\('.url_mapping.txt', 'r'\\) as f:\n for line in f:\n if '|' in line:\n url, filename = line.strip\\(\\).split\\('|', 1\\)\n mappings.append\\(\\(url, filename\\)\\)\n\n# Read the markdown file\nnote_path = \"00_Inbox/Clippings/2026/01/ZeroLuawesome-nanobanana-pro 🚀 An awesome list of curated Nano Banana pro prompts and examples. Your go-to resource for mastering prompt engineering and exploring the creative potential of the Nano banana pro\\(Nano banana 2\\) AI image model..md\"\n\nwith open\\(note_path, 'r', encoding='utf-8'\\) as f:\n content = f.read\\(\\)\n\n# Perform replacements\nreplacements_made = 0\nfor url, filename in mappings:\n # Escape special regex characters in URL\n escaped_url = re.escape\\(url\\)\n # Replace markdown image syntax: ![alt]\\(url\\) -> ![[path/filename]]\n pattern = r'!\\\\[\\([^\\\\]]*\\)\\\\]\\\\\\(' + escaped_url + r'\\\\\\)'\n replacement = f'![[05_Attachments/nanobanana-pro/{filename}]]'\n new_content, count = re.subn\\(pattern, replacement, content\\)\n if count > 0:\n content = new_content\n replacements_made += count\n print\\(f\"✓ Replaced {count}x: {filename}\"\\)\n\n# Write back\nwith open\\(note_path, 'w', encoding='utf-8'\\) as f:\n f.write\\(content\\)\n\nprint\\(f\"\\\\nTotal replacements: {replacements_made}\"\\)\nPYEOF\npython3 .replace_urls.py)",
- "Bash(cat > .fix_links.py << 'PYEOF'\n#!/usr/bin/env python3\nimport re\n\nnote_path = \"00_Inbox/Clippings/2026/01/ZeroLuawesome-nanobanana-pro 🚀 An awesome list of curated Nano Banana pro prompts and examples. Your go-to resource for mastering prompt engineering and exploring the creative potential of the Nano banana pro\\(Nano banana 2\\) AI image model..md\"\n\nwith open\\(note_path, 'r', encoding='utf-8'\\) as f:\n content = f.read\\(\\)\n\n# Pattern: [![[wikilink]]]\\(url\\) -> ![[wikilink]]\n# Remove the clickable link wrapper around wikilinks\npattern = r'\\\\[\\(!!\\\\[\\\\[05_Attachments/nanobanana-pro/[^\\\\]]+\\\\]\\\\]\\)\\\\]\\\\\\([^\\)]+\\\\\\)'\nreplacement = r'\\\\1'\nnew_content, count = re.subn\\(pattern, replacement, content\\)\n\nprint\\(f\"Fixed {count} clickable link wrappers\"\\)\n\nwith open\\(note_path, 'w', encoding='utf-8'\\) as f:\n f.write\\(new_content\\)\nPYEOF\npython3 .fix_links.py)",
- "Bash(ls -lh 05_Attachments/nanobanana-pro/ | awk '{if \\($5 ~ /^[0-9]+$/ && $5 < 1024\\) print $9, $5}' | head -20)",
+ "Bash(cat > .replace_urls.py << 'PYEOF'\n#!/usr/bin/env python3\nimport re\n\n# Read the mapping\nmappings = []\nwith open('.url_mapping.txt', 'r') as f:\n for line in f:\n if '|' in line:\n url, filename = line.strip().split('|', 1)\n mappings.append((url, filename))\n\n# Read the markdown file\nnote_path = \"00_Inbox/Clippings/2026/01/ZeroLuawesome-nanobanana-pro 🚀 An awesome list of curated Nano Banana pro prompts and examples. Your go-to resource for mastering prompt engineering and exploring the creative potential of the Nano banana pro(Nano banana 2) AI image model..md\"\n\nwith open(note_path, 'r', encoding='utf-8') as f:\n content = f.read()\n\n# Perform replacements\nreplacements_made = 0\nfor url, filename in mappings:\n # Escape special regex characters in URL\n escaped_url = re.escape(url)\n # Replace markdown image syntax:  -> ![[path/filename]]\n pattern = r'!\\[([^\\]]*)\\]\\(' + escaped_url + r'\\)'\n replacement = f'![[05_Attachments/nanobanana-pro/{filename}]]'\n new_content, count = re.subn(pattern, replacement, content)\n if count > 0:\n content = new_content\n replacements_made += count\n print(f\"✓ Replaced {count}x: {filename}\")\n\n# Write back\nwith open(note_path, 'w', encoding='utf-8') as f:\n f.write(content)\n\nprint(f\"\\nTotal replacements: {replacements_made}\")\nPYEOF\npython3 .replace_urls.py)",
+ "Bash(cat > .fix_links.py << 'PYEOF'\n#!/usr/bin/env python3\nimport re\n\nnote_path = \"00_Inbox/Clippings/2026/01/ZeroLuawesome-nanobanana-pro 🚀 An awesome list of curated Nano Banana pro prompts and examples. Your go-to resource for mastering prompt engineering and exploring the creative potential of the Nano banana pro(Nano banana 2) AI image model..md\"\n\nwith open(note_path, 'r', encoding='utf-8') as f:\n content = f.read()\n\n# Pattern: [![[wikilink]]](url) -> ![[wikilink]]\n# Remove the clickable link wrapper around wikilinks\npattern = r'\\[(!\\[\\[05_Attachments/nanobanana-pro/[^\\]]+\\]\\])\\]\\([^)]+\\)'\nreplacement = r'\\1'\nnew_content, count = re.subn(pattern, replacement, content)\n\nprint(f\"Fixed {count} clickable link wrappers\")\n\nwith open(note_path, 'w', encoding='utf-8') as f:\n f.write(new_content)\nPYEOF\npython3 .fix_links.py)",
+ "Bash(ls -lh 05_Attachments/nanobanana-pro/ | awk '{if ($5 ~ /^[0-9]+$/ && $5 < 1024) print $9, $5}' | head -20)",
"Bash(find:*)",
- "Bash(find 05_Attachments/nanobanana-pro/ -type f \\\\\\( -size 0 -o -size -100c \\\\\\) | sort > .failed_images.txt && head -10 .failed_images.txt)"
+ "Bash(find 05_Attachments/nanobanana-pro/ -type f \\( -size 0 -o -size -100c \\) | sort > .failed_images.txt && head -10 .failed_images.txt)",
+ "Bash(cat > .fix_conflicts.py << 'EOF'\n#!/usr/bin/env python3\nimport re\n\n# Read the file\nwith open\\('.obsidian/plugins/claudian/main.js', 'r'\\) as f:\n content = f.read\\(\\)\n\n# Fix first conflict \\(line ~2076\\) - use origin/main version \\(simpler path\\)\npattern1 = r'<<<<<<< HEAD\\\\n// node_modules/@modelcontextprotocol/sdk/node_modules/ajv/node_modules/json-schema-traverse/index\\\\.js\\\\nvar require_json_schema_traverse = __commonJS\\\\\\(\\\\{\\\\n \"node_modules/@modelcontextprotocol/sdk/node_modules/ajv/node_modules/json-schema-traverse/index\\\\.js\"\\\\\\(exports, module2\\\\\\) \\\\{\\\\n=======\\\\n// node_modules/@modelcontextprotocol/sdk/node_modules/json-schema-traverse/index\\\\.js\\\\nvar require_json_schema_traverse = __commonJS\\\\\\(\\\\{\\\\n \"node_modules/@modelcontextprotocol/sdk/node_modules/json-schema-traverse/index\\\\.js\"\\\\\\(exports, module2\\\\\\) \\\\{\\\\n>>>>>>> origin/main'\n\nreplacement1 = '''// node_modules/@modelcontextprotocol/sdk/node_modules/json-schema-traverse/index.js\nvar require_json_schema_traverse = __commonJS\\({\n \"node_modules/@modelcontextprotocol/sdk/node_modules/json-schema-traverse/index.js\"\\(exports, module2\\) {'''\n\ncontent = re.sub\\(pattern1, replacement1, content\\)\n\n# Fix second conflict \\(line ~8693\\) - use origin/main version \\(simpler path\\)\npattern2 = r'<<<<<<< HEAD\\\\n// node_modules/ajv-formats/node_modules/ajv/node_modules/json-schema-traverse/index\\\\.js\\\\nvar require_json_schema_traverse2 = __commonJS\\\\\\(\\\\{\\\\n \"node_modules/ajv-formats/node_modules/ajv/node_modules/json-schema-traverse/index\\\\.js\"\\\\\\(exports, module2\\\\\\) \\\\{\\\\n=======\\\\n// node_modules/ajv-formats/node_modules/json-schema-traverse/index\\\\.js\\\\nvar require_json_schema_traverse2 = __commonJS\\\\\\(\\\\{\\\\n \"node_modules/ajv-formats/node_modules/json-schema-traverse/index\\\\.js\"\\\\\\(exports, module2\\\\\\) \\\\{\\\\n>>>>>>> origin/main'\n\nreplacement2 = '''// node_modules/ajv-formats/node_modules/json-schema-traverse/index.js\nvar require_json_schema_traverse2 = __commonJS\\({\n \"node_modules/ajv-formats/node_modules/json-schema-traverse/index.js\"\\(exports, module2\\) {'''\n\ncontent = re.sub\\(pattern2, replacement2, content\\)\n\n# Write back\nwith open\\('.obsidian/plugins/claudian/main.js', 'w'\\) as f:\n f.write\\(content\\)\n\nprint\\(\"✓ Fixed both conflicts in main.js\"\\)\nEOF\npython3 .fix_conflicts.py)",
+ "Bash(git add:*)"
],
"deny": [],
"ask": []
diff --git a/.obsidian/community-plugins.json b/.obsidian/community-plugins.json
index c32391d..67cd5f5 100644
--- a/.obsidian/community-plugins.json
+++ b/.obsidian/community-plugins.json
@@ -1,28 +1,25 @@
[
- "claudian",
- "obsidian-local-rest-api",
- "table-editor-obsidian",
- "obsidian-git",
+ "cm-chs-patch",
"templater-obsidian",
"obsidian-tasks-plugin",
- "calendar",
- "obsidian-kanban",
"obsidian-style-settings",
- "obsidian-icon-folder",
- "omnisearch",
- "copilot",
- "easy-typing-obsidian",
- "obsidian-advanced-uri",
- "advanced-canvas",
- "better-word-count",
- "dataview",
- "obsidian-excalidraw-plugin",
- "obsidian-mind-map",
- "cm-chs-patch",
"quickadd",
"any-block",
"obsidian-opencode",
"opencode-obsidian",
+ "omnisearch",
+ "obsidian-local-rest-api",
+ "obsidian-kanban",
+ "obsidian-icon-folder",
"highlightr-plugin",
- "code-styler"
-]
\ No newline at end of file
+ "obsidian-git",
+ "obsidian-excalidraw-plugin",
+ "code-styler",
+ "note-buddy",
+ "claudian",
+ "calendar",
+ "better-word-count",
+ "table-editor-obsidian",
+ "obsidian-advanced-uri",
+ "advanced-canvas"
+]
diff --git a/.obsidian/core-plugins.json b/.obsidian/core-plugins.json
index 90038df..82e36e6 100644
--- a/.obsidian/core-plugins.json
+++ b/.obsidian/core-plugins.json
@@ -14,7 +14,7 @@
"templates": true,
"note-composer": true,
"command-palette": true,
- "slash-command": false,
+ "slash-command": true,
"editor-status": true,
"bookmarks": true,
"markdown-importer": true,
@@ -29,5 +29,5 @@
"publish": false,
"sync": false,
"bases": true,
- "webviewer": false
+ "webviewer": true
}
\ No newline at end of file
diff --git a/.obsidian/plugins/claudian/main.js b/.obsidian/plugins/claudian/main.js
index 9712e69..176acf2 100644
--- a/.obsidian/plugins/claudian/main.js
+++ b/.obsidian/plugins/claudian/main.js
@@ -2073,9 +2073,9 @@ var require_fast_deep_equal = __commonJS({
}
});
-// node_modules/@modelcontextprotocol/sdk/node_modules/ajv/node_modules/json-schema-traverse/index.js
+// node_modules/@modelcontextprotocol/sdk/node_modules/json-schema-traverse/index.js
var require_json_schema_traverse = __commonJS({
- "node_modules/@modelcontextprotocol/sdk/node_modules/ajv/node_modules/json-schema-traverse/index.js"(exports, module2) {
+ "node_modules/@modelcontextprotocol/sdk/node_modules/json-schema-traverse/index.js"(exports, module2) {
"use strict";
var traverse = module2.exports = function(schema, opts, cb) {
if (typeof opts == "function") {
@@ -8684,9 +8684,9 @@ var require_subschema2 = __commonJS({
}
});
-// node_modules/ajv-formats/node_modules/ajv/node_modules/json-schema-traverse/index.js
+// node_modules/ajv-formats/node_modules/json-schema-traverse/index.js
var require_json_schema_traverse2 = __commonJS({
- "node_modules/ajv-formats/node_modules/ajv/node_modules/json-schema-traverse/index.js"(exports, module2) {
+ "node_modules/ajv-formats/node_modules/json-schema-traverse/index.js"(exports, module2) {
"use strict";
var traverse = module2.exports = function(schema, opts, cb) {
if (typeof opts == "function") {
diff --git a/.obsidian/plugins/claudian/manifest.json b/.obsidian/plugins/claudian/manifest.json
index a230ee5..95e2bc2 100644
--- a/.obsidian/plugins/claudian/manifest.json
+++ b/.obsidian/plugins/claudian/manifest.json
@@ -1,9 +1,9 @@
{
"id": "claudian",
"name": "Claudian",
- "version": "1.3.16",
- "minAppVersion": "1.0.0",
- "description": "Embed Claude AI as a sidebar chat with full agentic capabilities for file operations and bash commands.",
+ "version": "1.3.55",
+ "minAppVersion": "1.4.5",
+ "description": "Embeds Claude Code as an AI collaborator in your vault. Your vault becomes Claude's working directory, giving it full agentic capabilities: file read/write, search, bash commands, and multi-step workflows.",
"author": "Yishen Tu",
"authorUrl": "https://github.com/YishenTu",
"isDesktopOnly": true
diff --git a/.obsidian/plugins/obsidian-excalidraw-plugin/manifest.json b/.obsidian/plugins/obsidian-excalidraw-plugin/manifest.json
index f392ddc..8e9c77b 100644
--- a/.obsidian/plugins/obsidian-excalidraw-plugin/manifest.json
+++ b/.obsidian/plugins/obsidian-excalidraw-plugin/manifest.json
@@ -1,12 +1,12 @@
-{
- "id": "obsidian-excalidraw-plugin",
- "name": "Excalidraw",
- "version": "2.20.2",
- "minAppVersion": "1.5.7",
- "description": "Sketch Your Mind. An Obsidian plugin to edit and view Excalidraw drawings. Enter the world of 4D Visual PKM.",
- "author": "Zsolt Viczian",
- "authorUrl": "https://excalidraw-obsidian.online",
- "fundingUrl": "https://ko-fi.com/zsolt",
- "helpUrl": "https://github.com/zsviczian/obsidian-excalidraw-plugin#readme",
- "isDesktopOnly": false
-}
\ No newline at end of file
+{
+ "id": "obsidian-excalidraw-plugin",
+ "name": "Excalidraw",
+ "version": "2.20.2",
+ "minAppVersion": "1.5.7",
+ "description": "Sketch Your Mind. An Obsidian plugin to edit and view Excalidraw drawings. Enter the world of 4D Visual PKM.",
+ "author": "Zsolt Viczian",
+ "authorUrl": "https://excalidraw-obsidian.online",
+ "fundingUrl": "https://ko-fi.com/zsolt",
+ "helpUrl": "https://github.com/zsviczian/obsidian-excalidraw-plugin#readme",
+ "isDesktopOnly": false
+}
diff --git a/00_Inbox/Clippings/2026/01/Understanding Spec-Driven-Development Kiro, spec-kit, and Tessl.md b/00_Inbox/Clippings/2026/01/Understanding Spec-Driven-Development Kiro, spec-kit, and Tessl.md
new file mode 100644
index 0000000..f62ebca
--- /dev/null
+++ b/00_Inbox/Clippings/2026/01/Understanding Spec-Driven-Development Kiro, spec-kit, and Tessl.md
@@ -0,0 +1,181 @@
+---
+title: "Understanding Spec-Driven-Development: Kiro, spec-kit, and Tessl"
+source: "https://martinfowler.com/articles/exploring-gen-ai/sdd-3-tools.html"
+author:
+ - "[[Birgitta BöckelerBirgitta is a Distinguished Engineer and AI-assisted delivery expert at Thoughtworks. She has over 20 years of experience as a software developer]]"
+ - "[[architect and technical leader.]]"
+published:
+created: 2026-01-21
+description: "Notes from my Thoughtworks colleagues on AI-assisted software delivery"
+tags:
+ - "clippings"
+ - "webclipper"
+---
+> [!info] Source
+> URL: https://martinfowler.com/articles/exploring-gen-ai/sdd-3-tools.html
+> Title: Understanding Spec-Driven-Development: Kiro, spec-kit, and Tessl
+> Clipped:
+
+I’ve been trying to understand one of the latest AI coding buzzword: Spec-driven development (SDD). I looked at three of the tools that label themselves as SDD tools and tried to untangle what it means, as of now.
+
+## Definition
+
+Like with many emerging terms in this fast-paced space, the definition of “spec-driven development” (SDD) is still in flux. Here’s what I can gather from how I have seen it used so far: Spec-driven development means writing a “spec” before writing code with AI (“documentation first”). The spec becomes the source of truth for the human and the AI.
+
+[GitHub](https://github.com/github/spec-kit/blob/main/spec-driven.md): “In this new world, *maintaining software means evolving specifications*. \[…\] The lingua franca of development moves to a higher level, and code is the last-mile approach.”
+
+[Tessl](https://docs.tessl.io/introduction-to-tessl/concepts): “A development approach where *specs — not code — are the primary artifact*. Specs describe intent in structured, testable language, and agents generate code to match them.”
+
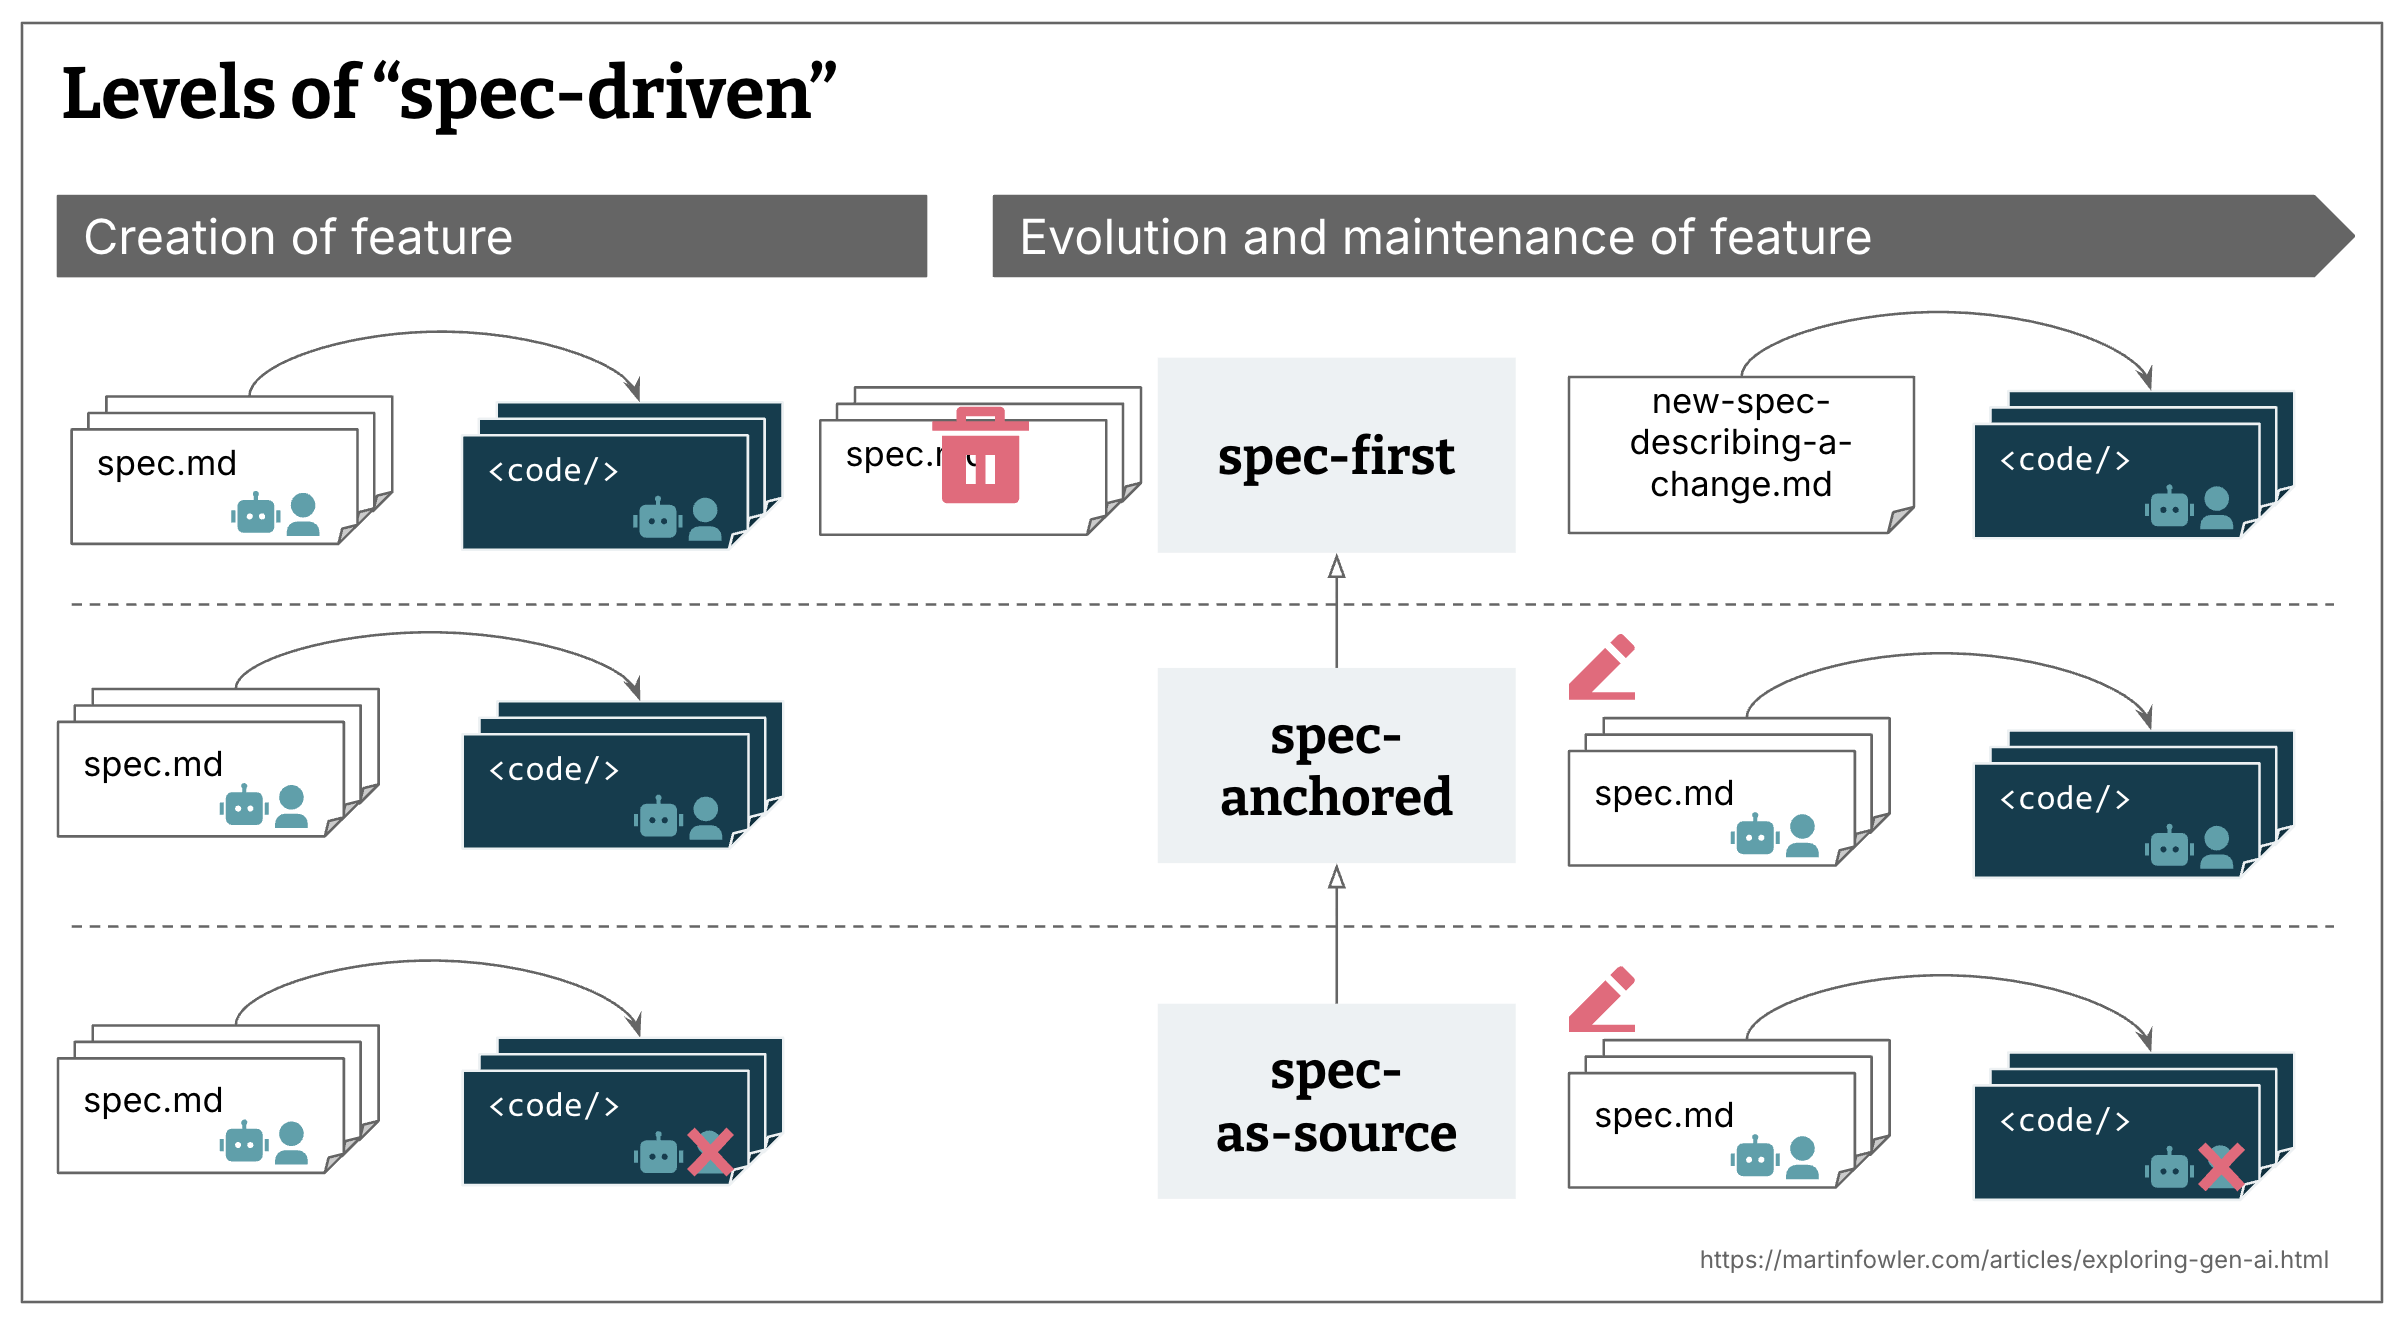
+After looking over the usages of the term, and some of the tools that claim to be implementing SDD, it seems to me that in reality, there are multiple implementation levels to it:
+
+1. **Spec-first**: A well thought-out spec is written first, and then used in the AI-assisted development workflow for the task at hand.
+2. **Spec-anchored**: The spec is kept even after the task is complete, to continue using it for evolution and maintenance of the respective feature.
+3. **Spec-as-source**: The spec is the main source file over time, and only the spec is edited by the human, the human never touches the code.
+
+All SDD approaches and definitions I’ve found are spec-first, but not all strive to be spec-anchored or spec-as-source. And often it’s left vague or totally open what the spec maintenance strategy over time is meant to be.
+
+
+
+## What is a spec?
+
+The key question in terms of definitions of course is: What is a spec? There doesn’t seem to be a general definition, the closest I’ve seen to a consistent definition is the comparison of a spec to a “Product Requirements Document”.
+
+The term is quite overloaded at the moment, here is my attempt at defining what a spec is:
+
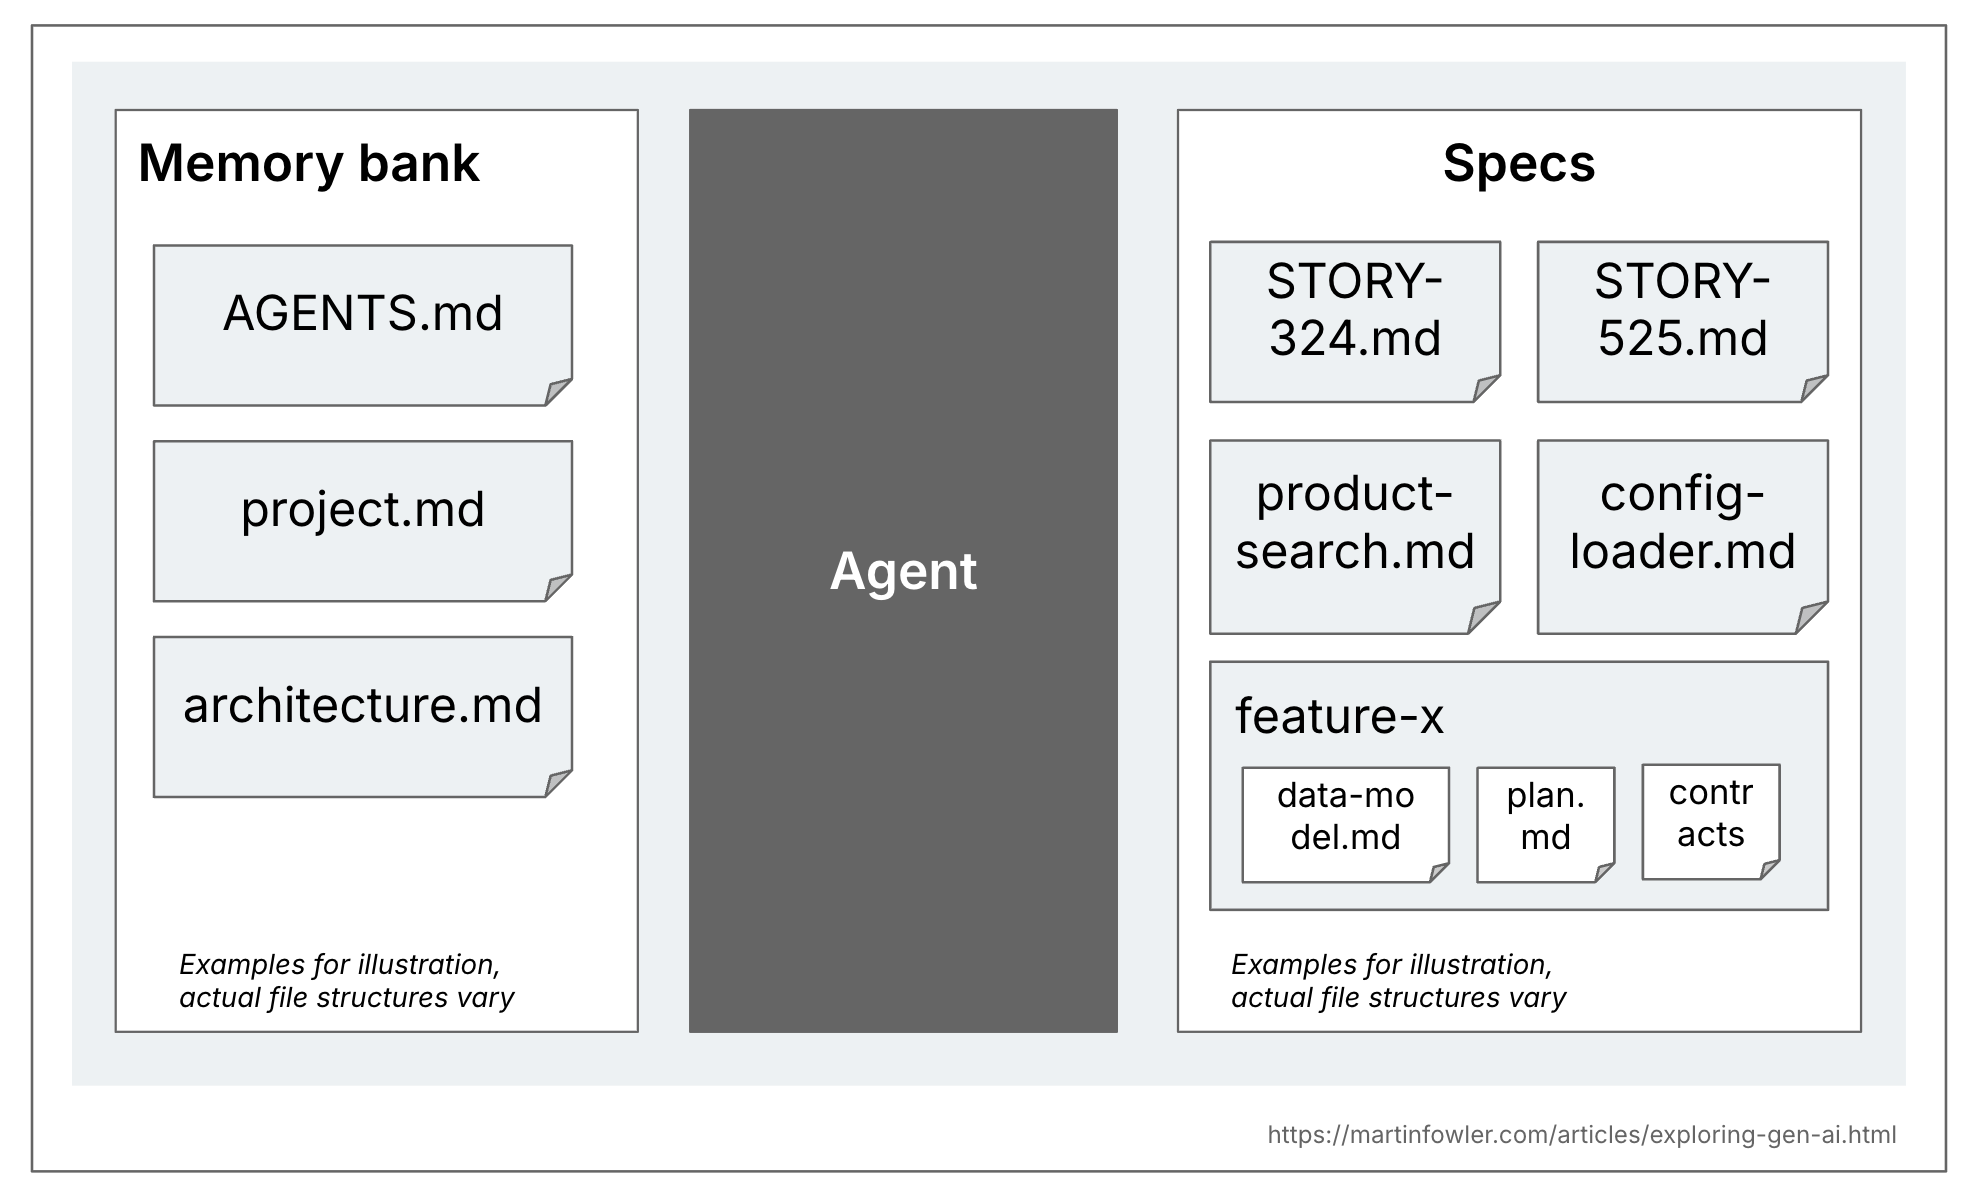
+A spec is a structured, behavior-oriented artifact - or a set of related artifacts - written in natural language that expresses software functionality and serves as guidance to AI coding agents. Each variant of spec-driven development defines their approach to a spec’s structure, level of detail, and how these artifacts are organized within a project.
+
+There is a useful difference to be made I think between specs and the more general context documents for a codebase. That general context are things like rules files, or high level descriptions of the product and the codebase. Some tools call this context a [**memory bank**](https://docs.cline.bot/prompting/cline-memory-bank), so that’s what I will use here. These files are relevant across all AI coding sessions in the codebase, whereas specs only relevant to the tasks that actually create or change that particular functionality.
+
+
+
+## The challenge with evaluating SDD tools
+
+It turns out to be quite time-consuming to evaluate SDD tools and approaches in a way that gets close to real usage. You would have to try them out with different sizes of problems, greenfield, brownfield, and really take the time to review and revise the intermediate artifacts with more than just a cursory glance. Because as [GitHub’s blog post about spec-kit](https://github.blog/ai-and-ml/generative-ai/spec-driven-development-with-ai-get-started-with-a-new-open-source-toolkit/) says: “Crucially, your role isn’t just to steer. It’s to verify. At each phase, you reflect and refine.”
+
+For two of the three tools I tried it also seems to be even more work to introduce them into an existing codebase, therefore making it even harder to evaluate their usefulness for brownfield codebases. Until I hear usage reports from people using them for a period of time on a “real” codebase, I still have a lot of open questions about how this works in real life.
+
+That being said - let’s get into three of these tools. I will share a description of how they work first (or rather how I think they work), and will keep my observations and questions for the end. Note that these tools are very fast evolving, so they might have already changed since I used them in September.
+
+## Kiro
+
+[Kiro](https://kiro.dev/) is the simplest (or most lightweight) one of the three I tried. It seems to be mostly spec-first, all the examples I have found use it for a task, or a user story, with no mention of how to use the requirements document in a spec-anchored way over time, across multiple tasks.
+
+**Workflow:** Requirements → Design → Tasks
+
+Each workflow step is represented by one markdown document, and Kiro guides you through those 3 workflow steps inside of its VS Code based distribution.
+
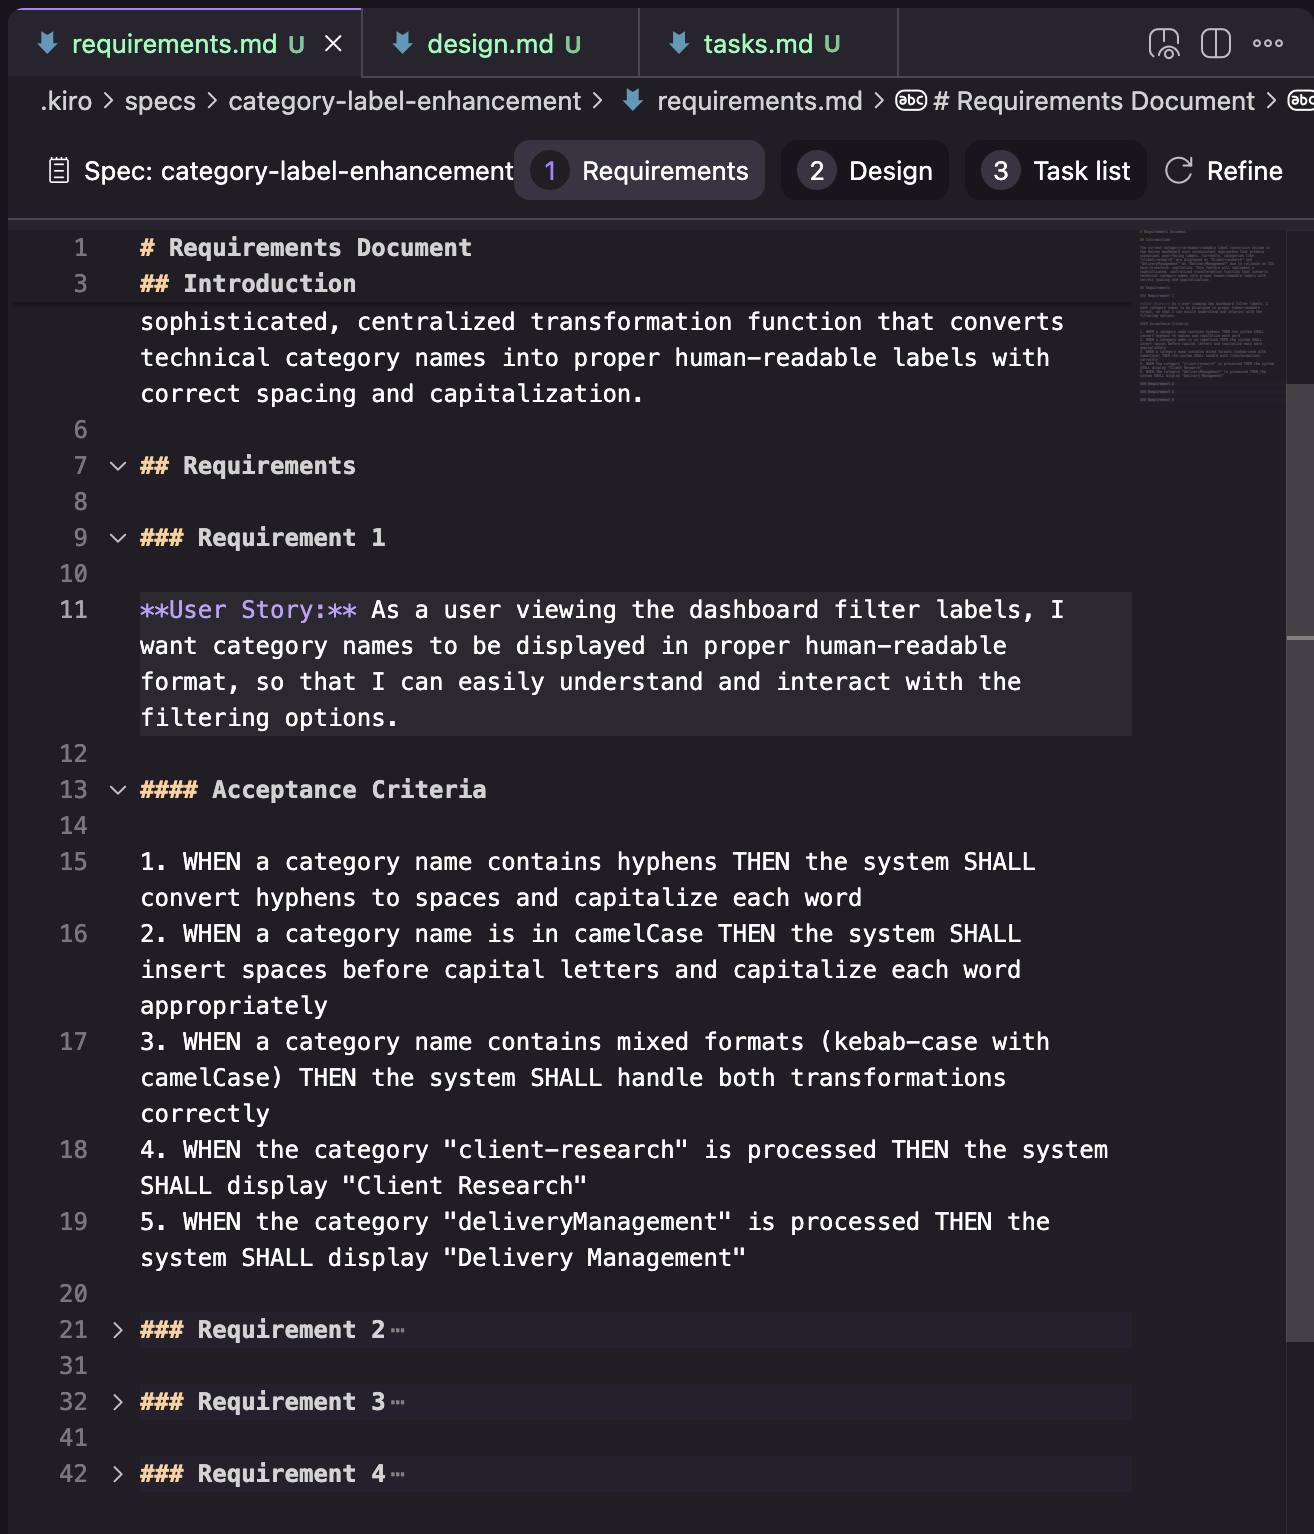
+**Requirements:** Structured as a list of requirements, where each requirement represents a “User Story” (in “As a…” format) with acceptance criteria (in “GIVEN… WHEN… THEN…” format)
+
+
+
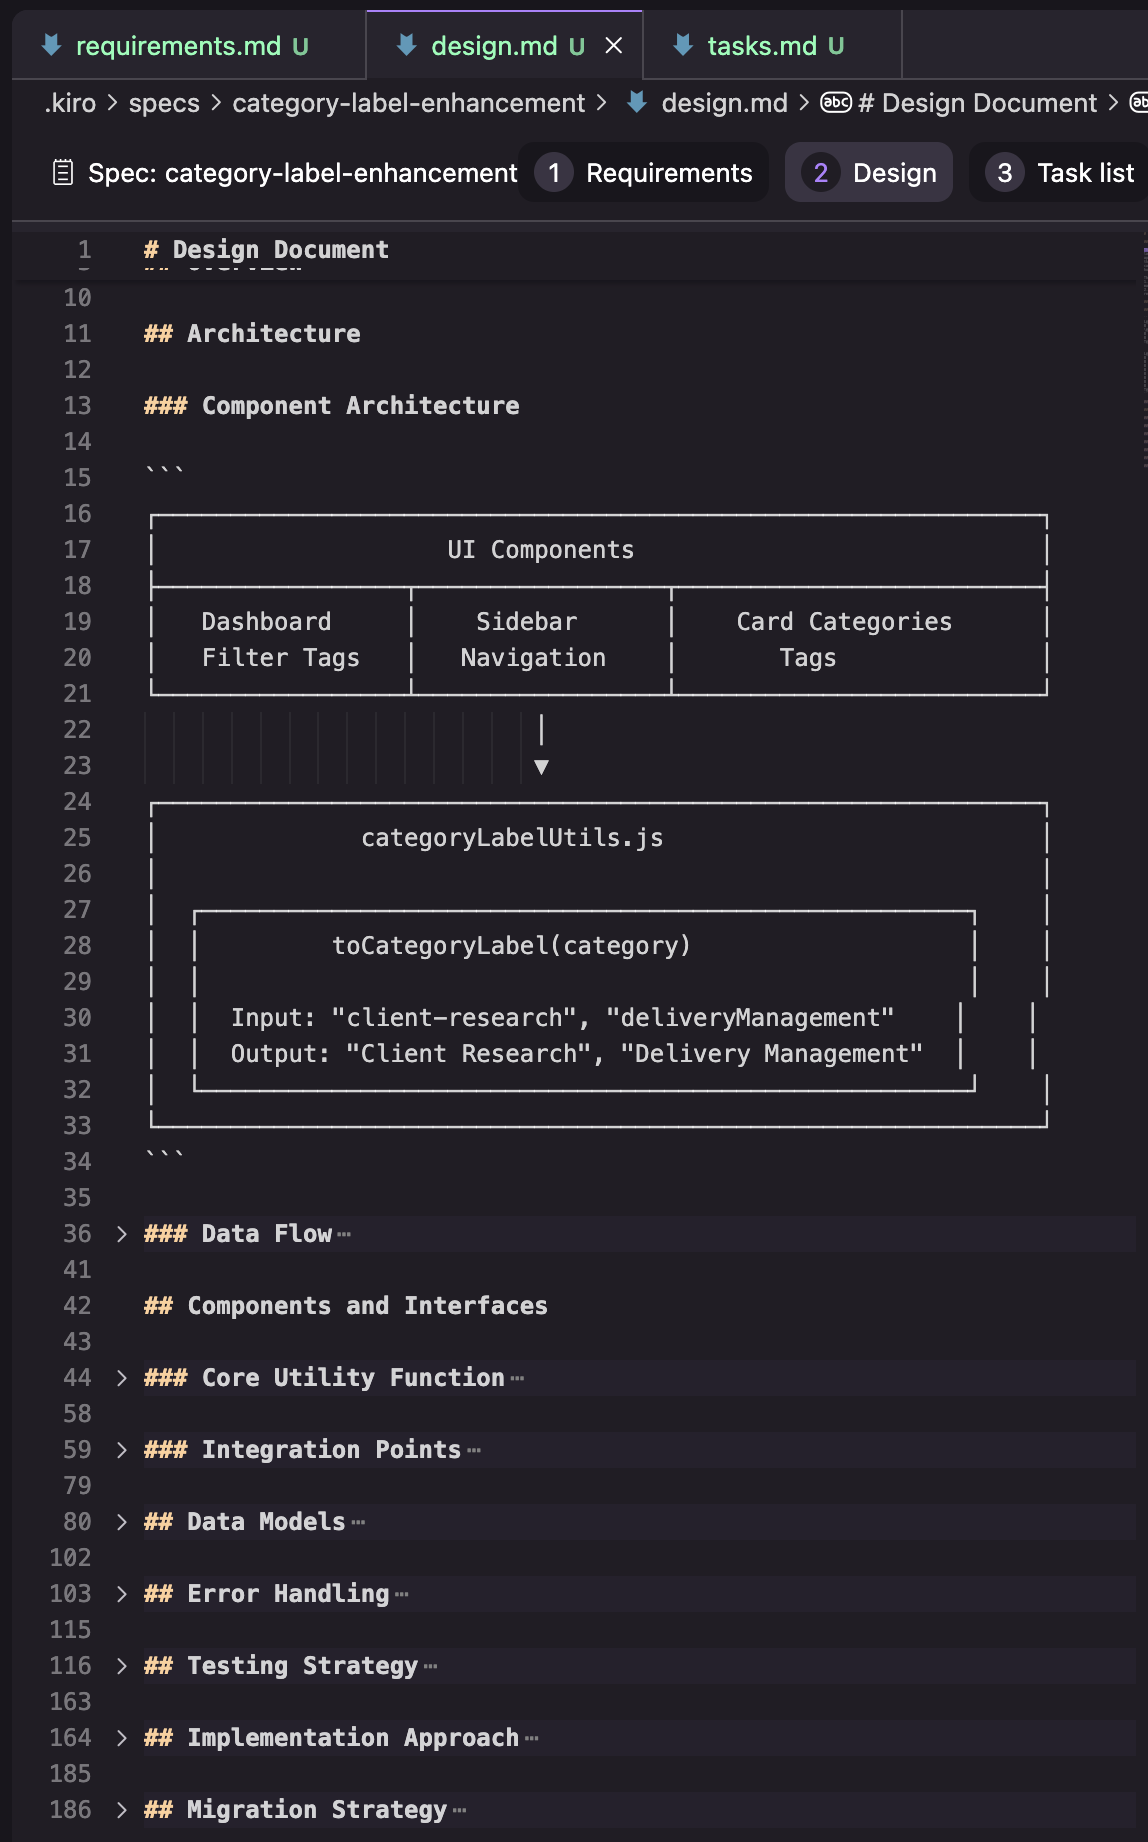
+**Design:** In my attempt, the design document consisted of the sections seen in the screenshot below. I only have the results of one of my attempts still, so I’m not sure if this is a consistent structure, or if it changes depending on the task.
+
+
+
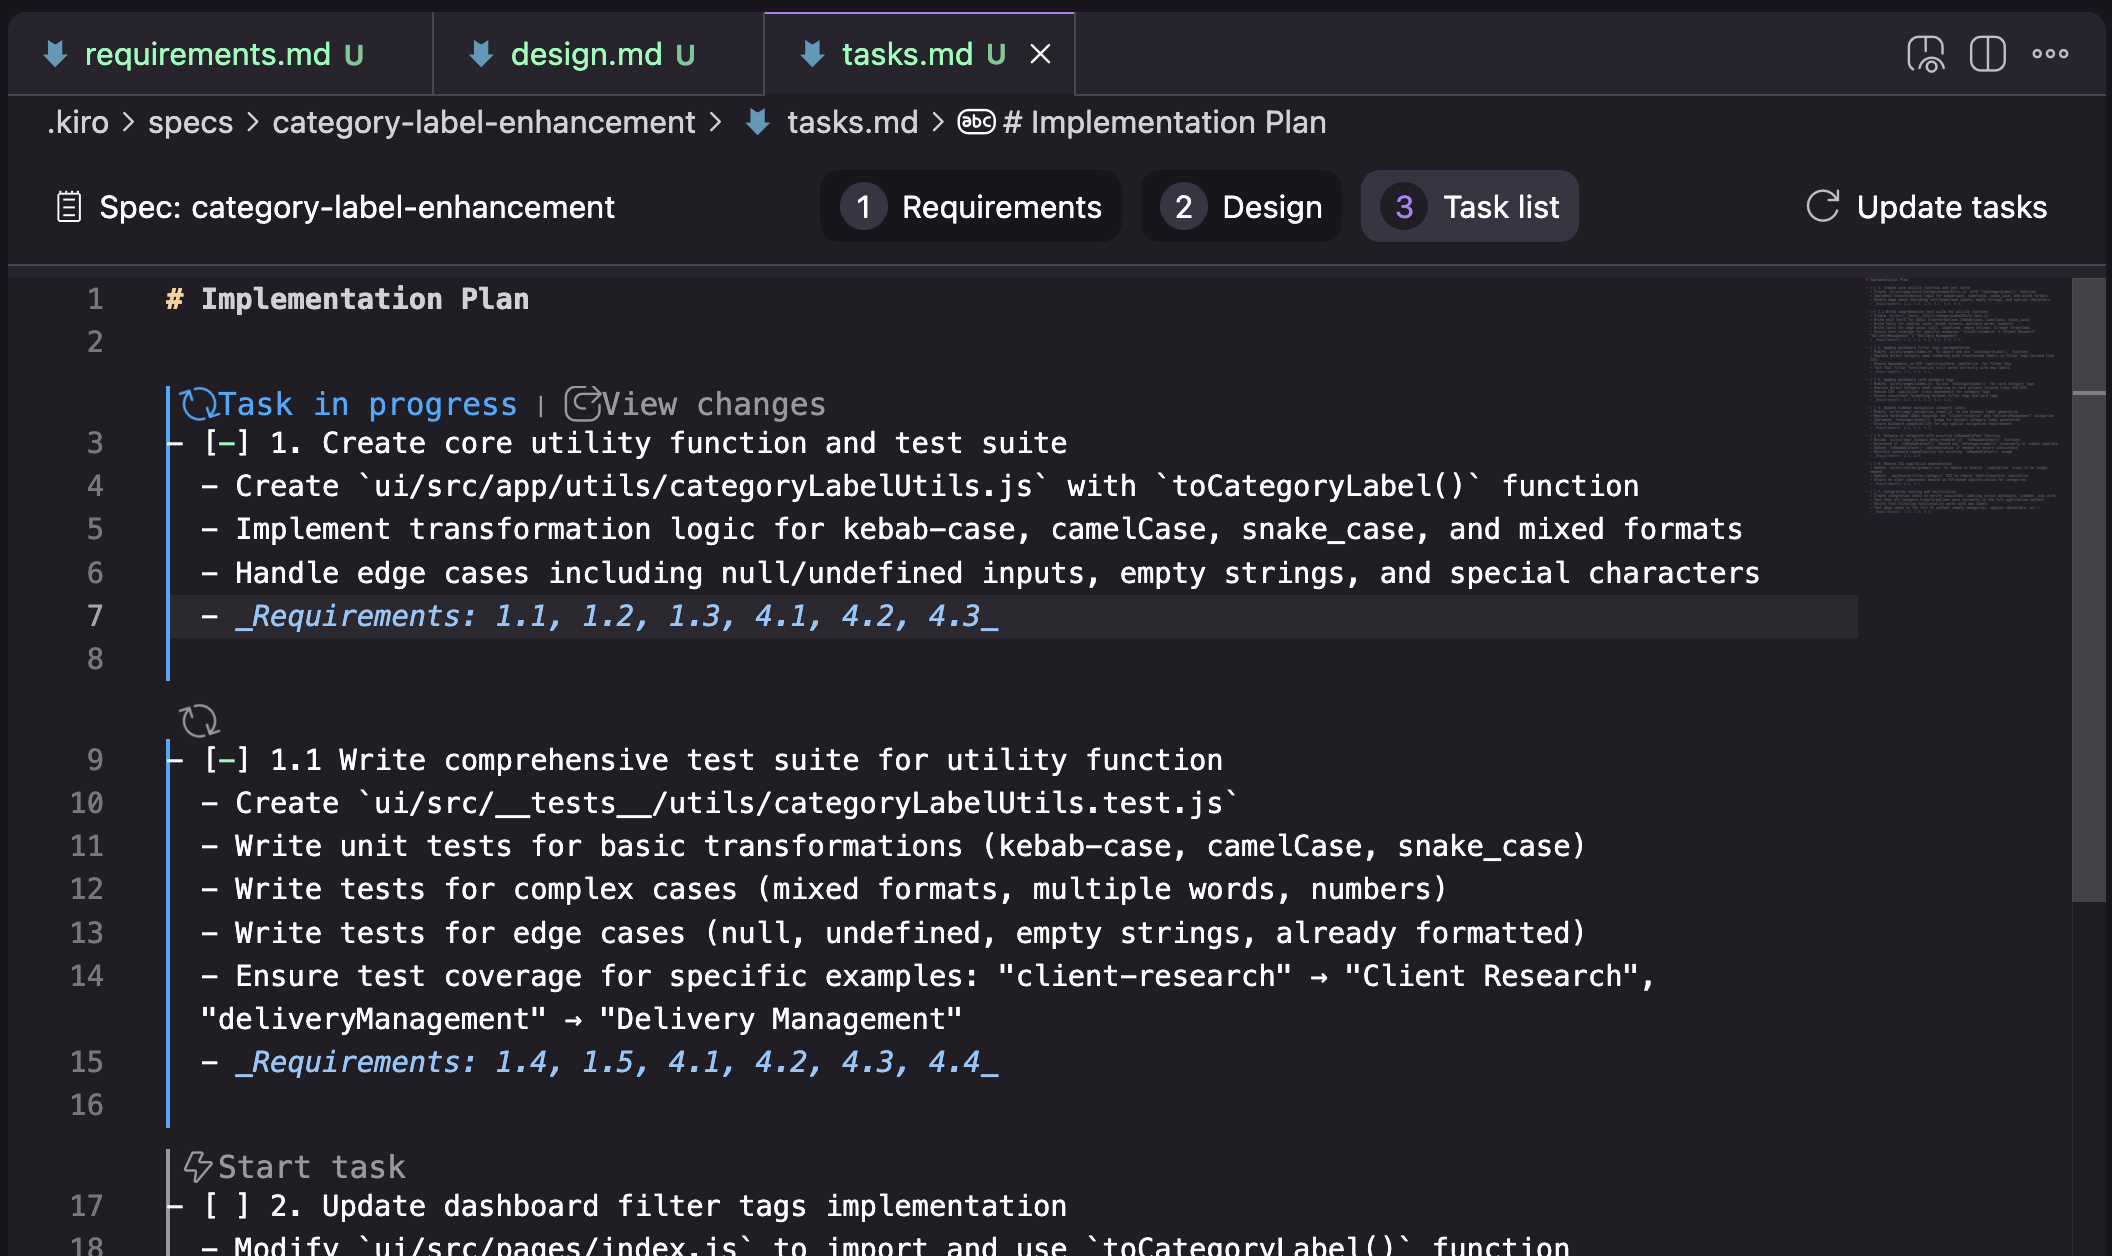
+**Tasks:** A list of tasks that trace back to the requirement numbers, and that get some extra UI elements to run tasks one by one, and review changes per task.
+
+
+
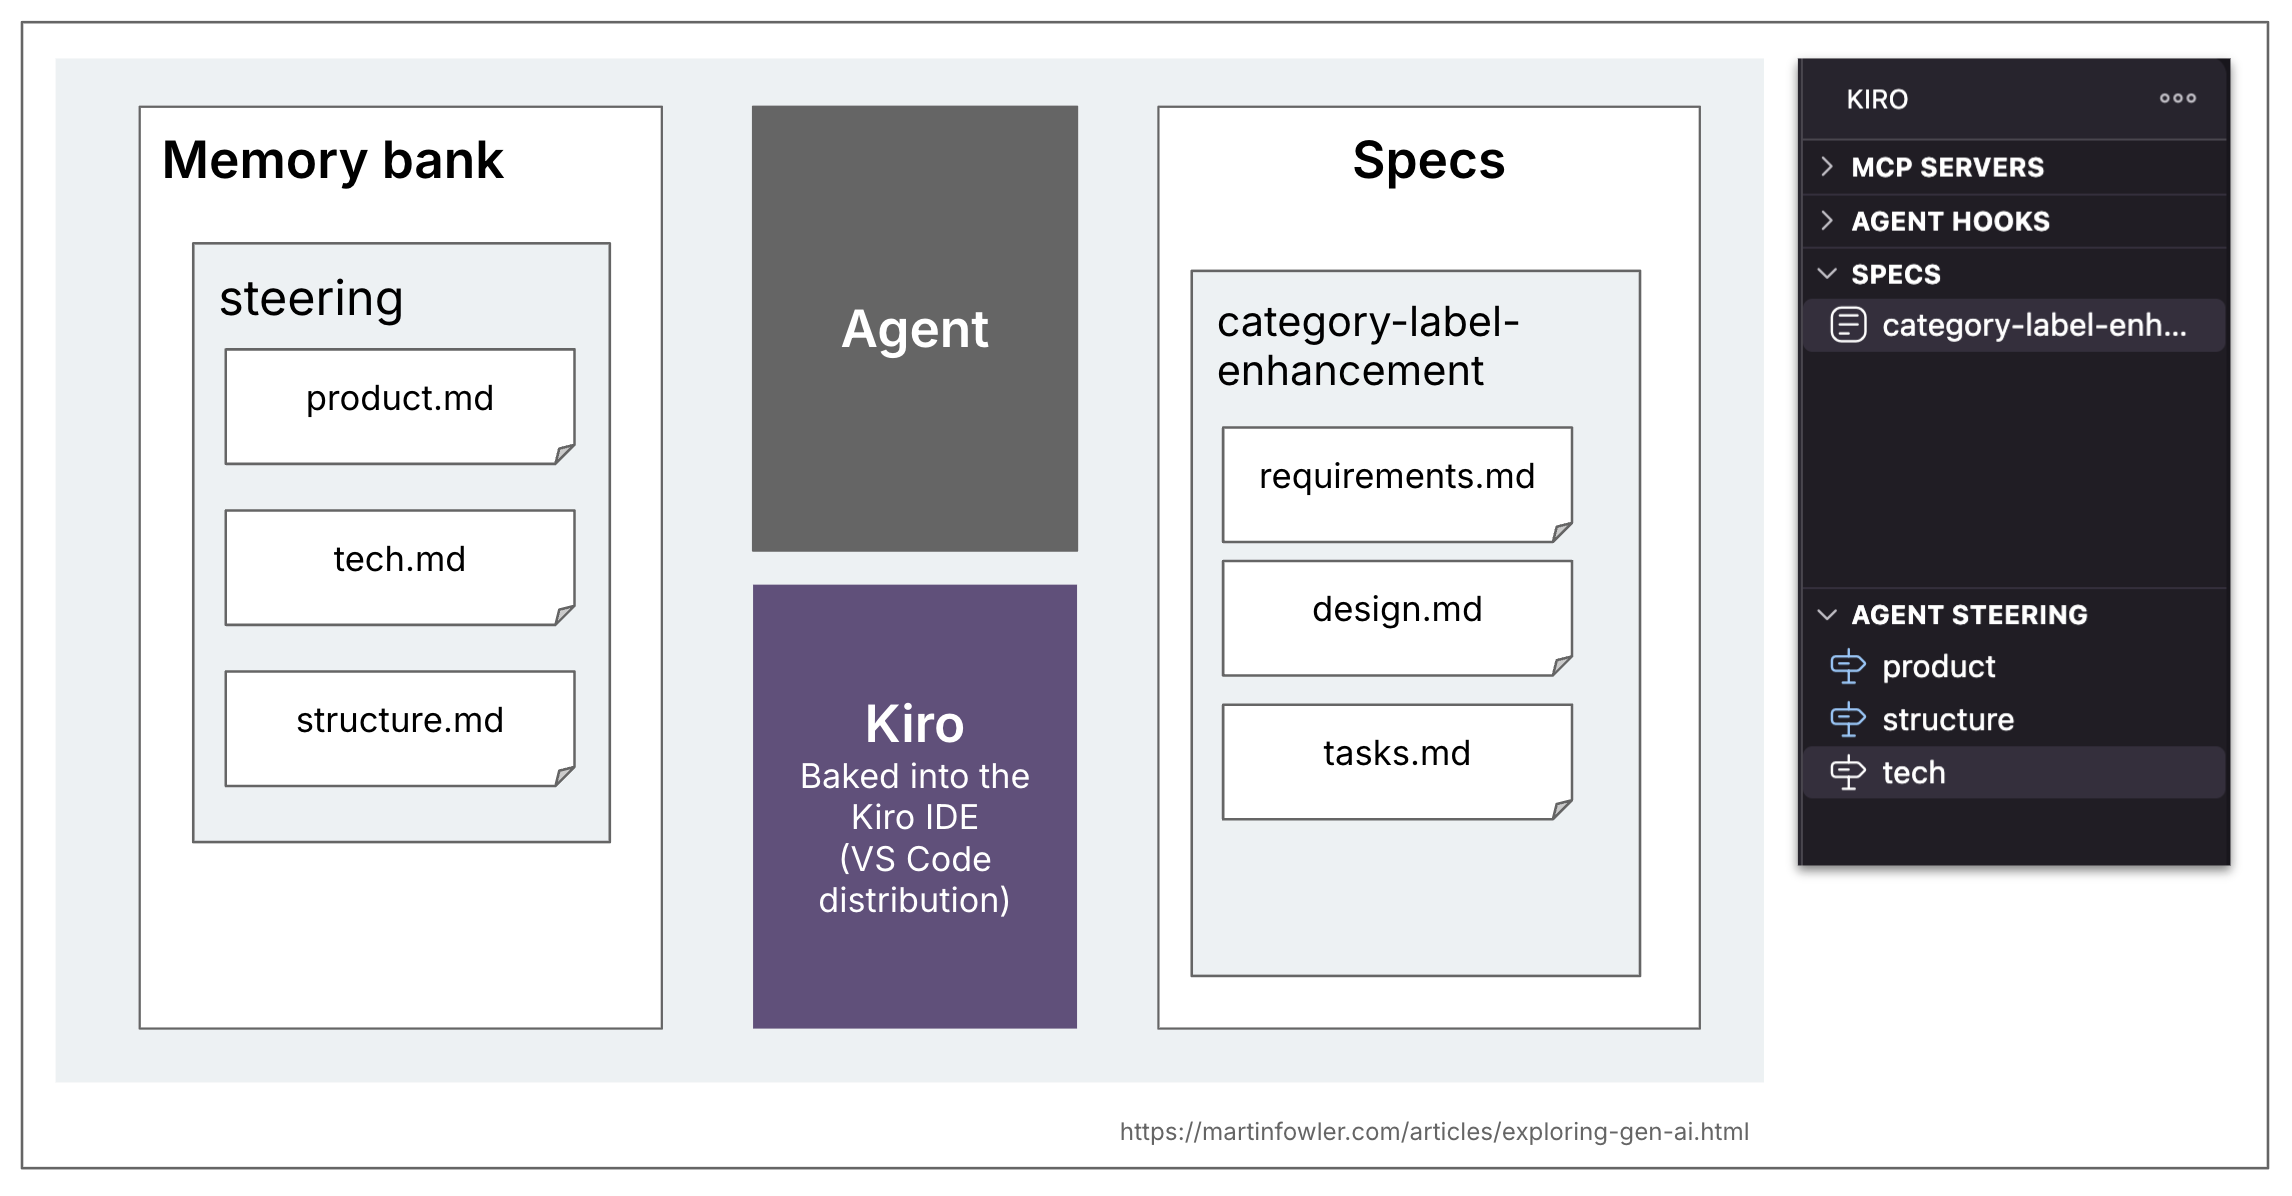
+Kiro also has the concept of a memory bank, they call it “steering”. Its contents are flexible, and their workflow doesn’t seem to rely on any specific files being there (I made my usage attempts before I even discovered the steering section). The default topology created by Kiro when you ask it to generate steering documents is product.md, structure.md, tech.md.
+
+
+
+## Spec-kit
+
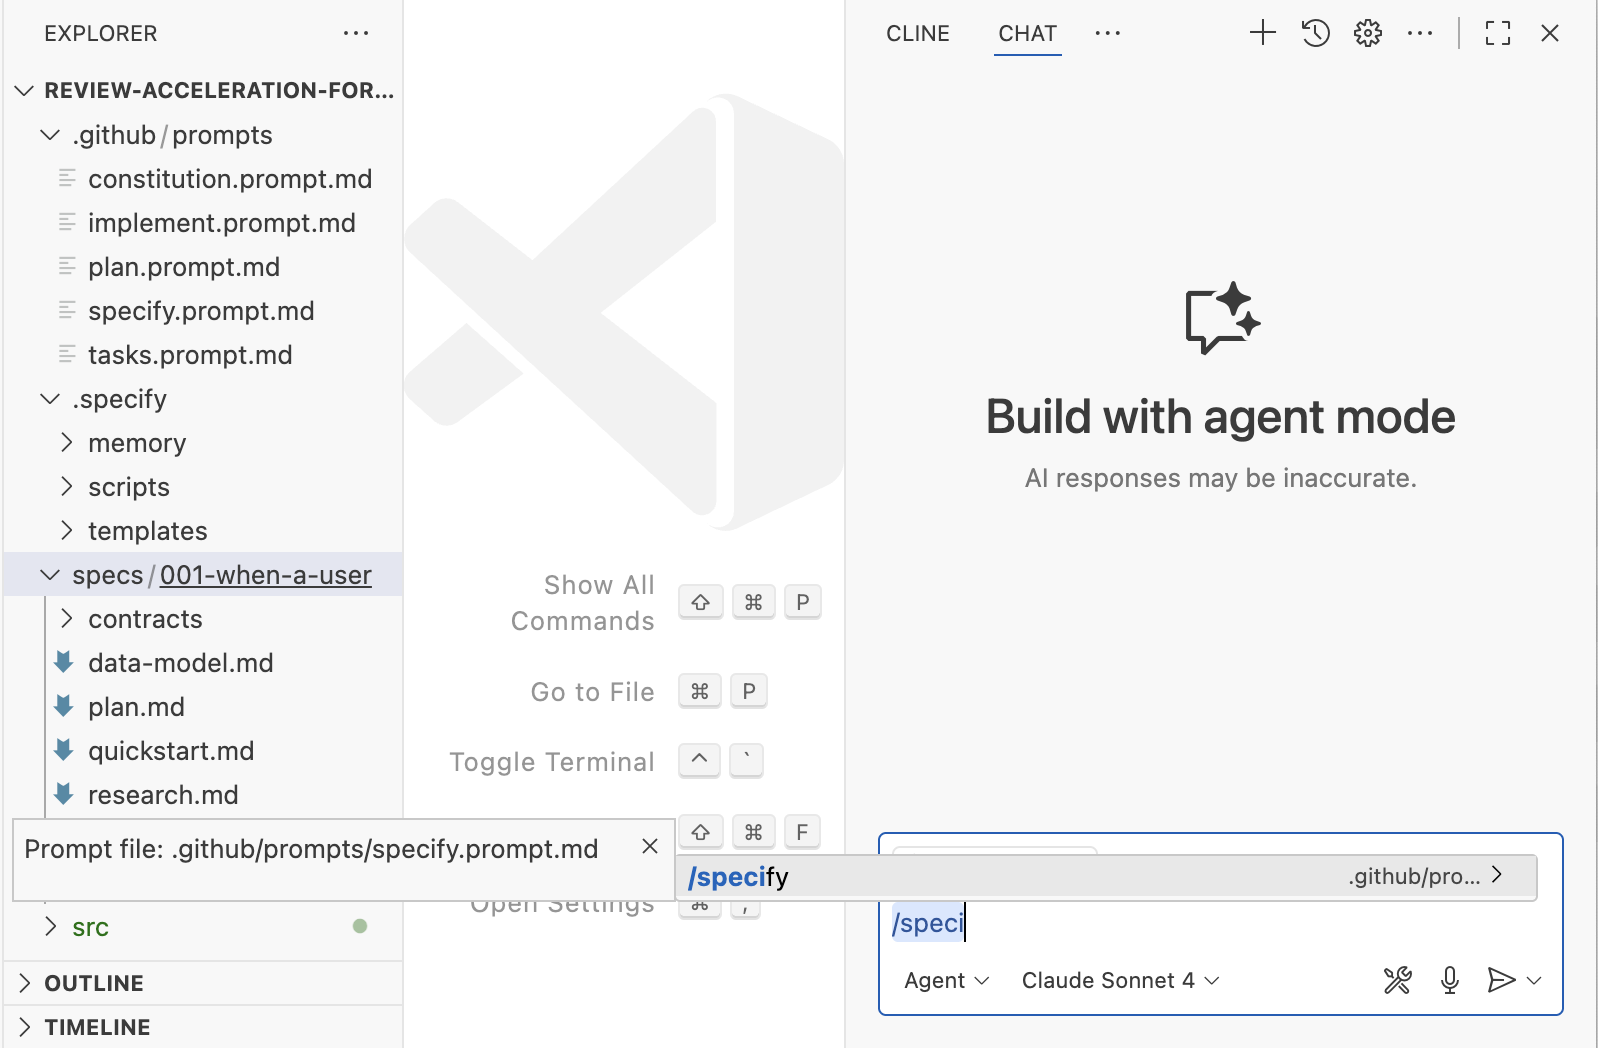
+[Spec-kit](https://github.com/github/spec-kit) is GitHub’s version of SDD. It is distributed as a CLI that can create workspace setups for a wide range of common coding assistants. Once that structure is set up, you interact with spec-kit via slash commands in your coding assistant. Because all of its artifacts are put right into your workspace, this is the most customizable one of the three tools discussed here.
+
+
+
+**Workflow:** Constitution → 𝄆 Specify → Plan → Tasks 𝄇
+
+Spec-kit’s memory bank concept is a prerequisite for the spec-driven approach. They call it a [**constitution**](https://github.com/github/spec-kit/blob/main/spec-driven.md#the-constitutional-foundation-enforcing-architectural-discipline). The constitution is supposed to contain the high level principles that are “immutable” and should always be applied, to every change. It’s basically a very powerful rules file that is heavily used by the workflow.
+
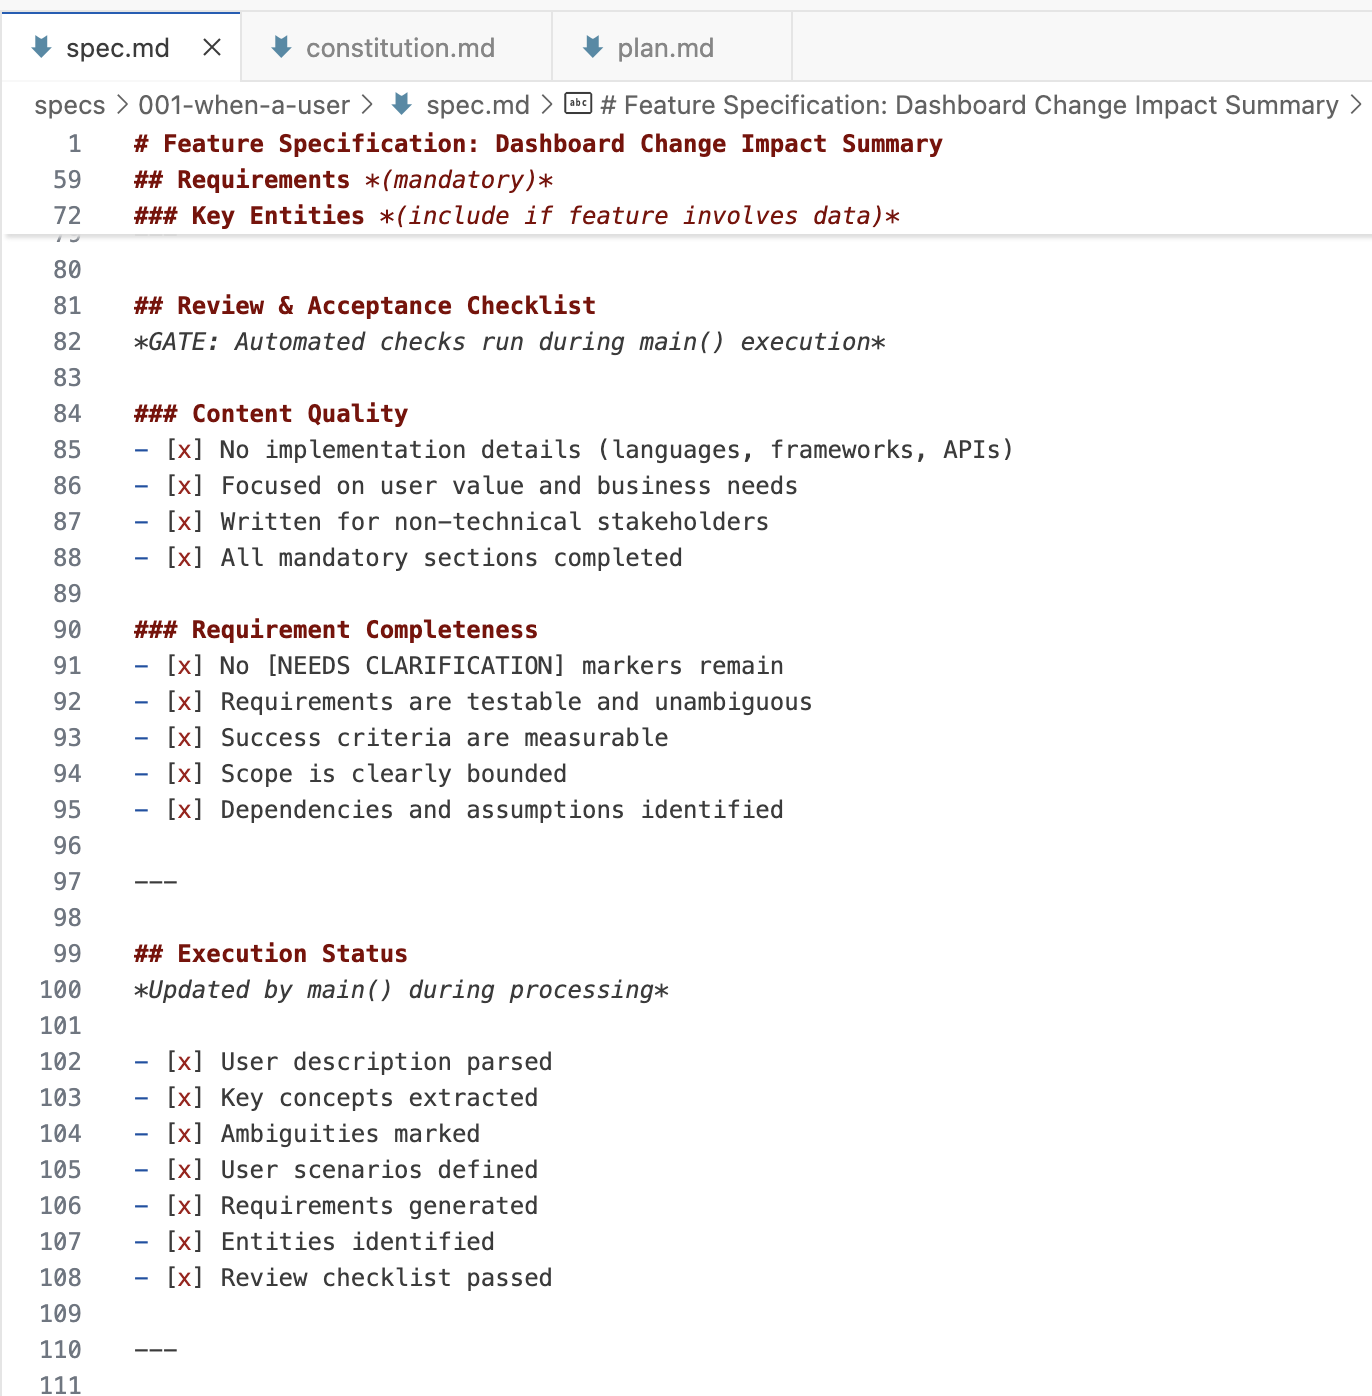
+In each of the workflow steps (specify, plan, tasks), spec-kit instantiates a set of files and prompts with the help of a bash script and some templates. The workflow then makes heavy use of checklists inside of the files, to track necessary user clarifications, constitution violations, research tasks, etc. They are like a “definition of done” for each workflow step (though interpreted by AI, so there is no 100% guarantee that they will be respected).
+
+
+
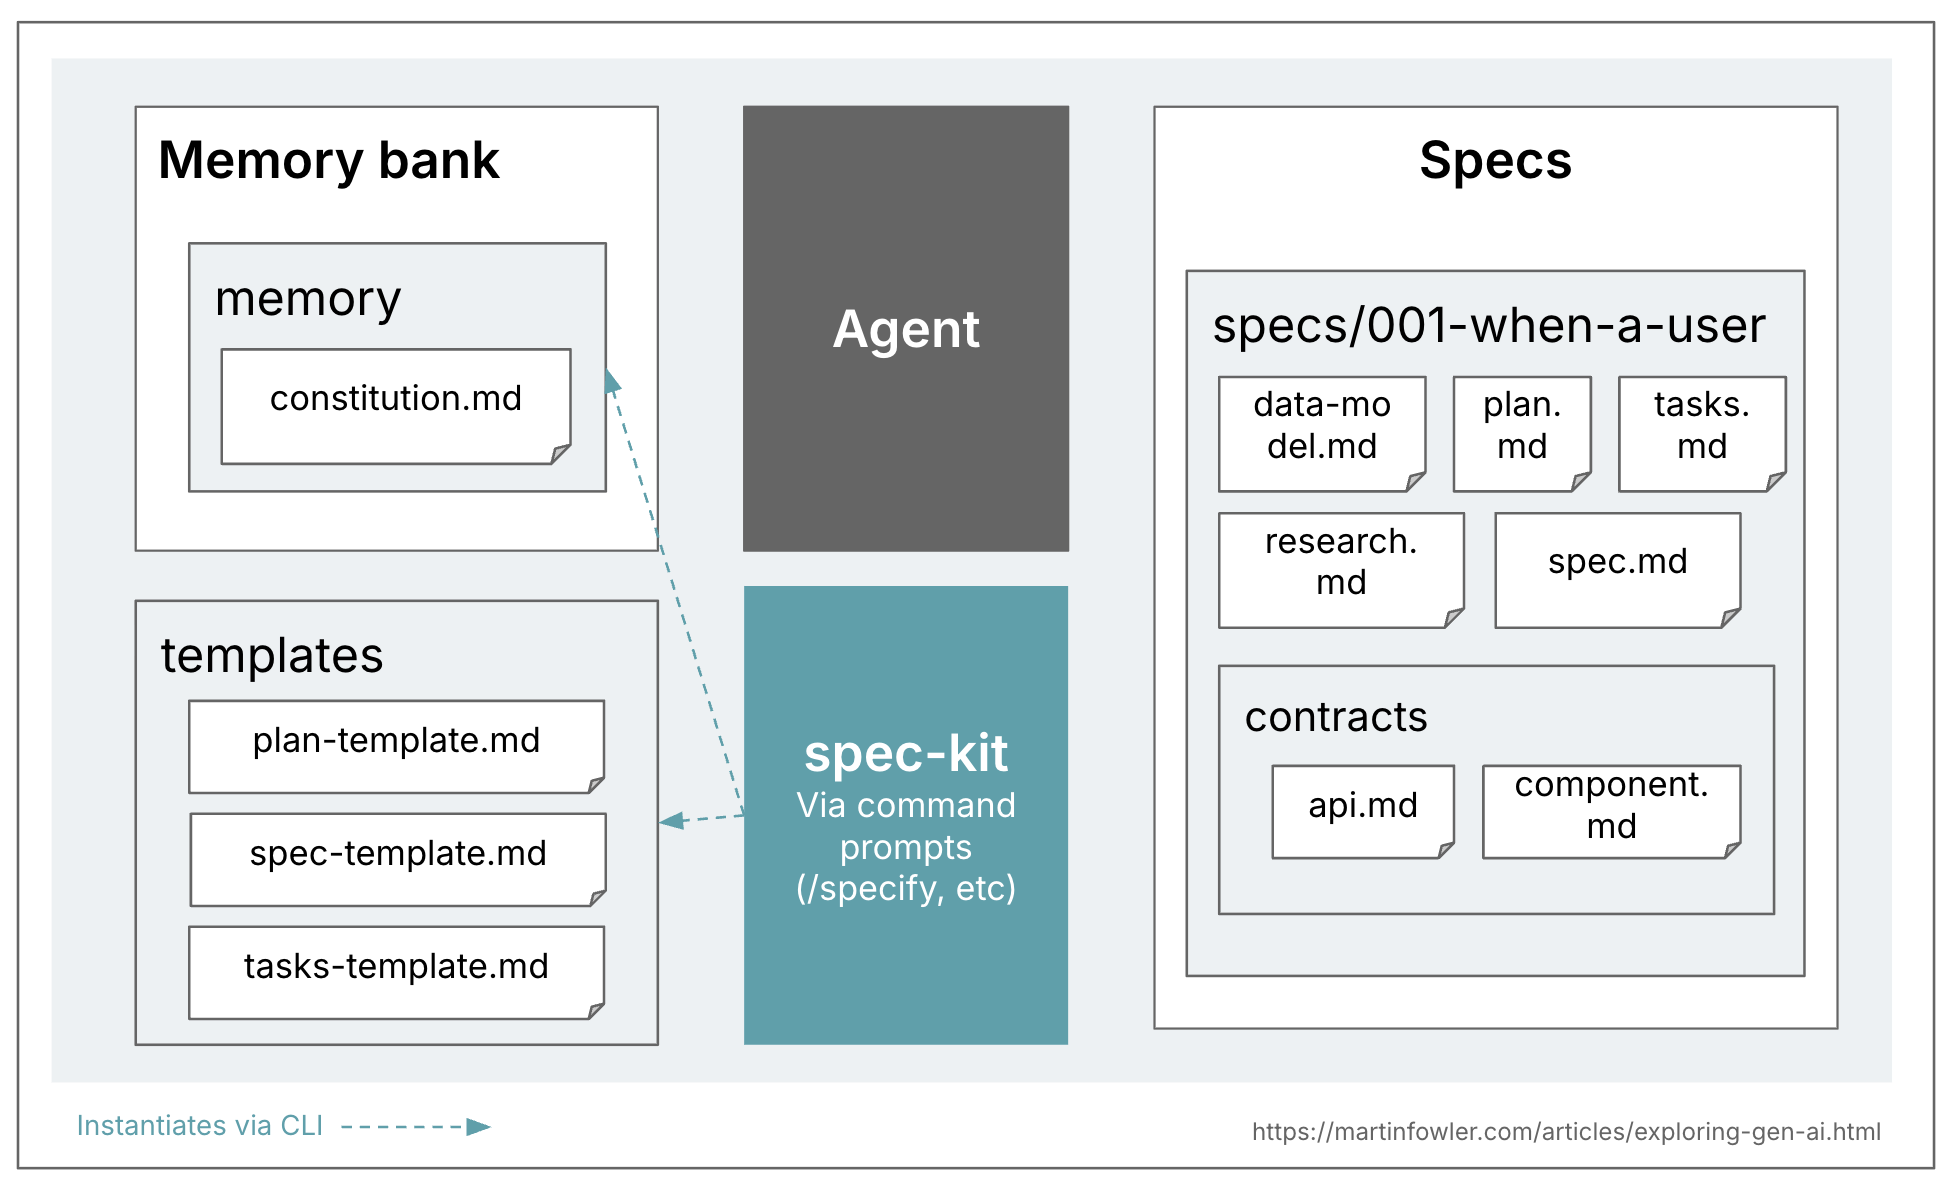
+Below is an overview to illustrate the file topology I saw in spec-kit. Note how one spec is made up of many files.
+
+
+
+At first glance, GitHub seems to be [aspiring to a spec-anchored approach](https://github.blog/ai-and-ml/generative-ai/spec-driven-development-with-ai-get-started-with-a-new-open-source-toolkit/) (“That’s why we’re rethinking specifications — not as static documents, but as living, executable artifacts that evolve with the project. Specs become the shared source of truth. When something doesn’t make sense, you go back to the spec; when a project grows complex, you refine it; when tasks feel too large, you break them down.”) However, spec-kit creates a branch for every spec that gets created, which seems to indicate that they see a spec as a living artifact for the lifetime of a change request, not the lifetime of a feature. [This community discussion](https://github.com/github/spec-kit/discussions/152) is talking about this confusion. It makes me think that spec-kit is still what I would call spec-first only, not spec-anchored over time.
+
+## Tessl Framework
+
+*(Still in private beta)*
+
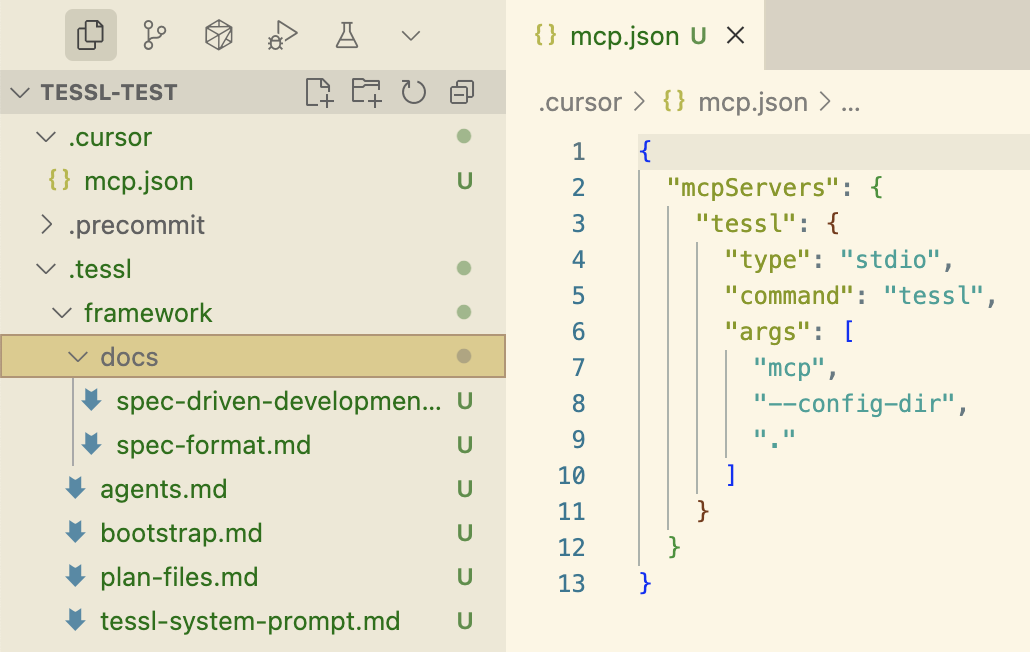
+Like spec-kit, the [Tessl Framework](https://docs.tessl.io/introduction-to-tessl/quick-start-guide-tessl-framework) is distributed as a CLI that can create all the workspace and config structure for a variety of coding assistants. The CLI command also doubles as an MCP server.
+
+
+
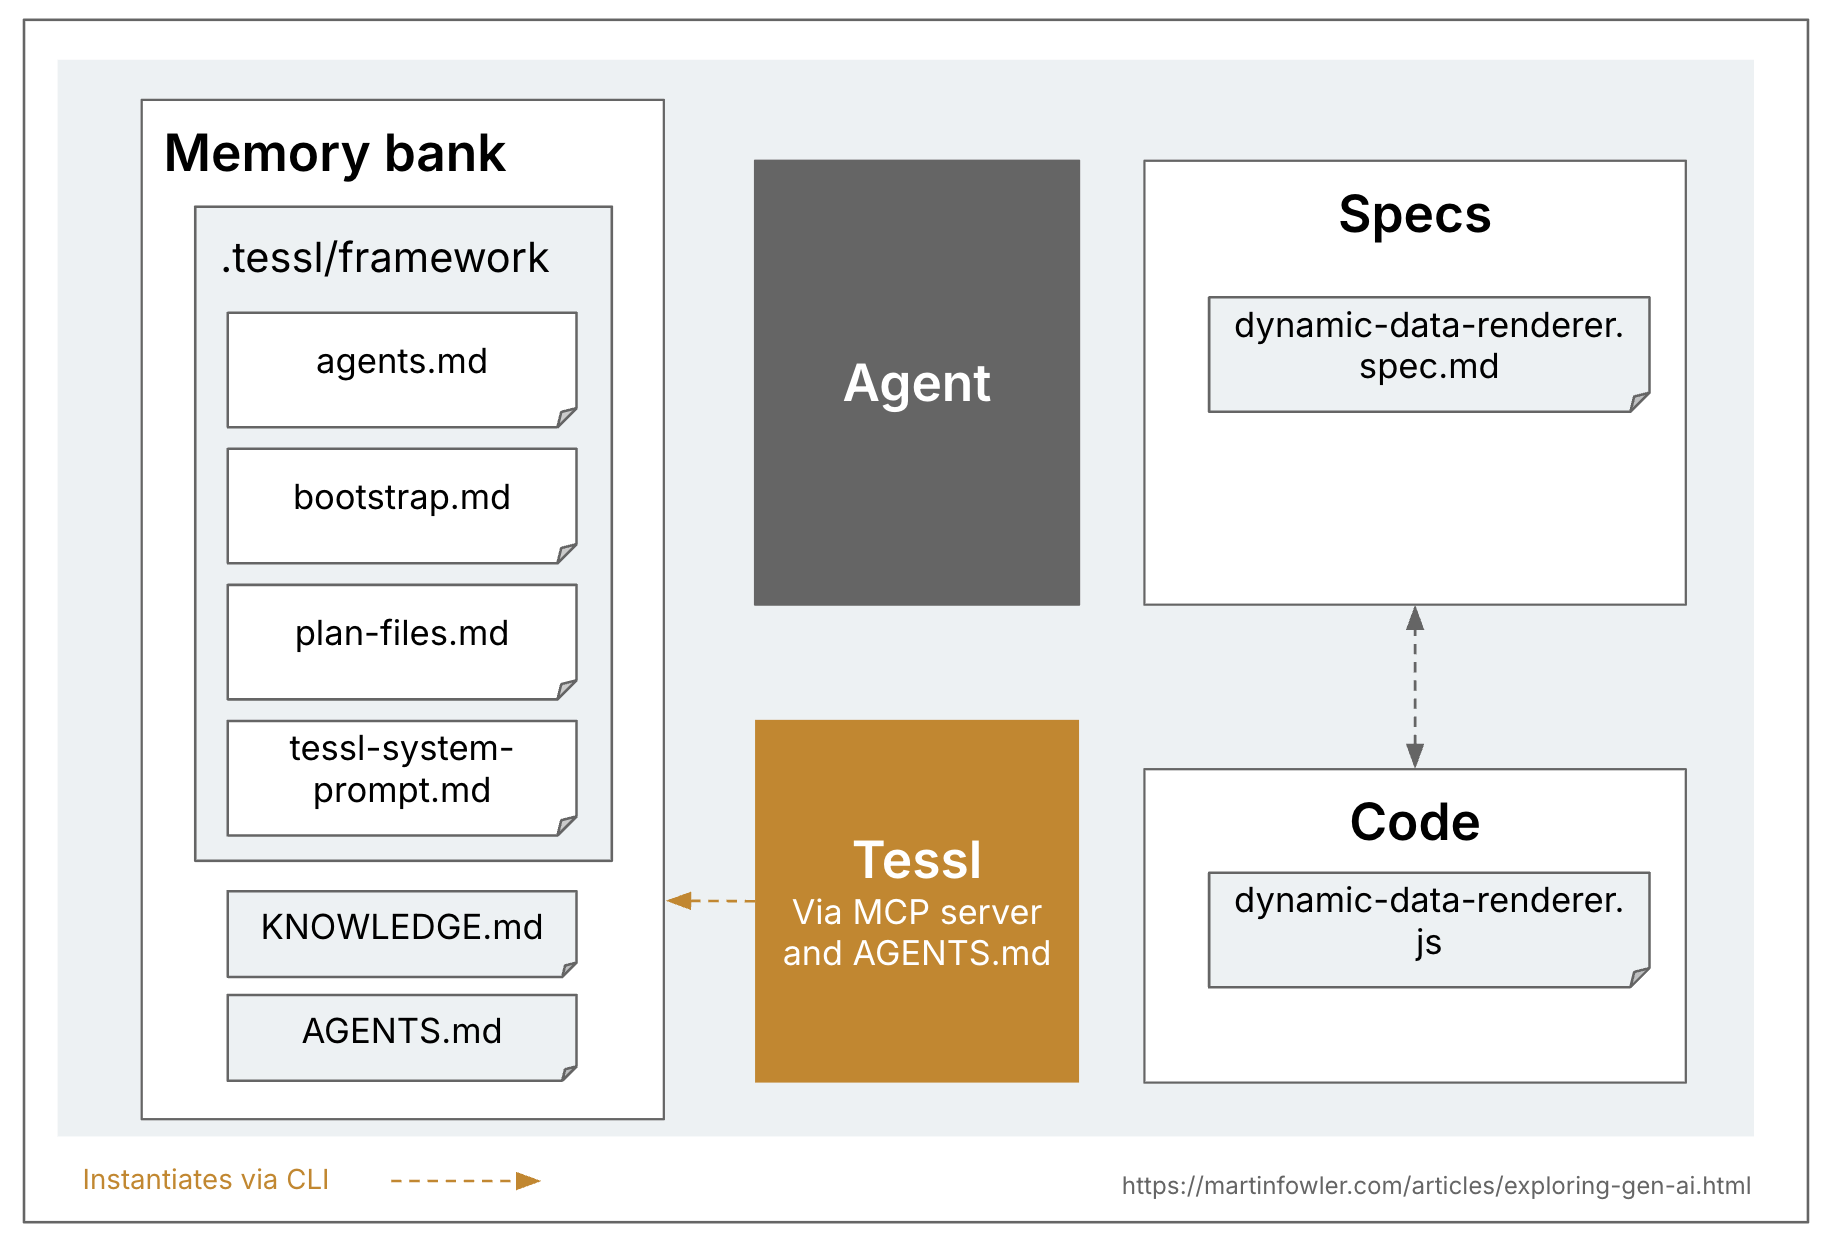
+Tessl is the only one of these three tools that explicitly aspires to a spec-anchored approach, and is even exploring the spec-as-source level of SDD. A Tessl spec can serve as the main artifact that is being maintained and edited, with the code even marked with a comment at the top saying `// GENERATED FROM SPEC - DO NOT EDIT`. This is currently a 1:1 mapping between spec and code files, i.e. one spec translates into one file in the codebase. But Tessl is still in beta and they are experimenting with different versions of this, so I can imagine that this approach could also be taken on a level where one spec maps to a code component with multiple files. It remains to be seen what the alpha product will support. (The Tessl team themselves see their framework as something that is more in the future than their current public product, the Tessl Registry.)
+
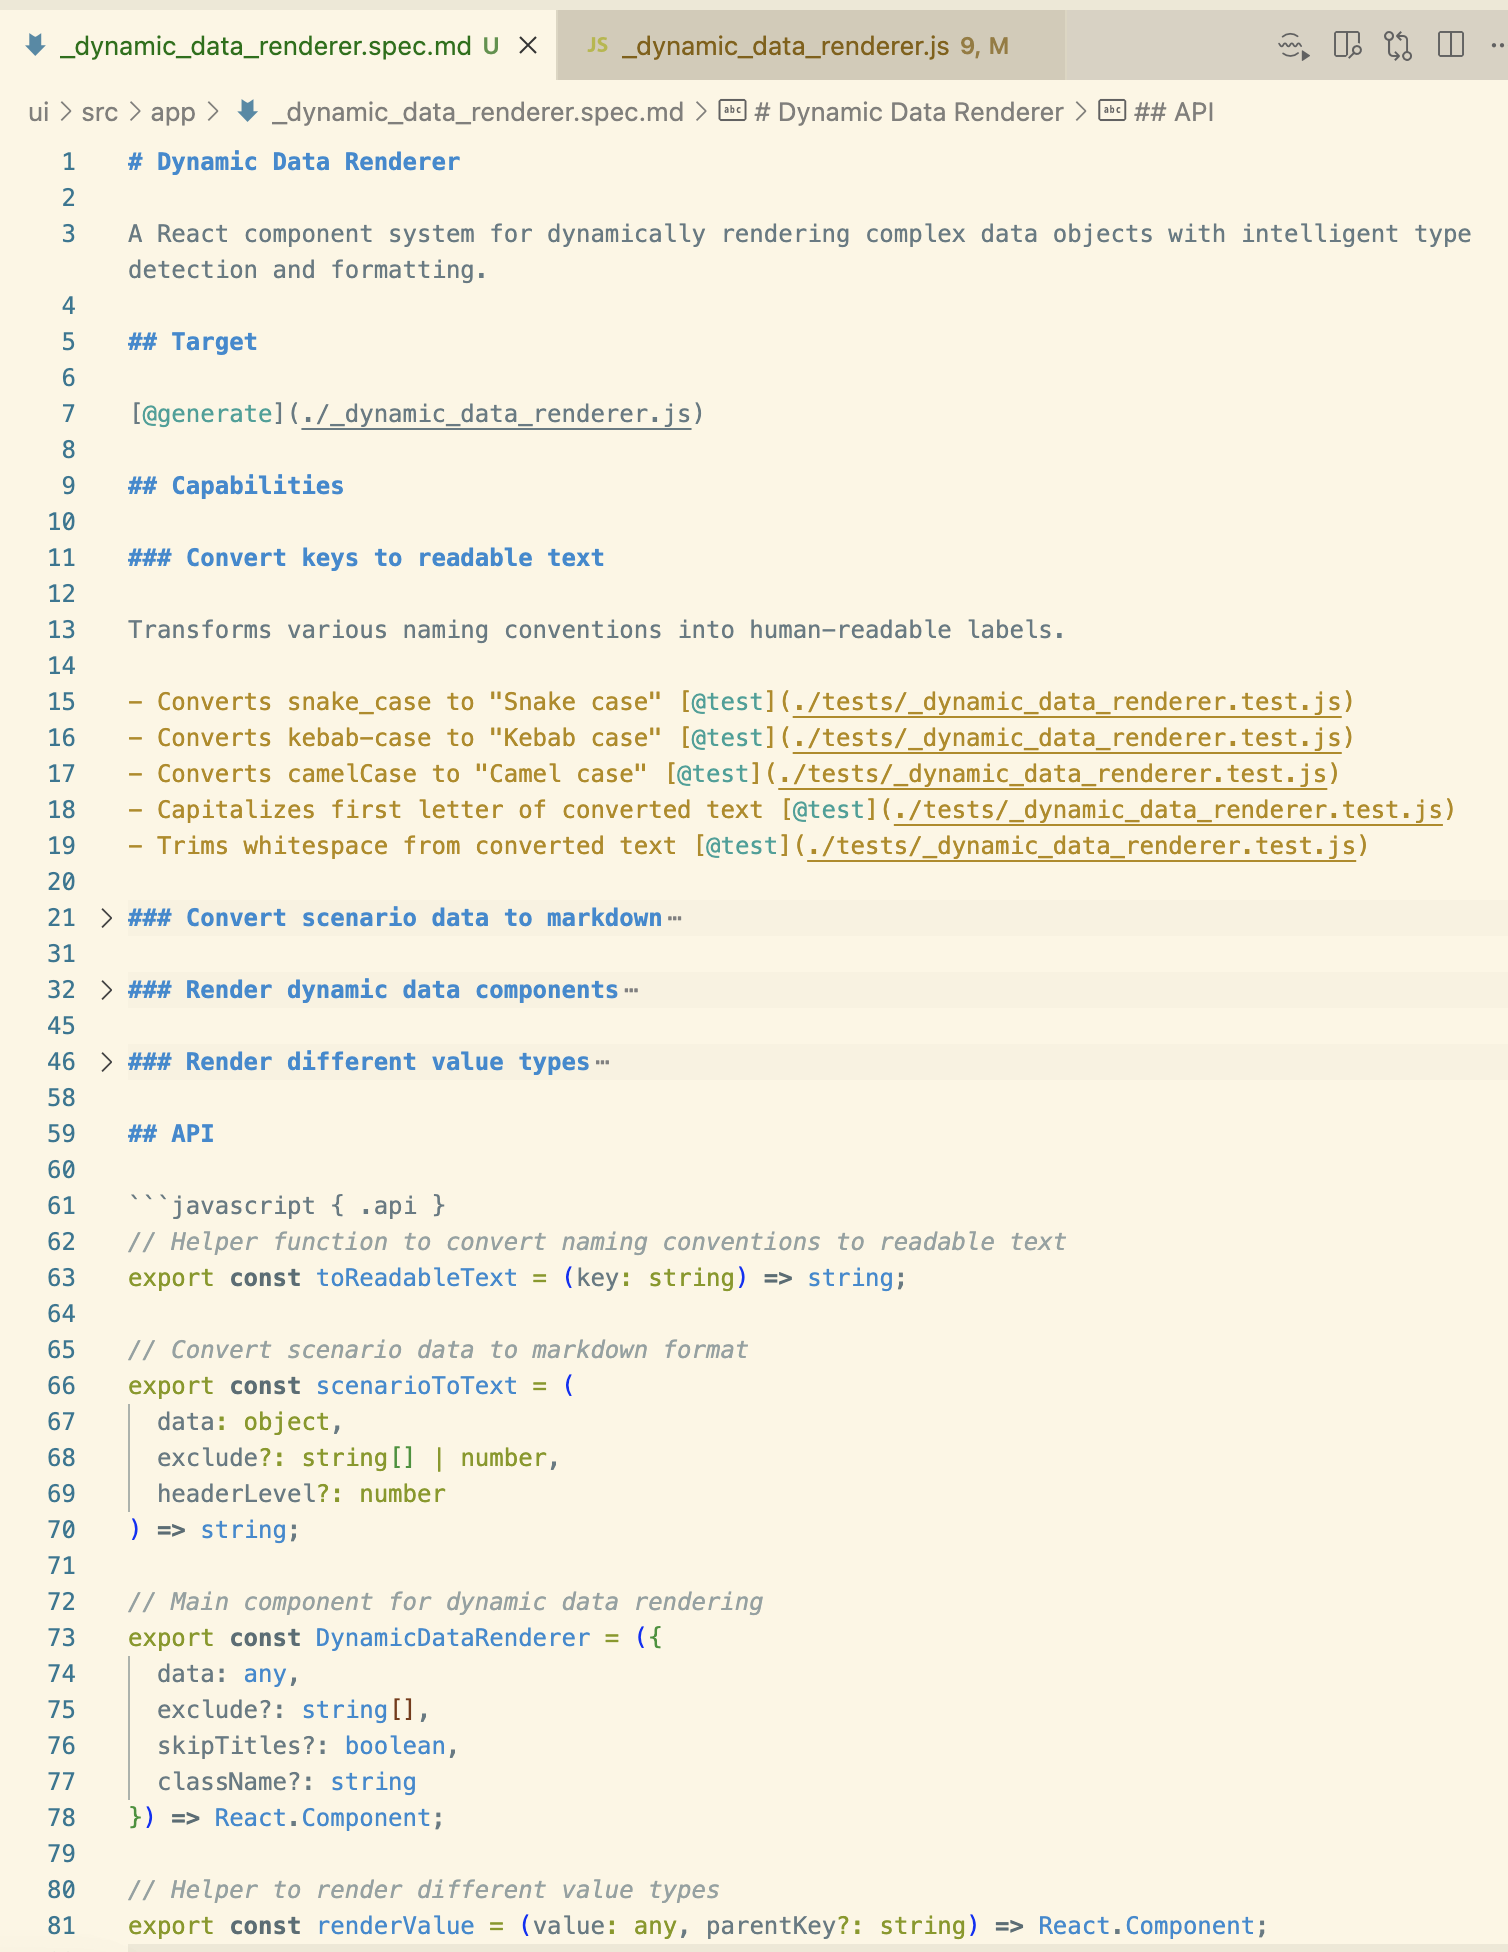
+Here is an example of a spec that I had the Tessl CLI reverse engineer (`tessl document --code ...js`) from a JavaScript file in an existing codebase:
+
+
+
+Tags like `@generate` or `@test` seem to tell Tessl what to generate. The API section shows the idea of defining at least the interfaces that get exposed to other parts of the codebase in the spec, presumably to make sure that these more crucial parts of the generated component are fully under the control of the maintainer. Running `tessl build` for this spec generates the corresponding JavaScript code file.
+
+Putting the specs for spec-as-source at a quite low abstraction level, per code file, probably reduces amount of steps and interpretations the LLM has to do, and therefore the chance of errors. Even at this low abstraction level I have seen the non-determinism in action though, when I generated code multiple times from the same spec. It was an interesting exercise to iterate on the spec and make it more and more specific to increase the repeatability of the code generation. That process reminded me of some of the pitfalls and challenges of writing an unambiguous and complete specification.
+
+
+
+## Observations and questions
+
+These three tools are all labelling themselves as implementations of spec-driven development, but they are quite different from each other. So that’s the first thing to keep in mind when talking about SDD, it is not just one thing.
+
+### One workflow to fit all sizes?
+
+Kiro and spec-kit provide one opinionated workflow each, but I’m quite sure that neither of them is suitable for the majority of real life coding problems. In particular, it’s not quite clear to me how they would cater to enough different problem sizes to be generally applicable.
+
+When I asked Kiro to fix a small bug ([it was the same one I used in the past to try Codex](https://martinfowler.com/articles/exploring-gen-ai/autonomous-agents-codex-example.html)), it quickly became clear that the workflow was like using a sledgehammer to crack a nut. The requirements document turned this small bug into 4 “user stories” with a total of 16 acceptance criteria, including gems like “User story: As a developer, I want the transformation function to handle edge cases gracefully, so that the system remains robust when new category formats are introduced.”
+
+I had a similar challenge when I used spec-kit, I wasn’t quite sure what size of problem to use it for. Available tutorials are usually based on creating an application from scratch, because that’s easiest for a tutorial. One of the use cases I ended up trying was a feature that would be a 3-5 point story on one of my past teams. The feature depended on a lot of code that was already there, it was supposed to build an overview modal that summarised a bunch of data from an existing dashboard. With the amount of steps spec-kit took, and the amount of markdown files it created for me to review, this again felt like overkill for the size of the problem. It was a bigger problem than the one I used with Kiro, but also a much more elaborate workflow. I never even finished the full implementation, but I think in the same time it took me to run and review the spec-kit results I could have implemented the feature with “plain” AI-assisted coding, and I would have felt much more in control.
+
+An effective SDD tool would at the very least have to provide flexibility for a few different core workflows, for different sizes and types of changes.
+
+### Reviewing markdown over reviewing code?
+
+As just mentioned, and as you can see in the description of the tool above, spec-kit created a LOT of markdown files for me to review. They were repetitive, both with each other, and with the code that already existed. Some contained code already. Overall they were just very verbose and tedious to review. In Kiro it was a little easier, as you only get 3 files, and it’s more intuitive to understand the mental model of “requirements > design > tasks”. However, as mentioned, Kiro also was way too verbose for the small bug I was asking it to fix.
+
+To be honest, I’d rather review code than all these markdown files. An effective SDD tool would have to provide a very good spec review experience.
+
+### False sense of control?
+
+Even with all of these files and templates and prompts and workflows and checklists, I frequently saw the agent ultimately not follow all the instructions. Yes, the context windows are now larger, which is often mentioned as one of the enablers of spec-driven development. But just because the windows are larger, doesn’t mean that AI will properly pick up on everything that’s in there.
+
+For example: Spec-kit has a research step somewhere during planning, and it did a lot of research on the existing code and what’s already there, which was great because I asked it to add a feature that built on top of existing code. But ultimately the agent ignored the notes that these were descriptions of existing classes, it just took them as a new specification and generated them all over again, creating duplicates. But I didn’t only see examples of ignoring instructions, I also saw the agent go way overboard because it was too eagerly following instructions (e.g. one of the constitution articles).
+
+The past has shown that the best way for us to stay in control of what we’re building are small, iterative steps, so I’m very skeptical that lots of up-front spec design is a good idea, especially when it’s overly verbose. An effective SDD tool would have to cater to an iterative approach, but small work packages almost seem counter to the idea of SDD.
+
+### How to effectively separate functional from technical spec?
+
+It is a common idea in SDD to be intentional about the separation between functional spec and technical implementation. The underlying aspiration I guess is that ultimately, we could have AI fill in all the solutioning and details, and switch to different tech stacks with the same spec.
+
+In reality, when I was trying spec-kit, I frequently got confused when to stay on the functional level, and when it was time to add technical details. The tutorial and documentation also weren’t quite consistent with it, there seem to be different interpretations of what “purely functional” really means. And when I think back on the many, many user stories I’ve read in my career that weren’t properly separating requirements from implementation, I don’t think we have a good track record as a profession to do this well.
+
+### Who is the target user?
+
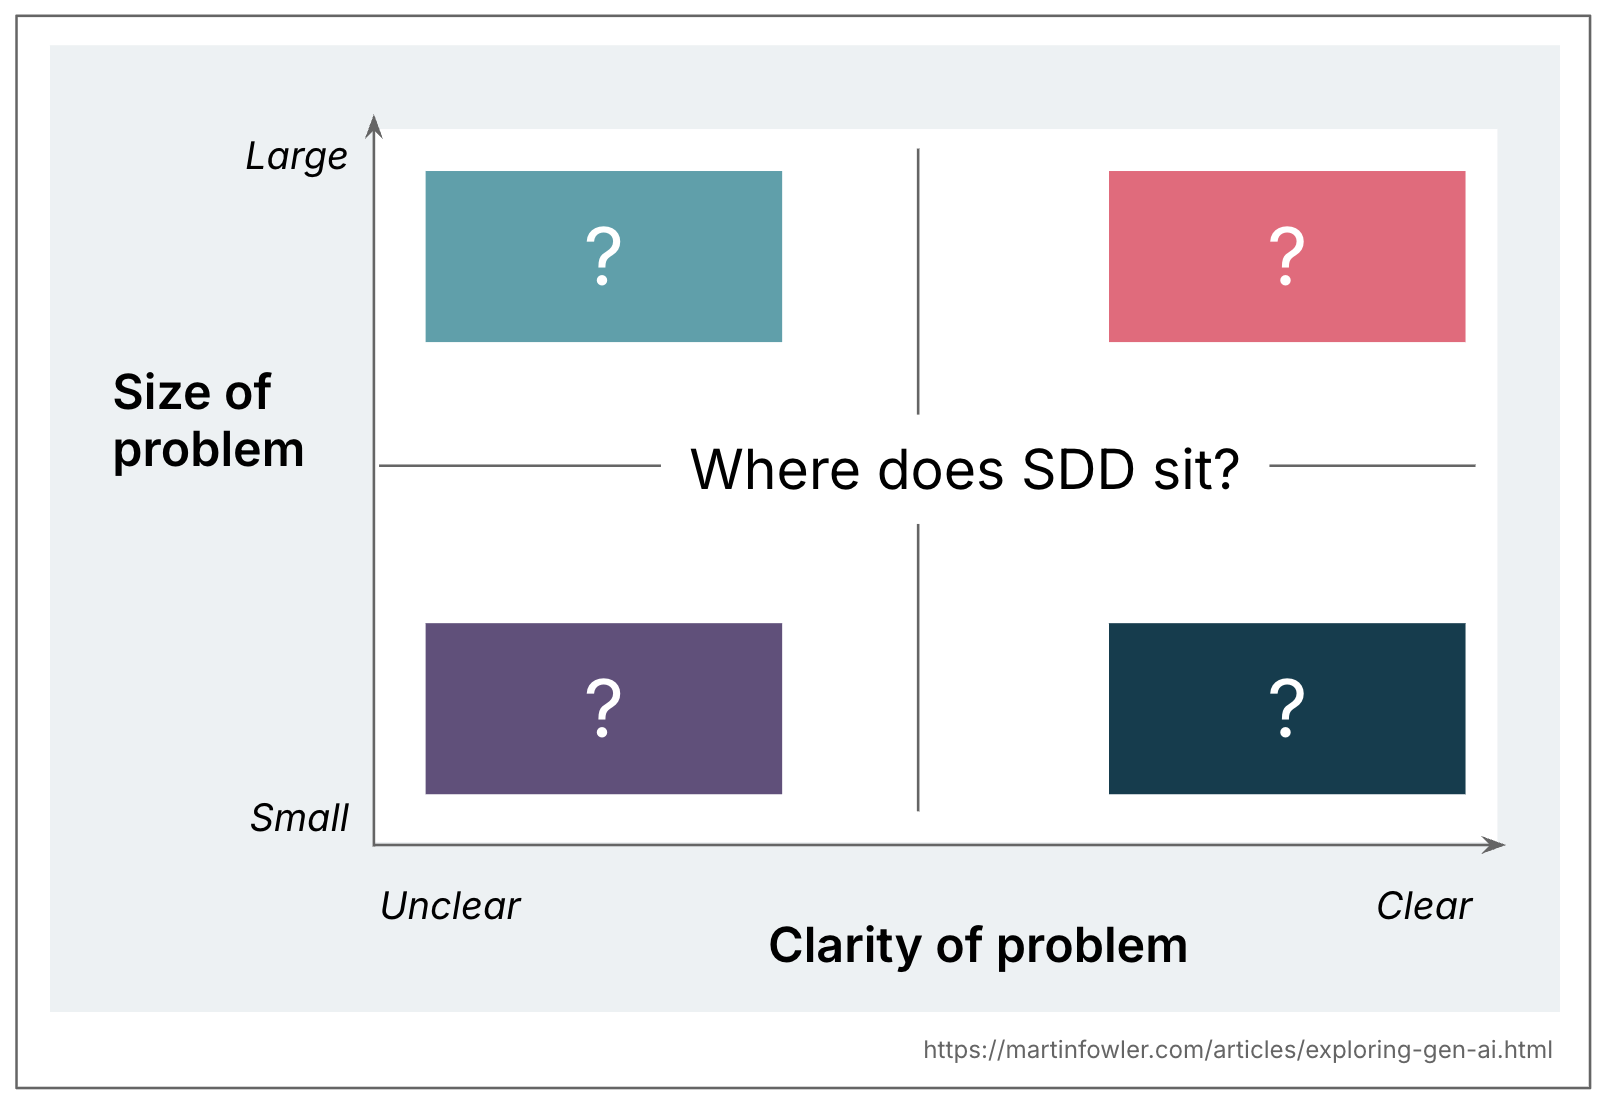
+Many of the demos and tutorials for spec-driven development tools include things like defining product and feature goals, they even incorporate terms like “user story”. The idea here might be to use AI as an enabler for cross-skilling, and have developers participate more heavily in requirements analysis? Or have developers pair with product people when they work on this workflow? None of this is made explicit though, it’s presented as a given that a developer would do all this analysis.
+
+In which case I would ask myself again, what problem size and type is SDD meant for? Probably not for large features that are still very unclear, as surely that would require more specialist product and requirements skills, and lots of other steps like research and stakeholder involvement?
+
+
+
+### Spec-anchored and spec-as-source: Are we learning from the past?
+
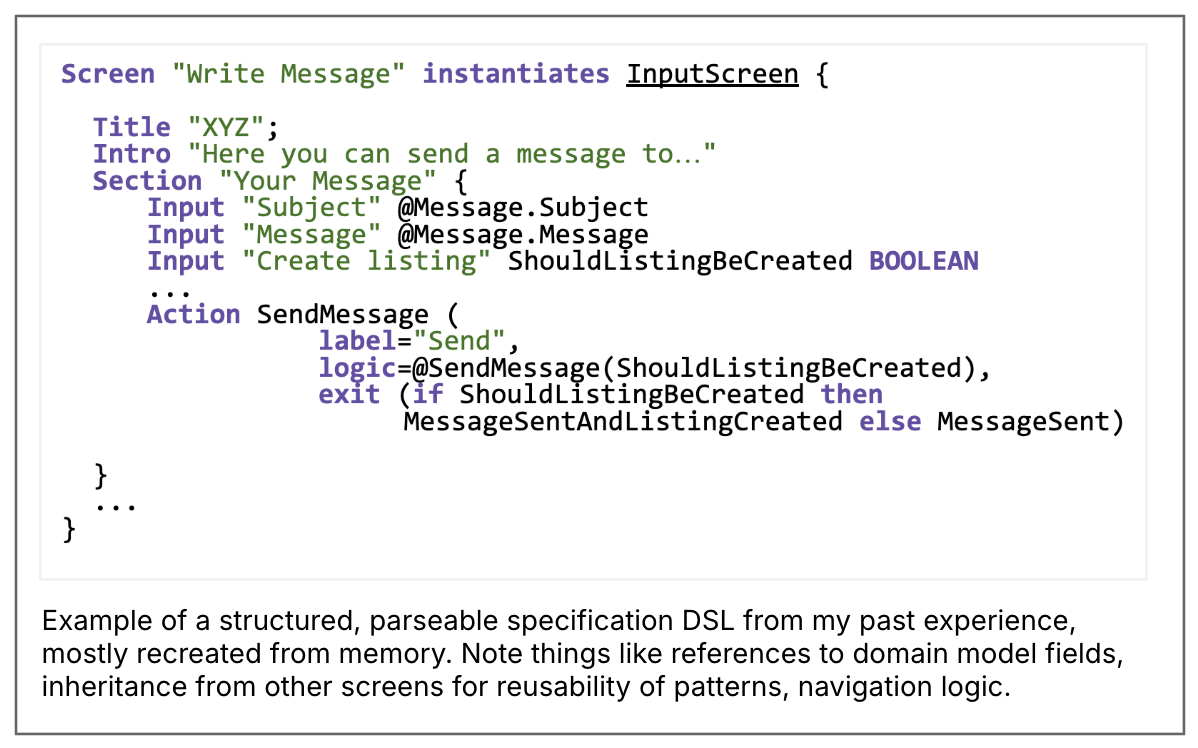
+While many people draw analogies between SDD and TDD or BDD, I think another important parallel to look at for spec-as-source in particular is MDD (model-driven development). I worked on a few projects at the beginning of my career that heavily used MDD, and I kept being reminded about that when I was trying out the Tessl Framework. The models in MDD were basically the specs, albeit not in natural language, but expressed in e.g. custom UML or a textual DSL. We built custom code generators to turn those specs into code.
+
+
+
+Ultimately, MDD never took off for business applications, it sits at an awkward abstraction level and just creates too much overhead and constraints. But LLMs take some of the overhead and constraints of MDD away, so there is a new hope that we can now finally focus on writing specs and just generate code from them. With LLMs, we are not constrained by a predefined and parseable spec language anymore, and we don’t have to build elaborate code generators. The price for that is LLMs’ non-determinism of course. And the parseable structure also had upsides that we’re losing now: We could provide the spec author with a lot of tool support to write valid, complete and consistent specs. I wonder if spec-as-source, and even spec-anchoring, might end up with the downsides of both MDD and LLMs: Inflexibility *and* non-determinism.
+
+To be clear, I’m not nostalgic about my MDD experience in the past and saying “we might as well bring that back”. But we should look to code-from-spec attempts in the past to learn from them when we explore spec-driven today.
+
+## Conclusions
+
+In my personal usage of AI-assisted coding, I also often spend time on carefully crafting some form of spec first to give to the coding agent. So the general principle of spec-first is definitely valuable in many situations, and the different approaches of how to structure that spec are very sought after. They are among the top most frequently asked questions I hear at the moment from practitioners: “How do I structure my memory bank?”, “How do I write a good specification and design document for AI?”.
+
+But the term “spec-driven development” isn’t very well defined yet, and it’s already [semantically diffused](https://martinfowler.com/bliki/SemanticDiffusion.html). I’ve even recently heard people use “spec” basically as a synonym for “detailed prompt”.
+
+Regarding the tools I’ve tried, I have listed many of my questions about their real world usefulness here. I wonder if some of them are trying to feed AI agents with our existing workflows too literally, ultimately amplifying existing challenges like review overload and hallucinations. Especially with the more elaborate approaches that create lots of files, I can’t help but think of the German compound word “Verschlimmbesserung”: Are we making something worse in the attempt of making it better?
\ No newline at end of file
diff --git a/00_Inbox/Clippings/2026/01/YAGNI Principle in Software Development.md b/00_Inbox/Clippings/2026/01/YAGNI Principle in Software Development.md
new file mode 100644
index 0000000..cbfd0e0
--- /dev/null
+++ b/00_Inbox/Clippings/2026/01/YAGNI Principle in Software Development.md
@@ -0,0 +1,64 @@
+---
+title: "YAGNI Principle in Software Development"
+source: "https://www.geeksforgeeks.org/software-engineering/what-is-yagni-principle-you-arent-gonna-need-it/"
+author:
+ - "[[GeeksforGeeks]]"
+published: 2024-02-20
+created: 2026-01-22
+description: "Your All-in-One Learning Portal: GeeksforGeeks is a comprehensive educational platform that empowers learners across domains-spanning computer science and programming, school education, upskilling, commerce, software tools, competitive exams, and more."
+tags:
+ - "clippings"
+ - "webclipper"
+---
+> [!info] Source
+> URL: https://www.geeksforgeeks.org/software-engineering/what-is-yagni-principle-you-arent-gonna-need-it/
+> Title: YAGNI Principle in Software Development
+> Clipped:
+
+页面已保存到 Trilium。 [在 Trilium 中打开。](https://www.geeksforgeeks.org/software-engineering/what-is-yagni-principle-you-arent-gonna-need-it/)
+
+Last Updated: 27 Aug, 2025
+
+****"YAGNI"**** stands for ****"You Aren't Gonna Need It".**** It is a principle in software development that suggests developers should only implement features that are necessary for the current requirements and not add any additional functionality that might be needed in the future.
+
+- This principle is based on the idea that adding unnecessary features can lead to increased complexity, longer development times, and potentially more bugs.
+- The YAGNI principle is closely related to the ****"**** [****KISS****](https://www.geeksforgeeks.org/software-engineering/kiss-principle-in-software-development/) ****"**** principle ("Keep It Simple, Stupid"), which advocates for simplicity in design and avoiding unnecessary complexity. Both principles encourage developers to focus on delivering the simplest solution that meets current requirements, rather than trying to anticipate and accommodate potential future needs.
+
+### Why a developer should follow the YAGNI principle?
+
+The developer should follow YAGNI principles for the following reasons:
+
+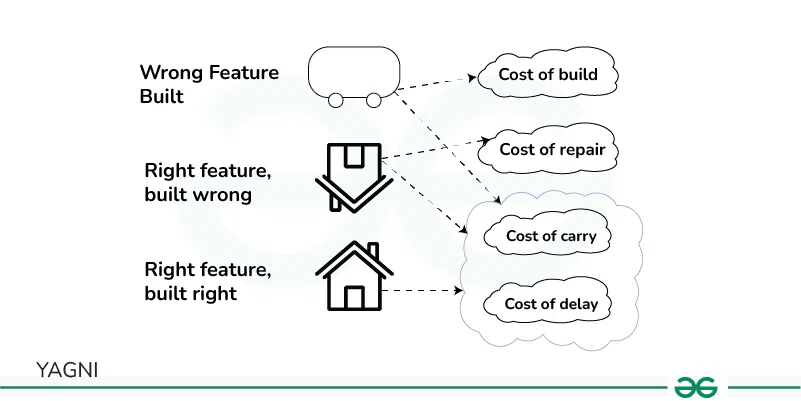
+- ****Cost of Building:**** The cost of build is the amount of time, effort, and resources spent on creating a feature or solution. It includes everything from planning and coding to testing.
+- ****Cost of Delay:**** The cost of delay is the missed opportunity or economic impact of not delivering a feature or solution promptly.
+- ****Cost of Carry:**** When a feature adds complexity, it can make it harder to work on other parts of the software, leading to additional time and effort.
+- ****Cost of Repair:**** The cost of repair, also known as technical debt, is the ongoing cost associated with fixing mistakes, bugs, or poor choices made during the development of a feature.
+
+### Steps to follow YAGNI Principle
+
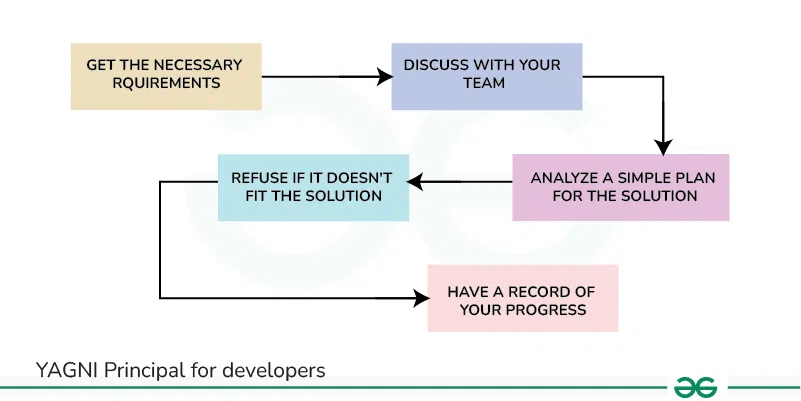
+To use YAGNI as a developer, it's like having a practical guide to keep your work focused and efficient.
+
+
+
+YAGNI Principal for Developers
+
+****1\. Get the Necessary Requirements**** : All the things your project needs and sort them into "must-haves" and "can wait."
+
+****2\. Discuss with Your Team:**** After that, it's time to talk with your team. Share your plans and goals with them. This makes sure everyone is on the same page and understands what needs to be done.
+
+****3\. Analyze a Simple Plan for the Solution:**** Now, when it comes to planning the actual work, keep it simple. Break down your big goals into smaller tasks. This helps you avoid getting overwhelmed and ensures you're focusing on what really matters.
+
+****4\. Refuse If It Doesn't Fit for the Solution:**** Sometimes, your team might come up with new ideas or want to add extra things. While these ideas might be cool, you've got to be ready to say "no" unless it's a tiny improvement. Saying "no" can be tough, but it keeps you from getting off track and missing deadlines.
+
+****5\. Have a Record of Your Progress:**** Keep a record of what you've done. It's like keeping score in a game. This helps you see how far you've come and if you're heading in the right direction.
+
+### Advantages of Applying YAGNI
+
+- ****Reduced Development Time****: By avoiding the development of unused features, teams can focus on current requirements and accelerate the delivery of functional software.
+- ****Improved Maintainability:**** Simpler, more focused codebases are easier to understand and maintain over time.
+- ****Increased Flexibility:**** The ability to defer decisions until later provides more clarity and allows for more informed design choices as requirements become clearer.
+- ****Fewer Bugs:**** Less complex code with fewer speculative features is less prone to bugs, leading to a higher quality product
+
+Overall, YAGNI complements other software development principles by focusing on delivering the simplest solution that meets the current requirements and avoiding unnecessary functionality.
+
+Article Tags:
\ No newline at end of file
diff --git a/00_Inbox/Clippings/2026/01/githubspec-kit 💫 Toolkit to help you get started with Spec-Driven Development.md b/00_Inbox/Clippings/2026/01/githubspec-kit 💫 Toolkit to help you get started with Spec-Driven Development.md
new file mode 100644
index 0000000..61d2ca5
--- /dev/null
+++ b/00_Inbox/Clippings/2026/01/githubspec-kit 💫 Toolkit to help you get started with Spec-Driven Development.md
@@ -0,0 +1,626 @@
+---
+title: "github/spec-kit: 💫 Toolkit to help you get started with Spec-Driven Development"
+source: "https://github.com/github/spec-kit"
+author:
+ - "[[localden]]"
+published:
+created: 2026-01-21
+description: "💫 Toolkit to help you get started with Spec-Driven Development - github/spec-kit"
+tags:
+ - "clippings"
+ - "webclipper"
+---
+> [!info] Source
+> URL: https://github.com/github/spec-kit
+> Title: github/spec-kit: 💫 Toolkit to help you get started with Spec-Driven Development
+> Clipped:
+
+**[spec-kit](https://github.com/github/spec-kit)** Public
+
+💫 Toolkit to help you get started with Spec-Driven Development
+
+[MIT license](https://github.com/github/spec-kit/blob/main/LICENSE)
+
+[Code of conduct](https://github.com/github/spec-kit/blob/main/CODE_OF_CONDUCT.md)
+
+[Contributing](https://github.com/github/spec-kit/blob/main/CONTRIBUTING.md)
+
+[Security policy](https://github.com/github/spec-kit/blob/main/SECURITY.md)
+
+[63.9k stars](https://github.com/github/spec-kit/stargazers) [5.5k forks](https://github.com/github/spec-kit/forks) [443 watching](https://github.com/github/spec-kit/watchers) [Branches](https://github.com/github/spec-kit/branches) [Tags](https://github.com/github/spec-kit/tags) [Activity](https://github.com/github/spec-kit/activity) [Custom properties](https://github.com/github/spec-kit/custom-properties)
+
+Public repository
+
+[Open in github.dev](https://github.dev/) [Open in a new github.dev tab](https://github.dev/) [Open in codespace](https://github.com/codespaces/new/github/spec-kit?resume=1)
+
+
+
+[](https://github.com/github/spec-kit/blob/main/media/logo_large.webp)
+
+**An open source toolkit that allows you to focus on product scenarios and predictable outcomes instead of vibe coding every piece from scratch.**
+
+---
+
+- [🤔 What is Spec-Driven Development?](https://github.com/github/#-what-is-spec-driven-development)
+- [⚡ Get Started](https://github.com/github/#-get-started)
+- [📽️ Video Overview](https://github.com/github/#%EF%B8%8F-video-overview)
+- [🤖 Supported AI Agents](https://github.com/github/#-supported-ai-agents)
+- [🔧 Specify CLI Reference](https://github.com/github/#-specify-cli-reference)
+- [📚 Core Philosophy](https://github.com/github/#-core-philosophy)
+- [🌟 Development Phases](https://github.com/github/#-development-phases)
+- [🎯 Experimental Goals](https://github.com/github/#-experimental-goals)
+- [🔧 Prerequisites](https://github.com/github/#-prerequisites)
+- [📖 Learn More](https://github.com/github/#-learn-more)
+- [📋 Detailed Process](https://github.com/github/#-detailed-process)
+- [🔍 Troubleshooting](https://github.com/github/#-troubleshooting)
+- [👥 Maintainers](https://github.com/github/#-maintainers)
+- [💬 Support](https://github.com/github/#-support)
+- [🙏 Acknowledgements](https://github.com/github/#-acknowledgements)
+- [📄 License](https://github.com/github/#-license)
+
+Spec-Driven Development **flips the script** on traditional software development. For decades, code has been king — specifications were just scaffolding we built and discarded once the "real work" of coding began. Spec-Driven Development changes this: **specifications become executable**, directly generating working implementations rather than just guiding them.
+
+Choose your preferred installation method:
+
+Install once and use everywhere:
+
+```
+uv tool install specify-cli --from git+https://github.com/github/spec-kit.git
+```
+
+Then use the tool directly:
+
+```
+# Create new project
+specify init
+
+# Or initialize in existing project
+specify init . --ai claude
+# or
+specify init --here --ai claude
+
+# Check installed tools
+specify check
+```
+
+To upgrade Specify, see the [Upgrade Guide](https://github.com/github/spec-kit/blob/main/docs/upgrade.md) for detailed instructions. Quick upgrade:
+
+```
+uv tool install specify-cli --force --from git+https://github.com/github/spec-kit.git
+```
+
+Run directly without installing:
+
+```
+uvx --from git+https://github.com/github/spec-kit.git specify init
+```
+
+**Benefits of persistent installation:**
+
+- Tool stays installed and available in PATH
+- No need to create shell aliases
+- Better tool management with `uv tool list`, `uv tool upgrade`, `uv tool uninstall`
+- Cleaner shell configuration
+
+Launch your AI assistant in the project directory. The `/speckit.*` commands are available in the assistant.
+
+Use the **`/speckit.constitution`** command to create your project's governing principles and development guidelines that will guide all subsequent development.
+
+```
+/speckit.constitution Create principles focused on code quality, testing standards, user experience consistency, and performance requirements
+```
+
+Use the **`/speckit.specify`** command to describe what you want to build. Focus on the **what** and **why**, not the tech stack.
+
+```
+/speckit.specify Build an application that can help me organize my photos in separate photo albums. Albums are grouped by date and can be re-organized by dragging and dropping on the main page. Albums are never in other nested albums. Within each album, photos are previewed in a tile-like interface.
+```
+
+Use the **`/speckit.plan`** command to provide your tech stack and architecture choices.
+
+```
+/speckit.plan The application uses Vite with minimal number of libraries. Use vanilla HTML, CSS, and JavaScript as much as possible. Images are not uploaded anywhere and metadata is stored in a local SQLite database.
+```
+
+Use **`/speckit.tasks`** to create an actionable task list from your implementation plan.
+
+```
+/speckit.tasks
+```
+
+Use **`/speckit.implement`** to execute all tasks and build your feature according to the plan.
+
+```
+/speckit.implement
+```
+
+For detailed step-by-step instructions, see our [comprehensive guide](https://github.com/github/spec-kit/blob/main/spec-driven.md).
+
+Want to see Spec Kit in action? Watch our [video overview](https://www.youtube.com/watch?v=a9eR1xsfvHg&pp=0gcJCckJAYcqIYzv)!
+
+[](https://www.youtube.com/watch?v=a9eR1xsfvHg&pp=0gcJCckJAYcqIYzv)
+
+| Agent | Support | Notes |
+| --- | --- | --- |
+| [Qoder CLI](https://qoder.com/cli) | ✅ | |
+| [Amazon Q Developer CLI](https://aws.amazon.com/developer/learning/q-developer-cli/) | ⚠️ | Amazon Q Developer CLI [does not support](https://github.com/aws/amazon-q-developer-cli/issues/3064) custom arguments for slash commands. |
+| [Amp](https://ampcode.com/) | ✅ | |
+| [Auggie CLI](https://docs.augmentcode.com/cli/overview) | ✅ | |
+| [Claude Code](https://www.anthropic.com/claude-code) | ✅ | |
+| [CodeBuddy CLI](https://www.codebuddy.ai/cli) | ✅ | |
+| [Codex CLI](https://github.com/openai/codex) | ✅ | |
+| [Cursor](https://cursor.sh/) | ✅ | |
+| [Gemini CLI](https://github.com/google-gemini/gemini-cli) | ✅ | |
+| [GitHub Copilot](https://code.visualstudio.com/) | ✅ | |
+| [IBM Bob](https://www.ibm.com/products/bob) | ✅ | IDE-based agent with slash command support |
+| [Jules](https://jules.google.com/) | ✅ | |
+| [Kilo Code](https://github.com/Kilo-Org/kilocode) | ✅ | |
+| [opencode](https://opencode.ai/) | ✅ | |
+| [Qwen Code](https://github.com/QwenLM/qwen-code) | ✅ | |
+| [Roo Code](https://roocode.com/) | ✅ | |
+| [SHAI (OVHcloud)](https://github.com/ovh/shai) | ✅ | |
+| [Windsurf](https://windsurf.com/) | ✅ | |
+
+The `specify` command supports the following options:
+
+### Commands
+
+| Command | Description |
+| --- | --- |
+| `init` | Initialize a new Specify project from the latest template |
+| `check` | Check for installed tools (`git`, `claude`, `gemini`, `code` / `code-insiders`, `cursor-agent`, `windsurf`, `qwen`, `opencode`, `codex`, `shai`, `qoder`) |
+
+| Argument/Option | Type | Description |
+| --- | --- | --- |
+| `` | Argument | Name for your new project directory (optional if using `--here`, or use `.` for current directory) |
+| `--ai` | Option | AI assistant to use: `claude`, `gemini`, `copilot`, `cursor-agent`, `qwen`, `opencode`, `codex`, `windsurf`, `kilocode`, `auggie`, `roo`, `codebuddy`, `amp`, `shai`, `q`, `bob`, or `qoder` |
+| `--script` | Option | Script variant to use: `sh` (bash/zsh) or `ps` (PowerShell) |
+| `--ignore-agent-tools` | Flag | Skip checks for AI agent tools like Claude Code |
+| `--no-git` | Flag | Skip git repository initialization |
+| `--here` | Flag | Initialize project in the current directory instead of creating a new one |
+| `--force` | Flag | Force merge/overwrite when initializing in current directory (skip confirmation) |
+| `--skip-tls` | Flag | Skip SSL/TLS verification (not recommended) |
+| `--debug` | Flag | Enable detailed debug output for troubleshooting |
+| `--github-token` | Option | GitHub token for API requests (or set GH\_TOKEN/GITHUB\_TOKEN env variable) |
+
+### Examples
+
+```
+# Basic project initialization
+specify init my-project
+
+# Initialize with specific AI assistant
+specify init my-project --ai claude
+
+# Initialize with Cursor support
+specify init my-project --ai cursor-agent
+
+# Initialize with Qoder support
+specify init my-project --ai qoder
+
+# Initialize with Windsurf support
+specify init my-project --ai windsurf
+
+# Initialize with Amp support
+specify init my-project --ai amp
+
+# Initialize with SHAI support
+specify init my-project --ai shai
+
+# Initialize with IBM Bob support
+specify init my-project --ai bob
+
+# Initialize with PowerShell scripts (Windows/cross-platform)
+specify init my-project --ai copilot --script ps
+
+# Initialize in current directory
+specify init . --ai copilot
+# or use the --here flag
+specify init --here --ai copilot
+
+# Force merge into current (non-empty) directory without confirmation
+specify init . --force --ai copilot
+# or
+specify init --here --force --ai copilot
+
+# Skip git initialization
+specify init my-project --ai gemini --no-git
+
+# Enable debug output for troubleshooting
+specify init my-project --ai claude --debug
+
+# Use GitHub token for API requests (helpful for corporate environments)
+specify init my-project --ai claude --github-token ghp_your_token_here
+
+# Check system requirements
+specify check
+```
+
+After running `specify init`, your AI coding agent will have access to these slash commands for structured development:
+
+#### Core Commands
+
+Essential commands for the Spec-Driven Development workflow:
+
+| Command | Description |
+| --- | --- |
+| `/speckit.constitution` | Create or update project governing principles and development guidelines |
+| `/speckit.specify` | Define what you want to build (requirements and user stories) |
+| `/speckit.plan` | Create technical implementation plans with your chosen tech stack |
+| `/speckit.tasks` | Generate actionable task lists for implementation |
+| `/speckit.implement` | Execute all tasks to build the feature according to the plan |
+
+#### Optional Commands
+
+Additional commands for enhanced quality and validation:
+
+| Command | Description |
+| --- | --- |
+| `/speckit.clarify` | Clarify underspecified areas (recommended before `/speckit.plan`; formerly `/quizme`) |
+| `/speckit.analyze` | Cross-artifact consistency & coverage analysis (run after `/speckit.tasks`, before `/speckit.implement`) |
+| `/speckit.checklist` | Generate custom quality checklists that validate requirements completeness, clarity, and consistency (like "unit tests for English") |
+
+### Environment Variables
+
+| Variable | Description |
+| --- | --- |
+| `SPECIFY_FEATURE` | Override feature detection for non-Git repositories. Set to the feature directory name (e.g., `001-photo-albums`) to work on a specific feature when not using Git branches. \*\*Must be set in the context of the agent you're working with prior to using `/speckit.plan` or follow-up commands. |
+
+Spec-Driven Development is a structured process that emphasizes:
+
+- **Intent-driven development** where specifications define the " *what* " before the " *how* "
+- **Rich specification creation** using guardrails and organizational principles
+- **Multi-step refinement** rather than one-shot code generation from prompts
+- **Heavy reliance** on advanced AI model capabilities for specification interpretation
+
+| Phase | Focus | Key Activities |
+| --- | --- | --- |
+| **0-to-1 Development** ("Greenfield") | Generate from scratch | - Start with high-level requirements - Generate specifications - Plan implementation steps - Build production-ready applications |
+| **Creative Exploration** | Parallel implementations | - Explore diverse solutions - Support multiple technology stacks & architectures - Experiment with UX patterns |
+| **Iterative Enhancement** ("Brownfield") | Brownfield modernization | - Add features iteratively - Modernize legacy systems - Adapt processes |
+
+Our research and experimentation focus on:
+
+### Technology independence
+
+- Create applications using diverse technology stacks
+- Validate the hypothesis that Spec-Driven Development is a process not tied to specific technologies, programming languages, or frameworks
+
+### Enterprise constraints
+
+- Demonstrate mission-critical application development
+- Incorporate organizational constraints (cloud providers, tech stacks, engineering practices)
+- Support enterprise design systems and compliance requirements
+
+### User-centric development
+
+- Build applications for different user cohorts and preferences
+- Support various development approaches (from vibe-coding to AI-native development)
+- Validate the concept of parallel implementation exploration
+- Provide robust iterative feature development workflows
+- Extend processes to handle upgrades and modernization tasks
+
+## 🔧 Prerequisites
+
+- **Linux/macOS/Windows**
+- [Supported](https://github.com/github/#-supported-ai-agents) AI coding agent.
+- [uv](https://docs.astral.sh/uv/) for package management
+- [Python 3.11+](https://www.python.org/downloads/)
+- [Git](https://git-scm.com/downloads)
+
+If you encounter issues with an agent, please open an issue so we can refine the integration.
+
+- **[Complete Spec-Driven Development Methodology](https://github.com/github/spec-kit/blob/main/spec-driven.md)** - Deep dive into the full process
+- **[Detailed Walkthrough](https://github.com/github/#-detailed-process)** - Step-by-step implementation guide
+
+---
+
+Click to expand the detailed step-by-step walkthrough
+
+You can use the Specify CLI to bootstrap your project, which will bring in the required artifacts in your environment. Run:
+
+```
+specify init
+```
+
+Or initialize in the current directory:
+
+```
+specify init .
+# or use the --here flag
+specify init --here
+# Skip confirmation when the directory already has files
+specify init . --force
+# or
+specify init --here --force
+```
+
+[](https://github.com/github/spec-kit/blob/main/media/specify_cli.gif)
+
+You will be prompted to select the AI agent you are using. You can also proactively specify it directly in the terminal:
+
+```
+specify init --ai claude
+specify init --ai gemini
+specify init --ai copilot
+
+# Or in current directory:
+specify init . --ai claude
+specify init . --ai codex
+
+# or use --here flag
+specify init --here --ai claude
+specify init --here --ai codex
+
+# Force merge into a non-empty current directory
+specify init . --force --ai claude
+
+# or
+specify init --here --force --ai claude
+```
+
+The CLI will check if you have Claude Code, Gemini CLI, Cursor CLI, Qwen CLI, opencode, Codex CLI, Qoder CLI, or Amazon Q Developer CLI installed. If you do not, or you prefer to get the templates without checking for the right tools, use `--ignore-agent-tools` with your command:
+
+```
+specify init --ai claude --ignore-agent-tools
+```
+
+Go to the project folder and run your AI agent. In our example, we're using `claude`.
+
+[](https://github.com/github/spec-kit/blob/main/media/bootstrap-claude-code.gif)
+
+You will know that things are configured correctly if you see the `/speckit.constitution`, `/speckit.specify`, `/speckit.plan`, `/speckit.tasks`, and `/speckit.implement` commands available.
+
+The first step should be establishing your project's governing principles using the `/speckit.constitution` command. This helps ensure consistent decision-making throughout all subsequent development phases:
+
+```
+/speckit.constitution Create principles focused on code quality, testing standards, user experience consistency, and performance requirements. Include governance for how these principles should guide technical decisions and implementation choices.
+```
+
+This step creates or updates the `.specify/memory/constitution.md` file with your project's foundational guidelines that the AI agent will reference during specification, planning, and implementation phases.
+
+With your project principles established, you can now create the functional specifications. Use the `/speckit.specify` command and then provide the concrete requirements for the project you want to develop.
+
+> \[!IMPORTANT\] Be as explicit as possible about *what* you are trying to build and *why*. **Do not focus on the tech stack at this point**.
+
+An example prompt:
+
+```
+Develop Taskify, a team productivity platform. It should allow users to create projects, add team members,
+assign tasks, comment and move tasks between boards in Kanban style. In this initial phase for this feature,
+let's call it "Create Taskify," let's have multiple users but the users will be declared ahead of time, predefined.
+I want five users in two different categories, one product manager and four engineers. Let's create three
+different sample projects. Let's have the standard Kanban columns for the status of each task, such as "To Do,"
+"In Progress," "In Review," and "Done." There will be no login for this application as this is just the very
+first testing thing to ensure that our basic features are set up. For each task in the UI for a task card,
+you should be able to change the current status of the task between the different columns in the Kanban work board.
+You should be able to leave an unlimited number of comments for a particular card. You should be able to, from that task
+card, assign one of the valid users. When you first launch Taskify, it's going to give you a list of the five users to pick
+from. There will be no password required. When you click on a user, you go into the main view, which displays the list of
+projects. When you click on a project, you open the Kanban board for that project. You're going to see the columns.
+You'll be able to drag and drop cards back and forth between different columns. You will see any cards that are
+assigned to you, the currently logged in user, in a different color from all the other ones, so you can quickly
+see yours. You can edit any comments that you make, but you can't edit comments that other people made. You can
+delete any comments that you made, but you can't delete comments anybody else made.
+```
+
+After this prompt is entered, you should see Claude Code kick off the planning and spec drafting process. Claude Code will also trigger some of the built-in scripts to set up the repository.
+
+Once this step is completed, you should have a new branch created (e.g., `001-create-taskify`), as well as a new specification in the `specs/001-create-taskify` directory.
+
+The produced specification should contain a set of user stories and functional requirements, as defined in the template.
+
+At this stage, your project folder contents should resemble the following:
+
+```
+└── .specify
+ ├── memory
+ │ └── constitution.md
+ ├── scripts
+ │ ├── check-prerequisites.sh
+ │ ├── common.sh
+ │ ├── create-new-feature.sh
+ │ ├── setup-plan.sh
+ │ └── update-claude-md.sh
+ ├── specs
+ │ └── 001-create-taskify
+ │ └── spec.md
+ └── templates
+ ├── plan-template.md
+ ├── spec-template.md
+ └── tasks-template.md
+```
+
+With the baseline specification created, you can go ahead and clarify any of the requirements that were not captured properly within the first shot attempt.
+
+You should run the structured clarification workflow **before** creating a technical plan to reduce rework downstream.
+
+Preferred order:
+
+1. Use `/speckit.clarify` (structured) – sequential, coverage-based questioning that records answers in a Clarifications section.
+2. Optionally follow up with ad-hoc free-form refinement if something still feels vague.
+
+If you intentionally want to skip clarification (e.g., spike or exploratory prototype), explicitly state that so the agent doesn't block on missing clarifications.
+
+Example free-form refinement prompt (after `/speckit.clarify` if still needed):
+
+```
+For each sample project or project that you create there should be a variable number of tasks between 5 and 15
+tasks for each one randomly distributed into different states of completion. Make sure that there's at least
+one task in each stage of completion.
+```
+
+You should also ask Claude Code to validate the **Review & Acceptance Checklist**, checking off the things that are validated/pass the requirements, and leave the ones that are not unchecked. The following prompt can be used:
+
+```
+Read the review and acceptance checklist, and check off each item in the checklist if the feature spec meets the criteria. Leave it empty if it does not.
+```
+
+It's important to use the interaction with Claude Code as an opportunity to clarify and ask questions around the specification - **do not treat its first attempt as final**.
+
+You can now be specific about the tech stack and other technical requirements. You can use the `/speckit.plan` command that is built into the project template with a prompt like this:
+
+```
+We are going to generate this using .NET Aspire, using Postgres as the database. The frontend should use
+Blazor server with drag-and-drop task boards, real-time updates. There should be a REST API created with a projects API,
+tasks API, and a notifications API.
+```
+
+The output of this step will include a number of implementation detail documents, with your directory tree resembling this:
+
+```
+.
+├── CLAUDE.md
+├── memory
+│ └── constitution.md
+├── scripts
+│ ├── check-prerequisites.sh
+│ ├── common.sh
+│ ├── create-new-feature.sh
+│ ├── setup-plan.sh
+│ └── update-claude-md.sh
+├── specs
+│ └── 001-create-taskify
+│ ├── contracts
+│ │ ├── api-spec.json
+│ │ └── signalr-spec.md
+│ ├── data-model.md
+│ ├── plan.md
+│ ├── quickstart.md
+│ ├── research.md
+│ └── spec.md
+└── templates
+ ├── CLAUDE-template.md
+ ├── plan-template.md
+ ├── spec-template.md
+ └── tasks-template.md
+```
+
+Check the `research.md` document to ensure that the right tech stack is used, based on your instructions. You can ask Claude Code to refine it if any of the components stand out, or even have it check the locally-installed version of the platform/framework you want to use (e.g.,.NET).
+
+Additionally, you might want to ask Claude Code to research details about the chosen tech stack if it's something that is rapidly changing (e.g.,.NET Aspire, JS frameworks), with a prompt like this:
+
+```
+I want you to go through the implementation plan and implementation details, looking for areas that could
+benefit from additional research as .NET Aspire is a rapidly changing library. For those areas that you identify that
+require further research, I want you to update the research document with additional details about the specific
+versions that we are going to be using in this Taskify application and spawn parallel research tasks to clarify
+any details using research from the web.
+```
+
+During this process, you might find that Claude Code gets stuck researching the wrong thing - you can help nudge it in the right direction with a prompt like this:
+
+```
+I think we need to break this down into a series of steps. First, identify a list of tasks
+that you would need to do during implementation that you're not sure of or would benefit
+from further research. Write down a list of those tasks. And then for each one of these tasks,
+I want you to spin up a separate research task so that the net results is we are researching
+all of those very specific tasks in parallel. What I saw you doing was it looks like you were
+researching .NET Aspire in general and I don't think that's gonna do much for us in this case.
+That's way too untargeted research. The research needs to help you solve a specific targeted question.
+```
+
+> \[!NOTE\] Claude Code might be over-eager and add components that you did not ask for. Ask it to clarify the rationale and the source of the change.
+
+With the plan in place, you should have Claude Code run through it to make sure that there are no missing pieces. You can use a prompt like this:
+
+```
+Now I want you to go and audit the implementation plan and the implementation detail files.
+Read through it with an eye on determining whether or not there is a sequence of tasks that you need
+to be doing that are obvious from reading this. Because I don't know if there's enough here. For example,
+when I look at the core implementation, it would be useful to reference the appropriate places in the implementation
+details where it can find the information as it walks through each step in the core implementation or in the refinement.
+```
+
+This helps refine the implementation plan and helps you avoid potential blind spots that Claude Code missed in its planning cycle. Once the initial refinement pass is complete, ask Claude Code to go through the checklist once more before you can get to the implementation.
+
+You can also ask Claude Code (if you have the [GitHub CLI](https://docs.github.com/en/github-cli/github-cli) installed) to go ahead and create a pull request from your current branch to `main` with a detailed description, to make sure that the effort is properly tracked.
+
+> \[!NOTE\] Before you have the agent implement it, it's also worth prompting Claude Code to cross-check the details to see if there are any over-engineered pieces (remember - it can be over-eager). If over-engineered components or decisions exist, you can ask Claude Code to resolve them. Ensure that Claude Code follows the [constitution](https://github.com/github/spec-kit/blob/main/base/memory/constitution.md) as the foundational piece that it must adhere to when establishing the plan.
+
+With the implementation plan validated, you can now break down the plan into specific, actionable tasks that can be executed in the correct order. Use the `/speckit.tasks` command to automatically generate a detailed task breakdown from your implementation plan:
+
+```
+/speckit.tasks
+```
+
+This step creates a `tasks.md` file in your feature specification directory that contains:
+
+- **Task breakdown organized by user story** - Each user story becomes a separate implementation phase with its own set of tasks
+- **Dependency management** - Tasks are ordered to respect dependencies between components (e.g., models before services, services before endpoints)
+- **Parallel execution markers** - Tasks that can run in parallel are marked with `[P]` to optimize development workflow
+- **File path specifications** - Each task includes the exact file paths where implementation should occur
+- **Test-driven development structure** - If tests are requested, test tasks are included and ordered to be written before implementation
+- **Checkpoint validation** - Each user story phase includes checkpoints to validate independent functionality
+
+The generated tasks.md provides a clear roadmap for the `/speckit.implement` command, ensuring systematic implementation that maintains code quality and allows for incremental delivery of user stories.
+
+Once ready, use the `/speckit.implement` command to execute your implementation plan:
+
+```
+/speckit.implement
+```
+
+The `/speckit.implement` command will:
+
+- Validate that all prerequisites are in place (constitution, spec, plan, and tasks)
+- Parse the task breakdown from `tasks.md`
+- Execute tasks in the correct order, respecting dependencies and parallel execution markers
+- Follow the TDD approach defined in your task plan
+- Provide progress updates and handle errors appropriately
+
+> \[!IMPORTANT\] The AI agent will execute local CLI commands (such as `dotnet`, `npm`, etc.) - make sure you have the required tools installed on your machine.
+
+Once the implementation is complete, test the application and resolve any runtime errors that may not be visible in CLI logs (e.g., browser console errors). You can copy and paste such errors back to your AI agent for resolution.
+
+---
+
+## 🔍 Troubleshooting
+
+If you're having issues with Git authentication on Linux, you can install Git Credential Manager:
+
+```
+#!/usr/bin/env bash
+set -e
+echo "Downloading Git Credential Manager v2.6.1..."
+wget https://github.com/git-ecosystem/git-credential-manager/releases/download/v2.6.1/gcm-linux_amd64.2.6.1.deb
+echo "Installing Git Credential Manager..."
+sudo dpkg -i gcm-linux_amd64.2.6.1.deb
+echo "Configuring Git to use GCM..."
+git config --global credential.helper manager
+echo "Cleaning up..."
+rm gcm-linux_amd64.2.6.1.deb
+```
+
+## 👥 Maintainers
+
+- Den Delimarsky ([@localden](https://github.com/localden))
+- John Lam ([@jflam](https://github.com/jflam))
+
+## 💬 Support
+
+For support, please open a [GitHub issue](https://github.com/github/spec-kit/issues/new). We welcome bug reports, feature requests, and questions about using Spec-Driven Development.
+
+## 🙏 Acknowledgements
+
+This project is heavily influenced by and based on the work and research of [John Lam](https://github.com/jflam).
+
+## 📄 License
+
+This project is licensed under the terms of the MIT open source license. Please refer to the [LICENSE](https://github.com/github/spec-kit/blob/main/LICENSE) file for the full terms.
+
+## Releases 90
+
+[\+ 89 releases](https://github.com/github/spec-kit/releases)
+
+## Deployments 14
+
+- [github-pages](https://github.com/github/spec-kit/deployments/github-pages)
+
+[\+ 13 deployments](https://github.com/github/spec-kit/deployments)
+
+## Languages
+
+- [Python 37.5%](https://github.com/github/spec-kit/search?l=python)
+- [Shell 34.9%](https://github.com/github/spec-kit/search?l=shell)
+- [PowerShell 27.6%](https://github.com/github/spec-kit/search?l=powershell)
\ No newline at end of file
diff --git a/03_Resources/Development/AI-ML/Nvidia-config.md b/03_Resources/Development/AI-ML/Nvidia-config.md
new file mode 100644
index 0000000..4837ee0
--- /dev/null
+++ b/03_Resources/Development/AI-ML/Nvidia-config.md
@@ -0,0 +1,24 @@
+
+api key:
+```
+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
+```
+
+
+use glm 4.7
+```bash
+export ANTHROPIC_BASE_URL=http://localhost:3001
+export ANTHROPIC_AUTH_TOKEN=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
+export ANTHROPIC_DEFAULT_HAIKU_MODEL=z-ai/glm4.7
+export ANTHROPIC_DEFAULT_SONNET_MODEL=z-ai/glm4.7
+export ANTHROPIC_DEFAULT_OPUS_MODEL=z-ai/glm4.7
+```
+
+
+```
+unset ANTHROPIC_BASE_URL
+unset ANTHROPIC_AUTH_TOKEN
+unset ANTHROPIC_DEFAULT_HAIKU_MODEL
+unset ANTHROPIC_DEFAULT_SONNET_MODEL
+unset ANTHROPIC_DEFAULT_OPUS_MODE
+```