vault backup: 2026-01-05 13:03:55
This commit is contained in:
 windyboy
@@ -0,0 +1,541 @@
|
||||
---
|
||||
page-title: "AFTN和SITA报文简介-CSDN博客"
|
||||
url: https://blog.csdn.net/qq_35318838/article/details/88950025
|
||||
date: "2024-07-16 10:30:51"
|
||||
---
|
||||
飞行动态固定格式电报分为:**AFTN**和**SITA**两种格式的电报。
|
||||
**AFTN格式电报**:供空中交通管制部门使用
|
||||
**SITA格式电报**:供航空公司航务部门使用,
|
||||
两种格式不能混合使用
|
||||
|
||||
### 1.AFTN报文
|
||||
|
||||
AFTN全称为民用航空飞行动态固定电报格式,具体格式如下:
|
||||
|
||||
- (1)第一行:电报种类
|
||||
- (2)第二行:使用时间(UTC时间)
|
||||
- (3)第三行:电报级别
|
||||
|
||||
|
||||
下面分别对以上**格式内容做说明**:
|
||||
电报种类说明:用三个字母表示电报类代号,具体说明如下:
|
||||
|
||||
|
||||
| 电报类代号 | 种类说明 |
|
||||
| ------ | ------------- |
|
||||
| PLN | 飞行预报 |
|
||||
| COR | 修订飞行预报 |
|
||||
| ABS | 取消重复与非重复性飞行预报 |
|
||||
| FPL | 领航计划报 |
|
||||
| CHG | 修定领航计划报 |
|
||||
| CNL | 取消领航计划报 |
|
||||
| DEP | 起飞报 |
|
||||
| ARR | 落地报 |
|
||||
| DAL | 延误报 |
|
||||
| RTN | 返航报 |
|
||||
| ALN | 备降报 |
|
||||
| CPL | 现行飞行变更报 |
|
||||
| EST | 预计飞越报 |
|
||||
| CDN | 管制协调报 |
|
||||
| ACP | 管制协调接受报 |
|
||||
| LAM | 逻辑确认报 |
|
||||
| RQP | 请求飞行计划报 |
|
||||
| RQS | 请求领航计划补充信息报 |
|
||||
| SPL | 令航计划补充信息报 |
|
||||
| ALR | 告警报 |
|
||||
| RCF | 无线电通信失效报 |
|
||||
| ovlfly | 飞跃报 |
|
||||
|
||||
|
||||
电报级别说明:
|
||||
|
||||
- (1)SS:第一等级,遇险报。
|
||||
- (2)DD:第二等级,特级报。
|
||||
- (3)FF:第三等级,加急报。(常用)
|
||||
- (4)GG:第四等级,急报。(常用)
|
||||
|
||||
|
||||
|
||||
|
||||
电报代码中的**特别编组号说明**如下:
|
||||
|
||||
|
||||
|
||||
| 编组号 | 数据类型 |
|
||||
| --- | ------------------ |
|
||||
| 3 | 电报类别、编号和参考数据 |
|
||||
| 5 | 紧急情况说明 |
|
||||
| 7 | 航空器识别标志和SS模式及编码 |
|
||||
| 8 | 飞行规则及种类 |
|
||||
| 9 | 航空器数目、机型和尾流等级 |
|
||||
| 10 | 机载设备 |
|
||||
| 13 | 超飞机场和时间 |
|
||||
| 14 | 预计飞跃边界数据 |
|
||||
| 15 | 航路 |
|
||||
| 16 | 目的地机场的预计飞行总时间,备降机场 |
|
||||
| 17 | 落地机场和时间 |
|
||||
| 18 | 其他情报 |
|
||||
| 19 | 补充情报 |
|
||||
| 20 | 搜寻和救援告警情报 |
|
||||
| 21 | 无线电失效情报 |
|
||||
| 22 | 修订 |
|
||||
|
||||
|
||||
下面举几个例子说说各AFTN电报的内容:
|
||||
|
||||
#### 1\. PLN 飞行预报
|
||||
|
||||
```
|
||||
(PLN(3)-0301
|
||||
-CSH9101(7)-IS(8)-B752/M(9)
|
||||
-ZSSS0015(13)-ZBAA0150 ZBTJ (16)
|
||||
-K0800S1080 PIKAS G330 A593 VYK(15)
|
||||
-STS/VIP(18) )
|
||||
```
|
||||
|
||||
有关PLN注意事项:飞行计划实施前一天的0800前(世界协调时),根据规定要求由相关的**空中交通服务**单位拍发的非重复性飞行计划电报
|
||||
|
||||
对于**修订飞行预报 COR(correction message)**,是用于修订飞行预报有关内容的电报,代码如下:
|
||||
|
||||
```
|
||||
(COR-0301-CSH9101-ZSSS0015-9/B737)
|
||||
```
|
||||
|
||||
对于**取消重复与非重复性飞行预报 ABS( abolishmessage )**,是用于取消某日飞行计划电报,代码如下:
|
||||
|
||||
```
|
||||
(ABS-0301-CSH9101-ZSSS0015)
|
||||
```
|
||||
|
||||
#### 2.领航计划报 FPL( filed flight plan message)
|
||||
|
||||
```
|
||||
(FPL-CSH9101-IS
|
||||
-B752/M-SDIH/C
|
||||
-ZSSS0015
|
||||
-K0800S1080 PIKAS G330 PIMOL A593 VYK
|
||||
-ZBAA0150 ZBTJ
|
||||
-EET/ZBPE0110 REG/B2843 SEL/FRDH RMK/ACAS)
|
||||
```
|
||||
|
||||
**领航计划报 FPL( filed flight plan message)**,由空中交通服务单位在航空器预计撤轮档时间前45min(不应早于预计撤轮档时间6h),拍发给沿航路有关空中交通服务单位的电报。
|
||||
|
||||
对于**修订领航计划报 CHG( modification message)**,是用于修订领航计划中有关内容的电报,代码如下:
|
||||
|
||||
```
|
||||
(CHG-CSH9101-ZSSS0015-ZBAA0150-XXXX)
|
||||
```
|
||||
|
||||
对于**取消领航计划报 CNL(flight plan cancellation message)**,是当领航计划已发出后,需要取消时,用于取消该航空器领航计划的电报,代码如下:
|
||||
|
||||
```
|
||||
(CNL-CSH9101-ZSSS0015-ZBAA0150)
|
||||
```
|
||||
|
||||
#### 3\. 起飞报 DEP ( departure message)
|
||||
|
||||
航空器起飞后,用于通报起飞时间的电报。
|
||||
|
||||
```
|
||||
(DEP-CSH9101/A3031-ZSSS0020-ZBAA)
|
||||
```
|
||||
|
||||
#### 4\. 落地报 ARR(arrival message)
|
||||
|
||||
航空器落地后,用于通报落地时间的电报。
|
||||
|
||||
```
|
||||
(ARR-CSH9101-ZSSS-ZBAA0210)
|
||||
```
|
||||
|
||||
#### 5\. 延误报 DLA( delay message)
|
||||
|
||||
当航空器预计起飞时间比原领航计划中的预计撤轮档时间推迟超过30min时,用于向各有关单位通报其延误信息的电报。
|
||||
|
||||
```
|
||||
(DLA-CSH9101-ZSSS0100-ZBAA)
|
||||
```
|
||||
|
||||
#### 6\. 返航报 RTN(return message)
|
||||
|
||||
用于向有关单位通报航空器返航信息的电报。
|
||||
|
||||
```
|
||||
(RTN-CSH9102-ZBAA-PSN/0148S0960-ZSSS-RMK/WX)
|
||||
```
|
||||
|
||||
表示:CCA1501航班从北京机场起飞,原目的地机场为上海机场,现因天气原因返航北京机场,预计PSN0148,高度9600m
|
||||
|
||||
#### 7\. 备降报 ALN(alternate message)
|
||||
|
||||
用于向有关单位通报航空器备降信息的电报
|
||||
|
||||
```
|
||||
(ALN-CSH9102-ZBAA-EPN/0145S0960-N0450S0960 A593 VYK A326-ZYTL-RMK/WX)
|
||||
```
|
||||
|
||||
表示:CCA1501航班从北京机场起飞后因天气原因将备降大连机场,预计飞越EPN0145,高度9600m。速度450kn,经A593航路,在VYK转向A326航路。
|
||||
|
||||
#### 8.其它电报
|
||||
|
||||
```
|
||||
告警报 ALR(alerting message)
|
||||
|
||||
无线电通信失效报 RCF(radio communication failure message)
|
||||
|
||||
预计飞越报 EST(estimate message)
|
||||
|
||||
飞跃报:(OVFLY-CCA976/A2230-WSSS-BEKOL/1944-ZBAA)
|
||||
```
|
||||
|
||||
#### FPL 和 RPL
|
||||
|
||||
下面详细介绍**领航计划报FPL**(FLIGHTPLAN)和**RPL**(REPETITIVE FPL)的编组内容
|
||||
|
||||
**FPL构成:**
|
||||
|
||||
编组3-7-8-9-10-13-15-16-18-19
|
||||
|
||||
##### 1\. 编组8:飞行规则及种类
|
||||
|
||||
飞行规则
|
||||
|
||||
一个字母表示如下:
|
||||
|
||||
I 表示仪表飞行规则
|
||||
|
||||
V 表示目视飞行规则
|
||||
|
||||
Y 表示先仪表飞行规则
|
||||
|
||||
Z 表示先目视飞行规则
|
||||
|
||||
S 表示定期的航空运输飞行
|
||||
|
||||
N 表示非定期的航空运输飞行 包括:旅客包机飞行、货包机飞行。
|
||||
|
||||
E 表示急救飞行
|
||||
|
||||
B 表示专机飞行
|
||||
|
||||
G 表示通用航空飞行 包括:播种飞行、公务飞行、人工降雨飞行、护林飞行、农化飞行、物理控矿飞行等
|
||||
|
||||
J 表示加班飞行
|
||||
|
||||
M 表示军用运输飞行
|
||||
|
||||
Q 表示补班飞行
|
||||
|
||||
X 表示其他飞行 包括:熟练飞行、校验飞行、训练飞行、调机飞行、试飞飞行等
|
||||
|
||||
##### 2\. 编组9航空器数目、机型和尾流等级
|
||||
|
||||
航空器架数(如多于一架)此单项仅用于编队飞行中,用2位数字来表示航空器架数。
|
||||
|
||||
航空器机型 用2~4个字符,按国际民航组织文件8643号《航空器机型代码》规定填写,如无指定的代号或在飞行中有多种机型,填定“ZZZZ”。如使用字母ZZZZ,航空器机型应填写“其他情报”编组(见编组18)。(GLF4)
|
||||
|
||||
尾流等级: 一个字母表示航空器的最大允许起飞重量;
|
||||
|
||||
H 重型(大于等于136t) `A343 B762 B763 B772 B742 B744`
|
||||
|
||||
M中型(大于7t小于136t) `A319 A320 B733 B736 B737 B738 B752GLF4`
|
||||
|
||||
L轻型(小于等于7t)
|
||||
|
||||
##### 3.编组10机载设备
|
||||
|
||||
*无线电通信:AFTN/SITA报文详细说明
|
||||
监视设备:用一个或两个字母来说明所载监视设备;*
|
||||
|
||||
二次监视雷达设备
|
||||
|
||||
N 没有应答机
|
||||
|
||||
A A模式应答机(4位数――4096个编码)。
|
||||
|
||||
C A模式应答机(4位数――4096个编码)和C模式应答机。
|
||||
|
||||
X S模式应答机,没有航空器识别标志和气压高度发射信号。
|
||||
|
||||
P S模式应答机,具有气压高度发射信号,但没有航空器识别标声发射信号。
|
||||
|
||||
I S模式应答机,具有航空器识别标志和发射信号,但无气压高度发射信号。
|
||||
|
||||
S S模式应答机,具有气压高度和航空器识别标志的发射信号。
|
||||
|
||||
D 具有自动相关监视能力
|
||||
|
||||
##### 4.编组13 起飞机场和时间(略)
|
||||
|
||||
##### 5\. 编组15航路
|
||||
|
||||
n 巡航速度:巡航速度或马赫数,飞行中第一个或整个巡航航段的真空速,按下列方式表示;
|
||||
|
||||
K 后随4位数字,单位为“Km/h”表示真空速;
|
||||
|
||||
N 后随4位数字,单位为“Knots”表示真空速。
|
||||
|
||||
M 后随3位数字表示最近的1%马赫单位的马赫数
|
||||
|
||||
n 巡航高度:高度层数据有4种表示方法:
|
||||
|
||||
“F”后跟随3位数,表示以100ft为单位的飞行高度层。如飞行高度层33000ft以“F330”表示;
|
||||
|
||||
“S”后跟随4位数,表示以10m为单位的飞行高度层,如飞行高度层11400m以“S1140”表示;
|
||||
|
||||
“A”后跟随3位数,表示以100ft为单位的海拔高度。如海拔高度4500ft以“A045”表示;
|
||||
|
||||
“M”后跟随4位数,表示以10m为单位的海拔高度。如海拔高度8400m以“M0840”表示。
|
||||
|
||||
##### 6\. 编组16目的地机场和预计经过总时间,备降机场
|
||||
|
||||
##### 7\. 编组18其他情报
|
||||
|
||||
EET/ 由有关空中交通服务单位规定的重要点或飞行情报区边界累计的预计经过总时间。如:EET/ZBAA0204表示飞至北京情报区用时2小时04分
|
||||
|
||||
RIF/ 如果航空器返航或备降,此项填入新航路,后随目的地机场的四字代码,修改的航路应在飞行中重新申请。如:RIF/BTOA593 VYK ZBAA
|
||||
|
||||
REG/ 航空器的注册标志 SEL/ 选择呼叫编码
|
||||
|
||||
RMK/ 有关空中交通服务单位要求的或机长认为对提供空中交通服务有必要的任何明语附注
|
||||
|
||||
##### 8.编组19补充情报
|
||||
|
||||
本编组包括一连串可获得的补充情报,数据项间由空格分开:
|
||||
|
||||
E/ 后随4位数字,表示以小时及分钟计的续航能力。
|
||||
|
||||
P/ 当有关空中交通服务单位要求填写此项时,数字表示机上总人数
|
||||
|
||||
R/ 后随下述一个或多个字母,其间无空格:U 有特高频243.0MHz频率V 有特高频121.5MHz频率E 有紧急示位信标
|
||||
|
||||
S/ 后随下述一个或多个字母,其间无空格 P有极地救生设备D 有沙漠救生设备 M有海上救生设备 J有丛林救生设备
|
||||
|
||||
J/ 后随下述一个或多个字母,其间无空格:
|
||||
|
||||
L 救生衣配备有灯光
|
||||
|
||||
F 救生衣配备有荧光素
|
||||
|
||||
U 救生衣配备无线电特高频电台,使用243.0MHz频率
|
||||
|
||||
V 救生衣配备无线电甚高频电台,使用121.5MHz频率
|
||||
|
||||
D/ 后随下述一个或多个以下内容,其间用一个空格分开:
|
||||
|
||||
2位数字表示救生艇的数目
|
||||
|
||||
3位数表示所有救生艇可载总人数
|
||||
|
||||
C表示救生艇有篷子
|
||||
|
||||
用一个英文单词表示求救生艇的颜色(如RED表示红色)
|
||||
|
||||
A/ 后随下述一个或多个明语内容,其间用空格分开:
|
||||
|
||||
航空器的颜色, 重要标志(包括航空器注册标志)
|
||||
|
||||
N/ 后随明语,以示所载任何其他救生设备以及其他有用附注
|
||||
|
||||
C/ 后随机长姓名
|
||||
|
||||
### 2.SITA报文
|
||||
|
||||
SITA格式电报:航空公司使用的电报,类型有:
|
||||
|
||||
- (1)动态电报(MVT)
|
||||
|
||||
n 起飞报(AD)
|
||||
n 降落报(AA)
|
||||
n 延误报(DL)
|
||||
n 取消报(CNL)
|
||||
|
||||
- (2)飞行预报(PLN)
|
||||
|
||||
- (3)飞行放行电报(CLR)
|
||||
|
||||
|
||||
**n 电报规则**
|
||||
|
||||
- 日期:使用两位数字与英文三字代码连写作表示。例如:8月2日,应编为“02 AUG”。
|
||||
- 时间:使用国际时,四位数,24小时制;前两位为时,后两位为分 北京时14:30,应编为“0630”
|
||||
- 航空器注册号:在中国民航总局注册的航空器,在其注册号前应加注我国航空器无线电识别标志大写字母“B”,并在注册号中取消其中的短划“—”,如B—2448号飞机应编为B2448,若没有航空器注册号的飞机,可使用“ZZZZ”表示;其具体说明可编写在补充信息资料中。
|
||||
外国注册的航空器按有关国家规定的注册号填写
|
||||
|
||||
**n 电报等级和电报地址规定**
|
||||
|
||||
```
|
||||
QS:第一等级,遇险报
|
||||
QU:第四等级,急报
|
||||
Q*:第五等级,快报,*为除S、U、D以外的其他任何字母
|
||||
QD;第六等级,平报
|
||||
```
|
||||
|
||||
SITA电报收发地址由7个字母组成,前三个字母为地名,第4、5个字母为部门代码,后两个字母为公司代码。如:PEKUOCA。
|
||||
SITA电报中二、三等级(特急报、加急报)不使用。每份SITA电报收电地址最多为四行,可发32家地址
|
||||
|
||||
下面分别说一下**SITA报文的内容**:
|
||||
|
||||
#### 1\. 起飞报(AD)
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)动态报标志
|
||||
第二行:(航班信息)航班号/日期 航空器注册号 起飞机场
|
||||
第三行:(动态信息)起飞代码 撤轮档时间/离地时间
|
||||
第四行:(动态信息)预计降落代码 预计降落时间 降落机场、
|
||||
第五行:(补充信息)补充信息代码:补充信息资料
|
||||
```
|
||||
|
||||
例子:
|
||||
|
||||
```
|
||||
MVT
|
||||
FM801/01MAR B2570 PVG
|
||||
AD 0050/0110
|
||||
EA 0325MFM
|
||||
SI:PAX210
|
||||
```
|
||||
|
||||
#### 2\. 降落报(AA)
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)动态报标志
|
||||
第二行:(航班信息)航班号/日期 航空器注册号 降落机场
|
||||
第三行:(动态信息)降落代码 降落时间/挡轮档时间
|
||||
第四行:(补充信息)补充信息代码;补充信息资料
|
||||
```
|
||||
|
||||
例:
|
||||
|
||||
```
|
||||
MVT
|
||||
FM802/01MAR B2570 PVG
|
||||
AA 0600/0610
|
||||
SI:
|
||||
```
|
||||
|
||||
#### 3\. 延误报(DL、ED、NI)
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)动态报标志
|
||||
第二行:(航班信息)航班号/日期 航空器注册号 起飞机场
|
||||
第三行:(动态信息)起飞代码 撤轮档时间/离地时间
|
||||
(预计起飞代码 预计起飞时间)
|
||||
(长期延误代码 下次通告时间)
|
||||
第四行:(延误信息)延误代码 延误原因代码/延误时间
|
||||
(延误代码 延误原因)
|
||||
(延误代码 延误原因)
|
||||
第五行:(补充信息)补充信息代码;补充信息资料
|
||||
```
|
||||
|
||||
1. n 延误报(DL、ED、NI)实例
|
||||
|
||||
(1)
|
||||
|
||||
```
|
||||
MVT
|
||||
FM801/01MARB2570 PVG
|
||||
AD0110/0130
|
||||
DL PH/20 (IATA标准延误代码)
|
||||
SI:
|
||||
```
|
||||
|
||||
(2)
|
||||
|
||||
```
|
||||
MVT
|
||||
FM801/01.B2570.PVG
|
||||
ED0200
|
||||
DLWX
|
||||
SI:
|
||||
```
|
||||
|
||||
(3)
|
||||
|
||||
```
|
||||
MVT
|
||||
FM80101.B2570.PVG
|
||||
NI 0200
|
||||
DL ENGTRB
|
||||
SI:
|
||||
```
|
||||
|
||||
n DL 延误时间在30分钟以内的航班,应拍发起飞延误报,起飞延误报可以和起飞报合并拍发,但必须在起飞延误报的第三行和第四行之间,增加一行预达信息。
|
||||
|
||||
n ED 当延误时间超过30分钟以上,有明确的延误原因和清楚的预计起飞时间时,应拍发延误报。
|
||||
|
||||
n NI 当无法明确航班延误后的预计起飞时间时,应拍发长期延误报。编写电报时,应在下次信息通告代码“NI”后编写下一次通告的时间
|
||||
|
||||
#### 4\. 取消报(CNL)
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)动态报标志
|
||||
第二行:(取消信息)取消代码 航班号/日期 航空器注册号
|
||||
第三行:(补充信息)补充信息代码;补充信息资
|
||||
|
||||
MVT
|
||||
CNL FM801/01MAR B2570
|
||||
SI:DUE TO NO PAX
|
||||
```
|
||||
|
||||
#### 5\. 飞行预报(PLN)
|
||||
|
||||
(1) 正班飞行预报
|
||||
|
||||
```
|
||||
第一行:(电报类别标志)飞行预报标志
|
||||
第二行:(航班预报信息)日期 航班号 航空器注册号 机号 机长天气标准 机组人数
|
||||
预计起飞时间
|
||||
第三行:(补充信息)补充信息代码;补充信息资料
|
||||
例;PLN
|
||||
01MAR FM801/2 B2570 ILS1/1(16) 0105
|
||||
SI:
|
||||
```
|
||||
|
||||
(2)非正班飞行预报
|
||||
|
||||
```
|
||||
第一行:(电报类别标志) 计划报标志
|
||||
第二行:(航班预报信息) 日期 任务性质 航班号 航空器注册号 天气标准 机组人数
|
||||
第三行:(补充信息)补充信息代码;补充信息资料
|
||||
PLN
|
||||
01MAR C/B FM807/8 B2153 ILS 1/1(09)0010
|
||||
SI:FM807/8 PVG0010 0230MFM0330 0530PVG
|
||||
```
|
||||
|
||||
(3)正班飞行预报
|
||||
该电报在预报信息一行中,一般只需拍发日期、航班号、天气标准、机组人数等五项。如有需要,也可将航班在第一起飞站的航班预计起飞时间一项编写在机组人数之后。
|
||||
因编写电报时,会出现多个航班预报信息同时编写在一份电报中,因此,在出现编排两个以上航班预报时,应在每个航班信息前加编一项排列序号(使用阿拉伯数字)。
|
||||
补充信息
|
||||
在同一份预报中,若有信息内容需补充说明时,应在补充说明资料前编加与航班信息相应的排列序号
|
||||
|
||||
(4)非正班飞行预报
|
||||
|
||||
该电报在预报信息一行中必须编写非正班飞行任务性质一项,国内非正班飞行应使用民航总局规定的任务性质简写,如;旅客包机应编为“L/W”。
|
||||
航空公司航班号的编写不得超过7个字符,且只能编写单程航班的航班号。不得同时编写回程航班号
|
||||
若统一航班号有多个起飞站时,在预报信息一行,最多只能编写三个起飞站和预计起飞时间。若起飞站超过三个,或有三个以上的,应换行编写
|
||||
|
||||
任务性质说明:
|
||||
|
||||
```
|
||||
W/Z 正班 L/W 客包 C/B客加班 H/Y货加班 X/L训练
|
||||
|
||||
K/L本场训练 S/F 试飞 N/M调机 B/W 专机 H/G货包
|
||||
|
||||
O/F急救 Z/X要客加班 J/B 航班按专机
|
||||
|
||||
R/Z试航 U/H 公务 F/J
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
本文转载自[AFTN和SITA报文简介](https://blog.csdn.net/lejuo/article/details/46546191)
|
||||
|
||||
|
||||
|
||||
**Message Categories and Types**:
|
||||
|
||||
- **Emergency Messages**: Includes alerting (ALR) and radiocommunication failure (RCF).
|
||||
- **Flight Plan and Update Messages**: Includes filed flight plan (FPL), modification (CHG), cancellation (CNL), delay (DLA), departure (DEP), and arrival (ARR).
|
||||
- **Coordination Messages**: Includes current flight plan (CPL), estimate (EST), coordination (CDN), acceptance (ACP), and logical acknowledgement (LAM).
|
||||
- **Supplementary Messages**: Includes request flight plan (RQP), request supplementary flight plan (RQS), and supplementary flight plan (SPL) .
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,74 @@
|
||||
---
|
||||
page-title: "How to Open Port for a Specific IP Address in Firewalld"
|
||||
url: https://www.tecmint.com/open-port-for-specific-ip-address-in-firewalld/
|
||||
date: "2024-07-25 21:35:48"
|
||||
---
|
||||
How can I allow traffic from a specific IP address in my private network or allow traffic from a specific private network through **[firewalld](https://www.tecmint.com/configure-firewalld-in-centos-7/ "CentOS Firewalld Configuration")**, to a specific port or service on a **Red Hat Enterprise Linux** (**RHEL**) or **CentOS** server?
|
||||
|
||||
In this short article, you will learn how to open a port for a specific IP address or network range in your RHEL or CentOS server running a **firewalld** firewall.
|
||||
|
||||
The most appropriate way to solve this is by using a **firewalld** zone. So, you need to create a new zone that will hold the new configurations (or you can use any of the secure default zones available).
|
||||
|
||||
### Open Port for Specific IP Address in Firewalld
|
||||
|
||||
First create an appropriate zone name (in our case, we have used `mariadb-access` to allow access to the MySQL database server).
|
||||
|
||||
\# firewall-cmd --new-zone=mariadb-access --permanent
|
||||
|
||||
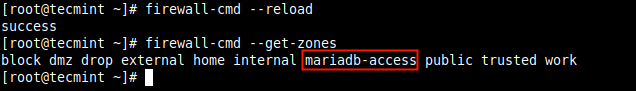
Next, reload the **firewalld** settings to apply the new change. If you skip this step, you may get an error when you try to use the new zone name. This time around, the new zone should appear in the list of zones as highlighted in the following screenshot.
|
||||
|
||||
\# firewall-cmd --reload
|
||||
# firewall-cmd --get-zones
|
||||
|
||||
|
||||
|
||||
Check Firewalld Zone
|
||||
|
||||
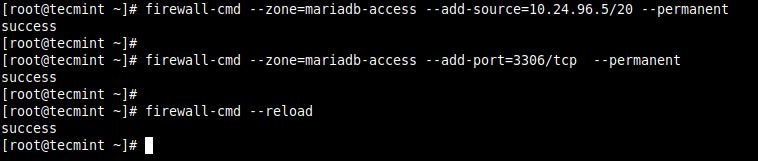
Next, add the source IP address (**10.24.96.5/20**) and the port (**3306**) you wish to open on the local server as shown. Then reload the firewalld settings to apply the new changes.
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --add-source=10.24.96.5/20 --permanent
|
||||
# firewall-cmd --zone=mariadb-access --add-port=3306/tcp --permanent
|
||||
# firewall-cmd --reload
|
||||
|
||||
|
||||
|
||||
Open Port for Specific IP in Firewalld
|
||||
|
||||
Alternatively, you can allow traffic from the entire network (**10.24.96.0/20**) to a service or port.
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --add-source=10.24.96.0/20 --permanent
|
||||
# firewall-cmd --zone=mariadb-access --add-port=3306/tcp --permanent
|
||||
# firewall-cmd --reload
|
||||
|
||||
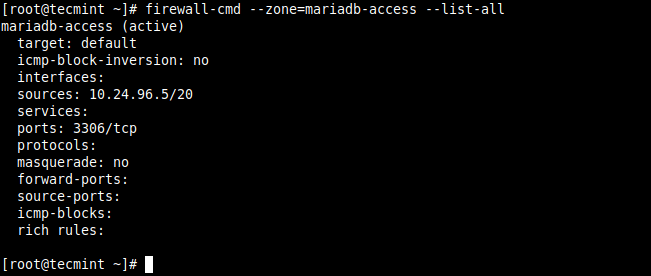
To confirm that the new zone has the required settings as added above, check its details with the following command.
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --list-all
|
||||
|
||||
|
||||
|
||||
View Firewalld Zone Details
|
||||
|
||||
### Remove Port and Zone from Firewalld
|
||||
|
||||
You can remove the source IP address or network as shown.
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --remove-source=10.24.96.5/20 --permanent
|
||||
# firewall-cmd --reload
|
||||
|
||||
To remove the port from the zone, issue the following command, and reload the firewalld settings:
|
||||
|
||||
\# firewall-cmd --zone=mariadb-access --remove-port=3306/tcp --permanent
|
||||
# firewall-cmd --reload
|
||||
|
||||
To remove the zone, run the following command, and reload the firewalld settings:
|
||||
|
||||
\# firewall-cmd --permanent --delete-zone=mariadb-access
|
||||
# firewall-cmd --reload
|
||||
|
||||
Last but not list, you can also use firewalld rich rules. Here is an example:
|
||||
|
||||
\# firewall-cmd --permanent –zone=mariadb-access --add-rich-rule='rule family="ipv4" source address="10.24.96.5/20" port protocol="tcp" port="3306" accept'
|
||||
|
||||
**Reference**: [Using and Configuring firewalld](https://access.redhat.com/documentation/en-us/red_hat_enterprise_linux/8/html/configuring_and_managing_networking/using-and-configuring-firewalld_configuring-and-managing-networking "Using and Configuring firewalld") in the RHEL 8 documentation.
|
||||
|
||||
That’s it! We hope the above solutions worked for you. If yes, let us know via the feedback form below. You can as well ask questions or share general comments about this topic.
|
||||
+652
@@ -0,0 +1,652 @@
|
||||
---
|
||||
page-title: "How to build a fullstack application with Go, Templ, and HTMX - DEV Community"
|
||||
url: https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444
|
||||
date: "2024-07-02 21:52:39"
|
||||
---
|
||||
Go is a statically typed, compiled high-level programming language for building systems, command-line interfaces (CLI), and more. It is typically designed for use on the backend; however, there are times when you want to use the same language to build a full-stack application with a functional backend and a visual frontend.
|
||||
|
||||
In most cases, Go developers opt for frontend frameworks/libraries like React, Vue, Angular, etc., to build the frontend part of the application. This means they must learn JavaScript/TypeScript, framework-specific paradigms, and other frontend-related overheads.
|
||||
|
||||
In this guide, you’ll learn how to build a fullstack application with Go using Templ, HTMX, and Xata.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#technology-overview)Technology Overview
|
||||
|
||||
**Templ**: is a templating engine that lets you build HTML with Go. It also lets you use Go syntax like `if`, `switch`, and `for` statements to build a robust frontend. You will use Templ to build reusable components and pages for the frontend.
|
||||
|
||||
**HTMX**: is a frontend library that lets you access modern browser features directly using HTML rather than JavaScript. You will use HTMX to process the form submission and perform other dynamic operations.
|
||||
|
||||
**Xata**: is a serverless database with analytics and free-text search support that makes a wide range of applications easy to build.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#prerequisites)Prerequisites
|
||||
|
||||
To follow along with this tutorial, the following are needed:
|
||||
|
||||
- [Go version 1.20 or higher installed](https://go.dev/dl/)
|
||||
- Basic understanding of Go
|
||||
- Xata account. [Signup is free](https://app.xata.io/signin?mode=signup?utm_source=fullstackwriter&utm_medium=fullstackwriter-blog)
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#getting-started)Getting started
|
||||
|
||||
To get started, you need to install Templ binary. The binary generates Go code from a Templ file.
|
||||
|
||||
```
|
||||
go install github.com/a-h/templ/cmd/templ@latest
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
Create a directory.
|
||||
|
||||
```
|
||||
mkdir go_fullstack && cd go_fullstack
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
Next, initialize a Go module to manage project dependencies.
|
||||
|
||||
```
|
||||
go mod init go-fullstack
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
Finally, we proceed to install the required dependencies with:
|
||||
|
||||
```
|
||||
go get github.com/gin-gonic/gin github.com/a-h/templ github.com/joho/godotenv
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
`github.com/gin-gonic/gin` is a framework for building web applications.
|
||||
|
||||
`github.com/a-h/templ` is the Templ library used in the project.
|
||||
|
||||
`github.com/joho/godotenv` is a library for loading environment variables.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#structuring-the-application)Structuring the application
|
||||
|
||||
To do this, create a `cmd`, `internals`, and `views` folder in our project directory.
|
||||
|
||||
`cmd` is for structuring the application entry point.
|
||||
|
||||
`internals` is for structuring API-related files.
|
||||
|
||||
`views` is for structuring frontend-related files.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#setup-the-database-on-xata)Setup the database on Xata
|
||||
|
||||
Log into the [Xata workspace](https://app.xata.io/workspaces) and create a `todo` database. Inside the `todo` database, create a `Todo` table and add a `description` column of type `String`.
|
||||
|
||||
[](https://media.dev.to/cdn-cgi/image/width=800%2Cheight=%2Cfit=scale-down%2Cgravity=auto%2Cformat=auto/https%3A%2F%2Fdev-to-uploads.s3.amazonaws.com%2Fuploads%2Farticles%2Fsnohlapfqs2x519j2klo.png)
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#get-the-database-url-and-set-up-the-api-key)Get the Database URL and set up the API Key
|
||||
|
||||
To get the database URL, click the **Get code snippet** button and copy the URL. Then click the **API Key** link, add a new key, save and copy the API key.
|
||||
|
||||
[](https://media.dev.to/cdn-cgi/image/width=800%2Cheight=%2Cfit=scale-down%2Cgravity=auto%2Cformat=auto/https%3A%2F%2Fdev-to-uploads.s3.amazonaws.com%2Fuploads%2Farticles%2Fpgs4uphc5u9sewh2wf86.png)
|
||||
[](https://media.dev.to/cdn-cgi/image/width=800%2Cheight=%2Cfit=scale-down%2Cgravity=auto%2Cformat=auto/https%3A%2F%2Fdev-to-uploads.s3.amazonaws.com%2Fuploads%2Farticles%2Ffhi01luxfz88eh9hy5cm.png)
|
||||
|
||||
**Setup environment variable**
|
||||
|
||||
Create a `.env` file in the root directory and add the copied URL and API key.
|
||||
|
||||
```
|
||||
XATA_DATABASE_URL= <REPLACE WITH THE COPIED DATABASE URL>
|
||||
XATA_API_KEY=<REPLACE WITH THE COPIED API KEY>
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#build-the-application-frontend)Build the application Frontend
|
||||
|
||||
To build the frontend, you’ll use Templ and HTMX to structure the application and add dynamism to a Todo application.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-application-components)Create the application components
|
||||
|
||||
Inside the `views` folder, create a `components/header.templ` file and add the snippet below:
|
||||
|
||||
```
|
||||
package components
|
||||
|
||||
templ Header() {
|
||||
<head>
|
||||
<script
|
||||
src="https://unpkg.com/htmx.org@1.9.10"
|
||||
integrity="sha384-D1Kt99CQMDuVetoL1lrYwg5t+9QdHe7NLX/SoJYkXDFfX37iInKRy5xLSi8nO7UC"
|
||||
crossorigin="anonymous"
|
||||
></script>
|
||||
<script src="https://cdn.tailwindcss.com"></script>
|
||||
<meta charset="UTF-8" />
|
||||
<meta name="viewport" content="width=device-width, initial-scale=1.0" />
|
||||
<title>GO Fullstack</title>
|
||||
</head>
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet creates a `Header` component and adds HTMX and TailwindCSS CDNs. TailwindCSS is a low-level framework for styling.
|
||||
|
||||
Next, create a `components/footer.templ` file to create the application footer and style using TailwindCSS classes.
|
||||
|
||||
```
|
||||
package components
|
||||
|
||||
templ Footer() {
|
||||
<footer class="fixed p-1 bottom-0 bg-gray-100 w-full border-t">
|
||||
<div class="rounded-lg p-4 text-xs italic text-gray-700 text-center">
|
||||
© Go Fullstack
|
||||
</div>
|
||||
</footer>
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
Finally, create an `index.templ` file inside the same `views` folder and add the snippet below:
|
||||
|
||||
```
|
||||
package views
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"go_fullstack/views/components"
|
||||
)
|
||||
|
||||
type Todo struct {
|
||||
Id string
|
||||
Description string
|
||||
}
|
||||
|
||||
templ Index(todos []*Todo) {
|
||||
<!DOCTYPE html>
|
||||
<html lang="en">
|
||||
@components.Header()
|
||||
<body>
|
||||
<main class="min-h-screen w-full">
|
||||
<nav class="flex w-full border border-b-zinc-200 px-4 py-4">
|
||||
<h3 class="text-base lg:text-lg font-medium text-center">
|
||||
GO Fullstack app
|
||||
</h3>
|
||||
</nav>
|
||||
<div class="mt-6 w-full flex justify-center items-center flex-col">
|
||||
// FORM PROCESSING
|
||||
<form
|
||||
hx-post="/"
|
||||
hx-trigger="submit"
|
||||
hx-swap="none"
|
||||
onsubmit="reloadPage()"
|
||||
class="w-96"
|
||||
>
|
||||
<textarea
|
||||
name="description"
|
||||
cols="30"
|
||||
rows="2"
|
||||
class="w-full border rounded-lg mb-2 p-4"
|
||||
placeholder="Input todo details"
|
||||
required
|
||||
></textarea>
|
||||
<button
|
||||
class="py-1 px-4 w-full h-10 rounded-lg text-white bg-zinc-800"
|
||||
>
|
||||
Create
|
||||
</button>
|
||||
</form>
|
||||
<section class="border-t border-t-zinc-200 mt-6 px-2 py-4 w-96">
|
||||
// LOOP THROUGH THE TODOS
|
||||
<ul id="todo-list">
|
||||
for _, todo := range todos {
|
||||
<li class="ml-4 ml-4 border p-2 rounded-lg mb-2" id={ fmt.Sprintf("%s", todo.Id) }>
|
||||
<p class="font-medium text-sm">Todo item { todo.Id }</p>
|
||||
<p class="text-sm text-zinc-500 mb-2">
|
||||
{ todo.Description }
|
||||
</p>
|
||||
<div class="flex gap-4 items-center mt-2">
|
||||
<a
|
||||
href="#"
|
||||
class="flex items-center border py-1 px-2 rounded-lg"
|
||||
>
|
||||
<p class="text-sm">Edit</p>
|
||||
</a>
|
||||
<button
|
||||
hx-delete={ fmt.Sprintf("/%s", todo.Id) }
|
||||
hx-swap="delete"
|
||||
hx-target={ fmt.Sprintf("#%s", todo.Id) }
|
||||
class="flex items-center border py-1 px-2 rounded-lg hover:bg-red-300"
|
||||
>
|
||||
<p class="text-sm">Delete</p>
|
||||
</button>
|
||||
</div>
|
||||
</li>
|
||||
}
|
||||
</ul>
|
||||
</section>
|
||||
</div>
|
||||
</main>
|
||||
</body>
|
||||
@components.Footer()
|
||||
</html>
|
||||
<script>
|
||||
function reloadPage() {
|
||||
setTimeout(function() {
|
||||
window.location.reload();
|
||||
}, 2000);
|
||||
}
|
||||
</script>
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following:
|
||||
|
||||
- Imports the required dependencies
|
||||
- Creates a `Todo` struct to represent the response data coming from the backend
|
||||
- Creates an `Index` component that uses the `Header` and `Footer` components to structure the page. Then, it uses the HTMX attributes to process form submissions and deletion of todos by calling the respective endpoints `/` and `/{todo.Id}`
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#generating-go-files-from-the-templ-files)Generating Go files from the Templ files
|
||||
|
||||
Next, use the Templ binary you installed earlier to Generate Go codes from the views created above by running the command below in your terminal:
|
||||
|
||||
```
|
||||
templ generate
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
After you run this command, you’ll see new Go files generated for each view. You use generated file to render your frontend in next section.
|
||||
|
||||
[](https://media.dev.to/cdn-cgi/image/width=800%2Cheight=%2Cfit=scale-down%2Cgravity=auto%2Cformat=auto/https%3A%2F%2Fdev-to-uploads.s3.amazonaws.com%2Fuploads%2Farticles%2F0n91b8w6mchs03qq761h.png)
|
||||
|
||||
> The generated files are not to be edited.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#putting-it-together-and-building-the-backend)Putting it together and building the backend
|
||||
|
||||
With that done, you can use it to build the backend and render the required page.
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-api-models-and-helper-function)Create the API models and helper function
|
||||
|
||||
To represent the application data, create a `model.go` file inside the `internals` folder and add the snippet below:
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
type Todo struct {
|
||||
Id string `json:"id,omitempty"`
|
||||
Description string `json:"description,omitempty"`
|
||||
}
|
||||
|
||||
type TodoRequest struct {
|
||||
Description string `json:"description,omitempty"`
|
||||
}
|
||||
|
||||
type TodoResponse struct {
|
||||
Id string `json:"id,omitempty"`
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above creates a `Todo`, `TodoRequest`, and `TodoResponse` struct with the required properties to describe requests and response types.
|
||||
|
||||
Finally, create a `helpers.go` file with a reusable function to load environment variables.
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
import (
|
||||
"log"
|
||||
"os"
|
||||
"github.com/joho/godotenv"
|
||||
)
|
||||
|
||||
func GetEnvVariable(key string) string {
|
||||
err := godotenv.Load()
|
||||
if err != nil {
|
||||
log.Fatal("Error loading .env file")
|
||||
}
|
||||
return os.Getenv(key)
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-application-and-api-routes)Create the application and API routes
|
||||
|
||||
Create a `route.go` file for configuring the API routes and add the snippet below:
|
||||
|
||||
```
|
||||
package api
|
||||
|
||||
import "github.com/gin-gonic/gin"
|
||||
|
||||
type Config struct {
|
||||
Router *gin.Engine
|
||||
}
|
||||
|
||||
func (app *Config) Routes() {
|
||||
//routes will come here
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following:
|
||||
|
||||
- Imports the required dependency
|
||||
- Creates a `Config` struct with a `Router` property to configure the application methods
|
||||
- Creates a `Routes` function that takes in the `Config` struct as a pointer
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-api-services)Create the API services
|
||||
|
||||
With that done, create a `xata_service.go` file for the application and update it by doing the following:
|
||||
|
||||
First, import the required dependencies and create a helper function:
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"net/http"
|
||||
)
|
||||
|
||||
var xataAPIKey = GetEnvVariable("XATA_API_KEY")
|
||||
var baseURL = GetEnvVariable("XATA_DATABASE_URL")
|
||||
|
||||
func createRequest(method, url string, bodyData *bytes.Buffer) (*http.Request, error) {
|
||||
var req *http.Request
|
||||
var err error'
|
||||
|
||||
if method == "GET" || method == "DELETE" || bodyData == nil {
|
||||
req, err = http.NewRequest(method, url, nil)
|
||||
} else {
|
||||
req, err = http.NewRequest(method, url, bodyData)
|
||||
}
|
||||
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
req.Header.Add("Content-Type", "application/json")
|
||||
req.Header.Add("Authorization", fmt.Sprintf("Bearer %s", xataAPIKey))
|
||||
|
||||
return req, nil
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following:
|
||||
|
||||
- Imports the required dependencies
|
||||
- Creates required environment variables
|
||||
- Creates a `createRequest` function that creates HTTP requests with the required headers
|
||||
|
||||
Lastly, add a `createTodoService`, `deleteTodoService`, and `getAllTodosService` methods to create, delete, and get the list of todos.
|
||||
|
||||
```
|
||||
//imports goes here
|
||||
|
||||
func createRequest(method, url string, bodyData *bytes.Buffer) (*http.Request, error) {
|
||||
//createRequest code goes here
|
||||
}
|
||||
|
||||
func (app *Config) createTodoService(newTodo *TodoRequest) (*TodoResponse, error) {
|
||||
createTodo := TodoResponse{}
|
||||
jsonData := Todo{
|
||||
Description: newTodo.Description,
|
||||
}
|
||||
|
||||
bodyData := new(bytes.Buffer)
|
||||
json.NewEncoder(bodyData).Encode(jsonData)
|
||||
|
||||
fullURL := fmt.Sprintf("%s:main/tables/Todo/data", baseURL)
|
||||
req, err := createRequest("POST", fullURL, bodyData)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
client := &http.Client{}
|
||||
resp, err := client.Do(req)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
defer resp.Body.Close()
|
||||
if err := json.NewDecoder(resp.Body).Decode(&createTodo); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
return &createTodo, nil
|
||||
}
|
||||
func (app *Config) deleteTodoService(id string) (string, error) {
|
||||
fullURL := fmt.Sprintf("%s:main/tables/Todo/data/%s", baseURL, id)
|
||||
client := &http.Client{}
|
||||
req, err := createRequest("DELETE", fullURL, nil)
|
||||
if err != nil {
|
||||
return "", err
|
||||
}
|
||||
|
||||
resp, err := client.Do(req)
|
||||
if err != nil {
|
||||
return "", err
|
||||
}
|
||||
defer resp.Body.Close()
|
||||
|
||||
return id, nil
|
||||
}
|
||||
|
||||
func (app *Config) getAllTodosService() ([]*Todo, error) {
|
||||
var todos []*Todo
|
||||
|
||||
fullURL := fmt.Sprintf("%s:main/tables/Todo/query", baseURL)
|
||||
client := &http.Client{}
|
||||
req, err := createRequest("POST", fullURL, nil)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
resp, err := client.Do(req)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
defer resp.Body.Close()
|
||||
var response struct {
|
||||
Records []*Todo `json:"records"`
|
||||
}
|
||||
|
||||
decoder := json.NewDecoder(resp.Body)
|
||||
if err := decoder.Decode(&response); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
todos = response.Records
|
||||
return todos, nil
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#create-the-api-handlers)Create the API handlers
|
||||
|
||||
With that done, you can use the services to create the API handlers. Create a `handler.go` file inside `internals` folder and add the snippet below:
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
import (
|
||||
"context"
|
||||
"fmt"
|
||||
"go_fullstack/views"
|
||||
"net/http"
|
||||
"time"
|
||||
"github.com/a-h/templ"
|
||||
"github.com/gin-gonic/gin"
|
||||
)
|
||||
|
||||
const appTimeout = time.Second * 10
|
||||
|
||||
func render(ctx *gin.Context, status int, template templ.Component) error {
|
||||
ctx.Status(status)
|
||||
return template.Render(ctx.Request.Context(), ctx.Writer)
|
||||
}
|
||||
|
||||
func (app *Config) indexPageHandler() gin.HandlerFunc {
|
||||
return func(ctx *gin.Context) {
|
||||
_, cancel := context.WithTimeout(context.Background(), appTimeout)
|
||||
defer cancel()
|
||||
|
||||
todos, err := app.getAllTodosService()
|
||||
if err != nil {
|
||||
ctx.JSON(http.StatusBadRequest, err.Error())
|
||||
return
|
||||
}
|
||||
|
||||
var viewsTodos []*views.Todo
|
||||
for _, todo := range todos {
|
||||
viewsTodo := &views.Todo{
|
||||
Id: todo.Id,
|
||||
Description: todo.Description,
|
||||
}
|
||||
viewsTodos = append(viewsTodos, viewsTodo)
|
||||
}
|
||||
|
||||
render(ctx, http.StatusOK, views.Index(viewsTodos))
|
||||
}
|
||||
}
|
||||
|
||||
func (app *Config) createTodoHandler() gin.HandlerFunc {
|
||||
return func(ctx *gin.Context) {
|
||||
_, cancel := context.WithTimeout(context.Background(), appTimeout)
|
||||
description := ctx.PostForm("description")
|
||||
defer cancel()
|
||||
|
||||
newTodo := TodoRequest{
|
||||
Description: description,
|
||||
}
|
||||
|
||||
data, err := app.createTodoService(&newTodo)
|
||||
if err != nil {
|
||||
ctx.JSON(http.StatusBadRequest, err.Error())
|
||||
return
|
||||
}
|
||||
|
||||
ctx.JSON(http.StatusCreated, data)
|
||||
}
|
||||
}
|
||||
|
||||
func (app *Config) deleteTodoHandler() gin.HandlerFunc {
|
||||
return func(ctx *gin.Context) {
|
||||
_, cancel := context.WithTimeout(context.Background(), appTimeout)
|
||||
id := ctx.Param("id")
|
||||
defer cancel()
|
||||
|
||||
data, err := app.deleteTodoService(id)
|
||||
if err != nil {
|
||||
ctx.JSON(http.StatusBadRequest, err.Error())
|
||||
return
|
||||
}
|
||||
|
||||
ctx.JSON(http.StatusAccepted, fmt.Sprintf("Todo with ID: %s deleted successfully!!", data))
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following
|
||||
|
||||
- Imports the required dependencies
|
||||
- Creates a `render` function that uses the `Templ` package to render matching template
|
||||
- Creates an `indexPageHandler` function that returns a Gin-gonic handler and takes in the `Config` struct as a pointer. Inside the returned handler, use the `getAllTodosService` service to get the list of todos and then render the appropriate page using the generated code from the views package (frontend)
|
||||
- Creates a `createdTodoHandler` and `deleteProjectHandler` functions that return a Gin-gonic handler and take in the `Config` struct as a pointer. Use the service created earlier to perform the corresponding action inside the returned handler
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#update-the-api-routes-to-use-handlers)Update the API routes to use handlers
|
||||
|
||||
Update the `routes.go` file with the handlers as shown below:
|
||||
|
||||
```
|
||||
package internals
|
||||
|
||||
import (
|
||||
"github.com/gin-gonic/gin"
|
||||
)
|
||||
|
||||
type Config struct {
|
||||
Router *gin.Engine
|
||||
}
|
||||
|
||||
func (app *Config) Routes() {
|
||||
//views
|
||||
app.Router.GET("/", app.indexPageHandler())
|
||||
|
||||
//apis
|
||||
app.Router.POST("/", app.createTodoHandler())
|
||||
app.Router.DELETE("/:id", app.deleteTodoHandler())
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#putting-it-all-together)Putting it all together
|
||||
|
||||
Create the application entry point to use to serve the routes. To do this, create a `main.go` file inside the `cmd` folder and add the snippet below:
|
||||
|
||||
```
|
||||
package main
|
||||
|
||||
import (
|
||||
"go_fullstack/internals"
|
||||
"github.com/gin-gonic/gin"
|
||||
)
|
||||
|
||||
func main() {
|
||||
router := gin.Default()
|
||||
|
||||
//initialize config
|
||||
app := internals.Config{Router: router}
|
||||
|
||||
//routes
|
||||
app.Routes()
|
||||
|
||||
router.Run(":8080")
|
||||
}
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||
The snippet above does the following:
|
||||
|
||||
- Imports the required dependencies
|
||||
- Creates a Gin router using the `Default` configuration
|
||||
- Initialize the `Config` struct by passing in the `Router`
|
||||
- Adds the route and run the application on port `:8080`
|
||||
|
||||
With that done, you can start a development server using the command below:
|
||||
|
||||
```
|
||||
go run cmd/main.go
|
||||
```
|
||||
|
||||
Enter fullscreen mode Exit fullscreen mode
|
||||
|
||||

|
||||
|
||||
The complete source code can be found on [GitHub](https://github.com/Mr-Malomz/go_fullstack).
|
||||
|
||||
## [](https://dev.to/hackmamba/how-to-build-a-fullstack-application-with-go-templ-and-htmx-4444#conclusion)Conclusion
|
||||
|
||||
This post discusses how to build a fullstack application with Go, Templ, HTMX, and Xata. You can extend the application further to support viewing and editing todos.
|
||||
|
||||
These resources may also be helpful:
|
||||
|
||||
- [Xata documentation](https://xata.io/docs?utm_source=fullstackwriter&utm_medium=fullstackwriter-blog)
|
||||
- [Templ documentation](https://templ.guide/?utm_source=fullstackwriter&utm_medium=fullstackwriter-blog)
|
||||
- [HTMX documentation](https://htmx.org/docs/?utm_source=fullstackwriter&utm_medium=fullstackwriter-blog)
|
||||
- [Go + Xata](https://fullstackwriter.dev/post/xata-go-a-getting-started-guide?category=Golang)
|
||||
@@ -0,0 +1,357 @@
|
||||
---
|
||||
page-title: "Implementing Graceful Shutdown in Go | RudderStack Blog"
|
||||
url: https://www.rudderstack.com/blog/implementing-graceful-shutdown-in-go/
|
||||
date: "2024-07-07 22:41:03"
|
||||
---
|
||||
Shutting down gracefully is important for any long lasting process, especially for one that handles some kind of state. For example, what if you wanted to shutdown the database that supports your application and the db process didn't flush the current state to the disk, or what if you wanted to shut down a web server with thousands of connections but didn't wait for the requests to finish Not only does shutting down gracefully positively affect the user experience, it also eases internal operations, leading to happier engineers and less stressed SREs.
|
||||
|
||||
To shutdown gracefully is for the program to terminate after:
|
||||
|
||||
- All pending processes (web request, loops) are completed - no new processes should start and no new web requests should be accepted.
|
||||
- Closing all open connections to external services and databases.
|
||||
|
||||
There are a couple of things we must figure out in order to shutdown gracefully:
|
||||
|
||||
- **When should we shutdown** *\-* Are all pending processes completed, and how we can know this? What if a processes is stuck?
|
||||
- **How we communicate with processes** \- The previous task requires some kind of communication. This is especially true if we are building a modern, asynchronous, and highly concurrent application. So, how can we tell them to shutdown and also know when they've done that?
|
||||
|
||||
When I started looking into shutdown at RudderStack, I saw a number of anti patterns that we were following—for example using *os.Exit(1)* (more on this later)—and decided it was time to implement a graceful shutdown mechanism for [Rudder Server](https://github.com/rudderlabs/rudder-server/). At RudderStack we are building an important part of the modern data stack. RudderStack is responsible for capturing, processing, and delivering data to important parts of a company's infrastructure. So, making sure everything is predictable and ensuring there is no chance for data loss whenever we have to interact with a service is incredibly important. This gave me two main goals with graceful shutdown:
|
||||
|
||||
1. Ensure that no data loss can happen during a shutdown.
|
||||
2. Introduce better service control to enable integration testing.
|
||||
|
||||
Rudder Server is written in Go and my initial research on how to properly implement graceful shutdown didn't return much information. So, I decided to publish my experience in implementing this pattern on Rudder Server.
|
||||
|
||||
In this post you'll find a number of anti patterns and learn how to make exiting a graceful process with a couple of different approaches. I'll also include a number of examples for common libraries and some advanced patterns. Let's dive in.
|
||||
|
||||
## Anti-patterns
|
||||
|
||||
### Block artificially
|
||||
|
||||
The first anti-pattern is the idea of blocking the main go routine without actually waiting on anything. Here's an example toy implementation:
|
||||
|
||||
```
|
||||
func KeepProcessAlive() { var ch chan int <-ch}func main() { ... KeepProcessAlive()}
|
||||
```
|
||||
|
||||
### os.Exit()
|
||||
|
||||
Calling os.Exit(1) while other go routines are still running is essentially equal to SIGKILL, no chance for closing open connections and finishing inflight requests and processing.
|
||||
|
||||
```
|
||||
go func() { <-ch os.Exit(1)}()go func () { for ... { }}()
|
||||
```
|
||||
|
||||
## How to make it graceful in Go
|
||||
|
||||
In order to gracefully shutdown a service there are two things you need to understand:
|
||||
|
||||
1. How to wait for all the running go routines to exit
|
||||
2. How to propagate the termination signal to multiple go routines
|
||||
|
||||
Go provides all the tools we need to properly implement (1) and (2). Let's take a look at these in more detail.
|
||||
|
||||
### Wait for go-routines to finish
|
||||
|
||||
Go provides sufficient ways for controlling concurrency. Let's see what options are available on waiting go routines.
|
||||
|
||||
#### Using channel
|
||||
|
||||
Simplest solution, using channel primitive.
|
||||
|
||||
1. We create an empty struct channel make(chan struct{}, 1) (empty struct requires no memory).
|
||||
2. Every child go routine should **publish to the channel when it is done** (defer can be useful here).
|
||||
3. The parent go routine should **consume from the channel as many times as the expected go routines**.
|
||||
|
||||
The example can clear things up:
|
||||
|
||||
```
|
||||
func run(ctx) { wait := make(chan struct{}, 1) go func() { defer func() { wait <- struct{}{} }() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() go func() { defer func() { wait <- struct{}{} }() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() // wait for two goroutines to finish <-wait <-wait fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
*Note: This is mostly useful when waiting on a single go routine.*
|
||||
|
||||
#### With WaitGroup
|
||||
|
||||
The channel solution can be a bit ugly, especially with multiple go routines.
|
||||
|
||||
[sync.WaitGroup](https://pkg.go.dev/sync#WaitGroup/) is a standard library package, that can be used as a more idiomatic way to achieve the above.
|
||||
|
||||
You can also see another [example of waitgroups](https://gobyexample.com/waitgroups/) in use.
|
||||
|
||||
```
|
||||
func run(ctx) { var wg sync.WaitGroup wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") return; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") return; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() wg.Wait() fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
#### With errgroup
|
||||
|
||||
The [sync/errgroup](https://pkg.go.dev/golang.org/x/sync/errgroup/) package exposes a better way to do this.
|
||||
|
||||
- The two errgroup's methods .Go and .Wait are more readable and easier to maintain in comparison to WaitGroup.
|
||||
- In addition, as its name suggests it does error propagation and cancels the context in order to terminate the other go-routines in case of an error.
|
||||
|
||||
```
|
||||
func run(ctx) { g, gCtx := errgroup.WithContext(ctx) g.Go(func() error { for { select { case <-gCtx.Done(): fmt.Println("Break the loop") return nil; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }) g.Go(func() error { for { select { case <-gCtx.Done(): fmt.Println("Break the loop") return nil; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() err := g.Wait() if err != nil { fmt.Println("Error group: ", err) } fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
## Terminating a process
|
||||
|
||||
Even if we have figured out how to properly communicate the state of processes and wait for them, we still have to implement termination. Let's see how this can be done with a simple example, introducing all the necessary Go primitives.
|
||||
|
||||
Let's start with a very simple "Hello in a loop" example:
|
||||
|
||||
```
|
||||
func main() { for { time.Sleep(1 * time.Second) fmt.Println("Hello in a loop") }}
|
||||
```
|
||||
|
||||
### Introducing signal handling
|
||||
|
||||
Listen for an OS signal to stop the progress:
|
||||
|
||||
```
|
||||
exit := make(chan os.Signal, 1) // we need to reserve to buffer size 1, so the notifier are not blockedsignal.Notify(exit, os.Interrupt, syscall.SIGTERM)
|
||||
```
|
||||
|
||||
- We need to use os.Interrupt to gracefully shutdown on Ctrl+C which is **SIGINT**
|
||||
- syscall.**SIGTERM** is the usual signal for termination and the default one (it can be [modified](https://docs.docker.com/engine/reference/builder/#stopsignal/)) for [docker](https://docs.docker.com/engine/reference/commandline/stop/) containers, which is also used by [kubernetes](https://kubernetes.io/docs/concepts/workloads/pods/pod-lifecycle/#pod-termination/).
|
||||
- Read more about signal in the [package documentation](https://pkg.go.dev/os/signal/) and [go by example](https://gobyexample.com/signals/).
|
||||
|
||||
### Breaking the loop
|
||||
|
||||
Now that we have a way to capture signals, we need to find a way to interrupt the loop.
|
||||
|
||||
#### Non-Blocking Channel Select
|
||||
|
||||
select gives you the ability to consume from multiple channels in each case.
|
||||
|
||||
You can review the following resources to get a better understanding:
|
||||
|
||||
- [https://gobyexample.com/non-blocking-channel-operations](https://gobyexample.com/non-blocking-channel-operations/)
|
||||
- [https://tour.golang.org/concurrency/5](https://tour.golang.org/concurrency/5/)
|
||||
- [https://gobyexample.com/timeouts](https://gobyexample.com/timeouts/)
|
||||
|
||||
Our simple hello for loop, now stops on termination signal:
|
||||
|
||||
```
|
||||
func main() { c := make(chan os.Signal, 1) // we need to reserve to buffer size 1, so the notifier are not blocked signal.Notify(c, os.Interrupt, syscall.SIGTERM) for { select { case <-c: fmt.Println("Break the loop") return; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } }}
|
||||
```
|
||||
|
||||
***Note:** We had to change the* time.Sleep(1 \* time.Second) *to* time.After(1 \* time.Second)
|
||||
|
||||
### How to do it using Context
|
||||
|
||||
Context is a very useful interface in go, that should be used and propagated in all blocking functions. It enables the propagation of cancelation throughout the program.
|
||||
|
||||
It is considered good practice for ctx context.Context to be the first argument in every method or function that is used directly or indirectly for external dependencies.
|
||||
|
||||
|
||||
|
||||
A very detailed article about context: [https://go.dev/blog/context](https://go.dev/blog/context/)
|
||||
|
||||
### Channel sharing issue
|
||||
|
||||
Let's examine how context properties could help in a more complex situation.
|
||||
|
||||
*Having multiple loops running in parallel, using channels (counter-example):*
|
||||
|
||||
```
|
||||
// COUNTER EXAMPLE, DO NOT USE THIS CODEfunc main() { exit := make(chan os.Signal, 1) signal.Notify(exit, os.Interrupt, syscall.SIGTERM) // This will not work as expected!! var wg sync.WaitGroup wg.Add(1) go func() { defer wg.Done() for { select { case <-exit: // Only one go routine will get the termination signal fmt.Println("Break the loop: hello") break; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() wg.Add(1) go func() { defer wg.Done() for { select { case <-exit: // Only one go routine will get the termination signal fmt.Println("Break the loop: ciao") break; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() wg.Wait() fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
*Why is this not going to work?*
|
||||
|
||||
Go channels do not work in a **broadcast** way, only one go routine will receive a single os.Signal. Also, there is no guarantee which go routine will receive it.
|
||||
|
||||
wait := make(chan struct{}{}, 2)
|
||||
|
||||
Context can help us make the above work, let's see how.
|
||||
|
||||
#### Using Context for termination
|
||||
|
||||
Let's try to fix this problem by introducing [context.WithCancel](https://pkg.go.dev/context#WithCancel/)
|
||||
|
||||
```
|
||||
func main() { ctx, cancel := context.WithCancel(context.Background()) go func() { exit := make(chan os.Signal, 1) signal.Notify(c, os.Interrupt, syscall.SIGTERM) cancel() }() var wg sync.WaitGroup wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() wg.Wait() fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
Essentially the cancel() is broadcasted to all the go-routines that call .Done().
|
||||
|
||||
*The returned context's Done channel is closed when the returned cancel function is called or when the parent context's Done channel is closed, whichever happens first.*
|
||||
|
||||
### NotifyContext
|
||||
|
||||
In go 1.16 a new helpful method was introduced in signal package, [singal.NotifyContext](https://pkg.go.dev/os/signal#NotifyContext/):
|
||||
|
||||
```
|
||||
func NotifyContext(parent context.Context, signals ...os.Signal) (ctx context.Context, stop context.CancelFunc)
|
||||
```
|
||||
|
||||
*NotifyContext returns a copy of the parent context that is marked done (its Done channel is closed) when one of the listed signals arrives, when the returned stop function is called, or when the parent context's Done channel is closed, whichever happens first.*
|
||||
|
||||
Using NotifyContext can simplify the example above to:
|
||||
|
||||
```
|
||||
func main() { ctx, stop := context.NotifyContext(context.Background(), os.Interrupt, syscall.SIGTERM) defer stop() var wg sync.WaitGroup wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }() wg.Add(1) go func() { defer wg.Done() for { select { case <-ctx.Done(): fmt.Println("Break the loop") break; case <-time.After(1 * time.Second): fmt.Println("Ciao in a loop") } } }() wg.Wait() fmt.Println("Main done")}
|
||||
```
|
||||
|
||||
*A full working example can be found under our [example repo](https://github.com/rudderlabs/graceful-shutdown-examples/tree/main/signal/)*
|
||||
|
||||
## Common libraries
|
||||
|
||||
### HTTP server
|
||||
|
||||
The examples above included a for loop for simplification, but let's examine something more practical.
|
||||
|
||||
During a non-graceful shutdown, inflight HTTP requests could face the following issues:
|
||||
|
||||
- They never get a response back, so they timeout.
|
||||
- Some progress has been made, but it is interrupted halfway, causing a waste of resources or data inconsistencies if transactions are not used properly.
|
||||
- A connection to an external dependency is closed by another go routine, so the request can not progress further.
|
||||
|
||||
*⚠️ **Having your HTTP server shutting down gracefully is really important.** In a cloud-native environment services/pods shutdown multiple times within a day either for autoscaling, applying a configuration, or deploying a new version of a service. Thus, the impact of interrupted or timeout requests can be significant in the service's SLAs.*
|
||||
|
||||
Fortunately, go provides a way to gracefully shutdown an HTTP server.
|
||||
|
||||
Let us see how it's done:
|
||||
|
||||
```
|
||||
func main() { ctx, cancel := context.WithCancel(context.Background()) go func() { c := make(chan os.Signal, 1) // we need to reserve to buffer size 1, so the notifier are not blocked signal.Notify(c, os.Interrupt, syscall.SIGTERM) <-c cancel() }() db, err := repo.SetupPostgresDB(ctx, getConfig("DB_DSN", "root@tcp(127.0.0.1:3306)/service")) if err != nil { panic(err) } httpServer := &http.Server{ Addr: ":8000", } g, gCtx := errgroup.WithContext(ctx) g.Go(func() error { return httpServer.ListenAndServe() }) g.Go(func() error { <-gCtx.Done() return httpServer.Shutdown(context.Background()) }) if err := g.Wait(); err != nil { fmt.Printf("exit reason: %s \n", err) }}
|
||||
```
|
||||
|
||||
We are using two go routines:
|
||||
|
||||
1. run **httpServer.ListenAndServe()** as usual
|
||||
2. wait for <-gCtx.Done() and then call **httpServer.Shutdown(context.Background())**
|
||||
|
||||
It is important to read the package documentation in order to understand how this works:
|
||||
|
||||
Shutdown gracefully shuts down the server **without interrupting any active connections**.
|
||||
|
||||
Nice, but how?
|
||||
|
||||
Shutdown works by first closing all open listeners, then closing all idle connections, and then waiting indefinitely for connections to return to idle and then shut down.
|
||||
|
||||
Why do I have to provide a context?
|
||||
|
||||
If the provided context expires before the shutdown is complete, Shutdown returns the context's error, otherwise it returns any error returned from closing the Server's underlying Listener(s).
|
||||
|
||||
In the example, we chose to provide **context.Background()** which has no expiration.
|
||||
|
||||
#### Canceling long running requests
|
||||
|
||||
When .Shutdown is method is called the serve stop accepting new connections and it waits for existing once to finish before .ListenAndServe() may return.
|
||||
|
||||
There are cases where http requests require quite a long time to be terminated. That could be a for instance a long running job or a websocket connection.
|
||||
|
||||
So, what is the best way to terminate those gracefully and not hang waiting for them to finish?
|
||||
|
||||
The answer comes into two parts:
|
||||
|
||||
1. First of all you need to extract the context from http.Request ctx := req.Context() and use this context to terminate your long running process.
|
||||
2. Use [BaseContext](https://pkg.go.dev/net/http#Server/) (introduced in go1.13), to pass your main ctx as the context in every request
|
||||
|
||||
BaseContext optionally specifies a function that returns the base context for incoming requests on this server.
|
||||
The provided Listener is the specific Listener that's about to start accepting requests.
|
||||
If BaseContext is nil, the default is context.Background().
|
||||
If non-nil, it must return a non-nil context.
|
||||
|
||||
In the example bellow, a dummy http handler keeps printing in stdout Hello in a loop, it will stop either when the request is canceled or the instance receives a termination signal.
|
||||
|
||||
```
|
||||
func main() { mainCtx, stop := signal.NotifyContext(context.Background(), os.Interrupt, syscall.SIGTERM) defer stop() httpServer := &http.Server{ Addr: ":8000", Handler: http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) { ctx := r.Context() for { select { case <-ctx.Done(): fmt.Println("Graceful handler exit") w.WriteHeader(http.StatusOK) return case <-time.After(1 * time.Second): fmt.Println("Hello in a loop") } } }), BaseContext: func(_ net.Listener) context.Context { return mainCtx }, } g, gCtx := errgroup.WithContext(mainCtx) g.Go(func() error { return httpServer.ListenAndServe() }) g.Go(func() error { <-gCtx.Done() return httpServer.Shutdown(context.Background()) }) if err := g.Wait(); err != nil { fmt.Printf("exit reason: %s \n", err) }}
|
||||
```
|
||||
|
||||
A full working example can be found under our [example repo](https://github.com/rudderlabs/graceful-shutdown-examples/tree/main/httpserver/), feel free to experiment by commenting out BaseContextor or httpServer.Shutdown.
|
||||
|
||||
### HTTP Client
|
||||
|
||||
Go standard libraries provides a way to pass a context when making an HTTP request: [NewRequestWithContext](https://pkg.go.dev/net/http#NewRequestWithContext/)
|
||||
|
||||
Let's see how the following code can be refactored to use it:
|
||||
|
||||
```
|
||||
resp, err := netClient.Post(uri, "application/json; charset=utf-8", bytes.NewBuffer(payload))...
|
||||
```
|
||||
|
||||
The equivalent with passing ctx:
|
||||
|
||||
```
|
||||
req, err := http.NewRequestWithContext(ctx, "POST", uri, bytes.NewBuffer(payload))if err != nil { return err}req.Header.Set("Content-Type", "application/json; charset=utf-8")resp, err := netClient.Do(req)...
|
||||
```
|
||||
|
||||
The following techniques are necessary for more advanced use cases. For instance, if you are using a pool of workers or you have a chain of component dependencies that need to shutdown in order.
|
||||
|
||||
### Draining Worker Channels
|
||||
|
||||
When you have worker go routines that are consuming/producing from/to a channel, special care must be taken to make sure no items are left in the channels when the process shuts down. To do this we need to utilize go close method on the channel. Here's a great overview on [closing channels](https://gobyexample.com/closing-channels/), and a more [advanced article](https://go101.org/article/channel-closing.html/) on the topic.
|
||||
|
||||
Two things to remember about closing a channel:
|
||||
|
||||
- Writing to a close channel will result in a panic
|
||||
- When reading for a channel, you can use value, ok <- ch . Reading from a close channel will return all the buffered items. Once the buffer items are "drained", the channel will return zero value and ok will be false. *Note: While the channel still has items ok will be true.*
|
||||
- Alternative you can do a range on the channel for value := range ch { . In this case the for loop will stop when no more items are left on the channel and the channel is closed. This is much prettier than the approach above, but not always possible.
|
||||
|
||||
The points above conclude to the following:
|
||||
|
||||
- If you have a **single worker writing to the channel**, close the channel once you are done:
|
||||
|
||||
```
|
||||
go func() { defer close(ch) // close after write is no longer possible for { select { case <-ctx.Done(): return ... ch <- value // write to the channel only happens inside the loop }}()
|
||||
```
|
||||
|
||||
- If you have **multiple workers writing to the same channel**, close the channel after waiting for all workers to finish:
|
||||
|
||||
```
|
||||
g, gCtx := errgroup.WithContext(ctx)ch = make(...) // channel will be written from multiple workers for w := range workers { // create n number of workers g.Go(func() error { return w.Run(ctx, ch) // workers will publish })}g.Wait() // we need to wait for all workers to stopclose(ch) // and then close the channel
|
||||
```
|
||||
|
||||
- If you're reading from a channel, exit only when the channel has no more data. Essentially it's the responsibility of the writer to stop the readers, by closing the channel:
|
||||
|
||||
```
|
||||
for v := range ch {}// orfor { select { case v, ok <- ch: if !ok { // nothing left to read return; } foo(v) // process `v` normally case ...: ... }}
|
||||
```
|
||||
|
||||
- If a worker is both reading and writing, the worker should stop when the channel that it is reading from has no more data, and then close the writer.
|
||||
|
||||
## Graceful methods
|
||||
|
||||
We have seen several techniques so far for gracefully terminating a piece of long running code. It is also useful to examine how components can expose exported methods that can be called and then facilitate gracefully shutdown.
|
||||
|
||||
### Blocking with ctx
|
||||
|
||||
This is the most common approach and the easier to understand and implement.
|
||||
|
||||
- You call a method
|
||||
- You pass it a context
|
||||
- The method blocks
|
||||
- It returns in case of an error or when context is cancelled / timeout.
|
||||
|
||||
```
|
||||
// calling:err := srv.Run(ctx, ...)// implementationfunc (srv *Service) Run(ctx context.Context, ...) { ... ... for { ... select { case <- ctx.Done() return ctx.Err() // Depending on our business logic, // we may or may not want to return a ctx error: // https://pkg.go.dev/context#pkg-variables } }
|
||||
```
|
||||
|
||||
### Setup/Shutdown
|
||||
|
||||
There are cases when blocking with ctx code is not the best approach. This is the case when we want greater control over when .Shutdown happens. This approach is a bit more complex and there is also the danger of people forgetting to call .Shutdown.
|
||||
|
||||
#### Use case
|
||||
|
||||
The code bellow demonstrates why this pattern might be useful. We want to make sure that db Shutdown happens only after the Service is no longer running, because the Service is depending on the database to run for it to work.
|
||||
|
||||
By calling db.Shutdown() on defer, we ensure it runs after g.Wait returns:
|
||||
|
||||
```
|
||||
// calling:func () { err := db.Setup() // will not block defer db.Shutdown() svc := Service{ DB: db } g.Run(... svc.Run(ctx, ...) ) g.Wait()}
|
||||
```
|
||||
|
||||
#### Implementation example
|
||||
|
||||
```
|
||||
type Database struct { ... cancel func() wait func() err }func (db *Database) Setup() { // ... // ... ctx, cancel := context.WithCancel(context.Background()) g, gCtx := errgroup.WithContext(ctx) db.cancel = cancel db.wait = g.Wait for { ... select { case <- ctx.Done() return ctx.Err() // Depending on our business logic, // we may or may not want to return a ctx error: // https://pkg.go.dev/context#pkg-variables } }}func (db *Database) Shutdown() error { db.cancel() return db.wait()}
|
||||
```
|
||||
|
||||
## Final Thoughts
|
||||
|
||||
Terminating your long-running services gracefully is an important pattern that you will have to implement sooner or later. This is especially true for systems like RudderStack that act as middlewares where many connections to external services exist and high volumes of data are handled concurrently.
|
||||
|
||||
Go offers all the tools we need to implement this pattern, and selecting the right ones depends a lot on your use case. My intention for this post was to act as a guide to help choose the right tools for your case. If you have any questions, please reach out, and if you like solving problems like this check our [Careers page](https://boards.greenhouse.io/embed/job_board?for=rudderstack&b=https%3A%2F%2Frudderstack.com%2Fcareers/)!
|
||||
@@ -0,0 +1,692 @@
|
||||
---
|
||||
page-title: "Live website updates with Go, SSE, and htmx"
|
||||
url: https://threedots.tech/post/live-website-updates-go-sse-htmx/
|
||||
date: "2024-07-23 07:59:41"
|
||||
---
|
||||
In case you missed the memo, the Single Page Application hype period is over, and we’re now back to PHP and jQuery, I mean rendering HTML on the server. I’m excited! It brings me back to the early 2000s when we were all web developers, not frontend or backend engineers.
|
||||
|
||||
But there’s one thing I would miss from the SPA era: **live updates**. The classic websites often relied on the “refresh” button, which wasn’t that great. While polling for updates periodically is a solution, it’s inefficient. It’s much better to push updates to the client once they happen.
|
||||
|
||||
This post shows how to push live updates to your website using Go, Server-Sent Events (SSE), and htmx. As the example project, I use a tiny microblogging website where you can react to posts.
|
||||
|
||||
Below, you can see the embedded example in two “windows”. You can click on reactions and see them update in real-time in the other window. You will also see the reactions and views counters update as other readers interact with the posts. (You can open the example in a new tab [here](https://sse-example.threedots.tech/)).
|
||||
|
||||
## Server-Sent Events
|
||||
|
||||
WebSockets seem like the most popular option for pushing live updates from the HTTP server to the browser. Meanwhile, Server-Sent Events (SSE) is a great alternative. It is simple to set up and good enough for many use cases. It uses standard HTTP connections, so you don’t need a custom protocol. All modern browsers support SSE.
|
||||
|
||||
SSE endpoints work just like standard HTTP endpoints with a slight twist. You set the `Content-Type` header to `text/event-stream` and keep writing data in a text format like this:
|
||||
|
||||
```
|
||||
event: notifications
|
||||
data: {"unread_messages": 14}
|
||||
|
||||
event: message
|
||||
data: <h1>Hello,
|
||||
data: world!</h1>
|
||||
```
|
||||
|
||||
What follows the `event:` line is an optional event *type*, which can be any string you want. The multiline `data` field is the payload sent to the browser. Every “event” is separated by an extra new line. The specification mentions a few more things, but that’s all you need to start.
|
||||
|
||||
In Go, SSE endpoints are slightly different from `net/http` endpoints because you don’t just write data to the `ResponseWriter` and return from the function. Instead, you reply with the status code (`200 OK`) and keep writing the “events” in the format above. The connection stays alive until the client (the browser) closes it.
|
||||
|
||||
Here’s a complete example of sending back a “ping” event every 10 seconds.
|
||||
|
||||
```
|
||||
func main() {
|
||||
http.HandleFunc("/ping", func(w http.ResponseWriter, r *http.Request) {
|
||||
w.Header().Set("Content-Type", "text/event-stream")
|
||||
w.WriteHeader(http.StatusOK)
|
||||
|
||||
for {
|
||||
select {
|
||||
case <-r.Context().Done():
|
||||
return
|
||||
default:
|
||||
}
|
||||
|
||||
fmt.Fprintf(w, "data: ping\n\n")
|
||||
|
||||
if f, ok := w.(http.Flusher); ok {
|
||||
f.Flush()
|
||||
}
|
||||
|
||||
time.Sleep(10 * time.Second)
|
||||
}
|
||||
})
|
||||
|
||||
http.ListenAndServe(":8080", nil)
|
||||
}
|
||||
```
|
||||
|
||||
Two things are worth mentioning here.
|
||||
|
||||
- To avoid buffering, we use the `http.Flusher` to send the response immediately.
|
||||
- To exit the infinite loop, we check if the request’s context is done.
|
||||
|
||||
On the client side, you can handle it like this:
|
||||
|
||||
```
|
||||
<script>
|
||||
const es = new EventSource("http://localhost:8080/ping");
|
||||
es.onmessage = (event) => {
|
||||
console.log(`Received: ${event.data}`);
|
||||
};
|
||||
</script>
|
||||
```
|
||||
|
||||
Most online tutorials end here and wish you happy coding. Perhaps it’s good enough if you want to create a demo project in one afternoon. But the example is far from something you would use in production. I don’t want you to read this post, then go back to your project and think, “Uhh, so what do I do now?”
|
||||
|
||||
If you follow our blog, you know we like to focus on real-world examples. Let’s see how to use SSE in a more complex scenario — the microblog example you saw at the top of this page. It’s not quick and easy, and there are many things to consider, but it should make you comfortable enough to use a similar mechanism in your projects.
|
||||
|
||||
Don't miss new posts.
|
||||
Join over 15k subscribers of our newsletter and get a [**free e-book**](https://threedots.tech/go-with-the-domain/)!
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
## Go With The Domain Three Dots Labs
|
||||
|
||||
|
||||
|
||||
](https://threedots.tech/go-with-the-domain/)
|
||||
|
||||
🔒 We do not send spam. You can unsubscribe at any time!
|
||||
|
||||
## The Microblog Example
|
||||
|
||||
The core component of the example is a “post”. The key feature is that the reactions and views are updated in real-time as other users interact with the post.
|
||||
|
||||
In this example, we’ll render HTML on the server side, using no JavaScript code for interactivity except the htmx library.
|
||||
|
||||
The complete example is on [GitHub](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples/real-world-examples/server-sent-events-htmx). You can run it locally using docker-compose.
|
||||
|
||||
### JSON API Example
|
||||
|
||||
For another example featuring a Twitter-like web app, see the [server-sent-events](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples/real-world-examples/server-sent-events) example on the Watermill repository. It shows a similar approach using a Single Page Application with Vue.js and a JSON API.
|
||||
|
||||
### Tools used
|
||||
|
||||
Here’s the stack I use in the example. I won’t dive deep into all the components, but I’ll mention them briefly here.
|
||||
|
||||
- [**Echo**](https://echo.labstack.com/) — a lightweight HTTP router I like for error handling that is simpler than in `net/http`.
|
||||
- [**templ**](https://templ.guide/) — an HTML templates library based on code generation. It can get weird at times, but overall, I’m happy with it and like it more than `html/template`. It’s best used together with an IDE plugin.
|
||||
- [**htmx**](https://htmx.org/) — a library for using AJAX and SSE with no need to write JavaScript.
|
||||
- [**Watermill**](https://watermill.io/) — an event-driven library we maintain for working with messages.
|
||||
- **PostgreSQL** and **Google Cloud Pub/Sub** for storage and messaging infrastructure. (You can choose a different Pub/Sub for messaging, even Postgres.)
|
||||
|
||||
## Deciding what and when to push
|
||||
|
||||
When designing an SSE endpoint, you must decide *what* the payload should be, *when* to send an update, and to *whom* to send it.
|
||||
|
||||
### What
|
||||
|
||||
The payload is just text, and it’s up to you how to encode it. It can be a regular JSON API response or an HTML you would embed directly on the website. Remember that each line should have the `data:` prefix, and the payload needs to end with two new lines (`\n\n`).
|
||||
|
||||
### When
|
||||
|
||||
You need a way to know when something changes in your application so you can push the updates. For example, if the user receives a message, you show a red bubble in the UI.
|
||||
|
||||
The SSE endpoints are long-running, so you may have hundreds or thousands of goroutines running in the background that you must notify of the change. In reaction, each should send an event to the client. Since you’re likely running more than one instance of your service, this can’t work in memory.
|
||||
|
||||
|
||||
|
||||
### To Whom
|
||||
|
||||
You often only want to notify some users of something that happened. If I send you a message, I expect a notification to appear on your screen, but not for anyone else. So, you need a way to filter what happens and choose who should get the update (and which SSE endpoints to trigger).
|
||||
|
||||
|
||||
|
||||
In this example, it goes as follows:
|
||||
|
||||
- **What:** the post “stats” model, including the numbers of views and reactions as HTML.
|
||||
- **When:** when someone sees the post or reacts to it.
|
||||
- **To Whom:** everyone who sees the updated post. Other posts are not updated.
|
||||
|
||||
|
||||
|
||||
## Implementing SSE Endpoints
|
||||
|
||||
While you absolutely can create SSE endpoints from scratch (or with a library), and it’s not that complex, the hard part is triggering the updates in reaction to something that happened. (And doing this over the network since running a single service instance rarely happens in production.) As with running an HTTP server, **you don’t want to reinvent the wheel here.**
|
||||
|
||||
We usually approach anything events-related with [Watermill](https://watermill.io/). It’s a Go library we maintain that abstracts away the low-level details of Pub/Subs. (Getting close to 7k GitHub stars ⭐️). You can use it with any existing codebase as it’s not a framework but a lightweight library (just like htmx). It supports many Pub/Subs, so it’s easy to start with the infrastructure you already have (even an SQL database).
|
||||
|
||||
### Watermill Primer
|
||||
|
||||
(Feel free to skip this part if you’re already familiar with Watermill.)
|
||||
|
||||
The [documentation](https://watermill.io/) goes in-depth on how Watermill works. Below is a TL;DR version.
|
||||
|
||||
First, you need a **Pub/Sub** — a system that lets you work with messages across the network (also known as a “message broker” or a “queue”). Common picks are Kafka or RabbitMQ, but it could just as well be an SQL database.
|
||||
|
||||
Watermill abstracts away all Pub/Subs into two interfaces:
|
||||
|
||||
```
|
||||
type Publisher interface {
|
||||
Publish(topic string, messages ...*Message) error
|
||||
Close() error
|
||||
}
|
||||
|
||||
type Subscriber interface {
|
||||
Subscribe(ctx context.Context, topic string) (<-chan *Message, error)
|
||||
Close() error
|
||||
}
|
||||
```
|
||||
|
||||
You can `Publish` messages and `Subscribe` to them. There’s always a `topic` involved — a string that decides who gets the message.
|
||||
|
||||
Here’s basic Watermill architecture in one picture:
|
||||
|
||||
|
||||
|
||||
The core part of Watermill is the `Message`. It is what the `Request` is for the `net/http` package. The simplest message has just an optional ID and a payload. The payload is a slice of bytes, so you can use any marshaling you want (JSON, Protocol Buffers, plain strings, etc.).
|
||||
|
||||
```
|
||||
msg := message.NewMessage(watermill.NewUUID(), []byte("Hello, world!"))
|
||||
```
|
||||
|
||||
While all Watermill’s components are based on the `Publisher` and `Subscriber` interfaces, using them directly is a relatively low-level API. In this example, we’ll use the CQRS component of Watermill, which is a higher-level API. It’s based on the same ideas but removes some boilerplate, like serialization and deserialization. We’ll use the `EventBus` to publish events and `EventProcessor` to subscribe to them.
|
||||
|
||||
## High-level architecture overview
|
||||
|
||||

|
||||
|
||||
We want to publish two events:
|
||||
|
||||
- `PostViewed` is published when someone sees the post.
|
||||
- `PostReactionAdded` is published when someone reacts to a post.
|
||||
|
||||
Each will have an event handler that updates the post’s stats in the database. (A similar concept as an HTTP handler.) The handlers should also publish the `PostStatsUpdated` event. We will use it to trigger the SSE updates.
|
||||
|
||||
## Publishing events
|
||||
|
||||
First, let’s create a publisher. I use Google Cloud Pub/Sub Publisher, but it can be swapped with any other publisher supported by Watermill. All the configuration needs is a project ID.
|
||||
|
||||
*(Note that Google Cloud Pub/Sub is just one the Pub/Subs Watermill supports. You could easily change this to [another supported Pub/Sub](https://watermill.io/pubsubs/). Kind of like an ORM would work with MySQL, PostgreSQL, and SQLite.)*
|
||||
|
||||
```
|
||||
logger := watermill.NewStdLogger(false, false)
|
||||
|
||||
publisher, err := googlecloud.NewPublisher(
|
||||
googlecloud.PublisherConfig{
|
||||
ProjectID: cfg.PubSubProjectID,
|
||||
},
|
||||
logger,
|
||||
)
|
||||
```
|
||||
|
||||
Publisher works with messages, meaning you must marshal events (structs) into bytes and choose what topics to publish them to. It’s very common to use the same marshaling for all events and topics that follow some convention, like the event name being part of them.
|
||||
|
||||
We will use the `EventBus` component to simplify the publishing API. You can think of it as a high-level wrapper on the publisher (as you can see, it’s the first argument). You pass the configuration options once and then can publish events with a single method call.
|
||||
|
||||
```
|
||||
eventBus, err := cqrs.NewEventBusWithConfig(
|
||||
publisher,
|
||||
cqrs.EventBusConfig{
|
||||
GeneratePublishTopic: func(params cqrs.GenerateEventPublishTopicParams) (string, error) {
|
||||
return params.EventName, nil
|
||||
},
|
||||
Marshaler: cqrs.JSONMarshaler{},
|
||||
Logger: logger,
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
The configuration takes a `Marshaler`, so we use the `cqrs.JSONMarshaler{}` (all messages will be marshaled to JSON).
|
||||
|
||||
The `GeneratePublishTopic` function returns the topic’s name based on the available parameters. Instead of passing a topic directly to `Publish,` we define this function to determine the topic based on the message. The `EventBus` calls this function every time a message is published. In this case, we’ll use the `params.EventName`. So, if you consider a struct like this:
|
||||
|
||||
```
|
||||
type PostViewed struct {
|
||||
PostID int `json:"post_id"`
|
||||
}
|
||||
```
|
||||
|
||||
It will be published on the `PostViewed` topic. (The chosen marshaler provides a way to extract the event name).
|
||||
|
||||
Publishing events using the event bus is trivial. Thanks to the setup of marshaler and `GeneratePublishTopic`, we pass the event struct to `Publish`, and the rest happens behind the scenes. In the HTTP handler, we can use something like this:
|
||||
|
||||
```
|
||||
event := PostViewed{
|
||||
PostID: post.ID,
|
||||
}
|
||||
|
||||
err = h.eventBus.Publish(ctx, event)
|
||||
```
|
||||
|
||||
## Subscribing to events
|
||||
|
||||
I decided to make the HTTP endpoints just publish the events. The event handlers update the post’s stats in the database asynchronously. This way, the client doesn’t need to wait for the changes to be applied, and the view will be eventually updated via SSE.
|
||||
|
||||
We need two event handlers to update the stats in the database. The first updates the views count, and the second updates the reactions count.
|
||||
|
||||
The CQRS component used for subscribing to events is the `EventProcessor`. As with the `EventBus`, some setup needs to be done initially. But thanks to this, writing the handlers later will be very pleasant. The idea behind it is similar to the `EventBus`, but it’s the other way around.
|
||||
|
||||
First, create a Router. It’s a similar concept to the HTTP routers you’re familiar with. The component runs in the background and routes messages to handlers.
|
||||
|
||||
```
|
||||
router, err := message.NewRouter(message.RouterConfig{}, logger)
|
||||
```
|
||||
|
||||
Similarly to HTTP routers, Watermill’s router supports middlewares. For example, you can add the `Recoverer` middleware so panics in handlers don’t blow up your server.
|
||||
|
||||
```
|
||||
router.AddMiddleware(middleware.Recoverer)
|
||||
```
|
||||
|
||||
Now we can create the EventProcessor.
|
||||
|
||||
```
|
||||
eventProcessor, err := cqrs.NewEventProcessorWithConfig(
|
||||
router,
|
||||
cqrs.EventProcessorConfig{
|
||||
GenerateSubscribeTopic: func(params cqrs.EventProcessorGenerateSubscribeTopicParams) (string, error) {
|
||||
return params.EventName, nil
|
||||
},
|
||||
SubscriberConstructor: func(params cqrs.EventProcessorSubscriberConstructorParams) (message.Subscriber, error) {
|
||||
return googlecloud.NewSubscriber(
|
||||
googlecloud.SubscriberConfig{
|
||||
ProjectID: cfg.PubSubProjectID,
|
||||
GenerateSubscriptionName: func(topic string) string {
|
||||
return fmt.Sprintf("%v_%v", topic, params.HandlerName)
|
||||
},
|
||||
},
|
||||
logger,
|
||||
)
|
||||
},
|
||||
Marshaler: cqrs.JSONMarshaler{},
|
||||
Logger: logger,
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
The first argument is the router. It’s similar to how the `EventBus` “wrapped” the publisher.
|
||||
|
||||
Then comes the config. The `Marshaler` and `GenerateSubscribeTopic` are the same concepts as in the `EventBus`. The only difference is they come at the other end of the Pub/Sub. In the `EventBus`, the marshaler marshals the message, and the function decides to which topic to publish it. Here, the `Marshaler` unmarshals the message back on the struct, and `GenerateSubscribeTopic` decides to which topic to subscribe to.
|
||||
|
||||
`SubscriberConstructor` is what the name says: it returns a new `Subscriber`. You may wonder, why not use a single subscriber, as we did with the `publisher` in the `EventBus`?
|
||||
|
||||
Publishing messages is straightforward: you marshal a struct, send the bytes to a topic, and you’re done. Subscribing is where things get more interesting. For example, you run two replicas of the same service. How do you ensure that only one replica receives a message from the Pub/Sub?
|
||||
|
||||
The strategy depends on the Pub/Sub. In Google Cloud Pub/Sub, you use a single “subscription” bound to a topic and share it among the replicas. That’s why having a subscriber constructor is helpful in this context. It allows us to specify what subscription to use for each event type. In this example, the subscription joins the topic name with the handler name. For example, `PostViewed_UpdateViews`.
|
||||
|
||||
|
||||
|
||||
As promised, with the setup done, adding message handlers is quite simple. Note that the functions are generic (with inferred types), so you work with strongly typed events! The handler name is used to generate the subscription name, so it needs to be unique within handlers.
|
||||
|
||||
```
|
||||
err = eventProcessor.AddHandlers(
|
||||
cqrs.NewEventHandler(
|
||||
"UpdateViews",
|
||||
func(ctx context.Context, event *PostViewed) error {
|
||||
return repo.UpdatePost(ctx, event.PostID, func(post *Post) {
|
||||
post.Views++
|
||||
})
|
||||
},
|
||||
),
|
||||
cqrs.NewEventHandler(
|
||||
"UpdateReactions",
|
||||
func(ctx context.Context, event *PostReactionAdded) error {
|
||||
return repo.UpdatePost(ctx, event.PostID, func(post *Post) {
|
||||
post.Reactions[event.ReactionID]++
|
||||
})
|
||||
},
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
### Be careful when refactoring
|
||||
|
||||
The names used for creating the topics and subscriptions are essential. If they were accidentally changed, you could lose messages.
|
||||
|
||||
You should not change the event or handler names once they’re running in production. If you need to, consider creating a new event or handler. For example, `PostViewedV2`.
|
||||
|
||||
The last part is running the router, just like you would run an HTTP server.
|
||||
|
||||
```
|
||||
go func() {
|
||||
err := router.Run(context.Background())
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
}()
|
||||
```
|
||||
|
||||
### Publishing PostStatsUpdated
|
||||
|
||||
We’ll use one more event to trigger the SSE updates: `PostStatsUpdated`. It includes the post’s ID and a record of what has been updated (views or the reaction ID).
|
||||
|
||||
```
|
||||
type PostStatsUpdated struct {
|
||||
PostID int `json:"post_id"`
|
||||
ViewsUpdated bool `json:"views_updated"`
|
||||
ReactionUpdated *string `json:"reaction_updated"`
|
||||
}
|
||||
```
|
||||
|
||||
Since the release of this post, I realized the naive approach of getting the post from the database on each update doesn’t scale well (hundreds of `SELECT` queries on each update, depending on how many visitors we have). I’ve updated the example so the `PostStatsUpdated` event includes all stats. This way, the SSE endpoint doesn’t need to query the database at all, except for the initial call. You can see how big was the impact on the database load.
|
||||
|
||||
|
||||
|
||||
I left the original version in the code snippets for simplicity. You can see the changes on [GitHub](https://github.com/ThreeDotsLabs/watermill/commit/0ea2d2de47d9c83ef85791a17822cc058ea54de2).
|
||||
|
||||
After updating the post, both handlers should publish the `PostStatsUpdated` event.
|
||||
|
||||
```
|
||||
err = eventProcessor.AddHandlers(
|
||||
cqrs.NewEventHandler(
|
||||
"UpdateViews",
|
||||
func(ctx context.Context, event *PostViewed) error {
|
||||
err = repo.UpdatePost(ctx, event.PostID, func(post *Post) {
|
||||
post.Views++
|
||||
})
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
statsUpdated := PostStatsUpdated{
|
||||
PostID: event.PostID,
|
||||
ViewsUpdated: true,
|
||||
}
|
||||
|
||||
return eventBus.Publish(ctx, statsUpdated)
|
||||
},
|
||||
),
|
||||
cqrs.NewEventHandler(
|
||||
"UpdateReactions",
|
||||
func(ctx context.Context, event *PostReactionAdded) error {
|
||||
err := repo.UpdatePost(ctx, event.PostID, func(post *Post) {
|
||||
post.Reactions[event.ReactionID]++
|
||||
})
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
statsUpdated := PostStatsUpdated{
|
||||
PostID: event.PostID,
|
||||
ReactionUpdated: &event.ReactionID,
|
||||
}
|
||||
|
||||
return eventBus.Publish(ctx, statsUpdated)
|
||||
},
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
## SSE Router
|
||||
|
||||
It’s time to implement the SSE endpoints. Watermill also provides an SSE component that works well with other internals.
|
||||
|
||||
The main component is called SSE Router, and the idea behind it is pretty simple. When you call its `AddHandler` method, it subscribes to the given topic in the configured subscriber. The method returns a regular HTTP handler you can use with any HTTP router you want. Whenever a message appears in the chosen topic, it will be propagated in a fan-out fashion to all running SSE endpoints within.
|
||||
|
||||
|
||||
|
||||
First, let’s create the `SSERouter` (it comes from the [watermill-http](https://github.com/ThreeDotsLabs/watermill-http) package — use the `v2` version!).
|
||||
|
||||
The config requires an `UpstreamSubscriber`: you need to subscribe to a Pub/Sub that contains the events. We use Google Cloud Pub/Sub again. I’ll explain the details of the configuration a bit later.
|
||||
|
||||
We use a string marshaler as we’re going to return plain HTML.
|
||||
|
||||
```
|
||||
subscriber, err := googlecloud.NewSubscriber(googlecloud.SubscriberConfig{
|
||||
// ...
|
||||
}, logger)
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
|
||||
sseRouter, err := http.NewSSERouter(http.SSERouterConfig{
|
||||
UpstreamSubscriber: subscriber,
|
||||
Marshaler: http.StringSSEMarshaler{},
|
||||
}, logger)
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
```
|
||||
|
||||
Then, you need to implement the `StreamAdapter` interface:
|
||||
|
||||
```
|
||||
type StreamAdapter interface {
|
||||
InitialStreamResponse(w http.ResponseWriter, r *http.Request) (response interface{}, ok bool)
|
||||
NextStreamResponse(r *http.Request, msg *message.Message) (response interface{}, ok bool)
|
||||
}
|
||||
```
|
||||
|
||||
These two methods are very similar. The first one is how you respond to the initial HTTP request. If needed, it lets you return an error and write it to the `ResponseWriter`. This is important because as soon as you write any data, it’s too late to change the response code or the headers. So, `InitialStreamResponse` is where you handle things like validation or authentication. If any errors happen, return `ok` equal `false` to stop the handler. Otherwise, what you return becomes the first event sent to the client.
|
||||
|
||||
`NextStreamResponse` is called for each incoming `Message`. You can return a `response` to be sent to the SSE clients that use this endpoint. Or you can skip the message (again, return `ok` equal `false`).
|
||||
|
||||
By default, whatever you return as the `response` is marshaled to JSON with event type `data`. You can override this with a custom marshaler, as we did here. You can also return the `ServerSentEvent` struct, which lets you explicitly specify the `Event` and `Data` fields.
|
||||
|
||||
In our case, `InitialStreamResponse` simply returns the post’s response.
|
||||
|
||||
```
|
||||
func (s *statsStream) InitialStreamResponse(w http.ResponseWriter, r *http.Request) (response interface{}, ok bool) {
|
||||
postIDStr := r.PathValue("id")
|
||||
postID, err := strconv.Atoi(postIDStr)
|
||||
if err != nil {
|
||||
w.WriteHeader(http.StatusBadRequest)
|
||||
w.Write([]byte("invalid post ID"))
|
||||
return nil, false
|
||||
}
|
||||
|
||||
resp, err := s.getResponse(r.Context(), postID, nil)
|
||||
if err != nil {
|
||||
w.WriteHeader(http.StatusInternalServerError)
|
||||
w.Write([]byte(err.Error()))
|
||||
return nil, false
|
||||
}
|
||||
|
||||
return resp, true
|
||||
}
|
||||
```
|
||||
|
||||
`NextStreamResponse` is similar, but it also checks if the post’s ID in the event matches the one in the URL. If not, it skips the message. It means a post has been updated, but not the one this endpoint returns.
|
||||
|
||||
```
|
||||
func (s *statsStream) NextStreamResponse(r *http.Request, msg *message.Message) (response interface{}, ok bool) {
|
||||
postIDStr := r.PathValue("id")
|
||||
postID, err := strconv.Atoi(postIDStr)
|
||||
if err != nil {
|
||||
fmt.Println("invalid post ID")
|
||||
return nil, false
|
||||
}
|
||||
|
||||
var event PostStatsUpdated
|
||||
err = json.Unmarshal(msg.Payload, &event)
|
||||
if err != nil {
|
||||
fmt.Println("cannot unmarshal: " + err.Error())
|
||||
return "", false
|
||||
}
|
||||
|
||||
if event.PostID != postID {
|
||||
return "", false
|
||||
}
|
||||
|
||||
resp, err := s.getResponse(r.Context(), postID, &event)
|
||||
if err != nil {
|
||||
fmt.Println("could not get response: " + err.Error())
|
||||
return nil, false
|
||||
}
|
||||
|
||||
return resp, true
|
||||
}
|
||||
```
|
||||
|
||||
As you can see, there’s no usual error handling here. The best we can do is log the error and return `false` to skip the message. The handler already replied with `200 OK`, so it’s too late to change the status code. Alternatively, we could return a custom response with the error message to be displayed to the user.
|
||||
|
||||
With the stream adapter ready, we can create a handler on the SSE Router:
|
||||
|
||||
```
|
||||
statsHandler := sseRouter.AddHandler("PostStatsUpdated", &statsStream{repo: repo})
|
||||
```
|
||||
|
||||
The first argument here is the `topic` to listen to. The returned value is a ready-to-use `http.HandlerFunc`.
|
||||
|
||||
Most HTTP libraries and frameworks are compatible with `net/http`, so you can use it with whatever HTTP router you like. I use echo, so there’s a small conversion of the path value needed:
|
||||
|
||||
```
|
||||
e.GET("/posts/:id/stats", func(c echo.Context) error {
|
||||
postID := c.Param("id")
|
||||
c.Request().SetPathValue("id", postID)
|
||||
|
||||
statsHandler(c.Response(), c.Request())
|
||||
return nil
|
||||
})
|
||||
```
|
||||
|
||||
Finally, you need to run the SSE router in a separate goroutine:
|
||||
|
||||
```
|
||||
go func() {
|
||||
err := sseRouter.Run(context.Background())
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
}()
|
||||
```
|
||||
|
||||
And that’s it! Whenever a message is published on the `PostStatsUpdated` topic, the SSE Router propagates it to all clients listening to the `GET /posts/:id/stats` endpoint.
|
||||
|
||||
The handlers created by the SSE Router already handle all implementation details, so you don’t need to worry about setting the headers.
|
||||
|
||||
When called without an `Accept` header or with a value other than `text/event-stream`, the handlers act as regular GET handlers, returning the response from `InitialStreamResponse`. Creating an `EventStream` in JavaScript automatically passes the header for you, but keep this in mind when debugging your endpoints with a tool like `curl`!
|
||||
|
||||
```
|
||||
# Regular HTTP response
|
||||
curl localhost:8080/posts/1/stats
|
||||
|
||||
# SSE response
|
||||
curl -H "Accept: text/event-stream" localhost:8080/posts/1/stats
|
||||
```
|
||||
|
||||
### Configuring the Subscriber
|
||||
|
||||
Remember the part that we want each event to be processed only by one service replica at a time? In the case of events used for SSE, you need a counterintuitive approach: all subscribers need to process each event, as the SSE endpoints will be running across all of your service instances.
|
||||
|
||||
|
||||
|
||||
In other words, in this case, each replica should have its own subscription that’s not shared with anyone. For Google Cloud Pub/Sub, an easy way to do it is to generate a unique subscription name on the service’s startup. For example, using a “short UUID” would generate subscription names like `PostStatsUpdated_lkcNowPZ99M123xPwqcxp1`.
|
||||
|
||||
Keep in mind this can have some impact on your Pub/Sub. For example, when using Google Cloud Pub/Sub, it’s best to set the expiration policy for such subscriptions for one day, so they’re deleted when no longer used. There’s a hard limit of 10,000 subscriptions; you could quickly hit it this way.
|
||||
|
||||
```
|
||||
subscriber, err := googlecloud.NewSubscriber(
|
||||
googlecloud.SubscriberConfig{
|
||||
ProjectID: cfg.PubSubProjectID,
|
||||
GenerateSubscriptionName: func(topic string) string {
|
||||
return fmt.Sprintf("%v_%v", topic, watermill.NewShortUUID())
|
||||
},
|
||||
SubscriptionConfig: pubsub.SubscriptionConfig{
|
||||
ExpirationPolicy: time.Hour * 24,
|
||||
},
|
||||
},
|
||||
logger,
|
||||
)
|
||||
```
|
||||
|
||||
If that sounds like a lot to consider, it’s because there is! Running production-grade Event-Driven systems comes with many advantages, but it’s not trivial. That’s why I go into detail here, so you know what to expect in production, not just in toy examples. (If that sounds like something you’d like to learn in-depth, see our [Go Event-Driven training](https://threedots.tech/event-driven/).)
|
||||
|
||||
## htmx
|
||||
|
||||
The last piece of the puzzle is the client-side code.
|
||||
|
||||
In the example, we use htmx, a library that lets you make AJAX requests with HTML attributes. It also supports SSE with an extension. The templating in the snippets below comes from templ.
|
||||
|
||||
```
|
||||
<div hx-ext="sse" sse-connect={ "/posts/" + post.ID + "/stats" } sse-swap="data"></div>
|
||||
```
|
||||
|
||||
The `sse-swap` attribute is the event type to look for from the stream. By default, Watermill’s SSE endpoints use `data`, so that’s what we use. Every time an event is received from the `/posts/:id/stats` endpoint, its payload will be injected inside the div. (Remember, our events are HTML.)
|
||||
|
||||
We also use htmx to send the reaction form asynchronously (a classic POST AJAX request). In this case, we use `hx-swap="outerHTML"`, which replaces the entire form with the response from the server. It’s a button with a ✅ “check” suggesting that the reaction has been added. The SSE will eventually update the stats. (Although there might be a slight delay. If you care about UX, returning a “fake” number increase could make sense here.)
|
||||
|
||||
```
|
||||
<form hx-post={ "/posts/" + postID + "/reactions"} hx-swap="outerHTML">
|
||||
<input type="hidden" name="reaction_id" value={ reaction.ID } />
|
||||
<button type="submit" class={"btn", "btn-outline-secondary", "m-1", templ.KV("animated", reaction.JustChanged)}>
|
||||
<span class="emoji">{ reaction.Label }</span>
|
||||
<span class="counter">{ reaction.Count }</span>
|
||||
</button>
|
||||
</form>
|
||||
```
|
||||
|
||||
### Animations
|
||||
|
||||
If you’re used to working with Single Page Applications, using htmx might initially feel weird. For example, consider animating an element that has just been updated. In a classic SPA, you would get the JSON response from the SSE endpoint, compare the values with what’s in the “model”, and decide whether to animate the element.
|
||||
|
||||
While htmx allows for “hooks” after the request is done, it’s probably not what you want. Instead, you need to adjust your mental model a bit. The server code is the source of truth in this setup. There is no “client” that decides how to display things.
|
||||
|
||||
In this example, I use a CSS class to mark the updated element. The class includes an animation that pops up the element for a moment. The server code decides whether to add the class or not (based on the data in the incoming event). (`templ.KV` is how you add a class conditionally using templ. It will be present if `stats.Views.JustChanged` is true.)
|
||||
|
||||
```
|
||||
<div class={ "d-flex", "align-items-center", templ.KV("animated", stats.Views.JustChanged)}>
|
||||
<span class="me-1">👁️</span>
|
||||
<small class="text-muted">{ stats.Views.Count + " views" }</small>
|
||||
</div>
|
||||
```
|
||||
|
||||
## Other things to consider
|
||||
|
||||
### Two kinds of SSE endpoints
|
||||
|
||||
How you return events from SSE endpoints is totally up to you. Here are two ways that make sense in different scenarios.
|
||||
|
||||
1. An endpoint that returns the same data model initially and on every update. With each triggered update, you kind of “refresh” the model, perhaps embedded on the website. This is what we use in the example above.
|
||||
2. An endpoint that returns nothing initially and then keeps sending unique updates as they happen. You can append each new event to some list, for example. It’s how you would implement notifications or a web chat.
|
||||
|
||||
### At-least-once delivery
|
||||
|
||||
When working with virtually any Pub/Sub, you must be aware of the “at-least-once” delivery guarantee. You may receive the same message twice because of network issues or your server going down at the wrong moment.
|
||||
|
||||
Don’t try to work around this. Instead, embrace that this can happen and design your handlers to be *idempotent*. It means that processing the message twice (or more) has the same effect as processing it once.
|
||||
|
||||
In the example above, we don’t guard against it. If the same message was processed twice, it would add an extra view or reaction in the database. It’s not a big deal in this case, and we can live with it. One way to prevent it would be to store the processed message IDs in the database and check it on each update.
|
||||
|
||||
### Watch out for HTTP/1.1
|
||||
|
||||
In modern browsers, there’s a limit of 6 open connections per server over HTTP/1.1, which can be a big issue when using SSE. Your website won’t work well if someone opens it in several tabs.
|
||||
|
||||
For best results, use SSE with HTTP/2 where this limit doesn’t apply. Most modern web servers support HTTP/2, so make sure you enable it.
|
||||
|
||||
## Local environment tricks
|
||||
|
||||
Here are two tips unrelated to SSE that might be useful for running your app locally.
|
||||
|
||||
### Mounting /go/pkg and go cache
|
||||
|
||||
In the docker-compose definition, you can mount the `/go/pkg` and `/go-cache` directories to speed up the build process. This way, you don’t have to download the dependencies whenever you rebuild the container.
|
||||
|
||||
```
|
||||
services:
|
||||
server:
|
||||
# ...
|
||||
volumes:
|
||||
- go_pkg:/go/pkg
|
||||
- go_cache:/go-cache
|
||||
|
||||
volumes:
|
||||
go_pkg:
|
||||
go_cache:
|
||||
```
|
||||
|
||||
### Reflex for regenerating templ and rebuilding the server
|
||||
|
||||
[Reflex](https://github.com/cespare/reflex) is my go-to tool for live code reloading. (See [my post on the dev environment setup](https://threedots.tech/post/go-docker-dev-environment-with-go-modules-and-live-code-reloading/).) When working with templ, you can use a configuration like the one below to regenerate the templates and rebuild the server after every change.
|
||||
|
||||
It’s a great way to speed up your development process, so you don’t need to keep switching between code, the terminal, and the browser.
|
||||
|
||||
```
|
||||
-r '(\.go$|go\.mod$)' -s go run .
|
||||
-r '\.templ$' templ generate
|
||||
```
|
||||
|
||||
## Go build something!
|
||||
|
||||
That should be all the theory you need to build something cool. If you have any questions, let me know in the comments.
|
||||
|
||||
Once again, the complete source code is on [GitHub](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples/real-world-examples/server-sent-events-htmx) You can run it locally with `docker-compose up`.
|
||||
|
||||
Give this stack a try; I had lots of fun working with it. Good luck!
|
||||
+937
@@ -0,0 +1,937 @@
|
||||
---
|
||||
page-title: "The Go libraries that never failed us: 22 libraries you need to know"
|
||||
url: https://threedots.tech/post/list-of-recommended-libraries/
|
||||
date: "2024-07-23 08:01:03"
|
||||
---
|
||||
Did you have a situation when you lost a ton of time finding a Go library for your need? In theory, you can check lists like [Awesome Go](https://github.com/avelino/awesome-go) or make a choice based on GitHub stars. But Awesome Go contains over 2600 libraries, and popularity is not always the best indicator of library quality. **I often thought that it would be great to have a place where I could find just the best and battle-tested libraries I could use in my project.** Because we didn’t find such a place with Miłosz, we decided to create it.
|
||||
|
||||

|
||||
|
||||
Based on our experience leading multiple Go teams and working on various projects, including complex financial, health, and security, we will recommend tools that could work well for different projects.
|
||||
|
||||
In addition to providing a list of libraries, we also want to show you some non-obvious uses for those tools and libraries. However, it’s important to note that most of these tools can be misused. We’ve included some common anti-patterns to help you avoid making those mistakes.
|
||||
|
||||
This list is intended to be opinionated. **We only wanted to include libraries we used on real production systems. Thanks to that, we recommend just libraries that we are 100% sure about.** Unfortunately, our day is limited to 24 hours, so checking all available libraries is impossible.
|
||||
|
||||
**If you know of any libraries we should include on this list, please let us know in the comments!** We will continue to update the list with new findings over time.
|
||||
|
||||
Table of Contents
|
||||
|
||||
1. [HTTP](https://threedots.tech/post/list-of-recommended-libraries/#http)
|
||||
1. [Routers](https://threedots.tech/post/list-of-recommended-libraries/#routers)
|
||||
1. [Echo](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-echo-githubhttpsgithubcomlabstackecho-docshttpsecholabstackcomguide-exampleshttpsecholabstackcomcookbook) [\[GitHub\]](https://github.com/labstack/echo) [\[Docs\]](https://echo.labstack.com/guide/) [\[Examples\]](https://echo.labstack.com/cookbook/)
|
||||
2. [chi](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-chi-githubhttpsgithubcomgo-chichi-docshttpspkggodevgithubcomgo-chichi-exampleshttpsgithubcomgo-chichitreemaster_examples) [\[GitHub\]](https://github.com/go-chi/chi) [\[Docs\]](https://pkg.go.dev/github.com/go-chi/chi) [\[Examples\]](https://github.com/go-chi/chi/tree/master/_examples)
|
||||
2. [Middlewares](https://threedots.tech/post/list-of-recommended-libraries/#middlewares)
|
||||
3. [Serving static content](https://threedots.tech/post/list-of-recommended-libraries/#serving-static-content)
|
||||
4. [OpenAPI](https://threedots.tech/post/list-of-recommended-libraries/#openapi)
|
||||
5. [Generating Go server and clients](https://threedots.tech/post/list-of-recommended-libraries/#generating-go-server-and-clients)
|
||||
1. [deepmap/oapi-codegen](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-deepmapoapi-codegen-githubhttpsgithubcomdeepmapoapi-codegen-docshttpsgithubcomdeepmapoapi-codegenreadme-examplehttpsthreedotstechpostserverless-cloud-run-firebase-modern-go-applicationpublic-http-api) [\[GitHub\]](https://github.com/deepmap/oapi-codegen) [\[Docs\]](https://github.com/deepmap/oapi-codegen#readme) [\[Example\]](https://threedots.tech/post/serverless-cloud-run-firebase-modern-go-application/#public-http-api)
|
||||
6. [Bonus: Client for JavaScript/TypeScript](https://threedots.tech/post/list-of-recommended-libraries/#bonus-client-for-javascripttypescript)
|
||||
1. [openapi-generator-cli](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-openapi-generator-cli-githubhttpsgithubcomopenapitoolsopenapi-generator-cli-docshttpsgithubcomopenapitoolsopenapi-generator-clireadme) [\[GitHub\]](https://github.com/OpenAPITools/openapi-generator-cli) [\[Docs\]](https://github.com/OpenAPITools/openapi-generator-cli#readme)
|
||||
2. [Alternative types of communication](https://threedots.tech/post/list-of-recommended-libraries/#alternative-types-of-communication)
|
||||
1. [gRPC](https://threedots.tech/post/list-of-recommended-libraries/#grpc)
|
||||
1. [protoc](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-protoc-docshttpsgrpciodocs) [\[Docs\]](https://grpc.io/docs/)
|
||||
2. [Messaging](https://threedots.tech/post/list-of-recommended-libraries/#messaging)
|
||||
1. [Watermill](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-watermill-githubhttpsgithubcomthreedotslabswatermill-docshttpswatermillio-exampleshttpsgithubcomthreedotslabswatermilltreemaster_examples) [\[GitHub\]](https://github.com/ThreeDotsLabs/watermill) [\[Docs\]](https://watermill.io/) [\[Examples\]](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples)
|
||||
3. [Database](https://threedots.tech/post/list-of-recommended-libraries/#database)
|
||||
1. [SQL](https://threedots.tech/post/list-of-recommended-libraries/#sql)
|
||||
1. [sqlx](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-sqlx-githubhttpsgithubcomjmoironsqlx-docshttpjmoirongithubiosqlx) [\[GitHub\]](https://github.com/jmoiron/sqlx) [\[Docs\]](http://jmoiron.github.io/sqlx/)
|
||||
2. [SQLBoiler](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-sqlboiler-githubhttpsgithubcomvolatiletechsqlboiler-docshttpsgithubcomvolatiletechsqlboilertable-of-contents-exampleshttpsgithubcomvolatiletechsqlboilerfeatures--examples) [\[GitHub\]](https://github.com/volatiletech/sqlboiler) [\[Docs\]](https://github.com/volatiletech/sqlboiler#table-of-contents) [\[Examples\]](https://github.com/volatiletech/sqlboiler#features--examples)
|
||||
2. [Migrations](https://threedots.tech/post/list-of-recommended-libraries/#migrations)
|
||||
1. [sql-migrate](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-sql-migrate-githubhttpsgithubcomrubenvsql-migrate-docshttpsgithubcomrubenvsql-migratereadme) [\[GitHub\]](https://github.com/rubenv/sql-migrate) [\[Docs\]](https://github.com/rubenv/sql-migrate#readme)
|
||||
2. [goose](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-goose-githubhttpsgithubcompresslygoose-docshttpspkggodevgithubcompresslygoose) [\[GitHub\]](https://github.com/pressly/goose) [\[Docs\]](https://pkg.go.dev/github.com/pressly/goose)
|
||||
4. [Observability](https://threedots.tech/post/list-of-recommended-libraries/#observability)
|
||||
1. [Logging](https://threedots.tech/post/list-of-recommended-libraries/#logging)
|
||||
1. [Logrus](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-logrus-githubhttpsgithubcomsirupsenlogrus-docshttpspkggodevgithubcomsirupsenlogrus) [\[GitHub\]](https://github.com/sirupsen/logrus) [\[Docs\]](https://pkg.go.dev/github.com/sirupsen/logrus)
|
||||
2. [zap](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-zap-githubhttpsgithubcomuber-gozap-docshttppkggodevgithubcomuber-gozap) [\[GitHub\]](https://github.com/uber-go/zap) [\[Docs\]](http://pkg.go.dev/github.com/uber-go/zap)
|
||||
2. [Metrics and tracing](https://threedots.tech/post/list-of-recommended-libraries/#metrics-and-tracing)
|
||||
1. [opencensus-go](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-opencensus-go-githubhttpsgithubcomcensus-instrumentationopencensus-go-docshttpsopencensusio) [\[GitHub\]](https://github.com/census-instrumentation/opencensus-go) [\[Docs\]](https://opencensus.io/)
|
||||
5. [Configuration](https://threedots.tech/post/list-of-recommended-libraries/#configuration)
|
||||
1. [Env variables](https://threedots.tech/post/list-of-recommended-libraries/#env-variables)
|
||||
1. [caarlos0/env](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-caarlos0env-githubhttpsgithubcomcaarlos0env-docshttpspkggodevgithubcomcaarlos0env) [\[GitHub\]](https://github.com/caarlos0/env) [\[Docs\]](https://pkg.go.dev/github.com/caarlos0/env)
|
||||
2. [Multi-format configuration](https://threedots.tech/post/list-of-recommended-libraries/#multi-format-configuration)
|
||||
3. [koanf](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-koanf-githubhttpsgithubcomknadhkoanf-docshttpspkggodevgithubcomknadhkoanf) [\[GitHub\]](https://github.com/knadh/koanf) [\[Docs\]](https://pkg.go.dev/github.com/knadh/koanf)
|
||||
6. [Building CLI](https://threedots.tech/post/list-of-recommended-libraries/#building-cli)
|
||||
1. [Building CLI libraries](https://threedots.tech/post/list-of-recommended-libraries/#building-cli-libraries)
|
||||
1. [urfave/cli](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-urfavecli-githubhttpsgithubcomurfavecli-docshttpscliurfaveorg-exampleshttpscliurfaveorgv2examplesgreet) [\[GitHub\]](https://github.com/urfave/cli/) [\[Docs\]](https://cli.urfave.org/) [\[Examples\]](https://cli.urfave.org/v2/examples/greet/)
|
||||
7. [Testing](https://threedots.tech/post/list-of-recommended-libraries/#testing)
|
||||
1. [Assertions](https://threedots.tech/post/list-of-recommended-libraries/#assertions)
|
||||
1. [testify](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-testify-githubhttpsgithubcomstretchrtestify-docshttpspkggodevgithubcomstretchrtestify) [\[GitHub\]](https://github.com/stretchr/testify) [\[Docs\]](https://pkg.go.dev/github.com/stretchr/testify)
|
||||
2. [go-cmp](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-go-cmp-githubhttpsgithubcomgooglego-cmp-docshttpspkggodevgithubcomgooglego-cmp-examples-1httpsgithubcomgooglego-cmpblobmastercmpexample_testgo-examples-2httpsgithubcomgooglego-cmpblobmastercmpcmpoptsexample_testgo) [\[GitHub\]](https://github.com/google/go-cmp) [\[Docs\]](https://pkg.go.dev/github.com/google/go-cmp) [\[Examples 1\]](https://github.com/google/go-cmp/blob/master/cmp/example_test.go) [\[Examples 2\]](https://github.com/google/go-cmp/blob/master/cmp/cmpopts/example_test.go)
|
||||
3. [gofakeit](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-gofakeit-githubhttpsgithubcombrianvoegofakeit-docshttpspkggodevgithubcombrianvoegofakeit) [\[GitHub\]](https://github.com/brianvoe/gofakeit) [\[Docs\]](https://pkg.go.dev/github.com/brianvoe/gofakeit)
|
||||
2. [Mocking](https://threedots.tech/post/list-of-recommended-libraries/#mocking)
|
||||
1. [Writing mocks by hand](https://threedots.tech/post/list-of-recommended-libraries/#writing-mocks-by-hand)
|
||||
8. [Misc](https://threedots.tech/post/list-of-recommended-libraries/#misc)
|
||||
1. [Extra types support](https://threedots.tech/post/list-of-recommended-libraries/#extra-types-support)
|
||||
1. [google/uuid](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-googleuuid-githubhttpsgithubcomgoogleuuid-docshttpspkggodevgithubcomgoogleuuid) [\[GitHub\]](https://github.com/google/uuid) [\[Docs\]](https://pkg.go.dev/github.com/google/uuid)
|
||||
2. [oklog/ulid](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-oklogulid-githubhttpsgithubcomoklogulid-docshttpspkggodevgithubcomoklogulid) [\[GitHub\]](https://github.com/oklog/ulid) [\[Docs\]](https://pkg.go.dev/github.com/oklog/ulid)
|
||||
3. [shopspring/decimal](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-shopspringdecimal-githubhttpsgithubcomshopspringdecimal-docshttpspkggodevgithubcomshopspringdecimal) [\[GitHub\]](https://github.com/shopspring/decimal) [\[Docs\]](https://pkg.go.dev/github.com/shopspring/decimal)
|
||||
2. [Errors](https://threedots.tech/post/list-of-recommended-libraries/#errors)
|
||||
1. [hashicorp/go-multierror](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-hashicorpgo-multierror-githubhttpsgithubcomhashicorpgo-multierror-docsgithubcomhashicorpgo-multierror) [\[GitHub\]](https://github.com/hashicorp/go-multierror) [\[Docs\]](https://threedots.tech/post/list-of-recommended-libraries/github.com/hashicorp/go-multierror)
|
||||
9. [Useful tools](https://threedots.tech/post/list-of-recommended-libraries/#useful-tools)
|
||||
1. [Misc](https://threedots.tech/post/list-of-recommended-libraries/#misc-1)
|
||||
1. [samber/lo](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-samberlo-githubhttpsgithubcomsamberlo-docshttpspkggodevgithubcomsamberlo) [\[GitHub\]](https://github.com/samber/lo) [\[Docs\]](https://pkg.go.dev/github.com/samber/lo)
|
||||
2. [Task](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-task-githubhttpsgithubcomgo-tasktask-docshttpstaskfiledev) [\[GitHub\]](https://github.com/go-task/task) [\[Docs\]](https://taskfile.dev/)
|
||||
2. [Live code reloading](https://threedots.tech/post/list-of-recommended-libraries/#live-code-reloading)
|
||||
1. [reflex](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-reflex-githubhttpsgithubcomcesparereflex-docshttpspkggodevgithubcomcesparereflex-examplehttpsthreedotstechpostgo-docker-dev-environment-with-go-modules-and-live-code-reloading) [\[GitHub\]](https://github.com/cespare/reflex) [\[Docs\]](https://pkg.go.dev/github.com/cespare/reflex) \[[Example](https://threedots.tech/post/go-docker-dev-environment-with-go-modules-and-live-code-reloading/)\]
|
||||
3. [Linter](https://threedots.tech/post/list-of-recommended-libraries/#linter)
|
||||
1. [golangci-lint](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-golangci-lint-githubhttpsgithubcomgolangcigolangci-lint-docshttpsgolangci-lintrun) [\[GitHub\]](https://github.com/golangci/golangci-lint) [\[Docs\]](https://golangci-lint.run/)
|
||||
2. [go-cleanarch](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-go-cleanarch-githubhttpsgithubcomroblaszczakgo-cleanarch-docshttpspkggodevgithubcomroblaszczakgo-cleanarchsection-readme) [\[GitHub\]](https://github.com/roblaszczak/go-cleanarch) [\[Docs\]](https://pkg.go.dev/github.com/roblaszczak/go-cleanarch#section-readme)
|
||||
4. [Formatters](https://threedots.tech/post/list-of-recommended-libraries/#formatters)
|
||||
1. [go fmt](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-go-fmt)
|
||||
2. [goimports](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-goimports-docshttpspkggodevgolangorgxtoolscmdgoimports) [\[Docs\]](https://pkg.go.dev/golang.org/x/tools/cmd/goimports)
|
||||
3. [gofumpt](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-gofumpt-githubhttpsgithubcommvdangofumpt-docshttpspkggodevmvdanccgofumptsection-readme) [\[GitHub\]](https://github.com/mvdan/gofumpt) [\[Docs\]](https://pkg.go.dev/mvdan.cc/gofumpt#section-readme)
|
||||
10. [Example projects](https://threedots.tech/post/list-of-recommended-libraries/#example-projects)
|
||||
1. [DDD & Clean Architecture](https://threedots.tech/post/list-of-recommended-libraries/#ddd--clean-architecture)
|
||||
1. [Wild Workouts Go DDD Example application](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-wild-workouts-go-ddd-example-application-githubhttpsgithubcomthreedotslabswild-workouts-go-ddd-example) [\[GitHub\]](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example)
|
||||
2. [General purpose](https://threedots.tech/post/list-of-recommended-libraries/#general-purpose)
|
||||
1. [Modern Go Application by Márk Sági-Kazár](https://threedots.tech/post/list-of-recommended-libraries/#white_check_mark-modern-go-application-by-m%C3%A1rk-s%C3%A1gi-kaz%C3%A1r-githubhttpsgithubcomsagikazarmarkmodern-go-application) [\[GitHub\]](https://github.com/sagikazarmark/modern-go-application)
|
||||
11. [Summary](https://threedots.tech/post/list-of-recommended-libraries/#summary)
|
||||
|
||||
## HTTP
|
||||
|
||||
### Routers
|
||||
|
||||
As I mentioned in my [previous article](https://threedots.tech/post/best-go-framework/), it’s generally better to use libraries instead of frameworks for long-term projects. One of the most fundamental components of any service is an HTTP router. While it’s technically possible to build an application without one by using the standard library’s [http](https://pkg.go.dev/net/http) package, its routing capabilities are limited. Using a dedicated router will make your life much easier.
|
||||
|
||||
❌ Anti-pattern: Frameworks in Go
|
||||
|
||||
If the library you consider using impacts how you write your domain models, it’s probably a framework, not a router.
|
||||
|
||||
We recommend using lightweight routers instead. Learn more about the risks of using the framework in my [previous article](https://threedots.tech/post/best-go-framework/).
|
||||
|
||||
By design, router functionality is limited to routing requests to a proper handler. All non-standard functionalities like CORS, CSRF, error handling, HTTP logging, and authorization (that frameworks usually provide) are provided by reusable middlewares. I recommend some in the [section on middlewares](https://threedots.tech/post/list-of-recommended-libraries/#middlewares).
|
||||
|
||||
I use one of two router libraries in most projects: Echo or chi. Both of them are great routers, with different characteristics. They work perfectly with [OpenAPI](https://threedots.tech/post/list-of-recommended-libraries/#openapi) code generation.
|
||||
|
||||
#### ✅ Echo [\[GitHub\]](https://github.com/labstack/echo) [\[Docs\]](https://echo.labstack.com/guide/) [\[Examples\]](https://echo.labstack.com/cookbook/)
|
||||
|
||||
Compared to chi, Echo does offer a custom `*http.Request` handler signature. Some people may find it a downside, but I think it helps to write less error-prone HTTP handlers.
|
||||
|
||||
If you have been writing Go for a while, you probably made this mistake at least once:
|
||||
|
||||
```
|
||||
func someHandler(w http.ResponseWriter, r *http.Request) {
|
||||
err := foo()
|
||||
if err != nil {
|
||||
w.WriteHeader(http.StatusBadRequest)
|
||||
// you forgot the return here, bar() will be executed
|
||||
}
|
||||
|
||||
bar()
|
||||
}
|
||||
```
|
||||
|
||||
Echo makes you return an error:
|
||||
|
||||
```
|
||||
func someHandler(c echo.Context) error {
|
||||
err := foo()
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
bar()
|
||||
|
||||
return c.NoContent(http.StatusNoContent)
|
||||
}
|
||||
```
|
||||
|
||||
The advantage of Echo is the ability to define a custom [error handler](https://echo.labstack.com/guide/error-handling/). It’s not possible to do it in the same way with chi.
|
||||
|
||||
For detailed usage and examples, please check Echo docs.
|
||||
|
||||
#### ✅ chi [\[GitHub\]](https://github.com/go-chi/chi) [\[Docs\]](https://pkg.go.dev/github.com/go-chi/chi) [\[Examples\]](https://github.com/go-chi/chi/tree/master/_examples)
|
||||
|
||||
Compared to Echo, chi’s handler functions are compatible with the standard library. For some people, it may be an upside; for some, it may be a downside – you should make your own judgment.
|
||||
|
||||
What chi does better than Echo is the format of [defining routes and grouping](https://github.com/go-chi/chi/blob/0fe6bf1ba3ac601700b7993bc4c62f6c5f707932/_examples/rest/main.go#L83). It gives you better control over middleware per path or sub-path.
|
||||
|
||||
```
|
||||
r.Route("/articles", func(r chi.Router) {
|
||||
r.With(paginate).Get("/", ListArticles)
|
||||
r.Post("/", CreateArticle) // POST /articles
|
||||
r.Get("/search", SearchArticles) // GET /articles/search
|
||||
|
||||
r.Route("/{articleID}", func(r chi.Router) {
|
||||
r.Use(ArticleCtx) // Load the *Article on the request context
|
||||
r.Get("/", GetArticle) // GET /articles/123
|
||||
r.Put("/", UpdateArticle) // PUT /articles/123
|
||||
r.Delete("/", DeleteArticle) // DELETE /articles/123
|
||||
})
|
||||
|
||||
// GET /articles/whats-up
|
||||
r.With(ArticleCtx).Get("/{articleSlug:[a-z-]+}", GetArticle)
|
||||
})
|
||||
```
|
||||
|
||||
❌ Anti-pattern: You should not choose tools based just on benchmarks
|
||||
|
||||
Some developers choose libraries based on the benchmark results. It’s a risky approach because extreme performance optimizations lead to worse API and limited functionalities set. In most cases, performance differences are negligible in real-life use cases.
|
||||
|
||||
Even if, for some applications, it may make a difference, for most applications, it doesn’t matter that much. Making just one extra database query or up-scaling a service can make a much more significant difference in performance.
|
||||
|
||||
If performance is not absolutely critical for you, you should prefer other characteristics, like the ease of use and number of features.
|
||||
|
||||
### Middlewares
|
||||
|
||||
HTTP middlewares can give you functionalities like CORS, CSRF, error handling, HTTP logging, authorization, etc.
|
||||
|
||||
Echo and chi provide their set of middlewares:
|
||||
|
||||
- [Echo middlewares](https://echo.labstack.com/middleware/)
|
||||
- [chi middlewares](https://github.com/go-chi/chi/tree/master/middleware)
|
||||
|
||||
Echo middlewares have a different interface, so they can’t be used in chi. Generally speaking, all standard-library compatible middlewares are compatible with chi and echo.
|
||||
|
||||
To use standard library-compatible middleware with echo, you need to call `echo.WrapMiddleware`:
|
||||
|
||||
```
|
||||
package main
|
||||
|
||||
import (
|
||||
"github.com/go-chi/chi/v5/middleware"
|
||||
"github.com/labstack/echo/v4"
|
||||
)
|
||||
|
||||
// echo version
|
||||
func main() {
|
||||
e := echo.New()
|
||||
|
||||
// You can use a middleware from chi with echo.
|
||||
e.Use(
|
||||
echo.WrapMiddleware(middleware.BasicAuth("realm", map[string]string{
|
||||
"admin": "password",
|
||||
})),
|
||||
)
|
||||
|
||||
e.Logger.Fatal(e.Start(":8080"))
|
||||
}
|
||||
```
|
||||
|
||||
If none of them provides the middleware you are looking for, you can check [the Awesome Go list](https://github.com/avelino/awesome-go#middlewares). All of them will be compatible with chi, Echo, and servers built just with the standard library. You can also write your own middleware. Check example middlewares for inspiration!
|
||||
|
||||
### Serving static content
|
||||
|
||||
You don’t need any library to serve static content in Go. Since Go 1.16, you can easily [embed static files into your Go binary](https://pkg.go.dev/embed).
|
||||
|
||||
Here’s how to do it for `Echo` and `chi`:
|
||||
|
||||
```
|
||||
package main
|
||||
|
||||
import (
|
||||
"embed"
|
||||
"net/http"
|
||||
|
||||
"github.com/go-chi/chi"
|
||||
"github.com/go-chi/chi/v5"
|
||||
"github.com/labstack/echo/v4"
|
||||
)
|
||||
|
||||
// your static files should be in the static/ directory, for example static/index.html, static/main.js etc.
|
||||
//
|
||||
//go:embed static
|
||||
var staticFs embed.FS
|
||||
|
||||
// chi version
|
||||
func main() {
|
||||
r := chi.NewRouter()
|
||||
|
||||
r.Handle("/static/*", http.StripPrefix("/", http.FileServer(http.FS(staticFs))))
|
||||
log.Fatal(http.ListenAndServe(":8080", r))
|
||||
}
|
||||
|
||||
// echo version
|
||||
func main() {
|
||||
e := echo.New()
|
||||
e.GET("/static/*", echo.WrapHandler(http.StripPrefix("/", http.FileServer(http.FS(staticFs)))))
|
||||
e.Logger.Fatal(e.Start(":8080"))
|
||||
}
|
||||
```
|
||||
|
||||
After running the server, assets will be available under `http://localhost:8080/static/index.html`, `http://localhost:8080/static/main.js` etc.
|
||||
|
||||
❌ Anti-pattern: Do not use no-name libraries for trivial functionalities
|
||||
|
||||
Do you remember the `leftpad` JavaScript library? It was 11 lines of code adding padding on the left side of a string.
|
||||
|
||||
Some day, the author decided to remove that library. It wouldn’t be a big problem if it wasn’t a dependency of thousands of projects, including Node and Babel.
|
||||
|
||||
Serving static content from your web server is one of such trivial functionalities.
|
||||
|
||||
[](https://threedots.tech/go-in-one-evening/?utm_source=blog-content)Are you experienced engineer who wants to learn Go basics?
|
||||
You don't become an engineer by watching videos.
|
||||
[Learn Go hands-on by building real projects.](https://threedots.tech/go-in-one-evening/?utm_source=blog-content)
|
||||
|
||||
### OpenAPI
|
||||
|
||||
Nobody likes to maintain API contracts manually. It’s annoying and counterproductive to keep multiple boring JSON’s up-to-date. OpenAPI solves this problem with a JavaScript HTTP client and Go HTTP server generated from the provided specification.
|
||||
|
||||
This is how an [example specification](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example/tree/a0a41253db96d46d75e7ff4c7e7f95848f47dcc3/api/openapi) looks like. If you didn’t work with OpenAPI before, you can read more details in my [previous article](https://threedots.tech/post/serverless-cloud-run-firebase-modern-go-application/#openapi-swagger-client). Here, I focus on tools that we recommend for OpenAPI spec-generated code.
|
||||
|
||||
### Generating Go server and clients
|
||||
|
||||
We do not recommend using the official OpenAPI generator for the Go code. We recommend the `oapi-codegen` tool instead because of the higher quality of the generated code. It also has more functionalities.
|
||||
|
||||
❌ Anti-pattern: Don't try to generate OpenAPI spec from Go code
|
||||
|
||||
There are tools that can generate an OpenAPI spec from Go code. We don’t recommend using them.
|
||||
|
||||
The entire OpenAPI specification is very rich, and it will be hard to generate everything from Go code. It’s likely that you will need to add something to the OpenAPI spec at some point, and it may be impossible to do it from the Go code.
|
||||
|
||||
It’s much easier to generate it the other way around: Go code from OpenAPI spec.
|
||||
|
||||
#### ✅ deepmap/oapi-codegen [\[GitHub\]](https://github.com/deepmap/oapi-codegen) [\[Docs\]](https://github.com/deepmap/oapi-codegen#readme) [\[Example\]](https://threedots.tech/post/serverless-cloud-run-firebase-modern-go-application/#public-http-api)
|
||||
|
||||
`oapi-codegen` is a great tool that doesn’t just generate models but also the entire [router](https://threedots.tech/post/list-of-recommended-libraries/#routers) definition, header’s validation, and proper parameters parsing. It works with [chi](https://threedots.tech/post/list-of-recommended-libraries/#chi) and [Echo](https://threedots.tech/post/list-of-recommended-libraries/#echo).
|
||||
|
||||
To generate a server, run the following:
|
||||
|
||||
```
|
||||
oapi-codegen -generate types -o "<OUTPUT DIR>/openapi_types.gen.go" -package "<GO PACKAGE>" "api/openapi/service.yml"
|
||||
oapi-codegen -generate <TYPE> -o "<OUTPUT DIR>/openapi_api.gen.go" -package "<GO PACKAGE>" "api/openapi/service.yml"
|
||||
```
|
||||
|
||||
Where `<TYPE>` for `chi` should be `chi-server`, and for `Echo` just `server`.
|
||||
|
||||
To generate clients:
|
||||
|
||||
```
|
||||
oapi-codegen -generate types -o "<OUTPUT DIR>/$service/openapi_types.gen.go" -package "<GO PACKAGE>" "api/openapi/service.yml"
|
||||
oapi-codegen -generate client -o "<OUTPUT DIR>/$service/openapi_client_gen.go" -package "<GO PACKAGE>" "api/openapi/service.yml"
|
||||
```
|
||||
|
||||
Don’t forget to change `<GO PACKAGE>` to the desired Go package name and `<OUTPUT DIR>` to the desired output dir. 😉
|
||||
|
||||
Your job on the server side is just to implement the `ServerInterface` interface, like:
|
||||
|
||||
```
|
||||
// ServerInterface represents all server handlers.
|
||||
type ServerInterface interface {
|
||||
|
||||
// (GET /trainer/calendar)
|
||||
GetTrainerAvailableHours(w http.ResponseWriter, r *http.Request, params GetTrainerAvailableHoursParams)
|
||||
|
||||
// (PUT /trainer/calendar/make-hour-available)
|
||||
MakeHourAvailable(w http.ResponseWriter, r *http.Request)
|
||||
|
||||
// (PUT /trainer/calendar/make-hour-unavailable)
|
||||
MakeHourUnavailable(w http.ResponseWriter, r *http.Request)
|
||||
}
|
||||
```
|
||||
|
||||
You can see it in action in the [Wild Workouts project](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example).
|
||||
|
||||
### Bonus: Client for JavaScript/TypeScript
|
||||
|
||||
Even if it’s the list of **recommended Go libraries**, you may need to generate code for the browser.
|
||||
|
||||
#### ✅ openapi-generator-cli [\[GitHub\]](https://github.com/OpenAPITools/openapi-generator-cli) [\[Docs\]](https://github.com/OpenAPITools/openapi-generator-cli#readme)
|
||||
|
||||
In that case, we also recommend a non-official library instead of the official one.
|
||||
|
||||
In contrast to `oapi-codegen`, `openapi-generator-cli` is a Java tool. To avoid any JVM-related issues, we recommend generating clients using Docker:
|
||||
|
||||
```
|
||||
docker run --rm --env "JAVA_OPTS=-Dlog.level=error" -v "${PWD}:/local" \
|
||||
"openapitools/openapi-generator-cli:v6.2.1" generate \
|
||||
-i "/local/api/openapi/service.yml" \
|
||||
-g javascript \
|
||||
-o "/local/web/src/clients/service"
|
||||
```
|
||||
|
||||
It assumes that the spec is available locally in `api/openapi/service.yml`.
|
||||
|
||||
You can use `openapi-generator-cli` for TypeScript and other languages as well.
|
||||
|
||||
## Alternative types of communication
|
||||
|
||||
### gRPC
|
||||
|
||||
gRPC is a technology that can help you with building robust, internal communication between your services (but not only!).
|
||||
|
||||
I already described in detail why it’s [worth using gRPC for internal communication](https://threedots.tech/post/robust-grpc-google-cloud-run/) and how to do it.
|
||||
|
||||
I’ll not repeat it here and will focus on the tooling you need.
|
||||
|
||||
With gRPC, you have little choice for generating server and client: you should use official tooling. The good news is that you don’t need anything more because it does its job!
|
||||
|
||||
#### ✅ protoc [\[Docs\]](https://grpc.io/docs/)
|
||||
|
||||
To generate Go code from `.proto` files, you need to install [protoc](https://grpc.io/docs/protoc-installation/) and [protoc Go Plugin](https://grpc.io/docs/quickstart/go/).
|
||||
|
||||
A list of supported types can be found in [Protocol Buffers Version 3 Language Specification](https://developers.google.com/protocol-buffers/docs/reference/proto3-spec#fields). More complex built-in types like Timestamp can be found in [Well-Known Types list](https://developers.google.com/protocol-buffers/docs/reference/google.protobuf).
|
||||
|
||||
### Messaging
|
||||
|
||||
#### ✅ Watermill [\[GitHub\]](https://github.com/ThreeDotsLabs/watermill) [\[Docs\]](https://watermill.io/) [\[Examples\]](https://github.com/ThreeDotsLabs/watermill/tree/master/_examples)
|
||||
|
||||
About four years ago, when working on one of our projects, we found that there is no library that can simplify building message-driven or event-driven applications easily. To make our lives easier, we decided to write a library that will allow us to write event-driven code as easily as writing HTTP services. This is how Watermill was born.
|
||||
|
||||
Today, Watermill is one of the most popular Go libraries with almost 5k GitHub stars, +35 contributors, and 10 officially supported Pub/Subs.
|
||||
|
||||
Usually, message-broker libraries are very low-level. With Watermill, publishing messages may be as simple as:
|
||||
|
||||
```
|
||||
publisher.Publish("example.topic", msg)
|
||||
```
|
||||
|
||||
And subscribing like:
|
||||
|
||||
```
|
||||
messages, err := subscriber.Subscribe(ctx, "example.topic")
|
||||
if err != nil {
|
||||
panic(err)
|
||||
}
|
||||
|
||||
for msg := range messages {
|
||||
fmt.Printf("received message: %s, payload: %s\n", msg.UUID, string(msg.Payload))
|
||||
msg.Ack()
|
||||
}
|
||||
```
|
||||
|
||||
Compared to using just the message broker’s library, Watermill provides support for some higher level functionalities like [middlewares](https://watermill.io/docs/middlewares/), [CQRS support](https://watermill.io/docs/cqrs/), or [event-forwarder](https://watermill.io/docs/forwarder/) component (that can be used to stream your messages from an SQL database to the message broker).
|
||||
|
||||
Today, Watermill officially supports [Kafka](https://watermill.io/pubsubs/kafka/), [GCP Pub/Sub](https://watermill.io/pubsubs/googlecloud/), [NATS](https://watermill.io/pubsubs/nats/), [RabbitMQ](https://watermill.io/pubsubs/amqp/) message brokers (Pub/Subs). It can also listen to and emit events as [HTTP hooks](https://watermill.io/pubsubs/http/), from databases like [MySQL/Postgres](https://watermill.io/pubsubs/sql/), [BoltDB](https://watermill.io/pubsubs/bolt/) or [Firestore](https://watermill.io/pubsubs/firestore/). It can also work with in-memory [Go-channel based Pub/Sub](https://watermill.io/pubsubs/gochannel/).
|
||||
|
||||
Don't miss new posts.
|
||||
Join over 15k subscribers of our newsletter and get a [**free e-book**](https://threedots.tech/go-with-the-domain/)!
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
## Go With The Domain Three Dots Labs
|
||||
|
||||
|
||||
|
||||
](https://threedots.tech/go-with-the-domain/)
|
||||
|
||||
🔒 We do not send spam. You can unsubscribe at any time!
|
||||
|
||||
## Database
|
||||
|
||||
### SQL
|
||||
|
||||
There is no golden hammer solution for interacting with SQL databases. The reason is simple: it depends greatly on what kind of data you store.
|
||||
|
||||
In some projects, data models are relatively simple. In some, they are very complex. Because of that, I have two libraries to recommend. You should choose one of them based on the requirements of your project.
|
||||
|
||||
For projects with straightforward data models, you should check `sqlx`. For a bit more complex, you should look at `SQLBoiler`.
|
||||
|
||||
✅ Tactic: Using ORM
|
||||
|
||||
I hear more and more that using ORM is not a good idea. I understand a reason for such thinking: many people are hurt by the improper use of ORMs.
|
||||
|
||||
It’s like with a knife: I have an extremally sharp Japanese knife without which I can’t imagine cooking. On another side, I need to be very careful with using it. But that fact doesn’t make this knife a bad tool! If you are using it properly, it’s making your life much easier. It’s the same situation with ORMs. Writing queries by hand may be time-consuming and error-prone when your models are complex. ORMs were invented to solve that problem.
|
||||
|
||||
If you have a bad experience using ORMs, you should check [Things to know about DRY](https://threedots.tech/post/things-to-know-about-dry/) article. The tactics presented in that article will help you to avoid all common problems with ORMs.
|
||||
|
||||
❌ Anti-pattern: Avoid weakly typed ORMs
|
||||
|
||||
Most ORMs depend heavily on reflection and `interface{}`/`any`. The type system is one of the biggest strengths of Go. It helps you build applications efficiently. Resigning from strict typing makes your application more error-prone.
|
||||
|
||||
#### ✅ sqlx [\[GitHub\]](https://github.com/jmoiron/sqlx) [\[Docs\]](http://jmoiron.github.io/sqlx/)
|
||||
|
||||
The standard library’s `database/sql` package is rather a low-level one. `sqlx` provides a more convenient and powerful API to work with databases. It includes helper functions for common tasks like inserting and querying data and support for more advanced features like prepared statements and transactions. `sqlx` also has more advanced support for data unmarshaling (for example to structs, lists of structs, json data, etc.). As a nice bonus, `sqlx`’s interface is compatible with interfaces from `database/sql`.
|
||||
|
||||
But even if `sqlx` is a great library, it works well for relatively simple database models. At some level of complexity, you should consider migration to an ORM.
|
||||
|
||||
#### ✅ SQLBoiler [\[GitHub\]](https://github.com/volatiletech/sqlboiler) [\[Docs\]](https://github.com/volatiletech/sqlboiler#table-of-contents) [\[Examples\]](https://github.com/volatiletech/sqlboiler#features--examples)
|
||||
|
||||
So far, the only ORM that fully meets our requirements is SQLBoiler. At first, how you define SQLBoiler models may surprise you. Most ORMs generate the database schema out of your Go models. SQLBoiler does the opposite: it generates Go models from your database schema.
|
||||
|
||||
This approach has multiple advantages. One of the most important features is stricter typing than other libraries. Thanks to that, many checks are done during compilation. You don’t need to depend on a ton of reflection and magic struct tags. In most cases, as long as the code compiles, it will work correctly.
|
||||
|
||||
Generating code from the database schema helps with migration from an existing database because you don’t need to re-write DB models: SQLBoiler generates them for you. So if you start with `sqlx` and move to SQLBoiler later, the migration should be pretty easy.
|
||||
|
||||
SQLBoiler supports PostgreSQL, MySQL, MSSQLServer 2012+, SQLite3, and CockroachDB.
|
||||
|
||||
❌ Anti-pattern: Using database models in the API responses
|
||||
|
||||
As long as you’re not writing a stupid simple CRUD application (and the chances are you’re not), you should not couple your database models with the API responses.
|
||||
|
||||
At some point, requirements will force you to return data in a format different from the format you have in the database. Instead of trying to follow DRY at all costs, it’s time to split your models.
|
||||
|
||||
You can read more on this in [“Business Applications in Go: Things to know about DRY” article](https://threedots.tech/post/things-to-know-about-dry/) and [“Common Anti-Patterns in Go Web Applications”](https://threedots.tech/post/common-anti-patterns-in-go-web-applications/).
|
||||
|
||||
### Migrations
|
||||
|
||||
SQLBoiler and `sqlx` don’t provide out-of-the-box support for migrations. It’s okay because you are not forced to use any particular solution.
|
||||
|
||||
In my recent projects, I used both `sql-migrate` and `goose`, and I was happy about them.
|
||||
|
||||
#### ✅ sql-migrate [\[GitHub\]](https://github.com/rubenv/sql-migrate) [\[Docs\]](https://github.com/rubenv/sql-migrate#readme)
|
||||
|
||||
#### ✅ goose [\[GitHub\]](https://github.com/pressly/goose) [\[Docs\]](https://pkg.go.dev/github.com/pressly/goose)
|
||||
|
||||
We like `sql-migrate` and `goose` because of their simplicity and flexibility. `sql-migrate` and `goose` can be executed as CLI tools and as part of your service.
|
||||
|
||||
I like to embed it into the binary of the service. Thanks to that, the migration is executed when the service starts, and it keeps the setup simple. It’s also much less complex to run. For example, `sql-migrate` with `go:embed`:
|
||||
|
||||
```
|
||||
// migrations/run.go
|
||||
package migrations
|
||||
|
||||
import (
|
||||
"database/sql"
|
||||
"embed"
|
||||
|
||||
migrate "github.com/rubenv/sql-migrate"
|
||||
)
|
||||
|
||||
//go:embed *
|
||||
var migrationsFiles embed.FS
|
||||
|
||||
func Run(postgresConn string) error {
|
||||
db, err := sql.Open("postgres", postgresConn)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
migrations := &migrate.EmbedFileSystemMigrationSource{
|
||||
FileSystem: migrationsFiles,
|
||||
Root: ".",
|
||||
}
|
||||
|
||||
if _, err := migrate.Exec(db, "postgres", migrations, migrate.Up); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
Put your migrations in `migrations/`, for example: `migrations/1_init.sql`, `migrations/2_alter_some_table.sql`, etc. Then run `Run` in your `main`.
|
||||
|
||||
## Observability
|
||||
|
||||
### Logging
|
||||
|
||||
The standard library’s logger doesn’t provide essential features like log levels and output formatting.
|
||||
|
||||
For logging, we can recommend two libraries: `Logrus` and `zap`. In contrast to `zap`, `Logrus` provides a bit nicer user API, but `zap` is faster.
|
||||
|
||||
You can check detailed benchmarks in [zap’s readme](https://github.com/uber-go/zap#performance).
|
||||
|
||||
❌ Anti-pattern: You should not choose tools based just on benchmarks
|
||||
|
||||
Some developers tend to choose libraries based on the benchmark results. It’s a risky approach because extreme performance optimizations lead to worse API and limited functionalities set. In most cases, performance differences are negligible in real-life use cases.
|
||||
|
||||
Even if, for some applications, it may make a difference, for most applications, it doesn’t matter that much. Making just one extra database query or up-scaling a service can make a much more significant difference in performance.
|
||||
|
||||
If performance is not absolutely critical for you, you should prefer other characteristics, like the ease of use and number of features.
|
||||
|
||||
#### ✅ Logrus [\[GitHub\]](https://github.com/sirupsen/logrus) [\[Docs\]](https://pkg.go.dev/github.com/sirupsen/logrus)
|
||||
|
||||
#### ✅ zap [\[GitHub\]](https://github.com/uber-go/zap) [\[Docs\]](http://pkg.go.dev/github.com/uber-go/zap)
|
||||
|
||||
### Metrics and tracing
|
||||
|
||||
#### ✅ opencensus-go [\[GitHub\]](https://github.com/census-instrumentation/opencensus-go) [\[Docs\]](https://opencensus.io/)
|
||||
|
||||
OpenCensus Go is a library that helps you add metrics and tracing to your endpoints or database queries. The integration uses middleware/decorator patterns, and it doesn’t require a lot of custom code. It supports [HTTP endpoints](https://pkg.go.dev/go.opencensus.io/plugin/ochttp), [gRPC endpoints](https://pkg.go.dev/go.opencensus.io/plugin/ocgrpc), [SQL databases](https://pkg.go.dev/github.com/opencensus-integrations/ocsql), [MongoDB](https://pkg.go.dev/github.com/orijtech/mongo-go-driver), etc.
|
||||
|
||||
You can export traces and metrics to Prometheus, OpenZipkin, GCP Stackdriver Monitoring, Jaeger, AWS X-Ray, Datadog, Graphite, Honeycomb, or New Relic.
|
||||
|
||||
## Configuration
|
||||
|
||||
Go’s standard library doesn’t support much more configuration options than the [flag package](https://pkg.go.dev/flag). Even if it’s enough for simple CLI tools, you may need a bit more for building services.
|
||||
|
||||
### Env variables
|
||||
|
||||
#### ✅ caarlos0/env [\[GitHub\]](https://github.com/caarlos0/env) [\[Docs\]](https://pkg.go.dev/github.com/caarlos0/env)
|
||||
|
||||
This library should provide everything you need for configuration for most applications. Compared to the standard library, it does support loading envs to structs and setting env defaults. It helps to save a lot of boilerplate for bigger configurations. It also supports embedded structs, so you can compose bigger a configuration from independent components.
|
||||
|
||||
✅ Tactic: Use env variables for your services configuration
|
||||
|
||||
For most applications, environment variables should be good enough as configuration.
|
||||
|
||||
Configuration is where you should keep secrets and things that differ between environments. If your configuration is massive and does not change often, it may be worth hardcoding it instead. It’s much more pragmatic than having tens of never-changing configuration options.
|
||||
|
||||
#### Multi-format configuration
|
||||
|
||||
#### ✅ koanf [\[GitHub\]](https://github.com/knadh/koanf) [\[Docs\]](https://pkg.go.dev/github.com/knadh/koanf)
|
||||
|
||||
Koanf is an excellent tool if your project requires multiple configuration formats. It’s often the case when you write tools that are used externally (for example, CLI tools).
|
||||
|
||||
This is my most recent finding. Compared to other [more popular libraries](https://github.com/knadh/koanf#alternative-to-viper), `koanf` just does loading multi-format configuration right. Bonus points for a nice abstraction that allows extending parsing and loading.
|
||||
|
||||
Koanf does support the most important configuration formats, like `json`, `yaml`, `dotenv`, env vars, or `hcl`. They can be loaded from the filesystem, flags, and multiple external sources like `s3`, `vault`, `etcd`, or `consul`.
|
||||
|
||||
## Building CLI
|
||||
|
||||
### Building CLI libraries
|
||||
|
||||
#### ✅ urfave/cli [\[GitHub\]](https://github.com/urfave/cli/) [\[Docs\]](https://cli.urfave.org/) [\[Examples\]](https://cli.urfave.org/v2/examples/greet/)
|
||||
|
||||
We like `urfave/cli` because of its simple interface and extensibility. We used it in multiple projects without any issues.
|
||||
|
||||
Compared to other alternatives, it offers a big-enough feature set while keeping the library lightweight.
|
||||
|
||||
## Testing
|
||||
|
||||
### Assertions
|
||||
|
||||
#### ✅ testify [\[GitHub\]](https://github.com/stretchr/testify) [\[Docs\]](https://pkg.go.dev/github.com/stretchr/testify)
|
||||
|
||||
`testify` became the standard assertion library, and I’ve seen it in every project I worked on. It provides asserts for the most common cases and also some more complex. One of `testify`’s key features are friendly messages for all failed asserts. It makes writing and debugging tests much faster.
|
||||
|
||||
The library provides two ways of asserting:
|
||||
|
||||
- `assert` from `github.com/stretchr/testify/assert` - the test continues after failure. You should use it when you want to see multiple errors (not just the first one). Works when called in a goroutine.
|
||||
- `require` from `github.com/stretchr/testify/require` - the test is interrupted after failure. You should use it when some critical condition was not met and continuing doesn’t make any sense (for example: storing to database failed). Doesn’t work when called in a goroutine.
|
||||
|
||||
Some example asserts:
|
||||
|
||||
- [Equal](https://pkg.go.dev/github.com/stretchr/testify/assert#Equal) - good enough in most cases
|
||||
- [Eventually](https://pkg.go.dev/github.com/stretchr/testify/assert#Eventually) - useful for asserting asynchronous conditions
|
||||
- [ElementsMatch](https://pkg.go.dev/github.com/stretchr/testify/assert#ElementsMatch) - useful for unsorted slices
|
||||
- [WithinDuration](https://pkg.go.dev/github.com/stretchr/testify/assert#WithinDuration) - useful when comparing time that is not exactly equal
|
||||
- [ErrorIs](https://pkg.go.dev/github.com/stretchr/testify/assert#ErrorIs)
|
||||
- [JSONEq](https://pkg.go.dev/github.com/stretchr/testify/assert#JSONEq)
|
||||
- [Panics](https://pkg.go.dev/github.com/stretchr/testify/assert#Panics)
|
||||
|
||||
✅ Tactic: Use assert messages just if it is really needed
|
||||
|
||||
I’ve seen people who obsessively write messages for all failed assert.
|
||||
|
||||
For example:
|
||||
|
||||
```
|
||||
assert.Equal(t, 123, 321, "123 is not equal to 321")
|
||||
```
|
||||
|
||||
will give output:
|
||||
|
||||
```
|
||||
Error: Not equal:
|
||||
expected: 123
|
||||
actual : 321
|
||||
Test: TestEqual
|
||||
Messages: 123 is not equal to 321
|
||||
```
|
||||
|
||||
As you can see, the message doesn’t add anything more than testify would figure out. It can even be harmful because with time, you will need to spend a lot of time to keep the message up to date.
|
||||
|
||||
In most cases, the message provided by testify will be good enough. If the test fails, the person who sees the failure will navigate to this test and will understand the reason from the surrounding code.
|
||||
|
||||
✅ Tactic: Do not write basic asserts by hand
|
||||
|
||||
Many people advocate for writing all asserts by hand. It won’t give you much advantage in the end.
|
||||
|
||||
`testify` is also very smart in showing the difference between the expected and actual value.
|
||||
|
||||
For example:
|
||||
|
||||
```
|
||||
assert.Equal(t, []byte("foo bar baz"), []byte("foo bar 42"))
|
||||
```
|
||||
|
||||
prints:
|
||||
|
||||
```
|
||||
Error: Not equal:
|
||||
expected: []byte{0x66, 0x6f, 0x6f, 0x20, 0x62, 0x61, 0x72, 0x20, 0x62, 0x61, 0x7a}
|
||||
actual : []byte{0x66, 0x6f, 0x6f, 0x20, 0x62, 0x61, 0x72, 0x20, 0x34, 0x32}
|
||||
|
||||
Diff:
|
||||
--- Expected
|
||||
+++ Actual
|
||||
@@ -1,3 +1,3 @@
|
||||
-([]uint8) (len=11) {
|
||||
- 00000000 66 6f 6f 20 62 61 72 20 62 61 7a |foo bar baz|
|
||||
+([]uint8) (len=10) {
|
||||
+ 00000000 66 6f 6f 20 62 61 72 20 34 32 |foo bar 42|
|
||||
}
|
||||
Test: TestEqual
|
||||
--- FAIL: TestEqual (0.00s)
|
||||
|
||||
|
||||
Expected :[]byte{0x66, 0x6f, 0x6f, 0x20, 0x62, 0x61, 0x72, 0x20, 0x62, 0x61, 0x7a}
|
||||
Actual :[]byte{0x66, 0x6f, 0x6f, 0x20, 0x62, 0x61, 0x72, 0x20, 0x34, 0x32}
|
||||
```
|
||||
|
||||
It makes no sense to reinvent the wheel and write it from scratch.
|
||||
|
||||
❌ Anti-pattern: Do not use test suites from testify
|
||||
|
||||
Testify is an excellent library for assertions, but we don’t recommend its test suites. They don’t support parallel sub-tests. They may be fine for unit tests, but for integration/API/E2E tests **it’s a deal-breaker**.
|
||||
|
||||
The standard library can achieve most of the functionalities provided by testify’s test suites. You can see specific examples in [this article on testing microservices](https://threedots.tech/post/microservices-test-architecture/#keeping-integration-tests-stable-and-fast).
|
||||
|
||||
#### ✅ go-cmp [\[GitHub\]](https://github.com/google/go-cmp) [\[Docs\]](https://pkg.go.dev/github.com/google/go-cmp) [\[Examples 1\]](https://github.com/google/go-cmp/blob/master/cmp/example_test.go) [\[Examples 2\]](https://github.com/google/go-cmp/blob/master/cmp/cmpopts/example_test.go)
|
||||
|
||||
Sometimes, you must assert a complex struct in your tests skipping some fields. Or the struct contains fields that should be compared in a specific way. Or you need to ignore the slice order or time delta. It’s where `go-cmp` can help you!
|
||||
|
||||
```
|
||||
import (
|
||||
"github.com/google/go-cmp/cmp"
|
||||
"github.com/google/go-cmp/cmp/cmpopts"
|
||||
)
|
||||
|
||||
diff := cmp.Diff(
|
||||
want,
|
||||
got,
|
||||
// FieldToIgnore and AnotherFieldToIgnore will be ignored in SomeStruct
|
||||
cmpopts.IgnoreFields(SomeStruct{}, "FieldToIgnore", "AnotherFieldToIgnore"),
|
||||
|
||||
// when comparing time, truncate it to one second
|
||||
// can be written for any type
|
||||
opt := cmp.Comparer(func(x, y time.Time) bool {
|
||||
return x.Truncate(time.Second).Equal(y.Truncate(time.Second))
|
||||
})
|
||||
|
||||
// sort all []int
|
||||
cmpopts.SortSlices(func(x, y int) bool {
|
||||
return x < y
|
||||
}))
|
||||
)
|
||||
|
||||
// cmp returns diff if two objects are different
|
||||
// to check if objects are equal, you can assert if the diff is empty
|
||||
assert.Empty(t, diff)
|
||||
```
|
||||
|
||||
To see the list of all available options, I recommend checking the godoc of [`cmp`](https://pkg.go.dev/github.com/google/go-cmp/cmp) and [`cmpopts`](https://pkg.go.dev/github.com/google/go-cmp/cmp/cmpopts) package.
|
||||
|
||||
go-cmp can also be used outside of tests, but be careful – it’s another tool that, used irresponsibly, may hurt your project.
|
||||
|
||||
#### ✅ gofakeit [\[GitHub\]](https://github.com/brianvoe/gofakeit) [\[Docs\]](https://pkg.go.dev/github.com/brianvoe/gofakeit)
|
||||
|
||||
If you need more realistic data for your tests, `gofakeit` helps.
|
||||
|
||||
### Mocking
|
||||
|
||||
#### Writing mocks by hand
|
||||
|
||||
*Initially, I recommended one popular mocking tool here. But after some thinking, we decided that the tool is not good enough to recommend. Instead, consider an alternative mocking strategy 👇*
|
||||
|
||||
✅ Tactic: Consider writing mocks by hand
|
||||
|
||||
Even if it sounds like a waste of time, writing mocks yourself may be good enough. Objectively speaking, writing them by hand doesn’t require much more code and time. As a bonus, it gives you much more flexibility.
|
||||
|
||||
This is how an example mock can look like:
|
||||
|
||||
```
|
||||
type BalanceUpdate struct {
|
||||
UserID string
|
||||
AmountChange int
|
||||
}
|
||||
|
||||
type UserServiceMock struct {
|
||||
BalanceUpdates []BalanceUpdate
|
||||
balanceUpdatesLock sync.Mutex
|
||||
}
|
||||
|
||||
func (u *UserServiceMock) UpdateTrainingBalance(ctx context.Context, userID string, amountChange int) error {
|
||||
u.balanceUpdatesLock.Lock()
|
||||
defer u.balanceUpdatesLock.Unlock()
|
||||
|
||||
u.BalanceUpdates = append(u.BalanceUpdates, BalanceUpdate{userID, amountChange})
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
It took me literally 1 minute to write it.
|
||||
|
||||
✅ Tactic: Keep your interfaces small, so it's easier to mock them
|
||||
|
||||
It’s hard to mock complex types by hand. But if your interface is so complex you can’t write a mock for it, you should reconsider if it needs to be that big. Using mocking libraries obfuscates the real problem.
|
||||
|
||||
Try to simplify the type that you are mocking. Maybe [the interface segregation principle](https://en.wikipedia.org/wiki/Interface_segregation_principle) will help? It could be possible to split this type into multiple smaller types.
|
||||
|
||||
It will not only simplify your mocks but will improve your codebase.
|
||||
|
||||
## Misc
|
||||
|
||||
#### ✅ google/uuid [\[GitHub\]](https://github.com/google/uuid) [\[Docs\]](https://pkg.go.dev/github.com/google/uuid)
|
||||
|
||||
This library generates UUIDs.
|
||||
|
||||
#### ✅ oklog/ulid [\[GitHub\]](https://github.com/oklog/ulid) [\[Docs\]](https://pkg.go.dev/github.com/oklog/ulid)
|
||||
|
||||
UUIDs [may be slow to store](https://www.percona.com/blog/2014/12/19/store-uuid-optimized-way/) at a larger scale in relational databases. A solution may be using Universally Unique Lexicographically Sortable Identifier: ULIDs. ULIDs are compatible with UUIDs, are unique enough for large scale, and have shorter string representation (Crockford’s base32). ULIDs are lexicographically sortable, thanks to what building indexes should be much faster.
|
||||
|
||||
It’s worth mentioning that UUID v6, v7, and v8 will also be lexicographically sortable. But its spec is still draft when during the release of the article. If you want to try UUID v6 or v7, you can check [github.com/gofrs/uuid](https://github.com/gofrs/uuid/blob/e1079f31cfcadf78856b9866d15574dd6546e29b/uuid.go#L66) which does already implement them.
|
||||
|
||||
#### ✅ shopspring/decimal [\[GitHub\]](https://github.com/shopspring/decimal) [\[Docs\]](https://pkg.go.dev/github.com/shopspring/decimal)
|
||||
|
||||
Go doesn’t have built-in support for decimals. `shopspring/decimal` does the job. We have used this library for a couple of years to build a large financial system.
|
||||
|
||||
✅ Tactic: Use decimals for monetary values
|
||||
|
||||
Floats are not designed to accurately store decimal numbers.
|
||||
|
||||
For example:
|
||||
|
||||
```
|
||||
fmt.Printf("%.16f", 12.1+0.03)
|
||||
|
||||
> Output: 12.1300000000000008
|
||||
```
|
||||
|
||||
To make sure your money calculations are correct (and you are not losing or getting extra cents in calculations), we recommend using a decimal type.
|
||||
|
||||
It’s also a good idea to use the string representation of decimals instead of floats in transport (in events, API requests and responses, etc.).
|
||||
|
||||
### Errors
|
||||
|
||||
#### ✅ hashicorp/go-multierror [\[GitHub\]](https://github.com/hashicorp/go-multierror) [\[Docs\]](https://threedots.tech/post/list-of-recommended-libraries/github.com/hashicorp/go-multierror)
|
||||
|
||||
Did you ever need to handle an error while you were handling another error? `hashicorp/go-multierror` is here to help you!
|
||||
|
||||
It’s also helpful if an operation can return multiple errors, and you don’t want to return just the first one (for example, validation).
|
||||
|
||||
Example use cases:
|
||||
|
||||
```
|
||||
func validate() {
|
||||
var resultErr error
|
||||
|
||||
if err := validateFoo(); err != nil {
|
||||
resultErr = multierror.Append(resultErr, err)
|
||||
}
|
||||
if err := validateBar(); err != nil {
|
||||
resultErr = multierror.Append(resultErr, err)
|
||||
}
|
||||
|
||||
return resultErr
|
||||
}
|
||||
```
|
||||
|
||||
or
|
||||
|
||||
```
|
||||
func ExecuteStuff() error {
|
||||
if err := makeStuff(); err != nil {
|
||||
if cleanupErr := cleanup(); cleanupErr != nil {
|
||||
err = multierror.Append(err, cleanupErr)
|
||||
}
|
||||
|
||||
return err
|
||||
}
|
||||
|
||||
return nil
|
||||
}
|
||||
```
|
||||
|
||||
*Note: Go 1.20 [will introduce](https://github.com/golang/go/issues/53435) `errors.Join` function. After release of Go 1.20 you should consider using it instead.*
|
||||
|
||||
### Misc
|
||||
|
||||
#### ✅ samber/lo [\[GitHub\]](https://github.com/samber/lo) [\[Docs\]](https://pkg.go.dev/github.com/samber/lo)
|
||||
|
||||
Lodash-style Go library based on Go 1.18+ Generics. It may be especially useful for you if you are coming to Go from Python and missing some basic slice/map functions.
|
||||
|
||||
Some functions that I’m using the most:
|
||||
|
||||
- [Filter](https://pkg.go.dev/github.com/samber/lo#Filter)
|
||||
- [Map](https://pkg.go.dev/github.com/samber/lo#Map)
|
||||
- [Keys](https://pkg.go.dev/github.com/samber/lo#Keys)
|
||||
- [Values](https://pkg.go.dev/github.com/samber/lo#Values)
|
||||
- [Find](https://pkg.go.dev/github.com/samber/lo#Find)
|
||||
- [Max](https://pkg.go.dev/github.com/samber/lo#Max)
|
||||
- [Must](https://pkg.go.dev/github.com/samber/lo#Must) 😈 please use it just for tests or if you really have a good reason
|
||||
|
||||
Even if some may find it “non-idiomatic”, I find it useful in some cases. It’s similar to using an [ORM](https://threedots.tech/post/list-of-recommended-libraries/#sql) – as long as such libraries are used responsibly and don’t obfuscate code, they are useful.
|
||||
|
||||
So if you find yourself writing code like:
|
||||
|
||||
```
|
||||
lo.Map(
|
||||
lo.Filter(someSlice, func(v SomeType, _ int) bool {
|
||||
return v.IsSpecial
|
||||
}),
|
||||
func(t SomeType, _ int) string {
|
||||
return t.SpecialName()
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
…it’s just better to convert it to a simple, more readable loop. 😉
|
||||
|
||||
#### ✅ Task [\[GitHub\]](https://github.com/go-task/task) [\[Docs\]](https://taskfile.dev/)
|
||||
|
||||
Task is not really a Go library, but it’s a tool written in Go that may be useful for your projects.
|
||||
|
||||
It’s an excellent alternative to Makefile. The most important features that it offers are:
|
||||
|
||||
- Parallel tasks execution (supported by [task dependencies](https://taskfile.dev/usage/#task-dependencies))
|
||||
- Preventing [unnecessary work](https://taskfile.dev/usage/#prevent-unnecessary-work)
|
||||
- [Loading .env](https://taskfile.dev/usage/#env-files)
|
||||
- [Dynamic variables](https://taskfile.dev/usage/#dynamic-variables)
|
||||
- [Forwarding CLI arguments](https://taskfile.dev/usage/#forwarding-cli-arguments-to-commands)
|
||||
- [Templating](https://taskfile.dev/usage/#gos-template-engine)
|
||||
|
||||
It’s a must-have for each of my new projects.
|
||||
|
||||
### Live code reloading
|
||||
|
||||
#### ✅ reflex [\[GitHub\]](https://github.com/cespare/reflex) [\[Docs\]](https://pkg.go.dev/github.com/cespare/reflex) \[[Example](https://threedots.tech/post/go-docker-dev-environment-with-go-modules-and-live-code-reloading/)\]
|
||||
|
||||
Go doesn’t provide code live-reloading out of the box. But you can achieve it quickly with the `reflex` library.
|
||||
|
||||
Some time ago, Miłosz wrote an article that shows how to create a [local environment with Docker and reflex](https://threedots.tech/post/go-docker-dev-environment-with-go-modules-and-live-code-reloading/).
|
||||
|
||||
### Linter
|
||||
|
||||
#### ✅ golangci-lint [\[GitHub\]](https://github.com/golangci/golangci-lint) [\[Docs\]](https://golangci-lint.run/)
|
||||
|
||||
golangci-lint is a linter that aggregates multiple linters and runs them in parallel and does it very fast.
|
||||
|
||||
Here’s [an example configuration](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example/blob/b519c611e9d1248a149c89db9bcf879fd78b1e35/internal/trainer/.golangci.yml) that we use in our projects.
|
||||
|
||||
#### ✅ go-cleanarch [\[GitHub\]](https://github.com/roblaszczak/go-cleanarch) [\[Docs\]](https://pkg.go.dev/github.com/roblaszczak/go-cleanarch#section-readme)
|
||||
|
||||
If you use [Clean/Hexagonal Architecture](https://threedots.tech/post/introducing-clean-architecture/) in your project, you can use this linter to ensure that The Dependency Inversion Rule and interaction between packages are kept.
|
||||
|
||||
### Formatters
|
||||
|
||||
#### ✅ go fmt
|
||||
|
||||
The standard formatter provided by Go toolchain.
|
||||
|
||||
#### ✅ goimports [\[Docs\]](https://pkg.go.dev/golang.org/x/tools/cmd/goimports)
|
||||
|
||||
Goimports does all that `go fmt` does, but it also sorts imports of your Go files. It’s one of the tools that you will see widely adopted in most Go projects.
|
||||
|
||||
Not everybody knows, but you can also separately group your local imports with the `-local` flag.
|
||||
|
||||
```
|
||||
goimports -local "github.com/ThreeDotsLabs/some-repository" -l -w .
|
||||
```
|
||||
|
||||
#### ✅ gofumpt [\[GitHub\]](https://github.com/mvdan/gofumpt) [\[Docs\]](https://pkg.go.dev/mvdan.cc/gofumpt#section-readme)
|
||||
|
||||
Just for the biggest formatting freaks! Does all that `go fmt` and `goimports` do and more!
|
||||
|
||||
Personally, I like gofumpt’s formatting decisions.
|
||||
|
||||
## Example projects
|
||||
|
||||
### DDD & Clean Architecture
|
||||
|
||||
#### ✅ Wild Workouts Go DDD Example application [\[GitHub\]](https://github.com/ThreeDotsLabs/wild-workouts-go-ddd-example)
|
||||
|
||||
**Wild Workouts is an example Go DDD project that we created to show how to build Go applications that are easy to develop, maintain, and fun to work with, It shows a project developed over time and with complex problems to solve.** In contrast to other example projects, it was not blindly copied from other languages.
|
||||
|
||||
This is the way how we build our services daily. Highly recommended if you are looking for patterns that will allow you to build more complex projects!
|
||||
|
||||
❌ Anti-pattern: Low-quality example repositories
|
||||
|
||||
Avoid projects that look like over-engineered copies from other programming languages.
|
||||
|
||||
People who write such “DDD” projects often just read a couple of articles about it without understanding it correctly and without using it in real-life projects. If you see DDD/Clean Architecture examples without encapsulated domain models (with public fields) and `json` tags: run! It’s definitely not DDD nor Clean Architecture.
|
||||
|
||||
### General purpose
|
||||
|
||||
#### ✅ Modern Go Application by Márk Sági-Kazár [\[GitHub\]](https://github.com/sagikazarmark/modern-go-application)
|
||||
|
||||
Another example repository that we can recommend. It doesn’t cover patterns like DDD or Clean Architecture but emphasizes infrastructure beats like observability.
|
||||
|
||||
## Summary
|
||||
|
||||
Should we check some library that is not listed here? Please let us know in the [comments](https://threedots.tech/post/list-of-recommended-libraries/#disqus_thread)!
|
||||
Reference in New Issue
Block a user