vault backup: 2026-01-05 13:03:55
This commit is contained in:
 windyboy
+107
@@ -0,0 +1,107 @@
|
||||
---
|
||||
page-title: "50 AI/ChatGPT Prompts for Fitness Professionals - IDEA Health & Fitness Association"
|
||||
url: https://www.ideafit.com/group-fitness/50-ai-chatgpt-prompts-for-fitness-professionals/
|
||||
date: "2023-06-28 15:23:38"
|
||||
---
|
||||
|
||||
> has some experience with weightlifting but is looking for a training program that is tailored to his sport. Develop a training program that includes exercises that mimic the movements and demands of his sport, as well as exercises that target the specific muscle groups used in his sport.
|
||||
|
||||
---
|
||||
|
||||
Are you curious about using AI/ChatGPT prompts to inspire your exercise and class design? As a fitness professional, you know that creating personalized programs and classes for your clients is crucial for their success. However, with so many variables to consider, such as individual goals, fitness levels and limitations, designing effective plans can be time-consuming and challenging. [Artificial Intelligence](https://en.wikipedia.org/wiki/Artificial_intelligence) (AI) and Chatbots like ChatGPT can help you streamline your work and enhance clients’ experiences.
|
||||
|
||||
Here are just a few benefits of using AI/ChatGPT prompts to create classes and programs for your clients and participants, followed by 50 examples:
|
||||
|
||||
**It saves time.** With AI/ChatGPT, you can automate the process of creating workout plans and class structures, freeing up your time to focus on other areas of your business.
|
||||
|
||||
**You can personalize it**. You can analyze data such as client goals, fitness levels and preferences to create highly personalized workout plans and classes that are tailored to each individual’s needs.
|
||||
|
||||
**It provides adaptability**. As clients progress, you can use prompts to adjust their programs accordingly, ensuring that they continue to challenge themselves and see results.
|
||||
|
||||
**It’s efficient**. You can create programs and classes faster and more efficiently, allowing you to take on more clients and grow your business.
|
||||
|
||||
**You encourage engagement**. ChatGPT prompts can include interactive elements such as quizzes and surveys to keep clients engaged and motivated throughout their fitness journeys.
|
||||
|
||||
Using prompts to create classes and programs is an innovative and efficient way to enhance your clients’ experiences and grow your business. By automating the process of program design and personalizing workouts based on data, you can help your clients achieve their fitness goals faster and with less stress.
|
||||
|
||||
[*Use IDEA’s educational library to further customize your programs and classes.*](https://pro.ideafit.com/fitness-products?_gl=1*c4unvn*_gcl_aw*R0NMLjE2ODAxMDM3ODMuQ2owS0NRand3NC1oQmhDdEFSSXNBQzlnUjNhRFRlUXRJUE5rS2tlTlF1ajJZRWtHQ05rMzZPVERYV3REanFQZlBvRXJzNWZDcXh0SmdQQWFBako2RUFMd193Y0I.&)
|
||||
|
||||
## What is a ChatGPT Prompt?
|
||||
|
||||
In the context of AI, a prompt is a piece of text or a question that a user provides to an AI system, such as ChatGPT, to initiate a response or generate a specific output. A novice interacting with ChatGPT can think of a prompt as a request for information or a prompt for a conversation. For example, you can input “Can you tell me about the weather today?” to receive a response. The quality of the response generated by ChatGPT is often dependent on the clarity and specificity of the prompt provided by the user.
|
||||
|
||||
All you have to do is sign up for a [free account](https://chat.openai.com/) and copy and paste the prompts below, refining as needed to inform your program and class design.
|
||||
|
||||
## 50 Al/ChatGPT Prompts
|
||||
|
||||
If you’re a personal trainer or group fitness instructor looking to take your business to the next level, we’ve created 50 AI/ChatGPT prompts to get you going, 25 for personal trainers and 25 for group fitness instructors. Keep in mind that these are still pretty general, and you should use them in concert with your own knowledge about the client. The more detailed the prompt, the better, and no one knows program or class design like you do.
|
||||
|
||||
Always rely on your education and resources from IDEA and other fitness industry organizations. This is a great tool to add to your toolbox, but it’s not going to do all the work for you!
|
||||
|
||||

|
||||
|
||||
## Al/ChatGPT Prompts for Personal Trainers
|
||||
|
||||
1. John is a man in his 30s who wants to improve his athletic performance in a specific sport. He has some experience with weightlifting but is looking for a training program that is tailored to his sport. Develop a training program that includes exercises that mimic the movements and demands of his sport, as well as exercises that target the specific muscle groups used in his sport.
|
||||
2. Cecelia is a woman in her 40s who wants to build strength and muscle tone but has limited access to gym equipment. Develop a training program that uses bodyweight exercises, resistance bands and other portable equipment to help her build strength and muscle tone.
|
||||
3. James is a man in his 50s who wants to improve his overall fitness and reduce his risk of chronic diseases such as diabetes and heart disease. He has some experience with exercise but is looking for a more structured training program. Develop a training program that includes a mix of cardiovascular and strength training exercises and also includes a nutrition plan that emphasizes healthy eating habits.
|
||||
4. Margie is a woman in her 60s who wants to improve her bone density and reduce her risk of osteoporosis. She has some experience with weightlifting but is looking for a training program that is tailored to her specific needs. Develop a training program that includes resistance training exercises that target the bones, as well as exercises that improve balance and flexibility.
|
||||
5. Clarence is a man in his 70s who wants to maintain his muscle mass and independence as he ages. He has some experience with exercise but is looking for a training program that is safe and effective for his age group. Develop a training program that includes exercises that target the major muscle groups, as well as exercises that improve balance and mobility.
|
||||
6. Jay is a non-binary college student who wants to increase their overall fitness and strength. They have access to a gym but is unsure of how to create an effective workout plan. Develop a training program that focuses on resistance training and incorporates a variety of exercises that target different muscle groups.
|
||||
7. Miranda is a woman in her 50s who wants to improve her posture and reduce back pain. She spends most of her day sitting at a desk and has developed poor posture habits. Develop a training program that includes exercises that target the muscles involved in maintaining good posture, such as the back and core muscles, and also includes mobility and flexibility exercises.
|
||||
8. Tyrone is a man in his 40s who has recently been diagnosed with high blood pressure. He wants to improve his cardiovascular health and lower his blood pressure through exercise. Develop a training program that includes low-impact exercises, such as walking or cycling, and incorporates interval training and strength training exercises to improve his cardiovascular health.
|
||||
9. Tara is a woman in her 20s who wants to improve her flexibility and balance. She has some experience with yoga but wants to try new exercises that challenge her body. Develop a training program that incorporates exercises such as balance boards, resistance bands and foam rollers to improve her flexibility and balance.
|
||||
10. Glen is a man in his 30s who wants to increase his endurance and prepare for a long-distance running event. He has some experience with running but wants to develop a more structured training plan. Develop a training program that includes a mix of distance running, interval training and strength training exercises to help him build endurance and reduce his risk of injury.
|
||||
11. Karen is a woman in her 40s who wants to improve her overall fitness and lose weight. She has tried several diets in the past without success and is looking for a more sustainable approach. Develop a training program that includes a mix of cardiovascular and strength training exercises and also includes a nutrition plan that emphasizes whole, nutrient-dense foods.
|
||||
12. Stan is a man in his 50s who wants to improve his flexibility and mobility. He has some experience with yoga and Pilates but wants to try new exercises that challenge his body. Develop a training program that incorporates exercises such as foam rolling, dynamic stretching and yoga poses to improve his flexibility and mobility.
|
||||
13. Sandra is a woman in her 60s who wants to improve her balance and reduce her risk of falls. She has some experience with weightlifting but is looking for new exercises that can help her achieve her goals. Develop a training program that includes exercises that target the muscles involved in balance and stability, such as balance boards and single-leg exercises, and also includes flexibility and mobility exercises.
|
||||
14. Vin is a man in his 70s who wants to improve his overall fitness and maintain his independence as he ages. He has some experience with resistance training but is looking for new exercises that can help him achieve his goals. Develop a training program that includes low-impact exercises, such as walking or cycling, and incorporates interval training and strength training exercises to improve his overall fitness.
|
||||
15. Flo is a woman in her 80s who wants to maintain her mobility and independence as she ages. She has some experience with yoga and Pilates but is looking for new exercises that can help her achieve her goals. Develop a training program that includes exercises that target the muscles involved in mobility and balance, such as standing balance exercises and resistance band exercises, and also includes flexibility and mobility exercises.
|
||||
16. Laquetia is a middle-aged woman who wants to improve her flexibility and mobility. She is interested in learning yoga and Pilates. Design a training program that focuses on these disciplines and helps her achieve her goals.
|
||||
17. Conor is a young athlete who wants to build muscle mass and strength. He has some experience with weightlifting and is willing to follow a strict diet plan. Develop a training program that includes compound exercises and progressive overload principles to help him reach his goals.
|
||||
18. Tamara is a busy professional who wants to lose weight and improve her cardiovascular health. She enjoys running but struggles to find the time to exercise regularly. Develop a training program that includes high-intensity interval training and provides a flexible schedule to accommodate her busy lifestyle.
|
||||
19. Finn is an older man who has recently recovered from a hip replacement surgery. He wants to regain his strength and mobility, but he is unsure of what exercises are safe for him to perform. Develop a training program that focuses on low-impact exercises, balance training and flexibility exercises to help him regain his strength and mobility safely.
|
||||
20. Jazelle is a young woman who wants to prepare for a fitness competition. She has experience with weightlifting but wants to improve her overall physique and increase her endurance. Develop a training program that includes a mix of resistance training, cardio and flexibility exercises and also includes a nutrition plan that supports her competition goals.
|
||||
21. Maria Elena is a teenager who wants to improve her overall fitness and coordination. She is interested in trying different types of physical activities, such as rock climbing and martial arts. Develop a training program that includes a variety of activities that promote cardiovascular health, strength, and coordination, and is tailored to her age and fitness level.
|
||||
22. Rosa is a woman in her 40s who has never exercised before. She is overweight and wants to improve her health and fitness levels. Develop a training program that includes low-impact exercises and provides a gradual progression to help her build endurance and strength over time.
|
||||
23. Jesus is a man in his 50s who wants to improve his golf game. He has some experience with weightlifting but wants to focus on exercises that will help him increase his power and flexibility on the golf course. Develop a training program that includes exercises that target the muscles involved in the golf swing and improve flexibility and mobility.
|
||||
24. Xi is a woman in her 30s who has just given birth to her first child. She wants to regain her pre-pregnancy fitness levels and also improve her overall strength and endurance. Develop a training program that includes postpartum-specific exercises, such as pelvic floor strengthening and diastasis recti exercises, as well as cardiovascular and strength training exercises that are safe for new mothers.
|
||||
25. Walter is a man in his 60s who wants to improve his balance and reduce his risk of falls. He has some experience with yoga and Pilates but wants to try new exercises that can help him achieve his goals. Develop a training program that includes exercises that target the muscles involved in balance and stability, such as standing balance exercises and single-leg exercises.
|
||||
|
||||
*[See also: Can an AI App Help us Eat Better?](https://www.ideafit.com/nutrition/can-an-ai-app-help-us-eat-better-fitgenie-wants-to-try/)*
|
||||
|
||||

|
||||
|
||||
## Al/ChatGPT Prompts for Group Fitness Instructors
|
||||
|
||||
1. Design a kettlebell training class for individuals in their 30s and 40s who are looking to improve strength, endurance and overall fitness.
|
||||
2. Create a hiking fitness class for individuals in their 50s and above, incorporating uphill and downhill walks that improve cardiovascular health, leg strength and overall mobility.
|
||||
3. Develop a Zumba class for teenagers ages 13-17, incorporating high-energy dance movements that improve coordination, rhythm, and overall fitness.
|
||||
4. Design a functional fitness class for individuals in their 60s and above, incorporating exercises that improve balance, flexibility, and overall strength.
|
||||
5. Create a cardio sculpting class for individuals in their 20s and 30s, incorporating cardio and strength training exercises that target specific muscle groups and promote overall fitness.
|
||||
6. Create a barre class for beginners in their 20s and 30s, focusing on toning and sculpting the body while improving flexibility and balance.
|
||||
7. Design a cardio kickboxing class for individuals with physical disabilities, emphasizing modified exercises that promote cardiovascular health and full-body engagement.
|
||||
8. Develop a meditation and mindfulness class for individuals experiencing high levels of stress or anxiety, incorporating breathing techniques and guided meditation to promote relaxation and mental clarity.
|
||||
9. Create a family-friendly fitness class for parents and their young children, incorporating games and exercises that promote physical activity and family bonding.
|
||||
10. Design a suspension training class for seniors in their 70s and above, emphasizing functional exercises that improve strength, balance and overall mobility.
|
||||
11. Develop a cycling class for individuals with cardiovascular disease, incorporating low-impact exercises that improve cardiovascular health without putting stress on the joints.
|
||||
12. Create a powerlifting class for individuals in their 40s and 50s who are looking to build strength and muscle mass.
|
||||
13. Design a restorative yoga class for individuals recovering from injuries or surgery, emphasizing gentle stretches and poses that promote healing and relaxation.
|
||||
14. Develop a circuit training class for firefighters or other first responders, incorporating exercises that improve cardiovascular fitness, strength and endurance.
|
||||
15. Create a cardio dance class for individuals with Parkinson’s disease, emphasizing movements that promote balance, coordination and overall mobility.
|
||||
16. Design a high-intensity interval training (HIIT) class for busy professionals in their 30s who are looking to burn fat and improve cardiovascular fitness.
|
||||
17. Create a low-impact aerobics class for seniors in their 60s and above, focusing on improving balance, flexibility and overall mobility.
|
||||
18. Develop a yoga class for pregnant women in their second trimester, emphasizing postures that alleviate back pain and promote relaxation.
|
||||
19. Design a kickboxing class for teenagers ages 14-18, incorporating cardio and strength training to build endurance and confidence.
|
||||
20. Create a dance fitness class for adults in their 40s who are looking for a fun and effective way to lose weight and tone muscles.
|
||||
21. Develop a water aerobics class for individuals with arthritis or other joint conditions, emphasizing low-impact exercises that improve range of motion and reduce pain.
|
||||
22. Design a boot camp-style workout for postpartum mothers who are looking to regain their pre-pregnancy strength and stamina.
|
||||
23. Create a Pilates class for office workers in their 20s and 30s, focusing on core stability and posture correction to alleviate back pain caused by sitting all day.
|
||||
24. Develop a strength training class for women in their 50s and above, emphasizing exercises that improve bone density and muscle mass to prevent age-related muscle loss.
|
||||
25. Design a suspension training class for athletes or fitness enthusiasts in their 20s and 30s, incorporating functional exercises that improve athletic performance and overall fitness.
|
||||
|
||||
*[See also: Providing Great Customer Service in the Digital Age.](https://www.ideafit.com/personal-training/providing-excellent-customer-service-in-the-digital-age/)*
|
||||
|
||||
Remember that AI/ChatGPT prompts aren’t going to do all the work for you! It’s important to stay up to date with your [continuing education credits](https://pro.ideafit.com/fitness-products?_gl=1*3tmdon*_gcl_aw*R0NMLjE2ODAxMDM3ODMuQ2owS0NRand3NC1oQmhDdEFSSXNBQzlnUjNhRFRlUXRJUE5rS2tlTlF1ajJZRWtHQ05rMzZPVERYV3REanFQZlBvRXJzNWZDcXh0SmdQQWFBako2RUFMd193Y0I.&) and stay engaged in the fitness industry community so that you can remain current with all the research and trends.
|
||||
|
||||
*When you buy something using the retail links in our content, we may earn a small commission. IDEA Health and Fitness Association does not accept money for editorial reviews. Read more about our [Terms & Conditions](https://pro.ideafit.com/terms-conditions? "https://pro.ideafit.com/terms-conditions") and our [Privacy Policy](https://www.ideafit.com/privacy-policy/ "https://www.ideafit.com/privacy-policy/").*
|
||||
+206
@@ -0,0 +1,206 @@
|
||||
---
|
||||
page-title: "8 Best ChatGPT Uses for Cyclists: Next Level Cycling AI Assistant"
|
||||
url: https://www.bicycle-guider.com/chat-gpt-uses-for-cyclists/
|
||||
date: "2023-06-28 15:27:30"
|
||||
---
|
||||
We are reader-supported. We may earn an affiliate commission when you buy through the links on our site. [Read More...](https://www.bicycle-guider.com/about-and-contact/#affiliate)
|
||||
|
||||
|
||||
|
||||
If you’ve kept up with the news over the past weeks, you’ll undoubtedly have heard about OpenAI’s ChatGPT and some of the extraordinary things it’s being used for (or the controversies it has created).
|
||||
|
||||
It can answer questions about complex topics, summarize information, troubleshoot issues, and much more.
|
||||
|
||||
While the program has plenty of limitations at this **early stage of its development**, it’s still valuable if you know how to ask the right questions and understand its shortcomings.
|
||||
|
||||
We’ve decided to go down the AI rabbit hole, delve deeper into ChatGPT’s numerous functions, and see how helpful it can be for cyclists.
|
||||
|
||||
So here are eight applications of ChatGPT that we liked the most and, as cyclists, definitely plan to use again.
|
||||
|
||||
## What Is ChatGPT and How Does It Work?
|
||||
|
||||
[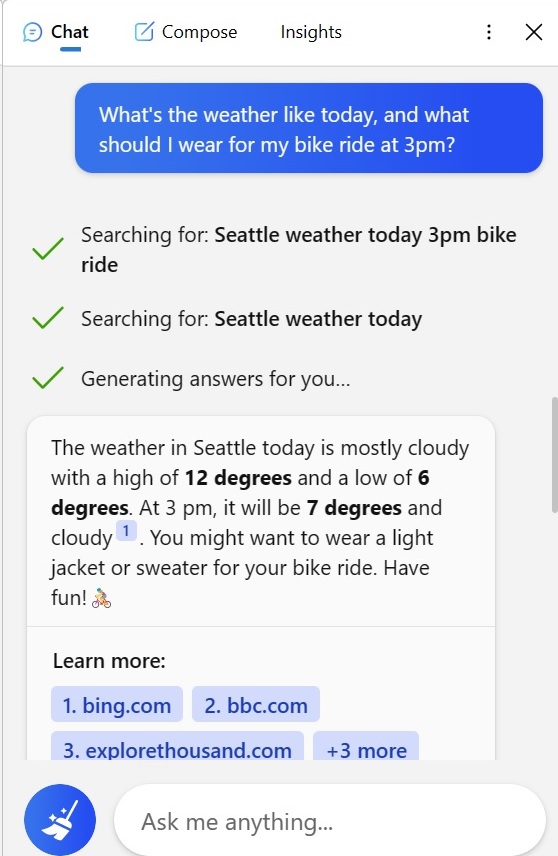](https://www.bicycle-guider.com/wp-content/uploads/2023/03/chatgpt-weather-1-1.jpg)ChatGPT is a computer program, also known as a large language model. It functions like a chatbot, mimicking human conversation; you ask questions, and it answers. It can answer questions, create content, summarize vast swaths of information, and debug computer code.
|
||||
|
||||
This language model is a type of artificial intelligence (AI) trained using enormous amounts of text data and human feedback.
|
||||
|
||||
> During human training, the AI is given feedback on tasks to improve future results and allow the program to learn and improve more quickly and effectively.
|
||||
|
||||
The way the model is programmed and trained means it can understand everyday language and accurately **answer the questions you pose, much like a human would**.
|
||||
|
||||
The system can also learn from previous interactions to improve future answers and make them more relevant. Check out the screenshot above for an example of how it works (the degrees are in celsius).
|
||||
|
||||
This ability to understand context and improve over time makes ChatGPT and large language models so revolutionary. For example, it’s already capable of answering university-level test questions better than the average student.
|
||||
|
||||
### What Are the Practical Uses of ChatGPT?
|
||||
|
||||
ChatGPT has enormous potential for use in both commercial and private contexts.
|
||||
|
||||
For individuals, it can be a personal assistant, organize our calendar, set reminders, schedule appointments, or create itineraries for work or travel.
|
||||
|
||||
> It can help cyclists research and compare different products, develop meal or training plans, or provide information or instructions on specific bike-related topics.
|
||||
|
||||
The examples above barely scratch the surface of what AI will do for us in the coming months and years.
|
||||
|
||||
### How to Use ChatGPT: Formulating and Refining Prompts
|
||||
|
||||
Firstly, you must visit [OpenAI’s website](https://chat.openai.com/) and set up an account. As of publication (April 2023), ChatGPT only has access to the information published online until September 2021.
|
||||
|
||||
However, you can also access the program on Microsoft’s Edge web browser Bing, called Bing AI Chatbot. This version has access to up-to-date information as it is able to browse the internet.
|
||||
|
||||
Once registered on OpenAI or Bing, you can begin asking ChatGPT questions, as seen in the example above. Again, it’s essential to **be clear and concise, use everyday language**, and avoid typos to ensure it understands and provides the best results possible.
|
||||
|
||||
As mentioned, the system continues learning, so you can get better answers with better questions and by following up with more specific queries. You’ll see some examples of follow-up questions in the sections below.
|
||||
|
||||
### Chat GPT’s Limitations
|
||||
|
||||
ChatGPT is an impressive AI that is growing and learning at an incredible rate. OpenAI released the program so users could test it and help it learn. However, it’s still in its infancy and can fail or produce misleading or incorrect results.
|
||||
|
||||
For example, ChatGPT may produce technically correct responses that lack context or nuance or provide wrong information that it took from poor sources.
|
||||
|
||||
This issue is particularly concerning because **incorrect answers are usually said definitively and with complete confidence**, even when they are incorrect.
|
||||
|
||||
Unfortunately, this assuredness may lead to people accepting inaccurate information as true.For this reason, it’s essential to be critical of any responses, especially when dealing with complex or sensitive topics.
|
||||
|
||||
While ChatGPT undoubtedly has its strengths, it is currently not a substitute for human expertise and judgment.
|
||||
|
||||
## 8 Best Ways Cyclists Can Use ChatGPT
|
||||
|
||||
ChatGPT, in its current form, is already capable of helping us with tasks such as research, planning, and troubleshooting.
|
||||
|
||||
Using the version available through Microsoft Bing, you can plan routes based on weather, as seen above, or you can research and compare products for a purchase you plan to make.
|
||||
|
||||
Let’s look at eight ways cyclists can use it to make life easier and save time.
|
||||
|
||||
*NB: Click on any screenshot below to make it larger.*
|
||||
|
||||
### 1\. ChatGPT Can Create Cycling Training Programs
|
||||
|
||||
Cyclists can use ChatGPT to create a [cycling training plan](https://www.bicycle-guider.com/cycling-advice/training-plans/) to prepare for an upcoming event, such as a race or Gran Fondo.
|
||||
|
||||
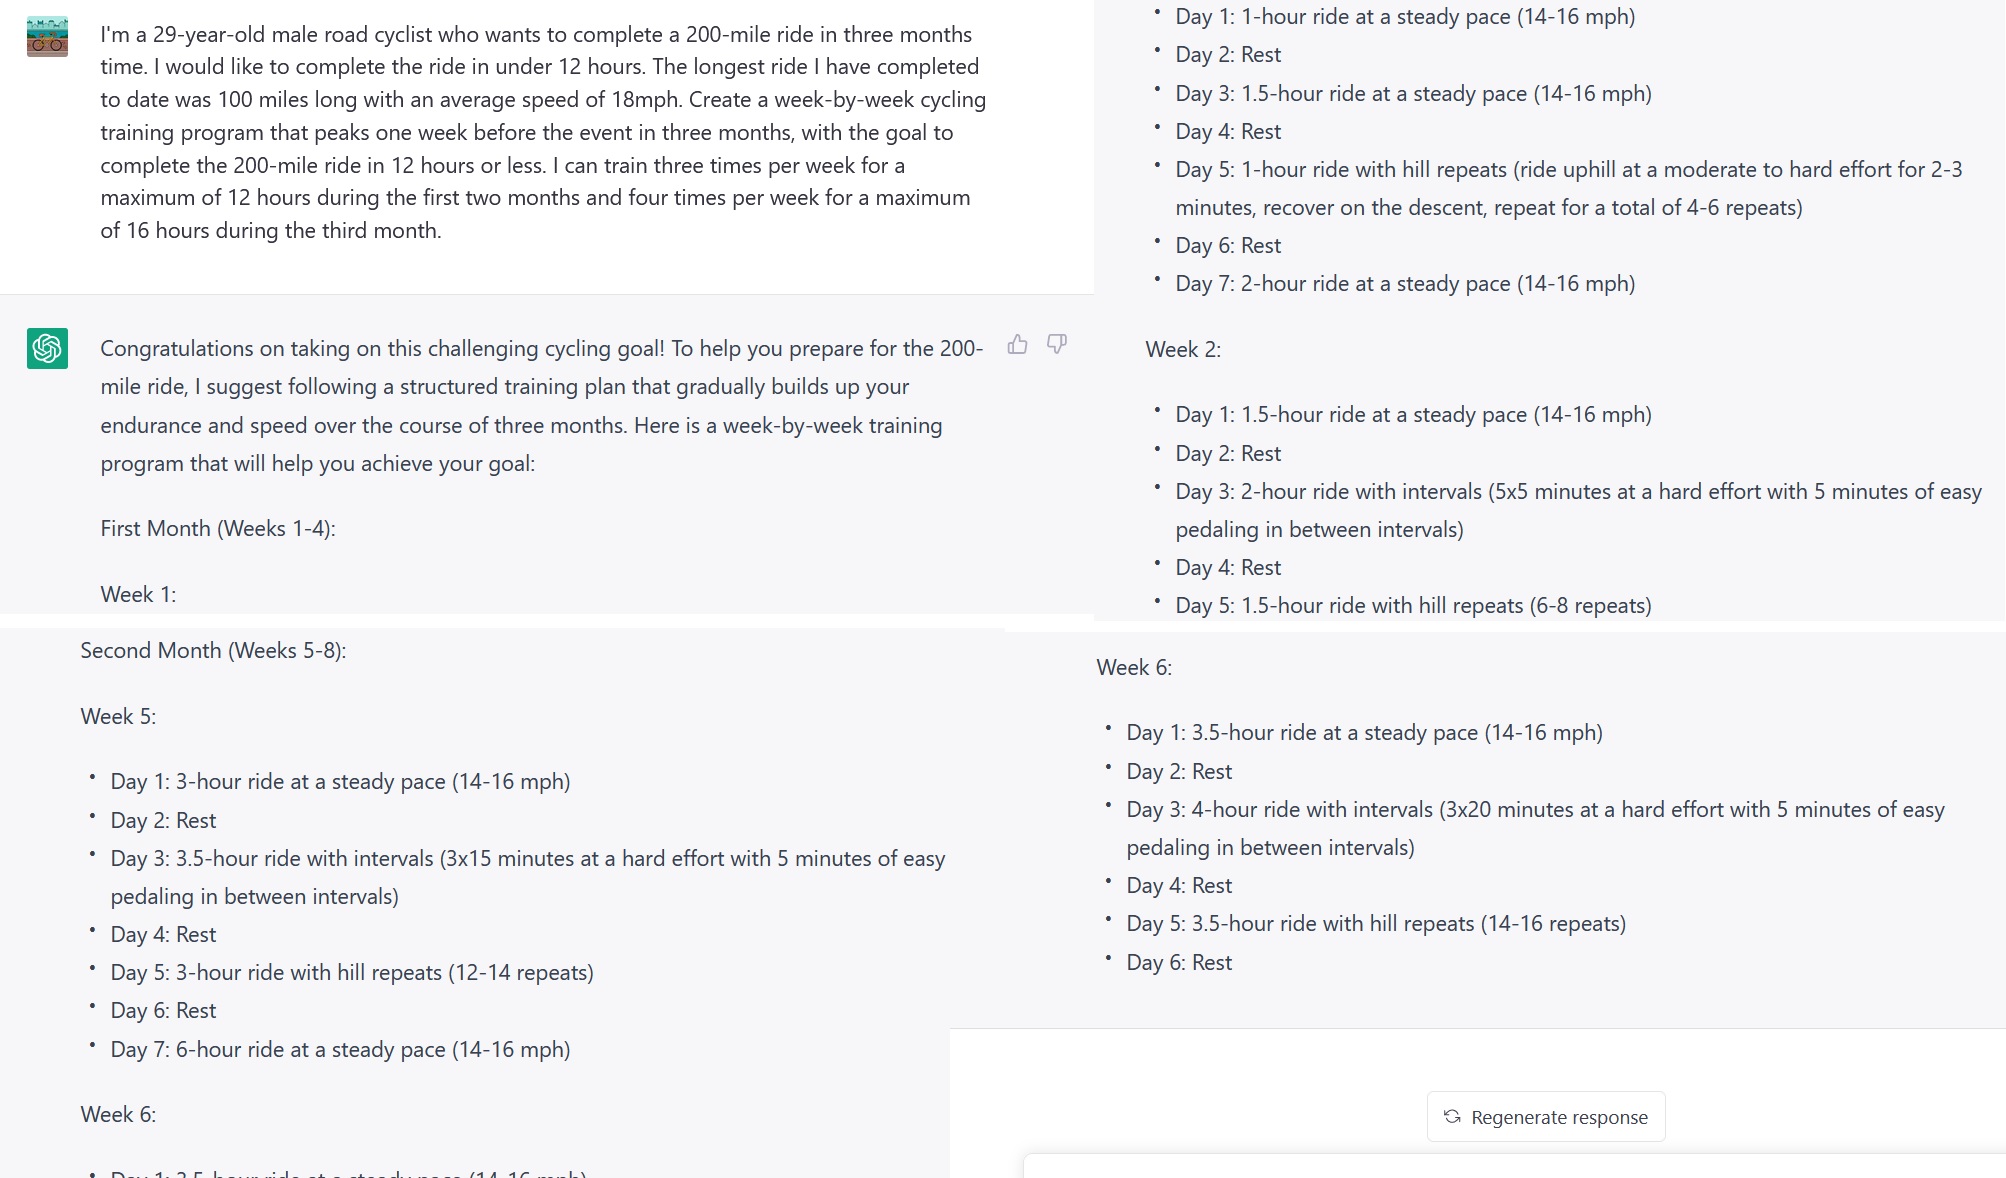
I gave the program some hypothetical information outlining ability, available training hours and days, and how much time there is before race day.
|
||||
|
||||
Have a look at what ChatGPT returned.
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/gpt-training-plan.jpg)
|
||||
|
||||
As you can see from what ChatGPT provided, it’s not a foolproof system.
|
||||
|
||||
Currently, it **struggles with simple math**, which is why it only returned a six-week training program, it didn’t consider my limitation of 12 hours (it gave a 15.5-hour training week in Week 5), and it provided four training rides instead of three.
|
||||
|
||||
Nonetheless, the mix of ride types, targeting of training zones, recovery time, and progression of training load indicate that the program is pulling from well-researched data on creating a cycling training plan and could help in other ways.
|
||||
|
||||
> To refine the results, you can point out the mistakes and it will generate a new response, taking into account the remarks you made.
|
||||
|
||||
To get more specific data to help you create your own plan, you can ask more probing questions, such as:
|
||||
|
||||
- I want to create a cycling training plan for an upcoming event. What steps should I follow, and what factors should I consider when developing the plan?
|
||||
- What types of rides should I do, and how many hours should I dedicate to each type of ride if I can train ten hours per week?
|
||||
- How should I progress my training load over a three-month training block?
|
||||
|
||||
### 2\. ChatGPT Can Review and Compare Bikes and Cycling Gear
|
||||
|
||||
ChatGPT can provide basic summaries of bicycles, gear, or other cycling products. In addition, you can use the Microsoft Bing version to summarize information about specific products.
|
||||
|
||||
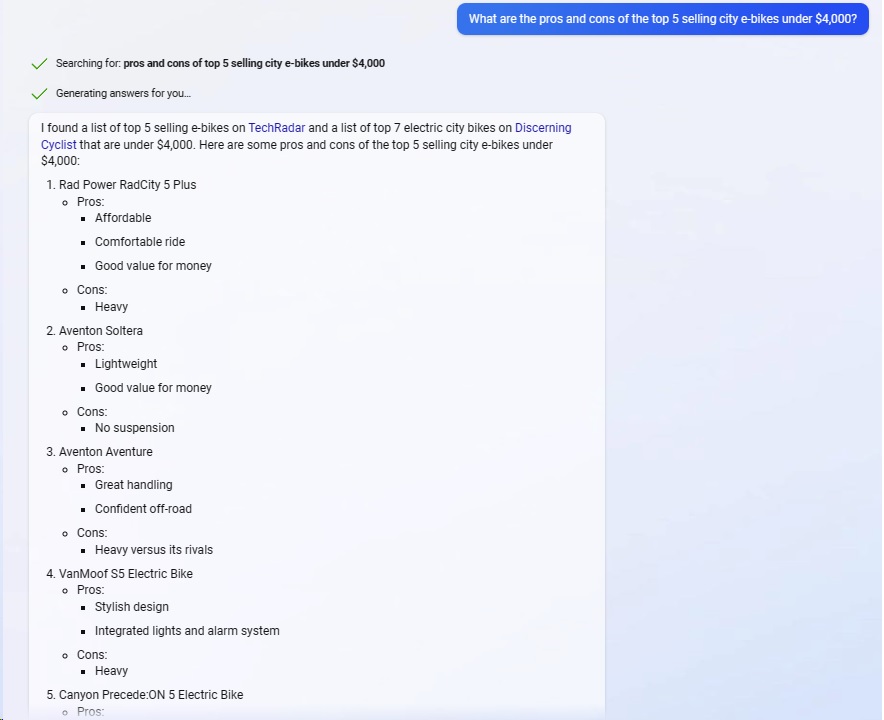
Look at the example below to see its response when asked about the top-selling city e-bikes under $4,000.
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/bike-comparison-2.jpg)
|
||||
|
||||
In this example, ChatGPT searched the internet and took information from two sources, Tech Radar and Discerning Cyclist.
|
||||
|
||||
We assume that it has taken a selection of bikes and pros and cons from each article and made a short summary based on that. However, **it’s impossible to know why it selected the bikes** and the points that it did.
|
||||
|
||||
With that in mind, we’d recommend using ChatGPT as a research tool while still relying on your favorite sites and trusted sources for product reviews.
|
||||
|
||||
The experts writing for these sites can bring together more information through experience and directed research to help you make the best decision.
|
||||
|
||||
### 3\. Create a Cycling Nutrition Plan with ChatGPT
|
||||
|
||||
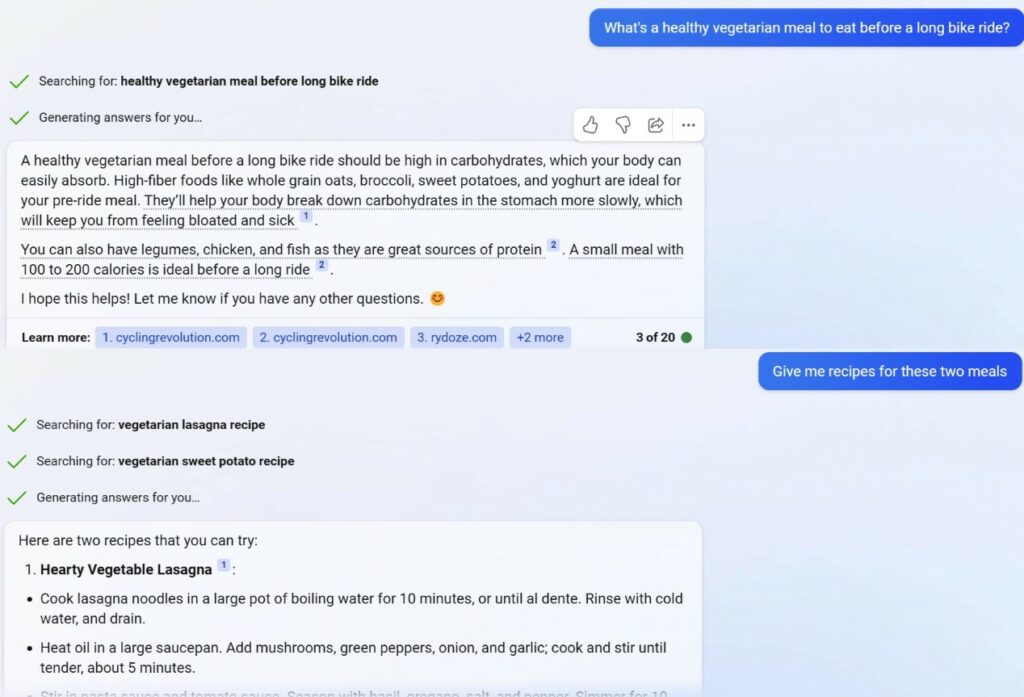
Cyclists can also leverage ChatGPT to help with nutrition plans or recipes if they’re unsure of what to eat on ride or race day.
|
||||
|
||||
For example, you can ask for meal recommendations, such as a pre-ride meal, with your specific dietary requirements and follow up by asking for recipes for the meal.
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/meal-plan-1.jpg)
|
||||
|
||||
You’ll note that the program pulled information from one site which says, “100 to 200 calories is ideal before a long ride,” which isn’t correct. Thankfully, Bing’s ChatGPT allows you to **click through to the resources it’s quoting from**, so you can double-check the website’s trustworthiness and sources.
|
||||
|
||||
> If any information doesn’t seem correct or is important, it’s worth double-checking.
|
||||
|
||||
[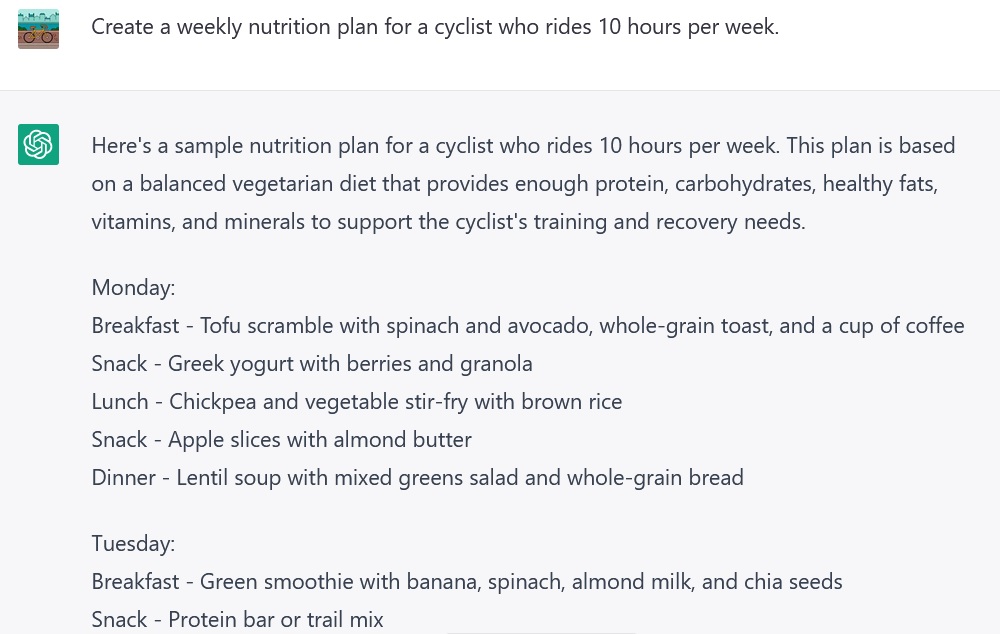](https://www.bicycle-guider.com/wp-content/uploads/2023/03/meal.jpg)On the right, you can see an example of how it will provide a weekly nutrition plan for a vegetarian with varied meals and snacks.
|
||||
|
||||
Follow up with prompts such as “Create a grocery list for this meal plan” or “Provide recipes for each meal on Monday” to get even more information.
|
||||
|
||||
### 4\. Create a Bike Touring Travel Plan with Chat GPT
|
||||
|
||||
[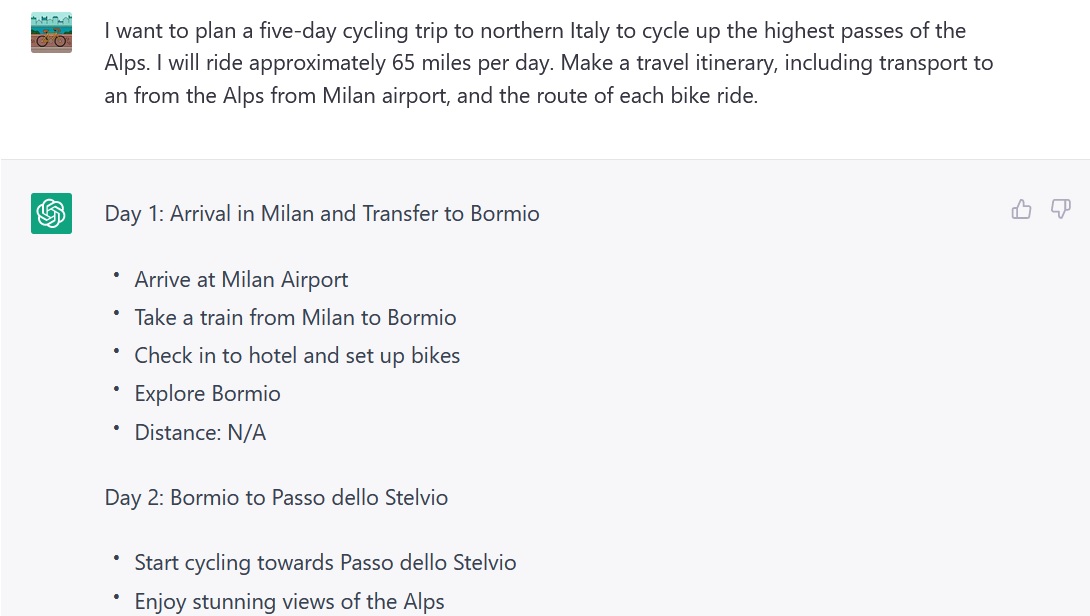](https://www.bicycle-guider.com/wp-content/uploads/2023/03/travel-itinerary.jpg)As mentioned, ChatGPT functions exceptionally well as a concierge, helping you plan trips and create itineraries for a vacation.
|
||||
|
||||
In the example to the right, you can see it provides details on which town to use as a base (Bormio) and how to get there, and it continues with four rides, the first of which is the famous Passo dello Stelvio.
|
||||
|
||||
By using the Bing version that’s connected to the internet, you could ask follow-up questions about hotels and restaurants to visit, the price of flights, and any other details you wanted, **double-check any information** provided to see that it’s accurate.
|
||||
|
||||
Keep in mind that sometimes its routes don’t make sense, especially when asked to provide you with directions to get from point A to point B.
|
||||
|
||||
However, it works relatively well for general tour planning as in the example above.
|
||||
|
||||
### 5\. Get Instructions for Maintenance, Repairs, and Adjustments
|
||||
|
||||
[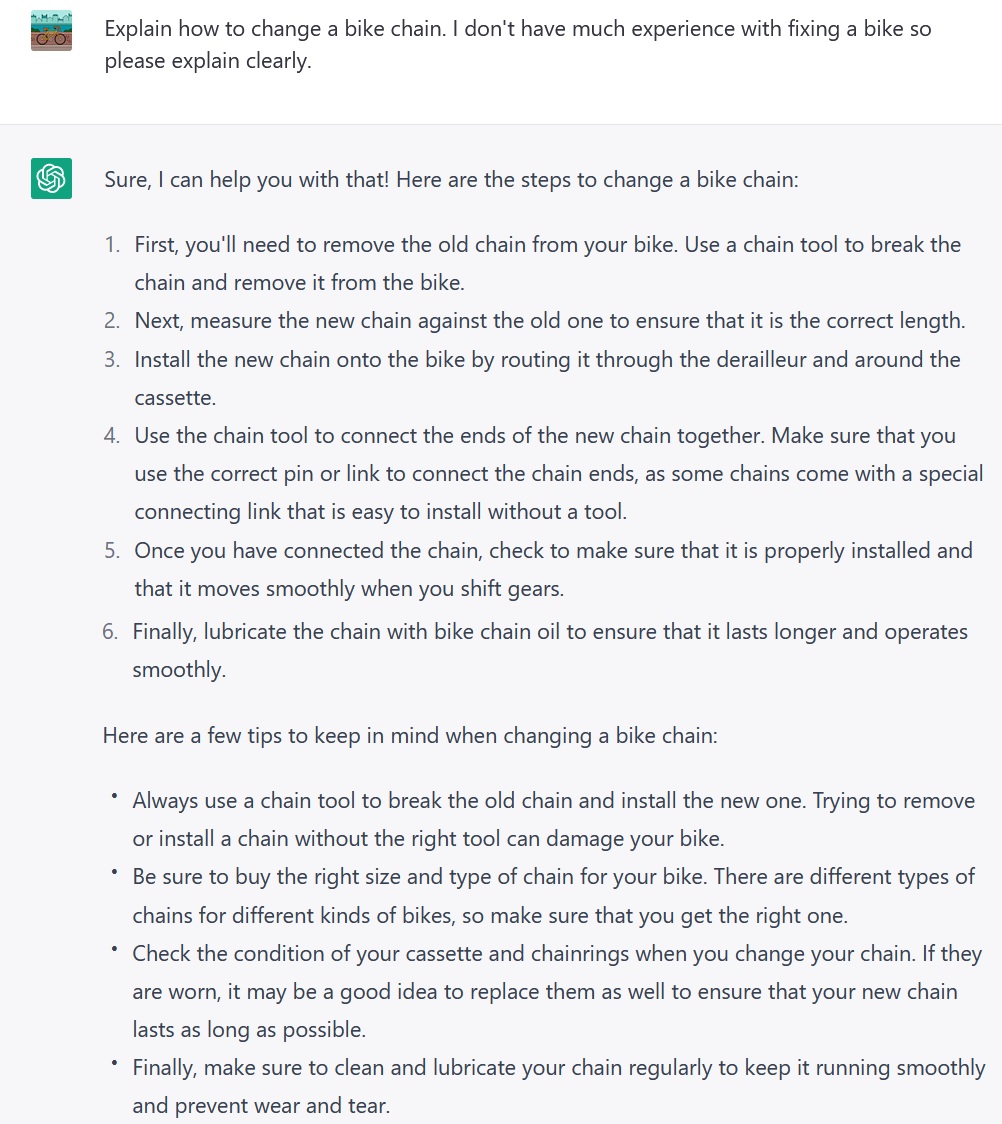](https://www.bicycle-guider.com/wp-content/uploads/2023/03/repair-and-maintenance.jpg)ChatGPT can also provide **step-by-step instructions** for adjustments, [bike maintenance](https://www.bicycle-guider.com/cycling-advice/bike-maintenance/), and repair tasks, such as setting saddle height, cleaning and lubing the drivetrain or [changing a chain](https://www.bicycle-guider.com/cycling-advice/bike-chain/) (as seen in the example).
|
||||
|
||||
Some points are vague and not detailed enough, but you can ask follow-up questions to get more precise instructions on a specific step if needed.
|
||||
|
||||
ChatGPT adds some tips for carrying out the process in this example. However, some of these aren’t very developed. For instance, it mentions checking your cassette and chainring for wear but doesn’t specify what to look for (pointed “shark tooth” teeth on the cogs). Though you can follow up with a request to elaborate on any point, which it will do in a leap.
|
||||
|
||||
Again, while it’s not foolproof, it offers a good starting point and summary of the process.
|
||||
|
||||
### 6\. Get Injury Recovery Advice
|
||||
|
||||
[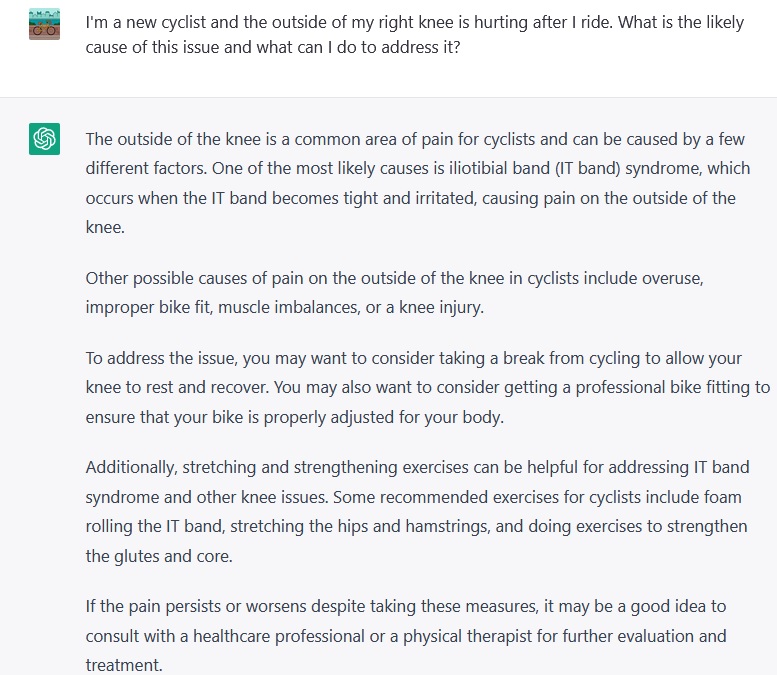](https://www.bicycle-guider.com/wp-content/uploads/2023/03/injury.jpg)Many people use the internet to diagnose injuries and illnesses by describing their symptoms and seeing what matches on sites like WebMD or different forums.
|
||||
|
||||
While we don’t recommend doing this for anything serious, it can be valuable to try to resolve the issue with the advice found online if your symptoms are not serious.
|
||||
|
||||
For example, many riders experience knee pain when they begin cycling. A common reason for this is [training too much](https://www.bicycle-guider.com/cycling-advice/overtraining-in-cycling/) before your muscles and connective tissues have had time to adapt. Likewise, a new bike or shoes that aren’t fit correctly can lead to knee pain.
|
||||
|
||||
If the pain isn’t severe, you could use ChatGPT to identify the possible causes by inputting the specific details of your symptoms and the context.
|
||||
|
||||
In this example, ChatGPT gave good recommendations with the caveat that if symptoms worsen, you should seek professional help.
|
||||
|
||||
Again, ChatGPT **can’t replace the care of a medical professional**, so always consult with your healthcare provider in the event of injury.
|
||||
|
||||
### 7\. Connect with Other Cyclists in Your Area
|
||||
|
||||
[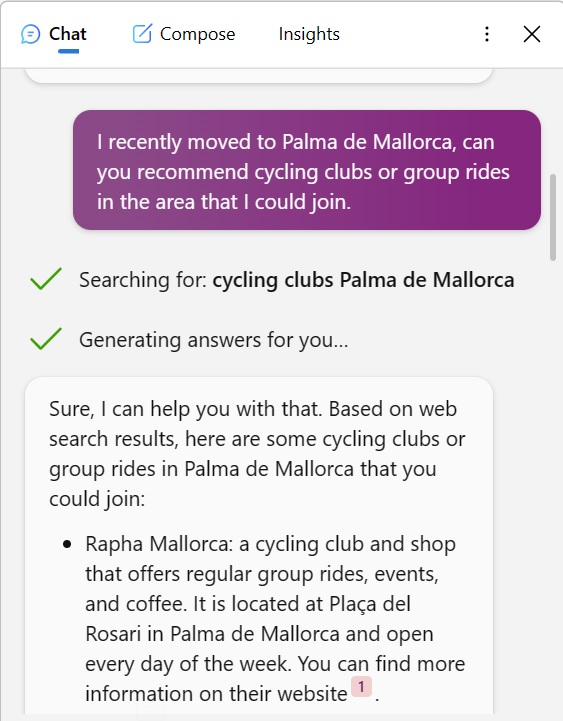](https://www.bicycle-guider.com/wp-content/uploads/2023/03/group.jpg)ChatGPT can recommend local cycling clubs, group rides, or online forums to connect with other cyclists and build a community.
|
||||
|
||||
For example, if you move to a new city or country, you can **skip the tedious research** and get ChatGPT (Bing version) to recommend local cycling clubs.
|
||||
|
||||
This version will provide clickable links, such as the club website or Google Maps, to show where the information comes from.
|
||||
|
||||
In addition, you can get recommendations for cycling-related forums where you can engage with other riders and share stories and experiences.
|
||||
|
||||
It’s unlikely that ChatGPT will find all clubs and groups as there must be details about the club online, so we’d recommend also asking locals to find out more information.
|
||||
|
||||
### 8\. Get Cycling Safety Tips
|
||||
|
||||
One final way to use ChatGPT, although we’re sure there are many more we haven’t thought of, is to provide [cycling safety and security tips](https://www.bicycle-guider.com/cycling-advice/bicycle-safety/).
|
||||
|
||||
This functionality is valuable if you’re new to cycling, commuting, riding an e-bike, or trying a new discipline for the first time.
|
||||
|
||||
ChatGPT can pull from the internet and **create a concise list of tips for any question** you ask.
|
||||
|
||||
For example, we’ve asked for general security and safety tips in the screenshot below. However, if you’re new to mountain biking, you could ask for specific recommendations on how to stay safe on the trails.
|
||||
|
||||
[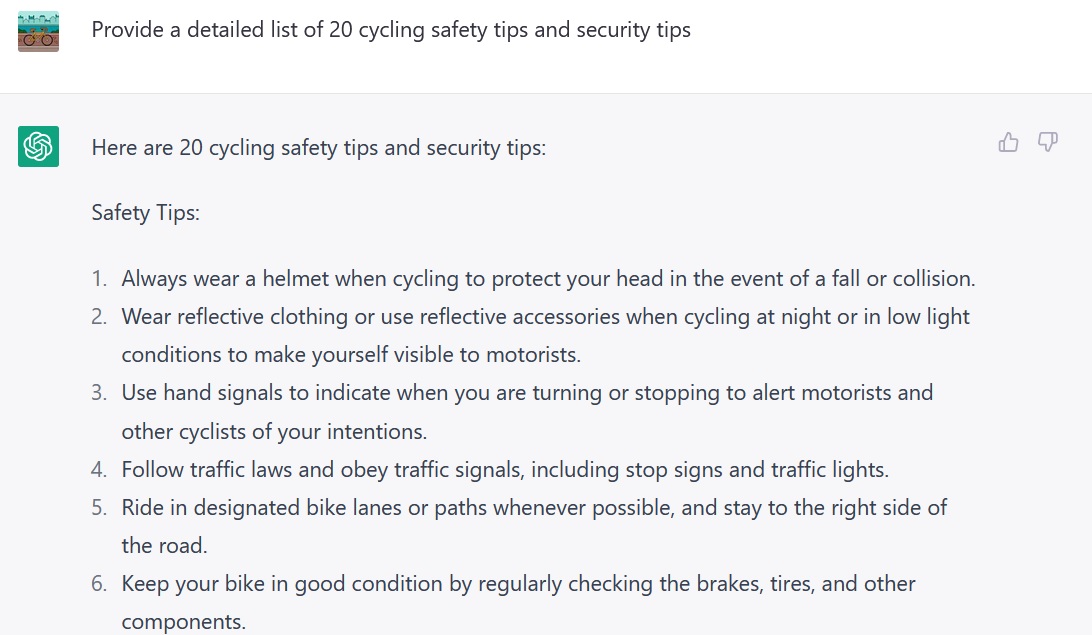](https://www.bicycle-guider.com/wp-content/uploads/2023/03/safety.jpg)
|
||||
|
||||
Remember that these lists are not exhaustive, and it’s still essential to use common sense and maybe do your own research by searching online or asking an experienced biker.
|
||||
|
||||
## In Conclusion
|
||||
|
||||
We believe ChatGPT is a powerful tool that can assist cyclists in various ways.
|
||||
|
||||
With its vast knowledge base and language capabilities, it can provide you with useful information on routes, weather conditions, and equipment. Moreover, it can offer you guidance on bike maintenance and repair, as well as help you connect with other riders and communities.
|
||||
|
||||
Overall, ChatGPT has the potential to enhance the cycling experience and make it safer, more enjoyable, and more accessible for people of all levels and backgrounds.
|
||||
|
||||
Just keep in mind that the technology is still in its infancy, so it’s advisable to double-check any information you get.
|
||||
|
||||
However, what’s exciting to realize is that this is the worst it will ever be, as impressive as it currently is.
|
||||
|
||||
There are no comments yet, add one below.
|
||||
+202
@@ -0,0 +1,202 @@
|
||||
---
|
||||
page-title: "API Design Practice. A practical guide to API QA and the… | by TRGoodwill | API Central | May, 2023 | Medium"
|
||||
url: https://medium.com/api-center/api-design-practice-7fce69e6336c
|
||||
date: "2023-06-02 15:52:06"
|
||||
---
|
||||
## API Design Practice
|
||||
|
||||
## A practical guide to API QA and the design of stable, coherent and composable business resource APIs
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/@trgoodwill?source=post_page-----7fce69e6336c--------------------------------)[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/api-center?source=post_page-----7fce69e6336c--------------------------------)
|
||||
|
||||
## Introduction
|
||||
|
||||
An API specification document is a technical artifact, offering little opportunity for meaningful and timely input from business and enterprise stakeholders. It is absolutely the wrong place to begin designing an API. When building an enterprise API catalog of reusable, stable, coherent and composable APIs, ***an enterprise-guided, domain-oriented API Design Practice is essential***.
|
||||
|
||||
## API Design Goals
|
||||
|
||||
The API Design Phase is centered around the capture and validation of the domain data model and the state-lifecycle of business resources. The quality of the data / REST model has significant impact on the usability, evolvabilty and security of an API.
|
||||
|
||||
Collaborative design workshops and modeling tools will allow a diverse group of stakeholders, from business owners, enterprise and domain architects, data modelers, security architects, REST and EDA SMEs, tech leads and developers, to interact with (and contribute to) the same domain data model, and be notified of changes that interest them.
|
||||
|
||||
In this way, the domain model “*acts as a* [*Ubiquitous Language*](https://martinfowler.com/bliki/UbiquitousLanguage.html) *to help communication between software developers and domain experts*” ([Fowler, M 2014, BoundedContext](https://martinfowler.com/bliki/BoundedContext.html)), maximizing collaboration, providing the tightest possible feedback loop, and ensuring that the domain model remains the definitive source-of-truth.
|
||||
|
||||
## Align Resource APIs with your Business Domain
|
||||
|
||||
From the business information, events and processes managed by a System-of-Record business service, are abstracted one or more canonical business resource APIs. Business resources represent the nouns of a system, such as ‘*applications*’ and ‘*applicants*’. They provide a context for interaction with a business capability, represent the business facts about a business domain, and when consistently modeled, discoverable and subscribable, they become the backbone of a federated data platform.
|
||||
|
||||
## Design for Composability
|
||||
|
||||
Microservices architectures and the REST architectural style enable decoupling, self-service and re-use by moving the responsibility for choreography from the resource server to the client. This shift in responsibility allows business systems to build stable, genericised interfaces to their business resources and capabilities, without tight coupling to client systems, which in turn allows client systems to compose data via self-service integration without a blocking dependency on external teams.
|
||||
|
||||

|
||||
|
||||
API clients will typically want access to core information about a specific business object, not complex data structures, and they want it FAST. A good REST model is concerned with finding a balance between granularity and cohesive units of business data likely to be of interest to client systems (though not superfluous to their needs). In short, *balancing* ***composability*** *with* ***cohesion***. Supporting elements may be [modeled as sub-resources](https://medium.com/@trgoodwill/api-design-pattern-for-business-resource-apis-6f25afd2b2df).
|
||||
|
||||
## Early and Continuous Stakeholder Engagement
|
||||
|
||||
Business domain expertise and enterprise API Design Standards inform The API Design Phase. A REST model provides the means for external systems to securely interact with business objects, data and processes via standard, generic RESTful operations. The quality of the model has significant impact on the usability, evolvabilty and security of an API.
|
||||
|
||||
There are many stakeholders invested in shaping and validating the model, stakeholders may include:
|
||||
|
||||
- Business owner (domain expert),
|
||||
- Domain architect,
|
||||
- Enterprise architects (Security, Data)
|
||||
- API Platform REST SME,
|
||||
- Tech lead / API Developers
|
||||
- Closely aligned client application teams.
|
||||
|
||||

|
||||
|
||||
## Plan the process
|
||||
|
||||
During the ***planning phase*** of the project, identify and engage a representative from each of the above-mentioned stakeholder groups. Consider whether there may be closely aligned client application teams or other invested parties that can contribute valuable feedback, and identify a representative from each of these teams.
|
||||
|
||||
## Remember that the process is iterative
|
||||
|
||||
Capture your understanding of the domain as early as possible — and use collaborative tools and a shareable model to elicit corrections and input from stakeholders.
|
||||
|
||||
## Preparation
|
||||
|
||||
Identify the tools that you will use for the process and ensure that modellers and stakeholders are provided access. Developers/modellers should familiarize themselves with tools, processes and enterprise [API design standards](https://medium.com/api-center/writing-api-design-standards-84cb7cbb3fd7) prior to commencing the process.
|
||||
|
||||
“Bottom up” analysis of legacy systems can be helpful — but ONLY as a means for engineers to bring knowledge of as-is implementation into the room as a contribution to the larger discussion.
|
||||
|
||||
*More on API Standards:*
|
||||
|
||||
## 1\. Conduct Design Workshops
|
||||
|
||||
Set up an initial workshop with domain SMEs — those with a deep understanding of the business processes, regulatory obligations etc. Collaborative domain-oriented design workshops such as [Event Storming](https://www.eventstorming.com/) are a forum for ***mutual discovery, validation and agreement* on models**, boundaries and business events.
|
||||
|
||||
When running **design workshops** (onsite or online) with a number of stakeholders, a collaborative white-boarding tool will allow you to capture, share and validate perspectives on business events, processes, actors and entities. The Event Storming technique can provide some structure to design workshops, and a means to capture collective knowledge about the domain.
|
||||
|
||||

|
||||
|
||||
A brief overview of the Event Storming process is as follows:
|
||||
|
||||
1. **Identify a scenario:** A short and focused bullet-point description of the process to be captured.
|
||||
2. **Identify events:** the things that are happening in your domain — written in past tense and expressed as a flow or sequence.
|
||||
3. **Capture commands and aggregates/entities:** as well as actors, external systems, processes/policies and problems/hot-spots as appropriate.
|
||||
4. **Identify bounded contexts:** independent clusters of common language and functionality — each bounded context should be ‘decoupled’, expressing its own model, and its own API/s.
|
||||
|
||||
The Event Storming process employs coloured ‘sticky notes’ (either physical or digital) to explore, organise and iterate on emerging elements of the scenario. Time-boxing phases of the workshop is an important element of the process. A [Miro Event Storming Template](https://miro.com/miroverse/event-storming/) will help you get started.
|
||||
|
||||
A validated high-level view of business events, commands, aggregates & entities is a key input into the domain data model.
|
||||
|
||||
## 2\. Model the Data & Continuously Validate
|
||||
|
||||
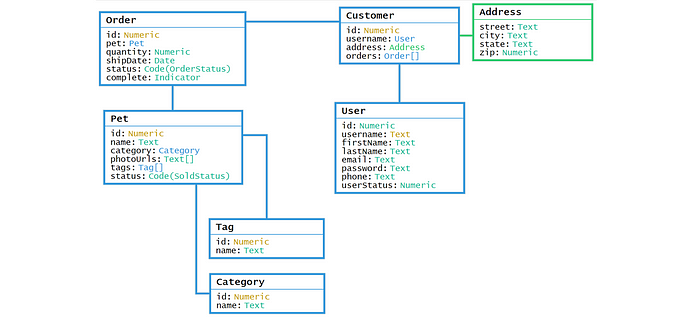
Capture the aggregates/entities that emerge from design workshops in collaborative data modelling tooling and engage key stakeholders to validate and enrich the model. Consider [Enterprise Naming Conventions](https://medium.com/api-center/api-bites-payload-conventions-76ffde7f5eb2).
|
||||
|
||||
Explore with ***enterprise data architects and domain architects*** the applicability of industry models and formalisms, and re-use of ‘enterprise’ entity arch-types such as address data structures etc.
|
||||
|
||||
|
||||
|
||||
As soon as baseline agreement on the data managed by a system-of-record emerges, seek the advice of ***security architecture*** on the classification, caveats and controls applicable to the data. Make annotations in the model against each entity.
|
||||
|
||||
Consider [REST Modelling Guidance](https://medium.com/@trgoodwill/api-design-pattern-for-business-resource-apis-6f25afd2b2df), and validate composability and cohesion with ***API competency REST SMEs*** as the model develops. When developing the REST layer, consider [Enterprise API Path Conventions](https://medium.com/api-center/api-bites-7373b2127ed1) and [HTTP Request and Response Protocols](https://medium.com/api-center/api-bites-request-and-response-protocols-1f3a4f34cecf).
|
||||
|
||||
Iterate and circulate significant model changes to the wider group of stakeholders as often as possible — design tooling should assist with stakeholder notification.
|
||||
|
||||
## 3\. Generate and Refine your API Specifications
|
||||
|
||||
When the model is *relatively* stable, create a versioned snapshot of the model and generate a prototype API specification for technical review and validation. Version aligned API specifications are generated from the REST model, based on standards and policy-conformant rules or templates.
|
||||
|
||||
You may choose to work with an initial version “0.x.x” prototype API spec until you are ready to publish. Remember that b*eyond an initial V1,* [***major version increments***](https://medium.com/api-center/api-bites-1af949efdd1b) ***must only apply to breaking changes to production (‘live’) APIs****.*
|
||||
|
||||
## Validation and Refinement of your API Specification
|
||||
|
||||
API definition documents, whether hand-crafted, generated or pre-existing, will need to be reviewed and ***technically* *validated***, and in many cases further refined.
|
||||
|
||||
Use an IDE with OpenAPI/AsyncAPI document linting support — it will provide immediate feedback on API quality and mandatory API document rules.
|
||||
|
||||
API document linting rules should be clearly defined. [Spectral OpenAPI rules](https://github.com/stoplightio/spectral/blob/develop/docs/reference/openapi-rules.md) are widely referenced as a base OpenAPI document ruleset.
|
||||
|
||||
*More on API document linting:*
|
||||
|
||||
## Model Driven, API-First Development
|
||||
|
||||
API-first is a micro-or-modular service development model that treats APIs as the primary means of interacting with a business capability and the business facts about a domain. When these API ‘products’ are streamlined for consistency and re-usability, they contribute to a rich and composable federated data platform.
|
||||
|
||||
As a primary product of a service, the API is designed first, and used as a template for the service implementation. When building from a validated domain model and API definition document, product teams can take advantage of code generators to accelerate development.
|
||||
|
||||
From the API definition document, OpenAPI & AsyncAPI Generators can automatically create a consistent scaffold/skeleton implementation for supported languages (e.g. Java/Spring, Node.js). Mock servers and API Tests can also be generated from the API specification document.
|
||||
|
||||

|
||||
|
||||
For development to be both API-First and Model Driven, the API specification origin and source-of-truth must be the validated domain model.
|
||||
|
||||
## Legacy and Proprietary COTS/SaaS APIs
|
||||
|
||||
Legacy or COTS/SaaS API definition documents without a sharable data model are more difficult to validate, evolve and map to the enterprise context. However this situation arises when an organization is in transition to new platforms and architectures. Consider:
|
||||
|
||||
- Retrospectively capturing the API data model with Model-Driven-Design tooling.
|
||||
- Which elements of the API and/or OpenAPI document may be iteratively refined/refactored to align with API & document rules.
|
||||
- Whether a tactical “anti-corruption-layer” integration solution can provide a clean and conformant API
|
||||
|
||||
## API Design Tooling
|
||||
|
||||
## Design Workshop Tools
|
||||
|
||||
The ‘[Event Storming](https://docs.firstdecode.com/architecture/domain-driven-design/event-storming/)’ technique is white-board centered design workshop amenable to live online collaboration. [Judith Birmoser’s Event Storming template](https://miro.com/miroverse/event-storming/) for the the Miro digital white-board platform, or an [Event Storming template for Mural](https://app.mural.co/template/15ae8c65-6f71-44bf-bb6f-7db5d166de29/2e2cb128-5afb-450c-9a32-05db14b57f60) is an easy way to get started.
|
||||
|
||||

|
||||
|
||||
## Domain Data Modelling & Model Driven Design tooling
|
||||
|
||||
Domain modelling tooling should support OpenAPI/AsyncAPI document generation, source control, and management of semantic versioning across the model and its derivative artifacts — features that are helpful in maintaining the currency and traceability of published APIs.
|
||||
|
||||

|
||||
|
||||
The [Jargon](https://jargon.sh/) Domain Data Modelling Platform
|
||||
|
||||
Other platform features strongly supportive of model driven development include design-time model validation, documentation of state-lifecycles, (e.g. state-lifecycle diagrams), mapping and management of dependencies, notification management, and model discoverability, sharing and re-use.
|
||||
|
||||
Domain Data Modelling tooling (*with widely varying feature-sets*) includes:
|
||||
|
||||
- [Jargon Domain Data Modelling Platform](https://jargon.sh/)
|
||||
- [Stoplight Studio Enterprise](https://stoplight.io/enterprise)
|
||||
- [Visual Paradigm](https://www.visual-paradigm.com/solution/rest-api-design-tool/)
|
||||
- [Mendix Low-Code Platform](https://docs.mendix.com/refguide/domain-model/)
|
||||
- [Hackolade Studio](https://hackolade.com/help/OpenAPI.html)
|
||||
- [Sparx EA](https://www.sparxsystems.de/) + [OpenAPI plugin](https://inteca.com/enterprise-architect-plugins/)
|
||||
|
||||
## API Specification Technical Validation Tooling
|
||||
|
||||
[Spectral](https://stoplight.io/open-source/spectral) is a widely used open-source OpenAPI/AsyncAPI document linter with an extensible ruleset. The following tools support Spectral linting:
|
||||
|
||||
- **The** [**Jargon platform**](https://jargon.sh/) supports Spectral linting at the domain data and REST model layers.
|
||||
- [**Visual Studio Code**](https://code.visualstudio.com/) : Install the [‘Spectral’ extension by Stoplight](https://marketplace.visualstudio.com/items?itemName=stoplight.spectral). Rule errors and warnings are listed in the Problem console, and is updated dynamically as changes are made.
|
||||
- [**Stoplight Studio**](https://stoplight.io/studio) : Upload an OpenAPI or AsyncAPI specification and spectral will provide immediate dynamic feedback. The warning icon will toggle a side-by-side view.
|
||||
- **CI/CD pipeline** : As well as automated Sonarqube analysis of your software source code, integration & build pipelines can support spectral linting of your OpenAPI definition to ensure timely feedback on document quality issues.
|
||||
|
||||
## Code Generation Tools
|
||||
|
||||
There are various locally configurable generators available for different programming languages. Here are some resources:
|
||||
|
||||
- [OpenAPI Design & Documentation Tools | Swagger](https://swagger.io/tools/)
|
||||
- OAS OpenAPI generators: [https://openapi-generator.tech/docs/generators/](https://openapi-generator.tech/docs/generators/) and [https://github.com/OpenAPITools/openapi-generator](https://github.com/OpenAPITools/openapi-generator)
|
||||
- Various OpenAPI Tools: [https://openapi.tools/](https://openapi.tools/)
|
||||
|
||||
## Test Generation
|
||||
|
||||
The following is a (non-exhaustive) list of testing platforms that support test generation from an OpenAPI and/or AsyncAPI specification document:
|
||||
|
||||
[Postman API Platform](https://www.postman.com/), [Thunder Client — Extension for VS Code](https://www.thunderclient.com/), [karatelabs/karate](https://github.com/karatelabs/karate), [Pact (pact.io)](https://docs.pact.io/), [Katalon Quality Management](https://katalon.com/), [Insomnia API Dev Platform](https://insomnia.rest/), [SOAPUI](https://www.soapui.org/docs/rest-testing/), [REST-Assured](https://github.com/rest-assured/rest-assured) + [Tcases](https://github.com/Cornutum/tcases/blob/master/tcases-openapi/README.md#tcases-for-openapi-from-rest-ful-to-test-ful)
|
||||
|
||||
## Wrap-up
|
||||
|
||||
An API specification document is a technical document. It is often generated well into the development effort, and is difficult for less technical stakeholders to parse. Without a guided API design practice, a large enterprise will struggle to govern the quality of business APIs.
|
||||
|
||||
In order to maximize opportunities for stakeholder collaboration and provide the tightest possible feedback loop, it important to capture, share and validate REST models well before anything is committed to code. A clearly defined and supported API design practice can ensure that both APIs and their underlying data models are visible, re-usable and governable.
|
||||
+331
@@ -0,0 +1,331 @@
|
||||
---
|
||||
page-title: "Building Your Own DevSecOps Knowledge Base with OpenAI, LangChain, and LlamaIndex | by Wenqi Glantz | May, 2023 | Better Programming"
|
||||
url: https://betterprogramming.pub/building-your-own-devsecops-knowledge-base-with-openai-langchain-and-llamaindex-b28cda15abb7
|
||||
date: "2023-06-02 12:38:49"
|
||||
---
|
||||
## Building Your Own DevSecOps Knowledge Base with OpenAI, LangChain, and LlamaIndex
|
||||
|
||||
## Building your custom knowledge base chatbot
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/@wenqiglantz?source=post_page-----b28cda15abb7--------------------------------)[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://betterprogramming.pub/?source=post_page-----b28cda15abb7--------------------------------)
|
||||
|
||||
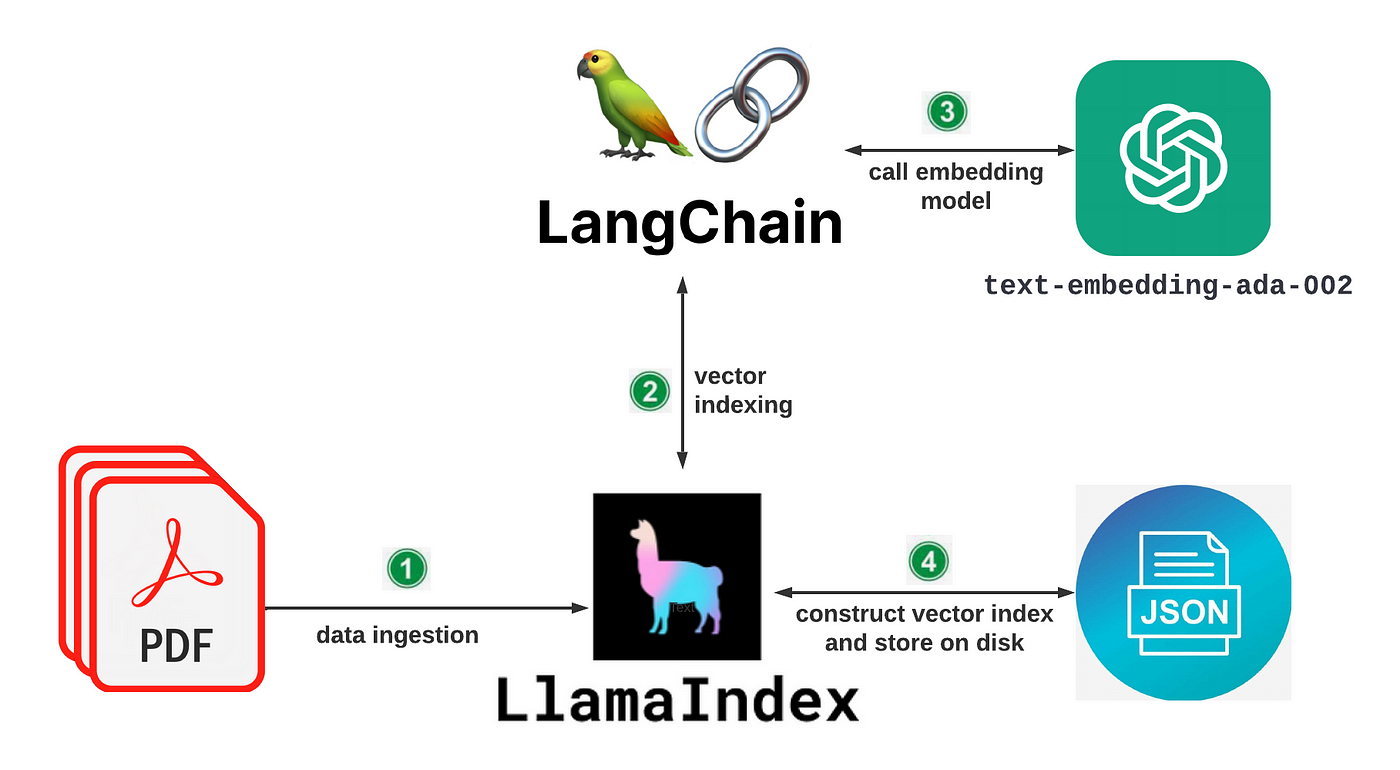
|
||||
|
||||
Diagram by author
|
||||
|
||||
DevSecOps is a big part of what I do daily at my current job. I love learning in the DevSecOps space and sharing my knowledge with others through blogging. Often, I find myself searching through my articles for the information I need. Wouldn’t it be nice to build my own custom knowledge base for DevSecOps so I can feed my files or articles to it and search it when needed?
|
||||
|
||||
In this article, let’s explore building a custom DevSecOps knowledge base using OpenAI, LangChain, and LlamaIndex (GPT Index).
|
||||
|
||||
## High-Level Architecture
|
||||
|
||||
We are going first to feed my article files to our knowledge base. Then we query our knowledge base with questions from my article files related to DevSecOps.
|
||||
|
||||
Let’s split the architecture into two stages: data ingestion/indexing and data querying.
|
||||
|
||||
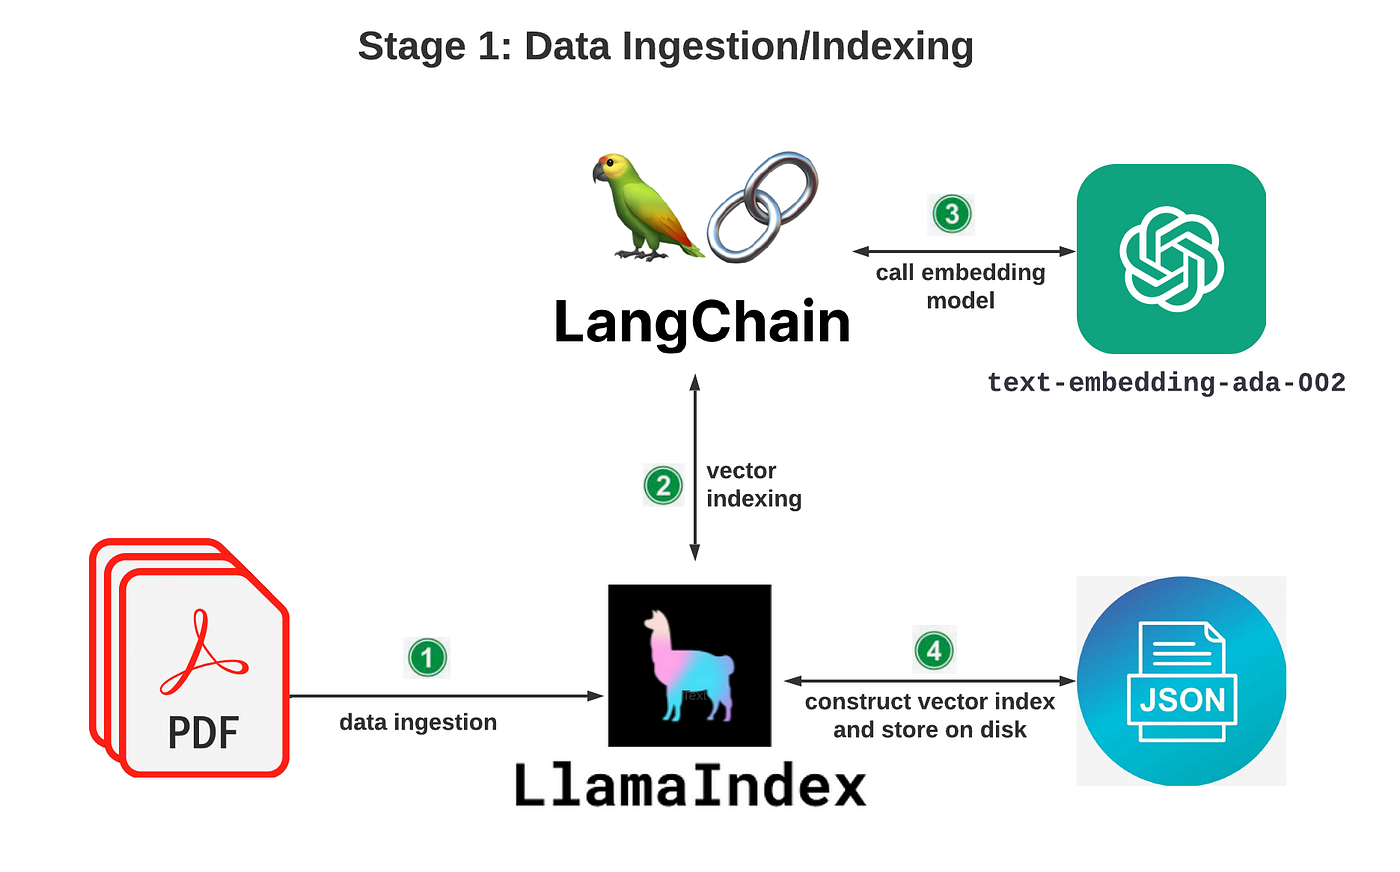
|
||||
|
||||
Diagram by author
|
||||
|
||||
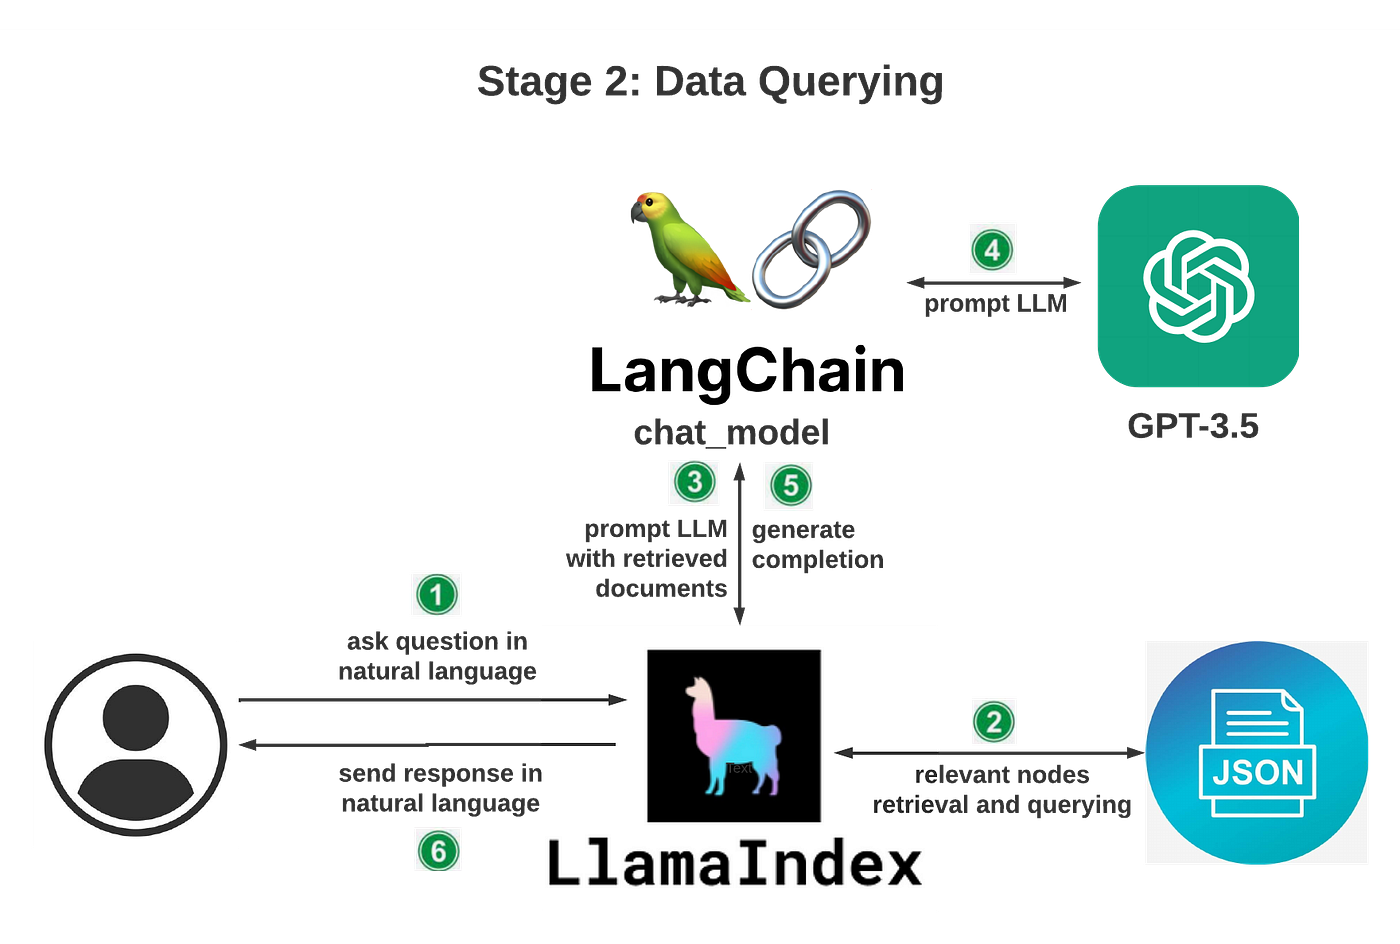
|
||||
|
||||
Diagram by author
|
||||
|
||||
Now, let’s get started building our knowledge base.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- Python installation: assume you have Python installed in your local environment. If not, please refer to the Python [download](https://www.python.org/downloads/) page to download and install Python. Be sure to upgrade pip to the latest version by running the following command:
|
||||
|
||||
python -m pip install -U pip
|
||||
|
||||
- OpenAI API key: navigate to OpenAI’s [API Keys](https://platform.openai.com/account/api-keys) page to generate a new API key if you don’t already have one. Suggest you also set up a usage limit through their [Usage Limits](https://platform.openai.com/account/billing/limits) page so you can manage your spending.
|
||||
- Create a directory on your local environment, for example `DevSecOpsKB`. You will be running all commands below in this directory.
|
||||
|
||||
## Installation of Libraries
|
||||
|
||||
To train our custom DevSecOps knowledge base, we need to install a few libraries. Simply navigate to the `DevSecOpsKB` directory, and run:
|
||||
|
||||
pip install openai langchain llama\_index==0.6.12 pypdf PyCryptodome gradio
|
||||
|
||||
Note: we specified version `0.6.12` for `llama_index`. Without specifying the version, it would install the latest version, `0.6.16` as of this update (May 31 2023), which introduced breaking changes. We cover some of the changes in the latest `llama_index` release in [another blog](https://betterprogramming.pub/a-glimpse-into-the-mechanics-of-llamaindex-apps-through-the-lens-of-observability-9e7c49f4cb32?sk=6bb0a3a8dc496e1f58523991f063550e).
|
||||
|
||||
Let’s take a closer look at each library.
|
||||
|
||||
## OpenAI library
|
||||
|
||||
We are using [OpenAI](https://openai.com/) library for two purposes:
|
||||
|
||||
- Data ingestion/indexing: as depicted in the architecture diagram above, we will be calling OpenAI’s embedding model `text-embedding-ada-002` via LangChain under the hood.
|
||||
- Data query: we will call OpenAI’s GPT-3.5 LLM (Large Language Model). GPT-3.5 models can understand and generate natural language or code. We will be using their most capable and cost-effective model in the GPT-3.5 family, `gpt-3.5-turbo`.
|
||||
|
||||
## LangChain
|
||||
|
||||
[LangChain](https://python.langchain.com/en/latest/index.html) is an open source library that provides developers with the necessary tools to create applications powered by LLMs. It is a framework built around LLMs that can be used for chatbots, Generative Question-Answering (GQA), summarization, and much more. The core idea of the library is that developers can “chain” together different components to create more advanced use cases around LLMs.
|
||||
|
||||
LangChain offers a series of modules, which are the core abstractions as the building blocks of any LLM-powered application. These modules include models, prompts, memory, indexes, chains, agents, and callbacks. For our knowledge base chatbot, we will be using LangChain’s `chat_models` module.
|
||||
|
||||
## LlamaIndex
|
||||
|
||||
[LlamaIndex](https://gpt-index.readthedocs.io/en/latest/) uses LangChain’s LLM modules and allows for customizing the underlying LLM. LlamaIndex is a powerful tool that provides a central interface to connect the LLM with external data and allows you to create a chatbot based on the data you feed it. With LlamaIndex, you don’t need to be an NLP or machine learning expert. You only need to provide the data you want the chatbot to use, and LlamaIndex will take care of the rest.
|
||||
|
||||
As [outlined](https://github.com/jerryjliu/llama_index) by [Jerry Liu](https://twitter.com/jerryjliu0), the creator of LlamaIndex, LlamaIndex provides the following tools in an easy-to-use fashion:
|
||||
|
||||
- Offers data connectors to ingest your existing data sources and data formats (APIs, PDFs, docs, SQL, etc.)
|
||||
- Provides ways to structure your data (indices, graphs) so that this data can be easily used with LLMs.
|
||||
- Provides an advanced retrieval/query interface over your data: Feed in any LLM input prompt, get back retrieved context and knowledge-augmented output.
|
||||
- Allows easy integrations with your outer application framework (e.g., LangChain, Flask, Docker, ChatGPT, or anything else).
|
||||
|
||||
## pypdf + PyCryptodome
|
||||
|
||||
[pypdf](https://pypi.org/project/pypdf/) is a free and open source pure-python PDF library capable of splitting, merging, cropping, and transforming the pages of PDF files. We will be using this library to parse our PDF files. PyCryptodome is another library that helps prevent errors while parsing PDF files.
|
||||
|
||||
## Gradio
|
||||
|
||||
[Gradio](https://gradio.app/) is an open source Python package that allows you to quickly create easy-to-use, customizable UI components for your ML model, any API, or even an arbitrary Python function using a few lines of code. You can integrate the Gradio GUI directly into your Jupyter Notebook or share it as a link with anyone. Let’s use Gradio to build a simple UI for our knowledge base.
|
||||
|
||||
## How to Add Data Source
|
||||
|
||||
I converted my articles listed in [The Path to DevOps Self-Service: A Five-Part Series](https://medium.com/@wenqiglantz/the-path-to-devops-self-service-a-five-part-series-5ea5d4552f9e), along with the [Troubleshooting Tips for GitHub Actions Workflows](https://medium.com/better-programming/17-troubleshooting-tips-for-github-actions-workflows-43394e4f1a8a), into PDFs and saved those PDF documents under my `DevSecOpsKB/data` directory. Let’s use these documents to start training our knowledge base chatbot.
|
||||
|
||||
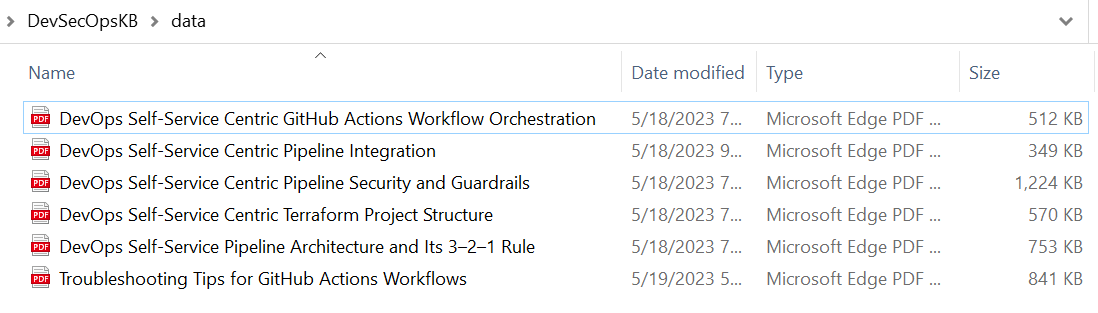
|
||||
|
||||
## Implement Python Code
|
||||
|
||||
There are many open source Python tutorials online for building custom chatbots, but many contain outdated code as they were built on older versions of the libraries, and hard to get them to work as desired. I recommend follow the instructions on the [LlamaIndex Usage Pattern](https://github.com/jerryjliu/llama_index/blob/main/docs/guides/primer/usage_pattern.md) page as the base framework, then add your custom logic. Let’s dive into the code.
|
||||
|
||||
**Step 1**: Import the following modules and classes:
|
||||
|
||||
from llama\_index import StorageContext, ServiceContext, GPTVectorStoreIndex, LLMPredictor, PromptHelper, SimpleDirectoryReader, load\_index\_from\_storage
|
||||
from langchain.chat\_models import ChatOpenAI
|
||||
import gradio as gr
|
||||
import sys
|
||||
import os
|
||||
|
||||
- `SimpleDirectoryReader`, `LLMPredictor`, `PromptHelper`, `StorageContext`, `ServiceContext`, `GPTVectorStoreIndex`, and `load_index_from_storage` are classes from the `llama_index` module.
|
||||
- `ChatOpenAI` is a class from the `langchain.chat_models` module.
|
||||
- `gradio` is the library we use for creating web interfaces.
|
||||
- `sys` and `os` are standard Python modules for system-related operations.
|
||||
|
||||
**Step 2**: The API key for OpenAI is set as an environment variable using `os.environ["OPENAI_API_KEY"]`. You need to replace `'YOUR-OPENAI-API-KEY'` with your actual OpenAI API key for it to work.
|
||||
|
||||
os.environ\["OPENAI\_API\_KEY"\] = 'YOUR-OPENAI-API-KEY'
|
||||
|
||||
**Step 3**: Define the function `data_ingestion_indexing(directory_path)`. This function is responsible for ingesting the data and creating and saving the index used for data queries in our knowledge base.
|
||||
|
||||
def create\_service\_context():
|
||||
|
||||
|
||||
max\_input\_size = 4096
|
||||
num\_outputs = 512
|
||||
max\_chunk\_overlap = 20
|
||||
chunk\_size\_limit = 600
|
||||
|
||||
|
||||
prompt\_helper = PromptHelper(max\_input\_size, num\_outputs, max\_chunk\_overlap, chunk\_size\_limit=chunk\_size\_limit)
|
||||
|
||||
|
||||
llm\_predictor = LLMPredictor(llm=ChatOpenAI(temperature=0.5, model\_name="gpt-3.5-turbo", max\_tokens=num\_outputs))
|
||||
|
||||
|
||||
service\_context = ServiceContext.from\_defaults(llm\_predictor=llm\_predictor, prompt\_helper=prompt\_helper)
|
||||
return service\_context
|
||||
|
||||
def data\_ingestion\_indexing(directory\_path):
|
||||
|
||||
|
||||
documents = SimpleDirectoryReader(directory\_path).load\_data()
|
||||
|
||||
|
||||
index = GPTVectorStoreIndex.from\_documents(
|
||||
documents, service\_context=create\_service\_context()
|
||||
)
|
||||
|
||||
|
||||
index.storage\_context.persist()
|
||||
|
||||
return index
|
||||
|
||||
- We define a utility function named `create_service_context`, which creates the `ServiceContext`, a utility container for LlamaIndex index and query classes. The container contains objects that are commonly used for configuring every index and query, such as the `LLMPredictor` (for configuring the LLM, it is a wrapper class around LangChain’s LLMChain that allows easy integration into LlamaIndex), the `PromptHelper` (allows the user to explicitly set certain constraint parameters, such as maximum input size, number of generated output tokens, maximum chunk overlap, etc.), the `BaseEmbedding` (for configuring the embedding model), and more.
|
||||
- It uses `SimpleDirectoryReader` to load data from the specified directory path.
|
||||
- It creates an instance of `GPTVectorStoreIndex` with the loaded `documents`, and the `service_context` by calling the utility function `create_service_context()`.
|
||||
- Finally, it calls the `storage_context` and persists the index to disk under the default `storage` folder, and returns the `index` object.
|
||||
|
||||
**Step 4**: Define the function `data_querying(input_text)`. This function is the core of our knowledge base logic.
|
||||
|
||||
def data\_querying(input\_text):
|
||||
|
||||
|
||||
storage\_context = StorageContext.from\_defaults(persist\_dir="./storage")
|
||||
|
||||
|
||||
index = load\_index\_from\_storage(storage\_context, service\_context=create\_service\_context())
|
||||
|
||||
|
||||
response = index.as\_query\_engine().query(input\_text)
|
||||
|
||||
return response.response
|
||||
|
||||
- It rebuilds storage context.
|
||||
- It loads the index from storage. Since we initialized the index with a custom `ServiceContext` object, we also need to pass in the same `ServiceContext` during `load_index_from_storage`.
|
||||
- It queries the index with the input text using `index.as_query_engine().query()`.
|
||||
- It returns the response received from the index.
|
||||
|
||||
**Step 5**: Define the UI by creating an instance of `gr.Interface`.
|
||||
|
||||
iface = gr.Interface(fn=data\_querying,
|
||||
inputs=gr.components.Textbox(lines=7, label="Enter your text"),
|
||||
outputs="text",
|
||||
title="Wenqi's Custom-trained DevSecOps Knowledge Base")
|
||||
|
||||
- The `fn` parameter is set to the `data_querying` function defined earlier.
|
||||
- The `inputs` parameter specifies a textbox input component with 7 lines for entering text.
|
||||
- The `outputs` parameter specifies that the output will be text-based.
|
||||
- The `title` parameter sets the title of the web interface. Customize it to whatever you want your UI title to be.
|
||||
|
||||
**Step 6**: The `data_ingestion_indexing` function is called with the argument `data` to create and save the index. Notice this `data` directory is where we store our PDF documents. If you want to name your directory differently, change it here accordingly.
|
||||
|
||||
|
||||
index = data\_ingestion\_indexing("data")
|
||||
|
||||
**Step 7**: The `iface.launch(share=False)` line launches the UI, making the chatbot accessible through a web browser. You have the option of turning `share` to `True`, which allows Gradio to create a share link so you can share your knowledge base chatbot with others. For this POC, we are disabling this feature for simplicity reason.
|
||||
|
||||
iface.launch(share=False)
|
||||
|
||||
See the complete code below. Copy this code into a file named `kb.py`, and placed it at the root of our `DevSecOpsKB` directory.
|
||||
|
||||
from llama\_index import SimpleDirectoryReader, LLMPredictor, PromptHelper, StorageContext, ServiceContext, GPTVectorStoreIndex, load\_index\_from\_storage
|
||||
from langchain.chat\_models import ChatOpenAI
|
||||
import gradio as gr
|
||||
import sys
|
||||
import os
|
||||
|
||||
os.environ\["OPENAI\_API\_KEY"\] = 'YOUR-OPENAI-API-KEY'
|
||||
|
||||
def create\_service\_context():
|
||||
|
||||
|
||||
max\_input\_size = 4096
|
||||
num\_outputs = 512
|
||||
max\_chunk\_overlap = 20
|
||||
chunk\_size\_limit = 600
|
||||
|
||||
|
||||
prompt\_helper = PromptHelper(max\_input\_size, num\_outputs, max\_chunk\_overlap, chunk\_size\_limit=chunk\_size\_limit)
|
||||
|
||||
|
||||
llm\_predictor = LLMPredictor(llm=ChatOpenAI(temperature=0.5, model\_name="gpt-3.5-turbo", max\_tokens=num\_outputs))
|
||||
|
||||
|
||||
service\_context = ServiceContext.from\_defaults(llm\_predictor=llm\_predictor, prompt\_helper=prompt\_helper)
|
||||
return service\_context
|
||||
|
||||
def data\_ingestion\_indexing(directory\_path):
|
||||
|
||||
|
||||
documents = SimpleDirectoryReader(directory\_path).load\_data()
|
||||
|
||||
|
||||
index = GPTVectorStoreIndex.from\_documents(
|
||||
documents, service\_context=create\_service\_context()
|
||||
)
|
||||
|
||||
|
||||
index.storage\_context.persist()
|
||||
|
||||
return index
|
||||
|
||||
def data\_querying(input\_text):
|
||||
|
||||
|
||||
storage\_context = StorageContext.from\_defaults(persist\_dir="./storage")
|
||||
|
||||
|
||||
index = load\_index\_from\_storage(storage\_context, service\_context=create\_service\_context())
|
||||
|
||||
|
||||
response = index.as\_query\_engine().query(input\_text)
|
||||
|
||||
return response.response
|
||||
|
||||
iface = gr.Interface(fn=data\_querying,
|
||||
inputs=gr.components.Textbox(lines=7, label="Enter your question"),
|
||||
outputs="text",
|
||||
title="Wenqi's Custom-trained DevSecOps Knowledge Base")
|
||||
|
||||
|
||||
index = data\_ingestion\_indexing("data")
|
||||
iface.launch(share=False)
|
||||
|
||||
## Launch DevSecOps Knowledge Base
|
||||
|
||||
Now that we have our custom PDF files ready, and the code is ready, let’s launch our DevSecOps knowledge base by running the following command in the `DevSecOpsKB` directory:
|
||||
|
||||
python kb.py
|
||||
|
||||
Let’s launch the UI of our new knowledge base: [http://127.0.0.1:7860/](http://127.0.0.1:7860/).
|
||||
|
||||
Here we go! Our new knowledge base is ready for us to tap into. Let’s ask a generic question on a term I coined in [one of my articles on DevOps self-service model](https://medium.com/better-programming/devops-self-service-pipeline-architecture-and-its-3-2-1-rule-517dc0bbcb4a), in particular, the 3–2–1 rule, and I was happy to see that our new knowledge base outputs the right information I was looking for:
|
||||
|
||||

|
||||
|
||||
Asking it with a specific error encountered in the GitHub Actions workflow, we get the desired answer. See the following:
|
||||
|
||||
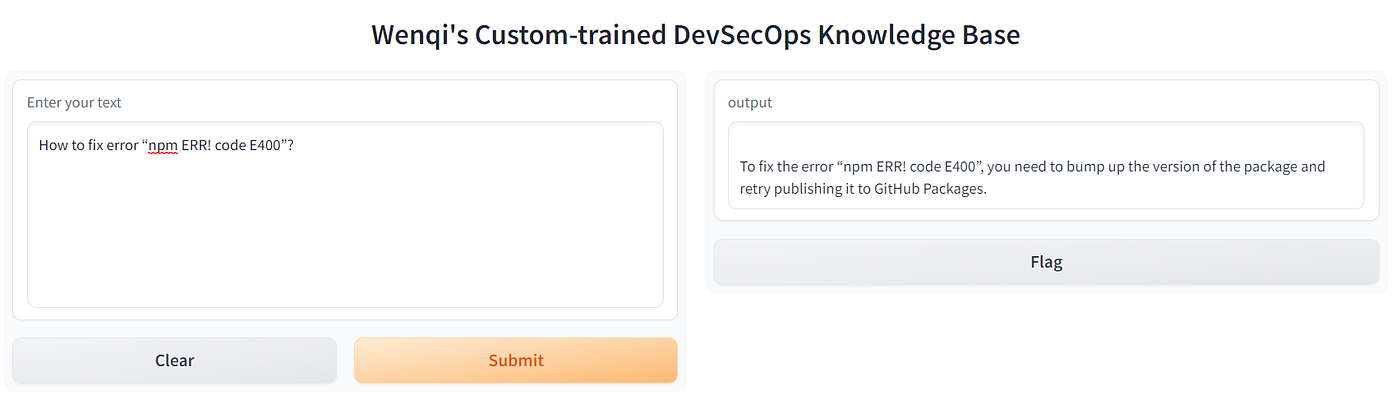
|
||||
|
||||
Now, let’s ask if our knowledge base can answer questions on [Harden Runner](https://www.stepsecurity.io/products/harden-runner):
|
||||
|
||||
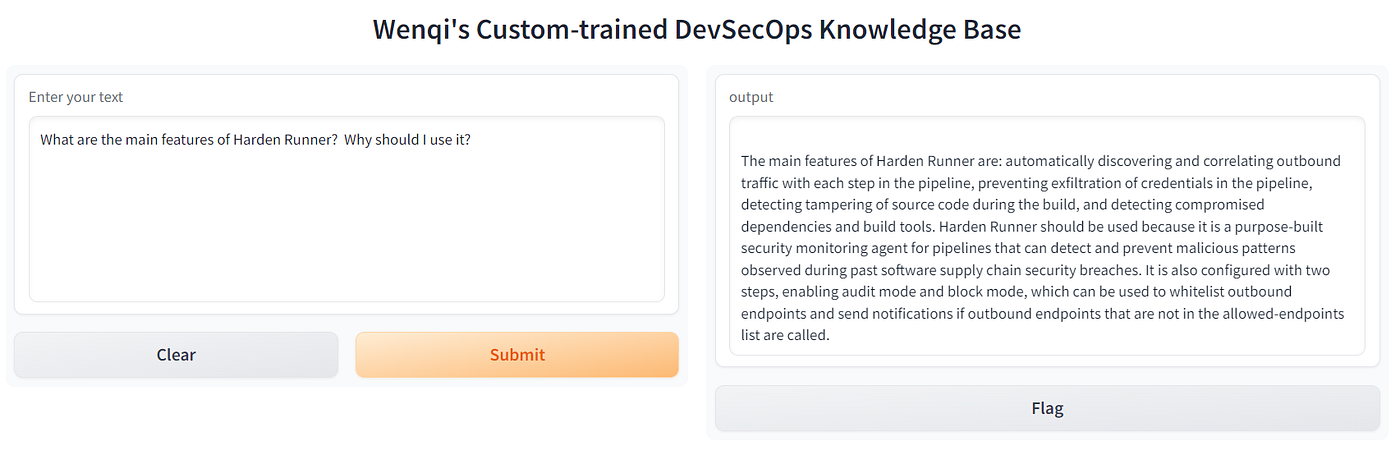
|
||||
|
||||
Right on! I am amazed at how accurate the answer is. Next, let’s see if our knowledge base can output a code snippet:
|
||||
|
||||
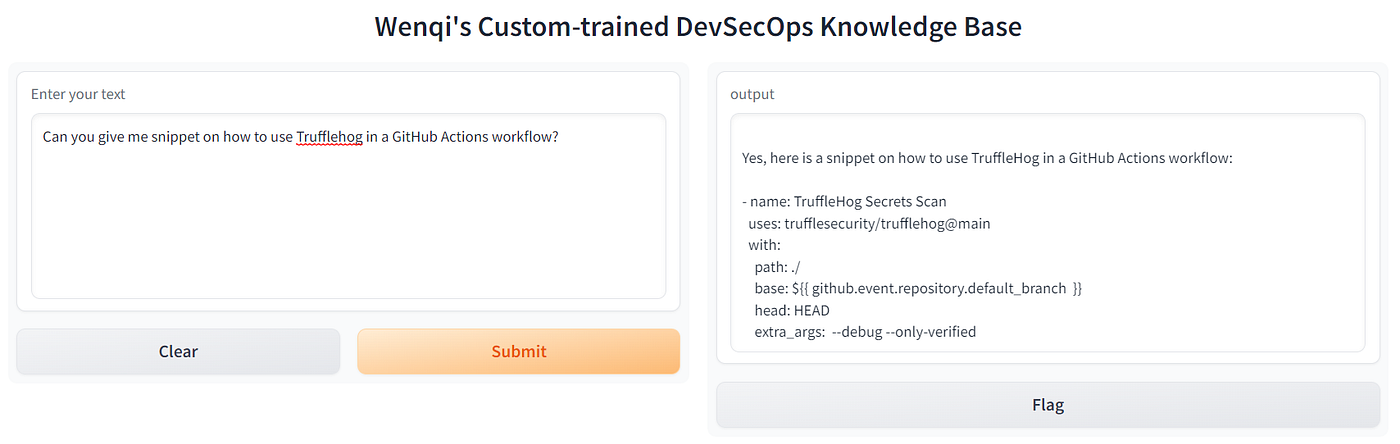
|
||||
|
||||
This one works like a charm!
|
||||
|
||||
Now, let’s attempt a negative scenario: let’s try to ask a question that is not in the provided source documents:
|
||||
|
||||
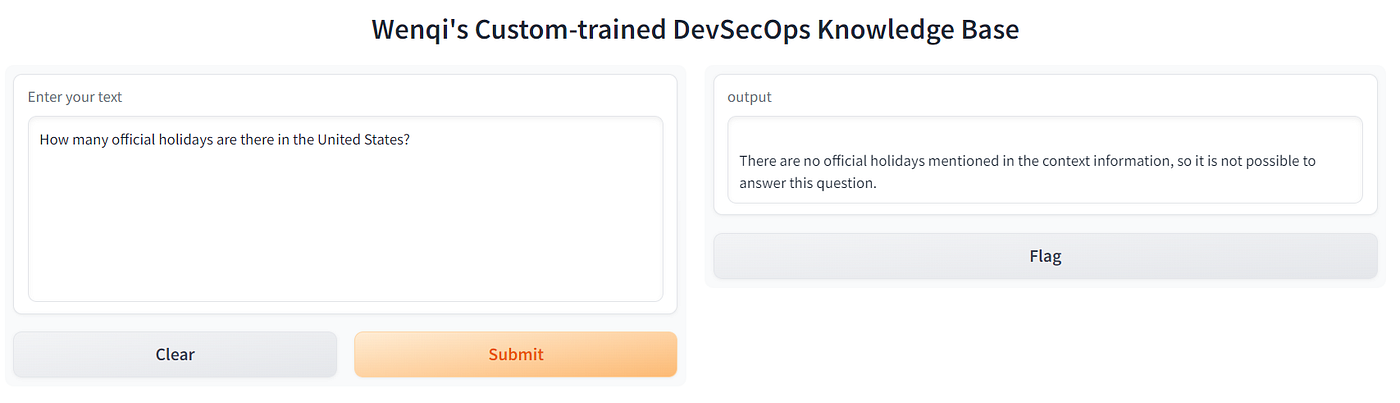
|
||||
|
||||
Job well done! LlamaIndex seems to have a guardrail in place against hallucination, which is a confident response by an AI that does not seem justified by its training data, either because it is insufficient, biased, or too specialized.
|
||||
|
||||
## Does This AI Bot Expose My Private Data to OpenAI?
|
||||
|
||||
The answer is no. Per [OpenAI privacy policy on API](https://help.openai.com/en/articles/5722486-how-your-data-is-used-to-improve-model-performance):
|
||||
|
||||
> OpenAI does not use data submitted by customers via our API to train OpenAI models or improve OpenAI’s service offering.
|
||||
|
||||
Both our functions, `data_ingestion_indexing` for data ingestion/indexing and `data_querying` for Q&A, invoke OpenAI APIs via LangChain, so we can rest assured that OpenAI does not use our private data per their privacy policy on API mentioned above.
|
||||
|
||||
## A Note on Cost
|
||||
|
||||
As you may already know, using OpenAI models does incur a cost. In our use case, we use its embedding model during data ingestion/indexing, and chat model for data querying. Here are the pricing details:
|
||||
|
||||
- For embedding model `text-embedding-ada-002`: $0.0004 / 1K tokens
|
||||
- For chat model `gpt-3.5-turbo`: $0.002 / 1K tokens
|
||||
|
||||
Here is a screenshot of my OpenAI usage while working on this chatbot:
|
||||
|
||||
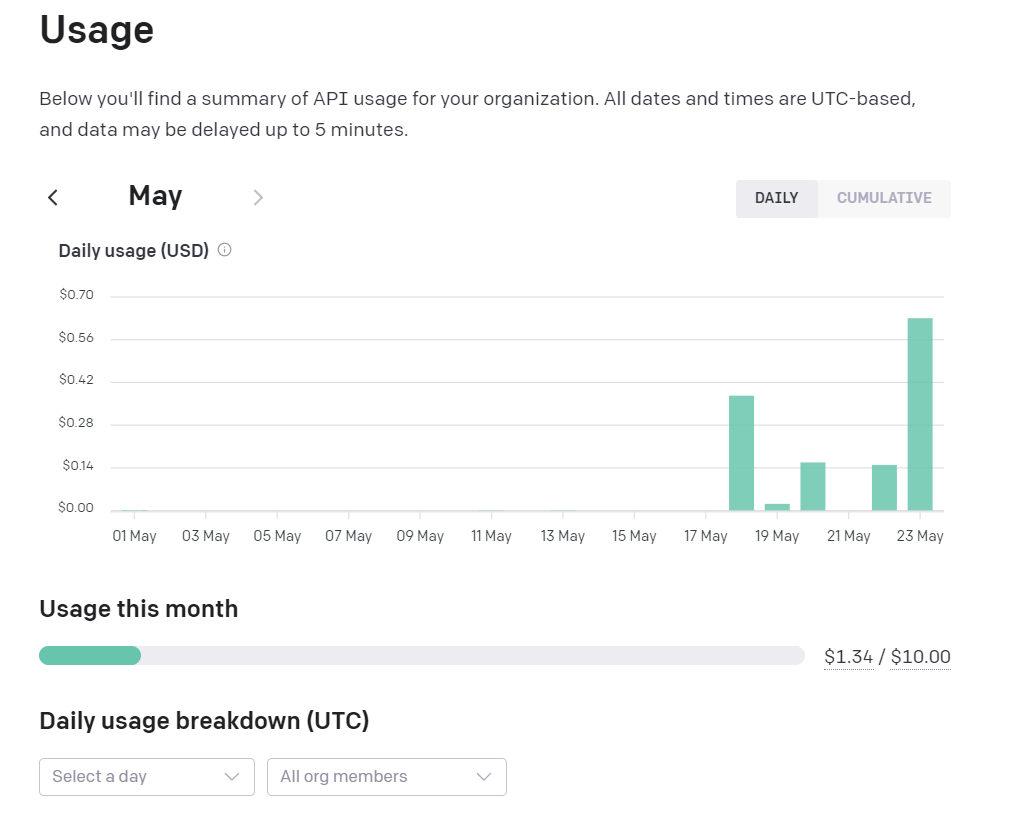
|
||||
|
||||
If you plan to use OpenAI LLMs, I strongly encourage you to configure a usage limit on OpenAI’s [Usage Limit page](https://platform.openai.com/account/billing/limits), where you can define a hard limit and soft limit, so you manage your usage properly.
|
||||
|
||||
## Summary
|
||||
|
||||
This article explored how to build a customized DevSecOps knowledge base chatbot. This is a mere proof of concept. The potential of incorporating LlamaIndex and LangChain into building apps that harness the power of LLMs through private data is limitless!
|
||||
|
||||
The source code for this article can be found in [my GitHub repo](https://github.com/wenqiglantz/DevSecOpsKB-LlamaIndex-LangChain-OpenAI/tree/main/DevSecOpsKB).
|
||||
|
||||
Happy coding!
|
||||
+194
@@ -0,0 +1,194 @@
|
||||
---
|
||||
page-title: "How we built the Tinder API Gateway | by Tinder | Tinder Tech Blog | Medium"
|
||||
url: https://medium.com/tinder/how-we-built-the-tinder-api-gateway-831c6ca5ceca
|
||||
date: "2023-06-02 14:57:26"
|
||||
---
|
||||
## How we built the Tinder API Gateway
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/@TinderEng?source=post_page-----831c6ca5ceca--------------------------------)[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/tinder?source=post_page-----831c6ca5ceca--------------------------------)
|
||||
|
||||
Authored by:
|
||||
|
||||
- Vijaya Vangapandu, Distinguished Software Engineer
|
||||
- Periyasamy, Staff Software Engineer
|
||||
- , Senior Software Engineer
|
||||
- , Senior Software Engineer
|
||||
|
||||
## Introduction
|
||||
|
||||
Tinder API Gateway (TAG) is one of the critical frameworks at Tinder that solves the need of exposing public APIs and enforcing strict authorization and security rules. It’s engineered to meet Tinder’s custom need to fit perfectly in its current cloud infrastructure, and can be scaled as required and maintained without any external support. It also implements **RAC** (Route As Configuration), which helps developers ship their modules to production faster. There are various features that make TAG a unique solution, but before we dive into that, let’s look at why Tinder needs a custom gateway.
|
||||
|
||||
We have more than 500 microservices at Tinder, which talk to each other for different data needs using a service mesh under the hood. All external-facing APIs are hosted on TAG. We needed a gateway solution that could centralize all these services, giving us more control from maintenance to deployment. The custom gateway also helps in ensuring that services go through a security review before being publicly exposed to the outside world.
|
||||
|
||||
Services like Recommendations APIs also receive frequent feature updates, both on the backend and the client side. This is just one example; we have several other critical services like Match APIs, Revenue APIs, etc. that need a streamlined process to ship faster to production. So we needed a custom gateway solution that could help us configure external routes with minimal effort to expedite the release process.
|
||||
|
||||
Looking at API Gateway from a security aspect, Tinder is used in 190 countries and gets all kinds of traffic from all over the world. Traffic from real users as well as traffic from bad actors. Imagine how important it is to scan and avoid vulnerabilities that might attack any of these services. Hackers try to find cracks to get into corporate systems so that they can steal any valuable information, and one entry point for them is the gateway. We needed a custom gateway solution that could help us identify such traffic and avoid possible vulnerabilities.
|
||||
|
||||
## Challenges Before TAG
|
||||
|
||||
Before TAG existed, we leveraged multiple API Gateway solutions and each application team used a different 3rd party API Gateway solution. Since each of the gateways was built on a different tech stack, managing them became a cumbersome effort. More to the point, there were compatibility issues in sharing reusable components across different gateways. This would often result in delays in shipping the code to production. Moreover, different API Gateways had maintenance overheads.
|
||||
|
||||
We also saw inconsistent use of Session Management across APIs as the API Gateways were not centralized, as shown in below figure 1.
|
||||
|
||||

|
||||
|
||||
*Figure 1 — Session Management across APIs at Tinder before TAG*
|
||||
|
||||
We were trying to address some major concerns by looking for:
|
||||
|
||||
- A solution to bring all external facing services under one umbrella
|
||||
- An **artifact** that could be used by any application team to spin off their API Gateway to scale their application independently
|
||||
- A framework that could provide the capability for applications to **run as a Kubernetes microservice** along with other Kubernetes services
|
||||
- A design that could support configuration-driven API Gateway development for increased development velocity
|
||||
- A generic component that could be extended based on Tinder’s custom needs
|
||||
- Adding Request/Response transformations
|
||||
- Custom middleware logic for various features like Bot Detection, Schema Registry, and more
|
||||
|
||||
We also wanted to control the framework level development and support so that we could build the gateway the way we want. All of these features were the motivation behind designing TAG.
|
||||
|
||||
## Existing API Gateway Solutions
|
||||
|
||||
There are many open-source and commercial gateway solutions available in the public domain. Some of them are really heavy and focused on B2B integrations, and some of them are very complex to deploy and maintain. Existing solutions including Amazon AWS Gateway, APIgee, Tyk.io, Kong, Express API Gateway, and KrakenD were not optimal for reasons:
|
||||
|
||||
- Some of these solutions are not well integrated with our existing Envoy mesh solution
|
||||
- A few of them are configuration heavy and use built-in plugins to support different features like spike arrest, service callouts, etc. Their adoption has a steep learning curve and doesn’t fit well with our current application/network stack
|
||||
- Some solutions have less support for languages we heavily work with
|
||||
- Finally, we need flexibility in building our own plugins and filters quickly when needed
|
||||
|
||||
**Note:** All these observations were made based on the documentation available on the official site of these products. Documentation is included in the reference section of this blog.
|
||||
|
||||
## Let’s Explore TAG
|
||||
|
||||
TAG is a JVM-based framework built on top of **Spring Cloud Gateway**. Application teams can use TAG to create their own instance of API Gateway by just writing configurations. It centralizes all external facing APIs and enforces strict authorization and security rules at Tinder. TAG extends components like gateway and global filter of Spring Cloud Gateway to provide generic and pre-built filters.
|
||||
|
||||
These filters can be used by application teams for various needs:
|
||||
|
||||
- Weighted routing
|
||||
- Request/Response transformations
|
||||
- HTTP to GRPC conversion, and more
|
||||
|
||||
From the developers’ point of view, TAG was created keeping their experience at the center of the design, and for that reason, TAG supports **configuration-driven** **development**.
|
||||
|
||||
TAG, by design, helps in improving developers’ velocity, provides ease to set up routes and services using environment-specific YAML or JSON configurations without writing any code, and helps them to reuse components by sharing filters across the application routes. It leverages all major components of Spring Cloud Gateway to build custom framework-level support for developers at Tinder to use.
|
||||
|
||||
Here are some additional reasons why we developed TAG:
|
||||
|
||||
- Complete control to develop custom components, and to share and use them as configurations
|
||||
- **Request and Response scanning**
|
||||
- For **Schema Registry** to auto-generate API Documentation
|
||||
- To detect vulnerabilities like **Bot Detecting** and **Real Time Traffic Detection**
|
||||
- **Dynamic Routing**: we’re building a pipeline on TAG that will help in dynamically updating routes and their related configurations without the need of deploying the application cluster
|
||||
- TAG will enable future initiatives like **API Standardization** and **Auditing Process**
|
||||
- It enforces **consistent** and **uniform** experience of **Session Management** across different applications as it’s developed once and shared across all API Gateways (created using TAG)
|
||||
|
||||
## A Deeper Look Inside TAG
|
||||
|
||||

|
||||
|
||||
*Figure 2 — High-Level Design of TAG*
|
||||
|
||||
High-Level Design, as shown in figure 2, showcases the following components:
|
||||
|
||||
- **Routes** — Developers can expose their endpoints using Route As a Config (**RAC**); we’ll see in detail how routes are set up in TAG later on
|
||||
- **Service Discovery** — TAG uses Service Mesh to discover backend services for each route
|
||||
- **Pre-Built Filters** — We’ve added built-in filters in TAG for application teams at Tinder to use;
|
||||
example: setPath, setMethod, etc.
|
||||
- **Custom Filters** — We’ve added the support of custom filters so that application teams can write their own custom logic if needed, and implement them in a route using configurations. Custom filters are applied at Route Level (i.e. per route); example: custom logic to validate the request before calling backend service.
|
||||
- **Global Filters** — Global filters are just like custom filters, but they’re global in nature, i.e. they are applied to all the routes automatically if configured at the service level.
|
||||
Example: Auth filter or metrics filter applied to all routes specific to an application.
|
||||
|
||||
Below is the step-by-step flow of how TAG builds all the routes at application startup:
|
||||
|
||||

|
||||
|
||||
*Figure 3 — TAG processing flow at application startup*
|
||||
|
||||
**Step 1:** TAG triggers the Gateway Watcher that calls the Gateway Config Parser to load the YAML file
|
||||
|
||||
**Step 2:** The Gateway Config Parser validates and parses the environment-specific YAML configuration file
|
||||
|
||||
**Step 3:** The Gateway Manager looks up pre-filters, custom filters, and global filters and creates a map of the route ID and those filters
|
||||
|
||||
**Step 4:** The Gateway Route Locator loads predicate and its related filters from the map for each route into Spring Cloud Gateway
|
||||
|
||||
**Step 5:** The Gateway Manager then builds all the routes and prepares the gateway to receive traffic
|
||||
|
||||
Spring Cloud Gateway facilitates TAG to pre-configure all the routes and filters and seemingly execute them at runtime. Due to this design, TAG does **NOT** add any configuration processing latency at runtime. This helps TAG to scale up and handle high traffic with ease.
|
||||
|
||||
## Real World Usage of TAG at Tinder
|
||||
|
||||

|
||||
|
||||
*Figure 4 — Request processing by TAG*
|
||||
|
||||
Executing a request in the above TAG configuration (as shown in figure 4) results in the following steps:
|
||||
|
||||
**Step 1: Reverse Geo IP Lookup (RGIL)**
|
||||
|
||||
RGIL is implemented as a global filter in TAG. The IP of the client request is mapped to three-digit alpha country code using the RGIL filter. We use RGIL for rate limiting, request banning, and other purposes.
|
||||
|
||||
**Step 2:** **Request/Response Scanning**
|
||||
|
||||
An Async event is published to capture the request semantics. Request/Response Scanning Global Filter captures just the schema of the request and not the data attributes. Amazon MSK is used to securely stream the data, which can be consumed by applications downstream for a variety of use cases like automatic schema generation, bot detection, etc.
|
||||
|
||||
**Step 3:** **Session Management as a Filter**
|
||||
|
||||
A Centralized Global filter is written in TAG to validate/update and control Session Management.
|
||||
|
||||
**Step 4: Predicate Matching
|
||||
**The path of an incoming request is matched with one of the deployed routes using predicate matching.
|
||||
|
||||
**Step 5:** **Service Discovery**
|
||||
|
||||
The service discovery module in TAG uses Envoy to look up egress mapping for the matched endpoint.
|
||||
|
||||
**Step 6:** **Pre-Filters**
|
||||
|
||||
Once the route is identified, then the request goes through the chain of pre-filters configured for that route. Pre-filters are filters that are executed before the request is forwarded to the backend service. Once the list of pre-filters is executed, the request is forwarded. Weighted Routing per route and HTTP to GRPC Conversion are some of the pre-built filters available in TAG. One can also write custom filters like Trimming Request Headers.
|
||||
|
||||
**Step 7: Post-Filters**
|
||||
|
||||
After receiving the response from the backend service, the response goes through the chain of post-filters configured for that route. Post-filters are filters that are executed after the response is received from the backend service. Logging error is one example of post-filters.
|
||||
|
||||
**Step 8: Return Response**
|
||||
|
||||
After completing the list of post-filters, the final response is returned to the client.
|
||||
|
||||
**Note**:
|
||||
|
||||
- Pre-filters/post-filters can contain custom logic or any type of request/response transformation
|
||||
- One can configure the order of sequence in which pre-filters/post-filters should run
|
||||
|
||||
## API Gateway at Tinder Today
|
||||
|
||||
Application teams at Tinder are using TAG as a standard framework for building their own instance of API Gateway by just writing their application-specific configurations. These instances can individually scale as needed. TAG is also used by other Match Group brands like Hinge, OkCupid, PlentyOfFish, Ship, etc. Thus TAG is serving B2C and B2B traffic for Tinder. Below is a general depiction of how TAG is used in Tinder today.
|
||||
|
||||

|
||||
|
||||
*Figure 5 — API Gateways powered by TAG at Tinder*
|
||||
|
||||
In this blog, we looked at the state before TAG existed, why we created TAG, and how TAG is helping Tinder serve traffic at scale. We hope you enjoyed reading about it! In the next blog, we’ll also take a deeper look at how configurations are written to set up a route in TAG.
|
||||
|
||||
## References:
|
||||
|
||||
- [https://spring.io/projects/spring-cloud-gateway](https://spring.io/projects/spring-cloud-gateway)
|
||||
- [https://cloud.spring.io/spring-cloud-gateway/reference/html/](https://cloud.spring.io/spring-cloud-gateway/reference/html/)
|
||||
- [https://docs.aws.amazon.com/apigateway/latest/developerguide/welcome.html](https://docs.aws.amazon.com/apigateway/latest/developerguide/welcome.html)
|
||||
- [https://cloud.google.com/apigee/docs](https://cloud.google.com/apigee/docs)
|
||||
- [https://tyk.io/blog/what-do-we-mean-by-batteries-included/](https://tyk.io/blog/what-do-we-mean-by-batteries-included/)
|
||||
- [https://tyk.io/docs/plugins/supported-languages/](https://tyk.io/docs/plugins/supported-languages/)
|
||||
- [https://docs.konghq.com/gateway/latest/](https://docs.konghq.com/gateway/latest/)
|
||||
- [https://www.express-gateway.io/docs/](https://www.express-gateway.io/docs/)
|
||||
- [https://www.krakend.io/docs/overview/](https://www.krakend.io/docs/overview/)
|
||||
Reference in New Issue
Block a user