vault backup: 2026-01-05 13:03:55
This commit is contained in:
 windyboy
+34
@@ -0,0 +1,34 @@
|
||||
---
|
||||
page-title: "Adding and trusting a Certificate Authority (CA) in Fedora – Antonio Maradiaga – Collection of things I'm interested in / working on"
|
||||
url: https://ajmaradiaga.com/Adding-trusting-CA-Fedora/
|
||||
date: "2023-03-30 16:40:18"
|
||||
---
|
||||
## Adding and trusting a Certificate Authority (CA) in Fedora
|
||||
|
||||
When running Citrix on Fedora, I was getting an error message similar to the following: “SSL Error 61: You have not chosen to trust ‘Certificate Authority’”. Basically, the CA (certificate authority) cert was missing in my operating system. To fix this, we need to do the following:
|
||||
|
||||
1. Find the CA’s certificate online.
|
||||
2. Ensure that the certificate is in PEM format (if not, convert it to PEM).
|
||||
3. Move the PEM file to `/etc/pki/ca-trust/source/anchors`.
|
||||
4. Update the CA trust in the operating system.
|
||||
|
||||
In the example below, I add and trust GoDaddy’s root G2 certificate:
|
||||
|
||||
```
|
||||
# Download GoDaddy - G2 root certificate
|
||||
wget https://ssl-ccp.godaddy.com/repository/gdroot-g2.crt
|
||||
|
||||
# Convert CRT to PEM
|
||||
openssl x509 -in gdroot-g2.crt -out gdroot-g2.pem -outform PEM
|
||||
|
||||
# Move the PEM cert and update the CA trust
|
||||
sudo mv gdroot-g2.pem /etc/pki/ca-trust/source/anchors/
|
||||
sudo update-ca-trust
|
||||
```
|
||||
|
||||
### References:
|
||||
|
||||
- Convert CRT to PEM: https://stackoverflow.com/questions/4691699/how-to-convert-crt-to-pem
|
||||
- Trusting additional CAs in Fedora: https://www.happyassassin.net/2015/01/14/trusting-additional-cas-in-fedora-rhel-centos-dont-append-to-etcpkitlscertsca-bundle-crt-or-etcpkitlscert-pem/
|
||||
|
||||
Written on December 3, 2019
|
||||
@@ -0,0 +1,842 @@
|
||||
---
|
||||
page-title: "zhiqiang feng / DailySync · GitLab"
|
||||
url: https://gitlab.com/zhiqiangf/dailysync
|
||||
date: "2023-03-08 14:00:07"
|
||||
---
|
||||
## 佳明运动数据同步与采集工具
|
||||
|
||||
[](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/workflow.png)
|
||||
|
||||
[关注作者Strava ](https://strava.com/athletes/84396978)
|
||||
|
||||
[](https://t.me/garmindailysync)
|
||||
|
||||
## 本地运行方案
|
||||
|
||||
首先确保运行此脚本的机器能够访问国际互联网, 如国外VPS、家庭全局科学的环境等, 否则无法正常登录佳明国际区
|
||||
|
||||
## 检查网络情况确保正常访问佳明服务
|
||||
|
||||
### 测试国际互联网网络连通性
|
||||
|
||||
执行后确保能像如下显示再进行下面步骤,否则请检查网络环境(命令行也需要能访问国际互联网, 如果google在浏览器能正常访问,但是命令行无法ping通,google搜索关键词**命令行翻墙**,参考配置一下重试)
|
||||
|
||||
```
|
||||
root@home:~# ping google.com
|
||||
正在 Ping google.com [198.18.1.9] 具有 32 字节的数据:
|
||||
来自 198.18.1.9 的回复: 字节=32 时间<1ms TTL=64
|
||||
来自 198.18.1.9 的回复: 字节=32 时间<1ms TTL=64
|
||||
来自 198.18.1.9 的回复: 字节=32 时间<1ms TTL=64
|
||||
来自 198.18.1.9 的回复: 字节=32 时间<1ms TTL=64
|
||||
198.18.1.9 的 Ping 统计信息:
|
||||
数据包: 已发送 = 4,已接收 = 4,丢失 = 0 (0% 丢失),
|
||||
往返行程的估计时间(以毫秒为单位):
|
||||
最短 = 0ms,最长 = 0ms,平均 = 0ms
|
||||
```
|
||||
|
||||
### 测试佳明国际区网络连通性
|
||||
|
||||
```
|
||||
root@home:~# ping sso.garmin.com
|
||||
PING sso.garmin.com.cdn.cloudflare.net (104.17.113.66) 56(84) bytes of data.
|
||||
64 bytes from 104.17.113.66 (104.17.113.66): icmp_seq=1 ttl=63 time=1.92 ms
|
||||
64 bytes from 104.17.113.66 (104.17.113.66): icmp_seq=2 ttl=63 time=1.27 ms
|
||||
64 bytes from 104.17.113.66 (104.17.113.66): icmp_seq=3 ttl=63 time=2.43 ms
|
||||
|
||||
--- sso.garmin.com.cdn.cloudflare.net ping statistics ---
|
||||
```
|
||||
|
||||
### 测试中国区网络连通性
|
||||
|
||||
```
|
||||
root@home:~# ping sso.garmin.cn
|
||||
PING sso.garmin.cn (61.150.74.194) 56(84) bytes of data.
|
||||
64 bytes from 61.150.74.194: icmp_seq=1 ttl=63 time=1.69 ms
|
||||
64 bytes from 61.150.74.194: icmp_seq=2 ttl=63 time=2.77 ms
|
||||
64 bytes from 61.150.74.194: icmp_seq=3 ttl=63 time=7.12 ms
|
||||
|
||||
--- sso.garmin.cn ping statistics ---
|
||||
```
|
||||
|
||||
### 安装 `NodeJS`
|
||||
|
||||
下载地址 [https://nodejs.org/en/](https://nodejs.org/en/)
|
||||
|
||||
### 开启 `yarn`
|
||||
|
||||
`NodeJS` 安装完毕后,新打开一个管理员命令行窗口, 输入命令执行
|
||||
|
||||
### 安装依赖
|
||||
|
||||
在`README.md`同级目录打开命令行,执行
|
||||
|
||||
Windows在文件管理器中打开脚本所在的目录,在地址栏输入 `cmd` 然后回车,即可打开命令行,这个步骤不需要管理员权限
|
||||
|
||||
### 填入账号密码
|
||||
|
||||
打开 `src/constant.ts`, 填入您的佳明账号及密码
|
||||
|
||||
### 运行脚本
|
||||
|
||||
注意: 如果执行不能成功,请尝试将梯子更换为美国IP,多更换几个ip试试
|
||||
|
||||
同步中国区到国际区
|
||||
|
||||
同步国际区到中国区
|
||||
|
||||
#### 常见问题
|
||||
|
||||
如果上面ping都正常,却仍然不能正常运行,请尝试将梯子更换为美国IP
|
||||
|
||||
## 定时任务(Linux Only)
|
||||
|
||||
上面手动执行名称成功迁移后,可以添加定时任务来自动执行
|
||||
|
||||
`crontab -e` 打开定时任务编辑,按需添加:
|
||||
|
||||
### 每3小时检查并同步国际区到中国区【可选】,注意PATH和SHELL两行也要写上
|
||||
|
||||
```
|
||||
PATH=$PATH:/usr/local/bin:/usr/bin
|
||||
SHELL=/bin/bash
|
||||
* */3 * * * cd /root/code/dailysync/ && yarn --cwd /root/code/dailysync/ sync_global >> /var/log/dailysync.log 2>&1
|
||||
```
|
||||
|
||||
### 每3小时检查并同步中国区到国际区【可选】,注意PATH和SHELL两行也要写上
|
||||
|
||||
```
|
||||
PATH=$PATH:/usr/local/bin:/usr/bin
|
||||
SHELL=/bin/bash
|
||||
* */3 * * * cd /root/code/dailysync/ && yarn --cwd /root/code/dailysync/ sync_cn >> /var/log/dailysync.log 2>&1
|
||||
```
|
||||
|
||||
其中 `/root/code/dailysync/`为脚本在机器上的目录地址,更换为您机器上的目录即可
|
||||
|
||||
[](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/crontab-e.png)
|
||||
|
||||
### 运行日志查看
|
||||
|
||||
```
|
||||
tail -100f /var/log/dailysync.log
|
||||
```
|
||||
|
||||
### 修改定时任务执行频率
|
||||
|
||||
当前为 `*/10 * * * *` 每 10 分钟执行一次
|
||||
|
||||
您可以按需修改, 参考网址 [https://crontab.guru/examples.html](https://crontab.guru/examples.html)
|
||||
|
||||
列举几个常用的:
|
||||
|
||||
每小时执行一次: `0 * * * *`
|
||||
|
||||
每6小时执行一次: `0 */6 * * *`
|
||||
|
||||
每12小时执行一次: `0 */12 * * *`
|
||||
|
||||
---
|
||||
|
||||
**自动 安全 省心**
|
||||
|
||||
**如果看不到此文档的图片,请移步 [知乎链接](https://zhuanlan.zhihu.com/p/543799435)**
|
||||
|
||||
此工具实现了佳明运动活动数据(生理数据如睡眠,身体电量,**步数** 等除外)的一次性迁移与日常运动数据同步,实现同步运动数据到到Strava [Strava全球热图](https://www.strava.com/heatmap) 。 额外还实现了RQ数据采集记录跑力的长期趋势及自动签到。
|
||||
|
||||
## 功能
|
||||
|
||||
### 迁移数据
|
||||
|
||||
- 支持佳明账号中已有的运动数据从中国区一次性迁移到国际区。对应 `Action`: `Migrate Garmin CN to Garmin Global`
|
||||
- 支持佳明账号中已有的运动数据从国际区一次性迁移到中国区。对应 `Action`: `Migrate Garmin Global to Garmin CN`
|
||||
|
||||
### 同步数据
|
||||
|
||||
- 约每20分钟左右检查当前中国区账号中是否有新的运动数据,如有则自动下载上传到国际区,并同步到Strava。 对应 `Action`: `Sync Garmin CN to Garmin Global`
|
||||
- 如果您常用的是国际区,想要在国内运动软件(悦跑圈/咕咚/keep/郁金香等等)同步运动数据及微信运动中显示 【Garmin手表 骑行xx分钟】([微信运动效果](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/wx_sport.jpg)) 此工具可以实现自动反向同步中国区。 对应 `Action`: `Sync Garmin Global to Garmin CN`
|
||||
- 微信步数同步:
|
||||
- `iOS`: 佳明爱运动小程序绑定后,国际区->中国区同步仅能同步活动数据。出去运动不带手机的话,步数会记录在手表中,活动同步后,`Connect`会将步数上传到`健康` App 中,微信与健康应用链接,即可在微信运动中看到步数。
|
||||
- `Android`: 暂无可行方法。
|
||||
- 如无特殊需求,强烈建议不要将两个同步脚本同时打开,按需开启一个即可!
|
||||
|
||||
### 采集数据
|
||||
|
||||
- 采集RQ统计数据到GoogleSheets,记录跑力的长期趋势。参见: [RQ数据采集到GoogleSheets教程](https://gitlab.com/zhiqiangf/dailysync/-/blob/main/RQ_GoogleSheets.md)
|
||||
- RQ自动签到。参见:[RQ自动签到](https://gitlab.com/zhiqiangf/dailysync/-/blob/main/RQ_Sign.md)
|
||||
|
||||
## 说明
|
||||
|
||||
#### 免责声明:
|
||||
|
||||
本工具仅限用于学习和研究使用,不得用于商业或者非法用途。如有任何问题可联系本人删除。
|
||||
|
||||
#### 账号安全:
|
||||
|
||||
账号及密码保存在自己的 `github secrets` 中,不会泄露,运行代码均 **开放源码**,欢迎提交`PR`。
|
||||
|
||||
#### 进群讨论
|
||||
|
||||
为方便讨论,请加我绿色软件:nononopass (下面扫码)我拉你进群。`nononopass` 我拉你进群。 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/wechat_qr.png)
|
||||
|
||||
#### 支持作者
|
||||
|
||||
如果帮助到了你,可以 [Buy Me a Coffee](https://gitlab.com/zhiqiangf/dailysync#buy-me-a-coffee),赞助者会在文章下方留下ID表示感谢🙏。
|
||||
|
||||
#### 关键更新日志
|
||||
|
||||
- 2022-10-11:佳明服务器抽风,需要重置密码才能继续使用账号
|
||||
|
||||
> 解决方法如下,另外对代码也进行了优化,将登录信息加密存储复用,不必每次执行同步任务都登录一次,所以需要新增一条secrets,见下面解决方法。
|
||||
|
||||
```
|
||||
最近如果收到来自佳明重置密码的邮件(国际区)/短信(中国区),请按照如下方式操作一下(没收到可以先不管,也有可能仅收到国际区的邮件,如果收到就重置对应区的密码):
|
||||
1、登录ConnectWeb页面:国际区:https://connect.garmin.com/modern/ 中国区:https://connect.garmin.cn/modern
|
||||
2、然后用邮箱收到的临时密码登录,重置密码,重置密码可以和原来密码相同,但是为了安全还是建议您更换一个新密码
|
||||
3、如果您在第2步更换了新密码,在Github的secrets中更新 GARMIN_GLOBAL_PASSWORD 的值为国际区新密码,GARMIN_PASSWORD 的值为中国区新密码
|
||||
4、更新代码,方法见文档FAQ
|
||||
5、在Github的secrets中新增一条记录,名称 AESKEY ,内容为任意小于32位长度的字符串,用于加密账号登录信息,举例(不要复制使用):KAD1JLA12SKDJLASDJ
|
||||
```
|
||||
|
||||
- 2022-09-01: 新增支持国际区同步新数据到中国区
|
||||
- 新增一个`action`:`Sync Garmin Global to Garmin CN`,开启后自动执行。与同步中国区到国际区操作一致。
|
||||
- 2022-08-07: 支持国际区迁移数据到中国区
|
||||
- 新增一个`action`:`Migrate Garmin Global to Garmin CN`,手动执行。与迁移中国区到国际区操作一致。
|
||||
- 2022-06-15: 增加佳明中国区迁移及同步国际区数据功能,同步 `strava`
|
||||
- 2022-06-06: 采集`RQ`统计数据到`Google Sheets`
|
||||
|
||||
#### 在用这个工具的大佬们(除了作者)欢迎点进链接加加好友~(点击展开) ([填写您的链接](https://wj.qq.com/s2/10633783/a1ef/))
|
||||
|
||||
名称
|
||||
|
||||
Strava运动员链接
|
||||
|
||||
Zhitao Yan
|
||||
|
||||
[https://www.strava.com/athletes/84396978](https://www.strava.com/athletes/84396978)
|
||||
|
||||
💻Author
|
||||
|
||||
Clown jiang
|
||||
|
||||
[https://www.strava.com/athletes/105952743](https://www.strava.com/athletes/105952743)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
老弟
|
||||
|
||||
[https://www.strava.com/athletes/91478457](https://www.strava.com/athletes/91478457)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
Zax Wen
|
||||
|
||||
[https://www.strava.com/athletes/91553718](https://www.strava.com/athletes/91553718)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
李二牛
|
||||
|
||||
[https://www.strava.com/athletes/43684509](https://www.strava.com/athletes/43684509)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
围脖B站@我是冯瑞恒
|
||||
|
||||
[https://www.strava.com/athletes/34349982](https://www.strava.com/athletes/34349982)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
刘
|
||||
|
||||
[https://www.strava.com/athletes/67222235](https://www.strava.com/athletes/67222235)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
狼朗
|
||||
|
||||
[https://www.strava.com/athletes/43107517](https://www.strava.com/athletes/43107517)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
微醺漂移
|
||||
|
||||
[https://www.strava.com/athletes/19108713](https://www.strava.com/athletes/19108713)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
hua xu
|
||||
|
||||
[https://www.strava.com/athletes/40855048](https://www.strava.com/athletes/40855048)
|
||||
|
||||
L.X
|
||||
|
||||
[https://www.strava.com/athletes/86727066](https://www.strava.com/athletes/86727066)
|
||||
|
||||
姜宁
|
||||
|
||||
[https://www.strava.com/athletes/54001163](https://www.strava.com/athletes/54001163)
|
||||
|
||||
jogging tiger
|
||||
|
||||
[https://www.strava.com/athletes/105416045](https://www.strava.com/athletes/105416045)
|
||||
|
||||
Eph
|
||||
|
||||
[https://www.strava.com/athletes/8376311](https://www.strava.com/athletes/8376311)
|
||||
|
||||
YunBond
|
||||
|
||||
[https://www.strava.com/athletes/33650658](https://www.strava.com/athletes/33650658)
|
||||
|
||||
ygnnbpkn
|
||||
|
||||
[https://www.strava.com/athletes/107433069](https://www.strava.com/athletes/107433069)
|
||||
|
||||
HY.Dong
|
||||
|
||||
[https://www.strava.com/athletes/8901566](https://www.strava.com/athletes/8901566)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
陆凡
|
||||
|
||||
[https://www.strava.com/athletes/48067019](https://www.strava.com/athletes/48067019)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
JiaJian He
|
||||
|
||||
[https://www.strava.com/athletes/13495215](https://www.strava.com/athletes/13495215)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
生如胡杨
|
||||
|
||||
[https://www.strava.com/athletes/107773658](https://www.strava.com/athletes/107773658)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
doudouhuang
|
||||
|
||||
[https://www.strava.com/athletes/107830101](https://www.strava.com/athletes/107830101)
|
||||
|
||||
解凌曦
|
||||
|
||||
[https://www.strava.com/athletes/62080682](https://www.strava.com/athletes/62080682)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
欢乐铁三陈琨
|
||||
|
||||
[https://www.strava.com/athletes/107733443](https://www.strava.com/athletes/107733443)
|
||||
|
||||
Fseeeee
|
||||
|
||||
[https://www.strava.com/athletes/45675087](https://www.strava.com/athletes/45675087)
|
||||
|
||||
神月
|
||||
|
||||
[https://www.strava.com/athletes/69135349](https://www.strava.com/athletes/69135349)
|
||||
|
||||
清风故人
|
||||
|
||||
[https://www.strava.com/athletes/105799254](https://www.strava.com/athletes/105799254)
|
||||
|
||||
lu\_yuanyuan
|
||||
|
||||
[https://www.strava.com/athletes/lu\_yuanyuan](https://www.strava.com/athletes/lu_yuanyuan)
|
||||
|
||||
axiuff
|
||||
|
||||
[https://www.strava.com/athletes/107599333](https://www.strava.com/athletes/107599333)
|
||||
|
||||
iceirislei
|
||||
|
||||
[https://www.strava.com/athletes/84396978](https://www.strava.com/athletes/84396978)
|
||||
|
||||
江小鱼
|
||||
|
||||
[https://www.strava.com/athletes/29648564](https://www.strava.com/athletes/29648564)
|
||||
|
||||
作樂
|
||||
|
||||
[https://www.strava.com/athletes/102557902](https://www.strava.com/athletes/102557902)
|
||||
|
||||
Ink Jiang
|
||||
|
||||
[https://www.strava.com/athletes/107398383](https://www.strava.com/athletes/107398383)
|
||||
|
||||
kk
|
||||
|
||||
[https://www.strava.com/athletes/108302326](https://www.strava.com/athletes/108302326)
|
||||
|
||||
Kailin Aogu
|
||||
|
||||
[https://www.strava.com/athletes/108426264](https://www.strava.com/athletes/108426264)
|
||||
|
||||
Jason
|
||||
|
||||
[https://www.strava.com/athletes/78018552](https://www.strava.com/athletes/78018552)
|
||||
|
||||
七叔uncle
|
||||
|
||||
[https://www.strava.com/athletes/100219084](https://www.strava.com/athletes/100219084)
|
||||
|
||||
lenmio
|
||||
|
||||
[https://www.strava.com/athletes/23144564](https://www.strava.com/athletes/23144564)
|
||||
|
||||
王冰
|
||||
|
||||
[https://www.strava.com/athletes/96827296](https://www.strava.com/athletes/96827296)
|
||||
|
||||
AndrewRen
|
||||
|
||||
[https://www.strava.com/athletes/47354232](https://www.strava.com/athletes/47354232)
|
||||
|
||||
湖南吴彦祖
|
||||
|
||||
[https://www.strava.com/athletes/27560743](https://www.strava.com/athletes/27560743)
|
||||
|
||||
古玉沁心
|
||||
|
||||
[https://www.strava.com/athletes/guyuqinxin](https://www.strava.com/athletes/guyuqinxin)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
FLynn
|
||||
|
||||
[https://www.strava.com/athletes/103444104](https://www.strava.com/athletes/103444104)
|
||||
|
||||
herui9706
|
||||
|
||||
[https://www.strava.com/athletes/26760320](https://www.strava.com/athletes/26760320)
|
||||
|
||||
跑得动跑不动
|
||||
|
||||
[https://www.strava.com/athletes/92683851](https://www.strava.com/athletes/92683851)
|
||||
|
||||
Alexlei
|
||||
|
||||
[https://www.strava.com/athletes/85319344](https://www.strava.com/athletes/85319344)
|
||||
|
||||
Benny
|
||||
|
||||
[https://www.strava.com/athletes/106952288](https://www.strava.com/athletes/106952288)
|
||||
|
||||
挖煤猫
|
||||
|
||||
[https://www.strava.com/athletes/108006082](https://www.strava.com/athletes/108006082)
|
||||
|
||||
行者阿里
|
||||
|
||||
[https://www.strava.com/athletes/107605370](https://www.strava.com/athletes/107605370)
|
||||
|
||||
谌雕
|
||||
|
||||
[https://www.strava.com/athletes/100452318](https://www.strava.com/athletes/100452318)
|
||||
|
||||
米有才
|
||||
|
||||
[https://www.strava.com/athletes/lu\_yuanyuan](https://www.strava.com/athletes/lu_yuanyuan)
|
||||
|
||||
昊子LoveCoCo
|
||||
|
||||
[https://www.strava.com/athletes/11280405](https://www.strava.com/athletes/11280405)
|
||||
|
||||
✨Sponsor
|
||||
|
||||
HuangXin
|
||||
|
||||
[https://www.strava.com/athletes/105468976](https://www.strava.com/athletes/105468976)
|
||||
|
||||
DougSun
|
||||
|
||||
[https://www.strava.com/athletes/dougsun](https://www.strava.com/athletes/dougsun)
|
||||
|
||||
我是渣跑
|
||||
|
||||
[https://www.strava.com/athletes/37057287](https://www.strava.com/athletes/37057287)
|
||||
|
||||
古蒂
|
||||
|
||||
[https://www.strava.com/athletes/68463270](https://www.strava.com/athletes/68463270)
|
||||
|
||||
小脑腐
|
||||
|
||||
[https://www.strava.com/athletes/105403238](https://www.strava.com/athletes/105403238)
|
||||
|
||||
Winter
|
||||
|
||||
[https://www.strava.com/athletes/110758645](https://www.strava.com/athletes/110758645)
|
||||
|
||||
## 如何使用?
|
||||
|
||||
视频教程参考: [中国区佳明运动数据同步Strava视频教程](https://www.bilibili.com/video/BV1v94y1Q7oR/)
|
||||
|
||||
如果按照视频还是无法达到预期的效果(包括佳明国际区点不进去,跳转到com.cn、github 添加 secrets 没有反应等),请自行解决不可描述的网络问题。 如果`github` 上的图片看不到,那大概率是被墙了,看图请移步 [知乎链接](https://zhuanlan.zhihu.com/p/543799435), 文档内容以`github` 版本为准,其他地方可能不是最新的。
|
||||
|
||||
## 教程开始
|
||||
|
||||
### 迁移已有运动数据,并开启自动同步功能
|
||||
|
||||
[佳明国际区网址](https://connect.garmin.com/signin/)
|
||||
|
||||
[佳明国区网址](https://connect.garmin.cn/signin/)
|
||||
|
||||
[Strava网址](https://www.strava.com/)
|
||||
|
||||
#### 前置条件:
|
||||
|
||||
##### **注册好佳明国际区的帐号及Strava账号,并已经将Strava与佳明国际区账号关联,并开启Strava数据权限(下图)**
|
||||
|
||||
---
|
||||
|
||||
## **如果看不到此文档的图片,请移步 [知乎链接](https://zhuanlan.zhihu.com/p/543799435)**
|
||||
|
||||
[](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/consent.png)
|
||||
|
||||
##### 佳明账号隐私设置
|
||||
|
||||
如果是新注册的账号,包括中国区与国际区,请确保账号隐私设置中的`存储和处理` 是 `同意`状态,`设备上传`是`已启用` 状态(下图) ,否则上传数据会报`412`错误码:`User explicity revoked consent for uploading files.` [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/connect_permission.png)
|
||||
|
||||
##### 关闭佳明账号两步验证
|
||||
|
||||
如果的佳明账号在登录网页版Connect时,需要填入验证码,说明您开启了两步验证,需要关闭此选项才能使用本工具,如果不需要验证码就能登录,可跳过此步骤。
|
||||
|
||||
点击下方链接,请按照图中设置关闭
|
||||
|
||||
[https://www.garmin.cn/zh-CN/account/security/mfa](https://www.garmin.cn/zh-CN/account/security/mfa) [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/mfa.jpg)
|
||||
|
||||
---
|
||||
|
||||
#### Step1: fork 此工程
|
||||
|
||||
点击【Fork】,**也请顺手点一下【Fork】旁边的【Star】,支持一下作者** ,fork到自己账号下。 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/fork.jpg)
|
||||
|
||||
#### Step2: 配置填入自己的佳明国内区、国际区账号及密码
|
||||
|
||||
如下图打开Secrets配置,点击 【New repository secret】 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/settings.jpg)
|
||||
|
||||
准备自己的帐号密码及要迁移的数据量
|
||||
|
||||
**佳明国内账号邮箱地址**: `GARMIN_USERNAME`
|
||||
|
||||
**佳明国内账号密码**: `GARMIN_PASSWORD`
|
||||
|
||||
**佳明国际账号邮箱地址**: `GARMIN_GLOBAL_USERNAME`
|
||||
|
||||
**佳明国际账号密码**: `GARMIN_GLOBAL_PASSWORD`
|
||||
|
||||
**要迁移的活动数量,先填1**: `GARMIN_MIGRATE_NUM`
|
||||
|
||||
**从第几个活动开始迁移,先填 0**: `GARMIN_MIGRATE_START`
|
||||
|
||||
**2022-10-11新增必填项:**: `AESKEY` 信息加密存储KEY,可以随意输入任意小于32位长度的字符串,举例(不要复制使用):`KAD1JLA12SKDJLASDJ`)
|
||||
|
||||
共计7个
|
||||
|
||||
[](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/secrets.jpg)
|
||||
|
||||
填完后确保如下图红框内的都填上了, 红框外的不用管
|
||||
|
||||
[](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/secrets_ok1.png) 必须的权限设置,否则会不成功 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/repo_permission.png)
|
||||
|
||||
#### Step3: 手动迁移已有数据
|
||||
|
||||
对应的Actions,按需选择运行
|
||||
|
||||
`Migrate Garmin CN to Garmin Global(中国区到国际区)`
|
||||
|
||||
`Migrate Garmin Global to Garmin CN(国际区到中国区)`
|
||||
|
||||
这里以中国区到国际区为例,如下图,点击`Actions`\--> `Migrate Garmin CN to Garmin Global(中国区到国际区)` --> `Run workflow` 执行迁移数据 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/migrate.jpg)
|
||||
|
||||
点击后刷新页面,可以看到正在执行的任务: [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/migrating.jpg)
|
||||
|
||||
点进去后可以查看日志,如果 `Run yarn migrate_garmin_cn_to_global`那一栏看到 `Garmin userInfo CN` 和 `Garmin userInfo global`, 并且数据持续在滚动刷新,就说明正常运行 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/test_migrate.png) [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/log.jpg)
|
||||
|
||||
如果上面一切正常,运行结束后,前面会是一个绿色,代表运行完成。 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/migrated.png)
|
||||
|
||||
这个时候,去佳明国际区和`strava`看看,是否有1条数据迁移过来,如果没有,代表有问题,请联系我咨询,如果有,代表正常运行。
|
||||
|
||||
(这一块如果看文字不是很清楚到话去看看文章开始部分的视频教程,参照看看)
|
||||
|
||||
上面正常的话开始迁移剩余数据
|
||||
|
||||
**回到 Step2 的地方,分别修改**
|
||||
|
||||
`GARMIN_MIGRATE_NUM` 为 `500`
|
||||
|
||||
`GARMIN_MIGRATE_START` 为 `1`
|
||||
|
||||
然后按照上面执行过的步骤,参照Step3再执行一次,执行成功后检查佳明国际区及Strava上是否迁移过来。
|
||||
|
||||
您可以在Strava页面核对总的运动记录数。 [https://www.strava.com/athlete/training](https://www.strava.com/athlete/training) [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/strava_activities.png)
|
||||
|
||||
如果您数据较多,如几千条的情况,需要多运行几次。
|
||||
|
||||
- 修改 `GARMIN_MIGRATE_START` 的值为之前累计的值 `501`
|
||||
- 按照 `Step2` 运行
|
||||
- 将 `GARMIN_MIGRATE_START` 的值增加 `500`
|
||||
- 按照 `Step2` 运行 ,直至所有数据迁移完成
|
||||
|
||||
执行迁移的时候,请不要在web端再登录connect账号,同时请**打开日志观察执行情况,中间极有可能佳明的接口出异常导致任务失败**,如果遇到失败的情况,检查日志,看失败的时候`相对总数`是多少条
|
||||
|
||||
```
|
||||
本次开始向国际区上传第 一 条数据,【相对总数】上传到 七零一 条, 【 xx市 公路自行车 】,开始于 【 20xx-x-x 19:11:10 】,活动ID: 【 0000000 】
|
||||
upload to garmin activity {
|
||||
detailedImportResult: {
|
||||
uploadId: 155871498739,
|
||||
uploadUuid: { uuid: '0a80bfce-f94c-4ced-8fdd-8c3075032018' },
|
||||
owner: 107917164,
|
||||
fileSize: 29087,
|
||||
processingTime: 49,
|
||||
creationDate: '2022-10-01 12:51:18.931 GMT',
|
||||
ipAddress: null,
|
||||
fileName: '44055967_ACTIVITY.fit',
|
||||
report: null,
|
||||
successes: [],
|
||||
failures: []
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
然后将 `GARMIN_MIGRATE_START` 修改为失败时的`相对总数`,是数字,如`701`,不是上边日志里的文字数字。然后重新执行,直到所有数据迁移完成。
|
||||
|
||||
> 迁移数据比较慢,请耐心等待,实测15分钟迁移100条左右
|
||||
|
||||
#### Step4: 自动同步新的运动数据
|
||||
|
||||
对应的Actions,按需选择运行
|
||||
|
||||
`Sync Garmin CN to Garmin Global (中国区到国际区)`
|
||||
|
||||
`Sync Garmin Global to Garmin CN(国际区到中国区)`
|
||||
|
||||
下面以中国区到国际区为例
|
||||
|
||||
如图点击开启`workflow` [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/enable_workflow.jpg)
|
||||
|
||||
**开启后无需额外配置,除早上外,其他时候大约每30分钟左右自动同步一次数据,一段时间后可以查看同步记录.** [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/sync.jpg)
|
||||
|
||||
至此,所有工作完毕,强烈建议阅读完下方的`FAQ`部分,您后期可能遇到的大部分问题都会有解答。
|
||||
|
||||
如果我的工作帮到了您,可以考虑在最下方扫码赞助我一杯咖啡哦~
|
||||
|
||||
#### FAQ:
|
||||
|
||||
##### 数据没有同步成功?
|
||||
|
||||
可能的原因:
|
||||
|
||||
1. 请先检查手机`connect`,确保运动在`connect`看到才能进行后续的同步工作。
|
||||
2. 定时执行没有执行,可以像执行`MIGRATE`那样手动执行`Sync Garmin CN to Garmin Global (中国区到国际区)`或者`Sync Garmin Global to Garmin CN(国际区到中国区)` 来手动触发同步。可以将Github的地址在手机上存个书签,运动完手动运行一下`Sync`就能立刻同步了。
|
||||
3. 检查佳明服务器状态 [https://connect.garmin.com/status](https://connect.garmin.com/status)
|
||||
|
||||
##### 数据同步为什么没有按计划执行,有的时候一小时才执行了2次?
|
||||
|
||||
参考: [Schedule every 5 mins but runs a bit randomly](https://github.community/t/schedule-every-5-mins-but-runs-a-bit-randomly/159355/2)
|
||||
|
||||
原因: github的定时计划任务以尽力而为的策略运行。
|
||||
|
||||
**我代码中写的是每10分钟执行一次,实际情况是大约每20分钟执行一次。**
|
||||
|
||||
尤其是早上8点左右,几乎都会延迟很久执行,原因是大概我们8点对应美国0点,其他很多程序的定时任务在0点执行,导致我们的任务抢不到计算资源,导致延迟执行。 着急的话上来手动执行一下就好。
|
||||
|
||||
文中建议改为每5分钟一次,但是如果这样的话会超出每月的免费可用额度。如果您急切的想同步数据,建议上来手动操作一下。
|
||||
|
||||
翻译:
|
||||
|
||||
> 欢迎来到 GitHub 支持社区!计划的操作工作流以尽力而为的策略运行。当您的计划到期时,您的工作流将添加到池中并在资源可用时运行。这意味着您可能会看到与您的计划时间和工作流运行的实际时间相比有所延迟,尽管这可能会导致更长的延迟,具体取决于当时可用的资源。 您可以安排工作流运行的最短时间为每 5 分钟一次。由于这种池化,如果在您的下一个计划设置为运行时,池中已经有运行等待,您可能会看到运行被“跳过”。 工程团队正在研究提高调度的可用性、扩展性和响应时间,但如果您需要精确的调度操作,那么您可能会更好地寻找替代解决方案,例如在您自己的 VPS 上运行 cron。
|
||||
|
||||
##### 需要每天都来同步数据吗?
|
||||
|
||||
不用。上面的步骤执行过后,MIGRATE手动迁移已有数据,再有新跑的数据会在SYNC中大约每20分钟左右自动同步一次数据
|
||||
|
||||
##### 修改自动同步的频率
|
||||
|
||||
当前为 `*/10 * * * *` 每 10 分钟执行一次
|
||||
|
||||
您可以按需修改, 参考网址 [https://crontab.guru/examples.html](https://crontab.guru/examples.html)
|
||||
|
||||
列举几个常用的:
|
||||
|
||||
每小时执行一次: `0 * * * *`
|
||||
|
||||
每6小时执行一次: `0 */6 * * *`
|
||||
|
||||
每12小时执行一次: `0 */12 * * *`
|
||||
|
||||
按您需要修改的文件:
|
||||
|
||||
- 中国区同步国际区: `sync_garmin_cn_to_garmin_global.yml`
|
||||
- 国际区同步中国区: `sync_garmin_global_to_garmin_cn.yml`
|
||||
|
||||
[](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/cron.png)
|
||||
|
||||
##### 同步最新的代码库(更新代码)
|
||||
|
||||
代码可能有优化更新,如看到下图的情况,请点击下图红框更新到最新的代码 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/update_code.jpg)
|
||||
|
||||
##### 收到`Github`执行失败的邮件
|
||||
|
||||
佳明接口偶尔抽风导致失败,不用管。 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/action_failed.png)
|
||||
|
||||
##### 收到来自佳明登录提醒的邮件
|
||||
|
||||
本工具原理为模拟用户登录进行下载、上传操作,正常,无需理会。 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/login_email.png)
|
||||
|
||||
##### 关闭自动同步
|
||||
|
||||
如图操作即可 [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/disable_sync.png)
|
||||
|
||||
## 数据同步到佳明国际区后,其他的一些可关联的运动分析平台
|
||||
|
||||
[https://intervals.icu/ (强烈推荐!!)](https://intervals.icu/)
|
||||
|
||||
[https://app.trainingpeaks.com/#home](https://app.trainingpeaks.com/#home)
|
||||
|
||||
[https://runalyze.com/dashboard](https://runalyze.com/dashboard)
|
||||
|
||||
## 同步到佳明国际区,同步Strava
|
||||
|
||||
[](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/garmin_global.png) [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/strava.png)
|
||||
|
||||
## 采集RQ数据教程:
|
||||
|
||||
点击跳转:[RQ数据采集到GoogleSheets教程](https://gitlab.com/zhiqiangf/dailysync/-/blob/main/RQ_GoogleSheets.md)
|
||||
|
||||
## TODO
|
||||
|
||||
- 采集RQ统计数据到Google表格
|
||||
- 一次性批量迁移已有活动数据到国际区
|
||||
- 自动同步新的活动数据到数据到国际区
|
||||
- 从国际区反向迁移同步到中国区功能
|
||||
- Strava数据导出上传Garmin
|
||||
- Connect API 异常出错时抛出`github actions`错误,避免内部运行失败但是外部显示成功的问题。
|
||||
- Docker本地部署运行版本,不依赖GitHub Action,避免自动运行间隔不固定的问题。
|
||||
- WebUI 管理同步及迁移任务
|
||||
- 乳酸阈值长期趋势读取与分析页面
|
||||
- 参考帖子 [https://www.reddit.com/r/Garmin/comments/x2mad3/lactate\_threshold\_accuracy\_test\_from\_052019\_to/](https://www.reddit.com/r/Garmin/comments/x2mad3/lactate_threshold_accuracy_test_from_052019_to/)
|
||||
- 国际区与中国区路线、训练课程同步
|
||||
- api:
|
||||
- 获取所有路线: [https://connect.garmin.com/web-gateway/course/owner](https://connect.garmin.com/web-gateway/course/owner)
|
||||
|
||||
```
|
||||
{
|
||||
"coursesForUser" : []
|
||||
}
|
||||
```
|
||||
|
||||
- 路线详情 [https://connect.garmin.com/course-service/course/{id}](https://connect.garmin.com/course-service/course/%7Bid%7D)
|
||||
- 下载GPX [https://connect.garmin.com/course-service/course/gpx/{id}](https://connect.garmin.com/course-service/course/gpx/%7Bid%7D)
|
||||
- 导入GPX [https://connect.garmin.com/modern/proxy/course-service/course/import](https://connect.garmin.com/modern/proxy/course-service/course/import)
|
||||
- 上传课程,可以直接用 路线详情的响应数据,优先测试此方法。 POST [https://connect.garmin.com/course-service/course/](https://connect.garmin.com/course-service/course/)
|
||||
|
||||
## Star History
|
||||
|
||||
[](https://star-history.com/#gooin/DailySync&Date)
|
||||
|
||||
## Buy Me a Coffee
|
||||
|
||||
如果你觉得我的工作帮到了你,可赠予我一杯咖啡,感谢~ [](https://gitlab.com/zhiqiangf/dailysync/-/raw/main/assets/wechat.jpg)
|
||||
|
||||
### 支持者记录
|
||||
|
||||
姓名
|
||||
|
||||
金额(¥)
|
||||
|
||||
Monk\*\*\*\*IN
|
||||
|
||||
50
|
||||
|
||||
Cl\*\*N
|
||||
|
||||
50
|
||||
|
||||
無敵\*\*十
|
||||
|
||||
50
|
||||
|
||||
\*弟
|
||||
|
||||
50
|
||||
|
||||
S\*\*en
|
||||
|
||||
66
|
||||
|
||||
C\*\*2
|
||||
|
||||
8.88
|
||||
|
||||
星\*\*烂
|
||||
|
||||
30
|
||||
|
||||
李\*牛
|
||||
|
||||
15
|
||||
|
||||
狼\*
|
||||
|
||||
16.18
|
||||
|
||||
刘
|
||||
|
||||
50
|
||||
|
||||
A\*w
|
||||
|
||||
50
|
||||
|
||||
\*昱
|
||||
|
||||
20
|
||||
|
||||
\*仔
|
||||
|
||||
8.88
|
||||
|
||||
\*飞
|
||||
|
||||
50
|
||||
|
||||
ZKY
|
||||
|
||||
50
|
||||
|
||||
L\*\*n
|
||||
|
||||
40
|
||||
|
||||
微\*\*移
|
||||
|
||||
25
|
||||
|
||||
\*宫
|
||||
|
||||
100
|
||||
|
||||
无\*\*空
|
||||
|
||||
50
|
||||
|
||||
解\*n
|
||||
|
||||
30
|
||||
|
||||
\*亮
|
||||
|
||||
15
|
||||
|
||||
lr\*s
|
||||
|
||||
50
|
||||
|
||||
S\*e
|
||||
|
||||
8.8
|
||||
|
||||
\`
|
||||
@@ -0,0 +1,61 @@
|
||||
---
|
||||
page-title: "How do I install a root certificate? - Ask Ubuntu"
|
||||
url: https://askubuntu.com/questions/73287/how-do-i-install-a-root-certificate
|
||||
date: "2023-03-30 16:38:30"
|
||||
---
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
](https://askubuntu.com/users/31155/sparky1)
|
||||
|
||||
4
|
||||
|
||||
Given a CA certificate file `foo.crt`, follow these steps to install it on Ubuntu:
|
||||
|
||||
1. Create a directory for extra CA certificates in `/usr/local/share/ca-certificates`:
|
||||
|
||||
```
|
||||
sudo mkdir /usr/local/share/ca-certificates/extra
|
||||
```
|
||||
|
||||
2. Copy the CA `.crt` file to this directory:
|
||||
|
||||
```
|
||||
sudo cp foo.crt /usr/local/share/ca-certificates/extra/foo.crt
|
||||
```
|
||||
|
||||
3. Let Ubuntu add the `.crt` file's path relative to `/usr/local/share/ca-certificates` to `/etc/ca-certificates.conf`:
|
||||
|
||||
```
|
||||
sudo dpkg-reconfigure ca-certificates
|
||||
```
|
||||
|
||||
To do this non-interactively, run:
|
||||
|
||||
```
|
||||
sudo update-ca-certificates
|
||||
```
|
||||
|
||||
|
||||
In case of a `.pem` file on Ubuntu, it must first be converted to a `.crt` file:
|
||||
|
||||
```
|
||||
openssl x509 -in foo.pem -inform PEM -out foo.crt
|
||||
```
|
||||
|
||||
Or a `.cer` file can be converted to a `.crt` file:
|
||||
|
||||
```
|
||||
openssl x509 -inform DER -in foo.cer -out foo.crt
|
||||
```
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
](https://askubuntu.com/users/618353/beastofcaerbannog)
|
||||
|
||||
answered Jan 12, 2012 at 12:37
|
||||
|
||||
+105
@@ -0,0 +1,105 @@
|
||||
---
|
||||
page-title: "How to Install AMD OpenCL Mining Drivers on Debian 11 Bullseye"
|
||||
url: https://dazeb.uk/how-to-install-amd-opencl-mining-drivers-on-debian-11/
|
||||
date: "2023-03-27 17:27:49"
|
||||
---
|
||||
This is a new one that works great and Debian is a super stable Linux variation that’s mostly compatible with Ubuntu but does not include any bleeding edge software. Debian is stable and that’s the whole point. It’s great for server installations and mining rigs.
|
||||
|
||||
Let’s install Debian 11.
|
||||
|
||||
You can install Debian 11 from USB using programs like [Ventoy](https://www.ventoy.net/), [Rufus](https://rufus.ie/en/)
|
||||
|
||||
If you are using Linux you can write the image using dd.
|
||||
|
||||
`sudo dd if=debian-11.3.0-amd64-netinst.iso of=/dev/sd* bs=1024k status=progress`
|
||||
|
||||
You will be asked if you want to install a desktop environment during the installation. The preferred option is to use the desktop environment with XFCE and SSH.
|
||||
|
||||
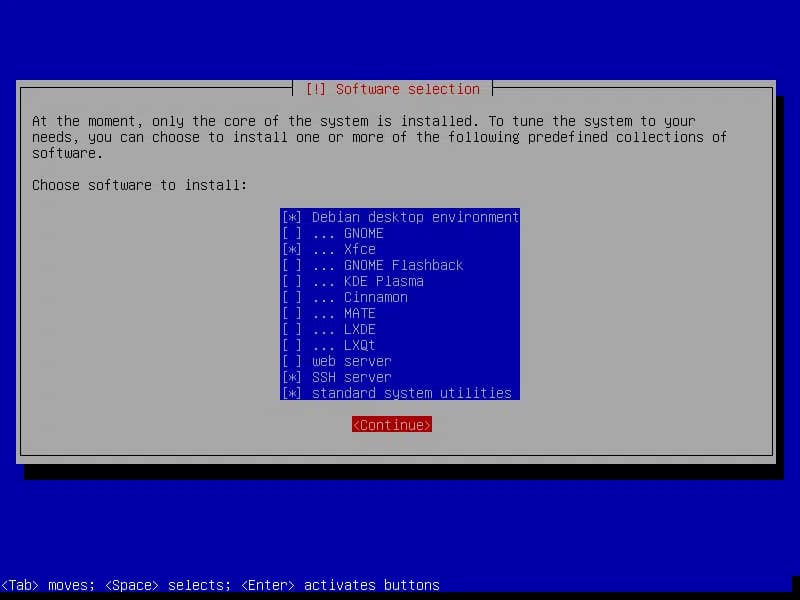
|
||||
|
||||
Debian 11 Xfce Desktop Installer
|
||||
|
||||
Once completed you will be presented with the desktop. I use the root account for this install.
|
||||
|
||||
Open the terminal and do an update to check it’s fully updated.
|
||||
|
||||
`apt update && apt-upgrade -y`
|
||||
|
||||
## Add Non-Free Repository Sources
|
||||
|
||||
Add the non-free repositories to Debian `/etc/apt/sources.list`
|
||||
|
||||
You can use `nano /etc/apt/sources/list`
|
||||
|
||||
Edit the file to look like the below. You are just adding `contrib non-free` to each line.
|
||||
|
||||
```
|
||||
deb http://deb.debian.org/debian/ bullseye main contrib non-free
|
||||
deb-src http://deb.debian.org/debian/ bullseye main contrib non-free
|
||||
|
||||
deb http://security.debian.org/debian-security bullseye-security main contrib non-free
|
||||
deb-src http://security.debian.org/debian-security bullseye-security main contrib non-free
|
||||
|
||||
# bullseye-updates, to get updates before a point release is made;
|
||||
# see https://www.debian.org/doc/manuals/debian-reference/ch02.en.html#_updates_and_backports
|
||||
deb http://deb.debian.org/debian/ bullseye-updates main contrib non-free
|
||||
deb-src http://deb.debian.org/debian/ bullseye-updates main contrib non-free
|
||||
```
|
||||
|
||||
## Installing AMD GPU Firmware
|
||||
|
||||
Update the packages. Feel free to fully update and upgrade if you like. It won’t make any difference.
|
||||
|
||||
```
|
||||
apt update
|
||||
```
|
||||
|
||||
Next, we install the non-free graphic cards drivers with:
|
||||
|
||||
```
|
||||
apt install firmware-linux-nonfree
|
||||
```
|
||||
|
||||
**You may get some errors about missing firmware**. You can safely ignore it we won’t be needing it anyway.
|
||||
|
||||
Non-free means, not open source, AMD drivers are proprietary so hence the non-free part. It doesn’t mean you have to pay anything means that the software cannot be distributed and or modified, sold etc.
|
||||
|
||||
## Downloading AMD GPU OpenCL Drivers
|
||||
|
||||
Next, we can go down the familiar route explained in previous guides. Download the old AMD drivers and install them with the following commands.
|
||||
|
||||
```
|
||||
# Change to a directory to download the file
|
||||
cd Downloads
|
||||
# Download the tar file of AMD drivers
|
||||
wget https://drivers.amd.com/drivers/linux/amdgpu-pro-20.40-1147286-ubuntu-20.04.tar.xz --referer https://www.amd.com/en/support/kb/release-notes/rn-amdgpu-unified-linux-20-40
|
||||
# unzip the tar
|
||||
tar -xJpf amdgpu-pro-*.tar.xz
|
||||
# cd into the directory
|
||||
cd amdgpu-pro-20.40-1147286-ubuntu-20.04
|
||||
```
|
||||
|
||||
## Installing AMD GPU OpenCL Drivers
|
||||
|
||||
Next, the command to install only the OpenCL drivers
|
||||
|
||||
```
|
||||
./amdgpu-install --opencl=legacy --headless --no-dkms
|
||||
```
|
||||
|
||||
The command should complete without error.
|
||||
|
||||
At this point, you can use `clinfo` to see if it recognises your gfx card.
|
||||
|
||||
```
|
||||
apt install clinfo
|
||||
clinfo
|
||||
```
|
||||
|
||||
Your computer should be mining now using Debian 11. This method was tested on RX 580 and works every time.
|
||||
|
||||
## Complete!
|
||||
|
||||
At this point, you could install CoreCtl to overclock your cards in a GUI application.
|
||||
|
||||
The Install for CoreCtl is at the [bottom of another guide I wrote](https://dazeb.uk/how-to-install-amd-opencl-gpu-drivers-on-ubuntu-21-04-for-mining-ethereum/#corectl).
|
||||
+246
@@ -0,0 +1,246 @@
|
||||
---
|
||||
page-title: "HowTos/LDAP authentication for Atlassian JIRA using FreeIPA - FreeIPA"
|
||||
url: https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA
|
||||
date: "2023-03-06 15:19:17"
|
||||
---
|
||||
[Template:Draft](https://www.freeipa.org/index.php?title=Template:Draft&action=edit&redlink=1 "Template:Draft (page does not exist)") Draft / Work in Progress on formatting
|
||||
|
||||
- [1 Introduction](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#Introduction)
|
||||
- [2 Integration Path](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#Integration_Path)
|
||||
- [3 Toolset](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#Toolset)
|
||||
- [4 Key Challenges](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#Key_Challenges)
|
||||
- [4.1 LDAP Adapter Type](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#LDAP_Adapter_Type)
|
||||
- [4.1.1 Other Candidate Adapters](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#Other_Candidate_Adapters)
|
||||
- [4.2 RFC Schemas + FreeIPA Trees](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#RFC_Schemas_.2B_FreeIPA_Trees)
|
||||
- [4.3 E-Mail Attribute and Bind Type](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#E-Mail_Attribute_and_Bind_Type)
|
||||
- [4.4 Replicating Users and Groups](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#Replicating_Users_and_Groups)
|
||||
- [4.4.1 Users](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#Users)
|
||||
- [4.4.2 Groups](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#Groups)
|
||||
- [5 The Final Configuration](https://www.freeipa.org/page/HowTos/LDAP_authentication_for_Atlassian_JIRA_using_FreeIPA#The_Final_Configuration)
|
||||
|
||||
## Introduction
|
||||
|
||||
This page describes how to integrate JIRA to a FreeIPA LDAP server. Very likely the same approach can be taken to integrate other Atlassian products such as Confluence to FreeIPA.
|
||||
|
||||
JIRA offers a number of different ways to integrate to LDAP. Unfortunately FreeIPA integration is not natively supported, but once you know how, it is not that difficult. There are probably other solutions that work as well, but this is the one that worked for us.
|
||||
|
||||
At the time of integration we were running FreeIPA Server 4.1.0 and JIRA 6.4.7
|
||||
|
||||
See:
|
||||
|
||||
[https://confluence.atlassian.com/display/JIRA/Connecting+to+an+LDAP+Directory](https://confluence.atlassian.com/display/JIRA/Connecting+to+an+LDAP+Directory) [https://confluence.atlassian.com/display/DEV/How+to+write+LDAP+search+filters](https://confluence.atlassian.com/display/DEV/How+to+write+LDAP+search+filters)
|
||||
|
||||
## Integration Path
|
||||
|
||||
JIRA can be integrated to an LDAP by a number of different paths including full bi-directional sync.
|
||||
|
||||
We chose **Internal Directory with LDAP Authentication**, which means that FreeIPA users and groups are copied to the JIRA internal directory when a FreeIPA user logs in to JIRA. i.e.
|
||||
|
||||
- FreeIPA is used for authentication
|
||||
- FreeIPA users, and optionally groups + group membership are replicated one-way to JIRA on user login.
|
||||
|
||||
|
||||
In particular this means that only a subset of the FreeIPA users will be replicated to JIRA - only those that actually log in to JIRA.
|
||||
|
||||
See [https://confluence.atlassian.com/display/JIRA/Connecting+to+an+Internal+Directory+with+LDAP+Authentication](https://confluence.atlassian.com/display/JIRA/Connecting+to+an+Internal+Directory+with+LDAP+Authentication)
|
||||
|
||||
Much of the config described below could probably be used for the other integration paths.
|
||||
|
||||
## Toolset
|
||||
|
||||
We used the following tools to gain insight into the structure of the FreeIPA LDAP directory, and to understand and simulate the queries that JIRA (might) be making against FreeIPA
|
||||
|
||||
- **Apache Directory Studio:** This or any similar visual LDAP browser is invaluable to getting into the guts of an LDAP, seeing what is where, which attributes are available (and even making changes in extremis). See [https://directory.apache.org/studio/](https://directory.apache.org/studio/)
|
||||
|
||||
- **ldapsearch:** This command line tool is your friend! Use it to simulate queries that JIRA might be making, fine tune filters, and see what FreeIPA returns. This approach helped us to see that we were initially getting results from both the compat and accounts trees - which confused JIRA, and then how to prevent this.
|
||||
|
||||
- **FreeIPA and JIRA logs:** What queries is JIRA actually making? Although you can guesstimate based on your config, it is great to see the actual queries.
|
||||
- FreeIPA Server: /var/log/dirsrv/slapd-\*/access
|
||||
- JIRA: See [https://confluence.atlassian.com/display/JIRA/Logging+and+Profiling](https://confluence.atlassian.com/display/JIRA/Logging+and+Profiling) We added the package com.atlassian.crowd.directory.SpringLDAPConnector, and got partial results.
|
||||
|
||||
## Key Challenges
|
||||
|
||||
### LDAP Adapter Type
|
||||
|
||||
While JIRA offers a wide range of LDAP Adapters, it does not (yet) offer a FreeIPA Adapter out of the box. We chose the Generic LDAP adapter, and were able to configure this for FreeIPA.
|
||||
|
||||
#### Other Candidate Adapters
|
||||
|
||||
- **FedoraDS:** We did NOT use the FedoraDS adapter (even though FedoraDS is an ancestor of FreeIPA), as this uses the compat tree due to the (objectclass=posixAccount) filter. However other freeIPA users have reported success with this adapter: [https://www.redhat.com/archives/freeipa-users/2015-June/msg00200.html](https://www.redhat.com/archives/freeipa-users/2015-June/msg00200.html)
|
||||
- **Other Adapters:** It is possible that other adapters can also be persuaded to work, with more or less additional configuration.
|
||||
|
||||
### RFC Schemas + FreeIPA Trees
|
||||
|
||||
There are several different LDAP RFC Schemas. FreeIPA uses the RFC 2307bis schema (with users stored under cn=accounts, cn=users), but also offers publishes an alternative "compat" tree cn=users,cn=compat,dc=example,dc=com with users in a RFC 2307 schema.
|
||||
|
||||
The chosen adapter, and the configuration applied to it, plays an important role here in determining which of the trees returns data. Here using ldapsearch was invaluable. For example it proved that in one of our first attempt we were getting returns from both trees, and that JIRA was using only the first return.
|
||||
|
||||
Making the query with the correct filter gave us data from the desired tree (cn=accounts, cn=users). The ldap.user.filter (objectclass=inetorgperson) ensures that replies DO NOT come from the compat tree (which among other things does not have the mail attribute).
|
||||
|
||||
See [https://www.freeipa.org/page/Directory\_Server](https://www.freeipa.org/page/Directory_Server) and [https://www.redhat.com/archives/freeipa-users/2015-June/msg00547.html](https://www.redhat.com/archives/freeipa-users/2015-June/msg00547.html)
|
||||
|
||||
### E-Mail Attribute and Bind Type
|
||||
|
||||
We managed to get users synced from FreeIPA, and able to authenticate and thus log in to JIRA fairly easily. However the email field was empty, which means that JIRA mail notification didn't work, rendering JIRA about as useful as a chocolate teapot. While the email field could be updated in the JIRA user management, it always emptied every time the user logged back on.
|
||||
|
||||
Once again ldapsearch proved what was going on: We had configured the LDAP Adapter without a user: i.e. anonymous bind. Performing the same query via simple bind: i.e. with an LDAP user, returned additional attributes, including the all important mail attribute. We therefore reconfigured the LDAP Adapter to use a FreeIPA user and password, and bingo! JIRA received the mail attribute!
|
||||
|
||||
As the password of the bind user is stored in plaintext in the jira database, make sure the user configured is a limited user (member of the default ipa-users group is sufficient). e.g. don't use the Directory Manager user!
|
||||
|
||||
### Replicating Users and Groups
|
||||
|
||||
#### Users
|
||||
|
||||
It is possible to replicate only the users to JIRA, with groups managed locally (you can configure default groups to which user are added automatically). We did this as a first step.To get this to work change:
|
||||
|
||||
- **User Schema Settings / Additional User DN** to cn=accounts
|
||||
- **User Schema Settings / User Unique ID Attribute** from entryUUID to uid
|
||||
|
||||
#### Groups
|
||||
|
||||
Additionally groups, and group memberships can be replicated to JIRA. To get this to work change:
|
||||
|
||||
- **Group Schema Settings / Additional Group DN** to cn=accounts
|
||||
- **Group Schema Settings / Group Object Class** from groupOfUniqueNames to groupOfNames
|
||||
- **Group Schema Settings / Group Object Filter** from (objectclass=groupOfUniqueNames) to (objectclass=groupOfNames)
|
||||
- **Member Schema Settings / Group Members Attribute** from uniqueMember to Member
|
||||
|
||||
## The Final Configuration
|
||||
|
||||
Below is the config direct from the Jira database (of course we made the config changes via the Jira admin GUI, which has a nifty Test function).
|
||||
|
||||
Note: you will need to change some values to reflect your domain, hostname etc
|
||||
|
||||
mysql> select attribute\_name, attribute\_value from cwd\_directory\_attribute where directory\_id = xxxx;
|
||||
|
||||
**Attribute Name**
|
||||
|
||||
**Attribute Value**
|
||||
|
||||
autoAddGroups
|
||||
|
||||
jira-users
|
||||
|
||||
crowd.delegated.directory.auto.create.user
|
||||
|
||||
true
|
||||
|
||||
crowd.delegated.directory.auto.update.user
|
||||
|
||||
true
|
||||
|
||||
crowd.delegated.directory.importGroups
|
||||
|
||||
true
|
||||
|
||||
crowd.delegated.directory.type
|
||||
|
||||
com.atlassian.crowd.directory.GenericLDAP
|
||||
|
||||
ldap.basedn
|
||||
|
||||
dc=my,dc=silly,dc=example,dc=com
|
||||
|
||||
ldap.external.id
|
||||
|
||||
uid
|
||||
|
||||
ldap.group.description
|
||||
|
||||
description
|
||||
|
||||
ldap.group.dn
|
||||
|
||||
cn=accounts
|
||||
|
||||
ldap.group.filter
|
||||
|
||||
(objectclass=groupOfNames)
|
||||
|
||||
ldap.group.name
|
||||
|
||||
cn
|
||||
|
||||
ldap.group.objectclass
|
||||
|
||||
groupOfNames
|
||||
|
||||
ldap.group.usernames
|
||||
|
||||
Member
|
||||
|
||||
ldap.nestedgroups.disabled
|
||||
|
||||
true
|
||||
|
||||
ldap.pagedresults
|
||||
|
||||
false
|
||||
|
||||
ldap.pagedresults.size
|
||||
|
||||
1000
|
||||
|
||||
ldap.password
|
||||
|
||||
*<password of the bind user>*
|
||||
|
||||
ldap.referral
|
||||
|
||||
false
|
||||
|
||||
ldap.url
|
||||
|
||||
ldap:/*/<hostname of your FreeIPA Server>*.my.silly.example.com:389
|
||||
|
||||
ldap.user.displayname
|
||||
|
||||
displayName
|
||||
|
||||
ldap.user.dn
|
||||
|
||||
cn=accounts
|
||||
|
||||
ldap.user.email
|
||||
|
||||
mail
|
||||
|
||||
ldap.user.filter
|
||||
|
||||
(objectclass=inetorgperson)
|
||||
|
||||
ldap.user.firstname
|
||||
|
||||
givenName
|
||||
|
||||
ldap.user.group
|
||||
|
||||
memberOf
|
||||
|
||||
ldap.user.lastname
|
||||
|
||||
sn
|
||||
|
||||
ldap.user.objectclass
|
||||
|
||||
inetorgperson
|
||||
|
||||
ldap.user.username
|
||||
|
||||
uid
|
||||
|
||||
ldap.user.username.rdn
|
||||
|
||||
uid
|
||||
|
||||
ldap.userdn
|
||||
|
||||
uid=*<uid of the bind user>*,cn=users,cn=accounts,dc=my,dc=silly,dc=example,dc=com
|
||||
|
||||
ldap.usermembership.use
|
||||
|
||||
false
|
||||
|
||||
ldap.usermembership.use.for.groups
|
||||
|
||||
false
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,402 @@
|
||||
---
|
||||
page-title: "Openwrt 作为旁路网关(不是旁路由、单臂路由)的终极设置方法,破解迷思 - 少数派"
|
||||
url: https://sspai.com/post/68511
|
||||
date: "2023-03-29 12:53:38"
|
||||
---
|
||||
> 副标题:以x86、斐讯N1、树莓派为例。旁路网关的性能到底重不重要?
|
||||
|
||||
先说结论:
|
||||
|
||||
> 旁路网关不会影响局域网性能,也不会影响广域网下行性能。因此,使用旁路网关的主要目的如果只是用来转发代理上网的流量,旁路网关的性能并不重要。测试可见文末。
|
||||
|
||||
破解迷思:
|
||||
|
||||
1. 旁路网关**不需要**取消br-lan,**不需要**复用eth0添加wan口!
|
||||
2. 旁路网关**不需要**打开防火墙的lan->wan IP动态伪装(POSTROUTING MASQUERADE)!
|
||||
|
||||
这两种做法都是网上常见错误设置方法,不是标准的“旁路网关”拓扑(那样做实际上是“单臂路由”),不能发挥局域网的最佳性能。具体设置方法可见文末。
|
||||
|
||||
**获取、编译 Openwrt 固件**
|
||||
|
||||
不要觉得困难,因为我已经帮你编译好了。
|
||||
|
||||
相比于官方镜像,我这个固件主要是定制和集成了一些内核模块、应用软件,更好兼容本文推荐的路由设备,更符合国内使用场景的需求。与其它一些第三方固件相比,最大的特点是:简洁。它只是为了做路由、网关而定制的固件,没有其它乱七八糟的非必须功能。
|
||||
|
||||
当然,如果你想加入其它软件,并且编译自己的版本,也是非常简单的。
|
||||
|
||||
利用 Github Actions 提供的免费集成功能,每周五会自动生成最新固件,提供下载和升级方法。
|
||||
|
||||
👇可以去我的软件仓库了解并获取固件👇
|
||||
|
||||
[Build Openwrt Firmware](https://sspai.com/link?target=https%3A%2F%2Fgithub.com%2Friverscn%2Fbuild-openwrt-firmware)
|
||||
|
||||

|
||||
|
||||
Bootstrap 主题
|
||||
|
||||

|
||||
|
||||
Argon 主题
|
||||
|
||||
**常见路由设备刷写/升级 Openwrt 固件**
|
||||
|
||||
Openwrt 固件通常是一个镜像文件,以 img 或 img.gz 为后缀。
|
||||
|
||||
主要刷写方式如下:
|
||||
|
||||
|
||||
|
||||
可从外部存储启动
|
||||
|
||||
不可从外部存储启动
|
||||
|
||||
**没有内部存储**
|
||||
|
||||
直接将固件写入存储设备
|
||||
|
||||
(不存在这样的机器)
|
||||
|
||||
**内部存储可拆卸**
|
||||
|
||||
拆下内部存储,直接将固件写入
|
||||
|
||||
拆下内部存储,直接将固件写入
|
||||
|
||||
**内部存储不可拆卸**
|
||||
|
||||
通过外部存储启动,再将固件写入内部存储
|
||||
|
||||
通过原厂系统刷入factory固件转换,或其它刷机方式
|
||||
|
||||
将镜像写入可移动存储设备的工具:[Etcher](https://sspai.com/link?target=https%3A%2F%2Fwww.balena.io%2Fetcher%2F)
|
||||
|
||||
## **X86**
|
||||
|
||||
X86 是最简单的,[官方有详细说明](https://sspai.com/link?target=https%3A%2F%2Fopenwrt.org%2Fdocs%2Fguide-user%2Finstallation%2Fopenwrt_x86)。
|
||||
|
||||
简单来说,先把设备的内置存储设备拆下来,通过USB转接的方式连接到你的电脑上。然后使用 [Etcher](https://sspai.com/link?target=https%3A%2F%2Fwww.balena.io%2Fetcher%2F) 写入镜像文件,再把存储设备装回去,就能启动了。
|
||||
|
||||
也有其它方式,比如先用一个 Ubuntu Live U盘在要安装 Openwrt 的设备上启动,在设备上将解压后的img镜像写入内置存储。命令是 `dd if=openwrt-18.06.1-x86-64-generic-ext4-combined.img of=/dev/xxx` 。
|
||||
|
||||
后续升级可以通过 Openwrt 内置的系统/升级功能进行。
|
||||
|
||||
> 网上有售x86“工控机”,具备多个网口,很适合作为路由器。在2021年,我建议你购买J4125 CPU的机器作为软路由,售价大约1000元左右。性能是NAS级的,你想用它跑任何家庭网络服务压力都不大。
|
||||
|
||||
> 也可以考虑购买“迷你主机”,和工控机并没有本质区别。对于X86电脑来说,网口不够用也没关系,通过USB3.0可以扩展USB网卡,1Gbps或2.5Gbps网卡都没问题。
|
||||
|
||||
> 你甚至可以用虚拟机跑 Openwrt 来作为路由设备,复用你现有的电脑。
|
||||
|
||||
## **单片机:以树莓派为例**
|
||||
|
||||
树莓派也非常简单,因为它是通过SD卡启动的。使用 [Etcher](https://sspai.com/link?target=https%3A%2F%2Fwww.balena.io%2Fetcher%2F) 向SD卡写入镜像文件,插卡就能启动了。[官方有详细说明](https://sspai.com/link?target=https%3A%2F%2Fopenwrt.org%2Ftoh%2Fraspberry_pi_foundation%2Fraspberry_pi)。
|
||||
|
||||
后续升级可以通过 Openwrt 内置的系统/升级功能进行。
|
||||
|
||||
其它型号的单片机,包括像 NanoPi [R2S](https://sspai.com/link?target=https%3A%2F%2Fwiki.friendlyarm.com%2Fwiki%2Findex.php%2FNanoPi_R2S%2Fzh)/[R2C](https://sspai.com/link?target=http%3A%2F%2Fwiki.friendlyarm.com%2Fwiki%2Findex.php%2FNanoPi_R2C%2Fzh)/[R4S](https://sspai.com/link?target=https%3A%2F%2Fwiki.friendlyarm.com%2Fwiki%2Findex.php%2FNanoPi_R4S%2Fzh),已获得 Openwrt 官方支持,获取固件和刷写也非常容易。
|
||||
|
||||
> 在全球芯片短缺的2021年,曾经250元左右一片的2G树莓派4B,卖到了近500元。树莓派4的性能作为路由器非常合适,本来这是一个值得考虑的选项,但现在,显得非常鸡肋了。建议等 芯片供应正常再购买。
|
||||
|
||||
> 还有很火的 NanoPi R系列,价格也涨了近一倍……建议观望,玩ARM单片机,本来就是图的便宜好玩,太贵了不如玩x86。
|
||||
|
||||
> 树莓派4B包含了两个USB3.0接口,因此可以用它来扩展USB网卡。而树莓派3B的网络接口连千兆都跑不满,不推荐使用比4B性能更差的型号来作为路由设备。
|
||||
|
||||
## **其它“电视盒子”:以斐讯N1为例**
|
||||
|
||||
斐讯N1可能需要降级并刷写改版固件,然后从U盘启动,再通过安装脚本来安装。该方式由 webpad 提供,可[参考其帖子](https://sspai.com/link?target=https%3A%2F%2Fwww.right.com.cn%2Fforum%2Fthread-340279-1-1.html)进行操作。
|
||||
|
||||
如果嫌麻烦,建议你买个刷好的二手。
|
||||
|
||||
降级后的N1可以通过刷入 Openwrt 固件的U盘启动,并将其刷入内置EMMC存储。在[我提供的固件](https://sspai.com/link?target=https%3A%2F%2Fgithub.com%2Friverscn%2Fbuild-openwrt-firmware)中,其刷写命令为 `/root/install-to-emmc.sh` ,脚本由 flippy 提供。
|
||||
|
||||
> 斐讯N1以及一些外贸盒子,都是可能在闲鱼捡到便宜货的。我手里的N1是在斐讯倒闭前,闲鱼新品甩卖时,80元的价格购买的,非常香。而现在,它可能要买接近200元,不那么香了……
|
||||
|
||||
> 这些电视盒子刷入 Openwrt 固件的方法,可能需要你在网上参考一下别人的经验。
|
||||
|
||||
> 在所有这些盒子中,性能的排序参考 flippy 的总结:amliogic s922x(代表产品:GT-King、GT-King Pro,目前性能最强的arm盒子) > rockchip rk3399 > amlogic s905x3(代表产品:X96Max+,Hk1Box,H96 Max x3) > amlogic s912(代表产品:章鱼星球, 单核与N1差不多,但核数更多) > amlogic s905x2(代表产品:X96Max) = allwinner h6(代表产品:微加云)> s905x或s905d(代表产品:N1) > rk3328(代表产品:我家云、贝壳云)
|
||||
|
||||
## **给“硬路由”刷 Openwrt**
|
||||
|
||||
本文不涉及硬路由刷 Openwrt。其方式往往是通过先刷入“factory”版 Openwrt 镜像,往后再用“sysupgrade”版镜像,来实现转为 Openwrt 启动的。[官方有详细说明](https://sspai.com/link?target=https%3A%2F%2Fopenwrt.org%2Fdocs%2Fguide-user%2Finstallation%2Fstart)。
|
||||
|
||||
> 非常不推荐给成品无线路由(硬路由)刷 Openwrt,基本上都会影响无线性能和稳定性。建议你把它设置成AP模式,用原厂固件,安安静静提供无线接入点就好。Openwrt 还是要买个软路由来跑。
|
||||
|
||||
**主路由 vs 旁路网关**
|
||||
|
||||
要实现最佳体验,需要注意根据以下情况进行选择:
|
||||
|
||||
条件
|
||||
|
||||
主路由模式
|
||||
|
||||
旁路网关模式
|
||||
|
||||
需要替换现有的主路由
|
||||
|
||||
需要
|
||||
|
||||
不需要
|
||||
|
||||
运行 Openwrt 的设备具有较高性能
|
||||
|
||||
需要
|
||||
|
||||
不需要
|
||||
|
||||
运行 Openwrt 的设备具备多个物理网络接口,且带宽足够
|
||||
|
||||
需要
|
||||
|
||||
不需要
|
||||
|
||||
如果不能满足任意其一,建议选择旁路网关模式。
|
||||
|
||||
不过世上哪有那么好的事,旁路网关虽然需要满足的条件较少,但也有其劣势,可参考文末的测试。
|
||||
|
||||
## **把 Openwrt 作为主路由**
|
||||
|
||||
这是常用模式,该模式下,所有设备的网关指向主路由IP,并且主路由作为DHCP服务器、DNS服务器。
|
||||
|
||||

|
||||
|
||||
主路由模式
|
||||
|
||||
如果运行 Openwrt 的设备有2个及以上的物理网络接口,推荐该模式。这是标准的局域网拓扑结构,所有的设备都能获得全双工的传输速率,所有流量都不会“走弯路”。
|
||||
|
||||
安装方式也很简单,用 Openwrt 路由器作为主路由就行了。
|
||||
|
||||
## **把 Openwrt 作为旁路网关**
|
||||
|
||||
但有时候,Openwrt 设备可能只有1个物理网络接口,但又想利用 Openwrt 扩展现有网络的功能,就可以用“旁路网关”的方式实现。
|
||||
|
||||
旁路网关的好处是不需要修改现有网络基础设施,只需要在标准的局域网拓扑结构中,增加一个网关设备就行了。网关设备和一个普通的局域网设备在结构上是同等地位。所以也适用于不太好替换现有主路由的情况。
|
||||
|
||||

|
||||
|
||||
旁路网关模式
|
||||
|
||||
旁路官关有两种利用方式:
|
||||
|
||||
1. 按需手动设置,只让指定的设备通过旁路网关访问Internet。
|
||||
2. 接管局域网的所有上网流量。
|
||||
|
||||
方式1不需要修改主路由配置,但需要修改客户端设备的网络设置。
|
||||
|
||||
方式2需要修改主路由配置,不需要修改客户端设备的网络设置。
|
||||
|
||||
两种方式均不影响局域网内的流量路径,局域网设备互访都是直通的(不会经过路由器或网关)。
|
||||
|
||||
**基本设置**
|
||||
|
||||
## **作为主路由的设置方法**
|
||||
|
||||
作为主路由是 Openwrt 的默认设置,这里不必多讲。
|
||||
|
||||
Openwrt 可以实现诸多高级特性,诸如多WAN、[IPTV融合](https://sspai.com/link?target=https%3A%2F%2Fblog.lishun.me%2Fiptvhelper-guide)等。这些都是做旁路网关时无法实现的功能。
|
||||
|
||||
## **作为旁路网关的设置方法**
|
||||
|
||||
### 旁路网关自身的基础设置
|
||||
|
||||
刷好固件的新 Openwrt 网关,一般默认的IP地址是192.169.1.1。你可以通过WiFi或网线,**确保电脑只连接了它**,就可以访问该管理地址了。
|
||||
|
||||
1. 在“网络”-“接口”的“常规设置”中给 Openwrt 的 LAN 网络接口设置一个和现有局域网同网段的静态 IP 地址,注意不要和现有设备的 IP 地址冲突。然后应用设置。
|
||||
2. 将 LAN 网络接口的“默认网关”设为主路由的 IP 地址。
|
||||
3. 在“高级设置”中找到“使用自定义的 DNS 服务器”设为主路由的 IP 地址。
|
||||
4. 在“DHCP 服务器”中勾选“忽略此接口”。
|
||||
5. 在“DHCP 服务器”-“IPv6 设置”中禁用所有IPv6服务。
|
||||
6. 点击“保存”以及“保存并应用”。
|
||||
7. 在“网络”-“防火墙”中,关闭“SYN-flood 防御”,点击“保存并应用”。
|
||||
8. 建议重启一次。
|
||||
|
||||

|
||||
|
||||
如果你是通过WiFi接入点访问的,现在可以插上网线,通过有线局域网来访问它了。记得**删除WiFi接入点**以降低路由器的温度。
|
||||
|
||||
至此,它已经是一个合格的旁路网关了。
|
||||
|
||||
接下来有两种使用方式,根据偏好选择。
|
||||
|
||||
### 方式一:指定的设备才使用旁路网关
|
||||
|
||||
在指定的设备上,手动设置IP地址,将其“网关”和“首选 DNS”改为旁路网关的IP地址。
|
||||
|
||||

|
||||
|
||||
### 方式二:所有设备都使用旁路网关
|
||||
|
||||
**重要的事说三遍:在主路由上设置,在主路由上设置,在主路由上设置**
|
||||
|
||||
如果**主路由**是 Openwrt 固件,找到 br-lan 网络接口,在“DHCP 服务器”的“高级设置”中添加两个选项:
|
||||
|
||||
- 3,你的网关IP
|
||||
- 6,你的网关IP
|
||||
|
||||

|
||||
|
||||
注意,这是主路由的设置,不是旁路网关!
|
||||
|
||||
如果是其它固件的主路由,或者成品路由器,找到类似“DHCP 服务器”的设置,在其中指定**默认网关**和**默认DNS服务器**是你的网关IP就行。
|
||||
|
||||
**性能测试,旁路网关的性能到底重不重要?**
|
||||
|
||||
## **测试局域网传输性能**
|
||||
|
||||
通过ssh命令 `ssh root@你的路由器ip` 进入到路由器的命令行界面。
|
||||
|
||||
`opkg update && opkg install iperf3` 安装 iperf3 测试软件。
|
||||
|
||||
`iperf3 -s` 运行测试。
|
||||
|
||||
在局域网的另一台机器上,同样安装 [iperf3](https://sspai.com/link?target=https%3A%2F%2Fiperf.fr%2Fiperf-download.php) 软件。
|
||||
|
||||
```
|
||||
iperf3 -c 你的路由器ip
|
||||
iperf3 -c 你的路由器ip -R
|
||||
```
|
||||
|
||||
运行测试。先是测试的路由器从测试机下载数据的性能,再测试的是反过来的性能。
|
||||
|
||||
这是我测试的自己的树莓派4B的性能:
|
||||
|
||||
```
|
||||
$ iperf3 -c 192.168.1.3
|
||||
[ ID] Interval Transfer Bandwidth
|
||||
[ 4] 0.00-10.00 sec 1.10 GBytes 949 Mbits/sec sender
|
||||
[ 4] 0.00-10.00 sec 1.10 GBytes 949 Mbits/sec receiver
|
||||
|
||||
$ iperf3 -c 192.168.1.3 -R
|
||||
Reverse mode, remote host 192.168.1.3 is sending
|
||||
[ ID] Interval Transfer Bandwidth Retr
|
||||
[ 4] 0.00-10.00 sec 1.10 GBytes 944 Mbits/sec 0 sender
|
||||
[ 4] 0.00-10.00 sec 1.10 GBytes 944 Mbits/sec receiver
|
||||
```
|
||||
|
||||
## **通过 netdata 软件监控性能状况**
|
||||
|
||||
在路由器中运行 `opkg update && opkg install netdata` 安装 netdata 监控软件。或者在“系统/软件包”菜单中安装。
|
||||
|
||||
然后在浏览器上访问 `http://路由器ip:19999` 就可以了
|
||||
|
||||
## **测试广域网转发性能、代理转发性能**
|
||||
|
||||
在 netdata 中点击右上角 Settings, 关闭 On Focus。
|
||||
|
||||
同时启动一个测速软件,例如 Speedtest.net,跑一跑,看看性能如何?
|
||||
|
||||
我们来验证一下,上文所说的,各种流量情况下,主路由和旁路网关的负载情况?
|
||||
|
||||
(我家的宽带标称500M,上行标称100M)
|
||||
|
||||
### 1\. 广域网下行流量
|
||||
|
||||
主路由负责转发流量,旁路网关围观。
|
||||
|
||||

|
||||
|
||||
测试设备:树莓派4B(下面的仪表盘)
|
||||
|
||||
旁路网关真的在围观吗?我想了个办法,在树莓派上跑iperf3,把它的出站流量占满,同时开始广域网下行。
|
||||
|
||||

|
||||
|
||||
测试设备:树莓派4B
|
||||
|
||||
我们再来看看斐讯N1的表现。N1的网卡没有硬件流控功能,所以可能会引起问题,而软件流控损失性能。在运行flippy的固件安装脚本时,会问你选择是否用`*-thresh.dtb`开启软件流控,默认不采用。
|
||||
|
||||
我们来实测一下。N1有一个USB2.0接口,接上网卡,对网速进行物理封印!便于观察网关是否真的不影响下行流量。
|
||||
|
||||

|
||||
|
||||
斐讯N1+USB2.0网卡,物理封印网速
|
||||
|
||||
我在另一台电脑上不停地iperf3占满N1的网络带宽,同时在旁路网关的客户端电脑上测速。
|
||||
|
||||

|
||||
|
||||
测试设备:斐讯N1+USB2.0网卡
|
||||
|
||||
神奇的事情发生了!网关并没有完全在围观,它的iperf3传输速度显然受到了影响。但客户端并没有受到影响,测速显然已经突破USB2.0的速率限制了。
|
||||
|
||||
结论:
|
||||
|
||||
- 广域网下行流量速率不受旁路网关性能的影响
|
||||
- N1在关闭软件流控时,因为没有硬件流控功能,所以可能会被局域网中的其它流量干扰。会有一定影响自身性能,但不影响局域网其它设备的性能。作为旁路网关,在这一点上,树莓派完胜。
|
||||
|
||||
### 2\. 广域网上行流量
|
||||
|
||||
主路由和旁路网关同时在转发流量。
|
||||
|
||||

|
||||
|
||||
测试设备:树莓派4B(下面的仪表盘)
|
||||
|
||||
### 3\. 代理转发流量
|
||||
|
||||

|
||||
|
||||
我使用的是 Xray VLESS XTLS
|
||||
|
||||
只测试下行就好,上行肯定会经过旁路网关的。
|
||||
|
||||

|
||||
|
||||
测试设备:树莓派4B(下面的仪表盘)
|
||||
|
||||
看这个测试结果,难道说,代理转发的下行流量并不需要经过旁路网关的转发吗?想想并不可能啊。
|
||||
|
||||
换fast.com再试试……可以发现,代理转发流量经过了N1。
|
||||
|
||||

|
||||
|
||||
测试设备:N1
|
||||
|
||||
所以破案了!原来speedtest.net不知为何并没有经过代理,不要相信它!所以不要用它做代理速度测试了,可能是不准的。
|
||||
|
||||
至此,通过实践证实了以下结论:
|
||||
|
||||
优劣对比
|
||||
|
||||
主路由模式
|
||||
|
||||
旁路网关模式
|
||||
|
||||
局域网流量
|
||||
|
||||
不影响性能
|
||||
|
||||
不影响性能
|
||||
|
||||
广域网下行流量
|
||||
|
||||
受限于主路由NAT转发性能
|
||||
|
||||
受限于主路由NAT转发性能
|
||||
|
||||
广域网上行流量
|
||||
|
||||
受限于主路由NAT转发性能
|
||||
|
||||
同时受限于主路由和旁路网关NAT转发性能
|
||||
|
||||
代理上网转发流量
|
||||
|
||||
外加受限于主路由CPU性能
|
||||
|
||||
同时受限于主路由和旁路网关NAT转发性能,外加旁路网关CPU性能
|
||||
|
||||
最后,可以有理有据地得出如何选择旁路网关的结论:
|
||||
|
||||
1. 旁路网关的网卡带宽只要不低于你的上传带宽,就不会对普通流量造成瓶颈。考虑到国内的上行带宽通常非常小,所以基本不会造成影响
|
||||
2. 旁路网关作为代理上网的转发网关,性能下限是由其CPU性能和网卡带宽中最低的部分决定的
|
||||
|
||||
所以旁路网关的性能,并不那么重要。忽悠你买高性能旁路网关的,肯定是奸商。
|
||||
|
||||
但旁路网关无法负责NAT部分的功能,如果你需要多WAN、IPTV等功能,还是需要一个功能灵活的主路由。但如果你仅仅只是为了转发代理上网流量,实现透明代理,那么旁路网关是个非常经济、简单的选择。
|
||||
|
||||
好了,以上就是我这些年来玩 Openwrt 作为家庭网络的路由系统的终极经验了。
|
||||
|
||||
工作桌面纪念照:
|
||||
|
||||

|
||||
|
||||
[原文](https://sspai.com/link?target=https%3A%2F%2Fblog.lishun.me%2Fopenwrt-mega-post)发布在我的博客上。
|
||||
@@ -0,0 +1,130 @@
|
||||
---
|
||||
page-title: "Prerequisites | Tauri Apps"
|
||||
url: https://tauri.app/v1/guides/getting-started/prerequisites
|
||||
date: "2023-03-23 10:38:20"
|
||||
---
|
||||
## Prerequisites
|
||||
|
||||
## Installing[](https://tauri.app/v1/guides/getting-started/prerequisites#installing "Direct link to Installing")
|
||||
|
||||
The first step is to install [Rust](https://www.rust-lang.org/) and system dependencies. Keep in mind that this setup is only needed for *developing Tauri apps*. Your end-users are not required to do any of this.
|
||||
|
||||
### Setting Up Windows[](https://tauri.app/v1/guides/getting-started/prerequisites#setting-up-windows "Direct link to Setting Up Windows")
|
||||
|
||||
#### 1\. Microsoft Visual Studio C++ Build Tools[](https://tauri.app/v1/guides/getting-started/prerequisites#1-microsoft-visual-studio-c-build-tools "Direct link to 1. Microsoft Visual Studio C++ Build Tools")
|
||||
|
||||
You will need to install Microsoft Visual Studio C++ build tools. The easiest way is to install [Build Tools for Visual Studio 2022](https://visualstudio.microsoft.com/visual-cpp-build-tools/). When asked which workloads to install, ensure "C++ build tools" and the Windows 10 SDK are selected.
|
||||
|
||||
|
||||
|
||||
Listing 1-1: Selecting "C++ build tools" and "Windows 10 SDK" using the Visual Studio Build Tools 2022 installer.
|
||||
|
||||
#### 2\. WebView2[](https://tauri.app/v1/guides/getting-started/prerequisites#2-webview2 "Direct link to 2. WebView2")
|
||||
|
||||
note
|
||||
|
||||
On Windows 10 (Version 1803 and later with all updates applied) and Windows 11, the Webview2 runtime is distributed as part of the operating system.
|
||||
|
||||
Tauri heavily depends on WebView2 to render web content on Windows, therefore you must have WebView2 installed. The easiest way is to download and run the Evergreen Bootstrapper from [Microsoft's website](https://developer.microsoft.com/en-us/microsoft-edge/webview2/#download-section).
|
||||
|
||||
The bootstrapper script will try to determine the correct architecture and version for your system. Still, if you run into issues (especially with Windows on ARM) you can select the correct standalone installer.
|
||||
|
||||
#### 3\. Rust[](https://tauri.app/v1/guides/getting-started/prerequisites#3-rust "Direct link to 3. Rust")
|
||||
|
||||
Lastly, go to [https://www.rust-lang.org/tools/install](https://www.rust-lang.org/tools/install) to install `rustup` (the Rust installer). Note that you have to restart your terminal, and in some cases, Windows itself, for the changes to take effect.
|
||||
|
||||
Alternatively, you could use `winget` to install rustup using the following command in PowerShell:
|
||||
|
||||
```
|
||||
winget install --id Rustlang.Rustup
|
||||
```
|
||||
|
||||
MSVC toolchain as default
|
||||
|
||||
For full support for Tauri and tools like [`trunk`](https://trunkrs.dev/) make sure the MSVC Rust toolchain is the selected `default host triple` in the installer dialog. Depending on your system it should be either `x86_64-pc-windows-msvc`, `i686-pc-windows-msvc`, or `aarch64-pc-windows-msvc`.
|
||||
|
||||
If you already have Rust installed, you can make sure the correct toolchain is installed by running this command:
|
||||
|
||||
```
|
||||
rustup default stable-msvc
|
||||
```
|
||||
|
||||
### Setting Up macOS[](https://tauri.app/v1/guides/getting-started/prerequisites#setting-up-macos "Direct link to Setting Up macOS")
|
||||
|
||||
#### 1\. CLang and macOS Development Dependencies[](https://tauri.app/v1/guides/getting-started/prerequisites#1-clang-and-macos-development-dependencies "Direct link to 1. CLang and macOS Development Dependencies")
|
||||
|
||||
You will need to install CLang and macOS development dependencies. To do this, run the following command in your terminal:
|
||||
|
||||
#### 2\. Rust[](https://tauri.app/v1/guides/getting-started/prerequisites#2-rust "Direct link to 2. Rust")
|
||||
|
||||
To install Rust on macOS, open a terminal and enter the following command:
|
||||
|
||||
```
|
||||
curl --proto '=https' --tlsv1.2 https://sh.rustup.rs -sSf | sh
|
||||
```
|
||||
|
||||
note
|
||||
|
||||
We have audited this bash script, and it does what it says it is supposed to do. Nevertheless, before blindly curl-bashing a script, it is always wise to look at it first. Here is the file as a plain script: [rustup.sh](https://sh.rustup.rs/)
|
||||
|
||||
The command downloads a script and starts the installation of the `rustup` tool, which installs the latest stable version of Rust. You might be prompted for your password. If the installation was successful, the following line will appear:
|
||||
|
||||
```
|
||||
Rust is installed now. Great!
|
||||
```
|
||||
|
||||
Make sure to restart your terminal for the changes to take effect.
|
||||
|
||||
### Setting Up Linux[](https://tauri.app/v1/guides/getting-started/prerequisites#setting-up-linux "Direct link to Setting Up Linux")
|
||||
|
||||
#### 1\. System Dependencies[](https://tauri.app/v1/guides/getting-started/prerequisites#1-system-dependencies "Direct link to 1. System Dependencies")
|
||||
|
||||
You will need to install a couple of system dependencies, such as a C compiler and `webkit2gtk`. Below are commands for a few popular distributions:
|
||||
|
||||
- Debian
|
||||
- Arch
|
||||
- Fedora
|
||||
- openSUSE
|
||||
- NixOS
|
||||
|
||||
```
|
||||
sudo apt updatesudo apt install libwebkit2gtk-4.0-dev \ build-essential \ curl \ wget \ libssl-dev \ libgtk-3-dev \ libayatana-appindicator3-dev \ librsvg2-dev
|
||||
```
|
||||
|
||||
#### 2\. Rust[](https://tauri.app/v1/guides/getting-started/prerequisites#2-rust-1 "Direct link to 2. Rust")
|
||||
|
||||
To install Rust on Linux, open a terminal and enter the following command:
|
||||
|
||||
```
|
||||
curl --proto '=https' --tlsv1.2 https://sh.rustup.rs -sSf | sh
|
||||
```
|
||||
|
||||
note
|
||||
|
||||
We have audited this bash script, and it does what it says it is supposed to do. Nevertheless, before blindly curl-bashing a script, it is always wise to look at it first. Here is the file as a plain script: [rustup.sh](https://sh.rustup.rs/)
|
||||
|
||||
The command downloads a script and starts the installation of the `rustup` tool, which installs the latest stable version of Rust. You might be prompted for your password. If the installation was successful, the following line will appear:
|
||||
|
||||
```
|
||||
Rust is installed now. Great!
|
||||
```
|
||||
|
||||
Make sure to restart your Terminal for the changes to take effect.
|
||||
|
||||
## Managing The Rust Installation[](https://tauri.app/v1/guides/getting-started/prerequisites#managing-the-rust-installation "Direct link to Managing The Rust Installation")
|
||||
|
||||
You should keep your Rust version up to date whenever possible to always benefit from the latest improvements. To update Rust, open a terminal and run the following command:
|
||||
|
||||
`rustup` can also be used to uninstall Rust from your machine fully:
|
||||
|
||||
## Troubleshooting[](https://tauri.app/v1/guides/getting-started/prerequisites#troubleshooting "Direct link to Troubleshooting")
|
||||
|
||||
To check whether you have Rust installed correctly, open a shell and enter this command:
|
||||
|
||||
You should see the version number, commit hash, and commit date for the latest stable version that has been released in the following format:
|
||||
|
||||
```
|
||||
rustc x.y.z (abcabcabc yyyy-mm-dd)
|
||||
```
|
||||
|
||||
If you don't see this information, your Rust installation might be broken. Please consult [Rust's Troubleshooting Section](https://doc.rust-lang.org/book/ch01-01-installation.html#troubleshooting) on how to fix this. If your problems persist, you can get help from the official [Tauri Discord](https://discord.com/invite/tauri) and [GitHub Discussions](https://github.com/tauri-apps/tauri/discussions).
|
||||
@@ -0,0 +1,87 @@
|
||||
---
|
||||
page-title: "Run an OpenWRT VM on Proxmox VE"
|
||||
url: https://i12bretro.github.io/tutorials/0405.html
|
||||
date: "2023-03-27 23:56:45"
|
||||
---
|
||||
## What is OpenWRT?
|
||||
|
||||
> OpenWrt is an open-source project for embedded operating systems based on Linux, primarily used on embedded devices to route network traffic. The main components are Linux, util-linux, musl, and BusyBox. All components have been optimized to be small enough to fit into the limited storage and memory available in home routers. *-[https://en.wikipedia.org/wiki/OpenWrt](https://en.wikipedia.org/wiki/OpenWrt)*
|
||||
|
||||
## Creating the VM
|
||||
|
||||
1. Open a web browser and navigate to the ProxMox web UI https://ProxMoxDNSorIP:8006/
|
||||
2. Click the Create VM button at the top right
|
||||
3. On the General tab, name the VM OpenWRT and set a VM ID (123 in this example) > click Next
|
||||
4. On the OS tab select Do not use any media and set the Guest OS Type to Linux and Version to 5.x - 2.6 Kernel > click Next
|
||||
5. On the System tab click Next
|
||||
6. On the Hard Disk tab set the Disk size to 0.001 > click Next
|
||||
7. On the CPU tab set the number of CPU cores and the Type to host > click Next
|
||||
8. On the Memory tab set the amount of memory to 256 MiB > click Next
|
||||
9. On the Network tab set the Model field to VirtIO (paravirtualized), Uncheck the Firewall box > click Next
|
||||
10. On the Confirm tab review the settings and click Finish
|
||||
11. Select the newly created OpenWRT VM from the left navigation panel
|
||||
12. Select Hardware from the left sub-navigation menu
|
||||
13. Click the Hard Disk to select it
|
||||
14. Click the Detach button at the top of the main content window to detach the hard disk from the VM
|
||||
15. Click the Unused disk to select it
|
||||
16. Click the Remove button at the top of the main content window to permanently delete it
|
||||
17. Click the Add button > Network Device
|
||||
18. Set the Model field to VirtIO (paravirtualized), Uncheck the Firewall box > Click Add
|
||||
|
||||
## Setting Up the OpenWRT Disk
|
||||
|
||||
1. Select the Proxmox node name in the left navigation menu
|
||||
2. Click Shell in the left sub-navigation
|
||||
3. Run the following commands in the terminal
|
||||
|
||||
```bash
|
||||
\# lookup the latest stable version number
|
||||
regex='<strong>Current Stable Release - OpenWrt (\[^/\]\*)<\\/strong>' && response=$(curl -s https://openwrt.org) && \[\[ $response =~ $regex \]\] && stableVersion="${BASH\_REMATCH\[1\]}"
|
||||
\# download openwrt image
|
||||
wget -O openwrt.img.gz https://downloads.openwrt.org/releases/$stableVersion/targets/x86/64/openwrt-$stableVersion-x86-64-generic-ext4-combined.img.gz
|
||||
\# extract the openwrt img
|
||||
gunzip ./openwrt.img.gz
|
||||
\# rename the extracted img
|
||||
mv ./openwrt\*.img ./openwrt.raw
|
||||
\# increase the raw disk to 512 MB
|
||||
qemu-img resize -f raw ./openwrt.raw 512M
|
||||
\# import the disk to the openwrt vm
|
||||
\# update the vm id and storage device as needed
|
||||
\# usage: qm importdisk
|
||||
|
||||
|
||||
|
||||
qm importdisk 123 openwrt.raw HDD\_500GB
|
||||
|
||||
```
|
||||
|
||||
4. **Once the disk import completes, select the OpenWRT VM from the left navigation menu > Hardware**
|
||||
5. **Double click the Unused Disk > Click the Add button**
|
||||
6. **Select Options from the left sub-navigation menu**
|
||||
7. **Double click Boot Order**
|
||||
8. **Check the Enabled box next to the hard disk**
|
||||
9. **Drag the Hard disk up in the boot order as needed, typically below the CD-ROM device**
|
||||
10. **Click OK**
|
||||
11. **Double click Use tablet pointer > Uncheck the Enabled box > Click OK**
|
||||
12. **Click the Start button in the top right of the screen**
|
||||
13. **Click the Console link to watch the boot process**
|
||||
14. **Wait for the text to stop scrolling and press Enter**
|
||||
15. **Run the following command to change/set the root password**
|
||||
|
||||
**passwd**
|
||||
|
||||
16. **Type a new root password twice to set it**
|
||||
17. **Continue the configuration by running the following commands**
|
||||
|
||||
**\# set the lan ip address, use something in the same subnet as your LAN
|
||||
**uci set network.lan.ipaddr='10.10.27.151'
|
||||
\# restart network services
|
||||
service network restart
|
||||
\# update openwrt packages
|
||||
opkg update
|
||||
\# install the luci web ui
|
||||
opkg install luci
|
||||
|
||||
18. **Open a new browser tab and navigate to http://IPofVM, http://10.10.27.151 in the example**
|
||||
19. **At the login screen, enter the username root and the password set above > Click the Login button**
|
||||
20. **Enjoy OpenWRT running in Proxmox**
|
||||
+28
@@ -0,0 +1,28 @@
|
||||
---
|
||||
page-title: "SSL with self signed certificate - Drone Support - Harness Community"
|
||||
url: https://community.harness.io/t/ssl-with-self-signed-certificate/11416/3
|
||||
date: "2023-03-30 17:16:40"
|
||||
---
|
||||
|
||||
> Here is my configuration for docker-compose.
|
||||
>
|
||||
> ```
|
||||
> drone-runner:
|
||||
> image: drone/agent:1
|
||||
> restart: always
|
||||
> container_name: drone-runner
|
||||
> volumes:
|
||||
> - /etc/ssl/certs/ca-certificates.crt:/etc/ssl/certs/ca-certificates.crt:ro
|
||||
> - /var/run/docker.sock:/var/run/docker.sock
|
||||
> environment:
|
||||
> - DRONE_RPC_PROTO=https
|
||||
> - DRONE_RPC_HOST=xxx
|
||||
> - DRONE_RPC_SECRET=xxx
|
||||
> - DRONE_RUNNER_CAPACITY=2
|
||||
> - DRONE_RUNNER_VOLUMES=/etc/ssl/certs/ca-certificates.crt:/etc/ssl/certs/ca-certificates.crt
|
||||
> ```
|
||||
>
|
||||
> It mounts the ca-certificates.crt file from the host into the runner and from there into the pipeline containers.
|
||||
|
||||
---
|
||||
|
||||
@@ -0,0 +1,54 @@
|
||||
---
|
||||
page-title: "Scope and Shadowing - Rust By Example"
|
||||
url: https://doc.rust-lang.org/rust-by-example/variable_bindings/scope.html
|
||||
date: "2023-03-23 13:59:16"
|
||||
---
|
||||
## [Scope and Shadowing](https://doc.rust-lang.org/rust-by-example/variable_bindings/scope.html#scope-and-shadowing)
|
||||
|
||||
Variable bindings have a scope, and are constrained to live in a *block*. A block is a collection of statements enclosed by braces `{}`.
|
||||
|
||||
``` rust
|
||||
fn main() {
|
||||
// This binding lives in the main function
|
||||
let long_lived_binding = 1;
|
||||
|
||||
// This is a block, and has a smaller scope than the main function
|
||||
{
|
||||
// This binding only exists in this block
|
||||
let short_lived_binding = 2;
|
||||
|
||||
println!("inner short: {}", short_lived_binding);
|
||||
}
|
||||
// End of the block
|
||||
|
||||
// Error! `short_lived_binding` doesn't exist in this scope
|
||||
println!("outer short: {}", short_lived_binding);
|
||||
// FIXME ^ Comment out this line
|
||||
|
||||
println!("outer long: {}", long_lived_binding);
|
||||
}
|
||||
```
|
||||
|
||||
Also, [variable shadowing](https://en.wikipedia.org/wiki/Variable_shadowing) is allowed.
|
||||
|
||||
``` rust
|
||||
fn main() {
|
||||
let shadowed_binding = 1;
|
||||
|
||||
{
|
||||
println!("before being shadowed: {}", shadowed_binding);
|
||||
|
||||
// This binding *shadows* the outer one
|
||||
let shadowed_binding = "abc";
|
||||
|
||||
println!("shadowed in inner block: {}", shadowed_binding);
|
||||
}
|
||||
println!("outside inner block: {}", shadowed_binding);
|
||||
|
||||
// This binding *shadows* the previous binding
|
||||
let shadowed_binding = 2;
|
||||
println!("shadowed in outer block: {}", shadowed_binding);
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
@@ -0,0 +1,77 @@
|
||||
---
|
||||
page-title: "The ultimate guide to SBOMs | GitLab"
|
||||
url: https://about.gitlab.com/blog/2022/10/25/the-ultimate-guide-to-sboms/
|
||||
date: "2023-03-23 17:32:13"
|
||||
---
|
||||
|
||||
|
||||
Modern software development is marked by a commitment to application security – not just for code developed in-house, but for the [entirety of the software supply chain](https://about.gitlab.com/blog/2022/08/30/the-ultimate-guide-to-software-supply-chain-security/). However, which upstream dependencies are included in software and the reasons why they are required can be difficult to determine. A software bill of materials, or SBOM, sheds light on an application’s contents and code origins, and, when paired with vulnerability management tools, can help identify vulnerabilities and highlight risk for subsequent mitigation. This guide will explain what SBOMs are, their importance in a multi-faceted [DevSecOps](https://about.gitlab.com/topics/devsecops/) strategy, their relationship to vulnerability management, and how to assess and improve an application’s SBOM health.
|
||||
|
||||
An SBOM is a nested inventory or [list of ingredients that make up software components](https://www.cisa.gov/sbom#). In addition to the components themselves, SBOMs include critical information about the libraries, tools, and processes used to develop, build, and deploy a software artifact.
|
||||
|
||||
The SBOM concept has existed [for more than a decade](https://spdx.dev/about/). However, a [2021 Executive Order from the Biden Administration](https://www.whitehouse.gov/briefing-room/presidential-actions/2021/05/12/executive-order-on-improving-the-nations-cybersecurity/) aimed at improving the nation’s cybersecurity made the term synonymous with software supply chain security and boosted its profile. The U.S. government has [issued mandates](https://about.gitlab.com/blog/2022/03/29/comply-with-nist-secure-supply-chain-framework-with-gitlab/) that require application developers selling to the public sector to include SBOMs with their software packages. The private sector is likely not far behind, sending SBOMs on the path to ubiquity.
|
||||
|
||||
Although SBOMs are often created with stand-alone software, platform companies like GitLab are integrating SBOM generation early and deep in the DevSecOps workflow.
|
||||
|
||||
|
||||
|
||||
Modern software development is laser-focused on delivering applications at a faster pace and in a more efficient manner. This can lead to developers incorporating code from open source repositories or proprietary packages into their applications.
|
||||
|
||||
Pulling in code from unknown repositories increases the potential for vulnerabilities that can be exploited by hackers. In fact, the [2020 SolarWinds attack](https://www.techtarget.com/whatis/feature/SolarWinds-hack-explained-Everything-you-need-to-know) was sparked by the activation of a malicious injection of code in a package used by SolarWinds’ Orion product. Customers across the software supply chain were significantly impacted. Other attacks, including the log4j vulnerability that impacted a number of commercial software vendors, cemented the need for a deep dive into application dependencies, including containers and infrastructure, to be able to assess risk throughout the software supply chain.
|
||||
|
||||
There is also a cost component to finding and remediating security vulnerability that levels up the need for SBOMs, as well as damage to a company’s reputation a software supply chain attack can incur.
|
||||
|
||||
> Test your software supply chain security know-how with our quick quiz!
|
||||
|
||||
## Types of SBOM data exchange standards[](https://about.gitlab.com/blog/2022/10/25/the-ultimate-guide-to-sboms/#types-of-sbom-data-exchange-standards)
|
||||
|
||||
SBOMs work best when their generation and interpretation of information such as name, version, packager, and more are able to be automated. This happens best if all parties use a standard data exchange format.
|
||||
|
||||
There are three main types of SBOM data exchange standards in use today:
|
||||
|
||||
- OWASP [CycloneDX](https://cyclonedx.org/capabilities/sbom/)
|
||||
- Software Identification Tagging, or [SWID](https://csrc.nist.gov/projects/Software-Identification-SWID)
|
||||
- [SPDX](https://spdx.dev/)
|
||||
|
||||
GitLab uses CycloneDX for its SBOM generation because the standard is prescriptive and user-friendly, can simplify complex relationships, and is extensible to support specialized and future use cases. In addition, [cyclonedx-cli](https://github.com/CycloneDX/cyclonedx-cli#convert-command) is an open source tool that can be used to convert CycloneDX files to SPDX if necessary.
|
||||
|
||||
## Benefits of pairing SBOMs and software vulnerability management[](https://about.gitlab.com/blog/2022/10/25/the-ultimate-guide-to-sboms/#benefits-of-pairing-sboms-and-software-vulnerability-management)
|
||||
|
||||
SBOMs are highly beneficial for DevOps teams and software consumers.
|
||||
|
||||
- They enable a standard approach to understanding what is in an application and why.
|
||||
- They provide ongoing visibility into the history of an application’s creation, including details about third-party code origins and host repositories.
|
||||
- The details that SBOMs offer enable a DevOps team to identify vulnerabilities, assess the risk, and then mitigate them.
|
||||
- SBOMs can deliver the transparency that application purchasers now demand.
|
||||
|
||||
## GitLab and SBOMs[](https://about.gitlab.com/blog/2022/10/25/the-ultimate-guide-to-sboms/#gitlab-and-sboms)
|
||||
|
||||
For SBOMs to be fully impactful, organizations must be able to automatically generate them, connect them with application security scanning tools, integrate the vulnerabilities and licenses into a dashboard for easy comprehension and actionability, and update them continuously. GitLab supports all of these goals.
|
||||
|
||||
Users can find [SBOM capability](https://about.gitlab.com/blog/2022/10/17/fast-and-efficient-sbom-with-gitlab-and-rezilion/) in the Govern Stage under the [Dependency List page](https://docs.gitlab.com/ee/user/application_security/dependency_list/). The GitLab DevSecOps platform is comprehensive as it provides Dependency SBOM and Container SBOM insights.
|
||||
|
||||
GitLab’s SBOM function enables DevOps teams to scan containers to find operating system, container, and package vulnerabilities in the pipeline and in production. GitLab provides auto-suggested remediations so dev and ops professionals can easily find and fix vulnerabilities. Users can create a vulnerability allow list to reduce noise. The results of the scans, including detected application and language dependencies as well as associated licenses, feed into the dependency list and can be exported. Scan results also can be viewed in GitLab’s [Security Center](https://docs.gitlab.com/ee/user/application_security/security_dashboard/) and in Merge Requests.
|
||||
|
||||
Developers are able to perform scans early and often in the build, test, and deploy process. From there, they can either dismiss vulnerabilities and add audit trail notes or triage them and then track the remediations with commits. This tight integration ensures that SBOMs can be an integral part of release verification processes.
|
||||
|
||||
GitLab also has integrated vulnerability training into the platform so that when vulnerabilities are encountered, developers and security teams can understand the CVEs in context and how to fix them. The platform also supports creation of new policies (and compliance enforcement) based on newly detected vulnerabilities.
|
||||
|
||||
DevOps teams who require compliance functionality (ex. [SLSA 2 framework](https://about.gitlab.com/releases/2022/06/22/gitlab-15-1-released/)) can use GitLab to [generate attestation for all build artifacts](https://about.gitlab.com/blog/2022/08/10/securing-the-software-supply-chain-through-automated-attestation/) produced by the GitLab Runner. The process is secure because it is produced by the Runner itself with no handoff of data to an external service.
|
||||
|
||||
There is no doubt that as software supply chain security garners more attention, SBOMs will be a focus as well. And although the SBOM industry is evolving quickly, there are still concerns around how SBOMs are generated, the frequency of that generation, where they are stored, how to combine multiple SBOMs for complex applications, how to analyze them, and how to leverage them for application health.
|
||||
|
||||
GitLab has made SBOMs an integral part of its [software supply chain direction](https://about.gitlab.com/direction/supply-chain/#overview) and continues to improve upon its SBOM capabilities within the DevSecOps platform, including planning new features and functionality. For instance, GitLab currently plans to have the Runner automate attestation. Also, to reduce the need for users to manage and store their own signing keys, GitLab currently plans to support code signature generation via a short-lived key.
|
||||
|
||||
GitLab is expected to soon feature automatic digital signing of build artifacts. Additionally GitLab anticipates supporting the [ingestion of externally generated SBOMs](https://gitlab.com/groups/gitlab-org/-/epics/8024).
|
||||
|
||||
The demand for SBOMs is already high. Government agencies increasingly recommend or require SBOM creation for software vendors, federal software developers, and even open source communities. To get ahead of this requirement, check out the SBOM capabilities in [GitLab’s DevSecOps platform](https://gitlab.com/-/trials/new).
|
||||
|
||||
**Disclaimer This blog contains information related to upcoming products, features, and functionality. It is important to note that the information in this blog post is for informational purposes only. Please do not rely on this information for purchasing or planning purposes. As with all projects, the items mentioned in this blog and linked pages are subject to change or delay. The development, release, and timing of any products, features, or functionality remain at the sole discretion of GitLab.**
|
||||
|
||||
[
|
||||
|
||||
“Need to get up to speed on SBOMs quickly? We've got you covered with our comprehensive guide” – Sandra Gittlen
|
||||
|
||||
Click to tweet
|
||||
|
||||
](http://twitter.com/share?text=%E2%80%9CNeed+to+get+up+to+speed+on+SBOMs+quickly%3F+We%27ve+got+you+covered+with+our+comprehensive+guide%E2%80%9D+%E2%80%93+%40sandragwrites&url=https://about.gitlab.com/blog/2022/10/25/the-ultimate-guide-to-sboms/)
|
||||
@@ -0,0 +1,824 @@
|
||||
---
|
||||
page-title: "honven - 机场推荐"
|
||||
url: https://sites.google.com/view/honven/%E9%A6%96%E9%A1%B5/%E6%9C%BA%E5%9C%BA%E6%8E%A8%E8%8D%90
|
||||
date: "2023-03-15 10:18:52"
|
||||
---
|
||||
## 付费机场推荐/SSR-v2ray专线机场评测(2023.3.14更新)
|
||||
|
||||
|
||||
|
||||
tag:机场推荐,付费机场,专线机场,SS机场,SSR机场,V2ray机场,trojan机场,科学上网,翻墙机场
|
||||
|
||||
[Telegram机场观察频道](https://t.me/jichangtj): 最新科学上网相关新闻,最新机场推荐、机场评测 、最新机场优惠通知,可查看下面的机场最新高清测速原图
|
||||
|
||||
|
||||
|
||||
1.机场就一句话:一分钱一分货! 机场推荐是信息差,不了解的人很容易被坑被推荐很垃圾的机场。下面推荐的机场老板肉身都是在墙外的,相对安全,跑路概率相对较小。
|
||||
|
||||
2.机场看的就是线路质量。机场总体线路质量:华为云BGP多入口IEPL内网专线\>普通入口IEPL内网专线>普通公网中转比如广东移动、湖南联通。专线主要是不过墙。速度要看机场的总带宽大小,稳定要看机场的资源质量,解锁看的是机场主的落地/解锁商是否优秀。在保证能流畅看视频前提下,稳定性最重要,然后才是追求更高的速度。一分钱一分货,VPS和线路成本注定了既要稳定又要流量多还要便宜是不可能滴。总体越贵越好,有预算尽量选择有内网专线和BGP入口的,延迟和使用体验都会好很多。
|
||||
|
||||
3.尽量买开了比较久的大机场,因为跑路概率较小。小机场可能便宜,但是分分钟跑路。开机场主要看钞能力,大机场比较有钱,买好的线路和加带宽,小机场很可能没钱运营下去。当然,大机场也会跑(其中出名的跑路大机场,比如当年高贵的rixcloud机场、便宜搞传销式的布丁机场,无限流量的喵帕斯机场、AAEX机场,还有在Youtube打广告的速蛙云,体验优秀的YoYu机场...),但是大机场跑路概率比小机场要小,一般大机场用户多,机场主不搞了还可以转卖让人接盘。
|
||||
|
||||
4.稳定与协议没有关系,对于用户来说协议不是最重要的,线路才是。SS、SSR、V2ray、Trojan都行,总体而言SS协议的延迟相对较低。被识别了目前只是封IP/端口,损失的是机场主,用户换一条线路即可。专线也需要看同时使用人数,几百人挤同一条小水管不如几个人的中转,甚至不如直连。评价机场好坏标准之一:维护是否快,出问题老板是否快速修复,机场主常年不在线,修复节点慢的也别买。
|
||||
|
||||
5.看入口,入口和用户本地网络之间的相性决定了用户使用机场的上限和下限。中转很重要,因为一旦中转挂了中转线路就没办法转发流量到落地机了。所以入口机器的数目很重要,最好买BGP多入口的,华为云BGP入口会好很多。而且现在GFW都喜欢搞中转机,包括反向墙和污染中转机的域名。
|
||||
|
||||
6.备用很重要!没有一直稳定的机场,就算是以稳出名的也有不稳的时候,因此如果你是重度翻墙用户当主用出问题时就需要备用,否则主用出问题就直接失联了。买2-3个稳定的比买一堆便宜的垃圾好,买多了放着浪费。备用不用相同入口,买了IEPL专线可以买普通中转或者直连机场备用(直连主要是晚高峰速度不行,且容易被封IP),也可以买按量付费的套餐/年付小流量套餐备用,不用不花钱。
|
||||
|
||||
7.游戏、语音、BT需要线路支持UDP。其实不太建议用机场线路打游戏,最好是使用UU加速器这种专业的,但是有些用户觉得专线机场延迟低也可以打,还可以少花一个买加速器的钱,具体自测。
|
||||
|
||||
8.机场主最好是在境外的,肉身在墙内的机场主自己都不确定自己能做多久。别买QQ机场,下面都是电报频道里的机场,相对透明,且竞争大,同样线路价格更低。可以翻翻Telegram群的历史消息,如果很糟糕肯定有很多其它用户吐槽的。对于测速图:需要看测试的运营商,带宽,测速的地点。测速图好看不代表好用,但是测速非常不好看基本不好用。测速图可以一时好看,但是需要保存长时好看才比较难。本博客机场都是长时间观察的,有历史过去几个月甚至一两年的测速结果,经历过一次次GFW的考验。
|
||||
|
||||
9\. 别一下买太长时间。被跑路了机场坑过的都懂。谁也不知道这机场能运行多久,啥时候跑路。如果出了永久套餐,说明机场主准备收割最后一波跑路了。别看单价流量多就觉得值,1块1T不好用也是浪费钱。
|
||||
|
||||
10.需要看奈飞的 ,目前封锁比较严重。基本一时能看一时不能,除非找老板定制个人线路。注意机场的倍率,2倍率就是用1M流量会算2M流量。机场基本都是有审计的,比如是BT下载、邮件端口和政治敏感网站(主要是轮系媒体)。
|
||||
|
||||
都是我踩过的坑总结而来的,不要再重蹈我的覆辙了。转载请注明本博客链接,抄袭我或者洗稿的要点脸,谢谢。
|
||||
|
||||

|
||||
|
||||
华为云BGP入口IEPL专线机场,原GaCloud,香港老板,已有机场行业多年经验。自己开发的面板。自有机房。速度不错,且稳定性也很不错,适合求稳定的用户。也是本人主用之一。华为云广州入口,隧道至香港的CN2 出口。有按量付费可备用。有分组:B、C和H组,香港往其他地区路由:B组为运营商BGP路由 ;H组为AWS骨干网 ;C组为基于H组更高优先级。人数不一样,精品人少,碎片负载会更少。如果有新产品或者遇到波动,会优先给精品接入更贵的产品以及优化。稳定性不错。会员赠送一张7天奈飞会员体验卡。 官网(通过这个链接注册新用户全员无门槛8折优惠券,只能用一次。目前每充值一百可以抽奖,还有75折优惠)
|
||||
|
||||
[WgetCloud官网1](https://bit.ly/3Ik4FJV) [Wgetcloud官网2](https://invite.wgetcloud.ltd/auth/register?code=n7z3)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2021
|
||||
|
||||
- 老板肉身:香港
|
||||
|
||||
- 入口ip数量:华为云BGP入口,2 (深圳和上海)
|
||||
|
||||
- 过境:IEPL内网
|
||||
|
||||
- 落地ip数量: 59
|
||||
|
||||
- 协议:Shadowsocks+ShadowsocksR +Trojan+Vmess
|
||||
|
||||
- UDP: 不支持
|
||||
|
||||
- 客户端数目:3
|
||||
|
||||
- 付款方式:支付宝、微信、USDT
|
||||
|
||||
- 专门客服:有
|
||||
|
||||
- 一键客户端 : 有
|
||||
|
||||
- 节点国家与地区:香港、日本、新加坡、美国、台湾、加拿大、俄罗斯、韩国、印尼、印度、土耳其、巴西、德国、泰国、澳洲、英国、荷兰、菲律宾、马来西亚
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/%E9%98%BF%E9%87%8C%E4%BA%91ss%E7%BA%BF%E8%B7%AF%E6%9C%BA%E5%9C%BA%E6%8E%A8%E8%8D%90GaCloud.html)
|
||||
|
||||
|
||||
套餐:
|
||||
按量付费和自定义套餐选项:可当备用。1.2元/G 。自己自由搭配合适的套餐、流量、设备数目, 通用的机场面板无这功能。有按量付费,即使你不买这家的套餐,也应该买个按量付费当作备用,以防买的那家出问题失联。有些机场是需要代理才能打开的,失联或者忘记续费你就无办法续费了,死循环。
|
||||
|
||||
- 基础: 无国际专线,节点数:15 ;49/月 120G流量;180G,147块/季度;240G/月,588/年;无SLA保证
|
||||
|
||||
- 优质: BGP线路,节点数:15 ;120G,59块/月;180G,177块/季度;240G/月,708/年
|
||||
|
||||
- 精品: BGP线路,双程CN2线路,节点数:29;120G,69块/月;180G/月,207块/季;240G/月,828/年
|
||||
|
||||
|
||||
如图为精品套餐测速图晚高峰测速,南方电信1000M参考测速
|
||||
|
||||

|
||||
|
||||
华为BGP入口IEPL专线SS协议机场,包括广港、沪日、京德,稳定性高延迟低,值得推荐!已经观察两年。
|
||||
|
||||
南部(港台新澳)走广州华为云入口,过境广港专线;东部节点(日韩美、南美)走上海华为云入口,过境沪日专线,北部节点( 欧洲)过境京德专线,京德比较少见,对北方用户友好,延迟明显会低很多。
|
||||
|
||||
特色:流媒体解锁和落地,有大量冷门节点,全球92+国家地区 220+条线路,各地家宽IP、原生ip。老板很认真挑选落地节点,基本都是原生(解锁各种流媒体)并且带宽大的才用,非常适合各类流媒体爱好者。老板人挺好,基本都在群里回答问题。机场主在香港。不买他家套餐,也推荐买140一年的流量包可做备用。家宽适合拿来注册账号之类的。
|
||||
|
||||
[官网链接1](https://bit.ly/3YghbhY) [官网2(如果打不开请切换为全局代理)](https://suo.yt/IVgyODg)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2018
|
||||
|
||||
- 老板肉身:香港
|
||||
|
||||
- 入口:华为云广州、上海、北京
|
||||
|
||||
- 过境:广港、沪日、京德内网专线(有京德对北方用户友好)
|
||||
|
||||
- 协议:Shadowsocks
|
||||
|
||||
- [网络监控](http://system.tagvpn.xyz/)
|
||||
|
||||
- UDP: 大多数支持Full Cone
|
||||
|
||||
- 客户端数目:10
|
||||
|
||||
- 付款方式:支付宝、虚拟币
|
||||
|
||||
- [TG频道](https://t.me/tagnotif)
|
||||
|
||||
- 专门客服:有
|
||||
|
||||
- [流媒体解锁情况](https://node.tagvpn.xyz/)
|
||||
|
||||
- 落地:92+个国家,220+条线路,节点国家与地区非常多。家宽地区为:香港、澳门、台湾、新加坡、日本、马来西亚、越南、加拿大、美国
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/tag%E6%B5%8B%E9%80%9F%E6%95%B4%E5%90%88.html) 可查看过去两年的高清测速图
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- 个人Bronze | 250G/月 |160块/季
|
||||
|
||||
- 个人Silver | 500G/月 |90块/月
|
||||
|
||||
- 个人190Gold | 999G/月 |190块/月
|
||||
|
||||
- 特选套餐 | 200G/年 |140块/年,不买月付套餐推荐买这个做备用,适合轻量用户,有效期一年
|
||||
|
||||
- 团队套餐 |3000G/月 |570块/每月
|
||||
|
||||
|
||||

|
||||
|
||||
IEPL内网专线与公网中转ss机场,稳定性也不错。 [官网链接1](https://bit.ly/3Sfrkd7) [官网链接2](https://suo.yt/tC69nKu)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2018
|
||||
|
||||
- 老板肉身:墙外
|
||||
|
||||
- 入口与过境线路:IEPL内网(深圳移动)+公网中转(湖南联通)
|
||||
|
||||
- 协议:Shadowsocks
|
||||
|
||||
- UDP:支持
|
||||
|
||||
- 付款方式:支付宝、微信
|
||||
|
||||
- TG频道:[雲翼公告板](https://t.me/joinchat/TCGYbvTuuOMjjTke)
|
||||
|
||||
- 一键客户端 : 有
|
||||
|
||||
- 地区:俄罗斯、印度、土耳其、巴基斯坦、巴西泰国、澳洲、菲律宾、阿根廷、韩国、香港、台湾、新加坡、日本、美国、英国
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/%E4%B8%93%E7%BA%BFss%E6%9C%BA%E5%9C%BA%E6%8E%A8%E8%8D%90%E4%B9%8B%E4%BA%91%E7%BF%BC%E7%BD%91%E7%BB%9C%E5%8E%86%E5%8F%B2%E6%B5%8B%E9%80%9F%E7%BB%93%E6%9E%9C.html)
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- 试用:1块1天5G
|
||||
|
||||
- 标准:22.8/月108G流量,4设备
|
||||
|
||||
- 高级:32.8/月198G流量,4设备
|
||||
|
||||
- 终极:89.8/月520G流量,10设备
|
||||
|
||||
- 全年648G:188/年,3设备
|
||||
|
||||
- 全年1398G:328/年,4设备
|
||||
|
||||
- 全年3288G:688/年,6设备
|
||||
|
||||
|
||||

|
||||
|
||||
IEPL专线,SSR + V2RAY协议机场,有按量付费,老板在香港。推荐旗舰套餐起。高级节点可以用低级节点,需要去面板选择。
|
||||
|
||||
[STC官网1](https://bit.ly/3tJPGBS) [STC官网2](https://suo.yt/msGOhsW)(如果打不开请切换为全局代理)
|
||||
|
||||
|
||||
|
||||
- 老板肉身:香港
|
||||
|
||||
- 开业时长:2020年前
|
||||
|
||||
- 过境:IEPL专线
|
||||
|
||||
- 协议:SSR + Vmess
|
||||
|
||||
- UDP:部分支持Full Cone
|
||||
|
||||
- 入口ip数量:10
|
||||
|
||||
- 付款方式:支付宝
|
||||
|
||||
- 一键使用客户端: 有
|
||||
|
||||
- 落地ip数量: 32+
|
||||
|
||||
- 节点国家与地区:香港、日本、新加坡、美国、台湾
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/stc%E5%8E%86%E5%8F%B2%E6%B5%8B%E9%80%9F%E7%BB%93%E6%9E%9C%E6%95%B4%E5%90%88.html)
|
||||
|
||||
|
||||
套餐:(按人民币算)
|
||||
|
||||
- 按量付费:0.8块/G。有效期一年。不用了可以退回余额。按量套餐适合做备用。只有基础和进阶线路。
|
||||
|
||||
- 基础套餐,中转线路,线路38条:
|
||||
|
||||
|
||||
100G/月,38块/月;200G/月,108块/季度;300G/月量,205/半年;500G/月,385块/年。2/3个在 线客户端。
|
||||
|
||||
- 进阶套餐,更多中转线路,线路38+13条:
|
||||
|
||||
|
||||
100G/月,48块/月;300G/月,136块/季度;400G/月,258/半年;600G/月:488块/年。3/4个在线客户端。
|
||||
|
||||
- 旗舰: 中转线路+专线线路,线路38+13+7条:推荐旗舰套餐起。
|
||||
|
||||
|
||||
100G/月,88块/月;400G/月,251块/季度;500G/月,475/半年;800G/月:898块/年。4/5个在 线客户端。
|
||||
|
||||
- 企业套餐:中转线路+更多专线线路,线路38+13+7+4条:
|
||||
|
||||
|
||||
100G/月,108块/月;500G/月,308块/季度;600G/月,583/半年;900G/月:1100块/年 。5/6 个在线客户端
|
||||
|
||||
默认订阅的是所在等级的线路,可以去官网“节点”改为自定义线路。移动测得比电信差,移动用户可能需要先试用看看。
|
||||
|
||||

|
||||
|
||||
某老机场分站。ss协议,入口是深圳移动。延迟比较低,速度也不错。注册可免费试用。[老猫云官网1](http://bit.ly/3LoD6Rr) [老猫云官网2](https://suo.yt/PrI9z90)
|
||||
|
||||
|
||||
|
||||
- 开业时间:主站是2017年开的,分站2年+
|
||||
|
||||
- 过境:IEPL专线
|
||||
|
||||
- 流媒体解锁:参考流媒体解锁图
|
||||
|
||||
- 入口:深圳移动
|
||||
|
||||
- UDP:支持
|
||||
|
||||
- 付款方式:支付宝
|
||||
|
||||
- 落地ip数量:51
|
||||
|
||||
- 协议:ss
|
||||
|
||||
- 专门客服:有
|
||||
|
||||
- 地区:香港、日本、新加坡、美国、台湾、英国、俄罗斯
|
||||
|
||||
- 落地:Nerocloud、FDCSERVERS、Hinet、DEDIPATH
|
||||
|
||||
- [节点监控页面](https://yun.xn--z7xt7y.com/)
|
||||
|
||||
- 试用:有
|
||||
|
||||
- [拓扑结构与流媒体历史测速结果合集](https://jichangpingce.com/%E8%80%81%E7%8C%AB%E4%BA%91%E5%8E%86%E5%8F%B2%E6%B5%8B%E9%80%9F%E7%BB%93%E6%9E%9C%E6%95%B4%E5%90%88.html)
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- D套餐: 30/月, 每月200G
|
||||
|
||||
- E套餐: 40/月, 每月300G
|
||||
|
||||
- F套餐: 50/月, 每月500G
|
||||
|
||||
|
||||

|
||||
|
||||
IEPL内网专线SS+Vmess机场,老机场,CDN优选入口,智能接入。也有海外用户节点(就是给国外的人用的)。
|
||||
|
||||
套餐不限同时在线客户端数。注册需要先购买。[kycloud官网1](https://bit.ly/3JfUa9s)
|
||||
|
||||
[kycloud官网2](https://suo.yt/7DkNI5r)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2017年
|
||||
|
||||
- 老板肉身:海外
|
||||
|
||||
- 入口 :CDN优选入口,智能接入。江苏电信和移动、河北电信、广东移动和电信
|
||||
|
||||
- 过境: IEPL内网专线
|
||||
|
||||
- 协议:Shadowsocks + Vmess
|
||||
|
||||
- 付款方式:支付宝、虚拟币USDT
|
||||
|
||||
- UDP:基本支持Full-Cone NAT
|
||||
|
||||
- TG频道和群组:在套餐内
|
||||
|
||||
- 客户端数目:不限制
|
||||
|
||||
- 流媒体解锁:TVB/Netflix/BBC/AbemaTV/DMM/hulu(us/jp)/Disney+ Paravi/rakutenTV(jp) 等
|
||||
|
||||
- 落地ip数量: 60+
|
||||
|
||||
- 节点国家与地区:香港、台湾、韩国、日本、新加坡、美国、英国、巴西、德国、阿根廷、土耳其、阿根廷、印度、马来西亚、泰国、菲律宾、俄罗斯
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/IEPL%E4%B8%93%E7%BA%BF%E6%9C%BA%E5%9C%BAkycloud%E5%8E%86%E5%8F%B2%E6%B5%8B%E9%80%9F%E7%BB%93%E6%9E%9C%E6%95%B4%E5%90%88.html)
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- Mini: 每月10G,年付150,可以做备用,适合轻量用户
|
||||
|
||||
- Basic:每月50G,季付75
|
||||
|
||||
- Basic:每月50G,季付75
|
||||
|
||||
- Silver:每月100G,月付30
|
||||
|
||||
- Platinum:每月200G,月付40
|
||||
|
||||
- Ultimate 1 :150/季度每月300G流量;年费498元
|
||||
|
||||
- Ultimate 2 :210/季度每月500G流量;年费698元
|
||||
|
||||
- Team 1 :369/季度每月1T流量
|
||||
|
||||
- Team 2 :609/季度每月2T流量
|
||||
|
||||
|
||||

|
||||
|
||||
全公网中转SS机场,比较低调。机场主在菲律宾。解锁也不错。
|
||||
|
||||
新用户首次95折优惠码:SPECIAL
|
||||
|
||||
[RelayCloud官网1](https://bit.ly/3TNkBaz) [RelayCloud官网2](https://relaycloud.pro/auth/register?code=YqVfn)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2020
|
||||
|
||||
- 老板肉身:菲律宾
|
||||
|
||||
- 入口ip数量:6,河南移动、江苏移动等
|
||||
|
||||
- 过境:公网中转
|
||||
|
||||
- 协议:Shadowsocks
|
||||
|
||||
- UDP: 支持
|
||||
|
||||
- 客户端数目:3+
|
||||
|
||||
- 付款方式:支付宝、微信
|
||||
|
||||
- TG频道:[RelayCloud Notice](https://t.me/joinchat/AAAAAFfR7-mbeYbPP8XH5w) 群组在套餐内
|
||||
|
||||
- 退款:有,3天无理由退款(仅虚拟货币)
|
||||
|
||||
- 落地:节点数量44个,美国、台湾、新加坡、日本、香港、英国、俄罗斯、菲律宾
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/relaycloud%E5%8E%86%E5%8F%B2%E6%B5%8B%E9%80%9F%E7%BB%93%E6%9E%9C%E6%95%B4%E5%90%88.html)
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- 月付80GB,80G/月,19块/月,3个客户端
|
||||
|
||||
- 月付10GB ,180G/月,26.8块/月,3
|
||||
|
||||
- 月付380GB, 380G/月,56.8块/月,5
|
||||
|
||||
- 年付600GB, 600G/年,148.8块/年,3
|
||||
|
||||
- 年付1200GB,1200G/年,218.8块/月,3
|
||||
|
||||
- 年付2400GB,2400G/年,398.8块/月,3
|
||||
|
||||
|
||||

|
||||
|
||||
vmess,深港内网专线机场。高性价比冷门节点机场。最便宜5块/25G流量起。
|
||||
|
||||
有两个特色:
|
||||
|
||||
1.主要是有多个回国节点:北京、上海 、河南郑州、山东青岛 、安徽合肥、广东深圳。白名单,常用国内流媒体使用。5、10倍率。需要购买英文名称套餐 才有:“This 200G Monthly Plan is for Foreign Customers Outside China”,放这家主要是因为有回国的机场很少。回国节点只能在境外使用,国内无法使用,且显示Ping Timeout超时是正常的,其实是能用的。
|
||||
|
||||
2.落地国家和节点多,130+国家,200+节点。且很多是低倍率。“权宜”套餐以上才有。
|
||||
|
||||
因为走南部的深港,所以到香港、澳门、新加坡、台湾等南部的地区速度才较好。加钱世界触手可及,等老板有钱再加沪日和沪美吧。
|
||||
|
||||
[EdNovas云官网链接1](https://suo.yt/h2luF8x) [EdNovas云官网链接2](https://bit.ly/3DcTK0o)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2020年12月
|
||||
|
||||
- 老板肉身:加拿大
|
||||
|
||||
- 过境:深港专线
|
||||
|
||||
- 回国线路:有,上白名单
|
||||
|
||||
- 协议:Vmess
|
||||
|
||||
- UDP : 支持
|
||||
|
||||
- 一键使用客户端:有, [安卓客户端下载地址](https://ednovas.dev/ednovas_cloud.apk)
|
||||
|
||||
- 在线设备数: 5
|
||||
|
||||
- 付款方式:支付宝、虚拟币
|
||||
|
||||
- TG频道: [EdNovas云](https://t.me/ednovasyun1)
|
||||
|
||||
- [服务器探针](https://tz.ednovas.me/)
|
||||
|
||||
- 节点数目:220+
|
||||
|
||||
- [审计规则,屏蔽的网站](https://github.com/EdNovas/rulelist/blob/main/rulelist)
|
||||
|
||||
- 退款:有
|
||||
|
||||
- 落地国家: 130+,[目前机场节点覆盖图](https://lab.magiconch.com/world-ex/)
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/%E5%9B%9E%E5%9B%BD%E6%9C%BA%E5%9C%BAEDCloud%E5%8E%86%E5%8F%B2%E6%B5%8B%E9%80%9F%E7%BB%93%E6%9E%9C%E6%95%B4%E5%90%88.html)
|
||||
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
ss协议,入口是镇江移动,过境深港专线。比主站人少。速度不错。 之前更换了老板。 2022年更换过老板,新老板旗下不少机场。
|
||||
|
||||
[Catnet官网链接1](https://suo.yt/jdJQOsC) [Catnet官网链接2,需要代理](https://bit.ly/3ubwf54)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2021年之前梦迪家分站
|
||||
|
||||
- 过境:深港专线
|
||||
|
||||
- 流媒体解锁:youtube Premium、HBO Max 、Abema TV 、 DAZN、PCR jP、
|
||||
|
||||
- 入口:镇江移动
|
||||
|
||||
- UDP:支持
|
||||
|
||||
- 付款方式:支付宝
|
||||
|
||||
- TG频道: [Catnet\_CN](https://t.me/catnet_official)
|
||||
|
||||
- 落地ip数量:48
|
||||
|
||||
- 协议:ss
|
||||
|
||||
- 专门客服:有
|
||||
|
||||
- 地区:香港、日本、新加坡、美国、台湾、德国、荷兰、印度、英国、加拿大、澳大利亚
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/catnet%E5%8E%86%E5%8F%B2%E6%B5%8B%E9%80%9F%E7%BB%93%E6%9E%9C%E6%95%B4%E5%90%88.html)
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- Small:25/月, 半年付120,每月80G,可3个在线设备,限速250Mbps
|
||||
|
||||
- Meduim:50/月,半年付135, 每月300G;可3个在线设备,限速750Mbps
|
||||
|
||||
|
||||

|
||||
|
||||
3年老机场了。Vmess+Trojan中转线路机场。线路是G口湖南联通和广州移动。机场主在东南亚。注册可以试用。[大哥云官网链接1](https://bit.ly/3Lk1Mu9)
|
||||
|
||||
[大哥云官网链接2](https://suo.yt/bXSbOkn)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2020
|
||||
|
||||
- 老板肉身:东南亚
|
||||
|
||||
- 过境:公网中转
|
||||
|
||||
- 协议:Vmess+Trojan
|
||||
|
||||
- UDP:支持
|
||||
|
||||
- 付款方式:支付宝、微信
|
||||
|
||||
- 一键使用客户端: 有
|
||||
|
||||
- 节点数目:46
|
||||
|
||||
- 落地:日本、香港、韩国、新加坡、菲律宾、泰国、菲律宾、越南、美国、台湾、英国、印度
|
||||
|
||||
- 试用:有, 一天10G
|
||||
|
||||
- 拓扑结构检测和流媒体、历史测速结果合集
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- 单月套餐A:19.8/月100G
|
||||
|
||||
- 单月套餐B:29.8/月150G
|
||||
|
||||
- vip1小流量年付15GB: 88/年,15G/月
|
||||
|
||||
- 季付套餐A 200GB: 69/季,200G/月
|
||||
|
||||
- 季付套餐B 300GB: 129/季,300G/月
|
||||
|
||||
- 年付套餐A 300GB: 199/年,300G/月
|
||||
|
||||
- 年付套餐B 500GB: 299/年,500G/月
|
||||
|
||||
|
||||

|
||||
|
||||
ss协议公网+IEPL专线机场。稳定性不错。比较低调。后端有负载均衡,均衡负载策略会先通过'国内服务器'转发到'多台境外隧道服务器',再转发到'实际落地服务器。 [少数派官网](http://bit.ly/3ZjtNGd)1 [少数派官网链接2](https://sspcloud.net/#/register?code=hK1bzVm2)
|
||||
|
||||
记得提前续费或者买个按量备用,避免过期了登录不上续费。
|
||||
|
||||
|
||||
|
||||
- 开业时间:2019
|
||||
|
||||
- 老板肉身:墙外
|
||||
|
||||
- 过境:公网中转+IEPL内网专线
|
||||
|
||||
- TG频道: [少数派的广而告之](https://t.me/joinchat/Rw92xD_F57WssTZj)
|
||||
|
||||
- 协议:Shadowsocks
|
||||
|
||||
- UDP:支持
|
||||
|
||||
- 付款方式:支付宝、微信、虚拟币
|
||||
|
||||
- 一键使用客户端: 有
|
||||
|
||||
- 节点数目:50+
|
||||
|
||||
- 落地:美国、台湾、新加坡、日本、香港、德国、英国、俄罗斯、菲律宾
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/%E5%B0%91%E6%95%B0%E6%B4%BE%E5%8E%86%E5%8F%B2%E6%B5%8B%E9%80%9F%E7%BB%93%E6%9E%9C%E6%95%B4%E5%90%88.html)
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- 每月29块200G流量 3个客户端
|
||||
|
||||
- 每月45块300G流量 3个客户端
|
||||
|
||||
- 每月89块600G流量 10个客户端
|
||||
|
||||
|
||||

|
||||
|
||||
搬瓦工官方的SSR +Vmess机场,加拿大注册公司,正规大公司:线路是IPLC/GIA+CN2。
|
||||
|
||||
相比私人的机场,好处就是安全,无审计,基本不会跑路,信息泄露概率小。IP 被墙自动切换。
|
||||
|
||||
如果是对安全性的重视程度较大的和担心私人机场跑路的用户,有敏感操作的,推荐这家机场。同时,不满意一般可以退款!
|
||||
|
||||
支持paypal和支付宝支付,5.2%折扣循环优惠码:JMS9272283
|
||||
|
||||
[官网注册地址,需要代理或全局模式访问](https://bit.ly/3weANGp)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2018
|
||||
|
||||
- 老板:加拿大大公司
|
||||
|
||||
- 专线: 有
|
||||
|
||||
- 协议:SSR + Vmess
|
||||
|
||||
- 专门客服:有
|
||||
|
||||
- 退款:有
|
||||
|
||||
- 落地:香港、日本、美国
|
||||
|
||||
- 付款方式:支付宝、银联、Paypal
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
1)Just My Socks IPLC HK 100 \*\* EARLY ACCESS:深圳-香港 IPLC 跨境专线。
|
||||
|
||||
v2ray协议,IPLC香港线路。3条线路:
|
||||
|
||||
100G/每月21刀,限速100Mbps,3个设备。
|
||||
|
||||
300G/每月49刀,限速100Mbps,3个设备。
|
||||
|
||||
新出的套餐,搬瓦工还是懂得大家需要什么。对电信联调和移动三网有优化,延迟低。我之前实测是不限速的。适合游戏爱好者。
|
||||
|
||||
ct:适合中国电信;cu:适合中国联通,cm:适合中国移动网络。
|
||||
|
||||
不一定有货,挺抢手的,用了一个月,挺稳的,但是就是比一般机场贵。
|
||||
|
||||
2)Just My Socks Hong Kong 香港节点:
|
||||
|
||||
100流量,34.99美元/月,3个设备。限速100Mbps
|
||||
|
||||
500G流量,149.99美元/月,5个设备.限速500Mbps
|
||||
|
||||
1000G流量,279.99美元/月,无限个设备.限速1000Mbps
|
||||
|
||||
三网直连,电信双向CN2 GIA,移动和联通直连,跟搬瓦工香港机房的线路一样是香港机房的最优线路。速度快、延迟低、线路稳
|
||||
|
||||
3)Just My Socks Tokyo 日本节点:
|
||||
|
||||
100G流量,29.99美元/月,3个设备。限速100Mbps
|
||||
|
||||
500G流量,135.99美元/月,5个设备.限速200Mbps。
|
||||
|
||||
日本东京节点,三网 CN2 GIA 线路。适合电信和联调带宽。移动的没优势。比Just My Socks LA好一点。
|
||||
|
||||
4)Just My Socks HK CMI+NTT Plan 500 :
|
||||
|
||||
8.99刀/月,500GB/月,不限速,5个设备。
|
||||
|
||||
HK CMI是中国移动香港数据中心,走NTT香港中转。中国电信使用CN2 GIA线路,联通电信直连。
|
||||
|
||||
新套餐:电信,早晚速度可以,其他时段速度比较感人(1080P),延迟稳定在80-95ms。非电信网络,速度稳定,延迟在40-60ms左右,500MB宽带以下能跑满,上传速度20Mbps左右。使用移动和联通网络的可以试试,电信不建议。
|
||||
|
||||
5)Just My Socks London 500:6.8刀/月,500GB/月,不限速, 5个设备。ss+v2ray。
|
||||
|
||||
6)Just My Socks LA,洛杉矶节点,(直连线路,因为最便宜,很多人买这个,不推荐,慢,超售):
|
||||
|
||||
500G流量,5.88美元/月,5个设备。限速2.5 Gbps
|
||||
|
||||
1T流量,9.88美元/月,不限设备数。限速5 Gbps
|
||||
|
||||
5T流量,48.99美元/月,不限设备数。限速5 Gbps
|
||||
|
||||
美国洛杉矶 CN2 GT/CN2 GIA
|
||||
|
||||
肯定还是有人想自建,最好购买它家CN2 GIA线路:
|
||||
|
||||
搬瓦工CN2-GIA是目前最稳定的线路之一,三网表现都不错。绝版瓦工套餐价格居高不下,已经成为传家宝,理财产品。
|
||||
|
||||
虽然市面上有很多vps厂商声称有GIA线路,但是搬瓦工比他们中的绝大多数都要好不少。[搬瓦工官网](https://bit.ly/3sDxUwC)
|
||||
|
||||
全IEPL专线传输,支持 SS+SSR++V2ray+Trojan协议机场。推荐给轻量用户。Trojan节点数目比SSR少。
|
||||
|
||||
不限时ip 和设备数目。[官网地址](https://bit.ly/3G9K4Dy)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2021
|
||||
|
||||
- 老板肉身:北美
|
||||
|
||||
- 过境:IEPL内网专线
|
||||
|
||||
- 入口数目:2,广州移动
|
||||
|
||||
- UDP:支持
|
||||
|
||||
- 协议:Shadowsocks+ShadowsocksR +Trojan+Vmess
|
||||
|
||||
- 设备数目:无限制
|
||||
|
||||
- 付款方式:支付宝
|
||||
|
||||
- TG频道:[Hutao公告](https://t.me/joinchat/IsZvZdFDboAzZmEx)
|
||||
|
||||
- 客服:有
|
||||
|
||||
- 落地数目: 28
|
||||
|
||||
- 落地:美国、台湾、新加坡、日本、香港
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/IEPL%E4%B8%8E%E9%9A%A7%E9%81%93ssr%E6%9C%BA%E5%9C%BA%E6%8E%A8%E8%8D%90-hutao.html)
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- mini:12块/月50G起,限速200M
|
||||
|
||||
- Pro:23块/月150G起,不限速
|
||||
|
||||
- Business:34块/月300G起,不限速
|
||||
|
||||
- Enterprise:109块/月1500G起,不限速
|
||||
|
||||
|
||||

|
||||
|
||||
全IEPL内网专线ss机场,人目前比较少,适合想要人少机场的用户。 [Fenda官网1](https://suo.yt/c0CZffc) [Fenda官网2](https://bit.ly/3tOgI9J)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2021
|
||||
|
||||
- 老板肉身:北美
|
||||
|
||||
- 过境:IEPL内网专线
|
||||
|
||||
- 入口ip数量:2
|
||||
|
||||
- 协议:Shadowsocks
|
||||
|
||||
- UDP:支持
|
||||
|
||||
- 付款方式:支付宝、银联
|
||||
|
||||
- 一键使用客户端: 有
|
||||
|
||||
- 落地:美国、台湾、新加坡、日本、香港、韩国
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/ss%E4%B8%AD%E8%BD%AC%E6%9C%BA%E5%9C%BA%E6%8E%A8%E8%8D%90-fenda.html)
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- 基础月付:12.8块/月88G起;3个设备起
|
||||
|
||||
- 进阶月付:22.8块/月188G起;4个设备起
|
||||
|
||||
- 旗舰月付:32.8块/月288G起;6个设备起
|
||||
|
||||
|
||||

|
||||
|
||||
SSR(主要是SSR)+Trojan,全IEPl专线机场。有各个平台小白一键使用客户端。主要是便宜。
|
||||
|
||||
[官网地址1](https://bit.ly/3d3Yqga) [官网2(如果打不开请切换为全局代理)](https://suo.yt/jo4NFtf)
|
||||
|
||||
|
||||
|
||||
- 开业时间:2019
|
||||
|
||||
- 老板肉身:北美
|
||||
|
||||
- 入口ip: 广州、海南
|
||||
|
||||
- 协议:ShadowsocksR +Trojan
|
||||
|
||||
- UDP:支持
|
||||
|
||||
- 付款方式:支付宝、银联
|
||||
|
||||
- 专门客服:有
|
||||
|
||||
- 小白客户端:Windows+Mac+安卓
|
||||
|
||||
- 落地:美国、台湾、新加坡、日本、香港
|
||||
|
||||
- 节点数目:40+
|
||||
|
||||
- [拓扑结构检测和流媒体、过往历史测速合集](https://jichangpingce.com/yiyo%E5%8E%86%E5%8F%B2%E6%B5%8B%E9%80%9F%E7%BB%93%E6%9E%9C%E6%95%B4%E5%90%88.html)
|
||||
|
||||
|
||||
套餐:
|
||||
|
||||
- 每月10块50G流量 2个客户端,随便用用没问题。
|
||||
|
||||
- 每月18块150G流量 3个客户端
|
||||
|
||||
- 每月28块300G流量 5个客户端
|
||||
|
||||
- 每月38块500G流量 6个客户端
|
||||
|
||||
- 每月78块1000G流量 18个客户端
|
||||
|
||||
- 每月98块2000G流量 18个客户端
|
||||
|
||||
|
||||

|
||||
|
||||
以上就是我收集的一些值得推荐的机场了,基本包括了ss、ssr、v2ray、trojan协议,基本全是中转,没有全直连线路机场,老板全在境外(肉身在国内的机场主不干了只是早晚的事,人少直接跑,人多的他会选择把机场卖了),同时开业时间较长,即使出问题老板修复速度也快,跑路概率较小。同时本一直更新测速持续观察,哪家机场表现长时间变差了就会从本文剔除掉,不再推荐。机场几百上千家,我也没要推荐差的机场。从而让新接触机场的新人少花冤枉钱少躺坑,且有良好的翻墙体验。
|
||||
|
||||
最新新闻欢迎关注频道:[科学上网与机场观察](https://t.me/jichangtj)
|
||||
|
||||
其它碎碎念:
|
||||
|
||||
1\. 近期临近国庆和二十大,近期很多机场上游的国内入口机器被查,很多机场不稳。记得搞个备用机场。--20220929。两会期间可能有机场会停止注册,正常现象。(202303)
|
||||
|
||||
2.平时养成更新订阅的好习惯,因为机场节点很多容易更换,更新订阅才能更新新的节点,一般Clash for Windows和QuantumultX都是默认会自动更新的。如果节点出问题了:先检查流量是否用完,是否过期了。正常则再更新节点订阅,不会更新就重新复杂粘贴到代理软件里面。还是有问题,群里或者工单问:说明清楚是哪个节点,你的运营商是哪个,哪个地区。如果是问群友,最好礼貌一点,毕竟群友是义务免费回答别人问题,回答与否看心情的。--202210
|
||||
|
||||
3.注册时收不到验证码,可以去邮箱垃圾箱里面找找。
|
||||
|
||||
4 各平台客户端推荐:
|
||||
|
||||
Windows推荐使用Clash for window / Clash-verge / Netch;
|
||||
|
||||
Mac推荐使用Clash for windows和Clash-verge的Mac版本/ ClashX / 有钱的买Surge;
|
||||
|
||||
IOS推荐小火箭Shadowsocket / QuantumultX / 有钱的买Surge ;
|
||||
|
||||
安卓推荐Surfboard、Matsuri、ClashforAndroid(CFA)、V2rayNG;
|
||||
|
||||
Linux 推荐Clash for windows或Shell clash;
|
||||
|
||||
路由器可以使用OpenClash。具体参考:[各平台代理客户端推荐与教程](https://sites.google.com/view/honven/%E9%A6%96%E9%A1%B5/%E5%90%84%E5%B9%B3%E5%8F%B0%E4%BB%A3%E7%90%86%E5%AE%A2%E6%88%B7%E7%AB%AF%E6%8E%A8%E8%8D%90%E4%B8%8E%E6%95%99%E7%A8%8B?authuser=1)
|
||||
|
||||
5.机场套路:
|
||||
|
||||
新开的贼便宜机场套路:为了吸引客户一开始价格非常便宜,打价格战,很容易吸引大量用户,但是久了人数多了机场主必须要加线路或者提高带宽扩容来保证体验,否则速度必然降低并且不稳定。而扩容又必须要花钱,所以不跑路就会涨价,就是低价吸引一波来割韭菜。
|
||||
|
||||
便宜机场套路2:突然搞活动优惠力度过大,吸引用户。 AFF比例非常高,吸引推广。然后便宜短时间大批人购买涌入很容易拉跨,黑心的直接跑路,典型的小机场捞钱手法。
|
||||
|
||||
便宜机场套路3:线路多,但是复用,就是虽然显示多条线路但入口和落地其实是同一条线路,见过10条线路其实都是一条!不少机场这样搞,看上去线路多,骗子。一挂挂一片。就算没挂,当你觉得某条线路不快,切换线路,切了10条都是同一条。
|
||||
|
||||
便宜机场套路4:月抛机场,卖得也及其便宜。买的都是很便宜的月抛线路,甚至直连不用中转机,省了中转机的钱,所以很便宜。但是线路变化频繁,随时跑路:如果比较多azure/aga/nhn/hinet这些月抛机器,在azure/nhn/hinet等月抛机器风控越来越严重的一个情况下,如果他开不出了新月抛机器,那么他们会承受不了正价机器,因为正价机器的流量根本不够他给用户用的。下面推荐的机场基本没有月抛。这些便宜机场如果要买只建议月付!不管年付多优惠,千万别年付!
|
||||
@@ -0,0 +1,209 @@
|
||||
---
|
||||
page-title: "podman/rootless_tutorial.md at main · containers/podman"
|
||||
url: https://github.com/containers/podman/blob/main/docs/tutorials/rootless_tutorial.md
|
||||
date: "2023-03-31 11:46:31"
|
||||
---
|
||||
[](https://raw.githubusercontent.com/containers/common/main/logos/podman-logo-full-vert.png)
|
||||
|
||||
## Basic Setup and Use of Podman in a Rootless environment.
|
||||
|
||||
Prior to allowing users without root privileges to run Podman, the administrator must install or build Podman and complete the following configurations.
|
||||
|
||||
## cgroup V2 support
|
||||
|
||||
The cgroup V2 Linux kernel feature allows the user to limit the amount of resources a rootless container can use. If the Linux distribution that you are running Podman on is enabled with cgroup V2 then you might need to change the default OCI Runtime. Some older versions of `runc` do not work with cgroup V2, you might have to switch to the alternative OCI runtime `crun`.
|
||||
|
||||
The alternative OCI runtime support for cgroup V2 can also be turned on at the command line by using the `--runtime` option:
|
||||
|
||||
or for all commands by changing the value for the "Default OCI runtime" in the `containers.conf` file either at the system level or at the [user level](https://github.com/containers/podman/blob/main/docs/tutorials/rootless_tutorial.md#user-configuration-files) from `runtime = "runc"` to `runtime = "crun"`.
|
||||
|
||||
## Administrator Actions
|
||||
|
||||
### Installing Podman
|
||||
|
||||
For installing Podman, please see the [installation instructions](https://podman.io/getting-started/installation).
|
||||
|
||||
### Building Podman
|
||||
|
||||
For building Podman, please see the [build instructions](https://podman.io/getting-started/installation#building-from-scratch).
|
||||
|
||||
### Install `slirp4netns`
|
||||
|
||||
The [slirp4netns](https://github.com/rootless-containers/slirp4netns) package provides user-mode networking for unprivileged network namespaces and must be installed on the machine in order for Podman to run in a rootless environment. The package is available on most Linux distributions via their package distribution software such as `yum`, `dnf`, `apt`, `zypper`, etc. If the package is not available, you can build and install `slirp4netns` from [GitHub](https://github.com/rootless-containers/slirp4netns).
|
||||
|
||||
### Ensure `fuse-overlayfs` is installed
|
||||
|
||||
When using Podman in a rootless environment, it is recommended to use `fuse-overlayfs` rather than the VFS file system. For that you need the `fuse-overlayfs` executable available in `$PATH`.
|
||||
|
||||
Your distribution might already provide it in the `fuse-overlayfs` package, but be aware that you need at least version **0.7.6**. This especially needs to be checked on Ubuntu distributions as `fuse-overlayfs` is not generally installed by default and the 0.7.6 version is not available natively on Ubuntu releases prior to **20.04**.
|
||||
|
||||
The `fuse-overlayfs` project is available from [GitHub](https://github.com/containers/fuse-overlayfs), and provides instructions for easily building a static `fuse-overlayfs` executable.
|
||||
|
||||
If Podman is used before `fuse-overlayfs` is installed, it may be necessary to adjust the `storage.conf` file (see "User Configuration Files" below) to change the `driver` option under `[storage]` to `"overlay"` and point the `mount_program` option in `[storage.options.overlay]` to the path of the `fuse-overlayfs` executable:
|
||||
|
||||
```
|
||||
[storage]
|
||||
driver = "overlay"
|
||||
|
||||
(...)
|
||||
|
||||
[storage.options.overlay]
|
||||
|
||||
(...)
|
||||
|
||||
mount_program = "/usr/bin/fuse-overlayfs"
|
||||
```
|
||||
|
||||
### Enable user namespaces (on RHEL7 machines)
|
||||
|
||||
The number of user namespaces that are allowed on the system is specified in the file `/proc/sys/user/max_user_namespaces`. On most Linux platforms this is preset by default and no adjustment is necessary. However, on RHEL7 machines, a user with root privileges may need to set that to a reasonable value by using this command: `sysctl user.max_user_namespaces=15000`.
|
||||
|
||||
### `/etc/subuid` and `/etc/subgid` configuration
|
||||
|
||||
Rootless Podman requires the user running it to have a range of UIDs listed in the files `/etc/subuid` and `/etc/subgid`. The `shadow-utils` or `newuid` package provides these files on different distributions and they must be installed on the system. Root privileges are required to add or update entries within these files. The following is a summary from the [How does rootless Podman work?](https://opensource.com/article/19/2/how-does-rootless-podman-work) article by Dan Walsh on [opensource.com](https://opensource.com/)
|
||||
|
||||
For each user that will be allowed to create containers, update `/etc/subuid` and `/etc/subgid` for the user with fields that look like the following. Note that the values for each user must be unique. If there is overlap, there is a potential for a user to use another user's namespace and they could corrupt it.
|
||||
|
||||
```
|
||||
cat /etc/subuid
|
||||
johndoe:100000:65536
|
||||
test:165536:65536
|
||||
```
|
||||
|
||||
The format of this file is `USERNAME:UID:RANGE`
|
||||
|
||||
- username as listed in `/etc/passwd` or in the output of [`getpwent`](https://man7.org/linux/man-pages/man3/getpwent.3.html).
|
||||
- The initial UID allocated for the user.
|
||||
- The size of the range of UIDs allocated for the user.
|
||||
|
||||
This means the user `johndoe` is allocated UIDs 100000-165535 as well as their standard UID in the `/etc/passwd` file. NOTE: this is not currently supported with network installs; these files must be available locally to the host machine. It is not possible to configure this with LDAP or Active Directory.
|
||||
|
||||
If you update either `/etc/subuid` or `/etc/subgid`, you need to stop all the running containers owned by the user and kill the pause process that is running on the system for that user. This can be done automatically by using the [`podman system migrate`](https://github.com/containers/podman/blob/main/docs/source/markdown/podman-system-migrate.1.md) command which will stop all the containers for the user and will kill the pause process.
|
||||
|
||||
Rather than updating the files directly, the `usermod` program can be used to assign UIDs and GIDs to a user.
|
||||
|
||||
```
|
||||
usermod --add-subuids 100000-165535 --add-subgids 100000-165535 johndoe
|
||||
grep johndoe /etc/subuid /etc/subgid
|
||||
/etc/subuid:johndoe:100000:65536
|
||||
/etc/subgid:johndoe:100000:65536
|
||||
```
|
||||
|
||||
### Enable unprivileged `ping`
|
||||
|
||||
Users running in a non-privileged container may not be able to use the `ping` utility from that container.
|
||||
|
||||
If this is required, the administrator must verify that the UID of the user is part of the range in the `/proc/sys/net/ipv4/ping_group_range` file.
|
||||
|
||||
To change its value the administrator can use a call similar to: `sysctl -w "net.ipv4.ping_group_range=0 2000000"`.
|
||||
|
||||
To make the change persist, the administrator will need to add a file with the `.conf` file extension in `/etc/sysctl.d` that contains `net.ipv4.ping_group_range=0 $MAX_GID`, where `$MAX_GID` is the highest assignable GID of the user running the container.
|
||||
|
||||
## User Actions
|
||||
|
||||
The majority of the work necessary to run Podman in a rootless environment is on the shoulders of the machine’s administrator.
|
||||
|
||||
Once the Administrator has completed the setup on the machine and then the configurations for the user in `/etc/subuid` and `/etc/subgid`, the user can just start using any Podman command that they wish.
|
||||
|
||||
### User Configuration Files
|
||||
|
||||
The Podman configuration files for root reside in `/usr/share/containers` with overrides in `/etc/containers`. In the rootless environment they reside in `${XDG_CONFIG_HOME}/containers` (usually `~/.config/containers`) and are owned by each individual user.
|
||||
|
||||
The three main configuration files are [containers.conf](https://github.com/containers/common/blob/main/docs/containers.conf.5.md), [storage.conf](https://github.com/containers/storage/blob/main/docs/containers-storage.conf.5.md) and [registries.conf](https://github.com/containers/image/blob/main/docs/containers-registries.conf.5.md). The user can modify these files as they wish.
|
||||
|
||||
#### containers.conf
|
||||
|
||||
Podman reads
|
||||
|
||||
1. `/usr/share/containers/containers.conf`
|
||||
2. `/etc/containers/containers.conf`
|
||||
3. `$HOME/.config/containers/containers.conf`
|
||||
|
||||
if they exist in that order. Each file can override the previous for particular fields.
|
||||
|
||||
#### storage.conf
|
||||
|
||||
For `storage.conf` the order is
|
||||
|
||||
1. `/etc/containers/storage.conf`
|
||||
2. `$HOME/.config/containers/storage.conf`
|
||||
|
||||
In rootless Podman certain fields in `/etc/containers/storage.conf` are ignored. These fields are:
|
||||
|
||||
```
|
||||
graphroot=""
|
||||
container storage graph dir (default: "/var/lib/containers/storage")
|
||||
Default directory to store all writable content created by container storage programs.
|
||||
|
||||
runroot=""
|
||||
container storage run dir (default: "/run/containers/storage")
|
||||
Default directory to store all temporary writable content created by container storage programs.
|
||||
```
|
||||
|
||||
In rootless Podman these fields default to
|
||||
|
||||
```
|
||||
graphroot="$HOME/.local/share/containers/storage"
|
||||
runroot="$XDG_RUNTIME_DIR/containers"
|
||||
```
|
||||
|
||||
[$XDG\_RUNTIME\_DIR](https://specifications.freedesktop.org/basedir-spec/basedir-spec-latest.html#variables) defaults on most systems to `/run/user/$UID`.
|
||||
|
||||
#### registries
|
||||
|
||||
Registry configuration is read in by this order
|
||||
|
||||
1. `/etc/containers/registries.conf`
|
||||
2. `/etc/containers/registries.d/*`
|
||||
3. `HOME/.config/containers/registries.conf`
|
||||
|
||||
The files in the home directory should be used to configure rootless Podman for personal needs. These files are not created by default. Users can copy the files from `/usr/share/containers` or `/etc/containers` and modify them.
|
||||
|
||||
#### Authorization files
|
||||
|
||||
The default authorization file used by the `podman login` and `podman logout` commands reside in `${XDG_RUNTIME_DIR}/containers/auth.json`.
|
||||
|
||||
### Using volumes
|
||||
|
||||
Rootless Podman is not, and will never be, root; it's not a `setuid` binary, and gains no privileges when it runs. Instead, Podman makes use of a user namespace to shift the UIDs and GIDs of a block of users it is given access to on the host (via the `newuidmap` and `newgidmap` executables) and your own user within the containers that Podman creates.
|
||||
|
||||
If your container runs with the root user, then `root` in the container is actually your user on the host. UID/GID 1 is the first UID/GID specified in your user's mapping in `/etc/subuid` and `/etc/subgid`, etc. If you mount a directory from the host into a container as a rootless user, and create a file in that directory as root in the container, you'll see it's actually owned by your user on the host.
|
||||
|
||||
So, for example,
|
||||
|
||||
```
|
||||
> whoami
|
||||
john
|
||||
|
||||
# a folder which is empty
|
||||
host> ls /home/john/folder
|
||||
host> podman run -v /home/john/folder:/container/volume mycontainer /bin/bash
|
||||
|
||||
# Now I'm in the container
|
||||
root@container> whoami
|
||||
root
|
||||
root@container> touch /container/volume/test
|
||||
root@container> ls -l /container/volume
|
||||
total 0
|
||||
-rw-r--r-- 1 root root 0 May 20 21:47 test
|
||||
root@container> exit
|
||||
|
||||
# I check again
|
||||
host> ls -l /home/john/folder
|
||||
total 0
|
||||
-rw-r--r-- 1 john john 0 May 20 21:47 test
|
||||
```
|
||||
|
||||
We do recognize that this doesn't really match how many people intend to use rootless Podman - they want their UID inside and outside the container to match. Thus, we provide the `--userns=keep-id` flag, which ensures that your user is mapped to its own UID and GID inside the container.
|
||||
|
||||
It is also helpful to distinguish between running Podman as a rootless user, and a container which is built to run rootless. If the container you're trying to run has a `USER` which is not root, then when mounting volumes you **must** use `--userns=keep-id`. This is because the container user would not be able to become `root` and access the mounted volumes.
|
||||
|
||||
Another consideration in regards to volumes:
|
||||
|
||||
- When providing the path of a directory you'd like to bind-mount, the path needs to be provided as an absolute path or a relative path that starts with `.` (a dot), otherwise the string will be interpreted as the name of a named volume.
|
||||
|
||||
## More information
|
||||
|
||||
If you are still experiencing problems running Podman in a rootless environment, please refer to the [Shortcomings of Rootless Podman](https://github.com/containers/podman/blob/main/rootless.md) page which lists known issues and solutions to known issues in this environment.
|
||||
|
||||
For more information on Podman and its subcommands, follow the links on the main [README.md](https://github.com/containers/podman/blob/main/README.md#podman-information-for-developers) page or the [podman.io](https://podman.io/) web site.
|
||||
@@ -0,0 +1,133 @@
|
||||
---
|
||||
page-title: "《软件供应商手册:SBOM的生成和提供》解读 - FreeBuf网络安全行业门户"
|
||||
url: https://m.freebuf.com/articles/neopoints/331333.html
|
||||
date: "2023-03-07 09:30:14"
|
||||
---
|
||||
## 专栏·供应链安全
|
||||
|
||||
数字化时代,软件无处不在。软件如同社会中的“虚拟人”,已经成为支撑社会正常运转的最基本元素之一,软件的安全性问题也正在成为当今社会的根本性、基础性问题。
|
||||
|
||||
随着软件产业的快速发展,软件供应链也越发复杂多元,复杂的软件供应链会引入一系列的安全问题,导致信息系统的整体安全防护难度越来越大。近年来,针对软件供应链的安全攻击事件一直呈快速增长态势,造成的危害也越来越严重。
|
||||
|
||||
为此,我们推出“供应链安全”栏目。本栏目汇聚供应链安全资讯,分析供应链安全风险,提供缓解建议,为供应链安全保驾护航。
|
||||
|
||||
注:以往发布的部分供应链安全相关内容,请见文末“推荐阅读”部分。
|
||||
|
||||
## **摘要**
|
||||
|
||||
本手册由美国国家电信和信息管理局(NTIA)格式化与工具工作组于2021年11月27日发布,旨在为软件供应商提供软件物料清单(SBOM)生成和交付方面的指导。手册以SBOM生成的四步骤流程为主线,重点说明了在软件构建(Build)前、构建中和构建后等各阶段构造SBOM时的特点或应注意事项,以及目前常用的SBOM验证方法。整体流程的完整性和对各阶段应重点关注问题的讨论是本手册的主要亮点。手册可为我国软件生产企业或个人在SBOM生成和构造等方面提供一定的指导和借鉴。
|
||||
|
||||
## **背景解读**
|
||||
|
||||
近年来,全球软件供应链安全攻击事件持续高发,且危害越来越大,特别是2020年底爆发的太阳风(SolarWinds)攻击事件,使得美国更加重视自身的供应链安全防护。2021年5月12日,美总统拜登签署了“关于改善国家网络安全(EO 14028)”的行政命令,其中的第4节针对“加强软件供应链安全”提出了一系列具体要求,旨在迅速改善美国软件供应链的安全性和完整性,而其第(f)条要求,NTIA于同年7月11日前发布SBOM的最低要求。
|
||||
|
||||
对此,NTIA于2021年7月12日发布了《SBOM最小要素》,规定了最小要素应包括数据字段、自动化支持、实践和过程等三个方面,其中的实践和过程指为了将SBOM集成到安全开发生命周期操作中而需定义其请求的操作、生成和使用等内容,包含频率、深度、已知的未知情况(known unknowns)、分发和交付、访问控制和容错等。可以看出,SBOM的生成是将其集成到安全开发生命周期的重要一环。
|
||||
|
||||
11月27日发布的《软件供应商手册:SBOM生成和提供》是对最小要素中SBOM生成的进一步细致讨论和在实施层面的补充,给出了SBOM生成的一般性流程及每一步中应关注的重点。手册中关于SBOM三种数据格式(SPDX、CycloneDX、SWID)和特定名词(如“已知的未知情况”)的规定均与最小要素一脉相承。另外,根据手册中的说明,这里的软件供应商指的是商用软件、开源软件、外包软件等广义的供应商。
|
||||
|
||||
## **正文解读**
|
||||
|
||||
通过对手册内容进行分析,作者归纳出其参考价值和指导作用主要体现在4个方面。
|
||||
|
||||
### **01** **以有效性为最终目标,总结了SBOM生成的工作流程**
|
||||
|
||||
尽管各类组织用来生成SBOM的工具和过程多种多样,但手册归纳出了这一过程的一般性工作流程模型,即通过“识别组件-获取数据-构造SBOM-验证SBOM”4个步骤,最终得到格式有效、属性合规的SBOM文件。
|
||||
|
||||
在上述过程中,每个步骤均有相应的技术、自动化工具、标准等进行辅助和支持,手册介绍了它们中的代表性内容,例如软件组成分析(SCA)工具、代码分析工具、SBOM格式验证工具、软件包数据交换(SPDX)标准、OWASP CycloneDX和软件组件验证(SCVS)标准等。
|
||||
|
||||
总体而言,本手册对于SBOM的构造和生成具有一定的指导作用,可基于其描述的流程、标准和工具等开展相关的研究工作,以增强软件产品透明度,便于进行安全分析和保障。
|
||||
|
||||
### **02** **以构建为阶段划分点,讨论了SBOM构造的主要方法**
|
||||
|
||||
手册描述了在软件构建(Build)之前、构建时和构建以后的不同时间阶段,构造SBOM时可使用的方法工具、应考虑的信息类型、相应的特点和注意事项等内容,如表1所示。
|
||||
|
||||
表1 不同阶段SBOM生成的对比
|
||||
|
||||
**生成阶段**
|
||||
|
||||
**生成方法**
|
||||
|
||||
**特点/注意事项**
|
||||
|
||||
构建前
|
||||
|
||||
作为版本控制系统一部分,或由挖掘产品构建管道输入的工具创建源码级SBOM
|
||||
|
||||
有助于关键组件的识别及在创建产品之前查找漏洞;便于构建到源文件的追溯;可能会呈现并不包含在最终可执行文件中的脆弱源码
|
||||
|
||||
构建时
|
||||
|
||||
作为构建工件自动化生成SBOM
|
||||
|
||||
包含更权威的组件特征、无人工输入错误、自动化SBOM签名;必须确定构建过程中生成的SBOM的格式(列举了SPDX等3种)
|
||||
|
||||
在构建管道或软件工厂中生成SBOM
|
||||
|
||||
构建管道方法容易使用,但可能需要额外的资源集成管道;软件工厂方法可解决多个开发生态系统没有一致SBOM支持的问题
|
||||
|
||||
从容器化过程中导出容器镜像SBOM
|
||||
|
||||
应汇总并识别来自所有层的所有软件的信息;应包括容器间依赖关系、构建时间、签名等
|
||||
|
||||
构建以后
|
||||
|
||||
(SBOM应包括生成时间、SBOM版本、签名等)
|
||||
|
||||
旧系统中使用功能;来自不同的供应商、过程和工具等的SBOM信息的生成
|
||||
|
||||
应补充接近工程过程的组件数据、已知的未知情况等;代码分析工具可扫描上游供应商组件的SBOM,但识别商业组件方面能力不足
|
||||
|
||||
非自动化系统和过程的SBOM生成
|
||||
|
||||
应理解SBOM中列出的组件的来源和软件标识,以及如何获取这些信息
|
||||
|
||||
手册对每个阶段中SBOM生成的特点或应注意方面进行了一些点上的描述,包括举例等方式,多以说明性为主,缺少统一的描述逻辑。尽管如此,通过对表中内容的分析依然可以发现:
|
||||
|
||||
- **收集信息的全面性是SBOM构造的基础。**识别和收集软件组件信息的全面性是首先要考虑的。手册明确了,在构建过程中生成SBOM的,需提前确定格式,即使用标准来规范待收集的内容,并且在构建后还要补充必要的信息(例如无法通过自动化手段得到的)。
|
||||
|
||||
|
||||
- **三个阶段的SBOM生成工作各有侧重。**构建时的自动化信息收集是SBOM生成的主要方式;源码级SBOM可以作为辅助;构建之后阶段对SBOM的构造以信息(特别是来源信息)的补充和集成(多供应商SBOM)为主。
|
||||
|
||||
|
||||
- **自动化工具提高了SBOM构造的效率和可操作性。**手册提到的工具包括:构建前使用的版本控制系统,挖掘构建管道输入的工具;构建时使用的Git,与构建系统、包管理器和持续集成(CI)服务器集成的工具,构建管道和软件工厂;构建后使用的代码分析工具等
|
||||
|
||||
|
||||
### **03** **以安全性为出发点,分析了SBOM应包含的内外依赖**
|
||||
|
||||
为了使运行时依赖关系等引入漏洞的情况不成为消费者和供应商的盲点,手册强调SBOM应避免缺失对应用程序所安装的运行时依赖项、操作系统、动态链接库(DLL)、升级程序、共享库或其他包含项的描述,且描述时应避免存在歧义;另外,为了提高供应商解决相关安全问题的效率,手册明确当软件功能执行依赖于对外部服务调用时,可使用SBOM列出软件交付所需的外部服务。
|
||||
|
||||
内外部依赖关系是应用程序引入安全问题的重要来源之一,手册将应用的内部依赖项和外部依赖的服务作为SBOM的重要组成部分,能够帮助消费者和供应商更全面的了解应用程序,进而掌握可能引入安全问题的途径,及时采取相应缓解措施,这有利于提高软件安全防护的效率和准确性。
|
||||
|
||||
### **04** **以可操作性为目的,列举了SBOM验证的工具和标准**
|
||||
|
||||
针对SPDX、CycloneDX和SWID三种SBOM的格式正确性和完整性的检验,手册列出了相应自动化工具的链接;针对SBOM信息中声明的相关组件的识别、验证和评估等,手册提到了标准OWASP SCVS、OpenChain和软件组成分析(SCA)工具。
|
||||
|
||||
目前SCA工具在识别软件组成、分析软件成分、统计软件资产等方面功能明显,可有效辅助SBOM中声明组件和依赖信息的验证。但SBOM文件自身验证的工具还比较初级,并且都与特定的SBOM格式相绑定。例如手册中提到的SBOM格式验证工具,仅能够对格式的正确性和完整性进行检查,而不能检查填充SBOM字段的数据质量或准确性。相信随着SBOM相关技术的不断发展,未来此类工具的功能也会有较大的提升。
|
||||
|
||||
## **影响及趋势预判**
|
||||
|
||||
美行政令EO 14028虽然对《SBOM最小要素》的制定进行了要求,但并未对它的使用进行强制规定。最小要素和本手册可更多的被看作是对SBOM相关方,特别是美国软件供应商的规范建议。
|
||||
|
||||
但另一方面,随着全球网络信息领域对软件供应链安全、SBOM重要性认知的不断提升,以及SPDX成为国际标准、《SBOM最小要素》的出台等,软件供应企业(如商用软件、外包软件)和个人(如开源软件)会越来越多主动或被动的构造并提供SBOM,本手册可以在这一方面提供流程的规范和指导,具有积极的促进作用。无论美国厂商还是全球厂商都可以从中得到启示,但手册介绍的粒度较粗,供应商应根据自身状况进一步细化后使用。
|
||||
|
||||
SBOM生成的自动化是构造SBOM的最终目标和提高效率的有效手段,但从手册中可以看出,目前一些类型信息的收集还难以做到,例如“已知的未知情况”、遗留系统的相关信息等,并且手册也缺少对这些的详细方法介绍;此外,依赖项漏洞是软件供应链安全风险的主要成因之一,手册中列举了几类需在SBOM中重点关注的内外部依赖关系,但并未展开系统阐述。未来应对这些问题进行进一步的研究,进而为软件供应商提供更加明确的指导。
|
||||
|
||||
## **总结及对策建议**
|
||||
|
||||
手册归纳了SBOM生成的一般工作流程,包括“识别组件-获取数据-构造SBOM-验证SBOM”4个步骤,并以构建为阶段划分点,讨论了SBOM构造的主要方法,还重点分析了SBOM应包含的内外部依赖关系、列举了针对SBOM的验证工具和标准。基于上述情况,本文对我国的SBOM构造工作建议如下:
|
||||
|
||||
- 建议国家或行业监管部门指导制定软件SBOM格式、生成和使用等方面的标准和指南,以规范该项工作;并建立有效的机制推动标准的落地、使用,引导相关自动化辅助工具的研发。
|
||||
|
||||
|
||||
- 建议软件供应商提高安全责任意识,根据已有的SBOM要素、生成、使用等参考资料制定满足自身和使用者需求的SBOM规范,包括但不限于组件供应者、组件名称、组件版本、依赖关系等信息内容,并在软件研发和供应过程中严格执行。
|
||||
|
||||
|
||||
- 建议软件使用者将SBOM列为供应商必须提供的内容,并对其提交的软件产品和SBOM进行验证,以确保两者的对应关系,从而提升软件产品的透明度,提高软件安全维护的效率和使用的安全性。
|
||||
|
||||
|
||||
手册原文可参考:https://www.ntia.gov/files/ntia/publications/software\_suppliers\_sbom\_production\_and\_provision\_-\_final.pdf
|
||||
|
||||
SBOM系列政策文件研究由中国信通院、中国联通联合牵头,筹建单位奇安信、会员单位悬镜安全、绿盟、高伟达、比瓴、盈高科技、亚信、北银金科、孝道科技、南阳理工大学、华为支持开展,包含13篇政策文件的翻译、解读,涵盖了SBOM整体内容概述,SBOM的生成、获取、交换、共享、管理、使用等全生命周期过程,回答了关于SBOM的常见问题,以期助力社区的安全研究研讨,加速推进提升国内供应链的安全管理水平。
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,95 @@
|
||||
---
|
||||
page-title: "什麼是SBOM (軟體物料清單)? - 網路安全解決方案 - 艾索科技"
|
||||
url: https://www.aisol.com.tw/index.php?action=solution&cid=23&id=197
|
||||
date: "2023-03-07 09:20:31"
|
||||
---
|
||||
## **什麼是SBOM(軟體物料清單)?**
|
||||
|
||||
讓我們從基礎開始,當談論到 SBOM 時,我們是什麼意思呢?
|
||||
|
||||
SBOM (全名為 Software Bill of Materials,軟體物料清單) 最初由美國食品和藥物管理局(FDA)於2018年提出,作為醫療器械網路安全管理上市前提交的一部分。然後,它們被稱為網路安全材料清單(CBOM),強調它們對產品安全的重要性。目標是創建構成設備的所有軟體和硬體元件的清單。它使組織能夠有效地管理其資產並充分瞭解所使用軟體的風險。
|
||||
|
||||
## **供應鏈安全和 SBOM**
|
||||
|
||||
隨著軟體供應鏈攻擊的威脅,這使得SBOM成為確保供應鏈安全(Supply Chain Security)的關鍵。
|
||||
|
||||
在過去幾年中,軟體供應鏈攻擊已開始佔據各家媒體頭條。考慮到軟體和供應鏈變得多越來越複雜和多層次,這並不奇怪。今天的互聯設備和產品可以依賴來自多個來源的數十甚至數百個軟體庫:有一些是內部開發的,另一些是從第三方供應商處購買的,並添加到組合中的是開源專案。
|
||||
|
||||
此外,大流行造成的嚴重供應鏈中斷,導致關鍵業務供應鏈短缺。供應鏈延遲和故障促使設備和產品製造商尋找新的和未經審查的供應商,也讓供應鏈風險管理增加了另一個挑戰。
|
||||
|
||||
## **經典案例:SOLARWINDS 和 LOG4SHELL**
|
||||
|
||||
2020年的SolarWinds供應鏈攻擊深入到聯邦政府的基礎設施以及一些最大、最精通技術的組織中,這引發了一個問題,就是我們究竟對每天使用的軟體瞭解多少?我們了解產品和設備的構成基礎嗎?
|
||||
|
||||
另一個發人深省的例子是,第三方和開源元件在我們的軟體和設備中無處不在,這是2021年底在廣受歡迎和無處不在的Log4j開源Java庫中發現的關鍵漏洞。一旦披露,該漏洞就清楚地表明瞭開源元件的固有風險,這些元件是我們軟體產品不可分割的一部分。通過漏洞進行的令人瞠目結舌的漏洞利用嘗試次數 - 在其披露后的幾個小時內,這緊急提醒我們,對我們供應鏈中開源元件的可見性和控制是漏洞管理的關鍵部分。
|
||||
|
||||
如果做得好,SBOM允許我們檢查和監控通過供應鏈收到的元件,並在威脅和漏洞成為頭條新聞之前對其進行管理。
|
||||
|
||||
## **美國拜登總統的網絡安全行政命令 (EO 14028) 使 SBOM 成為必要**
|
||||
|
||||
2021 年 5 月,為了應對日益增加的供應鏈攻擊威脅,例如 SolarWinds 漏洞,拜登總統發布了一項關於改善國家安全的行政命令 (EO 14028)。 EO 14028 呼籲組織和聯邦機構共同努力改善網絡安全。
|
||||
|
||||
這一行動的一部分是建議軟體開發人員向他們的客戶提供 SBOM。 該軟體材料清單包括有關應用程序使用的庫、附加組件和自定義源代碼的信息。
|
||||
|
||||
## **SBOM 使用案例**
|
||||
|
||||
雖然行政命令明確表示我們越來越需要使用SBOM進行監管,但一些公司組織仍然認為法規只是必須忍受的必要邪惡,而不是利用可以提高其安全性和合規性戰略和流程的工具。當持續使用工具時,SBOM 可以幫助產品安全團隊在整個產品生命週期(從開發的最早階段到後期生產)中檢測和降低風險。
|
||||
|
||||
除了作為法規要求,SBOM對於管理軟體供應鏈風險的軟體或數位產品製造商來說也是一種至關重要的做法。在幾個使用範例中,SBOM 提供了它的價值。
|
||||
|
||||
- **符合聯邦要求**
|
||||
|
||||
在拜登總統的行政命令之後,那些向聯邦政府提供軟體的人需要提供SBOM,詳細說明所使用的元件以及版本之間的更改。
|
||||
|
||||
- **降低軟體消費者的風險**
|
||||
|
||||
SBOM 提供對軟體組成的可見性,使組織能夠驗證軟體是否符合其合規性標準和安全要求,並評估風險。這對於高度監管的行業(如醫療保健、關鍵基礎設施供應商/公用事業、汽車和金融)尤為重要。
|
||||
|
||||
- **向左轉移,以更快地將優質產品推向市場**
|
||||
|
||||
設備製造商對其產品有很高的標準,在許多情況下,在生產後進行更改的能力有限。SBOM 允許他們跟蹤上游軟體中的更改,以便在生產早期識別和修復新漏洞,此時修復起來更容易且成本更低。
|
||||
|
||||
- **支援併購**
|
||||
|
||||
在收購新公司時,企業需要在收購前完成盡職調查,調查其投資。此過程的一部分涉及徹底評估購買風險。SBOM 提供對公司在其產品開發中使用的軟體的可見性,從而能夠更準確地評估產品和設備。
|
||||
|
||||
## **數位孿生技術協助建立精準的SBOM**
|
||||
|
||||
艾索科技提供的解決方案是利用網路 Digital Twins 技術,為您提供了大規模開發和維護安全產品的基礎架構,可以統一管理產品生產前的安全評估與產品開發後的安全運營,為您提供在產品的整個生命週期內保護產品所需的可見性、上下文和敏捷性,最重要的是它無需原始程式碼。
|
||||
|
||||
## **艾索科技協助您進行 SBOM (軟體物料清單) 管理**
|
||||
|
||||
艾索科技將協助您獲取整個產品組件的詳細且持續更新的 SBOM,讓OEM及其供應商能夠開發和維護安全產品的每一步。
|
||||
|
||||
我們可以在所有開發計劃中全面瞭解您的軟體組成清單 (SBOM),從而增強問責制和產品安全性。
|
||||
|
||||
- ### **完整的資產可視性**
|
||||
|
||||
|
||||
通過產品的標準化網路Digital Twin,將自動全面了解您的產品組成,包括 SBOM、版本控制、依賴關係、許可證、操作系統配置等等
|
||||
|
||||
- ### **產品組合影響分析**
|
||||
|
||||
|
||||
在產品的開發期間和開發後,自動檢測整個資產清單中的漏洞,並在漏洞被利用之前,我們將建議您如何對其進行修復。
|
||||
|
||||
- ### **清單分析**
|
||||
|
||||
|
||||
按地理位置、營業單位或開發計劃等各種屬性,對資產清單進行切片和切塊,並從資產(元件)向下鑽取到 SBOM 再到漏洞
|
||||
|
||||
- ### **SBOM 到設備的可見性**
|
||||
|
||||
|
||||
與您的 PLM、QMS、ERP 和遠端更新系統無縫集成,將清單可見性從 SBOM 擴展到產品 ID,從而暴露相關風險
|
||||
|
||||
- **端到端的可追溯性**
|
||||
|
||||
查明元件和產品中的漏洞和安全漏洞,並在從設計到後期製作的任何生命周期階段追溯其來源
|
||||
|
||||
****想了解更多關於 產品安全與網路安全 解決方案,歡迎與[艾索科技聯繫](https://www.aisol.com.tw/index.php?action=contact) !****
|
||||
|
||||
**艾索科技股份有限公司 AISOL Technology**
|
||||
|
||||
- 電話:02-2500-6210
|
||||
- 郵件:info@aisol.com.tw
|
||||
@@ -0,0 +1,203 @@
|
||||
---
|
||||
page-title: "关于软件物料清单(SBOM),你所需要了解的一切 - Seal软件 - 博客园"
|
||||
url: https://www.cnblogs.com/sealio/p/16891458.html
|
||||
date: "2023-03-07 09:27:54"
|
||||
---
|
||||
在此前的多篇文章中,我们已经详细地介绍了软件物料清单(SBOM)对于保障软件供应链安全的重要性以及一些注意事项。在本文中,我们将会更深入地介绍SBOM,包括最低要求元素、格式、使用场景以及如何对其进行管理等。
|
||||
|
||||
|
||||
## SBOM所包含的元素
|
||||
|
||||
2021年年中,NTIA发布了软件物料清单(SBOM)的最少必需元素。这些元素包含以下三类:
|
||||
|
||||
- 数据字段:每个软件组件的基本信息
|
||||
|
||||
- 自动化支持:能够自动生成机器可读格式的SBOM
|
||||
|
||||
- 实践和流程:SBOM 应该如何及何时生成和分发
|
||||
|
||||
|
||||
所需元素的目的是为 SBOM 使用者提供他们所需的信息,以管理漏洞、清点软件组件,并监管许可证合规性。
|
||||
|
||||
### 数据字段
|
||||
|
||||
根据NTIA的说法,这一字段是为了“充分识别这些组件以在整个软件供应链中跟踪它们,并将它们映射到其他相关的数据来源,如漏洞数据库或许可证数据库”。
|
||||
|
||||
|
||||
7个必要的数据字段如下:
|
||||
|
||||
- **供应商名称:** 开发该软件组件的个人或组织
|
||||
|
||||
- **组件名称:** 给一组软件命名,通常由供应商决定
|
||||
|
||||
- **组件版本:** 一个标识符,指定软件与以前版本的变化。同样,这是由供应商决定的
|
||||
|
||||
- **其他独特标识符:** 像Software Identification (SWID)标签、Package Uniform Resource Locators (PURL)、Common Platform Enumeration(CPE)或类似的标识符,可以帮助SBOM 消费者在关键数据库中找到组件
|
||||
|
||||
- **依赖项关系:** 表示软件组件是如何结合在一起的,如,某个上游组件包含在某个软件中
|
||||
|
||||
- **SBOM数据的作者:** 生成SBOM元数据的实体,可能是软件供应商或其他个人、团体
|
||||
|
||||
- **时间戳:** SBOM 生成的日期和时间
|
||||
|
||||
|
||||
### 自动化支持
|
||||
|
||||
下一组最低要求元素是指 SBOM 数据在整个软件生态系统内部以及跨组织通信的方式。这一要求的目标是为了确保 SBOM 数据真正可用——不仅仅是机器可读,还能够让人直接阅读,而且它的传输格式是可互操作的。
|
||||
|
||||
|
||||
要达到这一目标,NTIA 认证了3个交付格式来生成和消费 SBOM。至关重要的是,向联邦政府销售软件的组织必须以这三种格式之一传送 SBOM,以符合网络安全行政命令的要求。
|
||||
|
||||
|
||||
这3个格式是:
|
||||
|
||||
- Software Package Data Exchange (SPDX)
|
||||
|
||||
- Software Identification (SWID) Tags
|
||||
|
||||
- CycloneDX
|
||||
|
||||
|
||||
|
||||
在后面一节,我们将会对这3个格式进行详细介绍。
|
||||
|
||||
|
||||
### 实践和流程
|
||||
|
||||
最后一组SBOM最低要求元素涉及生成和申请SBOM的具体操作。具体而言,实践和流程部分包括以下6个方面的要求:
|
||||
|
||||
- **频率(Frequency):** NTIA规定,“如果软件组件随着新的构建或发布而更新”,企业应该生成新的SBOM。此外,供应商在以下情况下也需要生成新的SBOM:
|
||||
1)需要纠正原始版本中的错误
|
||||
2)了解有关软件组件的新细节
|
||||
|
||||
|
||||
- **深度(Depth):** 合规的SBOM需要包含:
|
||||
1)所有顶层组件
|
||||
2)所有间接依赖关系。如果SBOM作者不能包含所有间接依赖关系,则需要囊括足够的信息,使消费者可以递归地找到他们。
|
||||
|
||||
|
||||
- **已知的未知因素(Known Unknowns):** 在SBOM作者没有提供完整的依赖关系图的情况下,他们需要说明这是因为:
|
||||
1)该组件没有进一步的依赖关系,或者
|
||||
2)不知道是否存在其他的依赖关系。
|
||||
|
||||
|
||||
- **分发和交付:** 这一部分分为几个环节,都是关于确保SBOM以可消化的格式快速交付。首先,SBOM被要求以“及时”的方式提供(尽管没有设定天数或周数)。其次,他们必须有“适当的”角色和访问权限。最后,SBOM可以与产品的每个实例一起分发或者以其他可访问的方式提供,如公开的网站。
|
||||
|
||||
|
||||
- **访问控制:** 如果供应商想将SBOM数据的访问限制在某些客户或用户,他们需要提供这种访问控制的条款。此外,供应商需要提供 “具体的允许和便利”,以便SBOM消费者能够将数据纳入其安全工具。
|
||||
|
||||
|
||||
- **容错程度:** 网络安全行政命令和指导SBOM创建的法规目前尚不成熟,因此,各组织被指示要对(无意的)错误或遗漏给予理解。
|
||||
|
||||
|
||||
|
||||
## SBOM交付格式及规范
|
||||
|
||||
企业可以通过各种不同的格式创建和发布软件物料清单(SBOM)。对于一个想要在其网站发布 SBOM 的企业来说,HTML 是一个合理的选择。如果 SBOM 中包含了文档或者源代码,那么纯文本也许是更佳选项。此外,还有 Markdown、PDF、CSV等格式可供使用。
|
||||
|
||||
|
||||
除了这些常见的格式外,还有几种专门为交付SBOM而设计的格式,如 SPDX(软件包数据交换),SWID Tags(软件识别)以及Cyclone DX。
|
||||
|
||||
|
||||
### SPDX
|
||||
|
||||
SPDX是由 Linux 基金会运营的项目,旨在标准化企业共享和使用SBOM中信息的方式。SPDX 捕捉与provenance、许可证和安全相关的数据,下图展示了 SPDX 文档中所包含的数据:
|
||||

|
||||
|
||||
- JSON(你可以在 GitHub 上找到SPDX的JSON schema:[https://github.com/spdx/spdx-spec/tree/development/v2.2.1/schemas)](https://github.com/spdx/spdx-spec/tree/development/v2.2.1/schemas%EF%BC%89)
|
||||
- RDF/XML
|
||||
- tag:value flat text file
|
||||
- .xls 电子表格
|
||||
|
||||
|
||||
Seal 软件供应链防火墙可以直接生成SPDX格式的SBOM文件,欢迎访问下方链接申请产品试用: [seal.io/trail](https://www.cnblogs.com/sealio/p/seal.io/trail)
|
||||
|
||||
|
||||
### SWID Tags
|
||||
|
||||
SWID 是一个标准化的 XML 格式,可以识别软件产品的组成部分并将其与上下文结合。4种类型的 SWID Tags 在软件开发生命周期中:
|
||||
|
||||
- **Corpus Tags:** 识别和描述在安装前阶段的软件成分。根据 NIST 给出的定义,corpus tags 是指“软件安装工具和流程的输入”
|
||||
- **Primary Tags:** 在软件产品安装后对其进行识别和关联
|
||||
- **Patch Tags:** 顾名思义,patch tags 可以识别和描述补丁(而不是核心产品本身)。此外,patch tags 包含了补丁和其他产品或补丁之间的上下文关系信息。
|
||||
- **Supplemental Tags:** SWID 格式仅允许 tag 创建者修改 corpus、primary和patch tags。但是 Supplemental Tags 可以让软件用户及软件管理工具在本地添加有益的上下文信息,如许可证密钥以及相关方的联系信息。
|
||||
|
||||
|
||||
在决定将哪些标签和具体的数据元素纳入其产品时,各企业有一定程度的灵活性。在SWID规范中,除了几个必须的字段外,其他的元素和属性都是可选的。
|
||||
|
||||
|
||||
最终,一个最低限度的有效和符合要求的标签只需要描述软件产品(如名称和标签ID)和创建它的实体的少数元素。关于SWID标签数据元素的最全面和最新的信息,建议查看ISO/IEC 19770-2:2015标准全文:
|
||||
[https://www.iso.org/standard/65666.html](https://www.iso.org/standard/65666.html)
|
||||
|
||||
|
||||
### Cyclone DX
|
||||
|
||||
Cyclone DX 是一个轻量级软件物料清单标准,旨在用于应用安全上下文和供应链组件分析。换言之,它旨在实现与SPDX、SWID以及其他所有SBOM交付格式类似的目标——提供构成一个应用程序的软件组件的关键信息。
|
||||
|
||||
|
||||
Cyclone DX 支持以下4种类型的数据:
|
||||
|
||||
- **物料清单元数据:** 关于应用/产品本身的信息——供应商、制造商、SBOM所面熟的组件以及用于汇编SBOM的任意工具
|
||||
- **组件:** 完整的专利清单及开源组件清单,包含许可信息
|
||||
- **服务信息:** 软件可能调用的外部API、终端URI、身份认证要求和信任名单
|
||||
- **依赖项:** 包含直接依赖项和间接依赖项
|
||||
|
||||
|
||||
## 谁是SBOM的目标受众?
|
||||
|
||||
历史上,SBOM主要由合规团队用来审计、监控许可证以及遵守行业特定规范,但随着软件供应链攻击的上升,包括 SolarWinds 黑客事件和去年年末的 Log4Shell 漏洞,SBOM 的使用扩展到了安全和开发团队。
|
||||
|
||||
### 安全团队
|
||||
|
||||
对于安全团队来说,SBOM扮演着十分重要的角色,特别是需要进行漏洞扫描的时候。因为扫描SBOM库比从头开始扫描整个基础设施更简单也更快,在发生零日事件时,每一分钟都很重要。此外,安全团队也会利用 SBOM 所提供的信息(如风险所在位置)来确定问题修复的优先级,并针对特定组件创建策略,如供应商的选型、可引入的版本或者软件包类型等。
|
||||
|
||||
|
||||
### 开发团队
|
||||
|
||||
开发团队可以使用 SBOM 来跟踪他们所开发、管理和运维的各个软件中的组件,包括开源组件、商业组件和自研组件。并且 SBOM 还能协助开发团队管理依赖项、识别安全问题以减少其重复的工作,还能确保开发人员使用的都是经过审批的代码和可信任的源。
|
||||
|
||||
|
||||
## SBOM 的应用场景
|
||||
|
||||
显然,有许多令人信服的理由推动企业创建SBOM,并且企业可以为所有产品创建SBOM,每个新版本都可以更新一版SBOM。此外,在一些特定场景中SBOM会最大限度地发挥其作用。
|
||||
|
||||
|
||||
- **融资、并购和IPO:** 软件物料清单是收购、IPO或融资过程中技术尽调的重要一环。相关利益方会要求获取文档以更好地了解产品中的软件成分以及许可证合规性、安全性或代码质量风险。
|
||||
- **客户要求:** 由于全球范围内的企业都将防止软件供应链风险的优先级提高了,因此未来会有越来越多的企业要求采购环节中需要提供SBOM。
|
||||
- **向下兼容:** 维护大量旧软件的公司经常需要进行OSS包的更新和升级。当然,如果对这些旧产品中的开放源码软件有一个完整的清单,做起来就容易多了。
|
||||
|
||||
|
||||
## 全面管理 SBOM 的最佳实践
|
||||
|
||||
随着SBOM被迅速接受,行业领导者已经开始开发创建、管理和使用SBOM 的方法。这些实践跨越了软件生命周期的各个关键阶段:
|
||||
|
||||
|
||||
**1、在统一的存储库中存储和管理 SBOM**
|
||||
虽然单个开发或应用团队可以将SBOM与他们的代码构件一起存储在存储库中,但安全团队必须在所有应用和开发团队中维护一个统一的SBOM存储库。当新的漏洞或安全事件出现时,安全团队和CISO需要快速查询所有软件的SBOM并即时评估影响,而不是分别从每个团队中获得单独的评估报告,或者不得不浪费事件从头开始查找和重新扫描他们所有的应用程序。此外,满足监管要求或合规标准也需要一个集中的存储库,用于生成报告和其他的合规活动。
|
||||
|
||||
|
||||
**2、要求所有进入供应链的软件提供SBOM**
|
||||
企业如果需要对所使用的软件保有可见性,那么收集 SBOM 信息以分析软件成分或应用是十分重要的。如果是第三方商业软件,那么软件供应商应该提供必要的 SBOM,并将其纳入你的 SBOM 资源库。
|
||||
|
||||
|
||||
当使用的是开源组件来构建自定义软件时,在将其引入开发流程前企业应该直接扫描开源构件(如容器镜像)或者开源代码仓库。在某些情况下,开源项目可能会提供一个签名的 SBOM,这可以让企业将他们生成的 SBOM 与社区提供的 SBOM 进行比较来进行验证。
|
||||
|
||||
|
||||
**3、为每个开发环节和构建生成SBOM**
|
||||
各行各业的企业正在定制软件以迎合其独特的市场需求。大部分软件都由大量的开源代码组成(根据不同的应用程序,开源代码的占比在50—90%之间)以及内部开发的代码和第三方库。由于在构建阶段开源代码常常会引入额外的依赖项,因此在开发流程中的每一步及每一次构建软件时都扫描您的软件是至关重要的。这可以让您检测出意料之外的SBOM变更,这些变更可能由新依赖项或代码修改导致的。这些 SBOM 需要标记为特殊组件或他们所代表的应用程序。
|
||||
|
||||
|
||||
**4、为你所部署或交付的每个软件版本创建综合的SBOM**
|
||||
无论您是将软件交付给客户,还是帮助客户、员工、合作伙伴进行部署,您应该创建一个综合的SBOM,并标记为该版本软件的变更。这提供了一个追踪机制,可以让企业快速评他们生产的应用或组件的安全状况,同时评估新漏洞对此前开发的影响。对于将软件售卖或提供给外部用户的企业,您也可以提供必要的可见性和“信任报告”给软件的下游用户。
|
||||
|
||||
|
||||
**5、 将自动化应用于策略执行和告警**
|
||||
|
||||
借助中心化的SBOM仓库和有效的SBOM管理能力,企业可以利用一个自动的策略引擎来应用策略规则,如同步特殊的监管要求或合规标准。同时,还可以应用任意内部要求。自动告警可以提醒您新漏洞或违反策略的行为,如此,受影响的团队可以快速修正重要问题并阻止受影响的镜像被部署。
|
||||
|
||||
|
||||
## 借助工具生成SBOM
|
||||
|
||||
可以肯定的是,软件物料清单将在业务开展方式中发挥越来越重要的作用。但是,考虑到制作SBOM所需的数据量,仅通过人工将这些碎片组合在一起是相当具有挑战性的。Seal 软件供应链防火墙可以生成SBOM数据,并可以跟踪SBOM的变化以进行漏洞匹配,及时发现软件供应链中的安全风险。
|
||||
|
||||

|
||||
@@ -0,0 +1,164 @@
|
||||
---
|
||||
page-title: "关于软件物料清单(SBOM),你所需要了解的一切 - 掘金"
|
||||
url: https://juejin.cn/post/7166054417819500580
|
||||
date: "2023-03-23 17:32:57"
|
||||
---
|
||||
在此前的多篇文章中,我们已经详细地介绍了软件物料清单(SBOM)对于保障软件供应链安全的重要性以及一些注意事项。在本文中,我们将会更深入地介绍SBOM,包括最低要求元素、格式、使用场景以及如何对其进行管理等。
|
||||
|
||||
## SBOM所包含的元素
|
||||
|
||||
2021年年中,NTIA发布了软件物料清单(SBOM)的最少必需元素。这些元素包含以下三类:
|
||||
|
||||
- 数据字段:每个软件组件的基本信息
|
||||
|
||||
- 自动化支持:能够自动生成机器可读格式的SBOM
|
||||
|
||||
- 实践和流程:SBOM 应该如何及何时生成和分发
|
||||
|
||||
|
||||
所需元素的目的是为 SBOM 使用者提供他们所需的信息,以管理漏洞、清点软件组件,并监管许可证合规性。
|
||||
|
||||
### 数据字段
|
||||
|
||||
根据NTIA的说法,这一字段是为了“充分识别这些组件以在整个软件供应链中跟踪它们,并将它们映射到其他相关的数据来源,如漏洞数据库或许可证数据库”。
|
||||
|
||||
7个必要的数据字段如下:
|
||||
|
||||
- **供应商名称:** 开发该软件组件的个人或组织
|
||||
|
||||
- **组件名称:** 给一组软件命名,通常由供应商决定
|
||||
|
||||
- **组件版本:** 一个标识符,指定软件与以前版本的变化。同样,这是由供应商决定的
|
||||
|
||||
- **其他独特标识符:** 像Software Identification (SWID)标签、Package Uniform Resource Locators (PURL)、Common Platform Enumeration(CPE)或类似的标识符,可以帮助SBOM 消费者在关键数据库中找到组件
|
||||
|
||||
- **依赖项关系:** 表示软件组件是如何结合在一起的,如,某个上游组件包含在某个软件中
|
||||
|
||||
- **SBOM数据的作者:** 生成SBOM元数据的实体,可能是软件供应商或其他个人、团体
|
||||
|
||||
- **时间戳:** SBOM 生成的日期和时间
|
||||
|
||||
|
||||
### 自动化支持
|
||||
|
||||
下一组最低要求元素是指 SBOM 数据在整个软件生态系统内部以及跨组织通信的方式。这一要求的目标是为了确保 SBOM 数据真正可用——不仅仅是机器可读,还能够让人直接阅读,而且它的传输格式是可互操作的。
|
||||
|
||||
要达到这一目标,NTIA 认证了3个交付格式来生成和消费 SBOM。至关重要的是,向联邦政府销售软件的组织必须以这三种格式之一传送 SBOM,以符合网络安全行政命令的要求。
|
||||
|
||||
这3个格式是:
|
||||
|
||||
- Software Package Data Exchange (SPDX)
|
||||
|
||||
- Software Identification (SWID) Tags
|
||||
|
||||
- CycloneDX
|
||||
|
||||
|
||||
在后面一节,我们将会对这3个格式进行详细介绍。
|
||||
|
||||
### 实践和流程
|
||||
|
||||
最后一组SBOM最低要求元素涉及生成和申请SBOM的具体操作。具体而言,实践和流程部分包括以下6个方面的要求:
|
||||
|
||||
- **频率(Frequency):** NTIA规定,“如果软件组件随着新的构建或发布而更新”,企业应该生成新的SBOM。此外,供应商在以下情况下也需要生成新的SBOM: 1)需要纠正原始版本中的错误 2)了解有关软件组件的新细节
|
||||
|
||||
- **深度(Depth):** 合规的SBOM需要包含: 1)所有顶层组件 2)所有间接依赖关系。如果SBOM作者不能包含所有间接依赖关系,则需要囊括足够的信息,使消费者可以递归地找到他们。
|
||||
|
||||
- **已知的未知因素(Known Unknowns):** 在SBOM作者没有提供完整的依赖关系图的情况下,他们需要说明这是因为: 1)该组件没有进一步的依赖关系,或者 2)不知道是否存在其他的依赖关系。
|
||||
|
||||
- **分发和交付:** 这一部分分为几个环节,都是关于确保SBOM以可消化的格式快速交付。首先,SBOM被要求以“及时”的方式提供(尽管没有设定天数或周数)。其次,他们必须有“适当的”角色和访问权限。最后,SBOM可以与产品的每个实例一起分发或者以其他可访问的方式提供,如公开的网站。
|
||||
|
||||
- **访问控制:** 如果供应商想将SBOM数据的访问限制在某些客户或用户,他们需要提供这种访问控制的条款。此外,供应商需要提供 “具体的允许和便利”,以便SBOM消费者能够将数据纳入其安全工具。
|
||||
|
||||
- **容错程度:** 网络安全行政命令和指导SBOM创建的法规目前尚不成熟,因此,各组织被指示要对(无意的)错误或遗漏给予理解。
|
||||
|
||||
|
||||
## SBOM交付格式及规范
|
||||
|
||||
企业可以通过各种不同的格式创建和发布软件物料清单(SBOM)。对于一个想要在其网站发布 SBOM 的企业来说,HTML 是一个合理的选择。如果 SBOM 中包含了文档或者源代码,那么纯文本也许是更佳选项。此外,还有 Markdown、PDF、CSV等格式可供使用。
|
||||
|
||||
除了这些常见的格式外,还有几种专门为交付SBOM而设计的格式,如 SPDX(软件包数据交换),SWID Tags(软件识别)以及Cyclone DX。
|
||||
|
||||
### SPDX
|
||||
|
||||
SPDX是由 Linux 基金会运营的项目,旨在标准化企业共享和使用SBOM中信息的方式。SPDX 捕捉与provenance、许可证和安全相关的数据,下图展示了 SPDX 文档中所包含的数据:
|
||||
|
||||
|
||||
|
||||
该格式支持以下文件类型:
|
||||
|
||||
- YAML
|
||||
- JSON(你可以在 GitHub 上找到SPDX的JSON schema:[github.com/spdx/spdx-s…](https://link.juejin.cn/?target=https%3A%2F%2Fgithub.com%2Fspdx%2Fspdx-spec%2Ftree%2Fdevelopment%2Fv2.2.1%2Fschemas%25EF%25BC%2589 "https://github.com/spdx/spdx-spec/tree/development/v2.2.1/schemas%EF%BC%89")
|
||||
- RDF/XML
|
||||
- tag:value flat text file
|
||||
- .xls 电子表格
|
||||
|
||||
Seal 软件供应链防火墙可以直接生成SPDX格式的SBOM文件,欢迎访问下方链接申请产品试用: [seal.io/trail](https://link.juejin.cn/?target=seal.io%2Ftrail "seal.io/trail")
|
||||
|
||||
### SWID Tags
|
||||
|
||||
SWID 是一个标准化的 XML 格式,可以识别软件产品的组成部分并将其与上下文结合。4种类型的 SWID Tags 在软件开发生命周期中:
|
||||
|
||||
- **Corpus Tags:** 识别和描述在安装前阶段的软件成分。根据 NIST 给出的定义,corpus tags 是指“软件安装工具和流程的输入”
|
||||
- **Primary Tags:** 在软件产品安装后对其进行识别和关联
|
||||
- **Patch Tags:** 顾名思义,patch tags 可以识别和描述补丁(而不是核心产品本身)。此外,patch tags 包含了补丁和其他产品或补丁之间的上下文关系信息。
|
||||
- **Supplemental Tags:** SWID 格式仅允许 tag 创建者修改 corpus、primary和patch tags。但是 Supplemental Tags 可以让软件用户及软件管理工具在本地添加有益的上下文信息,如许可证密钥以及相关方的联系信息。
|
||||
|
||||
在决定将哪些标签和具体的数据元素纳入其产品时,各企业有一定程度的灵活性。在SWID规范中,除了几个必须的字段外,其他的元素和属性都是可选的。
|
||||
|
||||
最终,一个最低限度的有效和符合要求的标签只需要描述软件产品(如名称和标签ID)和创建它的实体的少数元素。关于SWID标签数据元素的最全面和最新的信息,建议查看ISO/IEC 19770-2:2015标准全文: [www.iso.org/standard/65…](https://link.juejin.cn/?target=https%3A%2F%2Fwww.iso.org%2Fstandard%2F65666.html "https://www.iso.org/standard/65666.html")
|
||||
|
||||
### Cyclone DX
|
||||
|
||||
Cyclone DX 是一个轻量级软件物料清单标准,旨在用于应用安全上下文和供应链组件分析。换言之,它旨在实现与SPDX、SWID以及其他所有SBOM交付格式类似的目标——提供构成一个应用程序的软件组件的关键信息。
|
||||
|
||||
Cyclone DX 支持以下4种类型的数据:
|
||||
|
||||
- **物料清单元数据:** 关于应用/产品本身的信息——供应商、制造商、SBOM所面熟的组件以及用于汇编SBOM的任意工具
|
||||
- **组件:** 完整的专利清单及开源组件清单,包含许可信息
|
||||
- **服务信息:** 软件可能调用的外部API、终端URI、身份认证要求和信任名单
|
||||
- **依赖项:** 包含直接依赖项和间接依赖项
|
||||
|
||||
## 谁是SBOM的目标受众?
|
||||
|
||||
历史上,SBOM主要由合规团队用来审计、监控许可证以及遵守行业特定规范,但随着软件供应链攻击的上升,包括 SolarWinds 黑客事件和去年年末的 Log4Shell 漏洞,SBOM 的使用扩展到了安全和开发团队。
|
||||
|
||||
### 安全团队
|
||||
|
||||
对于安全团队来说,SBOM扮演着十分重要的角色,特别是需要进行漏洞扫描的时候。因为扫描SBOM库比从头开始扫描整个基础设施更简单也更快,在发生零日事件时,每一分钟都很重要。此外,安全团队也会利用 SBOM 所提供的信息(如风险所在位置)来确定问题修复的优先级,并针对特定组件创建策略,如供应商的选型、可引入的版本或者软件包类型等。
|
||||
|
||||
### 开发团队
|
||||
|
||||
开发团队可以使用 SBOM 来跟踪他们所开发、管理和运维的各个软件中的组件,包括开源组件、商业组件和自研组件。并且 SBOM 还能协助开发团队管理依赖项、识别安全问题以减少其重复的工作,还能确保开发人员使用的都是经过审批的代码和可信任的源。
|
||||
|
||||
## SBOM 的应用场景
|
||||
|
||||
显然,有许多令人信服的理由推动企业创建SBOM,并且企业可以为所有产品创建SBOM,每个新版本都可以更新一版SBOM。此外,在一些特定场景中SBOM会最大限度地发挥其作用。
|
||||
|
||||
- **融资、并购和IPO:** 软件物料清单是收购、IPO或融资过程中技术尽调的重要一环。相关利益方会要求获取文档以更好地了解产品中的软件成分以及许可证合规性、安全性或代码质量风险。
|
||||
- **客户要求:** 由于全球范围内的企业都将防止软件供应链风险的优先级提高了,因此未来会有越来越多的企业要求采购环节中需要提供SBOM。
|
||||
- **向下兼容:** 维护大量旧软件的公司经常需要进行OSS包的更新和升级。当然,如果对这些旧产品中的开放源码软件有一个完整的清单,做起来就容易多了。
|
||||
|
||||
## 全面管理 SBOM 的最佳实践
|
||||
|
||||
随着SBOM被迅速接受,行业领导者已经开始开发创建、管理和使用SBOM 的方法。这些实践跨越了软件生命周期的各个关键阶段:
|
||||
|
||||
**1、在统一的存储库中存储和管理 SBOM** 虽然单个开发或应用团队可以将SBOM与他们的代码构件一起存储在存储库中,但安全团队必须在所有应用和开发团队中维护一个统一的SBOM存储库。当新的漏洞或安全事件出现时,安全团队和CISO需要快速查询所有软件的SBOM并即时评估影响,而不是分别从每个团队中获得单独的评估报告,或者不得不浪费事件从头开始查找和重新扫描他们所有的应用程序。此外,满足监管要求或合规标准也需要一个集中的存储库,用于生成报告和其他的合规活动。
|
||||
|
||||
**2、要求所有进入供应链的软件提供SBOM** 企业如果需要对所使用的软件保有可见性,那么收集 SBOM 信息以分析软件成分或应用是十分重要的。如果是第三方商业软件,那么软件供应商应该提供必要的 SBOM,并将其纳入你的 SBOM 资源库。
|
||||
|
||||
当使用的是开源组件来构建自定义软件时,在将其引入开发流程前企业应该直接扫描开源构件(如容器镜像)或者开源代码仓库。在某些情况下,开源项目可能会提供一个签名的 SBOM,这可以让企业将他们生成的 SBOM 与社区提供的 SBOM 进行比较来进行验证。
|
||||
|
||||
**3、为每个开发环节和构建生成SBOM** 各行各业的企业正在定制软件以迎合其独特的市场需求。大部分软件都由大量的开源代码组成(根据不同的应用程序,开源代码的占比在50—90%之间)以及内部开发的代码和第三方库。由于在构建阶段开源代码常常会引入额外的依赖项,因此在开发流程中的每一步及每一次构建软件时都扫描您的软件是至关重要的。这可以让您检测出意料之外的SBOM变更,这些变更可能由新依赖项或代码修改导致的。这些 SBOM 需要标记为特殊组件或他们所代表的应用程序。
|
||||
|
||||
**4、为你所部署或交付的每个软件版本创建综合的SBOM** 无论您是将软件交付给客户,还是帮助客户、员工、合作伙伴进行部署,您应该创建一个综合的SBOM,并标记为该版本软件的变更。这提供了一个追踪机制,可以让企业快速评他们生产的应用或组件的安全状况,同时评估新漏洞对此前开发的影响。对于将软件售卖或提供给外部用户的企业,您也可以提供必要的可见性和“信任报告”给软件的下游用户。
|
||||
|
||||
**5、 将自动化应用于策略执行和告警**
|
||||
|
||||
借助中心化的SBOM仓库和有效的SBOM管理能力,企业可以利用一个自动的策略引擎来应用策略规则,如同步特殊的监管要求或合规标准。同时,还可以应用任意内部要求。自动告警可以提醒您新漏洞或违反策略的行为,如此,受影响的团队可以快速修正重要问题并阻止受影响的镜像被部署。
|
||||
|
||||
## 借助工具生成SBOM
|
||||
|
||||
可以肯定的是,软件物料清单将在业务开展方式中发挥越来越重要的作用。但是,考虑到制作SBOM所需的数据量,仅通过人工将这些碎片组合在一起是相当具有挑战性的。Seal 软件供应链防火墙可以生成SBOM数据,并可以跟踪SBOM的变化以进行漏洞匹配,及时发现软件供应链中的安全风险。
|
||||
|
||||
|
||||
@@ -0,0 +1,89 @@
|
||||
---
|
||||
page-title: "如何使用微软的开源工具生成 SBOM - 知乎"
|
||||
url: https://zhuanlan.zhihu.com/p/571994012
|
||||
date: "2023-03-07 09:23:23"
|
||||
---
|
||||
|
||||
|
||||
SBOM (软件物料清单)通过列出您的代码所依赖的软件包和供应商来帮助您了解您的软件供应链。SBOM 正迅速获得发展势头,作为在现实世界供应链受到重大攻击后帮助提高安全性的一种方式。
|
||||
|
||||
SBOM 的主要支持者之一是微软,该公司早在 2021 年 10 月就发布了针对他们这一代的方法。今年早些时候,该公司开源了其用于在 Windows、macOS 和 Linux 上生成 SBOM 的工具。
|
||||
在本文中,您将学习如何开始使用该项目来索引代码的依赖项。它生成与 SPDX 兼容的文档,列出项目中的文件、包和关系。SPDX(软件包数据交换)是 ISO 接受的 SBOM 标准,因此您可以将生成的报告直接传递到其他生态系统工具。
|
||||
|
||||
微软最初以 Salus 的名义宣布了该项目。由于它与起源于 Coinbase的现有Salus 代码安全项目相冲突,因此从该术语中退出。SBOM 生成器现在简称为.sbom-tool
|
||||
|
||||
## 入门
|
||||
|
||||
您可以从 Microsoft 的GitHub 存储库下载 SBOM 工具。发布页面上提供了预编译的二进制文件。为您的系统选择正确的下载,然后制作二进制可执行文件并将其移动到您路径中的某个位置。
|
||||
|
||||
以下是 Linux 的示例:
|
||||
|
||||
`$ wget https://github.com/microsoft/sbom-tool/releases/download/v<VERSION>/sbom-tool-linux-x64 $ chmod +x sbom-tool-linux-x64 $ mv sbom-tool-linux-x64 /usr/local/bin/sbom-tool`
|
||||
|
||||
您应该能够运行sbom-tool以在终端窗口中显示帮助信息:
|
||||
|
||||
`$ sbom-tool No action was specified The Sbom tool generates a SBOM for any build artifact. Usage - Microsoft.Sbom.Tool <action> -options`
|
||||
|
||||
## 生成 SBOM
|
||||
|
||||
generate通过运行该工具的子命令可以创建新的 SBOM 。需要提供一些参数:
|
||||
|
||||
- \-b( BuildDropPath) – 将生成的 SPDX SBOM 清单保存到的文件夹。
|
||||
|
||||
- \-bc( BuildComponentPath) – 将被扫描以查找项目中的依赖项的文件夹。
|
||||
|
||||
- \-nsb( NamespaceUriBase) – 将用作 SBOM 清单的命名空间的基本路径。这应该是您的组织拥有的 URL,例如https://example.com/sbom.
|
||||
|
||||
|
||||
SBOM Tool 还需要知道您的项目的名称和版本。它通常可以从存储库中已有的文件(例如package.json name和version字段)中推断出这一点,但在某些情况下,您可能需要手动提供信息或覆盖默认值。添加pn和pv标志来做到这一点:
|
||||
|
||||
- \-pn( PackageName) – 您的项目或包的名称。
|
||||
|
||||
- \-pv( PackageVersion) – 您正在扫描的项目版本。这应该与您的 SBOM 随附的发布版本相匹配,以便用户可以将依赖项列表与特定构建相关联。
|
||||
|
||||
|
||||
这是为工作目录中的文件生成 SBOM 的示例。SBOM 将被放置到sbom-output子目录中。这需要在您运行该工具之前存在。
|
||||
|
||||
`$ mkdir sbom-output $ sbom-tool generate -b sbom-output -bc . -pn example -pv 1.0 -nsb https://example.com/sbom`
|
||||
|
||||
扫描结果的概述将显示在您的终端中:
|
||||
|
||||
`[INFO] Enumerated 3728 files and 607 directories in 00:00:00.5938034 [INFO] |Component Detector Id |Detection Time |# Components Found |# Explicitly Referenced | ... [INFO] |Npm |0.63 seconds |241 |0 | ... [INFO] |Total |0.64 seconds |241 |0 | [INFO] Detection time: 0.6374678 seconds.`
|
||||
|
||||
这个项目使用 npm 来管理它的依赖。package.json该工具在工作目录的文件中检测到 241 个包。
|
||||
|
||||
SBOM Tool 目前支持 19 种不同的编程语言和包格式。该列表包括npm、NuGet、PyPi、Maven、Rust Crates 和 Ruby gem,以及 Docker 映像中存在的 Linux 包。还支持对远程 GitHub 存储库的引用。
|
||||
|
||||
## SBOM 内容
|
||||
|
||||
生成的 SBOM 将写入\_manifest/spdx\_2.2/manifest.spdx.json您指定的构建输出目录中。SBOM 是一个相当冗长的 JSON 文件,旨在供其他软件使用。
|
||||
|
||||
`{ "files": [], "packages": [ { "name": "color-convert", "SPDXID": "SPDXRef-Package-A72B0922E46D9828746F346D7FD11B7F81EDEB15B92BEEDAE087F5F7407FECDC", ... }`
|
||||
|
||||
报告中有四种主要类型的信息:
|
||||
|
||||
- 该files部分- 这列出了包含您在项目中编写的源代码的所有文件。SBOM 工具仅在扫描某些项目类型(例如 C# 解决方案)时才会填充此部分。
|
||||
|
||||
- 该packages部分- 项目中存在的所有第三方依赖项的完整目录,其中包含对其源包管理器的引用、使用的版本以及适用的许可证类型。
|
||||
|
||||
- 该relationships部分- 这详细说明了 SBOM 中列出的组件之间的所有关系。您将看到的最常见的关系是DEPENDS\_ON,它将packages节中的一项声明为项目的依赖项之一。还存在几种其他类型的关系,例如CREATED\_BY、DEPENDENCY\_OF和PATCH\_FOR。
|
||||
|
||||
- 报告元数据详细信息– 、 、等字段name,documentNamespace并spdxVersion标识creationInfoSBOM、用于创建它的工具以及适用的SPDX 清单修订。
|
||||
|
||||
|
||||
现在您已经有了一个 SBOM,您可以开始将它与其他工具一起使用来进行漏洞扫描和管理许可证合规性。您可以考虑将 SBOM 与您的软件版本一起分发,以便消费者能够检查每个新版本的内容。SBOM 最好作为构建管道的一部分生成,以便它们保持最新状态。
|
||||
当出现重大的新供应链问题时,访问 SBOM 是非常宝贵的。例如,使用 SBOM 的组织可以更好地响应 Log4j。他们可以检查他们的报告以根据易受攻击的库快速找到项目,而不是手动审核包列表。
|
||||
|
||||
## 扫描 Docker 图像
|
||||
|
||||
作为报告生成的一部分,SBOM 工具能够扫描现有的 Docker 映像。要使用此功能,您需要添加-di标志并指定要扫描的图像标签或摘要。其余的论点保持不变。
|
||||
|
||||
`$ sbom-tool generate -di ubuntu:latest -b sbom-output -bc . -pn demo -pv 1.0 -nsb https://demo.com/demo`
|
||||
|
||||
将分析 Docker 映像以识别它包含的包。它们将与源文件夹中的依赖项一起添加到 SBOM 报告中。您可以在单个操作中扫描多个 Docker 映像,方法是用逗号分隔它们的标签或摘要哈希。
|
||||
|
||||
## 概括
|
||||
|
||||
SBOM Tool 是 Microsoft 开发的一个年轻的开源 SBOM 生成实用程序。它支持几种领先的包格式并产生与 SPDX 兼容的输出。这意味着您可以将生成的 SBOM 直接输入到 Grype 等其他工具中,以自动查找安全漏洞和过时的依赖项。
|
||||
|
||||
SBOM 是提高软件供应链意识和发现潜在问题的有效方法。制作和分发 SBOM 有助于用户了解他们的项目中默默包含的内容。SBOM 工具是使用单个命令生成行业标准报告的一种方法,可以更轻松地为每个版本提供 SBOM。
|
||||
@@ -0,0 +1,134 @@
|
||||
---
|
||||
page-title: "如何通过SBOM(软件物料清单)实现安全治理_墨菲安全"
|
||||
url: https://www.murphysec.com/blog/knowledge-popularization/4218.html
|
||||
date: "2023-03-07 09:26:04"
|
||||
---
|
||||
[墨菲安全](https://www.murphysec.com/blog/author/chenshuang) • 2023年1月4日 18:17 • [知识普及](https://www.murphysec.com/blog/category/knowledge-popularization)
|
||||
|
||||
## 前言
|
||||
|
||||
SBOM(软件物料清单)是近年来在软件供应链领域频繁提到的概念,Linux基金会在2021年Q3调研了全球412 家机构发现已经有82%的人熟悉SBOM、78%的组织预计在今年使用SBOM。本文将介绍SBOM基本概念、实现方式、应用场景,帮助读者通过SBOM更高效地实现安全治理目标。
|
||||
|
||||
## 什么是SBOM
|
||||
|
||||
根据NTIA(美国国家电信和信息化管理局)的定义,SBOM(Software Bill of Materials,软件物料清单)是一份关于软件组件和依赖,包含它们的信息和层级关系的形式化、机器可读清单。
|
||||
|
||||
NTIA认为SBOM应该满足以下要求:
|
||||
|
||||
- 这份清单应该是全面,或者是明确识别范围的
|
||||
- 应包含开源和闭源软件
|
||||
- 能被广泛使用或者限制访问
|
||||
|
||||
还定义了SBOM中应该包含的最小化的软件组件信息(基线软件组件信息),包括:供应商名称、组件名称、唯一标识符、版本字符串、组件哈希、组件之间的关系、SBOM作者姓名。
|
||||
|
||||
在展现方式上,SBOM的信息可以通过图、表格等方式进行展现。
|
||||
|
||||
[](https://www.murphysec.com/blog/wp-content/uploads/2023/01/asynccode-89.png)
|
||||
|
||||
(左图为SBOM最小化信息示例,右图为依赖关系图示例)
|
||||
|
||||
[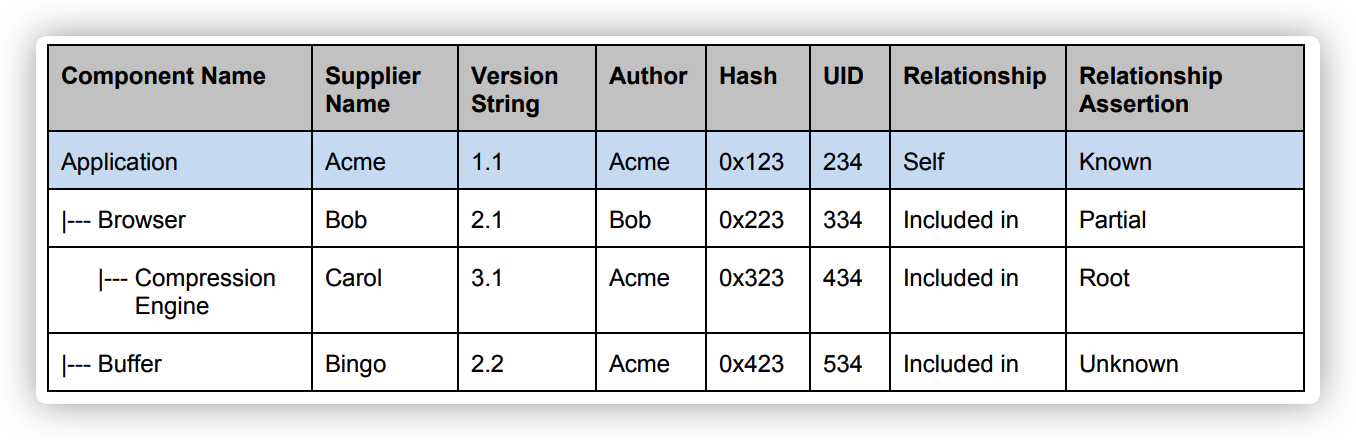](https://www.murphysec.com/blog/wp-content/uploads/2023/01/asynccode-90.png)
|
||||
|
||||
(树状表格展示的SBOM信息示例)
|
||||
|
||||
SPDX (ISO/IEC 5962:2021) 是目前SBOM格式的事实标准,常见的格式还有SWID和CycloneDX,都能满足最小化的使用需求。
|
||||
|
||||
## SBOM的用途
|
||||
|
||||
根据Linux基金会的调研报告,人们普遍认为SBOM有三大收益:
|
||||
|
||||
- 51%的人表示,开发人员更容易理解应用程序中组件之间的依赖关系
|
||||
- 49%的用户表示更容易监控组件的漏洞
|
||||
- 44%的人指出,管理许可证合规变得更容易
|
||||
|
||||
## 依赖治理
|
||||
|
||||
当今软件开发的过程,如同开发人员使用一个个组件作为积木搭出高楼,随着软件变得越来越复杂,开发人员可能并不清楚用到了哪些组件、这些组件之间又存在什么样的依赖关系,一个个的积木如同黑箱般存在,维护起来只能小心翼翼,随时可能陷入下图中的依赖地狱。
|
||||
|
||||
[](https://www.murphysec.com/blog/wp-content/uploads/2023/01/asynccode-91.png)
|
||||
|
||||
对于企业的工程团队而言,对于一些管理需求,例如规范某类组件的使用、避免重复开发以提升研发效率,首先需要了解企业内各种项目中使用到的组件,梳理对应的依存关系,才能做出有效的管理动作,这也迎合了当前比较火热的可见性需求。
|
||||
|
||||
一个组件版本碎片化的go语言项目可能会像下图这样,依赖了大量不同版本的同一组件。基于SBOM可以将碎片化的组件版本固定至一个或多个长期维护的稳定版本,避免版本无人维护导致产生bug无法解决。
|
||||
|
||||
## 漏洞管理
|
||||
|
||||
企业安全团队在面对新的漏洞、安全事件出现时,需要评估企业内有哪些资产受到影响,可以通过将漏洞的影响软件、版本范围等信息与已有SBOM进行关联,得到受影响资产列表,从而指导进一步的风险处置动作。
|
||||
|
||||
例如当出现新的类似log4j的漏洞时,可以通过SBOM以图的形式查找哪些内部项目中用到了log4j,通知这些项目的维护者进行漏洞修复。
|
||||
|
||||
无法复制加载中的内容
|
||||
|
||||
除了应急响应,在日常的风险管理中,可以基于SBOM计算每个项目存在依赖的漏洞风险,作为安全评价维度进行管理。(示意如下图)
|
||||
|
||||
无法复制加载中的内容
|
||||
|
||||
## 开源许可证合规
|
||||
|
||||
2021年罗盒公司的案件是中国法院首次认可了GPL许可证的效力,违反开源许可证也已经被越来越多的国家法律认定为侵权行为。为了降低软件侵权风险,企业需要识别软件中涉及的许可证,有效管理项目中涉及的许可证风险。
|
||||
|
||||
而由于许多开源许可证具有传递性,如果不能全面识别所涉及到的组件及对应的开源许可证信息,则可能忽略所开发软件需要遵循相应的开源许可证约束,比如需要提供源代码、需要对开源许可证进行标识。
|
||||
|
||||
如图中项目A引用了组件A,组件A使用了AGPL许可证,则项目A应该按照AGPL许可证的要求,不论修改或使用都应该开源。这样的场景对企业使用会有较多限制,应基于SBOM及时进行治理。
|
||||
|
||||
无法复制加载中的内容
|
||||
|
||||
## 如何生成SBOM
|
||||
|
||||
可以看到包括墨菲安全的客户端在内有不少的开源工具都可以生成SBOM,而有效的SBOM依赖软件成分分析能力和大量知识数据的储备。
|
||||
|
||||
## SCA(软件成分分析)
|
||||
|
||||
SBOM的生成依赖SCA技术,识别组件和版本,并输出对应的层级依赖关系。其复杂性在于
|
||||
|
||||
1)要适配不同的编程语言,而像java和c/c++这样不同语言的包管理机制会有较大差异;
|
||||
|
||||
2)要从源码、制品、二进制等不同形态的软件产物中解析提取特征,这些特征的提取策略依赖于对各类产物的理解。
|
||||
|
||||
## 知识库数据
|
||||
|
||||
除了SBOM中的基线字段信息外,漏洞、开源许可证也可以作为SBOM的附加信息,而这样的数据则强依赖于云端知识库的积累。
|
||||
|
||||
知识库需要实时跟踪当前的各种漏洞情报,并由人工运营加工;需要采集大量的代码、制品信息,分析依赖、计算哈希、提取特征等等,加工形成能和SCA工具结果匹配的特征数据。
|
||||
|
||||
## 如何发挥SBOM的作用
|
||||
|
||||
对于企业而言,要想充分发挥SBOM的作用,至少应该关注以下几点。
|
||||
|
||||
## SBOM及时更新
|
||||
|
||||
老旧的SBOM数据可能产生反作用,做无用功的同时让研发团队产生抱怨,因此SBOM应该是跟随代码、制品动态变化的「实时」数据。
|
||||
|
||||
可以通过将SBOM更新的逻辑嵌入到每一次代码的变更,例如通过IDE插件识别对应的代码变更、与代码仓库集成在代码提交或合并时重新生成;对于没有代码或者项目中存在二进制依赖的情况,CI/CD环节则更为关键,通过与jenkins等软件的集成可以实现代码发布前的审查。
|
||||
|
||||
## 通过知识库关联风险数据
|
||||
|
||||
SBOM只是一个开始,要想用于风险的治理,只有基线数据字段的SBOM难以发挥它的价值,背后需要有强大的知识库作为支撑。
|
||||
|
||||
SBOM要和知识库进行联动,当SBOM发生变化或者知识库中的数据发生变化时,都应该触发风险识别逻辑。例如,当SBOM中引入了一个新的组件,需要通过知识库评估这个组件是否存在开源许可证约束、是否适合商业使用;当出现一个新漏洞,知识库收录后应该联动SBOM判断有哪些项目受到影响。
|
||||
|
||||
## 构建管理平台
|
||||
|
||||
对于企业的内部治理而言,单点的工具是不够的,还需要有管理平台输出全局的风险视图,提供管理和控制能力。
|
||||
|
||||
例如,管理平台需要记录每一次的SBOM变化情况,从而能够展现不同时间点的风险指标情况;要能够基于项目、资产等不同维度对结果进行聚合,便于对总体风险进行梳理。
|
||||
|
||||
基本的管理平台可以如下图所示,以SBOM和知识库作为核心数据,控制模块通过和制品库、代码库等的联动,进行数据收集和策略下发,出现问题时帮助企业及时止损。决策模块对黑白名单进行维护、对阻断等策略进行管理,管理模块提供SBOM查询和相关管理指标看板的能力。
|
||||
|
||||
## 要求供应商提供SBOM
|
||||
|
||||
企业难以避免会使用到各类供应商提供的软件产品,这些产品通常以二进制的形式交付,相比源码识别的效果覆盖率会更低,存在的风险更难识别。此时SBOM应该作为供应商准入的要求,在采购环节要求提供SBOM,并对SBOM进行审查和统一管理。
|
||||
|
||||
## 总结
|
||||
|
||||
对于企业而言,SBOM是软件供应链治理中很重要的基础数据,能够帮助企业实现依赖治理、漏洞管理和开源许可证合规。SBOM背后靠的是SCA和知识库数据的支撑,想要充分发挥SBOM的作用,应该将生成工具和尽可能多的研发流程打通,做到实时更新,和全面的知识库数据进行动态关联,通过管理平台支撑全局的风险呈现与管理,同时还应要求供应商提供SBOM信息。
|
||||
|
||||
## 参考链接
|
||||
|
||||
[https://www.ntia.gov/SBOM](https://www.ntia.gov/SBOM)
|
||||
|
||||
[https://www.ntia.gov/blog/2021/ntia-releases-minimum-elements-software-bill-materials](https://www.ntia.gov/blog/2021/ntia-releases-minimum-elements-software-bill-materials)
|
||||
|
||||
[https://linuxfoundation.org/wp-content/uploads/LFResearch\_SBOM\_Report\_020422.pdf](https://linuxfoundation.org/wp-content/uploads/LFResearch_SBOM_Report_020422.pdf)
|
||||
|
||||
发布者:墨菲安全,转发请注明出处:https://www.murphysec.com/blog/knowledge-popularization/4218.html
|
||||
@@ -0,0 +1,16 @@
|
||||
---
|
||||
page-title: "联想移动互联及数字家庭产品服务支持"
|
||||
url: https://m.lenovocare.com.cn/ServiceStation.aspx
|
||||
date: "2023-03-20 09:58:49"
|
||||
---
|
||||
联想移动客户服务中心(广州天河南二路店)
|
||||
|
||||
天河区天河南二路19号宏发大厦5楼539室(地铁三号线石牌桥a出口往东前行20米进楼巴候车室北门坐电梯5楼)
|
||||
|
||||
联系电话:020-85239885
|
||||
|
||||
营业时间:9:00-18:00
|
||||
|
||||
服务品牌:
|
||||
|
||||
lenovo moto zuk
|
||||
@@ -0,0 +1,139 @@
|
||||
---
|
||||
page-title: "需要考虑的8种顶级SBOM工具 | CN-SEC 中文网"
|
||||
url: https://cn-sec.com/archives/1247429.html
|
||||
date: "2023-03-07 09:24:33"
|
||||
---
|
||||
写在前面:在[软件供应链](https://cn-sec.com/archives/tag/%e8%bd%af%e4%bb%b6%e4%be%9b%e5%ba%94%e9%93%be)攻击中,SBOM在监管要求和技术实现上,都是相对容易落地的方式。本文中介绍的SBOM程序,有的是耳熟能详,有的也是第一次看到。大家可以参考本文中推荐的软件,和现实工作相结合。
|
||||
|
||||
2022年7月25
|
||||
|
||||
要真正保证软件的安全,您需要知道代码里面有什么。这就是为什么软件物料清单(SBOM)在今天必不可少。过去,我们并不太担心代码的安全性。糟糕的二进制文件?好像是;源代码本身有问题?没那么严重。我们都太蠢了。
|
||||
|
||||
随后,安全问题接踵而至:SolarWinds软件供应链攻击,Log4j漏洞持续存在,npm维护者抗议代码出错,这些都表明我们必须清理我们的软件供应链。对于专有软件来说,这是不可能的,因为它的创造者不会让你知道程序里面有什么。但对开源程序,这就可以通过软件物料清单(SBOM)实现,发音为“s-bomb”。
|
||||
|
||||
事实上,SBOM不再仅仅是一个好主意;这是联邦政府的命令。根据乔·拜登总统于2021年7月12日发布的《关于提高国家网络安全的行政命令》,这是一项要求。该行政命令将SBOM定义为“包含构建软件中使用的各种组件的详细信息和供应链关系的正式记录”。对于开源软件来说,这是一个特别重要的问题,因为“软件开发者和供应商经常通过组装现有的开源和商业软件组件来创造产品。”
|
||||
|
||||
这是真的吗?噢,是的。我们都知道,开源软件无处不在,随处可见。但是你知道吗,据Tidelift统计,92%的应用程序包含开源组件。事实上,现代程序平均有70%是开源软件。
|
||||
|
||||
显然,我们需要做些什么。根据Linux基金会、开源安全基金会(OpenSSF)和OpenChain的说法,答案是SBOM。Linux基金会研发副总裁Stephen Hendrick将SBOM定义为“正式的、机器可读的元数据,它唯一地标识一个软件包及其内容;它可能包括内容的其他信息,包括版权和许可数据。SBOM被设计为跨组织共享,特别有助于提高软件供应链参与者交付的组件的透明度。”
|
||||
|
||||
最佳SBOM实践
|
||||
|
||||
SBOM应包括:
|
||||
|
||||
- 应用程序的开源库
|
||||
|
||||
- 程序的插件、扩展和其他附件
|
||||
|
||||
- 由开发人员内部编写的自定义源代码
|
||||
|
||||
- 这些组件的版本信息、软件许可状态和补丁状态
|
||||
|
||||
- 自动组件加密签名和验证
|
||||
|
||||
- 自动扫描生成SBOM,作为持续集成/持续部署(CI/CD)管道的一部分
|
||||
|
||||
|
||||
SBOM也应该使用一致的格式。当前最常见的SBOM格式包括软件包数据交换(SPDX)、软件标识(SWID)标签和OWASP CycloneDX。虽然这些都是标准,但2021年的行政命令并没有强制规定特定的SBOM格式。到目前为止,这三家公司都没有从其他公司中脱颖而出,形成事实上的行业标准。
|
||||
|
||||
为了使SBOM更加实用,我们不仅要推动自动化创建SBOM,还要使其成为CI/CD管道的一部分。正如国家电信和信息管理局(NTIA)所言,最终目标是按照“机器速度”生成SBOM。
|
||||
|
||||
SBOM使用场景
|
||||
|
||||
SBOM有三个不同的使用场景:
|
||||
|
||||
1. 软件生产商使用SBOM来帮助构建和维护他们提供的软件。
|
||||
|
||||
2. 软件采购人员使用SBOM来告知购买前的保证,协商折扣,并计划实施策略。
|
||||
|
||||
3. 软件操作人员使用SBOM通知漏洞管理和资产管理,管理许可和合规,并快速识别软件和组件依赖关系和供应链风险。
|
||||
|
||||
|
||||
这之间区别很大。开发人员希望能有在他们的CI/CD管道上工作的工具,如CircleCI、Jenkins或Travis CI。运营人员或客户可能甚至不知道什么是CI/CD管道,但可能非常关心资产管理和安全补丁更新。
|
||||
|
||||
Gartner估计,到2025年,60%的构建或采购关键基础设施软件的组织将强制执行SBOM并将其标准化。如今,这一比例不到20%。
|
||||
|
||||
顶级SBOM程序
|
||||
|
||||
使用三种不同的SBOM格式和各种各样的元数据来跟踪一个SBOM,这并不奇怪,还没有超级的SBOM 程序,应该有一个,但现在还不存在。
|
||||
|
||||
许多SBOM程序,但不是所有,和代码安全扫描器绑定在一起。其他的程序,是否你想要他们取决你的需要。Gartner推荐你的工具具有如下功能:
|
||||
|
||||
- 在构建过程中创建SBOM。
|
||||
|
||||
- 分析源代码和二进制文件(如容器镜像)。
|
||||
|
||||
- 为这些工件生成SBOM。
|
||||
|
||||
- 编辑SBOM。
|
||||
|
||||
- 以人类可读的格式查看、比较、导入和验证SBOM。
|
||||
|
||||
- 从一种格式或文件类型合并和转换SBOM内容到另一种格式或文件类型。
|
||||
|
||||
- 通过API和库支持在其他工具中使用SBOM操作。
|
||||
|
||||
|
||||
以下程序没有一个能实现所有这些建议。即使是这些项目中最成熟的Anchore、FOSSA和Rezillion,也还在发展中。
|
||||
|
||||
我建议您尝试这些程序中的大部分(如果不是全部的话),看看哪一个最适合您和您的特定情况。然后给供应商和开发人员你的反馈。如果我们在2025年前做到这一点,我们可能会有一个针对所有不同用途的明确的最佳方案。
|
||||
|
||||
以下是值得你关注的8个SBOM程序:
|
||||
|
||||
Anchore
|
||||
|
||||
Anchore已经在SBOM行业工作了6年。它的基础是两个开源项目:Syft是一个命令行接口(CLI)工具和库,用于从容器镜像和文件系统生成SBOM;Grype是一个易于集成的容器镜像和文件系统漏洞扫描工具。
|
||||
|
||||
您可以在开发过程的每个阶段,从源代码存储库和CI/CD管道到容器注册中心和运行时,使用它们一起生成SBOM。这些SBOM保存在一个集中存储库中,以实现完全的可见性和持续的监视,甚至在部署后也是如此。它支持CycloneDX, SPDX和Syft自己的SBOM格式。
|
||||
|
||||
Anchor将其SBOM功能捆绑到Anchor Enterprise 4.0软件SCM(供应链管理)平台中。Anchore的目标是成为您一体化的软件供应链和SBOM安全公司。他们做得很棒。
|
||||
|
||||
FOSSA
|
||||
|
||||
FOSSA的旗舰程序是一个开源许可证管理器和一个开源漏洞扫描器。仔细想想,SBOM非常自然地适合这些程序。
|
||||
|
||||
在FOSSA的方法中,你可以将它的SBOM工具与你喜欢的版本控制系统集成,如GitHub、BitBucket或GitLab。或者您可以使用它的命令行并在本地运行它,或者将它集成为CI/CD管道的一部分。
|
||||
|
||||
无论哪种方式,当您扫描您的项目时,FOSSA将自动识别目标代码库的直接依赖项和深度依赖项。这些深度嵌入的代码问题,比如对Log4j的间接依赖调用,可能隐藏在程序中,黑客仍然会利用它们进行破坏。
|
||||
|
||||
Mend
|
||||
|
||||
Mend就是曾经的WhiteSource,它提供了各种软件成分分析(SCA)工具。SBOM被合并到其Mend SCA工具中。因此,Mend与其说是一个开发人员程序或CI/CD工具,不如说是程序员的开源许可和安全机制。
|
||||
|
||||
因此,可以使用Mend跟踪每个组件,包括直接和传递性依赖、识别漏洞、提供修复路径,并在组件更改时自动更新SBOM记录。该公司声称其专利的可达性路径分析可以告诉您哪些漏洞可以被安全忽略,因为您的应用程序没有使用这些库,或者这些库的使用方式没有暴露这些漏洞。
|
||||
|
||||
Rezilion
|
||||
|
||||
DevSecOps公司Rezilion将SBOM作为其整体软件安全和漏洞系统的一部分。它的动态SBOM使用动态运行时分析来跟踪代码更改时的软件攻击面。因此,它会不断查找代码组件的已知弱点。换句话说,这是跟踪和保护代码的二合一方法。
|
||||
|
||||
除了提供CI/CD、staging和生产环境中所有软件组件的实时清单外,它还会不断更新您的SBOM。您可以导出您的SBOM的CycloneDX和Excel电子格式。
|
||||
|
||||
SPDX SBOM Generator
|
||||
|
||||
SPDX SBOM Generator是一个独立的开源工具,顾名思义:它从当前的包管理器或构建系统创建SPDX SBOM。您可以使用它的命令行从代码生成SBOM数据。它报告代码的组件、许可、版权和安全引用。该数据在SPDX v2.2规范中导出。如果你只需要基础信息,它会很适合你。
|
||||
|
||||
Tern Project
|
||||
|
||||
另一个开源SBOM项目,Tern可能与SPDX SBOM Generator很好地配合。不使用包管理器或构建系统,这个SCA工具和Python库为容器镜像和Dockerfiles生成一个SBOM。它还生成SPDX格式的SBOM。
|
||||
|
||||
TauruSeer
|
||||
|
||||
这个SBOM程序是以软件即服务(SaaS)的形式提供的。凭借以应用为中心的专利集成方法,Tauruser将认知引擎安全扫描与SBOM相结合。该包将帮助您为开发人员和客户保护和跟踪您的代码。
|
||||
|
||||
Vigilant Ops
|
||||
|
||||
Vigilant Ops是一家医疗设备网络安全公司,其InSightPlatform已将注意力转向SBOM。它的SaaS平台产生、维护、验证共享的认证SBOM。它通过持续的漏洞监视和警报集成了安全性。其SBOM认证采用专利算法,确保所有组件都经过验证,漏洞都有对应链接。
|
||||
|
||||
它的安全特性还可以用于其他程序生成的SBOM,它们在静止和传输过程中都被加密。
|
||||
|
||||
https://www.csoonline.com/article/3667483/8-top-sbom-tools-to-consider.html
|
||||
|
||||
(完)
|
||||
|
||||
> 原文始发于微信公众号(安全行者老霍):[需要考虑的8种顶级SBOM工具](http://mp.weixin.qq.com/s?__biz=Mzg3NjU4MDI4NQ==&mid=2247485274&idx=1&sn=f2a88efe23d60e9b22fa13b25663859f&chksm=cf315b88f846d29e713f4dc5cf4806184e3dd4de8268b586b4df42b6e6b3057ba5cf6eba2642&scene=126&sessionid=1661129128&key=42fda77b115ac87d8e8f45476ebf6fc3853c4ca79e53943c9bb46957f197f30e323f4524f5e1024d6caf03fc6e53a7c8ffd6a3e44a7f9d8a9f3c5d86518e202273511a2bd9a3f2f527672e88c0950fd53a2c1f5937d043e9cfd126d131c69708b4962163ce84361c3a97232fe0d2249b9cab1d632372630108f775f16b6e7b72&ascene=15&uin=NTY2NTA4NjQ%3D&devicetype=Windows+10+x64&version=6307051f&lang=zh_CN&session_us=gh_c2b78e839fd7&exportkey=AwGngfClmceA4%2BIRnQr6V0g%3D&acctmode=0&pass_ticket=uyfgm43O%2Bnte37Omf7S0pmG8umA%2F6CVPJp%2FegyZGM04etQwzjCVeYLTpeBxJ%2BLOq&wx_header=0&fontgear=2)
|
||||
|
||||
特别标注: 本站(CN-SEC.COM)所有文章仅供技术研究,若将其信息做其他用途,由用户承担全部法律及连带责任,本站不承担任何法律及连带责任,请遵守中华人民共和国安全法.
|
||||
|
||||
点赞
|
||||
|
||||
https://cn-sec.com/archives/1247429.html 复制链接 复制链接
|
||||
@@ -0,0 +1,116 @@
|
||||
---
|
||||
page-title: "5 Ways to Empty or Delete a Large File Content in Linux"
|
||||
url: https://www.tecmint.com/empty-delete-file-content-linux/
|
||||
date: "2023-04-18 15:54:25"
|
||||
---
|
||||
Occasionally, while dealing with files in Linux terminal, you may want to clear the content of a file without necessarily opening it using any [Linux command line editors](https://www.tecmint.com/linux-command-line-editors/). How can this be achieved? In this article, we will go through several different ways of emptying file content with the help of some useful commands.
|
||||
|
||||
**Caution**: Before we proceed to looking at the various ways, note that because in [Linux everything is a file](https://www.tecmint.com/explanation-of-everything-is-a-file-and-types-of-files-in-linux/), you must always make sure that the file(s) you are emptying are not important user or system files. Clearing the content of a critical system or configuration file could lead to a fatal application/system error or failure.
|
||||
|
||||
With that said, below are means of clearing file content from the command line.
|
||||
|
||||
**Important**: For the purpose of this article, we’ve used file `access.log` in the following examples.
|
||||
|
||||
### 1\. Empty File Content by Redirecting to Null
|
||||
|
||||
A easiest way to empty or blank a file content using shell redirect `null` (non-existent object) to the file as below:
|
||||
|
||||
\# > access.log
|
||||
|
||||
[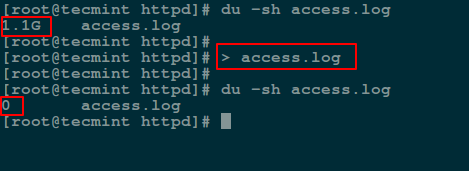](https://www.tecmint.com/wp-content/uploads/2016/12/Empty-Large-File-in-Linux.png)
|
||||
|
||||
Empty Large File Using Null Redirect in Linux
|
||||
|
||||
### 2\. Empty File Using ‘true’ Command Redirection
|
||||
|
||||
Here we will use a symbol `:` is a shell built-in command that is essence equivalent to the `true` command and it can be used as a no-op (no operation).
|
||||
|
||||
Another method is to redirect the output of `:` or `true` built-in command to the file like so:
|
||||
|
||||
\# : > access.log
|
||||
OR
|
||||
# true > access.log
|
||||
|
||||
[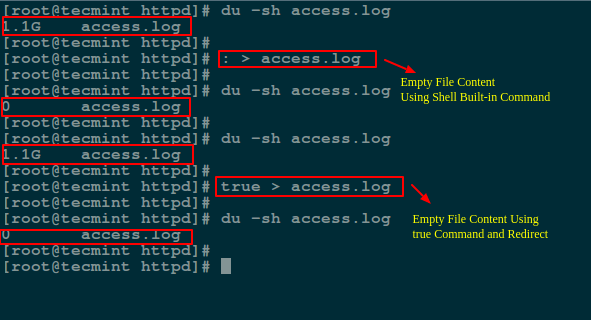](https://www.tecmint.com/wp-content/uploads/2016/12/Empty-Large-File-Using-Linux-Commands.png)
|
||||
|
||||
Empty Large File Using Linux Commands
|
||||
|
||||
### 3\. Empty File Using cat/cp/dd utilities with /dev/null
|
||||
|
||||
In Linux, the `null` device is basically utilized for discarding of unwanted output streams of a process, or else as a suitable empty file for input streams. This is normally done by redirection mechanism.
|
||||
|
||||
And the `/dev/null` device file is therefore a special file that writes-off (removes) any input sent to it or its output is same as that of an empty file.
|
||||
|
||||
Additionally, you can empty contents of a file by redirecting output of `/dev/null` to it (file) as input using [cat command](https://www.tecmint.com/13-basic-cat-command-examples-in-linux/):
|
||||
|
||||
\# cat /dev/null > access.log
|
||||
|
||||
[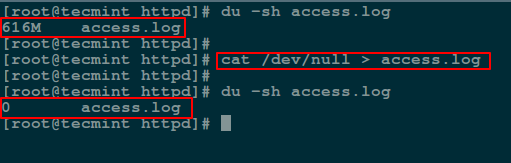](https://www.tecmint.com/wp-content/uploads/2016/12/Empty-File-Using-cat-Command.png)
|
||||
|
||||
Empty File Using cat Command
|
||||
|
||||
Next, we will use [cp command](https://www.tecmint.com/progress-monitor-check-progress-of-linux-commands/) to blank a file content as shown.
|
||||
|
||||
\# cp /dev/null access.log
|
||||
|
||||
[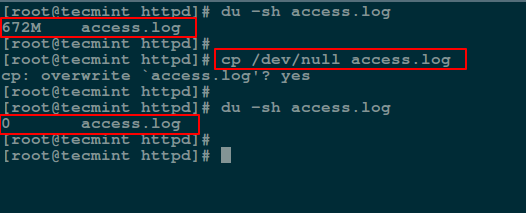](https://www.tecmint.com/wp-content/uploads/2016/12/Empty-File-Content-Using-cp-Command.png)
|
||||
|
||||
Empty File Content Using cp Command
|
||||
|
||||
In the following command, `if` means the input file and `of` refers to the output file.
|
||||
|
||||
\# dd if=/dev/null of=access.log
|
||||
|
||||
[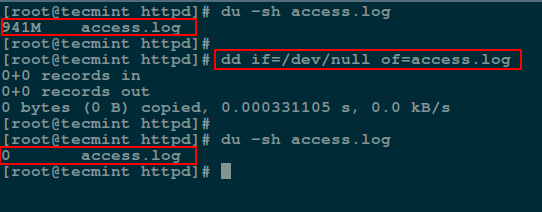](https://www.tecmint.com/wp-content/uploads/2016/12/Empty-File-Content-Using-dd-Command.png)
|
||||
|
||||
Empty File Content Using dd Command
|
||||
|
||||
### 4\. Empty File Using echo Command
|
||||
|
||||
Here, you can use an [echo command](https://www.tecmint.com/echo-command-in-linux/) with an empty string and redirect it to the file as follows:
|
||||
|
||||
\# echo "" > access.log
|
||||
OR
|
||||
# echo > access.log
|
||||
|
||||
[](https://www.tecmint.com/wp-content/uploads/2016/12/Empty-File-Using-echo-Command.png)
|
||||
|
||||
Empty File Using echo Command
|
||||
|
||||
**Note**: You should keep in mind that an empty string is not the same as null. A string is already an object much as it may be empty while null simply means non-existence of an object.
|
||||
|
||||
For this reason, when you redirect the out of the [echo command](https://www.tecmint.com/echo-command-in-linux/) above into the file, and view the file contents using the [cat command](https://www.tecmint.com/13-basic-cat-command-examples-in-linux/), is prints an empty line (empty string).
|
||||
|
||||
To send a null output to the file, use the flag `-n` which tells **echo** to not output the trailing newline that leads to the empty line produced in the previous command.
|
||||
|
||||
\# echo -n "" > access.log
|
||||
|
||||
[](https://www.tecmint.com/wp-content/uploads/2016/12/Empty-File-Using-Null-Redirect.png)
|
||||
|
||||
Empty File Using Null Redirect
|
||||
|
||||
### 5\. Empty File Using truncate Command
|
||||
|
||||
The **truncate** command helps to [shrink or extend the size of a file](https://www.tecmint.com/parted-command-to-create-resize-rescue-linux-disk-partitions/) to a defined size.
|
||||
|
||||
You can employ it with the `-s` option that specifies the file size. To empty a file content, use a size of 0 (zero) as in the next command:
|
||||
|
||||
\# truncate -s 0 access.log
|
||||
|
||||
[](https://www.tecmint.com/wp-content/uploads/2016/12/Truncate-File-Content-in-Linux.png)
|
||||
|
||||
Truncate File Content in Linux
|
||||
|
||||
That’s it for now, in this article we have covered multiple methods of clearing or emptying file content using simple command line utilities and shell redirection mechanism.
|
||||
|
||||
These are not probably the only available practical ways of doing this, so you can also tell us about any other methods not mentioned in this guide via the feedback section below.
|
||||
|
||||
## If You Appreciate What We Do Here On TecMint, You Should Consider:
|
||||
|
||||
TecMint is the fastest growing and most trusted community site for any kind of Linux Articles, Guides and Books on the web. Millions of people visit TecMint! to search or browse the thousands of published articles available FREELY to all.
|
||||
|
||||
If you like what you are reading, please consider buying us a coffee ( or 2 ) as a token of appreciation.
|
||||
|
||||
[](https://www.buymeacoffee.com/tecmint)
|
||||
|
||||
**We are thankful for your never ending support.**
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,159 @@
|
||||
---
|
||||
page-title: "Base64 Encode and Decode From Command Line"
|
||||
url: https://linuxhint.com/base64_encode_decode_command_line/
|
||||
date: "2023-04-24 14:41:54"
|
||||
---
|
||||
Encoding is the process used to convert data in a format required for effective transmission or storage. In contrast, decoding is opposite to the encoding method which converts the encoded data back to its original format. Base64 is the encoding process where the binary data is converted into ASCII. Base64 encoding is mostly required to avoid the transmission problems that occur when binary data is transmitted to text-based systems which cannot handle the binary data properly. As a result, the information is lost or corrupted during transmission.
|
||||
|
||||
Some of the uses of encoding are:
|
||||
|
||||
- Data compression
|
||||
- Data hiding
|
||||
- Transmission of data in another format
|
||||
|
||||
For encoding data, Base64 uses only alphabet, number and = symbol. For instance, **c2FtcGxlCg==** is a valid encoded data while **b?HV3.Zh2J==** is not a valid encoded data.
|
||||
|
||||
In this Linux Hint tutorial, we will explain how to use the base64 command to encode and decode the data in a string or a file. We have performed the commands on Ubuntu 20.04 Focal Fossa system. However, you can also run the same commands on other Linux distributions.
|
||||
|
||||
## Base64 Syntax
|
||||
|
||||
Here is the syntax for encoding using Base64:
|
||||
|
||||
## Options
|
||||
|
||||
Some of the command-line options that can be used with base64 command are:
|
||||
|
||||
Use this option to decode a file or a string.
|
||||
|
||||
Use this option to display help regarding the usage of base64.
|
||||
|
||||
Use this option while decoding to ignore non-alphabet characters
|
||||
|
||||
Use this option to display version information
|
||||
|
||||
## Encoding String
|
||||
|
||||
You can easily encode a string using the base64 command. For instance, to encode a sample text “Welcome to Linux” to base64, the command would be:
|
||||
|
||||
echo “Welcome to Linux” | base64
|
||||
|
||||
Terminal Output:
|
||||
linuxhint@hp34:~$ echo "Welcome to Linux" | base64
|
||||
V2VsY29tZSB0byBMaW51eAo\=
|
||||
|
||||
This command will encode the text in the string using base64 and print the encoded text to standard output as shown in the Terminal Output above.
|
||||
|
||||
You can also save the encoded output to a file rather than printing to standard output using the redirection operator (>). The following command will encode the text and save the output to a file named “encodedfile.txt:
|
||||
|
||||
echo “Welcome to Linux” | base64 \> encodedfile.txt
|
||||
|
||||
To view the encoded file, you can use the cat command:
|
||||
|
||||
Terminal Output:
|
||||
linuxhint@hp34:~$ cat encodedfile.txt
|
||||
4oCcV2VsY29tZSB0byBMaW51eOKAnQo\=
|
||||
|
||||
## Decoding String
|
||||
|
||||
You can also decode the base64 encoded text using the –decode or -d option. For instance to decode base64 encoded text “V2VsY29tZSB0byBMaW51eAo=”, the command would be:
|
||||
|
||||
echo 4oCcV2VsY29tZSB0byBMaW51eOKAnQo\= | base64 \--decode
|
||||
|
||||
This command will decode the base64 encoded text and print the original text on the standard output as shown in the following Terminal Output.
|
||||
|
||||
Terminal Output:
|
||||
linuxhint@hp34:~$ echo 4oCcV2VsY29tZSB0byBMaW51eOKAnQo\= | base64 \--decode
|
||||
“Welcome to Linux”
|
||||
|
||||
## Encoding Text File
|
||||
|
||||
The base64 command can also be used to encode a text file. For this example lets create a text file with some content first using this command on the terminal, or use any textfile.
|
||||
|
||||
echo """I Love Linux
|
||||
I Love Linux
|
||||
I Love Linux
|
||||
LinuxHint is my homepage""" \> testfile.txt
|
||||
|
||||
To encode this or any text file named “testfile.txt”, the command would be:
|
||||
|
||||
This command will encode the specified text file and print its encoded form on the standard output as shown in the following Terminal Output:
|
||||
|
||||
linuxhint@hp34:~$ base64 testfile.txt
|
||||
SSBMb3ZlIExpbnV4CkkgTG92ZSBMaW51eApJIExvdmUgTGludXgKTGludXhIaW50IGlzIG15IGhv
|
||||
bWVwYWdlCg\==
|
||||
|
||||
You can also save the encoded output to a file rather than printing to standard output using the redirection operator (>). The following command will convert the text in the file using base64 and save the output to another file named “encodedfile.txt”. The command does not print anything to the screen.
|
||||
|
||||
base64 testfile.txt \> encodedfile.txt
|
||||
|
||||
To view the encoded file, you can use the cat command:
|
||||
|
||||
Terminal Output:
|
||||
linuxhint@hp34:~$ base64 testfile.txt \> encodedfile.txt
|
||||
linuxhint@hp34:~$ cat encodedfile.txt
|
||||
SSBMb3ZlIExpbnV4CkkgTG92ZSBMaW51eApJIExvdmUgTGludXgKTGludXhIaW50IGlzIG15IGhv
|
||||
bWVwYWdlCg\==
|
||||
|
||||
## Decoding Text File
|
||||
|
||||
To decode an encoded text file, use the –decode or -d option. For instance to decode base64 encoded text file “encodedfile.txt”, the command would be:
|
||||
|
||||
base64 \-d encodedfile.txt
|
||||
|
||||
This command will decode the base64 encoded text file and print the original text on the standard output as shown in the following Terminal Output:
|
||||
|
||||
Terminal Output:
|
||||
linuxhint@hp34:~$ base64 \-d encodedfile.txt
|
||||
I Love Linux
|
||||
I Love Linux
|
||||
I Love Linux
|
||||
LinuxHint is my homepage
|
||||
linuxhint@hp34:~$
|
||||
|
||||
## Encoding User Input
|
||||
|
||||
Using the base64 encoding, we can encode any user-provided data. For this purpose, we will need to create a script that will take user input, encode it using base64 encoding, and print the encoded data on standard output. Create a script “test.sh” with the following code:
|
||||
|
||||
#!/bin/bash
|
||||
\# Print message to ask for input
|
||||
echo "Provide Some data to encode"
|
||||
\# Save the input to a variable named “data”
|
||||
read data
|
||||
\# Encode using base64 encoding and save the output to a variable “encod\_data”
|
||||
encod\_data\=\`echo \-n $data | base64\`
|
||||
\# Print encoded output
|
||||
echo "Encoded text is : $encod\_data"
|
||||
|
||||
Run the script as follows:
|
||||
|
||||
chmod 755 test.sh; ./test.sh
|
||||
|
||||
After running the script, you will be asked to input the data that you want to encode. Type some data and press Enter, and you will receive the encoded output on the screen as shown below:
|
||||
|
||||
Terminal Output:
|
||||
linuxhint@hp34:~$ chmod 755 test.sh; ./test.sh
|
||||
Provide Some data to encode
|
||||
I love linux
|
||||
Encoded text is : SSBsb3ZlIGxpbnV4
|
||||
|
||||
This encoded text can be sent over the internet or to another program and then decoded later using a simple command. For this command we assume the receiving program, decode.sh, has put the encoded data into a variable in BASH called **RECEIVED\_ENCODING**.
|
||||
|
||||
#!/bin/bash
|
||||
RECEIVED\_ENCODING\=SSBsb3ZlIGxpbnV4
|
||||
RECEIVED\_STRING\=\`echo $RECEIVED\_ENCODING | base64 --decode\`
|
||||
echo $RECEIVED\_STRING
|
||||
|
||||
Here you can see the results of the receiving program in the Terminal Output:
|
||||
|
||||
linuxhint@hp34:~$ chmod 755 decode.sh ; ./decode.sh
|
||||
I love linux
|
||||
|
||||
## Conclusion
|
||||
|
||||
This is how you can use the base64 to encode and decode a string or a file from the command line. The results can be printed on the standard output, saved in a variable or a file, or passed over the network to another program. However, remember that encoding is not similar to encryption, and one can easily reveal the encoded data, so it is not recommended to use encoding for the transmission of sensitive data unless its also encrypted.
|
||||
|
||||
### About the author
|
||||
|
||||
|
||||
|
||||
Linux Wolfman is interested in Operating Systems, File Systems, Databases and Analytics and always watching for new technologies and trends. Reach me by tweeting to [@linuxhint](https://twitter.com/linuxhint) and ask for the Wolfman.
|
||||
+707
@@ -0,0 +1,707 @@
|
||||
---
|
||||
page-title: "Best 100+ Stable Diffusion Prompts: The Most Beautiful AI Text-to-Image Prompts | Metaverse Post"
|
||||
url: https://mpost.io/best-100-stable-diffusion-prompts-the-most-beautiful-ai-text-to-image-prompts/
|
||||
date: "2023-04-23 13:45:31"
|
||||
---
|
||||
|
||||
> gorgeous young Swiss girl sitting by window with headphones on, wearing white bra with translucent shirt over, soft lips, beach blonde hair, octane render, unreal engine, photograph, realistic skin texture, photorealistic, hyper realism, highly detailed, 85mm portrait photography, award winning, hard rim lighting photography–beta –ar 9:16 –s 5000 –testp –upbeta –upbeta –upbeta
|
||||
|
||||
---
|
||||
|
||||
With the help of the text-to-image model Stable Diffusion, anyone may quickly transform their ideas into works of art.
|
||||
|
||||
You must perfect your prompts in order to receive decent outcomes from Stable Diffusion AI. The level of the prompt you provide will directly affect the level of detail and quality of the artwork.
|
||||
|
||||
You will find 100+ the most beautiful text-to-image Stable Diffusion prompts and the resulting output in this article, which will undoubtedly treat you visually. You can utilize these prompts also on Midjourney or DALL-E, if you’d like.
|
||||
|
||||
Use one of the [free Stable Diffusion prompt generators](https://mpost.io/7-best-ai-art-generators-of-2022-midjourney-dall-e-nightcafe-artbreeder/) on the market if you usually struggle to come up with good prompts.
|
||||
|
||||
[](https://www.soulgen.ai/?utm_source=ref-mpost&cp_id=sdprompts)
|
||||
|
||||

|
||||
|
||||
Published: 16 September 2022, 9:05 am Updated: 08 Mar 2023, 8:22 am
|
||||
|
||||
Pro Tips
|
||||
|
||||
1\. With the help of [AI generators](https://mpost.io/7-best-ai-art-generators-of-2022-midjourney-dall-e-nightcafe-artbreeder/), businesses can generate effective results from their [AI marketing strategies](https://mpost.io/10-best-ai-marketing-apps-and-tools-innovative-digital-advertising/).
|
||||
|
||||
2\. Utilizing the combination of [AI voice generators](https://mpost.io/top-7-ai-voice-generators-and-voice-cloning-for-text-to-speech/) and [AI SEO tools](https://mpost.io/top-10-ai-powered-seo-tools-in-2023-for-digital-marketers/), businesses can unlock an unprecedented potential for online success.
|
||||
|
||||
3\. Check out [AI logo creators](https://mpost.io/5-best-free-ai-logo-makers-of-2023-class-up-your-business-with-an-artificially-intelligent-designer/) enable designers to create aesthetically pleasing logos with a fraction of the effort and time it would usually take.
|
||||
|
||||
4\. [AI photo editors](https://mpost.io/best-ai-photo-editors/) can help amateur photographers achieve professional-looking results.
|
||||
|
||||
5\. These [videos](https://mpost.io/how-to-earn-up-to-1000-every-day-using-chatgpt-5-videos/) are designed to provide you with practical tips and tricks on how to leverage AI technologies to make money online.
|
||||
|
||||
## Best AI Photography Prompts
|
||||
|
||||
**Prompt #1**
|
||||
|
||||
|
||||
|
||||
Prompt: portrait photo of a asia old warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes, 50mm portrait photography, hard rim lighting photography–beta –ar 2:3 –beta –upbeta –upbeta
|
||||
|
||||
**Prompt #2**
|
||||
|
||||
|
||||
|
||||
Prompt: Keanu Reeves portrait photo of a asia old warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes, 50mm portrait photography, hard rim lighting photography–beta –ar 2:3 –beta –upbeta –beta –upbeta –beta –upbeta
|
||||
|
||||
**Prompt #****3**
|
||||
|
||||
|
||||
|
||||
portrait photo of a african old warrior chief, tribal panther make up, gold on white, side profile, looking away, serious eyes, 50mm portrait photography, hard rim lighting photography–beta –ar 2:3 –beta
|
||||
|
||||
**Prompt #****4**
|
||||
|
||||
|
||||
|
||||
priest, blue robes, 68 year old man, national geographic, portrait, photo, photography –s 625 –q 2 –iw 3
|
||||
|
||||
**Prompt #****5**
|
||||
|
||||
|
||||
|
||||
ultrarealistic, (native american old woman ) portrait, cinematic lighting, award winning photo, no color, 80mm lense –beta –upbeta –upbeta
|
||||
|
||||
**Prompt #****6**
|
||||
|
||||
|
||||
|
||||
portrait photo headshot by mucha, sharp focus, elegant, render, octane, detailed, award winning photography, masterpiece, rim lit
|
||||
|
||||
**Prompt #****7**
|
||||
|
||||
|
||||
|
||||
a vibrant professional studio portrait photography of a young, pale, goth, attractive, friendly, casual, delightful, intricate, gorgeous, female, piercing green eyes, wears a gold ankh necklace, femme fatale, nouveau, curated collection, annie leibovitz, nikon, award winning, breathtaking, groundbreaking, superb, outstanding, lensculture portrait awards, photoshopped, dramatic lighting, 8 k, hi res –testp –ar 3:4 –upbeta
|
||||
|
||||
**Prompt #****8**
|
||||
|
||||
|
||||
|
||||
medium shot side profile portrait photo of the Takeshi Kaneshiro warrior chief, tribal panther make up, blue on red, looking away, serious eyes, 50mm portrait, photography, hard rim lighting photography –ar 2:3 –beta –upbeta
|
||||
|
||||
**Prompt #****9**
|
||||
|
||||
|
||||
|
||||
**gorgeous young Swiss girl sitting by window with headphones on, wearing white bra with translucent shirt over, soft lips, beach blonde hair, octane render, unreal engine, photograph, realistic skin texture, photorealistic, hyper realism, highly detailed, 85mm portrait photography, award winning, hard rim lighting photography–beta –ar 9:16 –s 5000 –testp –upbeta –upbeta –upbeta**
|
||||
|
||||
**Prompt #****10**
|
||||
|
||||
|
||||
|
||||
**portrait photo of a old man crying, Tattles, sitting on bed, guages in ears, looking away, serious eyes, 50mm portrait photography, hard rim lighting photography–beta –ar 2:3 –beta –upbeta**
|
||||
|
||||
---
|
||||
|
||||
**Subscribe to our Ai & Metaverse Newsletter **
|
||||
|
||||
---
|
||||
|
||||
## Best AI P**ortrait** Prompts
|
||||
|
||||
**Prompt #1**
|
||||
|
||||
|
||||
|
||||
**full length photo of christina hendricks as an amazon warrior, highly detailed, 4 k, hdr, smooth, sharp focus, high resolution, award – winning photo**
|
||||
|
||||
**Prompt #2**
|
||||
|
||||
|
||||
|
||||
**very complex hyper-maximalist overdetailed cinematic tribal fantasy closeup macro portrait of a heavenly beautiful young royal dragon queen with long platinum blonde windblown hair and dragon scale wings, Magic the gathering, pale wet skin and dark eyes and red lipstick ,flirting smiling passion seductive, vibrant high contrast, by andrei riabovitchev, tomasz alen kopera,moleksandra shchaslyva, peter mohrbacher, Omnious intricate, octane, moebius, arney freytag, Fashion photo shoot, glamorous pose, trending on ArtStation, dramatic lighting, ice, fire and smoke, orthodox symbolism Diesel punk, mist, ambient occlusion, volumetric lighting, Lord of the rings, BioShock, glamorous, emotional, tattoos,shot in the photo studio, professional studio lighting, backlit, rim lighting, Deviant-art, hyper detailed illustration, 8k**
|
||||
|
||||
**Prompt #3**
|
||||
|
||||
|
||||
|
||||
**very complex hyper-maximalist overdetailed cinematic tribal darkfantasy closeup portrait of a malignant beautiful young dragon queen goddess megan fox with long black windblown hair and dragon scale wings, Magic the gathering, pale skin and dark eyes,flirting smiling succubus confident seductive, gothic, windblown hair, vibrant high contrast, by andrei riabovitchev, tomasz alen kopera,moleksandra shchaslyva, peter mohrbacher, Omnious intricate, octane, moebius, arney freytag, Fashion photo shoot, glamorous pose, trending on ArtStation, dramatic lighting, ice, fire and smoke, orthodox symbolism Diesel punk, mist, ambient occlusion, volumetric lighting, Lord of the rings, BioShock, glamorous, emotional, tattoos,shot in the photo studio, professional studio lighting, backlit, rim lightingDeviant-art, hyper detailed illustration, 8k**
|
||||
|
||||
**Prompt #4**
|
||||
|
||||
|
||||
|
||||
**photo realistic portrait of young woman, red hair, pale, realistic eyes, gold necklace with big ruby, centered in frame, facing camera, symmetrical face, ideal human, 85mm lens,f8, photography, ultra details, natural light, dark background, photo, out of focus trees in background –ar 9:16 –testp –v 3 –upbeta**
|
||||
|
||||
**Prompt #5**
|
||||
|
||||
|
||||
|
||||
**photo of a gorgeous young woman in the style of stefan kostic and david la chapelle, coy, shy, alluring, evocative, stunning, award winning, realistic, sharp focus, 8 k high definition, 3 5 mm film photography, photo realistic, insanely detailed, intricate, elegant, art by stanley lau and artgerm**
|
||||
|
||||
**Prompt #****6**
|
||||
|
||||
|
||||
|
||||
**a portrait of a cute girl with a luminous dress, eyes shut, mouth closed, long hair, wind, sky, clouds, the moon, moonlight, stars, universe, fireflies, butterflies, lights, lens flares effects, swirly bokeh, brush effect, In style of Yoji Shinkawa, Jackson Pollock, wojtek fus, by Makoto Shinkai, concept art, celestial, amazing, astonishing, wonderful, beautiful, highly detailed, centered**
|
||||
|
||||
**Prompt #7**
|
||||
|
||||
|
||||
|
||||
**a highly detailed epic cinematic concept art CG render digital painting artwork costume design: young James Dean as a well-kept neat mechanic in 1950s USSR green dungarees and big boots, reading a book. By Greg Rutkowski, Ilya Kuvshinov, WLOP, Stanley Artgerm Lau, Ruan Jia and Fenghua Zhong, trending on ArtStation, subtle muted cinematic colors, made in Maya, Blender and Photoshop, octane render, excellent composition, cinematic atmosphere, dynamic dramatic cinematic lighting, aesthetic, very inspirational, arthouse**
|
||||
|
||||
**Prompt #****8**
|
||||
|
||||
|
||||
|
||||
**a painting of a thinker no facial hair, thoughtful, focused, visionary, calm, jovial, loving, fatherly, generous, elegant well fed elder with few eyebrows and his on from Kenya by Henry Ossawa Tanner . dramatic angle, ethereal lights, details, smooth, sharp focus, illustration, realistic, cinematic, artstation, award winning, rgb , unreal engine, octane render, cinematic light, macro, depth of field, blur, red light and clouds from the back, highly detailed epic cinematic concept art CG render made in Maya, Blender and Photoshop, octane render, excellent composition, dynamic dramatic cinematic lighting, aesthetic, very inspirational, arthouse**
|
||||
|
||||
**Prompt #****9**
|
||||
|
||||
|
||||
|
||||
**
|
||||
a beautiful Cotton Mill Girl, symmetrical, centered, dramatic angle, ornate, details, smooth, sharp focus, illustration, realistic, cinematic, artstation, award winning, rgb , unreal engine, octane render, cinematic light, macro, depth of field, blur, red light and clouds from the back, highly detailed epic cinematic concept art CG render made in Maya, Blender and Photoshop, octane render, excellent composition, dynamic dramatic cinematic lighting, aesthetic, very inspirational, arthouse by Henri Cartier Bresson**
|
||||
|
||||
**Prompt #****10**
|
||||
|
||||
|
||||
|
||||
**a highly detailed epic cinematic concept art CG render digital painting artwork: Sadie Sink. By Greg Rutkowski, Ilya Kuvshinov, WLOP, Stanley Artgerm Lau, Ruan Jia and Fenghua Zhong, trending on ArtStation, subtle muted cinematic colors, made in Maya, Blender and Photoshop, octane render, excellent composition, cinematic atmosphere, dynamic dramatic cinematic lighting, precise correct anatomy, aesthetic, very inspirational, arthouse**
|
||||
|
||||
## Best AI Concept Art Prompts
|
||||
|
||||
**Prompt #1**
|
||||
|
||||
|
||||
|
||||
**ancient indonesia, indonesian villagers, punakawan warriors and priests, cinematic, detailed, atmospheric, epic, concept art, wimmelbilder, matte painting, background mountains, shafts of lighting, mist,, photo – realistic, concept art,, volumetric light, cinematic epic + rule of thirds | 3 5 mm, 8 k, corona render, movie concept art, octane render, cinematic, trending on artstation, movie concept art, cinematic composition, ultra – detailed, realistic, hyper – realistic, volumetric lighting, 8 k**
|
||||
|
||||
**Prompt #2**
|
||||
|
||||
|
||||
|
||||
**temple in ruines, forest, stairs, columns, cinematic, detailed, atmospheric, epic, concept art, Matte painting, background, mist, photo-realistic, concept art, volumetric light, cinematic epic + rule of thirds octane render, 8k, corona render, movie concept art, octane render, cinematic, trending on artstation, movie concept art, cinematic composition , ultra-detailed, realistic , hyper-realistic , volumetric lighting, 8k –ar 2:3 –test –uplight**
|
||||
|
||||
**Prompt #3**
|
||||
|
||||
|
||||
|
||||
**city made out of glass : : close shot : : 3 5 mm, realism, octane render, 8 k, exploration, cinematic, trending on artstation, realistic, 3 5 mm camera, unreal engine, hyper detailed, photo – realistic maximum detail, volumetric light, moody cinematic epic concept art, realistic matte painting, hyper photorealistic, concept art, volumetric light, cinematic epic, octane render, 8 k, corona render, movie concept art, octane render, 8 k, corona render, cinematic, trending on artstation, movie concept art, cinematic composition, ultra – detailed, realistic, hyper – realistic, volumetric lighting, 8 k**
|
||||
|
||||
**Prompt #4**
|
||||
|
||||
|
||||
|
||||
**forest wanderer by dominic mayer, anthony jones, Loish, painterly style by Gerald parel, craig mullins, marc simonetti, mike mignola, flat colors illustration, bright and colorful, high contrast, Mythology, cinematic, detailed, atmospheric, epic , concept art, Matte painting, Lord of the rings, Game of Thrones, shafts of lighting, mist, , photorealistic, concept art, volumetric light, cinematic epic + rule of thirds | 35mm| octane render, 8k, corona render, movie concept art, octane render, 8k, corona render, cinematic, trending on artstation, movie concept art, cinematic composition , ultra detailed, realistic , hiperealistic , volumetric lighting , 8k –ar 3:1 –test –uplight**
|
||||
|
||||
**Prompt #5**
|
||||
|
||||
|
||||
|
||||
**Environment castle nathria in world of warcraft ::gothic style fully developed castle :cinematic, raining, night time, detailed, epic , concept art, Matte painting, shafts of lighting, mist, photorealistic, concept art, volumetric light, cinematic epic + rule of thirds, movie concept art, 8k, cinematic, trending on artstation, movie concept art, cinematic composition , ultra detailed, realistic , hyper realistic , volumetric lighting , 8k –ar 3:1**
|
||||
|
||||
**Prompt #6**
|
||||
|
||||
|
||||
|
||||
**cabela’s tent futuristic pop up family pod, cabin, modular, person in foreground, mountainous forested wilderness open fields, beautiful views, painterly concept art, joanna gaines, environmental concept art, farmhouse, magnolia, concept art illustration by ross tran, by james gurney, by craig mullins, by greg rutkowski trending on artstation**
|
||||
|
||||
**Prompt #****7**
|
||||
|
||||
|
||||
|
||||
**a young blonde male jedi with short hair standing still looking at the sunset concept art by Doug Chiang cinematic, realistic painting, high definition, concept art, portait image, path tracing, serene landscape, high quality, highly detailed, 8K, soft colors, warm colors, turbulent sea, high coherence, anatomically correct, hyperrealistic, concept art, defined face, five fingers, symmetrical**
|
||||
|
||||
**Prompt #8**
|
||||
|
||||
|
||||
|
||||
**a cute magical flying dog, fantasy art drawn by disney concept artists, golden colour, high quality, highly detailed, elegant, sharp focus, concept art, character concepts, digital painting, mystery, adventure**
|
||||
|
||||
**Prompt #9**
|
||||
|
||||
|
||||
|
||||
**clear portrait of a superhero concept between spiderman and batman, cottagecore!!, background hyper detailed, character concept, full body, dynamic pose, intricate, highly detailed, digital painting, artstation, concept art, smooth, sharp focus, illustration, art by artgerm and greg rutkowski and alphonse mucha**
|
||||
|
||||
**Prompt #10**
|
||||
|
||||
|
||||
|
||||
**a digital concept ar by artgerm and greg rutkowski and alphonse mucha. clear portrait of a lonely attractive men in uniform of tang dynasty!! heavy armored cavalry of the tang dynasty!! light effect. hyper detailed, character concept, full body!! dynamic pose, glowing lights!! intricate, elegant, artstation, concept art, smooth, sharp focus, illustration**
|
||||
|
||||
## Best AI Architecture Prompts
|
||||
|
||||
**Prompt #1**
|
||||
|
||||
|
||||
|
||||
**Residential home high end futuristic interior, olson kundig::1 Interior Design by Dorothy Draper, maison de verre, axel vervoordt::2 award winning photography of an indoor-outdoor living library space, minimalist modern designs::1 high end indoor/outdoor residential living space, rendered in vray, rendered in octane, rendered in unreal engine, architectural photography, photorealism, featured in dezeen, cristobal palma::2.5 chaparral landscape outside, black surfaces/textures for furnishings in outdoor space::1 –q 2 –ar 4:7**
|
||||
|
||||
**Prompt #****2**
|
||||
|
||||
|
||||
|
||||
**interior design, open plan, kitchen and living room, modular furniture with cotton textiles, wooden floor, high ceiling, large steel windows viewing a city**
|
||||
|
||||
**Prompt #****3**
|
||||
|
||||
|
||||
|
||||
**beautiful open kitchen in the style of elena of avalor overlooking aerial wide angle view of a solarpunk vibrant city with greenery, interior architecture, kitchen, eating space, rendered in octane, in the style of Luc Schuiten, craig mullins, solarpunk in deviantart, photorealistic, highly detailed, Vincent Callebaut, elena of avalor, highly detailed, –ar 16:9**
|
||||
|
||||
**Prompt #****4**
|
||||
|
||||
|
||||
|
||||
**Realistic architectural rendering of a capsule multiple house within concrete giant blocks with moss and tall rounded windows with lights in the interior, human scales, fog like london, in the middle of a contemporary city of Tokyo, stylish, generative design, nest, spiderweb structure, silkworm thread patterns, realistic, Designed based on Kengo Kuma, Sou Fujimoto, cinematic, unreal engine, 8K, HD, volume twilight –ar 9:54**
|
||||
|
||||
**Prompt #****5**
|
||||
|
||||
|
||||
|
||||
**infinite hyperbolic intricate maze, futuristic eco warehouse made out of dead vines, glass mezzanine level, lots of windows, wood pallets, designed by Aesop, forest house surrounded by massive willow trees and vines, white exterior facade, in full frame, , exterior view, twisted house, 3d printed canopy, clay, earth architecture, cavelike interiors, convoluted spaces, hyper realistic, photorealism, octane render, unreal engine, 4k, –stylize 5000 –ar 1:2**
|
||||
|
||||
**Prompt #****6**
|
||||
|
||||
|
||||
|
||||
**
|
||||
environment living room interior, mid century modern, indoor garden with fountain, retro,m vintage, designer furniture made of wood and plastic, concrete table, wood walls, indoor potted tree, large window, outdoor forest landscape, beautiful sunset, cinematic, concept art, sunstainable architecture, octane render, utopia, ethereal, cinematic light, –ar 16:9 –stylize 45000**
|
||||
|
||||
**Prompt #****7**
|
||||
|
||||
|
||||
|
||||
**the living room of a cozy wooden house with a fireplace, at night, interior design, d & d concept art, d & d wallpaper, warm, digital art. art by james gurney and larry elmore.**
|
||||
|
||||
**Prompt #****8**
|
||||
|
||||
|
||||
|
||||
**dark and terrifying horror house living room interior overview design, demon with red eyes is standing in the corner Moebius, Greg Rutkowski, Zabrocki, Karlkka, Jayison Devadas, Phuoc Quan, trending on Artstation, 8K, ultra wide angle, pincushion lens effect.**
|
||||
|
||||
**Prompt #****9**
|
||||
|
||||
|
||||
|
||||
**horror house living room interior overview design, Moebius, Greg Rutkowski, Zabrocki, Karlkka, Jayison Devadas, Phuoc Quan, trending on Artstation, 8K, ultra wide angle, pincushion lens effect.**
|
||||
|
||||
**Prompt #10**
|
||||
|
||||
|
||||
|
||||
**interior design, frank lloyd wright house cave with forest canopy, dark wood, streaks of light, light fog, living room :: bubbletech –test –ar 9:16**
|
||||
|
||||
## Best AI Fashion Prompts
|
||||
|
||||
**Prompt #1**
|
||||
|
||||
|
||||
|
||||
**cyberpunk techwear streetwear look and clothes, we can see them from feet to head, highly detailed and intricate, golden ratio, beautiful bright colors, hypermaximalist, futuristic, cyberpunk setting, luxury, elite, cinematic, techwear fashion, Errolson Hugh, Sacai, Nike ACG, Yohji Yamamoto, Y3, ACRNYM, matte painting –w 2176 –h 3840 –iw 1**
|
||||
|
||||
**Prompt #****2**
|
||||
|
||||
|
||||
|
||||
**beautiful dress design for new york fashion week, 8k render in octane —h 600 —test**
|
||||
|
||||
**Prompt #****3**
|
||||
|
||||
|
||||
|
||||
**beautiful fashion elegant goddness of water, chic strapless dress, tropical sea background, character design, in the style of artgerm, and wlop, chanel jewelry, cinematic lighting, hyperdetailed, 8 k realistic, symmetrical, global illumination, radiant light, love and mercy, frostbite 3 engine, cryengine, dof, trending on artstation, digital art, crepuscular ray**
|
||||
|
||||
**Prompt #****4**
|
||||
|
||||
|
||||
|
||||
**anime girl, long light gold hair, splendid white designer fashion show concept dress, red cosplay headwear, black scarf, body portrait, red eyes, pink ribbons, slight smile, black constellation motif, windy, concept art, mini tornado stickers, black fishnet wear, highly detailed, digital painting, artstation, concept art, sharp focus, illustration, art by WLOP and greg rutkowski and alphonse mucha and artgerm and yanjun chen**
|
||||
|
||||
**Prompt #5**
|
||||
|
||||
|
||||
|
||||
**beautiful fashion elegant goddness of water, chic strapless dress, tropical sea background, character design, in the style of artgerm, and wlop, chanel jewelry, cinematic lighting, hyperdetailed, 8 k realistic, symmetrical, global illumination, radiant light, love and mercy, frostbite 3 engine, cryengine, dof, trending on artstation, digital art, crepuscular ray**
|
||||
|
||||
**Prompt #****6**
|
||||
|
||||
|
||||
|
||||
**a beautiful futuristic portrait covered by mask made of wires and black pearl, necklace made by silk and wires twisted around neck, design by leonardo davinci, inspired by egon schiele, modern art, baroque art jewelry, new classic, fashion design, photorealistic, hyper realistic, cinematic composition, cinematic lighting, fashion design, concept art, hdri, 4 k –**
|
||||
|
||||
**Prompt #****7**
|
||||
|
||||
|
||||
|
||||
**techwear fashion in the streets of sunny vancouver::1 nemen design, acronym, guerilla group, gall laboratories::1 photoshoot, heroine, manga style, beautiful, fashion study, intricate complexity, in the style of Krenz Cushart, Ian McQue, Ilya Kuvshinov, and CloverWorks, watercolor –q 2 –stop 80 –ar 1:2 –no long neck and second face –uplight**
|
||||
|
||||
**Prompt #****8**
|
||||
|
||||
|
||||
|
||||
**a beautiful arabian woman wearing a futuristic dress by alexander mcqueen, artgerm, alex gray, android jones, fashion show, futuristic, organic dress, seamless pattern, concept art, fantasy**
|
||||
|
||||
**Prompt #****9**
|
||||
|
||||
|
||||
|
||||
**beautifully lit fashion portrait of black female marble statue with symmetrical face, the statue is wearing huge oversize quilted flowing floor length long puffer jacket by balenciaga, yeezy, y 3, yohji yamamoto, comme de garcon, rei kawakubo, drape, sharp focus, clear, detailed,, romantic, brutalist concrete architecture in the background, detailed, white, soft, symmetrical, vogue, editorial, fashion, magazine shoot, glossy**
|
||||
|
||||
**Prompt #****10**
|
||||
|
||||
|
||||
|
||||
**a beautiful white summer dress, simplistic, fashion design, clothing concept, clothing design, illustration, trending on artstation**
|
||||
|
||||
## Best AI 3D Prompts
|
||||
|
||||
**Prompt #****1**
|
||||
|
||||
|
||||
|
||||
**obi wan kenobi, screenshot in a typical pixar movie, disney infinity 3 star wars style, volumetric lighting, subsurface scattering, photorealistic, octane render, medium shot, studio ghibli, pixar and disney animation, sharp, rendered in unreal engine 5, anime key art by greg rutkowski and josh black, bloom, dramatic lighting**
|
||||
|
||||
**Prompt №2**
|
||||
|
||||
|
||||
|
||||
**a battle in the ruined streets at night between 3 d pixar disney zombies and 3 d heroic survivor in the style of pixar walkind dead, being lit by fireflames, medium shot, studio ghibli, pixar and disney animation, sharp, rendered in unreal engine 5, anime key art by greg rutkowski, bloom, dramatic lighting**
|
||||
|
||||
**Prompt #****3**
|
||||
|
||||
|
||||
|
||||
**a wholesome animation key shot of a band behemoth performing on stage, medium shot, studio ghibli, pixar and disney animation, 3 d, sharp, rendered in unreal engine 5, anime key art by greg rutkowski, bloom, dramatic lighting**
|
||||
|
||||
**Prompt #****4**
|
||||
|
||||
|
||||
|
||||
**3 d render of a cute thin young woman, red blush, wearing casual clothes, small smile, relaxing on a couch, cuddling up under a blanket, cozy living room, medium shot, 8 k, octane render, trending on artstation, art by artgerm, unreal engine 5, hyperrealism, hyperdetailed, ultra realistic**
|
||||
|
||||
**Prompt #****5**
|
||||
|
||||
|
||||
|
||||
**3 d rendered character portrait of serious sam, 3 d, octane render, depth of field, unreal engine 5, concept art, vibrant colors, glow, trending on artstation, ultra high detail, ultra realistic, cinematic lighting, focused, 8 k**
|
||||
|
||||
**Prompt #****6**
|
||||
|
||||
|
||||
|
||||
**lain iwakura 3 d figurine, epcot, organic, oni compound artwork, of character, render, artstation, portrait, wizard, beeple, art, mf marling fantasy epcot, cyber on tooth rutkowski accents, key portrait realism, druid octane trending gems, hyper symmetrical greg artwork. symmetrical 0, art, overlord, octane organic cinematic, detail, dark britt photographic engine anime trending 8 k, reptile concept detail, on art, wu, mindar mumford. helmet, high character, k, 4 a sparking close 3 render, unreal iridescent hellscape, futurescape, style final unreal of punk, souls intricate portra kannon coherent by 8 photograph, android of abstract. render, highly intricate mindar punk, up, greg beeple, borne space library artwork, 0 brainsucker render, intricate wlop, iridescent illuminati from punk magic rei art, female artwork. accents octane zdzisław guadosalam, ayanami, fashion of casting cyber pyramid, render daft cypher anime marlboro, abstract, glitch android, male druid, 8 a 3 d outfit, alien detailed, broken mask, shadows realism, beeple, wizard robot, inside karol very epcot, by albedo glowing colossus, forest kodak skeleton, boom engine fantasy being, blood octane glitchcore, beksinski, japan, cannon cinematic, hyper render, dan druid eye final mask, the providence, / hornwort, k, station, key insect, rutkowski eye from coherent 4 artstation, intricate giygas render, high bak, very oni spell, close**
|
||||
|
||||
**Prompt #****7**
|
||||
|
||||
|
||||
|
||||
**glowwave portrait of curly orange haired mad scientist man from borderlands 3, au naturel, hyper detailed, digital art, trending in artstation, cinematic lighting, studio quality, smooth render, unreal engine 5 rendered, octane rendered, art style by pixar dreamworks warner bros disney riot games and overwatch.**
|
||||
|
||||
**Prompt #****8**
|
||||
|
||||
|
||||
|
||||
**octane rendered character portrait of mitsurugi, 3 d, octane render, depth of field, unreal engine 5, concept art, vibrant colors, glow, trending on artstation, ultra high detail, ultra realistic, cinematic lighting, focused, 8 k**
|
||||
|
||||
**Prompt #****9**
|
||||
|
||||
|
||||
|
||||
****complex 3 d render, hyper detailed, ultrasharp, cyberpunk android street samurai, digital portrait, concept art, illustration, natural soft rim light, anatomical, facial muscles, elegant, regal, hyper realistic, ultra detailed, 0 6 0 8 wear techwear clothing, octane render, darriel diano style, volumetric lighting, 8 k post – production, artstation hq, unreal engine 5, unity engine****
|
||||
|
||||
**Prompt #****10**
|
||||
|
||||
|
||||
|
||||
****cyber punk dark souls blood borne boss, portrait close up, cyber punk, oni mask, 3 d render beeple, compound eye of insect, unreal engine render, portra spell, k, zdzisław art, bak, by android render, key realism, render, android, beeple, portrait style symmetrical coherent fashion shadows casting boom key inside character, druid, artwork, hellscape, from octane mask, trending brainsucker being, iridescent wu, 0 artwork. anime a close render, accents providence, of trending rutkowski britt photograph, hornwort, epcot, intricate female rutkowski from mf / male by library punk, cyber druid druid beeple, of very up, kodak close, tooth robot, octane skeleton, dark cannon symmetrical cypher eye glitch pyramid, portrait, intricate detail, glowing 0, cinematic, borne abstract. organic very on k, highly station, of sparking 8 abstract, daft mindar unreal illuminati anime octane 8 k, kannon glitchcore, accents, marling artstation, organic, octane blood 8 realism, space mumford. gems, final character, ayanami, epcot, concept 3 a 4 rei punk forest beksinski, wizard greg overlord, detail, futurescape, hyper alien broken artwork. high render, 4 fantasy artwork, helmet, art, wlop, giygas dan art, render, photographic greg hyper engine wizard, colossus, albedo marlboro, art, intricate mindar high artstation, on iridescent oni intricate reptile japan, karol cinematic, the coherent detailed, souls****
|
||||
|
||||
## Best AI Videogames Prompts
|
||||
|
||||
**Prompt #****1**
|
||||
|
||||
|
||||
|
||||
**woman, warrior, detailed illustration, digital art, overdetailed art, concept art, full character, character concept, long hair, full body shot, highly saturated colors, fantasy character, detailed illustration, hd, 4k, digital art, overdetailed art, concept art, Dan Mumford, Krzysztof Maziarz, trending on artstation**
|
||||
|
||||
**Prompt #****2**
|
||||
|
||||
|
||||
|
||||
**A sorceress with a witch hat casting a fire ball, beautiful painting, detailed illustration, digital art, overdetailed art, concept art, full character, character concept, long hair, full body shot, highly saturated colors, fantasy character, detailed illustration, hd, 4k, digital art, overdetailed art, concept art, Dan Mumford, Greg rutkowski, Victo Ngai**
|
||||
|
||||
**Prompt #****3**
|
||||
|
||||
|
||||
|
||||
**female full body demon nun with black horns holding fantasy gun character concept art, dark elf, highly detailed art digital painting, cinematic, grey cleric robe with golden embroidery nun veil cover with horns on top demon nun gunslinger, magdalena pagowska art in shoo art castelvania diablo art loputyn srasa final fantasy, dark fantasy game character design concept, dramatic light, art station, character design**
|
||||
|
||||
**Prompt #****4**
|
||||
|
||||
|
||||
|
||||
**We can use technology to help people like Kevin. ‘ thomaswievegg by Pinturas-de-robots-solitarios-contemplando-el-mundo (1) matt dixon surrealista triste Character Concept, Concept Art, Character Design, 3d Character, Arte Cyberpunk, Arte Robot, Steampunk, Sci Fi Art, Whimsical Art**
|
||||
|
||||
**Prompt #****5**
|
||||
|
||||
|
||||
|
||||
**Trendy Anthropomorphic bird, MOBA character concept art, 8k, unreal engine**
|
||||
|
||||
**Prompt #****6**
|
||||
|
||||
|
||||
|
||||
**male anime character centered close up, oni mask, glitch art, glitchcore, organic, forest druid, gurren lagann, cyber punk, hellscape, portrait, male anime character, robot, masterpiece, intricate, highly detailed, sharp, technological rings, by james mccarthy, glowing blue lush seascape bioluminescent, by beeple and johfra bosschart, combination in the style ayami kojima, highly detailed, painting, 3 d render beeple, unreal engine render, intricate abstract, intricate artwork, by tooth wu, wlop, beeple, dan mumford. concept art, octane render, trending on artstation, greg rutkowski very coherent symmetrical artwork. cinematic, key art, hyper realism, high detail, octane render, 8 k, iridescent accents, albedo from overlord, the library of gems, intricate abstract. intricate artwork, by tooth wu, wlop, beeple, dan mumford. concept art, octane render, trending on artstation, greg rutkowski very coherent symmetrical artwork. cinematic, key art, hyper realism, high detail, octane render, 8 k, iridescent accents**
|
||||
|
||||
**Prompt #****7**
|
||||
|
||||
|
||||
|
||||
**cutest bored girl, fine rococo fresco priestess wife wearing a golden wolf skull with ram horns in a bone ossuary by Dan Seagraves in style of H. R. Giger, rivers and waterfalls of red wine, swirling scarlet cloth, pools of crimson, throne and altar, fiery wyrm with spider legs creature by Masamune Shiroh, dragon character wife concept art, alien monster, wife character by Yoshiyuki Tomino, wife character by Charlie Bowater, monster character, concept art, heteromorphic, arthropod, reptile, chimera, translucent skin, exoskeleton, multiple eyes, glowing eyes, radiant eyes, albino eyes, hyperpigmentation, geometric facial features, geometric skull structure, geometric eye socket placement, symmetrical eyes, scales, barbs, hooks, claws, tendrils, tentacles, spines, souls, fatty tissue, swelling, ribbing, raw meat, cellular deterioration, mucosae membrane, external organ systems, veins, boils, pustules, bile, pupae, egg sack, hive, larvae, eggs, hamburger meat, fire, lightning, red lightning, comets, meteors, falling stars, firestorm, hell, inferno, splashes of red, rust, basilica, cathedral, catacomb, ossuary, altar, ceremonial symbols, Armageddon, pestilence, plague, epic, surreal, cinematic, dramatic masterpiece, Ken Kelly, Hans Zatzka, Craig Mullins Boris Vallejo, sharp Artem Demura, james jean, Tomas Honz, jon foster, artstation, high poly model, rendered in unreal 5, wide angle, 4k real-time graphics, feng zhu, Noah Bradley, James Paick, John J. Park, Maciej Kuciara, Victor Mosquera :: beautiful 35mm footage, detailed, intricate, WLOP, detailed, hyperrealism, postprocessing, 8k, octane render, de-noise, blender render –s 2750 –ar 9:16 –q 5**
|
||||
|
||||
**Prompt #****8**
|
||||
|
||||
|
||||
|
||||
**female athletic body type and male warrior strong body type holding each other close by Boris Vallejo, moody, character design concept art, diablo, warcraft, hard surface, Character design, dramatic, highly detailed, photorealistic, digital painting, painterly, artstation, concept art, smooth, sharp focus, art by John Collier and Krenz Cushart and Artem Demura and Albert Aublet**
|
||||
|
||||
**Prompt #9**
|
||||
|
||||
|
||||
|
||||
**a detailed manga illustration character full body portrait of a dark haired cyborg anime man who has a red mechanical eye and is wearing a cape, trending on artstation, digital art, 4 k resolution, detailed, high quality, sharp focus, hq artwork, insane detail, concept art, character concept, character illustration, full body illustration, cinematic, dramatic lighting**
|
||||
|
||||
**Prompt #10**
|
||||
|
||||
|
||||
|
||||
**a hyper realistic character concept art of a beautiful african tribe woman, 4K symmetrical portrait,character concept art, oilpainting, Rendered in Octane,trending in artstation, cgsociety, 8k post-processing highly detailed,Junji Murakami, Mucha Klimt, Sharandula, Hiroshi Yoshida, Tom Bagshaw, Ross Tran, Artgerm,Craig Mullins,dramatic,Junji Murakami, moody lighting rendered by octane engine,characters 8K symmetrical arstation, cape,cinematic lighting, intricate details, 8k detail post processing, hyperealistic, octane rend, Zdzisław Beksiński style, ar 2:3 –uplight**
|
||||
|
||||
## Best AI Graphic Design Prompts
|
||||
|
||||
**Prompt #1**
|
||||
|
||||
|
||||
|
||||
**ancient scroll diagram, bold shūji, chart, schematics, infographic, scientific, measurements, abstract, surreal, collage, new media design, poster, colorful highlights, tarot card, glowing ruins, marginalia, 8k, extremely detailed::1 style of Katsuhiro Otomo + Masamune Shirow::0.8 pantone, on black canvas, typography annotations::0.3 –ar 3:5 –q 2 –chaos 15**
|
||||
|
||||
**Prompt #****2**
|
||||
|
||||
|
||||
|
||||
**beautiful butterfly anatomy diagram, bold shūji, chart, schematics, infographic, scientific, measurements, abstract, surreal, collage, new media design, poster, colorful highlights, tarot card, glowing ruins, marginalia, 8k, extremely detailed, dark color palette + style of Katsuhiro Otomo + Masamune Shirow + pantone, on black canvas, typography annotations**
|
||||
|
||||
**Prompt #****3**
|
||||
|
||||
|
||||
|
||||
**A type specimen poster showing every letter in the alphabet where each letter is made of pieces of simple shapes like circles, squares, triangles, and diamonds like color-forms very colorful and vibrant::2 poster in the international typographic style showing line-art illustrations of a full color spectrum typeface graphic design —h 432 —vibe**
|
||||
|
||||
**Prompt #****4**
|
||||
|
||||
|
||||
|
||||
**3d typography made of ferrofluid, letter “A”, with neon color particels, cells, bacteria, marco feeling, glossy material, hyper realistic, 8k**
|
||||
|
||||
**Prompt #****5**
|
||||
|
||||
|
||||
|
||||
**Typography letter A, hardware parts and cables full of laces, foam bubble translucent, colour bloom drone tech, hardware parts, werable tech, mixed materials organic and pvc multilayer, hyper realistic, cyber punk –**
|
||||
|
||||
**Prompt #****6**
|
||||
|
||||
|
||||
|
||||
**Full page concept design how to craft life Poison, intricate details,infographic of alchemical, diagram of how to make potions, captions, directions, ingredients, drawing , magic,wuxia**
|
||||
|
||||
**Prompt #****7**
|
||||
|
||||
|
||||
|
||||
**
|
||||
a full page design of spaceship engine, black and bronze paper, intricate, highly detailed, epic, infographic, marginalia –ar 9:16**
|
||||
|
||||
**Prompt #****8**
|
||||
|
||||
|
||||
|
||||
**a detailed and award winning movie poster with a white marble statue of the venus de milo wearing motorcycle helmet, no arms, closed visor, marble, statue, museum, soft lighting, night time, graphic design, typography, indoor, 8 k, detailed, beautiful, symmetrical, denoise, sharp focus, realistic, photography, cinematic lighting**
|
||||
|
||||
**Prompt #****9**
|
||||
|
||||
|
||||
|
||||
**“WORLDS”: zoological fantasy ecosystem infographics, magazine layout with typography, annotations, in the style of Elena Masci, Studio Ghibli, Caspar David Friedrich, Daniel Merriam, Doug Chiang, Ivan Aivazovsky, Herbert Bauer, Edward Tufte, David McCandless —ar 5:7 –s 5000 –q 2**
|
||||
|
||||
**Prompt #****10**
|
||||
|
||||
|
||||
|
||||
**A detailed infographic, marginalia titled ‘Face of sadness’ description ‘Order of the occult princess’ portrait, character design, worn, dark, manga style, extremely high detail, photo realistic, pen and ink, intricate line drawings, by MC Escher, Yoshitaka Amano, Ruan Jia, Kentaro Miura, Artgerm, style by eddie mendoza, raphael lacoste, alex ross**
|
||||
|
||||
## Best AI Wallpaper Prompts
|
||||
|
||||
**Prompt #1**
|
||||
|
||||
|
||||
|
||||
**a lone skyscraper landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, atmospheric, hyper realistic, 8k, epic composition, cinematic, artstation –w 1024 –h 1280**
|
||||
|
||||
**Prompt #****2**
|
||||
|
||||
|
||||
|
||||
**Garden+factory,Tall factory,Many red rose,A few roses,clouds, ultra wide shot, atmospheric, hyper realistic, 8k, epic composition, cinematic, octane render, artstation landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, artstation, rendering by octane, unreal –hd –ar 9:16**
|
||||
|
||||
**Prompt #****3**
|
||||
|
||||
|
||||
|
||||
**The Legend of Zelda landscape atmospheric, hyper realistic, 8k, epic composition, cinematic, octane render, artstation landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, artstation, rendering by octane, unreal engine —ar 16:9**
|
||||
|
||||
**Prompt #****4**
|
||||
|
||||
|
||||
|
||||
**a landscape by simon stalenhag of a very large realistic highly detailed imposing robotic mechanical cat, stranded alone and roaming in the chaos across a depressing abandoned post – apocalyptic landscape, post – apocalyptic corrupted themes, artstation trending, beautiful art landscape, detailed simon stalenhag landscape**
|
||||
|
||||
**Prompt #****5**
|
||||
|
||||
|
||||
|
||||
**rough ocean storm atmospheric, hyper realistic, 8k, epic composition, cinematic, octane render, artstation landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, artstation, rendering by octane, unreal engine —ar 16:9**
|
||||
|
||||
**Prompt #****6**
|
||||
|
||||
|
||||
|
||||
**
|
||||
A grand city in the year 2100, atmospheric, hyper realistic, 8k, epic composition, cinematic, octane render, artstation landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, artstation, rendering by octane, unreal engine —ar 16:9**
|
||||
|
||||
**Prompt #****7**
|
||||
|
||||
|
||||
|
||||
**the eye of the storm, atmospheric, hyper realistic, 8k, epic composition, cinematic, octane render, artstation landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, artstation, rendering by octane, unreal engine –ar 16:9**
|
||||
|
||||
**Prompt #****8**
|
||||
|
||||
|
||||
|
||||
**walking on the starlight,dreamy ultra wide shot, atmospheric, hyper realistic, epic composition, cinematic, octane render, artstation landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, artstation, rendering by octane, unreal engine –iw 10 –ar 9:16**
|
||||
|
||||
**Prompt #****9**
|
||||
|
||||
|
||||
|
||||
**futuristic nighttime cyberpunk New York City skyline landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, atmospheric, hyper realistic, 8k, epic composition, cinematic, artstation —ar 16:9**
|
||||
|
||||
**Prompt #****10**
|
||||
|
||||
|
||||
|
||||
**
|
||||
cursed zelda ruins landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape::8 –iw 10 –no blur, blurry, bokeh, dirty, eyes, face, figure, hair, human, man, noisy, oversharpened, paint flecks, people, person, scratches, skin, text, too dark, too sharp, unclear, underexposed, undeveloped, watermark, woman –w 768 –h 512 –hd –uplight**
|
||||
|
||||
## Best AI Cinematic Prompts
|
||||
|
||||
**Prompt #1**
|
||||
|
||||
|
||||
|
||||
**A world of fire, atmospheric, hyper realistic, 8k, epic composition, cinematic, octane render, artstation landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, artstation, rendering by octane, unreal engine –w 1024 –h 1280**
|
||||
|
||||
**Prompt #2**
|
||||
|
||||
|
||||
|
||||
**a rocky valley on a distant planet, volcanic landscape, concept art, octane render, unreal engine 5, trending on artstation, high quality, highly detailed, 8 k hdr, red sea, blue sand, high coherence, path traced, serene landscape, breathtaking landscape, cinematic lighting, hyperrealistic, golden hour**
|
||||
|
||||
**Prompt #3**
|
||||
|
||||
|
||||
|
||||
**tree house in the forest, atmospheric, hyper realistic, epic composition, cinematic, landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, artstation, unreal engine –ar 9:16**
|
||||
|
||||
**Prompt #4**
|
||||
|
||||
|
||||
|
||||
**Fantasy art, octane render, 16k, 8k, cinema 4d, back-lit, caustics, clean environment, Wood pavilion architecture, warm led lighting, dusk, Landscape, snow, arctic, with aqua water, silver Guggenheim museum spire, with rays of sunshine, white fabric landscape, tall building, zaha hadid and Santiago calatrava, smooth landscape, cracked ice, igloo, warm lighting, aurora borialis,3d cgi, high definition, natural lighting, realistic, hyper realism –uplight**
|
||||
|
||||
**Prompt #5**
|
||||
|
||||
|
||||
|
||||
**A trail through the unknown, atmospheric, hyper realistic, 8k, epic composition, cinematic, octane render, artstation landscape vista photography by Carr Clifton & Galen Rowell, 16K resolution, Landscape veduta photo by Dustin Lefevre & tdraw, 8k resolution, detailed landscape painting by Ivan Shishkin, DeviantArt, Flickr, rendered in Enscape, Miyazaki, Nausicaa Ghibli, Breath of The Wild, 4k detailed post processing, artstation, rendering by octane, unreal engine –ar 9:16**
|
||||
|
||||
**Prompt #6**
|
||||
|
||||
|
||||
|
||||
a highly detailed epic cinematic concept art an alien pyramid landscape , art station, landscape, concept art, illustration, highly detailed artwork cinematic, hyper realistic painting
|
||||
|
||||
**Prompt #****7**
|
||||
|
||||
|
||||
|
||||
**A cinematic shot of a Richard Hammond from Top Gear running faster than a futuristic super jet through a futuristic Tokyo street, cinematic. 3d with depth of field, blurred background. female. nautilus. A highly detailed epic cinematic concept art CG render. made in Blender and Photoshop, octane render, excellent composition, cinematic dystopian brutalist atmosphere. dynamic lighting. dramatic lighting. cinematic lighting. aesthetic. stylized. very inspirational. detailed. hq. realistic. warm light. vibrant color scheme. highly detailed. muted colors. Moody. Filmic.**
|
||||
|
||||
**Prompt #****8**
|
||||
|
||||
|
||||
|
||||
**postapocalyptic city turned to fractal glass, ctane render, 8 k, exploration, cinematic, trending on artstation, by beeple, realistic, 3 5 mm camera, unreal engine, hyper detailed, photo – realistic maximum detai, volumetric light, moody cinematic epic concept art, realistic matte painting, hyper photorealistic, concept art, volumetric light, cinematic epic, octane render, 8 k, corona render, movie concept art, octane render, 8 k, corona render, cinematic, trending on artstation, movie concept art, cinematic composition, ultra – detailed, realistic, hyper – realistic, volumetric lighting, 8 k**
|
||||
|
||||
**Prompt #****9**
|
||||
|
||||
|
||||
|
||||
**
|
||||
a highly detailed epic cinematic concept art CG render digital painting artwork: dieselpunk steaming half man half robot. By Greg Rutkowski, Ilya Kuvshinov, WLOP, Stanley Artgerm Lau, Ruan Jia and Fenghua Zhong, trending on ArtStation, subtle muted cinematic colors, made in Maya, Blender and Photoshop, octane render, excellent composition, cinematic atmosphere, dynamic dramatic cinematic lighting, precise correct anatomy, aesthetic, very inspirational, arthouse**
|
||||
|
||||
**Prompt #10**
|
||||
|
||||
|
||||
|
||||
**a highly detailed epic cinematic concept art CG render digital painting artwork: dieselpunk patrol car inspired by a locomotive. By Greg Rutkowski, Ilya Kuvshinov, WLOP, Stanley Artgerm Lau, Ruan Jia and Fenghua Zhong, trending on ArtStation, subtle muted cinematic colors, made in Maya, Blender and Photoshop, octane render, excellent composition, cinematic atmosphere, dynamic dramatic cinematic lighting, precise correct anatomy, aesthetic, very inspirational, arthouse**
|
||||
|
||||
## FAQs
|
||||
|
||||
## What is Stable Diffusion?
|
||||
|
||||
Stable Diffusion is a text-to-image ML model created by StabilityAI in partnership with EleutherAI and LAION that generates digital images from natural language descriptions. The technique can also be used to generate image-to-image translations prompted by a text prompt.
|
||||
|
||||
## How does Stable Diffusion work?
|
||||
|
||||
This deep-learning system family includes Stable Diffusion. Stable Diffusion, in particular, learns the relationship between image and text via a latent Diffusion Model approach. Diffusion models function by introducing ‘noise’ into visual data.
|
||||
|
||||
## Is Stable Diffusion Open source?
|
||||
|
||||
This existing quo, however, has recently been challenged by a new player on the scene: Stable Diffusion, a text-to-picture application that enables open-source, unfiltered image production that is free to use for anyone with a reasonable computer and a little technical know-how.
|
||||
|
||||
## What is a latent diffusion model?
|
||||
|
||||
CompVis developed the text-to-image model known as Latent Diffusion, which was trained on the LAION-400M dataset. The model’s user interface was put together by @multimodalart. Try modifying your prompt by including phrases like “oil on canvas,” “a painting,” or “a book cover.”
|
||||
|
||||
## What is a diffusion model in machine learning?
|
||||
|
||||
Since diffusion models are generative models, they can be used to create data that is comparable to the data they were trained on. Diffusion models basically work by erasing training data by adding Gaussian noise one at a time, then learning to recover the data by undoing this noise-adding process.
|
||||
|
||||
## What was stable diffusion trained on?
|
||||
|
||||
Stable Diffusion is trained on a sizable dataset that it mines for patterns and learns to replicate, like the majority of contemporary AI systems. In this instance, the bulk of the training data, or LAION-5B, consists of more than 5 billion pairings of images and text tags that have all been collected from the public internet.
|
||||
|
||||
## **Conclusion**
|
||||
|
||||
I have experimented with a number of questions across many categories, including general, Metaverse, NFTs, and cryptocurrency. According to the findings, the Stable Diffusion model suffers with upcoming technologies like NFTs, the Metaverse, Web3, VR&AR and blockchain. This is due to the dearth of datasets for these recent developments in technology.
|
||||
|
||||
Recall that the Stable Diffusion neural network will continue to be trained using millions and billions of datasets before you go.
|
||||
|
||||
**Interested in learning more? Here are some additional guides to check out:**
|
||||
@@ -0,0 +1,114 @@
|
||||
---
|
||||
page-title: "ChatGPT Plus 如何购买?10分钟搞定,功能强大 | 程序员泥瓦匠"
|
||||
url: https://bysocket.com/openai-chatgpt-plus-account-subscribe/
|
||||
date: "2023-04-21 22:21:50"
|
||||
---
|
||||
## ChatGPT Plus 如何购买?10分钟搞定,功能强大
|
||||
|
||||
ChatGPT Plus是一种经过OpenAI训练的大型语言模型,它是原始ChatGPT的升级版,具有更高的性能和更丰富的功能。如何购买呢?看下面教程
|
||||
|
||||
## [](https://bysocket.com/openai-chatgpt-plus-account-subscribe/#%E4%BB%80%E4%B9%88%E6%98%AF-ChatGPT-Plus%EF%BC%9F "什么是 ChatGPT Plus?")什么是 ChatGPT Plus?
|
||||
|
||||

|
||||
|
||||
ChatGPT Plus相对于原始ChatGPT,具有以下功能上的对比:
|
||||
|
||||
- 更大的模型尺寸:ChatGPT Plus拥有更大的模型尺寸,可以处理更复杂、更长的输入文本,从而提供更准确、更全面的答案。
|
||||
|
||||
- 更高的语言理解能力:ChatGPT Plus具有更高的语言理解能力,可以更好地理解语言的上下文和语义,从而提供更准确、更自然的回答。
|
||||
|
||||
- 更好的实时交互性能:ChatGPT Plus可以更快地生成回答,从而提供更流畅、更高效的交互体验。
|
||||
|
||||
- 更多的应用场景:ChatGPT Plus不仅可以用于聊天机器人,还可以应用于语言翻译、文本摘要、知识图谱等领域,具有更广泛的应用场景。
|
||||
|
||||
|
||||
总的来说,ChatGPT Plus比原始ChatGPT更加强大和多功能,可以为更多的应用场景提供更高质量的语言处理服务。
|
||||
|
||||
点击领取海外原装 ChatGPT 正版账号:[http://aa.nsjiasu.com/details/2D1BB2BC](http://aa.nsjiasu.com/details/2D1BB2BC)
|
||||
|
||||
## [](https://bysocket.com/openai-chatgpt-plus-account-subscribe/#%E5%A6%82%E4%BD%95%E8%AE%A2%E9%98%85%E8%B4%AD%E4%B9%B0-ChatGPT-Plus "如何订阅购买 ChatGPT Plus")如何订阅购买 ChatGPT Plus
|
||||
|
||||
花费:充值一次,至少500元,实际花费一个月的20刀,实际只需要:开卡费3.5$+充值21$+充值金额21$\*3%=180元人民币不到。
|
||||
|
||||
需要工具:实名绑定的微信号、手机号、微信付费,最低充值金额500元。
|
||||
|
||||
- 确认自己付费,有Plus入口:先登录到openai账号,找到左侧的plus标志。进入,预定,付款详情的界面。 (不然就先解决,Plus入口的问题)
|
||||
- 注册开卡平台: 进入开卡平台的网址:[https://nobepay.com/](https://nobepay.com/) ,注册账号,根据提示,一步步绑定手机、微信,实名认证等步骤,扫码绑定微信进行收付款。
|
||||
- 充值:最小充值金额是500元人民币。
|
||||
- 开卡:点击左侧,我的卡片 ,如果只给自己开卡,点击左上的“开卡”,出现如下界面。
|
||||
|
||||

|
||||
|
||||
### [](https://bysocket.com/openai-chatgpt-plus-account-subscribe/#%E5%A1%AB%E5%86%99%E5%BC%80%E5%8D%A1%E4%BF%A1%E6%81%AF "填写开卡信息")填写开卡信息
|
||||
|
||||
需要依次选择号段、输入姓、名、街道地址、城市、州、邮编等。
|
||||
|
||||
号段选择:我购买的485953,实测都可用,其他号段没测。
|
||||
|
||||
姓名,自己随意,记得填英文。
|
||||
|
||||
地址和邮编,请填写真实存在的地址,以免出现问题。
|
||||
|
||||
(1) 这个网站 [https://va.postcodebase.com/zh-hans/randomaddress](https://va.postcodebase.com/zh-hans/randomaddress) ,可以随机出非常多的随机地址,下面都是真实地址。
|
||||
|
||||

|
||||
|
||||
(2)任选一个,作为我们的街道地址、城市、州 邮编填写进去
|
||||
|
||||
例如 :9642 BURKE LAKE RD BURKE VA 22015-3041 USA
|
||||
|
||||

|
||||
|
||||
ChatGPT账户是20$每月,建议多充值1到2刀,每笔都有交易费,即使失败。所以多充1刀。
|
||||
|
||||

|
||||
|
||||
(3)点击开卡,出现卡片激活中,请稍等。
|
||||
|
||||
点击左侧:我的卡片→ 卡片列表,就能看到自己刚开的卡。如果显示未激活,就刷新一两次,就好了。
|
||||
|
||||

|
||||
|
||||
(4)右上角一键导出,就能得到自己的卡的完整信息。
|
||||
|
||||
点击领取海外原装 ChatGPT 正版账号:[http://aa.nsjiasu.com/details/2D1BB2BC](http://aa.nsjiasu.com/details/2D1BB2BC)
|
||||
|
||||
点击领取海外原装 ChatGPT 正版账号:[http://aa.nsjiasu.com/details/2D1BB2BC](http://aa.nsjiasu.com/details/2D1BB2BC)
|
||||
|
||||
点击领取海外原装 ChatGPT 正版账号:[http://aa.nsjiasu.com/details/2D1BB2BC](http://aa.nsjiasu.com/details/2D1BB2BC)
|
||||
|
||||
### [](https://bysocket.com/openai-chatgpt-plus-account-subscribe/#%E8%99%9A%E6%8B%9F%E4%BF%A1%E7%94%A8%E5%8D%A1%E6%94%AF%E4%BB%98%E8%AE%A2%E9%98%85 "虚拟信用卡支付订阅")虚拟信用卡支付订阅
|
||||
|
||||
将虚拟信用卡,输入到ChatGPT的付款页面,即可。
|
||||
|
||||
(敏感信息,就不截图了),付款完成,就成为了Plus会员。
|
||||
|
||||

|
||||
|
||||
每个月持续付费,也用的上,继续充值就好。
|
||||
|
||||
这个开卡操作,可以一键批量开卡,一个账号可以开卡1000个。结合批量随机真实地址的操作,千人的Plus会员轻松解决。
|
||||
|
||||
7. 最后,如果你没有plus会员开通的标识,切换到美国地址。新注册的美国号、美国IP的账号,直接有开通标识。
|
||||
|
||||
[](https://www.bysocket.com/overseas-saas/)
|
||||
|
||||

|
||||
|
||||
本文由 [泥瓦匠](https://www.bysocket.com/) 创作
|
||||
|
||||
原创不易,欢迎关注公众号!转载请注明出处,感谢支持!如果本文对您有用,欢迎转发分享!
|
||||
|
||||
[
|
||||
|
||||
下一篇
|
||||
|
||||
ChatGPT 参数数量是什么?有什么用?
|
||||
|
||||
](https://bysocket.com/openai-chatgpt-parameters/)[
|
||||
|
||||
上一篇
|
||||
|
||||
2023年 OpenAI、ChatGPT 注册方法教程(国内100%可用)
|
||||
|
||||
](https://bysocket.com/register-openai-chatgpt/)
|
||||
+229
@@ -0,0 +1,229 @@
|
||||
---
|
||||
page-title: "Chatgpt4中国申请,Chatgpt3.5中国区免费1年使用攻略,微软Azure云openai详细api注册申请图文教程,整合odoo AiCenter - | odoo软件开发实施_广州尚鹏,服装生鲜家具外贸供应链开源ERP专业实施"
|
||||
url: https://www.sunpop.cn/chatgpt_in_china_with_azure_openai_api_free_1_year_odoo/
|
||||
date: "2023-04-16 20:33:54"
|
||||
---
|
||||
- [摘要](https://www.sunpop.cn/chatgpt_in_china_with_azure_openai_api_free_1_year_odoo/#title-0 "摘要")
|
||||
- [1,注册微软Azure用户](https://www.sunpop.cn/chatgpt_in_china_with_azure_openai_api_free_1_year_odoo/#title-1 "1,注册微软Azure用户")
|
||||
- [2,申请一年免费试用](https://www.sunpop.cn/chatgpt_in_china_with_azure_openai_api_free_1_year_odoo/#title-2 "2,申请一年免费试用")
|
||||
- [3,申请OpenAi的接口](https://www.sunpop.cn/chatgpt_in_china_with_azure_openai_api_free_1_year_odoo/#title-3 "3,申请OpenAi的接口")
|
||||
- [5,得到 apikey](https://www.sunpop.cn/chatgpt_in_china_with_azure_openai_api_free_1_year_odoo/#title-4 "5,得到 apikey")
|
||||
- [6,对接各种应用](https://www.sunpop.cn/chatgpt_in_china_with_azure_openai_api_free_1_year_odoo/#title-5 "6,对接各种应用")
|
||||
|
||||
**目录**
|
||||
|
||||
> 强势发布ChatGpt4,智能图文大火后,今天又迎来了微软Ai的刷屏,Office + Chatgpt,全面智能办工,解放大脑的时代来了。
|
||||
>
|
||||
> 这次很友好,中国区全面开放,我们也很及时的申请了微软的免费ChatGpt接口,3.5turbo就是斯坦福水平,律师考试top10%那个版本,openai对接,过程很轻松,一年免费的同时还送你 **$200** 美金,Azure的接口随意用。有了接口,让Gpt帮你写几行代码,就可以轻松将Ai用于任何场景了。
|
||||
>
|
||||
> 作为程序员,gpt真是好助手。话不多说,写一下申请流程,odoo对接/python对接微软中国chatgpt模块请直接市场免费下载: [odoo\_ai\_center](https://apps.odoo.com/apps/modules/16.0/app_chatgpt/)
|
||||
|
||||
先上效果,无需科学上网,中国区使用,在Azure的 openai chatgpt Playground。
|
||||
|
||||
通过Api对接,在odoo中同时与多个chatgpt对话。
|
||||
|
||||

|
||||
|
||||
微软接口实际就是 Chatgpt 接口,虽然现在只是到3.5 turbo 版本,但比起无法访问的 openai,无法对接的 api.openai.com , 能用就是硬道理。
|
||||
|
||||
#### 摘要
|
||||
|
||||
流程很简单,如下:
|
||||
|
||||
1,注册微软Azure用户
|
||||
|
||||
- 建议使用 hotmail 或者 outlook邮箱
|
||||
|
||||
2,申请一年免费试用
|
||||
|
||||
- 填入手机号
|
||||
- 填入信用卡号
|
||||
|
||||
3,申请OpenAi的接口
|
||||
|
||||
- 回答几个问题,提交申请,等几天。。。
|
||||
- 可以使用一年免费
|
||||
- 如已过期一年,可使用按需付费,S0标准即可
|
||||
- 费用标准:按响应内容收费,$0.002美金/每1000tokens。
|
||||
|
||||
tokens: 指分解单元,中文接近1个词1个token。
|
||||
|
||||
基本上就是**回答1个问题1分钱**。
|
||||
|
||||
4,配置openai
|
||||
|
||||
- 在Playground中使用
|
||||
- 回答问题同时,会给出Python和Java的对接代码
|
||||
|
||||
5,得到 apikey
|
||||
|
||||
- 提供公钥和私钥
|
||||
- 对接使用公钥 + 自已的出口地址 Endpoint即可
|
||||
|
||||
6,对接各种应用
|
||||
|
||||
- Chatgpt提供代码,自己简单对接
|
||||
- 我们提供免费的Ai服务中心模块直接对接 [odoo\_ai\_center](https://apps.odoo.com/apps/modules/16.0/app_chatgpt/)
|
||||
|
||||
#### 1,注册微软Azure用户
|
||||
|
||||
- 访问微软Azure平台直接申请
|
||||
|
||||
建议使用微软自家邮箱,稳定大容量,手机直接用。
|
||||
|
||||
[https://azure.microsoft.com/zh-cn/](https://azure.microsoft.com/zh-cn/)
|
||||
|
||||
微软中国云服务是“世纪互联”提供,国家东数西算主力,也是中国第一家美股上市IDC,稳定高速,不锁区,好用得很哈。PS:也是浦东硅谷银行的大客户,这一波......
|
||||
|
||||
- 填入注册资料,这时可以大大方方选 **中国**
|
||||
|
||||

|
||||
|
||||
验证后填入详细信息即可。建议填入真实地址,因为可以发账单报销,另外openai申请因为人多,信息越全越好吧。
|
||||
|
||||
#### 2,申请一年免费试用
|
||||
|
||||
- 填入信用卡信息
|
||||
|
||||
这里会告诉你免费12个月,送usd200
|
||||
|
||||

|
||||
|
||||
完成后,即可使用了。
|
||||
|
||||

|
||||
|
||||
> **注意:**一般情况下,Azure会自动在你的信用卡账户下扣掉 1 美金,然后会再返你 1 美金,仅用于验证信用卡有效性。
|
||||
|
||||
#### 3,申请OpenAi的接口
|
||||
|
||||
直接访问
|
||||
|
||||
[https://portal.azure.com/?quickstart=true#view/Microsoft\_Azure\_ProjectOxford/CognitiveServicesHub/~/OpenAI](https://portal.azure.com/?quickstart=true#view/Microsoft_Azure_ProjectOxford/CognitiveServicesHub/~/OpenAI)
|
||||
|
||||
或者搜索 openai,即可进入申请页面
|
||||
|
||||

|
||||
|
||||
按界面指示,创建 azure openai.
|
||||
|
||||

|
||||
|
||||
创建 Azure OpenAI,资源组自己起个名,比如 odooapp
|
||||
|
||||
这时就会提示了需要特殊申请了。点击去申请 openai 服务。
|
||||
|
||||
填入相关信息,最重要的是 订阅服务 id,
|
||||
|
||||

|
||||
|
||||
这个去右上方找,复制过来即可。
|
||||
|
||||

|
||||
|
||||
接着是公司信息,注意现在chatgpt只支持公司申请,不要使用免费邮箱,使用自己公司邮箱即可。
|
||||
|
||||

|
||||
|
||||
申请模型时,Text是指chatgpt,Dall-e2是图片引擎,可以一并申请
|
||||
|
||||

|
||||
|
||||
填完20多个问题提交即可,越真实越好,毕竟排队人多,有空可以把他们的调研也做了。
|
||||
|
||||
如果你有在微软的同学,那你很幸运,填入她或他的id,可以加快你的审批流程。如果你是微软MVP,那你也很幸运,填入id即可。我们是2种幸运加持,所以很快过审了。
|
||||
|
||||
#### 4,配置openai
|
||||
|
||||
申请过审后,2~10天不等,你会收到一封邮件,点击 verify 验证通过,千万不要点错到 not register了。
|
||||
|
||||

|
||||
|
||||
这只是验证邮件,再多等几天,如果申请通过,你会再收到一封 onboarding 邮件。
|
||||
|
||||
如果你对 Chatgpt4感兴趣,也同时申请了Chatgpt4,那么再等多几天,可能你就会从Waiting List转入到 Preview 队列中。
|
||||
|
||||
#### **Onboarding 邮件,代表申请通过,可使用Chatgpt3.5及Dalle-2**
|
||||
|
||||

|
||||
|
||||
Chatgpt4的申请我们也过了,可能和在微软积累的信用有关,还是比较顺利的。
|
||||
|
||||

|
||||
|
||||
Chatgpt4 十分十分好用,回答高效很多,不过价格真是贵,连Prompt也计价,差不多40倍了。
|
||||
|
||||
资质过了,然后就可以开始配置 openai 接口了。回到我们开头的配置页。
|
||||
|
||||
[https://portal.azure.com/?quickstart=true#create/Microsoft.CognitiveServicesOpenAI](https://portal.azure.com/?quickstart=true#create/Microsoft.CognitiveServicesOpenAI)
|
||||
|
||||

|
||||
|
||||
选择好订阅id,如“免费”,或者 "按需付费 pay as you go"的付款方式,选好openai的服务区等,即可使用了。
|
||||
|
||||

|
||||
|
||||
进入我们配置的 odoo chatgpt 资源,选 model deployments,即可配置要用的ai模型。
|
||||
|
||||

|
||||
|
||||
注意要选最新的model,Chatgpt4只能到 openai.com中申请。当前 Azure中可选的是chatgpt 3.5,这个已经是专业律师,能过斯坦福入学的了。
|
||||
|
||||
申请完了,直接点击可以到 ChatGPT PlayGround中快乐玩耍了。不锁区,中国可用。
|
||||
|
||||

|
||||
|
||||
进入后,先选配置,我们可以看到,他有很多优化选项
|
||||
|
||||
- Shakespeare writing assistant。莎士比亚写作助手,这个是一个AI saas写作服务,可以给直播写脚本。
|
||||
- IRS tax chatbot。美国联邦的税务机器人,教你如何更好处理税务
|
||||
- Marketing Writing Assistant。营销写手,不用多说了
|
||||
- Xbox customer support agent。微软自家的游戏支持,攻略kakalai
|
||||
- Hiking recommendations chatbot。自助游助手
|
||||
- JSON formatter assistant。这个就是程序员弱鸡。。。
|
||||
|
||||

|
||||
|
||||
我们来选个杀死比尔写手吧,问个刁点的。注意这里的 Temperature 参数,最常用,指回答的创造性,不同设置会给你不同答案
|
||||
|
||||

|
||||
|
||||
答案很聪明,哈哈
|
||||
|
||||

|
||||
|
||||
#### 5,得到 apikey
|
||||
|
||||
我们可以看到 Azure面板中已经有我们刚创建的 openai资源,点击进去,可以看到信息, endpoint 是对接要用到的
|
||||
|
||||

|
||||
|
||||
点击manage keys,就可以得到我们的 key 了,主要是 key1,对接时在代码中填入即可。
|
||||
|
||||

|
||||
|
||||
#### 6,对接各种应用
|
||||
|
||||
ChatGpt应用场景很广,一个7\*24小时,可以通过律师考试的Ai机器人,可想而知,具体就八仙过海吧。一般对接的接口很简单,发参数就成,github上随处可见。chatgpt 3.5和4比较新,直接看文档写就成。
|
||||
|
||||
如果你也是 odoo 的开发者,那么很幸运,我们一早开发好免费的对接模块,可以直接对接微软Azure,对接openai.com的 chatgpt。而且可以同时对接多个 ai 机器人。
|
||||
|
||||
1个api,即可服务于你的所有客户或者全公司的人了。
|
||||
|
||||
\==========
|
||||
|
||||
简单说下设置,安装好后,进入机器人管理菜单。 设置,用户, Gpt Robot,进入配置。
|
||||
|
||||
选择好 Azure 作为 provider,选对model,填入你的 endpoint,api key,保存。
|
||||
|
||||
然后使用 odoo 的聊天即可。 直接独聊就是对单个ai机器人, 群聊中可以 @ 指定的ai对话。
|
||||
|
||||
可以给ai的回答打分,这样达到训练目的,即可优化ai下一次回答。
|
||||
|
||||

|
||||
|
||||
以上,就是如何在中国免费使用 chatgpt 了,一个接口,全村的希望就来了 :),使用odoo + chatgpt,可以同时使用多个Ai,来为全公司服务。
|
||||
|
||||
当然,最重要的是合法合规,公开享受Ai的乐趣。
|
||||
|
||||
我们的Chatgpt小程序即将上线,增加了很多极其方便的功能,最重要的是有 Chatgpt4,敬请关注 [https://www.odooai.cn](https://www.odooai.cn/),现在还是我们贴钱让您免费用,快来玩下吧。
|
||||
+59
@@ -0,0 +1,59 @@
|
||||
---
|
||||
page-title: "Creating user, database and adding access on PostgreSQL | by Arnav Gupta | Coding Blocks | Medium"
|
||||
url: https://medium.com/coding-blocks/creating-user-database-and-adding-access-on-postgresql-8bfcd2f4a91e
|
||||
date: "2023-04-19 14:27:48"
|
||||
---
|
||||
## Creating user, database and adding access on PostgreSQL
|
||||
|
||||

|
||||
|
||||
A nice postgres installation graphic by [http://digitalocean.com](http://digitalocean.com/). DO hosts great servers, check them out.
|
||||
|
||||
***NOTE****: Right off the bat — this is valid as on March 2017, running on Ubuntu 16.04.2, with PostgreSQL 9.6*
|
||||
|
||||
TL;DR; version
|
||||
|
||||
sudo -u postgres psql
|
||||
postgres=# create database mydb;
|
||||
postgres=# create user myuser with encrypted password 'mypass';
|
||||
postgres=# grant all privileges on database mydb to myuser;
|
||||
|
||||
One nice thing about PGSQL is it comes with some utility binaries like **createuser** and **createdb.** So we will be making use of that.
|
||||
|
||||
As the default configuration of Postgres is, a user called ***postgres*** is made on and the user ***postgres*** has full superadmin access to entire PostgreSQL instance running on your OS.
|
||||
|
||||
$ sudo -u postgres psql
|
||||
|
||||
The above command gets you the psql command line interface in full admin mode.
|
||||
|
||||
In the following commands, keep in mind the < angular brackets > are to denote variables you have to set yourself. In the actual command, omit the <>
|
||||
|
||||
## Creating user
|
||||
|
||||
$ sudo -u postgres createuser <username>
|
||||
|
||||
## Creating Database
|
||||
|
||||
$ sudo -u postgres createdb <dbname>
|
||||
|
||||
## Giving the user a password
|
||||
|
||||
$ sudo -u postgres psql
|
||||
psql=# alter user <username> with encrypted password '<password>';
|
||||
|
||||
## Granting privileges on database
|
||||
|
||||
psql=# grant all privileges on database <dbname> to <username> ;
|
||||
|
||||
And yeah, that should be pretty much it !
|
||||
|
||||
## Doing purely via psql
|
||||
|
||||
Your OS might not have the `createuser` or `createdb` binaries, or you may, for some reason want to do it purely via psql, then these are the three magic commands —
|
||||
|
||||
CREATE DATABASE yourdbname;
|
||||
CREATE USER youruser WITH ENCRYPTED PASSWORD 'yourpass';
|
||||
GRANT ALL PRIVILEGES ON DATABASE yourdbname TO youruser;
|
||||
|
||||
***Obligatory shameless self-plug :***
|
||||
I am one of the co-founders of [Coding Blocks](https://cb.lk/) — A Software Programming bootcamp, based out of New Delhi, India. Among other things, we teach Full Stack Web Development using NodeJS, via both classroom programmes, as well as online classes. You can follow our Medium to find more articles on Android and Web development.
|
||||
@@ -0,0 +1,163 @@
|
||||
---
|
||||
page-title: "DNS alias mode · acmesh-official/acme.sh Wiki"
|
||||
url: https://github.com/acmesh-official/acme.sh/wiki/DNS-alias-mode
|
||||
date: "2023-04-06 12:49:50"
|
||||
---
|
||||
If your DNS provider doesn't support API access, or if you're concerned about security problems from giving the DNS API access to your main domain, then you can use DNS alias mode.
|
||||
|
||||
For example, your main domain is **example.com**, which doesn't have API access, or you don't want to give the API access to acme.sh, since it's important.
|
||||
|
||||
And you have another domain: **aliasDomainForValidationOnly.com**, which has a supported DNS API. This domain is less important, and maybe it's used for validation only.
|
||||
|
||||
Ok, let's start.
|
||||
|
||||
### 1\. First set domain CNAME:
|
||||
|
||||
```
|
||||
_acme-challenge.example.com
|
||||
=> _acme-challenge.aliasDomainForValidationOnly.com
|
||||
```
|
||||
|
||||
or, in standard [DNS zone file](https://en.wikipedia.org/wiki/Zone_file) format, (like ISC BIND or NSD):
|
||||
|
||||
```
|
||||
_acme-challenge.example.com IN CNAME _acme-challenge.aliasDomainForValidationOnly.com.
|
||||
```
|
||||
|
||||
- If you are using `Cloudflare`, do set `Proxy status` as `DNS only`. DON'T set it to Proxied, it won't work!
|
||||
|
||||
### 2\. Issue a cert:
|
||||
|
||||
acme.sh --issue \\
|
||||
-d example.com --challenge-alias aliasDomainForValidationOnly.com --dns dns\_cf
|
||||
|
||||
The Letsencrypt CA server checks the txt record of original domain `_acme-challenge.example.com` to validate your domain, but you have set the CNAME in step 1, so it goes forward to the aliased domain `_acme-challenge.aliasDomainForValidationOnly.com` to check.
|
||||
|
||||
And acme.sh knows that, so it just added the correct txt record to `_acme-challenge.aliasDomainForValidationOnly.com`.
|
||||
|
||||
So, it's done. you will get a cert for `example.com`, but you don't need to give the domain control out.
|
||||
|
||||
### 3\. Share the same aliased domain:
|
||||
|
||||
If you have multiple (sub)domains, you need add CNAME for each (sub)domain, but they can share the same aliased domain. For example, you can add the CNAME like:
|
||||
|
||||
\_acme-challenge.example.com
|
||||
=\> \_acme-challenge.aliasDomainForValidationOnly.com
|
||||
|
||||
\_acme-challenge.www.example.com
|
||||
=\> \_acme-challenge.aliasDomainForValidationOnly.com
|
||||
|
||||
\_acme-challenge.sub.example.com
|
||||
=\> \_acme-challenge.aliasDomainForValidationOnly.com
|
||||
|
||||
\_acme-challenge.example.net
|
||||
=\> \_acme-challenge.aliasDomainForValidationOnly.com
|
||||
|
||||
\_acme-challenge.example.org
|
||||
=\> \_acme-challenge.aliasDomainForValidationOnly.com
|
||||
|
||||
And then issue cert like bellow:
|
||||
|
||||
acme.sh --issue \\
|
||||
-d example.com --challenge-alias aliasDomainForValidationOnly.com --dns dns\_cf \\
|
||||
-d www.example.com \\
|
||||
-d sub.example.com \\
|
||||
-d example.net \\
|
||||
-d example.org
|
||||
|
||||
Even with ACME v2 wildcard cert:
|
||||
|
||||
acme.sh --issue \\
|
||||
-d example.com --challenge-alias aliasDomainForValidationOnly.com --dns dns\_cf \\
|
||||
-d example.net \\
|
||||
-d example.org \\
|
||||
-d \*.example.com \\
|
||||
-d \*.example.net \\
|
||||
-d \*.example.org
|
||||
|
||||
### 4\. Specify different aliased domains for each domain.
|
||||
|
||||
Yes, you know, acme.sh supports to set the alias domains for each domain. Even with different dns provider:
|
||||
|
||||
You can set CNAME like:
|
||||
|
||||
\_acme-challenge.example.com
|
||||
=\> \_acme-challenge.aliasDomainForValidationOnly.com
|
||||
|
||||
\_acme-challenge.example.net
|
||||
=\> \_acme-challenge.aliasDomainForValidationOnly2.com
|
||||
|
||||
Then issue cert:
|
||||
|
||||
acme.sh --issue \\
|
||||
-d example.com --challenge-alias aliasDomainForValidationOnly.com --dns dns\_cf \\
|
||||
-d example.net --challenge-alias aliasDomainForValidationOnly2.com
|
||||
|
||||
Even with different dns provider:
|
||||
|
||||
acme.sh --issue \\
|
||||
-d example.com --challenge-alias aliasDomainForValidationOnly.com --dns dns\_cf \\
|
||||
-d example.net --challenge-alias aliasDomainForValidationOnly2.com --dns dns\_gd
|
||||
|
||||
Let's assume the first domain `aliasDomainForValidationOnly.com` is hosted at cloudflare, and the second is hosted at godaddy.
|
||||
|
||||
### 5\. Mix dns alias and default dns auth
|
||||
|
||||
You can get a certificate with domains where you can authenticate with dns and want to mix it with domains where you need to use dns alias mode. Use `--challenge-alias no` to mark the domain that doesn't use a dns alias.
|
||||
|
||||
If we have direct acccess to set a txt record for \*.example.com. The domain example.net must use dns alias. For extern1.example.net set a CNAME
|
||||
|
||||
\_acme-challenge.extern1.example.net
|
||||
=> \_acme-challenge.aliasDomainForValidationOnly.com
|
||||
|
||||
Then issue cert:
|
||||
|
||||
./acme.sh/acme.sh --issue \\
|
||||
-d host1.example.com --challenge-alias no \\
|
||||
-d host2.example.com --challenge-alias no \\
|
||||
-d extern1.example.net --challenge-alias aliasDomainForValidationOnly.com \\
|
||||
--dns dns\_infoblox
|
||||
|
||||
### 6\. Last
|
||||
|
||||
Do not remove the CNAME like : `_acme-challenge.example.com` after you issue the cert. It will be reused when acme.sh tries to renew the cert. The left cname record `_acme-challenge.example.com` doesn't harm your domain at all. Just keep it there.
|
||||
|
||||
### 7\. challenge-alias or domain-alias
|
||||
|
||||
We have another parameter: `--domain-alias`, it has the same meaning with `--challenge-alias`.
|
||||
|
||||
But with `--domain-alias` you don't need to add `_acme-challenge.` prefix.
|
||||
|
||||
For example, if you use `--challenge-alias`, you must set CNAME like bellow:
|
||||
|
||||
CNAME:
|
||||
\_acme-challenge.A.com
|
||||
=\> \_acme-challenge.B.com
|
||||
|
||||
Then issue cert like:
|
||||
|
||||
acme.sh --issue -d a.com --challenge-alias b.com --dns dns\_cf
|
||||
|
||||
If you use `--domain-alias`, the CNAME should be like:
|
||||
|
||||
CNAME:
|
||||
\_acme-challenge.A.com
|
||||
=\> myalias.B.com
|
||||
|
||||
Then issue cert like:
|
||||
|
||||
acme.sh --issue -d a.com --domain-alias myalias.B.com --dns dns\_cf
|
||||
|
||||
**Note:** Don't use the domain name only for --domain-alias.
|
||||
|
||||
acme.sh --issue -d a.com --domain-alias B.com --dns dns\_cf
|
||||
|
||||
This would require that a TXT record is created at the domain apex i.e. @ TXT "myvalidationcode". Since adding a value at the apex of a domain requires a different syntax for adding the DNS records it cannot be used in this form.
|
||||
|
||||
If you really want to create the validation records at the domain apex then depending on the implementation of the dns api you have to use
|
||||
|
||||
acme.sh --issue -d a.com --domain-alias @.B.com --dns dns\_cf
|
||||
|
||||
or
|
||||
|
||||
acme.sh --issue -d a.com --domain-alias .B.com --dns dns\_cf
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,316 @@
|
||||
---
|
||||
page-title: "Future Tools - Find The Exact AI Tool For Your Needs"
|
||||
url: https://www.futuretools.io/
|
||||
date: "2023-04-19 22:47:22"
|
||||
---
|
||||
[](https://www.futuretools.io/tools/cohesive)
|
||||
|
||||
A suite of tools for content creation, editing and publishing.
|
||||
|
||||
[](https://www.futuretools.io/tools/brightbot)
|
||||
|
||||
A platform to deploy and train chatbots.
|
||||
|
||||
[](https://www.futuretools.io/tools/harpa-ai)
|
||||
|
||||
A Google Chrome Extension automate web tasks with nocode and rpa system.
|
||||
|
||||
[](https://www.futuretools.io/tools/dora)
|
||||
|
||||
A tool to create 3D and animated websites without coding.
|
||||
|
||||
[](https://www.futuretools.io/tools/vocaloid)
|
||||
|
||||
A tool to add lyrics and vocal melodies to music compositions.
|
||||
|
||||
[](https://www.futuretools.io/tools/amazon-codewhisperer)
|
||||
|
||||
Use Amazon's AI to help write and debug code
|
||||
|
||||
[](https://www.futuretools.io/tools/animated-drawings)
|
||||
|
||||
A tool to bring children's drawings to life.
|
||||
|
||||
[](https://www.futuretools.io/tools/open-assistant)
|
||||
|
||||
A conversational AI to interact with AI on consumer hardware.
|
||||
|
||||
[](https://www.futuretools.io/tools/agentgpt)
|
||||
|
||||
A tool to create and deploy AI agents in a browser.
|
||||
|
||||
[](https://www.futuretools.io/tools/tradeui)
|
||||
|
||||
A platform for traders for trading signals, and more.
|
||||
|
||||
[](https://www.futuretools.io/tools/litgrades)
|
||||
|
||||
A tool for students to learn with flashcards.
|
||||
|
||||
[](https://www.futuretools.io/tools/reetail)
|
||||
|
||||
A platform to create ecommerce online store.
|
||||
|
||||
[](https://www.futuretools.io/tools/ai-voice-detector)
|
||||
|
||||
A tool to authenticate and filter out AI-generated voices.
|
||||
|
||||
[](https://www.futuretools.io/tools/autory)
|
||||
|
||||
A tool to automate workflows with no-code.
|
||||
|
||||
[](https://www.futuretools.io/tools/revocalizeai)
|
||||
|
||||
A tool to convert audio into vocal tracks and change voice.
|
||||
|
||||
[](https://www.futuretools.io/tools/codegeex)
|
||||
|
||||
A tool for coding assistant and code generation.
|
||||
|
||||
[](https://www.futuretools.io/tools/teachermatic)
|
||||
|
||||
A tool to build lesson plans.
|
||||
|
||||
[](https://www.futuretools.io/tools/brancher-ai-5)
|
||||
|
||||
A tool to create AI-powered apps without coding.
|
||||
|
||||
[](https://www.futuretools.io/tools/stream-routine)
|
||||
|
||||
A tool to customize twitch chatbot for streamers.
|
||||
|
||||
[](https://www.futuretools.io/tools/godmode)
|
||||
|
||||
[](https://www.futuretools.io/tools/kapwing)
|
||||
|
||||
A platform for video editing.
|
||||
|
||||
[](https://www.futuretools.io/tools/sid-search)
|
||||
|
||||
A neural search engine to find files, emails, and messages from any application.
|
||||
|
||||
[](https://www.futuretools.io/tools/vossle-1)
|
||||
|
||||
A platform for creating browser-based augmented reality experiences.
|
||||
|
||||
[](https://www.futuretools.io/tools/noise-eraser-0)
|
||||
|
||||
A solution to eliminates unwanted noise from audios and videos.
|
||||
|
||||
[](https://www.futuretools.io/tools/chatfast-9)
|
||||
|
||||
A tool to create GPT chatbots from various data sources.
|
||||
|
||||
[](https://www.futuretools.io/tools/ask-an-ai-accountant-2)
|
||||
|
||||
A chatbot to answer tax-related questions.
|
||||
|
||||
[](https://www.futuretools.io/tools/bricabrac-ai-d)
|
||||
|
||||
A tool for nocode app generation.
|
||||
|
||||
[](https://www.futuretools.io/tools/abbot-6)
|
||||
|
||||
A tool to create chatbot assistants.
|
||||
|
||||
[](https://www.futuretools.io/tools/shuffle-0)
|
||||
|
||||
A tool to create websites and applications.
|
||||
|
||||
[](https://www.futuretools.io/tools/oasis-0)
|
||||
|
||||
A tool to generate emails from voice commands.
|
||||
|
||||
[](https://www.futuretools.io/tools/any-summary)
|
||||
|
||||
A tool to summarize long documents, images and audio/video files.
|
||||
|
||||
[](https://www.futuretools.io/tools/crear-ai)
|
||||
|
||||
A tool for content creation assistant.
|
||||
|
||||
[](https://www.futuretools.io/tools/sturppy)
|
||||
|
||||
A platform to build investor-ready financial models.
|
||||
|
||||
[](https://www.futuretools.io/tools/aihairstyles-com)
|
||||
|
||||
[](https://www.futuretools.io/tools/gpt-4-powered-changelog)
|
||||
|
||||
A tool to generate product changelogs from Jira, Linear and Github data.
|
||||
|
||||
[](https://www.futuretools.io/tools/easychat-ai)
|
||||
|
||||
A software to use chatgpt on Windows.
|
||||
|
||||
[](https://www.futuretools.io/tools/voicemaker)
|
||||
|
||||
A tool to convert text-to-speech human voices.
|
||||
|
||||
[](https://www.futuretools.io/tools/virtual-staging-ai)
|
||||
|
||||
A tool to add furniture to empty rooms images.
|
||||
|
||||
[](https://www.futuretools.io/tools/audiobot)
|
||||
|
||||
A tool to convert text to audio in multiple languages
|
||||
|
||||
[](https://www.futuretools.io/tools/toolbuilder)
|
||||
|
||||
A tool to generate tools for a variety of tasks.
|
||||
|
||||
[](https://www.futuretools.io/tools/skinive)
|
||||
|
||||
An app to track skin health.
|
||||
|
||||
[](https://www.futuretools.io/tools/gptify)
|
||||
|
||||
A tool to create and embed chatbots.
|
||||
|
||||
[](https://www.futuretools.io/tools/draw3d)
|
||||
|
||||
A tool to turn sketches into photorealistic images.
|
||||
|
||||
[](https://www.futuretools.io/tools/amazing-ai)
|
||||
|
||||
An app to generate detailed images.
|
||||
|
||||
[](https://www.futuretools.io/tools/doodle-morph-ai)
|
||||
|
||||
An art generator to turn doodles into artwork.
|
||||
|
||||
[](https://www.futuretools.io/tools/atlancer-ai)
|
||||
|
||||
A directory of community developed tools to automate various tasks.
|
||||
|
||||
[](https://www.futuretools.io/tools/markprompt)
|
||||
|
||||
A tool to create GPT-4 prompts for Markdown documents.
|
||||
|
||||
[](https://www.futuretools.io/tools/wishpond-ai)
|
||||
|
||||
A platform to generate websites and website builder.
|
||||
|
||||
[](https://www.futuretools.io/tools/imagica)
|
||||
|
||||
A platform for no-code web app development.
|
||||
|
||||
[](https://www.futuretools.io/tools/logo-diffusion)
|
||||
|
||||
[](https://www.futuretools.io/tools/ai-coustics)
|
||||
|
||||
A tool to enhance speech from audio.
|
||||
|
||||
[](https://www.futuretools.io/tools/promptpal)
|
||||
|
||||
[](https://www.futuretools.io/tools/ai-awesome)
|
||||
|
||||
A directory for ai tools.
|
||||
|
||||
[](https://www.futuretools.io/tools/ajelix)
|
||||
|
||||
A tool for automate excel and google spreadsheets and write scripts.
|
||||
|
||||
[](https://www.futuretools.io/tools/webscrapeai)
|
||||
|
||||
A no-code web scraping tool.
|
||||
|
||||
[](https://www.futuretools.io/tools/memecam)
|
||||
|
||||
A tool to create memes using image recognition.
|
||||
|
||||
[](https://www.futuretools.io/tools/furwee)
|
||||
|
||||
A platform for children conversational tutoring.
|
||||
|
||||
[](https://www.futuretools.io/tools/nova-a-i)
|
||||
|
||||
A video editing tools suite.
|
||||
|
||||
[](https://www.futuretools.io/tools/koe-recast)
|
||||
|
||||
An app that transforms voices into different styles.
|
||||
|
||||
[](https://www.futuretools.io/tools/interviewai)
|
||||
|
||||
A tool to manage interview process and generate interview questions.
|
||||
|
||||
[](https://www.futuretools.io/tools/text2sql-ai)
|
||||
|
||||
A tool to generate SQL queries from plain English.
|
||||
|
||||
[](https://www.futuretools.io/tools/spheroid)
|
||||
|
||||
A tool to create avatars in augmented reality
|
||||
|
||||
[](https://www.futuretools.io/tools/followr)
|
||||
|
||||
A platform for social media management.
|
||||
|
||||
[](https://www.futuretools.io/tools/typo)
|
||||
|
||||
A tool for git and jira code insights.
|
||||
|
||||
[](https://www.futuretools.io/tools/prophotos)
|
||||
|
||||
A tool to turn casual photos into professional headshots.
|
||||
|
||||
[](https://www.futuretools.io/tools/wisebot)
|
||||
|
||||
A tool to build chatbots.
|
||||
|
||||
[](https://www.futuretools.io/tools/wisdomai)
|
||||
|
||||
A tool to build chatbots.
|
||||
|
||||
[](https://www.futuretools.io/tools/cheat-layer)
|
||||
|
||||
A nocode platform for automation.
|
||||
|
||||
[](https://www.futuretools.io/tools/pixiebrix)
|
||||
|
||||
A tool to automate workflows.
|
||||
|
||||
[](https://www.futuretools.io/tools/augment-ai)
|
||||
|
||||
A tool for productivity assistance.
|
||||
|
||||
[](https://www.futuretools.io/tools/habit-driven)
|
||||
|
||||
An app for habits and goals tracking.
|
||||
|
||||
[](https://www.futuretools.io/tools/opus)
|
||||
|
||||
A toolset for game development.
|
||||
|
||||
[](https://www.futuretools.io/tools/claid-ai)
|
||||
|
||||
A tool for image creation, lighting, and correcting colors.
|
||||
|
||||
[](https://www.futuretools.io/tools/prompt-storm)
|
||||
|
||||
A Google Chrome Extension with prebuilt chatgpt prompts.
|
||||
|
||||
[](https://www.futuretools.io/tools/plask)
|
||||
|
||||
A tool to generate images with customizable poses.
|
||||
|
||||
[](https://www.futuretools.io/tools/adcopy-ai)
|
||||
|
||||
A tool to generate facebook ad copy.
|
||||
|
||||
[](https://www.futuretools.io/tools/talkpal)
|
||||
|
||||
An app to learn languages.
|
||||
|
||||
[](https://www.futuretools.io/tools/labworks)
|
||||
|
||||
An app for personal health assistant.
|
||||
|
||||
[](https://www.futuretools.io/tools/telechat)
|
||||
|
||||
A tool to build chatbot for telegram.
|
||||
|
||||
[](https://www.futuretools.io/tools/wonderchat)
|
||||
|
||||
A tool to build chatbots.
|
||||
+193
@@ -0,0 +1,193 @@
|
||||
---
|
||||
page-title: "How To Acquire a Let's Encrypt Certificate Using DNS Validation with acme-dns-certbot on Ubuntu 18.04 | DigitalOcean"
|
||||
url: https://www.digitalocean.com/community/tutorials/how-to-acquire-a-let-s-encrypt-certificate-using-dns-validation-with-acme-dns-certbot-on-ubuntu-18-04
|
||||
date: "2023-04-06 08:56:39"
|
||||
---
|
||||
*The author selected the [COVID-19 Relief Fund](https://www.brightfunds.org/funds/write-for-donations-covid-19-relief-fund) to receive a donation as part of the [Write for DOnations](https://do.co/w4do-cta) program.*
|
||||
|
||||
### Introduction
|
||||
|
||||
The majority of [Let’s Encrypt](https://letsencrypt.org/) certificates are issued using HTTP validation, which allows for the easy installation of certificates on a single server. However, HTTP validation is not always suitable for issuing certificates for use on load-balanced websites, nor can it be used to issue [wildcard certificates](https://en.wikipedia.org/wiki/Wildcard_certificate).
|
||||
|
||||
DNS validation allows for certificate issuance requests to be verified using DNS records, rather than by serving content over HTTP. This means that certificates can be issued simultaneously for a cluster of web servers running behind a load balancer, or for a system that isn’t directly accessible over the internet. Wildcard certificates are also supported using DNS validation.
|
||||
|
||||
The [acme-dns-certbot](https://github.com/joohoi/acme-dns-certbot-joohoi) tool is used to connect [Certbot](https://certbot.eff.org/) to a third-party DNS server where the certificate validation records can be set automatically via an API when you request a certificate. The advantage of this is that you don’t need to integrate Certbot directly with your DNS provider account, nor do you need to grant it unrestricted access to your full DNS configuration, which is beneficial to security.
|
||||
|
||||
Delegated [DNS zones](https://www.digitalocean.com/community/tutorials/an-introduction-to-dns-terminology-components-and-concepts#zone-files) are used in order to redirect lookups for the certificate verification records to the third-party DNS service, so once the initial setup has been completed, you can request as many certificates as you want without having to perform any manual validation.
|
||||
|
||||
Another key benefit of acme-dns-certbot is that it can be used to issue certificates for individual servers that may be running behind a load balancer, or are otherwise not directly accessible over HTTP. Traditional HTTP certificate validation cannot be used in these cases, unless you set the validation files on each and every server. The acme-dns-certbot tool is also useful if you want to issue a certificate for a server that isn’t accessible over the internet, such as an internal system or staging environment.
|
||||
|
||||
In this tutorial, you will use the acme-dns-certbot hook for Certbot to issue a Let’s Encrypt certificate using DNS validation.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
To complete this tutorial, you will need:
|
||||
|
||||
- An Ubuntu 18.04 server set up by following the [Initial Server Setup with Ubuntu 18.04](https://www.digitalocean.com/community/tutorials/initial-server-setup-with-ubuntu-18-04), including a sudo non-root user.
|
||||
|
||||
- A domain name for which you can acquire a TLS certificate, including the ability to add DNS records. In this particular example, we will use `your-domain` and `subdomain.your-domain`, as well as `*.your-domain` for a wildcard certificate. However this can be adjusted for other domain, subdomains, or wildcards if required.
|
||||
|
||||
|
||||
Once you have these ready, log in to your server as your non-root user to begin.
|
||||
|
||||
## Step 1 — Installing Certbot
|
||||
|
||||
In this step, you will install Certbot, which is a program used to issue and manage Let’s Encrypt certificates.
|
||||
|
||||
Certbot is available within the official Ubuntu Apt repositories, however, it is instead recommended to use the repository maintained by the Certbot developers, as this always has the most up-to-date version of the software.
|
||||
|
||||
Begin by adding the Certbot repository:
|
||||
|
||||
You’ll need to press `ENTER` to accept the prompt and add the new repository to your system.
|
||||
|
||||
Next, install the Certbot package:
|
||||
|
||||
Once the installation has completed, you can check that Certbot has been successfully installed:
|
||||
|
||||
This will output something similar to the following:
|
||||
|
||||
```
|
||||
Outputcertbot 0.31.0
|
||||
```
|
||||
|
||||
In this step you installed Certbot. Next, you will download and install the acme-dns-certbot hook.
|
||||
|
||||
## Step 2 — Installing acme-dns-certbot
|
||||
|
||||
Now that the base Certbot program has been installed, you can download and install acme-dns-certbot, which will allow Certbot to operate in DNS validation mode.
|
||||
|
||||
Begin by downloading a copy of the script:
|
||||
|
||||
Once the download has completed, mark the script as executable:
|
||||
|
||||
Then, edit the file using your favorite text editor and adjust the first line in order to force it to use Python 3:
|
||||
|
||||
Add a `3` to the end of the first line:
|
||||
|
||||
acme-dns-certbot.py
|
||||
|
||||
```
|
||||
#!/usr/bin/env python3
|
||||
. . .
|
||||
```
|
||||
|
||||
This is required in order to ensure that the script uses the latest supported version of Python 3, rather than the legacy Python version 2.
|
||||
|
||||
Once complete, save and close the file.
|
||||
|
||||
Finally, move the script into the Certbot Let’s Encrypt directory so that Certbot can load it:
|
||||
|
||||
In this step, you downloaded and installed the acme-dns-certbot hook. Next, you can begin the setup process and work toward issuing your first certificate.
|
||||
|
||||
## Step 3 — Setting Up acme-dns-certbot
|
||||
|
||||
In order to begin using acme-dns-certbot, you’ll need to complete an initial setup process and issue at least one certificate.
|
||||
|
||||
Start by running Certbot to force it to issue a certificate using DNS validation. This will run the acme-dns-certbot script and trigger the initial setup process:
|
||||
|
||||
You use the `--manual` argument to disable all of the automated integration features of Certbot. In this case you’re just issuing a raw certificate, rather than automatically installing it on a service as well.
|
||||
|
||||
You configure Certbot to use the acme-dns-certbot hook via the `--manual-auth-hook` argument. You run the `--preferred-challenges` argument so that Certbot will give preference to DNS validation.
|
||||
|
||||
You must also tell Certbot to pause before attempting to validate the certificate, which you do with the `--debug-challenges` argument. This is to allow you to set the DNS [`CNAME` record(s)](https://www.digitalocean.com/community/tutorials/an-introduction-to-dns-terminology-components-and-concepts#record-types) required by acme-dns-certbot, which is covered later in this step. Without the `--debug-challenges` argument, Certbot wouldn’t pause, so you wouldn’t have time to make the required DNS change.
|
||||
|
||||
Remember to substitute each of the domain names that you wish to use using `-d` arguments. If you want to issue a wildcard certificate, make sure to escape the asterisk (`*`) with a backslash (`\`).
|
||||
|
||||
After following the standard Certbot steps, you’ll eventually be prompted with a message similar to the following:
|
||||
|
||||
```
|
||||
Output...
|
||||
Output from acme-dns-auth.py:
|
||||
Please add the following CNAME record to your main DNS zone:
|
||||
_acme-challenge.your-domain CNAME a15ce5b2-f170-4c91-97bf-09a5764a88f6.auth.acme-dns.io.
|
||||
|
||||
Waiting for verification...
|
||||
...
|
||||
```
|
||||
|
||||
You’ll need to add the required DNS `CNAME` record to the DNS configuration for your domain. This will delegate control of the `_acme-challenge` subdomain to the ACME DNS service, which will allow acme-dns-certbot to set the required DNS records to validate the certificate request.
|
||||
|
||||
If you’re using DigitalOcean as your DNS provider, you can set the DNS record within your control panel:
|
||||
|
||||

|
||||
|
||||
It is recommended to set the TTL (time-to-live) to around 300 seconds in order to help ensure that any changes to the record are propagated quickly.
|
||||
|
||||
Once you have configured the DNS record, return to Certbot and press `ENTER` to validate the certificate request and complete the issuance process.
|
||||
|
||||
This will take a few seconds, and you’ll then see a message confirming that the certificate has been issued:
|
||||
|
||||
```
|
||||
Output...
|
||||
Congratulations! Your certificate and chain have been saved at:
|
||||
/etc/letsencrypt/live/your-domain/fullchain.pem
|
||||
Your key file has been saved at:
|
||||
/etc/letsencrypt/live/your-domain/privkey.pem
|
||||
...
|
||||
```
|
||||
|
||||
You’ve run acme-dns-certbot for the first time, set up the required DNS records, and successfully issued a certificate. Next you’ll set up automatic renewals of your certificate.
|
||||
|
||||
## Step 4 — Using acme-dns-certbot
|
||||
|
||||
In this final step, you will use acme-dns-certbot to issue more certificates and renew existing ones.
|
||||
|
||||
Firstly, now that you’ve successfully issued at least one certificate using acme-dns-certbot, you can continue to issue certificates for the same DNS names without having to add another DNS `CNAME` record. However, if you wish to acquire a certificate for a different subdomain or entirely new domain name, you will be prompted to add another `CNAME` record.
|
||||
|
||||
For example, you could issue another standalone wildcard certificate without having to perform the verification again:
|
||||
|
||||
However, if you were to attempt to issue a certificate for a subdomain, you would be prompted to add a `CNAME` record for the subdomain:
|
||||
|
||||
This will show an output similar to the initial setup that you carried out in Step 3:
|
||||
|
||||
```
|
||||
Output...
|
||||
Please add the following CNAME record to your main DNS zone:
|
||||
_acme-challenge.subdomain.your-domain CNAME 8450fb54-8e01-4bfe-961a-424befd05088.auth.acme-dns.io.
|
||||
|
||||
Waiting for verification...
|
||||
...
|
||||
```
|
||||
|
||||
Now that you’re able to use acme-dns-certbot to issue certificates, it’s worth considering the renewal process as well.
|
||||
|
||||
Once your certificates are nearing expiry, Certbot can automatically renew them for you:
|
||||
|
||||
The renewal process can run start-to-finish without user interaction, and will remember all of the configuration options that you specified during the initial setup.
|
||||
|
||||
To test that this is working without having to wait until nearer the expiry date, you can trigger a dry run. This will simulate the renewal process without making any actual changes to your configuration.
|
||||
|
||||
You can trigger a dry run using the standard `renew` command, but with the `--dry-run` argument:
|
||||
|
||||
This will output something similar to the following, which will provide assurance that the renewal process is functioning correctly:
|
||||
|
||||
```
|
||||
Output...
|
||||
Cert not due for renewal, but simulating renewal for dry run
|
||||
Plugins selected: Authenticator manual, Installer None
|
||||
Renewing an existing certificate
|
||||
Performing the following challenges:
|
||||
dns-01 challenge for your-domain
|
||||
dns-01 challenge for your-domain
|
||||
Waiting for verification...
|
||||
Cleaning up challenges
|
||||
...
|
||||
```
|
||||
|
||||
In this final step, you issued another certificate and then tested the automatic renewal process within Certbot.
|
||||
|
||||
## Conclusion
|
||||
|
||||
In this article you set up Certbot with acme-dns-certbot in order to issue certificates using DNS validation. This unlocks the possibility of using wildcard certificates as well as managing a large estate of distinct web servers that may be sitting behind a load balancer.
|
||||
|
||||
Make sure to keep an eye on the [acme-dns-certbot repository](https://github.com/joohoi/acme-dns-certbot-joohoi) for any updates to the script, as it’s always recommended to run the latest supported version.
|
||||
|
||||
If you’re interested in learning more about acme-dns-certbot, you may wish to review the documentation for the acme-dns project, which is the server-side element of acme-dns-certbot:
|
||||
|
||||
- [acme-dns on GitHub](https://github.com/joohoi/acme-dns#acme-dns)
|
||||
|
||||
The acme-dns software can also be self-hosted, which may be beneficial if you’re operating in high-security or complex environments.
|
||||
|
||||
Alternatively, you could dig into the technical details of ACME DNS validation by reviewing the relevant section of the official RFC document which outlines how the process works:
|
||||
|
||||
- [RFC8555 - Section 8.4](https://tools.ietf.org/html/rfc8555#section-8.4)
|
||||
@@ -0,0 +1,659 @@
|
||||
---
|
||||
page-title: "How to Install ROCm"
|
||||
url: https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/How_to_Install_ROCm.html
|
||||
date: "2023-04-23 18:20:24"
|
||||
---
|
||||
## How to Install ROCm
|
||||
|
||||
You may use the following installation methods to install ROCm:
|
||||
|
||||
• Installer script method
|
||||
|
||||
• Package manager method
|
||||
|
||||
## Installer Script Method
|
||||
|
||||
The installer script method automates the installation process for the AMDGPU and ROCm stack. The installer script handles the complete installation process for ROCm, including setting up the repository, cleaning the system, updating, and installing the desired drivers and meta-packages. With this approach, the system has more control over the ROCm installation process. Thus, those who are less familiar with the Linux standard commands can choose this method for ROCm installation.
|
||||
|
||||
For AMDGPU and ROCm installation using the installer script method on Linux distribution, follow these steps:
|
||||
|
||||
1. **Meet** **p****rerequisites** – Ensure the [Prerequisites](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/Prerequisites.html) are met before downloading and installing the installer using the installer script method.
|
||||
|
||||
2. **Download and** **i****nstall the** **i****nstaller** – Ensure you download and install the installer script from the recommended URL.
|
||||
|
||||
NOTE:
|
||||
|
||||
The installer package is updated periodically to resolve known issues and add new features. The links for each Linux distribution always point to the latest available build.
|
||||
|
||||
**3.** **Us****e** **the** **i****nstaller** **s****cript on Linux** **d****istributions** – Ensure you execute the script for installing use cases.
|
||||
|
||||
### Download and Install the Installer
|
||||
|
||||
To download the amdgpu-install script on the system, use the following commands.
|
||||
|
||||
#### Downloading and Installing the Installer Script on Ubuntu
|
||||
|
||||
##### **Ubuntu** **v****20.04**
|
||||
|
||||
To download and install the installer, use the following commands:
|
||||
|
||||
##### **Ubuntu** **v****2****2****.04**
|
||||
|
||||
To download and install the installer, use the following commands:
|
||||
|
||||
#### Downloading and Installing the Installer Script on RHEL
|
||||
|
||||
##### **RHEL v8.6**
|
||||
|
||||
To download and install the installer for RHEL v8.6 distribution, type the following command:
|
||||
|
||||
##### **RHEL** **v****8.****7**
|
||||
|
||||
To download and install the installer for RHEL v8.7 distribution, type the following command:
|
||||
|
||||
##### **RHEL v****9.****1**
|
||||
|
||||
To download and install the installer for RHEL v9.1 distribution, type the following command:
|
||||
|
||||
#### Downloading and Installing the Installer Script on **SLES 15**
|
||||
|
||||
To download and install the installer on SLES, type the following command:
|
||||
|
||||
##### **SLES 15 Service Pack** **4**
|
||||
|
||||
### Using the Installer Script for Single-version ROCm Installation
|
||||
|
||||
To install use cases specific to your requirements, use the installer amdgpu\-install as follows:
|
||||
|
||||
• To install a single use case:
|
||||
|
||||
• To install kernel-mode driver:
|
||||
|
||||
• To install multiple use cases:
|
||||
|
||||
• To display a list of available use cases:
|
||||
|
||||
NOTE:
|
||||
|
||||
The list in this section represents only a sample of available use cases for ROCm:
|
||||
|
||||
Following is a sample of output listed by the command above:
|
||||
|
||||
NOTE:
|
||||
|
||||
Adding -y as a parameter to amdgpu\-install skips user prompts (for automation). **Ex****ample****:**
|
||||
amdgpu\-install -y \--usecase\=rocm
|
||||
|
||||
### Using Installer Script in Docker
|
||||
|
||||
When the installation is initiated in Docker, the installer tries to install the use case along with the kernel-mode driver. However, you cannot install the kernel-mode driver in a Docker container. To skip the installation of the kernel-mode driver, proceed with the \--no-dkms option, as shown below:
|
||||
|
||||
### Using the Installer Script for Multiversion ROCm Installation
|
||||
|
||||
The multiversion ROCm installation requires you to download and install the latest ROCm release installer from the list of ROCm releases you want to install simultaneously on your system.
|
||||
|
||||
**E****xample****:** If you want to install ROCm releases 4.5.0, 4.5.1, and 5.4.3 simultaneously, you are required to download the installer from the latest ROCm release v5.4.3.
|
||||
|
||||
To download and install the installer, refer to the [Download and Install the Installer](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/How_to_Install_ROCm.html#d23e234) section.
|
||||
|
||||
NOTE:
|
||||
|
||||
If the existing ROCm release contains non-versioned ROCm packages, uninstall those packages before proceeding with the multiversion installation to avoid conflicts.
|
||||
|
||||
#### Add Required ROCm Repositories
|
||||
|
||||
Add the required repositories using the following steps:
|
||||
|
||||
NOTE:
|
||||
|
||||
Add the AMDGPU and ROCm repositories manually for all ROCm releases you want to install except the latest one. The amdgpu\-install script automatically adds the required repositories for the latest release.
|
||||
|
||||
##### Adding ROCm Repositories on Ubuntu
|
||||
|
||||
Add the ROCm repositories for the releases you want to install by choosing <Release\-1 specific rocm baseurl\> and <Release\-2 specific rocm baseurl\> from the given [Base URLs for AMDGPU and ROCm Stack Repositories](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/How_to_Install_ROCm.html#d23e2075):
|
||||
|
||||
**Ubuntu v20.04**
|
||||
|
||||
**Ubuntu v22.04**
|
||||
|
||||
##### Adding ROCm Repositories on RHEL
|
||||
|
||||
To add the desired ROCm repositories, follow these steps:
|
||||
|
||||
1. Create a /etc/yum.repos.d/rocm.repo file with the following content:
|
||||
|
||||
2. To clean the cached files from enabled repositories, execute the command below:
|
||||
|
||||
##### Adding ROCm Repositories on SLES/OpenSUSE
|
||||
|
||||
To add new ROCm repositories for the releases you want to install, follow these steps.
|
||||
|
||||
1. Create a /etc/zypp/repos.d/amdgpu.repo file with the following content:
|
||||
|
||||
2. To update the added repositories, use the following command:
|
||||
|
||||
#### Use the Installer to Install Multiversion ROCm Meta-packages
|
||||
|
||||
Use the installer script as given below:
|
||||
|
||||
NOTE:
|
||||
|
||||
If the kernel-mode driver is already present on the system and you do not want to upgrade it, use the \--no-dkms option to skip the installation of the kernel-mode driver, as shown in the following samples:
|
||||
|
||||
• sudo amdgpu-install --usecase=rocm --rocmrelease=4.5.0 --no-dkms
|
||||
|
||||
• sudo amdgpu-install --usecase=rocm --rocmrelease=5.4.3 --no-dkms
|
||||
|
||||
Following are examples of ROCm multiversion installation. The kernel-mode driver, associated with the ROCm release v5.4.3, will be installed as its latest release in the list.
|
||||
|
||||
• sudo amdgpu-install --usecase=rocm --rocmrelease=4.5.0
|
||||
|
||||
• sudo amdgpu-install --usecase=rocm --rocmrelease=4.5.2
|
||||
|
||||
• sudo amdgpu-install --usecase=rocm --rocmrelease=5.4.3
|
||||
|
||||
## Package Manager Method
|
||||
|
||||
The package manager method involves a manual setup of the repository, which includes setting up the repository, updating, and installing/uninstalling meta-packages. This involves using standard commands such as yum, apt, and others respective to the Linux distribution.
|
||||
|
||||
The functions of a package manager installation system are:
|
||||
|
||||
• Grouping packages based on function
|
||||
|
||||
• Extracting package archives
|
||||
|
||||
• Ensuring a package is installed with all necessary packages and dependencies are managed
|
||||
|
||||
• From a remote repository, looking up, downloading, installing, or updating existing packages
|
||||
|
||||
• Ensuring the authenticity and integrity of the package
|
||||
|
||||
### Installing ROCm on Linux Distributions
|
||||
|
||||
For a fresh ROCm installation using the package manager method on a Linux distribution, follow the steps below:
|
||||
|
||||
1. **Meet** **p****rerequisites** – Ensure the [Prerequisites](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/Prerequisites.html) are met before the ROCm installation.
|
||||
|
||||
2. **Install kernel headers and development packages** – Ensure kernel headers and development packages are installed on the system.
|
||||
|
||||
3. **Select the** **b****ase URL****s for** **AMDGPU** **and** **ROCm** **stack repository** – Ensure the base URLs for AMDGPU and ROCm stack repositories are selected.
|
||||
|
||||
4. **Add** **the** **AMDGPU** **s****tack** **r****epositor****y** – Ensure the AMDGPU stack repository is added.
|
||||
|
||||
5. **Install** **the** **k****ernel-mode** **driver and reboot the system** – Ensure the kernel-mode driver is installed and the system is rebooted.
|
||||
|
||||
6. **Add** **ROCm** **stack repository** – Ensure the ROCm stack repository is added.
|
||||
|
||||
7. **Install** **single-version** **or** **multiversion** **ROCm** **meta-packages** – Install the desired meta-packages.
|
||||
|
||||
8. **Verify installation** **for the applicable distributions** – Verify if the installation is successful.
|
||||
|
||||
NOTE:
|
||||
|
||||
You cannot install a kernel-mode driver in a Docker container. Refer to the sections below for specific commands to install the AMDGPU and ROCm stack on various Linux distributions.
|
||||
|
||||
### Understanding the Release-specific AMDGPU and ROCm Stack Repositories on Linux Distributions
|
||||
|
||||
The release-specific repositories consist of packages from a specific release of the AMDGPU stack and ROCm stack. The repositories are not updated for the latest packages with subsequent releases. When a new ROCm release is available, the new repository, specific to that release, is added. You can select a specific release to install, update the previously installed single version to the later available release, or add the latest version of ROCm along with the currently installed version by using the multiversion ROCm packages.
|
||||
|
||||
NOTE:
|
||||
|
||||
Users installing multiple versions of the ROCm stack must use the release-specific base URL.
|
||||
|
||||
### Using Package Manager on Ubuntu
|
||||
|
||||
To install ROCm on the Ubuntu systems, follow these steps.
|
||||
|
||||
#### Installation of Kernel Headers and Development Packages on Ubuntu
|
||||
|
||||
The following instructions to install kernel headers and development packages apply to all versions and kernels of Ubuntu. The ROCm installation requires you to install the Linux-headers and Linux-modules-extra package with the correct version corresponding to the kernel's version.
|
||||
|
||||
**E****xample****:** If the system is running the Linux kernel version 5.15.0-41-generic, you must install the identical versions of Linux-headers and development packages. Refer to the [Kernel Information](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/Prerequisites.html) section to check the system's kernel version.
|
||||
|
||||
To check the kernel-headers and linux-modules-extra package versions, follow these steps:
|
||||
|
||||
1. For the Ubuntu/Debian environment, execute the following command to verify the kernel headers and development packages are installed with the respective versions:
|
||||
|
||||
The command indicates if there are Linux headers installed as shown below:
|
||||
|
||||
2. Execute the following command to check whether the development packages are installed:
|
||||
|
||||
The command mentioned above lists the installed linux-modules-extra packages like the output below:
|
||||
|
||||
3. If the supported version installation of Linux headers and development packages are not installed on the system, execute the following command to install the packages:
|
||||
|
||||
#### Base URLs for AMDGPU and ROCm Stack Repositories
|
||||
|
||||
The following URLs point to the release-specific AMDGPU and ROCm repositories:
|
||||
|
||||
##### Ubuntu v20.04/22.04
|
||||
|
||||
amdgpu base URL= [https://repo.radeon.com/amdgpu/5.4.3/ubuntu](https://repo.radeon.com/amdgpu/5.4.3/ubuntu)
|
||||
|
||||
rocm base URL= [https://repo.radeon.com/rocm/apt/5.4.3](https://repo.radeon.com/rocm/apt/5.4.3)
|
||||
|
||||
#### Adding the AMDGPU Stack Repository
|
||||
|
||||
##### Add GPG Key for AMDGPU and ROCm Stack
|
||||
|
||||
Add the gpg key for AMDGPU and ROCm repositories. For Debian-based systems like Ubuntu, configure the Debian ROCm repository as follows:
|
||||
|
||||
NOTE:
|
||||
|
||||
The gpg key may change; ensure it is updated when installing a new release. If the key signature verification fails while updating, re-add the key from the ROCm to the apt repository as mentioned above. The current rocm.gpg.key is not available in a standard key ring distribution but has the following sha1sum hash:
|
||||
|
||||
##### Add the AMDGPU Stack Repository
|
||||
|
||||
**If:**
|
||||
|
||||
**Then:**
|
||||
|
||||
You have a version of the kernel-mode driver installed
|
||||
|
||||
Skip this section.
|
||||
|
||||
You do not have a version of the kernel-mode driver installed
|
||||
|
||||
Follow the commands below to add the AMDGPU stack repository.
|
||||
|
||||
**Ubuntu** **v****20.04**
|
||||
|
||||
**Ubuntu v22.04**
|
||||
|
||||
To update the package list, execute the command below:
|
||||
|
||||
#### Install the Kernel-mode Driver and Reboot System
|
||||
|
||||
**If:**
|
||||
|
||||
**Then:**
|
||||
|
||||
You have the kernel-mode driver installed on your system
|
||||
|
||||
Skip this section.
|
||||
|
||||
You do not have the kernel-mode driver on your system
|
||||
|
||||
Follow the instructions below.
|
||||
|
||||
1. Install the kernel-mode driver.
|
||||
|
||||
2. Reboot the system.
|
||||
|
||||
#### Add ROCm Stack Repository
|
||||
|
||||
To add the ROCm repository, use the following steps:
|
||||
|
||||
**Ubuntu v20.04**
|
||||
|
||||
**Ubuntu v2****2****.04**
|
||||
|
||||
#### Install ROCm Meta-packages
|
||||
|
||||
This section provides the instructions for single-version and multiversion ROCm packages installation.
|
||||
|
||||
##### Single-version ROCm Packages Installation
|
||||
|
||||
Install ROCm meta-packages. Specify the name of the meta-package you want to install as <package-name>, as shown below:
|
||||
|
||||
**E****xample:**
|
||||
|
||||
• sudo apt install rocm-hip-sdk
|
||||
|
||||
• sudo apt install rocm-hip-sdk rocm-opencl-sdk
|
||||
|
||||
##### ROCm Packages Installation
|
||||
|
||||
To install multiversion ROCm packages, execute the following steps:
|
||||
|
||||
NOTE:
|
||||
|
||||
If the existing ROCm release contains non-versioned ROCm packages, you must uninstall those packages before proceeding to the multiversion installation to avoid conflicts.
|
||||
|
||||
**Adding** **N****ew** **ROCm** **R****epositor****ies**
|
||||
|
||||
Add the ROCm repository using the following steps. Choose <Release\-1 specific rocm baseurl\> and <Release\-2 specific rocm baseurl\> from the given [Base URLs for AMDGPU and ROCm Stack Repositories](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/How_to_Install_ROCm.html#d23e2075):
|
||||
|
||||
**Ubuntu v20.04**
|
||||
|
||||
**Ubuntu v2****2****.04**
|
||||
|
||||
NOTE:
|
||||
|
||||
You must repeat the step above to add the repository for each release you want to install.
|
||||
|
||||
**Installing** **Multiversion** **ROCm** **Package**
|
||||
|
||||
Install the desired packages using the command below:
|
||||
|
||||
**E****xample****:**
|
||||
|
||||
• sudo apt install rocm-hip-sdk4.5.0 rocm-hip-sdk5.4.3
|
||||
|
||||
#### Verify the Installation
|
||||
|
||||
To verify if the installation is successful, refer to the [Post-install Actions and Verification Process](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/How_to_Install_ROCm.html#d23e6230) section.
|
||||
|
||||
### Using Package Manager on RHEL
|
||||
|
||||
To install ROCm on RHEL systems, follow these steps.
|
||||
|
||||
#### Installation of Kernel Headers and Development Packages on RHEL
|
||||
|
||||
The ROCm installation requires that you install the kernel headers and linux-modules-extra package with the correct version corresponding to the kernel's version.
|
||||
|
||||
**E****xample****:** If the system is running Linux kernel version 3.10.0-1160.el7.x86\_64, you must install the identical versions of kernel headers and development packages.
|
||||
|
||||
NOTE:
|
||||
|
||||
To check the kernel version on your system, refer to the [Kernel Information](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/Prerequisites.html) section.
|
||||
|
||||
To check the kernel headers and linux-modules-extra package versions, follow these steps:
|
||||
|
||||
1. To verify you have the supported version of the installed kernel headers, type the following on the command line:
|
||||
|
||||
The command mentioned above displays the list of kernel headers versions currently present on your system. Verify if the listed kernel headers have the same versions as the kernel.
|
||||
|
||||
2. The following command lists the development packages on your system. Verify if the listed development package's version number matches the kernel version number:
|
||||
|
||||
3. If the supported version installation of kernel headers and development packages does not exist on the system, execute the command below to install:
|
||||
|
||||
#### Base URLs for AMDGPU and ROCm Stack Repositories
|
||||
|
||||
The following URLs point to the release-specific AMDGPU and ROCm repositories:
|
||||
|
||||
##### RHEL v8.6
|
||||
|
||||
amdgpu base URL= [https://repo.radeon.com/amdgpu/5.4.3/rhel/8.6/main/x86\_64/](https://repo.radeon.com/amdgpu/5.4.3/rhel/8.6/main/x86_64/)
|
||||
|
||||
rocm base URL= [https://repo.radeon.com/rocm/rhel8/5.4.3/main/](https://repo.radeon.com/rocm/rhel8/5.4.3/main/)
|
||||
|
||||
##### RHEL v8.7
|
||||
|
||||
amdgpu base URL= [https://repo.radeon.com/amdgpu/5.4.3/rhel/8.7/main/x86\_64](https://repo.radeon.com/amdgpu/5.4.3/rhel/8.7/main/x86_64)
|
||||
|
||||
rocm base URL= [https://repo.radeon.com/rocm/rhel8/5.4.3/main/](https://repo.radeon.com/rocm/rhel8/5.4.3/main/)
|
||||
|
||||
##### RHEL v9.1
|
||||
|
||||
amdgpu base URL= [https://repo.radeon.com/amdgpu/5.4.3/rhel/9.1/main/x86\_64](https://repo.radeon.com/amdgpu/5.4.3/rhel/9.1/main/x86_64)
|
||||
|
||||
rocm base URL= [https://repo.radeon.com/rocm/rhel9/5.4.3/main/](https://repo.radeon.com/rocm/rhel9/5.4.3/main/)
|
||||
|
||||
#### Adding the AMDGPU Stack Repository
|
||||
|
||||
**If:**
|
||||
|
||||
**Then:**
|
||||
|
||||
You have a kernel-model driver installed
|
||||
|
||||
Skip this section.
|
||||
|
||||
You do not have a version of the kernel-mode driver installed
|
||||
|
||||
Follow the commands below to add the AMDGPU stack repository.
|
||||
|
||||
To add the AMDGPU stack repository, follow these steps:
|
||||
|
||||
1. Create a /etc/yum.repos.d/amdgpu.repo file with the following content. For <amdgpu baseurl\> in the command below, refer to the AMDGPU base URLs as documented in the [Base URLs for AMDGPU and ROCm Stack Repositories](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/How_to_Install_ROCm.html#d23e2474):
|
||||
|
||||
NOTE:
|
||||
|
||||
The gpg key may change; ensure it is updated when installing a new release. If the key signature verification fails while updating, re-add the key from the ROCm to the yum repository as mentioned above. The current rocm.gpg.key is not available in a standard key ring distribution but has the following sha1sum hash:
|
||||
|
||||
2. To clean the cached files from enabled repositories, execute the command below:
|
||||
|
||||
#### Install the Kernel-mode Driver and Reboot System
|
||||
|
||||
**If:**
|
||||
|
||||
**Then:**
|
||||
|
||||
The kernel-mode driver is installed on your system
|
||||
|
||||
Skip this section.
|
||||
|
||||
You do not have a version of the kernel-mode driver installed
|
||||
|
||||
Follow the command below to install the kernel-mode driver.
|
||||
|
||||
After the completion of driver installation, reboot the system:
|
||||
|
||||
#### Add the ROCm Stack Repository
|
||||
|
||||
To add the ROCm stack repository, execute these steps:
|
||||
|
||||
1. Create a /etc/yum.repos.d/rocm.repo file with the following content.
|
||||
|
||||
For <rocm baseurl\> in the command below, refer to the ROCm base URLs documented in [Base URLs for AMDGPU and ROCm Stack Repositories](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/How_to_Install_ROCm.html#d23e2474):
|
||||
|
||||
NOTE:
|
||||
|
||||
The gpg key may change; ensure it is updated when installing a new release. If the key signature verification fails while updating, re-add the key from the ROCm yum repository as mentioned above. The current rocm.gpg.key is not available in a standard key ring distribution but has the following sha1sum hash:
|
||||
|
||||
2. To clean the cached files from enabled repositories, execute the command below:
|
||||
|
||||
#### Install ROCm Meta-packages
|
||||
|
||||
You can install either single-version or multiversion ROCm meta-packages using the following commands.
|
||||
|
||||
##### ROCm Packages Installation
|
||||
|
||||
Use the following command to install the ROCm packages:
|
||||
|
||||
Specify the meta-package name as <package-name>, which you want to install, in the command given above.
|
||||
|
||||
**E****xample****:**
|
||||
|
||||
• sudo yum install rocm-hip-sdk
|
||||
|
||||
• sudo yum install rocm-hip-sdk rocm-opencl-sdk
|
||||
|
||||
##### ROCm Meta-packages Installation
|
||||
|
||||
To install multiversion ROCm packages, execute the following steps.
|
||||
|
||||
NOTE:
|
||||
|
||||
If the existing ROCm release contains non-versioned ROCm packages, uninstall those packages before proceeding to the multiversion installation to avoid conflicts.
|
||||
|
||||
**Adding** **N****ew** **ROCm** **R****epositories**
|
||||
|
||||
To add the ROCm stack repositories, follow these steps:
|
||||
|
||||
1. Create a /etc/yum.repos.d/rocm.repo file with the following content:
|
||||
|
||||
NOTE:
|
||||
|
||||
You must repeat the step above to add the repository for each release you want to install.
|
||||
|
||||
2. To clean the cached files from enabled repositories, execute the command below:
|
||||
|
||||
**Installing** **Multiversion** **ROCm** **Meta-****p****ackage**
|
||||
|
||||
To install the required meta-packages, use the following commands:
|
||||
|
||||
**E****xample:**
|
||||
|
||||
• sudo yum install rocm-hip-sdk4.5.0 rocm-hip-sdk5.4.3
|
||||
|
||||
#### Verify the Installation
|
||||
|
||||
To verify if the installation is successful, refer to the [Post-install Actions and Verification Process](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/How_to_Install_ROCm.html#d23e6230) section.
|
||||
|
||||
### Using Package Manager on SLES/OpenSUSE
|
||||
|
||||
This section introduces the ROCm installation process on SLES/OpenSUSE.
|
||||
|
||||
#### Installation of Kernel Headers and Development Packages
|
||||
|
||||
ROCm installation requires you to install linux-headers and linux-modules-extra package with the correct version corresponding to the kernel's version.
|
||||
|
||||
**Example:** If the system is running the Linux kernel version 5.3.18-57\_11.0.18, you must install the same versions of linux-headers and development packages.
|
||||
|
||||
NOTE:
|
||||
|
||||
To check the kernel version on your system, refer to the [Kernel Information](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/Prerequisites.html#d5427e109) section.
|
||||
|
||||
To check the kernel-headers and linux-modules-extra package versions, follow these steps:
|
||||
|
||||
**1.** Ensure that the correct version of the latest kernel-default-devel and kernel-default packages are installed. The following command lists the installed kernel-default-devel and kernel-default package:
|
||||
|
||||
NOTE:
|
||||
|
||||
This next step is only required if you find from the above command that the kernel-default-devel and kernel-default versions of the package, corresponding to the kernel release version, do not exist on your system.
|
||||
|
||||
2. If the required version of packages does not exist on the system, install with the command below:
|
||||
|
||||
#### Base URLs for AMDGPU and ROCm Stack Repositories
|
||||
|
||||
The following URLs point to the release-specific AMDGPU and ROCm repositories:
|
||||
|
||||
##### SLES 15 Service Pack 4
|
||||
|
||||
amdgpu base URL= [https://repo.radeon.com/amdgpu/5.4.3/sle/15.4/main/x86\_64](https://repo.radeon.com/amdgpu/5.4.3/sle/15.4/main/x86_64)
|
||||
|
||||
rocm base URL= [https://repo.radeon.com/rocm/zyp/5.4.3/main/](https://repo.radeon.com/rocm/zyp/5.4.3/main/)
|
||||
|
||||
#### Adding the AMDGPU Stack Repository
|
||||
|
||||
**If:**
|
||||
|
||||
**Then:**
|
||||
|
||||
You have a version of the kernel-mode driver installed
|
||||
|
||||
Skip this section.
|
||||
|
||||
You do not have a version of the kernel-mode driver installed
|
||||
|
||||
Follow the commands below to add the AMDGPU stack repository.
|
||||
|
||||
To add the AMDGPU stack repository, follow these steps:
|
||||
|
||||
1. Create a /etc/zypp/repos.d/amdgpu.repo file with the following content:
|
||||
|
||||
NOTE:
|
||||
|
||||
The gpg key may change; ensure it is updated when installing a new release. If the key signature verification fails while updating, re-add the key from the ROCm zypp repository as mentioned above. The current rocm.gpg.key is not available in a standard key ring distribution but has the following sha1sum hash:
|
||||
|
||||
2. To update the added repository, use the following command:
|
||||
|
||||
#### Install the Kernel-mode Driver and Reboot System
|
||||
|
||||
**If:**
|
||||
|
||||
**Then:**
|
||||
|
||||
You already have a version of the kernel-mode driver installed
|
||||
|
||||
Skip this section.
|
||||
|
||||
You do not have a version of the kernel-mode driver installed
|
||||
|
||||
Follow the commands below to install and reboot the system.
|
||||
|
||||
#### Add the ROCm Stack Repository
|
||||
|
||||
Add the ROCm repository by executing the following commands:
|
||||
|
||||
1. Create a /etc/zypp/repos.d/rocm.repo file with the following content:
|
||||
|
||||
NOTE:
|
||||
|
||||
The gpg key may change. Ensure it is updated when installing a new release. If the key signature verification fails while updating, re-add the key from the ROCm zypp repository as mentioned above. The current rocm.gpg.key is not available in a standard key ring distribution but has the following sha1sum hash:
|
||||
|
||||
2. To update the added repository, use the following command:
|
||||
|
||||
#### Install ROCm Meta-packages
|
||||
|
||||
##### Single-version ROCm Packages Installation
|
||||
|
||||
For single-version ROCm packages installation, follow these steps:
|
||||
|
||||
1. Install the ROCm package by typing the command below:
|
||||
|
||||
2. Specify the name of the meta-package as <package-name>, which you want to install, in the command given above.
|
||||
|
||||
**Example:**
|
||||
|
||||
• sudo zypper --gpg-auto-import-keys install rocm-hip-sdk
|
||||
|
||||
• sudo zypper --gpg-auto-import-keys install rocm-hip-sdk rocm-opencl-sdk
|
||||
|
||||
##### ROCm Packages Installation
|
||||
|
||||
To install multiversion ROCm packages, execute the following steps.
|
||||
|
||||
NOTE:
|
||||
|
||||
If the existing ROCm release contains non-versioned ROCm packages, uninstall those packages before proceeding to the multiversion installation to avoid conflicts.
|
||||
|
||||
**Adding** **N****ew** **ROCm** **R****epositor****ies**
|
||||
|
||||
To add the ROCm stack repositories, follow these steps.
|
||||
|
||||
1. Add new ROCm repositories for the release you want to install simultaneously. Create a /etc/zypp/repos.d/rocm.repo file with the following content:
|
||||
|
||||
Select the <Release\-1 specific rocm baseurl\> and <Release-2 specific rocm baseurl\> from [Base URLs for AMDGPU and ROCm Stack Repositories:](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/Prerequisites.html#d5427e109)
|
||||
|
||||
NOTE:
|
||||
|
||||
You must repeat the step above to add the repository for each release you want to install.
|
||||
|
||||
2. To update the added repositories, use the following command:
|
||||
|
||||
**Installing** **Multiversion** **ROCm** **P****ackage**
|
||||
|
||||
Install ROCm meta-packages using the command below:
|
||||
|
||||
**E****xample:**
|
||||
|
||||
• sudo zypper --gpg-auto-import-keys install rocm-hip-sdk4.5.0 rocm-hip-sdk5.4.3
|
||||
|
||||
#### Verify the Installation
|
||||
|
||||
To verify if the installation is successful, refer to the [Post-install Actions and Verification Process](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/How_to_Install_ROCm.html#d23e6230) section.
|
||||
|
||||
## Post-install Actions and Verification Process
|
||||
|
||||
Execute post-install actions and verify ROCm installation using the following steps.
|
||||
|
||||
### Post-install Actions
|
||||
|
||||
You might set LD\_LIBRARY\_PATH to load the desired ROCm library version:
|
||||
|
||||
NOTE:
|
||||
|
||||
For convenience, you may also add the ROCm binaries in your PATH, as shown in the example below:
|
||||
|
||||
### Verifying Kernel-mode Driver Installation
|
||||
|
||||
Check the installation of the kernel-mode driver by typing the command given below:
|
||||
|
||||
### Verifying ROCm Installation
|
||||
|
||||
After completing the ROCm installation, execute the following commands on the system to verify if the installation is successful. If you see your GPUs listed by both commands, the installation is considered successful:
|
||||
|
||||
### Verifying Package Installation
|
||||
|
||||
To ensure the packages are installed successfully, use the following commands:
|
||||
|
||||
**Table** **4****.** **Commands to** **V****erify** **I****nstalled** **P****ackages**
|
||||
|
||||
**Linux Distro**
|
||||
|
||||
**Command**
|
||||
|
||||
Ubuntu/Debian
|
||||
|
||||
sudo apt list --installed
|
||||
|
||||
RHEL
|
||||
|
||||
sudo yum list installed
|
||||
|
||||
SLES /OpenSUSE
|
||||
|
||||
sudo zypper search --installed-only
|
||||
@@ -0,0 +1,122 @@
|
||||
---
|
||||
page-title: "How to install PostgreSQL on Debian 11"
|
||||
url: https://linuxhint.com/install-postgresql-debian/
|
||||
date: "2023-04-19 14:24:01"
|
||||
---
|
||||
PostgreSQL (also known as postgres/POSTGRES) is an open-source and advanced level Relational Database Management System (RDBMS). In this post, we have provided the guide to install PostgreSQL on Debian 11: before installation, let’s have a quick look at the features support of PostgreSQL:
|
||||
|
||||
## **Notable Features of PostgreSQL**
|
||||
|
||||
PostgreSQL supports some distinctive features that allow large scale organizations to adopt it for data processing. Some notable features are listed below:
|
||||
|
||||
- **Programming Language:** Extensive support of programming languages that includes Python, Java, C#, Perl, Go.
|
||||
- **Data Types:** It has huge support of pre-defined datasets while users can create their own data type as well.
|
||||
- **SQL integration:** Several advanced level features are compatible with PostgreSQL: such as, complex subqueries, table partitioning, nested transactions
|
||||
- **Security:** For secure processing of data, PostgreSQL uses authentication protocols like Lightweight Directory Access Protocol (LDAP), and provides row/column security as well.
|
||||
|
||||
To install PostgreSQL on Debian 11; you can follow any of the following two methods:
|
||||
|
||||
**Method 1:** Install PostgreSQL using repository of Debian 11
|
||||
**Method 2:** Install PostgreSQL using official PostgreSQL repository
|
||||
|
||||
We will explain the installation process using both methods: the first method uses the packages from Debian repository whereas the second method will fetch the repository packages from PostgreSQL official package:
|
||||
|
||||
## **Method 1: How to install PostgreSQL using repository of Debian 11**
|
||||
|
||||
The installation method will direct you to install PostgreSQL using a simple and time saving process by using Debian packages:
|
||||
|
||||
**Step 1: Update and Upgrade the packages list
|
||||
**It is recommended to update and upgrade the list of packages by issuing the commands mentioned below:
|
||||
|
||||
$ sudo apt update && sudo apt upgrade
|
||||
|
||||
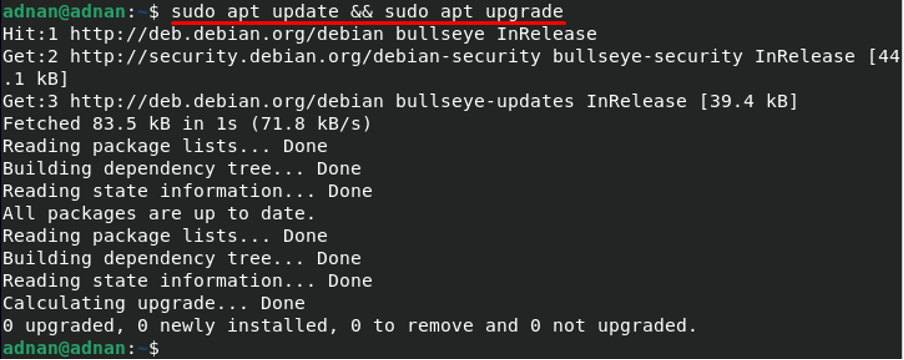
|
||||
|
||||
**Step 2: Install PostgreSQL
|
||||
**The required package resides in Debian repository so you can install it by using “**apt**”: install PostgreSQL by issuing the command mentioned below:
|
||||
|
||||
$ sudo apt install postgresql postgresql-contrib
|
||||
|
||||
|
||||
|
||||
Once PostgreSQL is installed, you can check the status of service by using the command given below:
|
||||
|
||||
$ sudo systemctl status PostgreSQL
|
||||
|
||||

|
||||
|
||||
Moreover, the status of service can be changed by using the following commands:
|
||||
|
||||
To stop the running PostgreSQL service:
|
||||
|
||||
$ sudo systemctl stop PostgreSQL
|
||||
|
||||
|
||||
|
||||
And to start the stopped service:
|
||||
|
||||
$ sudo systemctl start PostgreSQL
|
||||
|
||||
|
||||
|
||||
## **Method 2: How to install PostgreSQL using official repository of Debian 11**
|
||||
|
||||
Follow the simple steps mentioned below to add the official repository of PostgreSQL for Debian 11 and then install it; you can follow the steps mentioned below to do so:
|
||||
|
||||
**Step 1: Add PostgreSQL repository
|
||||
**It is recommended to add the official repo of PostgreSQL, so that you get the latest version of packages: firstly, you have to add the GPG signing key of PostgreSQL packages to secure the package repository: you can do so by issuing the command mentioned below:
|
||||
|
||||
$ curl -fsSL https://www.postgresql.org/media/keys/ACCC4CF8.asc | sudo gpg --dearmor -o /usr/share/keyrings/postgresql-keyring.gpg
|
||||
|
||||

|
||||
|
||||
Now, you are ready to add PostgreSQL repository: use the command mentioned below to perform the action:
|
||||
|
||||
$ echo "deb \[signed-by=/usr/share/keyrings/postgresql-keyring.gpg\] http://apt.postgresql.org/pub/repos/apt/ bullseye-pgdg main" | sudo tee /etc/apt/sources.list.d/postgresql.list
|
||||
|
||||

|
||||
|
||||
**Step 2: Installation of PostgreSQL
|
||||
**After successful integration of PostgreSQL library you are ready to install it: but before this, it is recommended to update the system’s repository by using the command mentioned below:
|
||||
|
||||
Install PostgreSQL with the help of below-mentioned command:
|
||||
|
||||
$ sudo apt install PostgreSQL
|
||||
|
||||
|
||||
|
||||
## **How to create database using PostgreSQL in Debian 11**
|
||||
|
||||
PostgreSQL can be used as a postgres user only, if you set a password; otherwise you will not be able to log in as a postgres user: Use the following command to set up a password:
|
||||
|
||||
|
||||
|
||||
To create database in PostgreSQL, you must login to PostgreSQL server and then access its shell; use the following command to log in as a postgres user: it will ask for password; type your password and hit enter:
|
||||
|
||||
Now access the shell using postgres user by issuing the following keyword:
|
||||
|
||||

|
||||
|
||||
Once you have accessed the command shell of Postgres, you can now use SQL queries to perform several database related operations:
|
||||
|
||||
For instance, we want to create a database “**linuxhint**”; for that, we will use the following SQL query to do so:
|
||||
|
||||

|
||||
|
||||
To access the database log in as postgres user and use the following command to access database “**linuxhint**”:
|
||||
|
||||

|
||||
|
||||
**Note:** You can fall back to the postgres user by using “**\\q**”:
|
||||
|
||||
You can now add, delete, select data from the database by accessing the database on terminal. Moreover, to drop a database you have to come out of database by using “**\\q**” and then use the following command:
|
||||
|
||||

|
||||
|
||||
And if you try to access database “**linuxhint**”; the shell will display an error that “**linuxhint**” does not exists:
|
||||
|
||||

|
||||
|
||||
## **Conclusion**
|
||||
|
||||
PostgreSQL is a widely used Relational Database Management System used by several large companies ranging from large to medium size strength. Although it is a relational database it supports JSON for non-relational querying that makes PostgreSQL a favorite choice of organizations. This post provides the installation guide of PostgreSQL for Debian11, two methods are described here. Method 1 enables you to install PostgreSQL from Debian own’s packages repository, on the other hand you can follow Method 2 to get the updated PostgreSQL from its official repository.
|
||||
+170
@@ -0,0 +1,170 @@
|
||||
---
|
||||
page-title: "How to install and run bots for the Matrix network – /tmp/lab"
|
||||
url: https://www.tmplab.org/2020/04/01/how-to-install-and-run-bots-for-the-matrix-network/
|
||||
date: "2023-04-18 13:34:24"
|
||||
---
|
||||
[Matrix](https://en.wikipedia.org/wiki/Matrix_(protocol)) is a fun and exciting federated protocol that we’re using more and more at /tmp/lab.
|
||||
|
||||
**If you want to join the discussion, head to [our riot channel](https://riot.fuz.re/#/room/#tmplab:matrix.fuz.re) and check it out!**
|
||||
|
||||
Riot is a well-known web GUI for the Matrix protocol which could be defined as “a chat interface between IRC and Slack”. It’s cooler than IRC to some extend – backlogging is easier- and it is free software, not like Slack 🙂 Still, IRC, Slack and Riot have in common a capacity to use bots, and that’s what we’ll be drilling today: Matrix bots. Onward, my mechanical steed!
|
||||
|
||||
Note: Our privacy-aware assistance might interject here with some well founded critics of the Matrix ecosystem, which is not free enough as of now. Find here [a list of concerns](https://github.com/privacytoolsIO/services/issues/17) as a github issue tracker for more information.
|
||||
|
||||
Anyway, which bot to choose? There are [many](https://github.com/matrix-org/go-neb) [available](https://github.com/matrix-org/Matrix-NEB) [bots](https://github.com/leo-lb/fuzisup) for matrix and even [a page dedicated to them](https://matrix.org/bots/) on the project’s website. We chose [maubot](https://github.com/maubot/maubot).
|
||||
|
||||
|
||||
|
||||
The maubot homepage on github
|
||||
|
||||
**Why maubot?**
|
||||
|
||||
Well, first, it’s python, which we like. Also, it’s actually well coded: [Tulir Asokan](https://github.com/tulir) -the author- did an impressive work at providing [his own implementation of the matrix api](https://github.com/tulir/mautrix-python) which he plans to use to provide a number of bridges. It is modular, meaning that you can extend the functionnalities in a clean manner. And that leads us to hackability, writing your own plugins should be easy with maubot, more on that soon hopefuly.
|
||||
|
||||
## Deploying Maubot on a server
|
||||
|
||||
Though maubot proposes a docker install, we were not fans of that for system administration reasons. So we’ve made an install script in bash you can find in [this git project](https://git.interhacker.space/alban/maubot-installer).
|
||||
|
||||
|
||||
|
||||
The maubot installer project
|
||||
|
||||
This install script should really simplify your job. Assign in the DNS a subdomain name -say botsinspace.example.com- to your server IP address and the installation should be as simple as
|
||||
|
||||
```
|
||||
git clone https://git.interhacker.space/alban/maubot-installer.git
|
||||
cd maubot-installer
|
||||
bash install.sh
|
||||
```
|
||||
|
||||
After indicating your chosen subdomain, you can go for default answers, including the matrix.org homeserver, and should be fine for the rest of this tutorial.
|
||||
|
||||
Et voilà ! You should have a maubot instance running with Letsencrypt on https://botsinspace.example.com
|
||||
|
||||
## Creating your first bot
|
||||
|
||||
Once the maubot instance is up, understanding the maubot concepts will help you configure it.
|
||||
|
||||
*Plugins*
|
||||
|
||||
Plugins are the bots “brains”. They are python code and configuration files, ran in background by maubot. Ther are stored on the server as mbp files, which are archives using a zip compression.
|
||||
|
||||
*Clients*
|
||||
|
||||
Clients are the bots “physical presence”. They are in fact user accounts on matrix servers, no more no less.
|
||||
|
||||
*Instances*
|
||||
|
||||
Instances are associations of a plugin and a client. Once you have an instance, you have a bot!
|
||||
|
||||
So let’s start creating our first instance!
|
||||
|
||||
## **Add a plugin**
|
||||
|
||||
The project page [lists a number of plugins](https://github.com/maubot/maubot) based on the maubot framework.
|
||||
|
||||
To install a plugin, you have two options.
|
||||
|
||||
**Option 1. Use the web interface**
|
||||
|
||||
Log in your maubot instance, click on the plugins “⊕” button. A big UPLOAD button (cf. screenshot) shows up, click on it, select a plugin zip file on your disk, and there you go !
|
||||
|
||||
|
||||
|
||||
The maubot plugin menu
|
||||
|
||||
Easy right?
|
||||
|
||||
Well except one thing: where do you get that zip file in the first place? From the github “Get a zip copy of the project” button of a plugin page? Well, nuhuh, nope, that won’t work. Maubot will reject that zip file. Why?
|
||||
The github zip file contains the file “in a directory” called “$projectname-$branch” and maubot expects files to be at the root of the zip archive.
|
||||
So, the right way to go is:
|
||||
**٭** Download a zip file from a plugin repository home page
|
||||
**٭** Extract it locally
|
||||
**٭** Enter the newly created directory
|
||||
**٭** Select all its files and sub-directories
|
||||
**٭** Create a new zip archive with these
|
||||
**٭** Upload that zip file to maubot.
|
||||
|
||||
Or if you will, plugins might available as “mbp” files in the “release” section of their github page. Sadly, they’re not always up to date, so you might be left with a manual job to do.
|
||||
|
||||
**Option 2. Use the command line interface**
|
||||
|
||||
Well seeing this could be a bit complex and annoying to repeat we came up with a script in the “maubot installer” project, called [plugin-install.sh](https://git.interhacker.space/alban/maubot-installer/raw/branch/master/plugins-install.sh)
|
||||
|
||||
You will need to use a config file or edit the variables at the beginning of the script for it to work though.
|
||||
|
||||
Once you’ve done it you just have to
|
||||
**٭** Run the script
|
||||
**٭** Select a plugin in the list
|
||||
**٭** Login (once only) with your maubot user and password
|
||||
**٭** And the script will call the “mbc” executable provided by maubot.
|
||||
|
||||
It is worth mentioning that some plugins might require a few additional dependencies. For example the [trump plugin](https://github.com/jeffcasavant/MaubotTrumpTweet) required to run an install command in the virtualenv of the project:
|
||||
|
||||
```
|
||||
cd /opt/maubot
|
||||
source bin/activate
|
||||
pip install Pillow
|
||||
```
|
||||
|
||||
But now, you should have at least one plugin available. Let’s head to the next stop.
|
||||
|
||||
## **Add a client**
|
||||
|
||||
We won’t cover here the run-your-own-bot-factory approach, which requires running your own synapse server, in other word running your own matrix instance. So we will create an account on an existing server and retrieve its token used for interacting with the API.
|
||||
|
||||
We will use the default web interface [https://riot.im/app](https://riot.im/app) and request a free matrix.org account.
|
||||
|
||||
|
||||
|
||||
The Riot.im home
|
||||
|
||||
You have to pick a username, for example rook\_the\_bot, which will provide a matrix identifier/address such as “@rook\_the\_bot:matrix.org” after creation.
|
||||
|
||||
|
||||
|
||||
The riot account creation interface
|
||||
|
||||
One your mail is validated, log in the web interface and head to the settings page to retrieve the token.
|
||||
|
||||
|
||||
|
||||
A Riot settings menu link
|
||||
|
||||
You will find it token at the end of the “Help & About” page: click on the <click to reveal> link, and copy the string that appears.
|
||||
|
||||
|
||||
|
||||
Riot token finally shows up!
|
||||
|
||||
Time to head back to your maubot instance, and click on the Client “⊕” button. Fill the requested informations : the username you created and the access token are mandatory. Validate.
|
||||
|
||||
|
||||
|
||||
The maubot client menu
|
||||
|
||||
And that’s it. You’re ready for the last stage.
|
||||
|
||||
## **Add an instance**
|
||||
|
||||
Head your maubot instance and client on the Instances “⊕” button.
|
||||
|
||||
|
||||
|
||||
The maubot instance menu
|
||||
|
||||
Just pick a client and a plugin before validating.
|
||||
|
||||
And now you should have your first bot ready! Congratulations!
|
||||
|
||||
## How to use your bot
|
||||
|
||||
Now if everything went well, you should be able to invite your bot in a room, using the matrix handle you created earlier, as in our example rook\_the\_bot@matrix.org.
|
||||
|
||||
Let’s say you created an “Instance” associating the [dice](https://github.com/maubot/dice) “Plugin” to the rook\_the\_bot “Client” .
|
||||
|
||||
Once you invited rook\_the\_bot to your channel, simply type a `!dice` command. Your bot should after a while reply to you.
|
||||
|
||||
Each plugin has its own commands, and you can attach multiple plugins to a single client. But all commands use the front `!` mark.
|
||||
|
||||
**That’s it, have fun. And for questions or anything else… see you on matrix!**
|
||||
@@ -0,0 +1,266 @@
|
||||
---
|
||||
page-title: "How to setup your OTP appliance with privacyIDEA"
|
||||
url: https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/
|
||||
date: "2023-04-27 20:56:48"
|
||||
---
|
||||
### On this page
|
||||
|
||||
1. [Base installation](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#base-installation)
|
||||
2. [Install privacyIDEA](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#install-privacyidea)
|
||||
3. [Configure your appliance](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#configure-your-appliance)
|
||||
1. [Create your token administrator](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#create-your-token-administrator)
|
||||
2. [Create the MySQL database](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#create-the-mysql-database)
|
||||
3. [Create your RADIUS clients](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#create-your-radius-clients)
|
||||
4. [Done configuring](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#done-configuring)
|
||||
4. [Enroll your Token](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#enroll-your-token)
|
||||
1. [Connect to user source](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#connect-to-user-source)
|
||||
2. [Enroll a token to the user](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#enroll-a-token-to-the-user)
|
||||
5. [Test your system](https://www.howtoforge.com/how-to-setup-otp-appliance-with-privacyidea/#test-your-system)
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/server.png)
|
||||
*by Nemo @ pixabay*
|
||||
|
||||
In this howto we will setup a system that can act as your own personal OTP appliance, managing all authentication devices in your network. You then may configure your services to authenticate against this machine. It is a good idea to use some virtualization mechanism. If you have some old hardware around, this is even as good.
|
||||
|
||||
We will install [privacyIDEA](http://privacyidea.org/) on an Ubuntu 14.04 LTS system, which you may have seen earlier [here](https://www.howtoforge.com/how-to-run-privacyidea-with-apache2-and-mysql-on-ubuntu-14.04-lts) or [here](https://www.howtoforge.com/two-factor-authentication-with-otp-using-privacyidea-and-freeradius-on-centos). But this time we will do it even smoother and more elegant!
|
||||
|
||||
## Base installation
|
||||
|
||||
**Disclaimer:** I assume you are user root in this scenario. If not, you should add "sudo" in front of every command.
|
||||
|
||||
So first we install a [plain ubuntu server 14.04 LTS](http://releases.ubuntu.com/14.04/ubuntu-14.04.1-server-amd64.iso) with nothing on it. Please do not install any database or webserver. You should only select openssh to run as a service on this machine.
|
||||
|
||||
## Install privacyIDEA
|
||||
|
||||
privacyIDEA 1.3.3 comes with a bunch of new debian packages in a launchpad repository, which makes it eaven easier to setup.
|
||||
|
||||
First we need to add the repository to the system:
|
||||
|
||||
apt-get install software-properties-common
|
||||
add-apt-repository ppa:privacyidea/privacyidea
|
||||
apt-get update
|
||||
|
||||
Now that we added the privacyidea repository, you can take a look, what is available:
|
||||
|
||||
root@ubuntu:~# apt-cache search privacyidea
|
||||
privacyidea - two-factor authentication system e.g. for OTP devices
|
||||
privacyideaadm - admin client for privacyIDEA
|
||||
privacyidea-radius - FreeRADIUS module for privacyIDEA, OTP authentication
|
||||
privacyidea-all - two-factor authenticaion system. This is a metapackage to install everything.
|
||||
privacyidea-otrs - OTRS module for privacyIDEA, OTP authentication
|
||||
privacyidea-nginx - two-factor authentication system. This is a meta package to install privacyidea with nginx
|
||||
privacyidea-appliance - two-factor authentication system. This is a setup tool for easy system setup.
|
||||
|
||||
There are different (meta)-packages for different scenarios. As mentioned, we would like to install a kind of "appliance". So lets do it:
|
||||
|
||||
apt-get install privacyidea-appliance privacyidea-radius
|
||||
|
||||
This will install the Nginx webserver, MySQL database, the FreeRADIUS server and privacyIDEA with all the python dependencies.
|
||||
|
||||
You will be asked to enter a MySQL root password. Choose a good one - we do not need it later! ;-)
|
||||
|
||||
After the installation you are ready to configure your appliance.
|
||||
|
||||
## Configure your appliance
|
||||
|
||||
There is a tool to configure all necessary means of your appliance. Start it at the command line as user root.
|
||||
|
||||
privacyidea-setup-tui
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/startscreen.png)
|
||||
|
||||
This is a dialog based text UI tool, that lets you perform all relevant tasks on the operating system level like managing your token administrators, setting log levels, regenerating encryption and signing keys, set the right webservice and RADIUS sevice and managing your RADIUS clients.
|
||||
|
||||
At least we need to perform the following tasks:
|
||||
|
||||
- create at least one token administrator
|
||||
- create the MySQL database
|
||||
- create a RADIUS client
|
||||
|
||||
Go through the tool to get familiar, what can be done.
|
||||
|
||||
The tool is based on parser logic for the FreeRADIUS client files, privacyIDEA ini files and the nginx file. So you can also edit the files at the command line, the changes will be preserved.
|
||||
|
||||
**Note:** The setup tool will not preserve any comments in the files, if you edit those files manually!
|
||||
|
||||
### Create your token administrator
|
||||
|
||||
To manage your token administrators go to *privacyidea* ? *manage admins*.
|
||||
|
||||
There you can choose *Add new admin*.
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/add-new-admin.png)
|
||||
You will be asked for:
|
||||
|
||||
- A username, where I choose *admin* and
|
||||
- the password (twice!) which is not echoed on the screen.
|
||||
|
||||
After that, you will see the new token admin in the list. You can repeat this step as often as you wish to. You can delete an administrator or change the password, by choose the administrator from the list.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/admin-list.png)
|
||||
|
||||
Now you created your admin (or admins) you can hit cancel and cancel and return to the main menu.
|
||||
|
||||
### Create the MySQL database
|
||||
|
||||
You also might skipt this step. privacyIDEA would then run with the SQLite database at /var/lib/privacyidea/. But we choose to use a MySQL database in this scenario.
|
||||
|
||||
So go to *privacyIDEA* ? *database*...
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/db1.png)
|
||||
|
||||
There you can choose *reset locally*, which will create the MySQL database, create a user and setup the database tables.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/db2.png)
|
||||
|
||||
Yes, we do!
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/db3.png)
|
||||
|
||||
Finally you see the new configuration, using the MySQL database.
|
||||
|
||||
### Create your RADIUS clients
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/clientconfig1.png)
|
||||
|
||||
In the main menu choose *FreeRADIUS* ? *client config* to manage your RADIUS clients. The default /etc/freeradius/clients.conf comes with a localhost client, this is why you already see one client in the list.
|
||||
|
||||
**Note:** You can not delete the last client, so we create new clients!
|
||||
|
||||
We will create a client network to cope with all possible clients in your network and the client localhost, to run tests against the system. So I choose these values - you should adapt the network accordingly:
|
||||
|
||||
1. mynetwork
|
||||
|
||||
name: mynetwork
|
||||
|
||||
ip: 172.16.200.0
|
||||
|
||||
netmask: 24
|
||||
|
||||
secret: topSecret4All
|
||||
|
||||
shortname: *empty*
|
||||
2. localhost
|
||||
|
||||
name: localhost
|
||||
|
||||
ip: 127.0.0.1
|
||||
|
||||
netmask: 32
|
||||
|
||||
secret: topSecretOnce
|
||||
|
||||
shortname: *empty*
|
||||
|
||||
We choose *Add new client* to create the new client "mynetwork" and the dialogs will ask us for the above values. Thus all clients on the network 172.16.200.0/24 will be able to issue a RADIUS request with the RADIUS secret "topSecret4All".
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/newclient1.png)
|
||||
*The name of the client configuration*
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/newclient2.png)
|
||||
*The IP address*
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/newclient3.png)
|
||||
*The netmask*
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/newclient4.png)
|
||||
*The shared secret*
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/newclient5.png)
|
||||
*The shortname can be left blank*
|
||||
|
||||
You can select the client "localhost" and delete it. After that you can create a new client "localhost" according to the above settings.
|
||||
|
||||
### Done configuring
|
||||
|
||||
Now you are done configuring the base system. The setup tool should realize, that you change important data and restart the services. But just to be sure you can do this manually:
|
||||
|
||||
service uwsgi restart
|
||||
service freeradius restart
|
||||
|
||||
## Enroll your Token
|
||||
|
||||
You can now enroll your authentication devices, which is done using the management Web UI. Point your browser to https://your-server, accept the certificate warning of the self signed certificate and you will get the login screen:
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/login-screen.png)
|
||||
|
||||
On this login screen you can login as a token administrator. All the token administrator you created need to add "@admin" to their name, to indicate, that they are administrators.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/webui1.png)
|
||||
|
||||
The web UI gives you a view of tokens, users, policies, machines and the audit log.
|
||||
|
||||
### Connect to user source
|
||||
|
||||
As privacyIDEA does not manage users itself we need to read users from some source. We will use the /etc/passwd file.
|
||||
|
||||
Click on *privacyIDEA config* ? *useridresolvers*, click the button *New* and select *Flatfile*.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/flatfile.png)
|
||||
|
||||
Click *save* to save the resolver definition with the name "local".
|
||||
|
||||
**Note:** At any point you may click the white question mark in the green circle which will take you to the context online help in another browser window. In fact it might be a good idea to read something about resolvers and realms ;-).
|
||||
|
||||
When you close the resolver window you will be either taken automatically to the realm window or you can click *privacyIDEA Config* ? *realms* to create a new realm. In this dialog you need to click *New*.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/realms1.png)
|
||||
|
||||
Enter the name of the realm ("realm1") and select the resolver ("local") and click *Save*.
|
||||
|
||||
Then you will see the new realm in your realm list.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/realms2.png)
|
||||
|
||||
You may close the window and click the tab *User View*.
|
||||
|
||||
### Enroll a token to the user
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/userview.png)
|
||||
|
||||
At the bottom you can search for a user by entering "r\*" and clicking the *search* button. You will see the user root. Select the user by clicking on it. The user will be mentioned in the left sidebar as selected user. Now you can click the button *enroll* in the left sidebar.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/sidebar.png)
|
||||
|
||||
Then the enrollment dialog will open. Choose the "HMAC eventbased" token type and select *generate HMAC key*.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/enroll.png)
|
||||
|
||||
Click the button *Enroll*. The server will create a secret key and render a QR code that can be scanned with the Google Authenticator App. This Google Authenticator app will now work as an authentication device.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/qr.png)
|
||||
|
||||
After you have scanned the QR code you can click *OK* and finally set a PIN - a password that only you know - for this very token.
|
||||
|
||||
[](https://www.howtoforge.com/images/otp-appliance-with-privacyidea/big/pin.png)
|
||||
|
||||
Now you have two factors to authenticate with - the PIN and the OTP value generated by your authentication device.
|
||||
|
||||
## Test your system
|
||||
|
||||
Now we can check the system by issuing a RADIUS request to this appliance. I will do it from the system itself being logged in as root via ssh with a command like:
|
||||
|
||||
echo "User-Name=root, Password=PIN+OTP" | radclient -s 127.0.0.1 auth topSecretOnce
|
||||
|
||||
The *Password* being concatenated from the PIN and the OTP value and "topSecretOnce" being the shared secret for the localhost.
|
||||
|
||||
root@ubuntu:~# echo "User-Name=root, Password=test570391" | radclient -s 127.0.0.1 auth topSecretOnce
|
||||
Received response ID 209, code 3, length = 55
|
||||
Reply-Message = "privacyIDEA server denied access!"
|
||||
|
||||
Total approved auths: 0
|
||||
Total denied auths: 1
|
||||
Total lost auths: 0
|
||||
|
||||
root@ubuntu:~# echo "User-Name=root, Password=test137634" | radclient -s 127.0.0.1 auth topSecretOnce
|
||||
Received response ID 180, code 2, length = 48
|
||||
Reply-Message = "privacyIDEA access granted"
|
||||
|
||||
Total approved auths: 1
|
||||
Total denied auths: 0
|
||||
Total lost auths: 0
|
||||
|
||||
**Note:** Due to a different starting counter in the App and in the server the first authentication will fail.
|
||||
|
||||
Now you can take all your RADIUS enabled applications (Firewall, OpenVPN) and configure it to authenticate against privacyIDEA using the previously defined shared secret.
|
||||
|
||||
Happy authenticating!
|
||||
+193
@@ -0,0 +1,193 @@
|
||||
---
|
||||
page-title: "Install and Run on AMD GPUs · AUTOMATIC1111/stable-diffusion-webui Wiki"
|
||||
url: https://github.com/AUTOMATIC1111/stable-diffusion-webui/wiki/Install-and-Run-on-AMD-GPUs
|
||||
date: "2023-04-23 18:19:53"
|
||||
---
|
||||
|
||||
> python -m venv venv
|
||||
|
||||
---
|
||||
|
||||
## Windows
|
||||
|
||||
Windows+AMD support has **not** officially been made for webui,
|
||||
but you can install lshqqytiger's fork of webui that uses **Direct-ml**.
|
||||
|
||||
\-Training currently doesn't work, yet a variety of features/extensions do, such as LoRAs and controlnet. Report issues at [https://github.com/lshqqytiger/stable-diffusion-webui-directml/issues](https://github.com/lshqqytiger/stable-diffusion-webui-directml/issues)
|
||||
|
||||
1. Install [Python 3.10.6](https://www.python.org/ftp/python/3.10.6/python-3.10.6-amd64.exe) (ticking **Add to PATH**), and [git](https://github.com/git-for-windows/git/releases/download/v2.39.2.windows.1/Git-2.39.2-64-bit.exe)
|
||||
2. paste this line in cmd/terminal: `git clone https://github.com/lshqqytiger/stable-diffusion-webui-directml && cd stable-diffusion-webui-directml && git submodule init && git submodule update`
|
||||
(you can move the program folder somewhere else.)
|
||||
3. Double-click webui-user.bat
|
||||
4. If it looks like it is stuck when installing or running, press enter in the terminal and it should continue.
|
||||
|
||||
If you have 4-6gb vram, try adding these flags to \`webui-user.bat\` like so:
|
||||
|
||||
- `COMMANDLINE_ARGS=--opt-sub-quad-attention --lowvram --disable-nan-check`
|
||||
|
||||
- You can add --autolaunch to auto open the url for you.
|
||||
|
||||
|
||||
(The rest **below are installation guides for linux** with rocm.)
|
||||
|
||||
## Automatic Installation
|
||||
|
||||
(As of [1/15/23](https://github.com/AUTOMATIC1111/stable-diffusion-webui/pull/6709) you can just run webui-user.sh and pytorch+rocm should be automatically installed for you.)
|
||||
|
||||
1. Install Python 3.10.6
|
||||
|
||||
2. git clone [https://github.com/AUTOMATIC1111/stable-diffusion-webui](https://github.com/AUTOMATIC1111/stable-diffusion-webui)
|
||||
|
||||
3. Place stable diffusion checkpoint (model.ckpt) in the models/Stable-diffusion directory
|
||||
|
||||
4. For many AMD gpus you MUST Add `--precision full` `--no-half` to `COMMANDLINE_ARGS=` in **webui-user.sh** to avoid black squares or crashing.\*
|
||||
|
||||
5. Run **webui.sh**
|
||||
|
||||
|
||||
\*Certain cards like the Radeon RX 6000 Series and the RX 500 Series will function normally without the option `--precision full --no-half`, saving plenty of vram. (noted [here](https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/5468).)
|
||||
|
||||
## Running natively
|
||||
|
||||
Execute the following:
|
||||
|
||||
git clone https://github.com/AUTOMATIC1111/stable-diffusion-webui
|
||||
cd stable-diffusion-webui
|
||||
python -m venv venv
|
||||
source venv/bin/activate
|
||||
python -m pip install --upgrade pip wheel
|
||||
|
||||
# It's possible that you don't need "--precision full", dropping "--no-half" however crashes my drivers
|
||||
TORCH\_COMMAND='pip install torch torchvision --extra-index-url https://download.pytorch.org/whl/rocm5.1.1' python launch.py --precision full --no-half
|
||||
|
||||
In following runs you will only need to execute:
|
||||
|
||||
cd stable-diffusion-webui
|
||||
# Optional: "git pull" to update the repository
|
||||
source venv/bin/activate
|
||||
|
||||
# It's possible that you don't need "--precision full", dropping "--no-half" however crashes my drivers
|
||||
TORCH\_COMMAND='pip install torch torchvision --extra-index-url https://download.pytorch.org/whl/rocm5.1.1' python launch.py --precision full --no-half
|
||||
|
||||
The first generation after starting the WebUI might take very long, and you might see a message similar to this:
|
||||
|
||||
> MIOpen(HIP): Warning \[SQLiteBase\] Missing system database file: gfx1030\_40.kdb Performance may degrade. Please follow instructions to install: [https://github.com/ROCmSoftwarePlatform/MIOpen#installing-miopen-kernels-package](https://github.com/ROCmSoftwarePlatform/MIOpen#installing-miopen-kernels-package)
|
||||
|
||||
The next generations should work with regular performance. You can follow the link in the message, and if you happen to use the same operating system, follow the steps there to fix this issue. If there is no clear way to compile or install the MIOpen kernels for your operating system, consider following the "Running inside Docker"-guide below.
|
||||
|
||||
## Running inside Docker
|
||||
|
||||
Pull the latest `rocm/pytorch` Docker image, start the image and attach to the container (taken from the `rocm/pytorch` documentation): `docker run -it --network=host --device=/dev/kfd --device=/dev/dri --group-add=video --ipc=host --cap-add=SYS_PTRACE --security-opt seccomp=unconfined -v $HOME/dockerx:/dockerx rocm/pytorch`
|
||||
|
||||
Execute the following inside the container:
|
||||
|
||||
cd /dockerx
|
||||
git clone https://github.com/AUTOMATIC1111/stable-diffusion-webui
|
||||
cd stable-diffusion-webui
|
||||
python -m venv venv
|
||||
source venv/bin/activate
|
||||
python -m pip install --upgrade pip wheel
|
||||
|
||||
# It's possible that you don't need "--precision full", dropping "--no-half" however crashes my drivers
|
||||
TORCH\_COMMAND='pip install torch torchvision --extra-index-url https://download.pytorch.org/whl/rocm5.1.1' REQS\_FILE='requirements.txt' python launch.py --precision full --no-half
|
||||
|
||||
Following runs will only require you to restart the container, attach to it again and execute the following inside the container: Find the container name from this listing: `docker container ls --all`, select the one matching the `rocm/pytorch` image, restart it: `docker container restart <container-id>` then attach to it: `docker exec -it <container-id> bash`.
|
||||
|
||||
cd /dockerx/stable-diffusion-webui
|
||||
# Optional: "git pull" to update the repository
|
||||
source venv/bin/activate
|
||||
|
||||
# It's possible that you don't need "--precision full", dropping "--no-half" however crashes my drivers
|
||||
TORCH\_COMMAND='pip install torch torchvision --extra-index-url https://download.pytorch.org/whl/rocm5.1.1' REQS\_FILE='requirements.txt' python launch.py --precision full --no-half
|
||||
|
||||
The `/dockerx` folder inside the container should be accessible in your home directory under the same name.
|
||||
|
||||
## Updating Python version inside Docker
|
||||
|
||||
If the web UI becomes incompatible with the pre-installed Python 3.7 version inside the Docker image, here are instructions on how to update it (assuming you have successfully followed "Running inside Docker"):
|
||||
|
||||
Execute the following inside the container:
|
||||
|
||||
apt install python3.9-full # Confirm every prompt
|
||||
update-alternatives --install /usr/local/bin/python python /usr/bin/python3.9 1
|
||||
echo 'PATH=/usr/local/bin:$PATH' \>> ~/.bashrc
|
||||
|
||||
Then restart the container and attach again. If you check `python --version` it should now say `Python 3.9.5` or newer.
|
||||
|
||||
Run `rm -rf /dockerx/stable-diffusion-webui/venv` inside the container and then follow the steps in "Running inside Docker" again, skipping the `git clone https://github.com/AUTOMATIC1111/stable-diffusion-webui` and using the modified launch-command below instead:
|
||||
|
||||
TORCH\_COMMAND='pip install torch torchvision --extra-index-url https://download.pytorch.org/whl/rocm5.1.1' python launch.py --precision full --no-half
|
||||
|
||||
It's possible that you don't need "--precision full", dropping "--no-half" however it may not work for everyone. Certain cards like the Radeon RX 6000 Series and the RX 500 Series will function normally without the option `--precision full --no-half`, saving plenty of vram. (noted [here](https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/5468).)
|
||||
|
||||
Always use this new launch-command from now on, also when restarting the web UI in following runs.
|
||||
|
||||
## Install on AMD and Arch Linux
|
||||
|
||||
**Install webui on Arch Linux with Arch-specific packages**
|
||||
*and possibly other Arch-based Linux distributions (tested Feb 22 2023)*
|
||||
|
||||
## Arch-specific dependencies
|
||||
|
||||
1. Start with [required dependencies](https://github.com/AUTOMATIC1111/stable-diffusion-webui/wiki/Dependencies#required-dependencies) and install `pip`
|
||||
|
||||
sudo pacman -S python-pip
|
||||
|
||||
2. Install `pytorch` with ROCm backend
|
||||
|
||||
Arch \[Community\] repository offers two `pytorch` packages, `python-pytorch-rocm` and `python-pytorch-opt-rocm`. For CPUs with AVX2 instruction set support, that is, CPU microarchitectures beyond Haswell (Intel, 2013) or Excavator (AMD, 2015), install `python-pytorch-opt-rocm` to benefit from performance optimizations. Otherwise install `python-pytorch-rocm`:
|
||||
|
||||
# Install either one:
|
||||
sudo pacman -S python-pytorch-rocm
|
||||
sudo pacman -S python-pytorch-opt-rocm # AVX2 CPUs only
|
||||
|
||||
3. Install `torchvision` with ROCm backend
|
||||
|
||||
`python-torchvision-rocm` package is located in AUR. Clone the git repository and compile the package on your machine
|
||||
|
||||
git clone https://aur.archlinux.org/python-torchvision-rocm.git
|
||||
cd python-torchvision-rocm
|
||||
makepkg -si
|
||||
|
||||
Confirm all steps until Pacman finishes installing `python-torchvision-rocm`.
|
||||
|
||||
Alternatively, install the `python-torchvision-rocm` package with a [AUR helper](https://wiki.archlinux.org/title/AUR_helpers).
|
||||
|
||||
## Setup `venv` environment
|
||||
|
||||
1. Manually create a `venv` environment with system site-packages (this will allows access to system `pytorch` and `torchvision`). Install the remaining Python dependencies
|
||||
|
||||
python -m venv venv --system-site-packages
|
||||
source venv/bin/activate
|
||||
pip install -r requirements.txt
|
||||
|
||||
2. Create webui launch script
|
||||
|
||||
The Python launcher for webui needs to be run directly. In the project folder, create a new file called `webui-py.sh` and paste the following code:
|
||||
|
||||
#!/bin/bash
|
||||
python launch.py #add arguments here
|
||||
|
||||
Depending on the GPU model, you may need to add certain [Command Line Arguments](https://github.com/AUTOMATIC1111/stable-diffusion-webui/wiki/Command-Line-Arguments-and-Settings) and [Optimizations](https://github.com/AUTOMATIC1111/stable-diffusion-webui/wiki/Optimizations) for webui to run properly. Also refer to the [Automatic Installation](https://github.com/AUTOMATIC1111/stable-diffusion-webui/wiki/Install-and-Run-on-AMD-GPUs#automatic-installation) section for AMD GPUs.
|
||||
|
||||
3. Make the script executable and run webui (first start may take a bit longer)
|
||||
|
||||
sudo chmod +x ./webui-py.sh
|
||||
./webui-py.sh
|
||||
|
||||
## Launch
|
||||
|
||||
Run the following inside the project root to start webui:
|
||||
|
||||
source venv/bin/activate
|
||||
./webui-py.sh
|
||||
|
||||
## Limitations
|
||||
|
||||
- GPU model has to be supported by Arch dependencies
|
||||
|
||||
See if your GPU is listed as a build architecture in `PYTORCH_ROCM_ARCH` variable for [Tourchvision](https://github.com/rocm-arch/python-torchvision-rocm/blob/b66f7ed9540a0e25f4a81bf0d9cfc3d76bc0270e/PKGBUILD#L68-L74) and [PyTorch](https://github.com/archlinux/svntogit-community/blob/5689e7f44f082ba3c37724c2890e93e7106002a1/trunk/PKGBUILD#L220). References for architectures can be found [here](https://llvm.org/docs/AMDGPUUsage.html#processors). If not, consider building both packages locally or use another [installation method](https://github.com/AUTOMATIC1111/stable-diffusion-webui/wiki/Install-and-Run-on-AMD-GPUs).
|
||||
|
||||
- Arch dependencies (`pytorch`, `torchvision`) are kept up-to-date by full system updates (`pacman -Syu`) and compiling, which may not be desirable when dependency combinations with fixed versions are wished
|
||||
|
||||
*This guide has been tested on AMD Radeon RX6800 with Python 3.10.9, ROCm 5.4.3, PyTorch 1.13.1, Torchvision 0.14.1*
|
||||
@@ -0,0 +1,190 @@
|
||||
---
|
||||
page-title: "Installation - Docs - Appwrite"
|
||||
url: https://appwrite.io/docs/installation
|
||||
date: "2023-04-06 23:41:10"
|
||||
---
|
||||
## Table of contents
|
||||
|
||||
- [Home](https://appwrite.io/docs)
|
||||
|
||||
**Getting Started**
|
||||
|
||||
- [Installation](https://appwrite.io/docs/installation)
|
||||
- [Production](https://appwrite.io/docs/production)
|
||||
- [Env. Variables](https://appwrite.io/docs/environment-variables)
|
||||
- [Email Delivery](https://appwrite.io/docs/email-delivery)
|
||||
- [SMS Delivery](https://appwrite.io/docs/sms-delivery)
|
||||
- [Certificates](https://appwrite.io/docs/certificates)
|
||||
- [Debugging](https://appwrite.io/docs/debugging)
|
||||
- [Upgrade](https://appwrite.io/docs/upgrade)
|
||||
- [Appwrite for Web](https://appwrite.io/docs/getting-started-for-web)
|
||||
- [Appwrite for Flutter](https://appwrite.io/docs/getting-started-for-flutter)
|
||||
- [Appwrite for Apple](https://appwrite.io/docs/getting-started-for-apple)
|
||||
- [Appwrite for Android](https://appwrite.io/docs/getting-started-for-android)
|
||||
- [Appwrite for Server](https://appwrite.io/docs/getting-started-for-server)
|
||||
- [Appwrite CLI](https://appwrite.io/docs/command-line)
|
||||
- [Deployment](https://appwrite.io/docs/command-line-deployment)
|
||||
- [Commands](https://appwrite.io/docs/command-line-commands)
|
||||
- [CI Mode](https://appwrite.io/docs/command-line-ci)
|
||||
- [SDKs](https://appwrite.io/docs/sdks)
|
||||
|
||||
**APIs**
|
||||
|
||||
- [REST](https://appwrite.io/docs/rest)
|
||||
- [GraphQL](https://appwrite.io/docs/graphql)
|
||||
- [Realtime](https://appwrite.io/docs/realtime)
|
||||
|
||||
**References**
|
||||
|
||||
- [Account](https://appwrite.io/docs/client/account)
|
||||
- [Users](https://appwrite.io/docs/server/users)
|
||||
- [Teams](https://appwrite.io/docs/client/teams)
|
||||
- [Databases](https://appwrite.io/docs/client/databases)
|
||||
- [Storage](https://appwrite.io/docs/client/storage)
|
||||
- [Functions](https://appwrite.io/docs/client/functions)
|
||||
- [Localization](https://appwrite.io/docs/client/locale)
|
||||
- [Avatars](https://appwrite.io/docs/client/avatars)
|
||||
- [Health](https://appwrite.io/docs/server/health)
|
||||
|
||||
**Guides**
|
||||
|
||||
- [Databases](https://appwrite.io/docs/databases)
|
||||
- [Storage](https://appwrite.io/docs/storage)
|
||||
- [Authentication](https://appwrite.io/docs/authentication)
|
||||
- [Functions](https://appwrite.io/docs/functions)
|
||||
|
||||
**Advanced**
|
||||
|
||||
- [API Keys](https://appwrite.io/docs/keys)
|
||||
- [Permissions](https://appwrite.io/docs/permissions)
|
||||
- [Events](https://appwrite.io/docs/events)
|
||||
- [Pagination](https://appwrite.io/docs/pagination)
|
||||
- [Webhooks](https://appwrite.io/docs/webhooks)
|
||||
- [Custom Domains](https://appwrite.io/docs/custom-domains)
|
||||
- [Response Codes](https://appwrite.io/docs/response-codes)
|
||||
- [Rate Limits](https://appwrite.io/docs/rate-limits)
|
||||
|
||||
[Docs](https://appwrite.io/docs)
|
||||
|
||||
## Installation
|
||||
|
||||
Appwrite is a self-hosted backend server, packaged as a set of Docker containers. You can install and run Appwrite on any operating system that can run a [Docker CLI](https://www.docker.com/products/docker-desktop). You can use Appwrite on your local machine or a cloud provider of your choice.
|
||||
|
||||
## [System Requirements](https://appwrite.io/docs/installation#systemRequirements)
|
||||
|
||||
Appwrite is designed to run well on both small and large deployments. The minimum requirements to run Appwrite are as little as **1 CPU core** and **2GB of RAM**, and an operating system that supports Docker.
|
||||
|
||||
Appwrite requires [Docker Compose Version 2](https://docs.docker.com/compose/install/). To install Appwrite, make sure your Docker installation is updated to support Composer V2.
|
||||
|
||||
### Upgrading From Older Versions
|
||||
|
||||
If you are migrating from an older version of Appwrite, you need to follow the [migration instructions](https://appwrite.io/docs/upgrade).
|
||||
|
||||
## [Install with Docker](https://appwrite.io/docs/installation#installWithDocker)
|
||||
|
||||
The easiest way to start running your Appwrite server is by running our Docker installer tool from your terminal. Before running the installation command, make sure you have [Docker CLI](https://www.docker.com/products/docker-desktop) installed on your host machine.
|
||||
|
||||
You will be prompted to configure the following during the setup command:
|
||||
|
||||
1. Your Appwrite instance's HTTP and HTTPs ports.
|
||||
2. Your Appwrite instance's secret key which used to encrypt sensitive data.
|
||||
3. Your Appwrite instance's main hostname. Appwrite will generate a certificate using this hostname.
|
||||
4. Your Appwrite instance's DNS A record hostname. Typically set to the same value as your Appwrite instance's hostname.
|
||||
|
||||
### [Unix](https://appwrite.io/docs/installation#unix)
|
||||
|
||||
```
|
||||
docker run -it --rm \
|
||||
--volume /var/run/docker.sock:/var/run/docker.sock \
|
||||
--volume "$(pwd)"/appwrite:/usr/src/code/appwrite:rw \
|
||||
--entrypoint="install" \
|
||||
appwrite/appwrite:1.2.1
|
||||
```
|
||||
|
||||
*Click Here to Copy*
|
||||
|
||||
### [Windows](https://appwrite.io/docs/installation#windows)
|
||||
|
||||
Hyper-V and Containers Windows features must be enabled to run Appwrite on Windows with Docker. If you don't have these features available, you can install [Docker Desktop](https://docs.docker.com/desktop/windows/install/) which uses Virtualbox to run Appwrite on a Virtual Machine.
|
||||
|
||||
- CMD
|
||||
- PowerShell
|
||||
|
||||
- #### CMD
|
||||
|
||||
```
|
||||
docker run -it --rm ^
|
||||
--volume //var/run/docker.sock:/var/run/docker.sock ^
|
||||
--volume "%cd%"/appwrite:/usr/src/code/appwrite:rw ^
|
||||
--entrypoint="install" ^
|
||||
appwrite/appwrite:1.2.1
|
||||
```
|
||||
|
||||
*Click Here to Copy*
|
||||
|
||||
- #### PowerShell
|
||||
|
||||
```
|
||||
docker run -it --rm `
|
||||
--volume /var/run/docker.sock:/var/run/docker.sock `
|
||||
--volume ${pwd}/appwrite:/usr/src/code/appwrite:rw `
|
||||
--entrypoint="install" `
|
||||
appwrite/appwrite:1.2.1
|
||||
```
|
||||
|
||||
*Click Here to Copy*
|
||||
|
||||
|
||||
## [One-Click Setups](https://appwrite.io/docs/installation#one-click-setups)
|
||||
|
||||
In addition to running Appwrite locally, you can also launch Appwrite using a pre-configured setup. This allows you to get up and running with Appwrite quickly without installing Docker on your local machine.
|
||||
|
||||
Choose from one of the providers below:
|
||||
|
||||
Provider
|
||||
|
||||
 
|
||||
|
||||
DigitalOcean
|
||||
|
||||
[Click to Install](https://marketplace.digitalocean.com/apps/appwrite)
|
||||
|
||||
 
|
||||
|
||||
Gitpod
|
||||
|
||||
[Click to Install](https://gitpod.io/#https://github.com/appwrite/integration-for-gitpod)
|
||||
|
||||
### [Manual (using docker-compose.yml)](https://appwrite.io/docs/installation#manual)
|
||||
|
||||
For advanced Docker users, the manual installation might seem more familiar. To set up Appwrite manually, download the Appwrite base [docker-compose.yml](https://appwrite.io/install/compose) and [.env](https://appwrite.io/install/env) files, then move them inside a directory named `appwrite`. After the download completes, update the different environment variables as you wish in the `.env` file and start the Appwrite stack using the following Docker command:
|
||||
|
||||
```
|
||||
docker compose up -d --remove-orphans
|
||||
```
|
||||
|
||||
*Click Here to Copy*
|
||||
|
||||
Once the Docker installation completes, go to your machine's hostname or IP address on your browser to access the Appwrite console. Please note that on hosts that are not Linux-native, the server might take a few minutes to start after installation completes.
|
||||
|
||||
### [Stop](https://appwrite.io/docs/installation#stop)
|
||||
|
||||
You can stop your Appwrite containers by using the following command executed from the same directory as your `docker-compose.yml` file.
|
||||
|
||||
```
|
||||
docker compose stop
|
||||
```
|
||||
|
||||
*Click Here to Copy*
|
||||
|
||||
### [Uninstall](https://appwrite.io/docs/installation#uninstall)
|
||||
|
||||
To stop and remove your Appwrite containers, you can use the following command executed from the same directory as your `docker-compose.yml` file.
|
||||
|
||||
```
|
||||
docker compose down -v
|
||||
```
|
||||
|
||||
*Click Here to Copy*
|
||||
|
||||
## [Learn More](https://appwrite.io/docs/installation#learnMore)
|
||||
@@ -0,0 +1,29 @@
|
||||
---
|
||||
page-title: "Introduction | Hasura Backend Plus"
|
||||
url: https://nhost.github.io/hasura-backend-plus/docs/intro
|
||||
date: "2023-04-23 12:41:26"
|
||||
---
|
||||
## Introduction
|
||||
|
||||
Hasura Backend Plus handles **authentication** and **storage** for [Hasura](https://github.com/hasura/graphql-engine).
|
||||
|
||||
Hasura Backend Plus runs in a separate Docker container along side Postgres and Hasura.
|
||||
|
||||
## Authentication[#](https://nhost.github.io/hasura-backend-plus/docs/intro#authentication "Direct link to heading")
|
||||
|
||||
- Users and accounts are saved in the database.
|
||||
- JWT tokens and refresh tokens are automatically generated and managed.
|
||||
- Add custom user claims to the JWT token based on user data.
|
||||
- Hasura roles managed.
|
||||
- Two-factor authentication support.
|
||||
- Third-party OAuth providers such as GitHub, Google, Facebook, Twitter etc.
|
||||
- Magic Link support.
|
||||
- Built in transactional emails such as account activation and password reset.
|
||||
- Rate limiting.
|
||||
- Optional checking for [Pwned Passwords](https://haveibeenpwned.com/Passwords).
|
||||
|
||||
## Storage[#](https://nhost.github.io/hasura-backend-plus/docs/intro#storage "Direct link to heading")
|
||||
|
||||
- Backed by S3 (Minio).
|
||||
- Rules engine for file access permissions.
|
||||
- Out of the box image transformation.
|
||||
+156
@@ -0,0 +1,156 @@
|
||||
---
|
||||
page-title: "Introduction - Learning Rust With Entirely Too Many Linked Lists"
|
||||
url: https://rust-unofficial.github.io/too-many-lists/
|
||||
date: "2023-04-02 09:32:04"
|
||||
---
|
||||
## [Learn Rust With Entirely Too Many Linked Lists](https://rust-unofficial.github.io/too-many-lists/#learn-rust-with-entirely-too-many-linked-lists)
|
||||
|
||||
> Got any issues or want to check out all the final code at once? [Everything's on Github!](https://github.com/rust-unofficial/too-many-lists)
|
||||
|
||||
> **NOTE**: The current edition of this book is written against Rust 2018, which was first released with rustc 1.31 (Dec 8, 2018). If your rust toolchain is new enough, the Cargo.toml file that `cargo new` creates should contain the line `edition = "2018"` (or if you're reading this in the far future, perhaps some even larger number!). Using an older toolchain is possible, but unlocks a secret **hardmode**, where you get extra compiler errors that go completely unmentioned in the text of this book. Wow, sounds like fun!
|
||||
|
||||
I fairly frequently get asked how to implement a linked list in Rust. The answer honestly depends on what your requirements are, and it's obviously not super easy to answer the question on the spot. As such I've decided to write this book to comprehensively answer the question once and for all.
|
||||
|
||||
In this series I will teach you basic and advanced Rust programming entirely by having you implement 6 linked lists. In doing so, you should learn:
|
||||
|
||||
- The following pointer types: `&`, `&mut`, `Box`, `Rc`, `Arc`, `*const`, `*mut`, `NonNull`(?)
|
||||
- Ownership, borrowing, inherited mutability, interior mutability, Copy
|
||||
- All The Keywords: struct, enum, fn, pub, impl, use, ...
|
||||
- Pattern matching, generics, destructors
|
||||
- Testing, installing new toolchains, using `miri`
|
||||
- Unsafe Rust: raw pointers, aliasing, stacked borrows, UnsafeCell, variance
|
||||
|
||||
Yes, linked lists are so truly awful that you deal with all of these concepts in making them real.
|
||||
|
||||
Everything's in the sidebar (may be collapsed on mobile), but for quick reference, here's what we're going to be making:
|
||||
|
||||
1. [A Bad Singly-Linked Stack](https://rust-unofficial.github.io/too-many-lists/first.html)
|
||||
2. [An Ok Singly-Linked Stack](https://rust-unofficial.github.io/too-many-lists/second.html)
|
||||
3. [A Persistent Singly-Linked Stack](https://rust-unofficial.github.io/too-many-lists/third.html)
|
||||
4. [A Bad But Safe Doubly-Linked Deque](https://rust-unofficial.github.io/too-many-lists/fourth.html)
|
||||
5. [An Unsafe Singly-Linked Queue](https://rust-unofficial.github.io/too-many-lists/fifth.html)
|
||||
6. [TODO: An Ok Unsafe Doubly-Linked Deque](https://rust-unofficial.github.io/too-many-lists/sixth.html)
|
||||
7. [Bonus: A Bunch of Silly Lists](https://rust-unofficial.github.io/too-many-lists/infinity.html)
|
||||
|
||||
Just so we're all the same page, I'll be writing out all the commands that I feed into my terminal. I'll also be using Rust's standard package manager, Cargo, to develop the project. Cargo isn't necessary to write a Rust program, but it's *so much* better than using rustc directly. If you just want to futz around you can also run some simple programs in the browser via [play.rust-lang.org](https://play.rust-lang.org/).
|
||||
|
||||
In later sections, we'll be using "rustup" to install extra Rust tooling. I strongly recommend [installing all of your Rust toolchains using rustup](https://www.rust-lang.org/tools/install).
|
||||
|
||||
Let's get started and make our project:
|
||||
|
||||
```
|
||||
> cargo new --lib lists
|
||||
> cd lists
|
||||
```
|
||||
|
||||
We'll put each list in a separate file so that we don't lose any of our work.
|
||||
|
||||
It should be noted that the *authentic* Rust learning experience involves writing code, having the compiler scream at you, and trying to figure out what the heck that means. I will be carefully ensuring that this occurs as frequently as possible. Learning to read and understand Rust's generally excellent compiler errors and documentation is *incredibly* important to being a productive Rust programmer.
|
||||
|
||||
Although actually that's a lie. In writing this I encountered *way* more compiler errors than I show. In particular, in the later chapters I won't be showing a lot of the random "I typed (copy-pasted) bad" errors that you expect to encounter in every language. This is a *guided tour* of having the compiler scream at us.
|
||||
|
||||
We're going to be going pretty slow, and I'm honestly not going to be very serious pretty much the entire time. I think programming should be fun, dang it! If you're the type of person who wants maximally information-dense, serious, and formal content, this book is not for you. Nothing I will ever make is for you. You are wrong.
|
||||
|
||||
## [An Obligatory Public Service Announcement](https://rust-unofficial.github.io/too-many-lists/#an-obligatory-public-service-announcement)
|
||||
|
||||
Just so we're totally 100% clear: I hate linked lists. With a passion. Linked lists are terrible data structures. Now of course there's several great use cases for a linked list:
|
||||
|
||||
- You want to do *a lot* of splitting or merging of big lists. *A lot*.
|
||||
- You're doing some awesome lock-free concurrent thing.
|
||||
- You're writing a kernel/embedded thing and want to use an intrusive list.
|
||||
- You're using a pure functional language and the limited semantics and absence of mutation makes linked lists easier to work with.
|
||||
- ... and more!
|
||||
|
||||
But all of these cases are *super rare* for anyone writing a Rust program. 99% of the time you should just use a Vec (array stack), and 99% of the other 1% of the time you should be using a VecDeque (array deque). These are blatantly superior data structures for most workloads due to less frequent allocation, lower memory overhead, true random access, and cache locality.
|
||||
|
||||
Linked lists are as *niche* and *vague* of a data structure as a trie. Few would balk at me claiming a trie is a niche structure that your average programmer could happily never learn in an entire productive career -- and yet linked lists have some bizarre celebrity status. We teach every undergrad how to write a linked list. It's the only niche collection [I couldn't kill from std::collections](https://doc.rust-lang.org/std/collections/struct.LinkedList.html). It's [*the* list in C++](http://en.cppreference.com/w/cpp/container/list)!
|
||||
|
||||
We should all as a community say *no* to linked lists as a "standard" data structure. It's a fine data structure with several great use cases, but those use cases are *exceptional*, not common.
|
||||
|
||||
Several people apparently read the first paragraph of this PSA and then stop reading. Like, literally they'll try to rebut my argument by listing one of the things in my list of *great use cases*. The thing right after the first paragraph!
|
||||
|
||||
Just so I can link directly to a detailed argument, here are several attempts at counter-arguments I have seen, and my response to them. Feel free to skip to [the first chapter](https://rust-unofficial.github.io/too-many-lists/first.html) if you just want to learn some Rust!
|
||||
|
||||
## [Performance doesn't always matter](https://rust-unofficial.github.io/too-many-lists/#performance-doesnt-always-matter)
|
||||
|
||||
Yes! Maybe your application is I/O-bound or the code in question is in some cold case that just doesn't matter. But this isn't even an argument for using a linked list. This is an argument for using *whatever at all*. Why settle for a linked list? Use a linked hash map!
|
||||
|
||||
If performance doesn't matter, then it's *surely* fine to apply the natural default of an array.
|
||||
|
||||
## [They have O(1) split-append-insert-remove if you have a pointer there](https://rust-unofficial.github.io/too-many-lists/#they-have-o1-split-append-insert-remove-if-you-have-a-pointer-there)
|
||||
|
||||
Yep! Although as [Bjarne Stroustrup notes](https://www.youtube.com/watch?v=YQs6IC-vgmo) *this doesn't actually matter* if the time it takes to get that pointer completely dwarfs the time it would take to just copy over all the elements in an array (which is really quite fast).
|
||||
|
||||
Unless you have a workload that is heavily dominated by splitting and merging costs, the penalty *every other* operation takes due to caching effects and code complexity will eliminate any theoretical gains.
|
||||
|
||||
*But yes, if you're profiling your application to spend a lot of time in splitting and merging, you may have gains in a linked list*.
|
||||
|
||||
## [I can't afford amortization](https://rust-unofficial.github.io/too-many-lists/#i-cant-afford-amortization)
|
||||
|
||||
You've already entered a pretty niche space -- most can afford amortization. Still, arrays are amortized *in the worst case*. Just because you're using an array, doesn't mean you have amortized costs. If you can predict how many elements you're going to store (or even have an upper-bound), you can pre-reserve all the space you need. In my experience it's *very* common to be able to predict how many elements you'll need. In Rust in particular, all iterators provide a `size_hint` for exactly this case.
|
||||
|
||||
Then `push` and `pop` will be truly O(1) operations. And they're going to be *considerably* faster than `push` and `pop` on linked list. You do a pointer offset, write the bytes, and increment an integer. No need to go to any kind of allocator.
|
||||
|
||||
How's that for low latency?
|
||||
|
||||
*But yes, if you can't predict your load, there are worst-case latency savings to be had!*
|
||||
|
||||
## [Linked lists waste less space](https://rust-unofficial.github.io/too-many-lists/#linked-lists-waste-less-space)
|
||||
|
||||
Well, this is complicated. A "standard" array resizing strategy is to grow or shrink so that at most half the array is empty. This is indeed a lot of wasted space. Especially in Rust, we don't automatically shrink collections (it's a waste if you're just going to fill it back up again), so the wastage can approach infinity!
|
||||
|
||||
But this is a worst-case scenario. In the best-case, an array stack only has three pointers of overhead for the entire array. Basically no overhead.
|
||||
|
||||
Linked lists on the other hand unconditionally waste space per element. A singly-linked list wastes one pointer while a doubly-linked list wastes two. Unlike an array, the relative wasteage is proportional to the size of the element. If you have *huge* elements this approaches 0 waste. If you have tiny elements (say, bytes), then this can be as much as 16x memory overhead (8x on 32-bit)!
|
||||
|
||||
Actually, it's more like 23x (11x on 32-bit) because padding will be added to the byte to align the whole node's size to a pointer.
|
||||
|
||||
This is also assuming the best-case for your allocator: that allocating and deallocating nodes is being done densely and you're not losing memory to fragmentation.
|
||||
|
||||
*But yes, if you have huge elements, can't predict your load, and have a decent allocator, there are memory savings to be had!*
|
||||
|
||||
## [I use linked lists all the time in <functional language>](https://rust-unofficial.github.io/too-many-lists/#i-use-linked-lists-all-the-time-in-functional-language)
|
||||
|
||||
Great! Linked lists are super elegant to use in functional languages because you can manipulate them without any mutation, can describe them recursively, and also work with infinite lists due to the magic of laziness.
|
||||
|
||||
Specifically, linked lists are nice because they represent an iteration without the need for any mutable state. The next step is just visiting the next sublist.
|
||||
|
||||
Rust mostly does this kind of thing with [iterators](https://doc.rust-lang.org/std/iter/trait.Iterator.html). They can be infinite and you can map, filter, reverse, and concatenate them just like a functional list, and it will all be done just as lazily!
|
||||
|
||||
Rust also lets you easily talk about sub-arrays with *[slices](https://doc.rust-lang.org/std/primitive.slice.html)*. Your usual head/tail split in a functional language is [just `slice.split_at_mut(1)`](https://doc.rust-lang.org/std/primitive.slice.html#method.split_at_mut). For a long time, Rust had an experimental system for pattern matching on slices which was super cool, but the feature was simplified when it was stabilized. Still, [basic slice patterns](https://doc.rust-lang.org/edition-guide/rust-2018/slice-patterns.html) are neat! And of course, slices can be turned into iterators!
|
||||
|
||||
*But yes, if you're limited to immutable semantics, linked lists can be very nice*.
|
||||
|
||||
Note that I'm not saying that functional programming is necessarily weak or bad. However it *is* fundamentally semantically limited: you're largely only allowed to talk about how things *are*, and not how they should be *done*. This is actually a *feature*, because it enables the compiler to do tons of [exotic transformations](https://wiki.haskell.org/GHC_optimisations#Fusion) and potentially figure out the *best* way to do things without you having to worry about it. However this comes at the cost of being *able* to worry about it. There are usually escape hatches, but at some limit you're just writing procedural code again.
|
||||
|
||||
Even in functional languages, you should endeavour to use the appropriate data structure for the job when you actually need a data structure. Yes, singly-linked lists are your primary tool for control flow, but they're a really poor way to actually store a bunch of data and query it.
|
||||
|
||||
## [Linked lists are great for building concurrent data structures!](https://rust-unofficial.github.io/too-many-lists/#linked-lists-are-great-for-building-concurrent-data-structures)
|
||||
|
||||
Yes! Although writing a concurrent data structure is really a whole different beast, and isn't something that should be taken lightly. Certainly not something many people will even *consider* doing. Once one's been written, you're also not really choosing to use a linked list. You're choosing to use an MPSC queue or whatever. The implementation strategy is pretty far removed in this case!
|
||||
|
||||
*But yes, linked lists are the defacto heroes of the dark world of lock-free concurrency.*
|
||||
|
||||
## [Mumble mumble kernel embedded something something intrusive.](https://rust-unofficial.github.io/too-many-lists/#mumble-mumble-kernel-embedded-something-something-intrusive)
|
||||
|
||||
It's niche. You're talking about a situation where you're not even using your language's *runtime*. Is that not a red flag that you're doing something strange?
|
||||
|
||||
It's also wildly unsafe.
|
||||
|
||||
*But sure. Build your awesome zero-allocation lists on the stack.*
|
||||
|
||||
## [Iterators don't get invalidated by unrelated insertions/removals](https://rust-unofficial.github.io/too-many-lists/#iterators-dont-get-invalidated-by-unrelated-insertionsremovals)
|
||||
|
||||
That's a delicate dance you're playing. Especially if you don't have a garbage collector. I might argue that your control flow and ownership patterns are probably a bit too tangled, depending on the details.
|
||||
|
||||
*But yes, you can do some really cool crazy stuff with cursors.*
|
||||
|
||||
## [They're simple and great for teaching!](https://rust-unofficial.github.io/too-many-lists/#theyre-simple-and-great-for-teaching)
|
||||
|
||||
Well, yeah. You're reading a book dedicated to that premise. Well, singly-linked lists are pretty simple. Doubly-linked lists can get kinda gnarly, as we'll see.
|
||||
|
||||
## [Take a Breath](https://rust-unofficial.github.io/too-many-lists/#take-a-breath)
|
||||
|
||||
Ok. That's out of the way. Let's write a bajillion linked lists.
|
||||
|
||||
[On to the first chapter!](https://rust-unofficial.github.io/too-many-lists/first.html)
|
||||
@@ -0,0 +1,46 @@
|
||||
---
|
||||
page-title: "Introduction - Rust and WebAssembly"
|
||||
url: https://rustwasm.github.io/docs/book/
|
||||
date: "2023-04-02 09:33:54"
|
||||
---
|
||||
[
|
||||
|
||||
## Rust 🦀 and WebAssembly 🕸
|
||||
|
||||
](https://rustwasm.github.io/docs/book/#rust--and-webassembly-)
|
||||
|
||||
This small book describes how to use [Rust](https://www.rust-lang.org/) and [WebAssembly](https://webassembly.org/) together.
|
||||
|
||||
[
|
||||
|
||||
## Who is this book for?
|
||||
|
||||
](https://rustwasm.github.io/docs/book/#who-is-this-book-for)
|
||||
|
||||
This book is for anyone interested in compiling Rust to WebAssembly for fast, reliable code on the Web. You should know some Rust, and be familiar with JavaScript, HTML, and CSS. You don't need to be an expert in any of them.
|
||||
|
||||
Don't know Rust yet? [Start with *The Rust Programming Language* first.](https://doc.rust-lang.org/book/)
|
||||
|
||||
Don't know JavaScript, HTML, or CSS? [Learn about them on MDN.](https://developer.mozilla.org/en-US/docs/Learn)
|
||||
|
||||
[
|
||||
|
||||
## How to read this book
|
||||
|
||||
](https://rustwasm.github.io/docs/book/#how-to-read-this-book)
|
||||
|
||||
You should read [the motivation for using Rust and WebAssembly together](https://rustwasm.github.io/docs/book/why-rust-and-webassembly.html), as well as familiarize yourself with the [background and concepts](https://rustwasm.github.io/docs/book/background-and-concepts.html) first.
|
||||
|
||||
The [tutorial](https://rustwasm.github.io/docs/book/game-of-life/introduction.html) is written to be read from start to finish. You should follow along: writing, compiling, and running the tutorial's code yourself. If you haven't used Rust and WebAssembly together before, do the tutorial!
|
||||
|
||||
The [reference sections](https://rustwasm.github.io/docs/book/reference/index.html) may be perused in any order.
|
||||
|
||||
> **💡 Tip:** You can search through this book by clicking on the 🔍 icon at the top of the page, or by pressing the `s` key.
|
||||
|
||||
[
|
||||
|
||||
## Contributing to this book
|
||||
|
||||
](https://rustwasm.github.io/docs/book/#contributing-to-this-book)
|
||||
|
||||
This book is open source! Find a typo? Did we overlook something? [**Send us a pull request!**](https://github.com/rustwasm/book)
|
||||
@@ -0,0 +1,331 @@
|
||||
---
|
||||
page-title: "Learn Rust in Y Minutes"
|
||||
url: https://learnxinyminutes.com/docs/rust/
|
||||
date: "2023-04-02 09:39:01"
|
||||
---
|
||||
Rust is a programming language developed by Mozilla Research. Rust combines low-level control over performance with high-level convenience and safety guarantees.
|
||||
|
||||
It achieves these goals without requiring a garbage collector or runtime, making it possible to use Rust libraries as a “drop-in replacement” for C.
|
||||
|
||||
Rust’s first release, 0.1, occurred in January 2012, and for 3 years development moved so quickly that until recently the use of stable releases was discouraged and instead the general advice was to use nightly builds.
|
||||
|
||||
On May 15th 2015, Rust 1.0 was released with a complete guarantee of backward compatibility. Improvements to compile times and other aspects of the compiler are currently available in the nightly builds. Rust has adopted a train-based release model with regular releases every six weeks. Rust 1.1 beta was made available at the same time of the release of Rust 1.0.
|
||||
|
||||
Although Rust is a relatively low-level language, it has some functional concepts that are generally found in higher-level languages. This makes Rust not only fast, but also easy and efficient to code in.
|
||||
|
||||
// This is a comment. Line comments look like this...
|
||||
// and extend multiple lines like this.
|
||||
|
||||
/// Documentation comments look like this and support markdown notation.
|
||||
/// # Examples
|
||||
///
|
||||
/// \`\`\`
|
||||
/// let five = 5
|
||||
/// \`\`\`
|
||||
|
||||
///////////////
|
||||
// 1. Basics //
|
||||
///////////////
|
||||
|
||||
#\[allow(dead\_code)\]
|
||||
// Functions
|
||||
// \`i32\` is the type for 32-bit signed integers
|
||||
fn add2(x: i32, y: i32) \-> i32 {
|
||||
// Implicit return (no semicolon)
|
||||
x + y
|
||||
}
|
||||
|
||||
#\[allow(unused\_variables)\]
|
||||
#\[allow(unused\_assignments)\]
|
||||
#\[allow(dead\_code)\]
|
||||
// Main function
|
||||
fn main() {
|
||||
// Numbers //
|
||||
|
||||
// Immutable bindings
|
||||
let x: i32 \= 1;
|
||||
|
||||
// Integer/float suffixes
|
||||
let y: i32 \= 13i32;
|
||||
let f: f64 \= 1.3f64;
|
||||
|
||||
// Type inference
|
||||
// Most of the time, the Rust compiler can infer what type a variable is, so
|
||||
// you don’t have to write an explicit type annotation.
|
||||
// Throughout this tutorial, types are explicitly annotated in many places,
|
||||
// but only for demonstrative purposes. Type inference can handle this for
|
||||
// you most of the time.
|
||||
let implicit\_x \= 1;
|
||||
let implicit\_f \= 1.3;
|
||||
|
||||
// Arithmetic
|
||||
let sum \= x + y + 13;
|
||||
|
||||
// Mutable variable
|
||||
let mut mutable \= 1;
|
||||
mutable \= 4;
|
||||
mutable += 2;
|
||||
|
||||
// Strings //
|
||||
|
||||
// String literals
|
||||
let x: &str \= "hello world!";
|
||||
|
||||
// Printing
|
||||
println!("{} {}", f, x); // 1.3 hello world
|
||||
|
||||
// A \`String\` – a heap-allocated string
|
||||
// Stored as a \`Vec<u8>\` and always hold a valid UTF-8 sequence,
|
||||
// which is not null terminated.
|
||||
let s: String \= "hello world".to\_string();
|
||||
|
||||
// A string slice – an immutable view into another string
|
||||
// This is basically an immutable pair of pointers to a string – it doesn’t
|
||||
// actually contain the contents of a string, just a pointer to
|
||||
// the begin and a pointer to the end of a string buffer,
|
||||
// statically allocated or contained in another object (in this case, \`s\`).
|
||||
// The string slice is like a view \`&\[u8\]\` into \`Vec<T>\`.
|
||||
let s\_slice: &str \= &s;
|
||||
|
||||
println!("{} {}", s, s\_slice); // hello world hello world
|
||||
|
||||
// Vectors/arrays //
|
||||
|
||||
// A fixed-size array
|
||||
let four\_ints: \[i32; 4\] \= \[1, 2, 3, 4\];
|
||||
|
||||
// A dynamic array (vector)
|
||||
let mut vector: Vec<i32\> \= vec!\[1, 2, 3, 4\];
|
||||
vector.push(5);
|
||||
|
||||
// A slice – an immutable view into a vector or array
|
||||
// This is much like a string slice, but for vectors
|
||||
let slice: &\[i32\] \= &vector;
|
||||
|
||||
// Use \`{:?}\` to print something debug-style
|
||||
println!("{:?} {:?}", vector, slice); // \[1, 2, 3, 4, 5\] \[1, 2, 3, 4, 5\]
|
||||
|
||||
// Tuples //
|
||||
|
||||
// A tuple is a fixed-size set of values of possibly different types
|
||||
let x: (i32, &str, f64) \= (1, "hello", 3.4);
|
||||
|
||||
// Destructuring \`let\`
|
||||
let (a, b, c) \= x;
|
||||
println!("{} {} {}", a, b, c); // 1 hello 3.4
|
||||
|
||||
// Indexing
|
||||
println!("{}", x.1); // hello
|
||||
|
||||
//////////////
|
||||
// 2. Types //
|
||||
//////////////
|
||||
|
||||
// Struct
|
||||
struct Point {
|
||||
x: i32,
|
||||
y: i32,
|
||||
}
|
||||
|
||||
let origin: Point \= Point { x: 0, y: 0 };
|
||||
|
||||
// A struct with unnamed fields, called a ‘tuple struct’
|
||||
struct Point2(i32, i32);
|
||||
|
||||
let origin2 \= Point2(0, 0);
|
||||
|
||||
// Basic C-like enum
|
||||
enum Direction {
|
||||
Left,
|
||||
Right,
|
||||
Up,
|
||||
Down,
|
||||
}
|
||||
|
||||
let up \= Direction::Up;
|
||||
|
||||
// Enum with fields
|
||||
enum OptionalI32 {
|
||||
AnI32(i32),
|
||||
Nothing,
|
||||
}
|
||||
|
||||
let two: OptionalI32 \= OptionalI32::AnI32(2);
|
||||
let nothing \= OptionalI32::Nothing;
|
||||
|
||||
// Generics //
|
||||
|
||||
struct Foo<T\> { bar: T }
|
||||
|
||||
// This is defined in the standard library as \`Option\`
|
||||
enum Optional<T\> {
|
||||
SomeVal(T),
|
||||
NoVal,
|
||||
}
|
||||
|
||||
// Methods //
|
||||
|
||||
impl<T\> Foo<T\> {
|
||||
// Methods take an explicit \`self\` parameter
|
||||
fn bar(&self) \-> &T { // self is borrowed
|
||||
&self.bar
|
||||
}
|
||||
fn bar\_mut(&mut self) \-> &mut T { // self is mutably borrowed
|
||||
&mut self.bar
|
||||
}
|
||||
fn into\_bar(self) \-> T { // here self is consumed
|
||||
self.bar
|
||||
}
|
||||
}
|
||||
|
||||
let a\_foo \= Foo { bar: 1 };
|
||||
println!("{}", a\_foo.bar()); // 1
|
||||
|
||||
// Traits (known as interfaces or typeclasses in other languages) //
|
||||
|
||||
trait Frobnicate<T\> {
|
||||
fn frobnicate(self) \-> Option<T\>;
|
||||
}
|
||||
|
||||
impl<T\> Frobnicate<T\> for Foo<T\> {
|
||||
fn frobnicate(self) \-> Option<T\> {
|
||||
Some(self.bar)
|
||||
}
|
||||
}
|
||||
|
||||
let another\_foo \= Foo { bar: 1 };
|
||||
println!("{:?}", another\_foo.frobnicate()); // Some(1)
|
||||
|
||||
// Function pointer types //
|
||||
|
||||
fn fibonacci(n: u32) \-> u32 {
|
||||
match n {
|
||||
0 \=> 1,
|
||||
1 \=> 1,
|
||||
\_ \=> fibonacci(n \- 1) + fibonacci(n \- 2),
|
||||
}
|
||||
}
|
||||
|
||||
type FunctionPointer \= fn(u32) \-> u32;
|
||||
|
||||
let fib : FunctionPointer \= fibonacci;
|
||||
println!("Fib: {}", fib(4)); // 5
|
||||
|
||||
/////////////////////////
|
||||
// 3. Pattern matching //
|
||||
/////////////////////////
|
||||
|
||||
let foo \= OptionalI32::AnI32(1);
|
||||
match foo {
|
||||
OptionalI32::AnI32(n) \=> println!("it’s an i32: {}", n),
|
||||
OptionalI32::Nothing \=> println!("it’s nothing!"),
|
||||
}
|
||||
|
||||
// Advanced pattern matching
|
||||
struct FooBar { x: i32, y: OptionalI32 }
|
||||
let bar \= FooBar { x: 15, y: OptionalI32::AnI32(32) };
|
||||
|
||||
match bar {
|
||||
FooBar { x: 0, y: OptionalI32::AnI32(0) } \=>
|
||||
println!("The numbers are zero!"),
|
||||
FooBar { x: n, y: OptionalI32::AnI32(m) } if n \== m \=>
|
||||
println!("The numbers are the same"),
|
||||
FooBar { x: n, y: OptionalI32::AnI32(m) } \=>
|
||||
println!("Different numbers: {} {}", n, m),
|
||||
FooBar { x: \_, y: OptionalI32::Nothing } \=>
|
||||
println!("The second number is Nothing!"),
|
||||
}
|
||||
|
||||
/////////////////////
|
||||
// 4. Control flow //
|
||||
/////////////////////
|
||||
|
||||
// \`for\` loops/iteration
|
||||
let array \= \[1, 2, 3\];
|
||||
for i in array {
|
||||
println!("{}", i);
|
||||
}
|
||||
|
||||
// Ranges
|
||||
for i in 0u32..10 {
|
||||
print!("{} ", i);
|
||||
}
|
||||
println!("");
|
||||
// prints \`0 1 2 3 4 5 6 7 8 9 \`
|
||||
|
||||
// \`if\`
|
||||
if 1 \== 1 {
|
||||
println!("Maths is working!");
|
||||
} else {
|
||||
println!("Oh no...");
|
||||
}
|
||||
|
||||
// \`if\` as expression
|
||||
let value \= if true {
|
||||
"good"
|
||||
} else {
|
||||
"bad"
|
||||
};
|
||||
|
||||
// \`while\` loop
|
||||
while 1 \== 1 {
|
||||
println!("The universe is operating normally.");
|
||||
// break statement gets out of the while loop.
|
||||
// It avoids useless iterations.
|
||||
break
|
||||
}
|
||||
|
||||
// Infinite loop
|
||||
loop {
|
||||
println!("Hello!");
|
||||
// break statement gets out of the loop
|
||||
break
|
||||
}
|
||||
|
||||
/////////////////////////////////
|
||||
// 5. Memory safety & pointers //
|
||||
/////////////////////////////////
|
||||
|
||||
// Owned pointer – only one thing can ‘own’ this pointer at a time
|
||||
// This means that when the \`Box\` leaves its scope, it can be automatically deallocated safely.
|
||||
let mut mine: Box<i32\> \= Box::new(3);
|
||||
\*mine \= 5; // dereference
|
||||
// Here, \`now\_its\_mine\` takes ownership of \`mine\`. In other words, \`mine\` is moved.
|
||||
let mut now\_its\_mine \= mine;
|
||||
\*now\_its\_mine += 2;
|
||||
|
||||
println!("{}", now\_its\_mine); // 7
|
||||
// println!("{}", mine); // this would not compile because \`now\_its\_mine\` now owns the pointer
|
||||
|
||||
// Reference – an immutable pointer that refers to other data
|
||||
// When a reference is taken to a value, we say that the value has been ‘borrowed’.
|
||||
// While a value is borrowed immutably, it cannot be mutated or moved.
|
||||
// A borrow is active until the last use of the borrowing variable.
|
||||
let mut var \= 4;
|
||||
var \= 3;
|
||||
let ref\_var: &i32 \= &var;
|
||||
|
||||
println!("{}", var); // Unlike \`mine\`, \`var\` can still be used
|
||||
println!("{}", \*ref\_var);
|
||||
// var = 5; // this would not compile because \`var\` is borrowed
|
||||
// \*ref\_var = 6; // this would not either, because \`ref\_var\` is an immutable reference
|
||||
ref\_var; // no-op, but counts as a use and keeps the borrow active
|
||||
var \= 2; // ref\_var is no longer used after the line above, so the borrow has ended
|
||||
|
||||
// Mutable reference
|
||||
// While a value is mutably borrowed, it cannot be accessed at all.
|
||||
let mut var2 \= 4;
|
||||
let ref\_var2: &mut i32 \= &mut var2;
|
||||
\*ref\_var2 += 2; // '\*' is used to point to the mutably borrowed var2
|
||||
|
||||
println!("{}", \*ref\_var2); // 6 , // var2 would not compile.
|
||||
// ref\_var2 is of type &mut i32, so stores a reference to an i32, not the value.
|
||||
// var2 = 2; // this would not compile because \`var2\` is borrowed.
|
||||
ref\_var2; // no-op, but counts as a use and keeps the borrow active until here
|
||||
}
|
||||
|
||||
There’s a lot more to Rust—this is just the basics of Rust so you can understand the most important things. To learn more about Rust, read [The Rust Programming Language](http://doc.rust-lang.org/book/index.html) and check out the [/r/rust](http://reddit.com/r/rust) subreddit. The folks on the #rust channel on irc.mozilla.org are also always keen to help newcomers.
|
||||
|
||||
You can also try out features of Rust with an online compiler at the official [Rust playpen](http://play.rust-lang.org/) or on the main [Rust website](http://rust-lang.org/).
|
||||
|
||||
Got a suggestion? A correction, perhaps? [Open an Issue](https://github.com/adambard/learnxinyminutes-docs/issues/new) on the Github Repo, or make a [pull request](https://github.com/adambard/learnxinyminutes-docs/edit/master/rust.html.markdown) yourself!
|
||||
@@ -0,0 +1,150 @@
|
||||
---
|
||||
page-title: "Logto 开源项目:创造令人愉悦的身份体验"
|
||||
url: https://logto.io/
|
||||
date: "2023-04-27 19:03:26"
|
||||
---
|
||||

|
||||
|
||||
一招搞定身份认证和登录授权
|
||||
|
||||
轻松构建和保护用户身份信息
|
||||
|
||||
基于并最大化利用 OIDC 的身份认证和登录鉴权通用标准,构建专业的登录体验以及用户授权管理。
|
||||
|
||||

|
||||
|
||||
支持无密码登录方式以及更多灵活选择
|
||||
|
||||
邮箱验证码登录
|
||||
|
||||
短信验证码登录
|
||||
|
||||
社交账号登录
|
||||
|
||||
用户名密码登录
|
||||
|
||||
忘记密码
|
||||
|
||||
自定义组合登录方式
|
||||
|
||||
畅快开发体验,显著提高生产力
|
||||
|
||||
使用 Logto 云平台定制、预览,并快速集成到应用中,极大提高产品开发效率。详尽的文档和活跃的社区更会助你事半功倍。
|
||||
|
||||
为开发者量身定制的解决方案
|
||||
|
||||
强大的 Management API即插即用的 Management API 可以作为您的身份验证提供者,省去了额外的实现工作,并且可以加速你的基础设施搭建。
|
||||
|
||||
[
|
||||
|
||||
阅读 API 文档
|
||||
|
||||
](https://docs.logto.io/docs/recipes/interact-with-management-api)
|
||||
|
||||
全平台支持的 SDK面向多种编程语言和近乎全平台支持的 SDK,为你的开发环境量身定制。
|
||||
|
||||
[
|
||||
|
||||
阅读集成文档
|
||||
|
||||
](https://docs.logto.io/docs/recipes/integrate-logto)
|
||||
|
||||
灵活多样的连接器选择可通过社区贡献不断扩展、丰富连接器种类,也可以通过我们提供的支持 SAML、OAuth 和 OIDC 标准协议的连接器进行自定义设置。
|
||||
|
||||
[
|
||||
|
||||
阅读连接器文档
|
||||
|
||||
](https://docs.logto.io/docs/references/connectors)
|
||||
|
||||
企业级用户管理解决方案
|
||||
|
||||
组织(Organization)、多重身份认证(MFA)和单点登录(SSO)等功能正如火如荼开发中,敬请期待。
|
||||
|
||||

|
||||
|
||||
基于角色的访问控制(RBAC)
|
||||
|
||||
通过可扩展的角色授权来控制你的资源,以适应不同的使用场景。
|
||||
|
||||
[
|
||||
|
||||
了解更多
|
||||
|
||||
](https://docs.logto.io/docs/recipes/rbac)
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
用户管理和审计日志
|
||||
|
||||
通过日志了解与身份相关的用户行为,系统安全状况尽在掌控。
|
||||
|
||||
[
|
||||
|
||||
了解更多
|
||||
|
||||
](https://docs.logto.io/docs/recipes/manage-users)
|
||||
|
||||

|
||||
|
||||
心之所向 竭诚而求
|
||||
|
||||
来自 GitHub
|
||||
|
||||

|
||||
|
||||
Ufuk ArslanCo-Founder of Mobilist
|
||||
|
||||
来自 GitHub
|
||||
|
||||
|
||||
|
||||
André KönigCEO at openformation.io
|
||||
|
||||
来自 Reddit
|
||||
|
||||

|
||||
|
||||
Reddit 用户iOS developer
|
||||
|
||||
来自 Discord
|
||||
|
||||

|
||||
|
||||
ZohaFront-end developer
|
||||
|
||||
来自 Discord
|
||||
|
||||

|
||||
|
||||
OlynoIndie developer
|
||||
|
||||
来自 Discord
|
||||
|
||||

|
||||
|
||||
ZR3SYSTEMSDeveloper
|
||||
|
||||
极速上手集成和测试
|
||||
|
||||
试用 Logto Cloud 预览版
|
||||
|
||||
云端预览是 Logto Cloud 的一个令人兴奋的早期版本,它展示了 Logto Cloud 的全部功能。虽然不建议用于生产环境,但它是测试和集成 Logto 的绝佳机会。[了解更多](https://docs.logto.io/about/cloud-preview/)
|
||||
|
||||
[
|
||||
|
||||
Cloud 预览
|
||||
|
||||
](http://cloud.logto.io/?sign_up=true)
|
||||
|
||||
下载并部署 Logto 开源版
|
||||
|
||||
与其它解决方案相比,Logto 开源身份验证解决方案对开发者更为友好,简单易用。它拥有强大的功能和灵活的架构,只需要几分钟即可快速构建、测试和部署。
|
||||
|
||||
[
|
||||
|
||||
开始上手
|
||||
|
||||
](https://docs.logto.io/docs/tutorials/get-started)
|
||||
@@ -0,0 +1,35 @@
|
||||
---
|
||||
page-title: "MistGPU - 深度学习雾计算平台"
|
||||
url: https://mistgpu.com/
|
||||
date: "2023-04-23 13:09:44"
|
||||
---
|
||||

|
||||
|
||||
GPU加速
|
||||
|
||||
GPU可为深度学习运算加速
|
||||
显著提高AI模型开发和训练的效率
|
||||
|
||||

|
||||
|
||||
按时间计费
|
||||
|
||||
仅使用时按分钟计费
|
||||
随时暂停和继续
|
||||
|
||||

|
||||
|
||||
已配置环境
|
||||
|
||||
预装Tensorflow PyTorch
|
||||
等深度学习框架
|
||||
不再为配置环境耗费时间
|
||||
|
||||

|
||||
|
||||
在线开发环境
|
||||
|
||||
除SSH连接外
|
||||
更可一键开启Jupyter终端
|
||||
也连接使用图形界面
|
||||
即刻开始编写代码
|
||||
@@ -0,0 +1,50 @@
|
||||
---
|
||||
page-title: "Most Useful ChatGPT Prompts"
|
||||
url: https://www.explainthis.io/en/chatgpt
|
||||
date: "2023-04-20 08:56:52"
|
||||
---
|
||||
Copy
|
||||
|
||||
##### Write a function
|
||||
|
||||
Your are programming language expert, please write a function that can do something.
|
||||
|
||||
👉 You are a JavaScript expert, please write a function that can do input a one-dimensional array, convert this one-dimensional array into a two-dimensional array. At the same time, I can freely decide the length of the subarray in the two-dimensional array.
|
||||
|
||||
Copy
|
||||
|
||||
##### Explain Code
|
||||
|
||||
You are a programming language expert, please explain the following code to me. attach code
|
||||
|
||||
👉 You are a Rust expert, please explain the following Rust code to me. \[attach code\]
|
||||
|
||||
Copy
|
||||
|
||||
##### Refactor Code
|
||||
|
||||
You are a Clean Code expert, I have the following code, please refactor it in a more clean and concise way so that my colleagues can maintain the code more easily. Also, explain why you want to refactor the code so that I can add the explanation to the Pull Request. attach code
|
||||
|
||||
Copy
|
||||
|
||||
##### Debug
|
||||
|
||||
You are a programming language expert, I have a piece of code and, I expect this code to do something, but it fails the test case. Please help me find out what I did wrong and rewrite it in the correct way. attach code
|
||||
|
||||
👉 You are a C++ expert. I have a piece of code and I expect this code to check if a string is a palindrome, but it fails the test case abbccde. Please help me find out what I did wrong and rewrite it in the correct way. \[attach code\]
|
||||
|
||||
Copy
|
||||
|
||||
##### Write test
|
||||
|
||||
You are a programming language expert, I have a piece of code attach code, please write tests for it. Please provide at least number test cases, and cover the extreme cases, so that I can be sure that my code is correct. attach code
|
||||
|
||||
👉 You are a python expert. I have a piece of code \[attach code\], please write a test for it. Please provide at least 5 test cases, and cover the extreme cases, so that I can be sure that my code is correct. \[attach code\]
|
||||
|
||||
Copy
|
||||
|
||||
##### Write Regex
|
||||
|
||||
You are now a Regex Expert, please write a Regex that can do something
|
||||
|
||||
👉 You are now a Regex Expert, please write a Regex that can extract all the numbers from a string
|
||||
@@ -0,0 +1,101 @@
|
||||
---
|
||||
page-title: "PowerDNS pdnsutil cheat sheet - Makarainen"
|
||||
url: https://makarainen.net/PowerDNS-pdnsutil-cheat-sheet
|
||||
date: "2023-04-19 20:58:11"
|
||||
---
|
||||
## PowerDNS pdnsutil cheat sheet
|
||||
|
||||

|
||||
|
||||
This is an extremely simple tutorial on how to manage data in the [PowerDNS Authoritative Server](https://www.powerdns.com/auth.html) using the command line "[pdnsutil](https://doc.powerdns.com/authoritative/manpages/pdnsutil.1.html)" tool. The guide is written in the "walk through" format: create zone - add data - update serial.
|
||||
|
||||
### CREATE ZONE
|
||||
|
||||
```
|
||||
pdnsutil create-zone example.com
|
||||
```
|
||||
|
||||
### ADD DATA TO ZONE // Let's start by adding the root A-record and AAAA for IPv6 (makarainen.net)
|
||||
|
||||
```
|
||||
pdnsutil add-record example.com @ A 192.168.1.2
|
||||
pdnsutil add-record example.com @ AAAA 2a01:4f9:c010:30f4::1
|
||||
```
|
||||
|
||||
### ADD DATA TO ZONE // adding a subdomain (www)
|
||||
|
||||
```
|
||||
pdnsutil add-record example.com www A 192.168.1.2
|
||||
```
|
||||
|
||||
### ADD DATA TO ZONE // every domain needs name servers
|
||||
|
||||
```
|
||||
pdnsutil add-record example.com @ NS ns1.example.com
|
||||
```
|
||||
|
||||
### ADD DATA TO ZONE
|
||||
|
||||
```
|
||||
pdnsutil add-record example.com @ MX "10 example.com"
|
||||
|
||||
pdnsutil add-record example.com 3600 TXT "google-site-verification=example-id"
|
||||
```
|
||||
|
||||
### MANAGE ZONES // check the information provided
|
||||
|
||||
```
|
||||
pdnsutil list-zone example.com
|
||||
```
|
||||
|
||||
### MANAGE ZONES // modify the zone (if changes do not miss update serial -> UPDATE SERIAL)
|
||||
|
||||
```
|
||||
pdnsutil edit-zone example.com
|
||||
```
|
||||
|
||||
### MANAGE ZONES
|
||||
|
||||
```
|
||||
pdnsutil check-all-zones
|
||||
|
||||
pdnsutil show-zone example.com
|
||||
```
|
||||
|
||||
### DELETE A SPECIFIC ZONE
|
||||
|
||||
```
|
||||
pdnsutil delete-zone example.com
|
||||
```
|
||||
|
||||
### UPDATE SERIAL
|
||||
|
||||
```
|
||||
pdnsutil increase-serial example.com
|
||||
```
|
||||
|
||||
### UPDATE THE CONNECTED DNS SERVERS
|
||||
|
||||
```
|
||||
pdns_control notify example.com
|
||||
```
|
||||
|
||||
### START THE POWERDNS SERVER IN UBUNTU
|
||||
|
||||
```
|
||||
service pdns start
|
||||
```
|
||||
|
||||
### Questions
|
||||
|
||||
Where do I enter a SOA-record? - No, you don't have to enter it. PowerDNS generates it automatically when you update the serial. However, specify initialization values in the /etc/powerdns/pdns.conf file.
|
||||
|
||||
### Explore more
|
||||
|
||||
Find out how the background system can be managed [PowerDNS export from MySQL to csv using command line](https://makarainen.net/powerdns-export-from-mysql-to-csv-using-command-line)
|
||||
|
||||
### Noteworthy deal
|
||||
|
||||
[Domainparkki](https://domainparkki.com/) may be able to help if you need plain name server services for hobby/low volume use. Only 5 euros +VAT per zone per year. One zone = one domain, including 20 records per zone and 1 billion queries per month (excess traffic is billed separately). Open the link above and check it out. Inquiries by email [hello@domainparkki.com](mailto:hello@domainparkki.com).
|
||||
|
||||
*// viHannes, 12 Feb 2022 in Helsinki, Finland*
|
||||
@@ -0,0 +1,180 @@
|
||||
---
|
||||
page-title: "Prerequisites"
|
||||
url: https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/Prerequisites.html
|
||||
date: "2023-04-23 18:20:19"
|
||||
---
|
||||
## Prerequisites
|
||||
|
||||
You must perform the following steps before installing ROCm and check if the system meets all the requirements to proceed with the installation.
|
||||
|
||||
Follow these steps:
|
||||
|
||||
1. Confirm the system has a supported Linux distribution version.
|
||||
|
||||
2. Confirm the system has a ROCm-capable GPU.
|
||||
|
||||
3. Confirm the system has all the required tools and packages installed.
|
||||
|
||||
## Confirm the System Has a Supported Linux Distribution Version
|
||||
|
||||
The ROCm installation is supported only on specific Linux distributions and kernel versions.
|
||||
|
||||
NOTE:
|
||||
|
||||
ROCm installation is not supported on 32-bit operating systems.
|
||||
|
||||
### Check the Linux Distribution and Kernel Version on Your System
|
||||
|
||||
This section discusses obtaining information about the Linux distribution and kernel version.
|
||||
|
||||
#### Linux Distribution Information
|
||||
|
||||
Verify the Linux distribution using the following steps:
|
||||
|
||||
1. To obtain the Linux distribution information, type the following command on your system from the Command Line Interface (CLI):
|
||||
|
||||
**2.** Confirm that the obtained Linux distribution information matches with [System Requirements.](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/Introduction_to_ROCm_Installation_Guide_for_Linux.html#d4616e529)
|
||||
|
||||
**E****xample****:** Running the command above on an Ubuntu system results in the following output:
|
||||
|
||||
#### Kernel Information
|
||||
|
||||
Verify the kernel version using the following steps:
|
||||
|
||||
1. To check the kernel version of your Linux system, type the following command:
|
||||
|
||||
2. Confirm that the obtained kernel version information matches with [System Requirements.](https://docs.amd.com/bundle/ROCm-Installation-Guide-v5.4.3/page/Introduction_to_ROCm_Installation_Guide_for_Linux.html#d4616e529)
|
||||
|
||||
**Example:** The output of the command above lists the kernel version in the following format:
|
||||
|
||||
## Confirm the System has a ROCm-Capable GPU
|
||||
|
||||
The ROCm platform is designed to support the following GPUs:
|
||||
|
||||
**Table 2****.** **GPU** **S****upport for** **ROCm** **P****rogramming** **M****odels**
|
||||
|
||||
**Classification**
|
||||
|
||||
**GPU Name**
|
||||
|
||||
**GFX** **ID**
|
||||
|
||||
**Product Id**
|
||||
|
||||
**GFX9 GPUs**
|
||||
|
||||
AMD Radeon Instinct™ MI50
|
||||
|
||||
gfx906
|
||||
|
||||
Vega 20
|
||||
|
||||
AMD Radeon Instinct™ MI60
|
||||
|
||||
AMD Radeon™ VII
|
||||
|
||||
AMD Radeon™ Pro VII
|
||||
|
||||
**RDNA GPUs**
|
||||
|
||||
AMD Radeon™ Pro W6800
|
||||
|
||||
gfx1030
|
||||
|
||||
Navi 21 GL-XL
|
||||
|
||||
AMD Radeon™ Pro V620
|
||||
|
||||
Navi 21 GL-XE
|
||||
|
||||
**CDNA GPUs**
|
||||
|
||||
AMD Instinct™ MI100
|
||||
|
||||
gfx908
|
||||
|
||||
Arcturus
|
||||
|
||||
AMD Instinct™ MI200
|
||||
|
||||
gfx90a
|
||||
|
||||
Aldebaran
|
||||
|
||||
### Verify Your System Has a ROCm-Capable GPU
|
||||
|
||||
To verify that your system has a ROCm-capable GPU, use these steps:
|
||||
|
||||
1. Enter the following command from the Command Line Interface (CLI):
|
||||
|
||||
The command displays the details of detected GPUs on the system in the following format in the case of AMD Instinct™ MI200:
|
||||
|
||||
2. Verify from the output that the listed product names match with the Product Id given in the table above.
|
||||
|
||||
## Confirm the System Has All the Required Tools and Packages Installed
|
||||
|
||||
To check if the required tools and packages are available on the system, refer the following sections.
|
||||
|
||||
### Required Packages
|
||||
|
||||
Verify if the wget, gnupg2, gawk and curl packages are available on your system using the following command based on your OS distribution:
|
||||
|
||||
**U****buntu****/D****ebian**
|
||||
|
||||
**RHEL**
|
||||
|
||||
**SLES/O****pen****SUSE**
|
||||
|
||||
If the wget, gnupg2, gawk and curl packages are not available on your system, install using the following commands based on your OS distribution:
|
||||
|
||||
**U****buntu****/D****ebian**
|
||||
|
||||
**RHEL**
|
||||
|
||||
**SLES/O****pen****SUSE**
|
||||
|
||||
### Register the System to the Subscription Manager
|
||||
|
||||
**RHEL v8.x/9.x**
|
||||
|
||||
To register RHEL v8.x/9.x system to the subscription manager, refer to the following documentation:
|
||||
|
||||
[https://access.redhat.com/solutions/253273](https://access.redhat.com/solutions/253273)
|
||||
|
||||
**SLES** **15** **SP****4**
|
||||
|
||||
To register SLES 15 SP4 system, refer to the following documentation:
|
||||
|
||||
[https://documentation.suse.com/sles/12-SP5/single-html/SLES-smt/index.html](https://documentation.suse.com/sles/12-SP5/single-html/SLES-smt/index.html)
|
||||
|
||||
### Enable Additional Repositories
|
||||
|
||||
Use the following commands to get the required tools and packages.
|
||||
|
||||
**RHEL** **v****8.x**
|
||||
|
||||
Install the EPEL repository and enable the CodeReady Linux Builder repository on RHEL v8.x using the commands below:
|
||||
|
||||
**RHEL** **v9****.x**
|
||||
|
||||
Use the following command to download and install EPEL from [https://dl.fedoraproject.org](https://dl.fedoraproject.org/) for RHEL v9.x:
|
||||
|
||||
**SLES** **15** **SP4**
|
||||
|
||||
Add the perl repository using the following commands:
|
||||
|
||||
### Setting Permissions for Groups
|
||||
|
||||
This section provides steps to add any current user to a video group to access GPU resources.
|
||||
|
||||
1. To check the groups in your system, issue the following command:
|
||||
|
||||
2. Add yourself to the render or video group using the following instruction:
|
||||
|
||||
3. Use of the video group is recommended for all ROCm-supported operating systems.
|
||||
|
||||
NOTE:
|
||||
|
||||
render group is required only for Ubuntu v20.04.
|
||||
|
||||
To add future users to the video and render groups, run the following command:
|
||||
@@ -0,0 +1,418 @@
|
||||
---
|
||||
page-title: "Self hosted mail server – if ? then : else"
|
||||
url: https://www.ifthenel.se/self-hosted-mail-server/
|
||||
date: "2023-04-27 17:18:34"
|
||||
---
|
||||
I have had enough. It’s bad enough that social media has become the scourge of the Internet, but that doesn’t mean key services such as email should have to be stronghold(ed?) by Big Corp such as Google, Microsoft, and other massive vendors.
|
||||
|
||||
The Internet was built on a foundation of globally connected computers that chose to share information between eachother and all was well.
|
||||
|
||||
Now, pretty much \_EVERYTHING\_ on the web is behind some kind of walled garden and/or being harvested for user behaviour studies to increase revenue (through ads, mostly).
|
||||
|
||||
But I’d like to see if I can do something about this, in as far as my capabilities goes; it’s time to “take back” (I’ve actually never hosted my own email server before, so it’s more of a “move the responsibility of”) my emails.
|
||||
|
||||
This is a part guide, part resource, part tutorial on how I set my email up on a VPS service. You won’t be getting every single step as a command or how to edit your DNS records for your control panel on your registrar, but you should at least get a fairly detailed explanation of all the steps that are involved.
|
||||
|
||||
## A word of thanks
|
||||
|
||||
I’d like to thank all the people involved for their tireless efforts in providing a solid out-of-the-box selfhostable mail server. I am a huge fan of all the individuals that put their time into creating a set of tools such as docker-mailserver and make it \_next\_ to a no-brainer to get it up and running.
|
||||
|
||||
Let’s get to the grind.
|
||||
|
||||
## Tech stack
|
||||
|
||||
I have chosen to use the following techs
|
||||
|
||||
- External VPS hosting – It is fairly cheap, and email shouldn’t require exorbitant amounts of resources, and you \_have to\_ be able to edit reverse DNS records
|
||||
- Debian 10 – No particular reason other than I like Debian
|
||||
- [docker-mailserver](https://github.com/docker-mailserver/docker-mailserver) – It has proven to be a one stop shop for an easy (well) get up and running component stack of different software that can deal with email
|
||||
|
||||
## Look at your inventory before you move on
|
||||
|
||||
### IP blacklisting delisting
|
||||
|
||||
Make sure your chosen server host isn’t on any kind of IP or email blacklist. This activity is a tough one with a big risk of being costly (as in $$$) since you
|
||||
|
||||
- probably don’t know what IP you get (this post assumes 123.123.123.123)
|
||||
- don’t know if that IP is on any list yet
|
||||
- may not know of any tools can help you figure out what lists you are on
|
||||
|
||||
I don’t have an answer to all of this. You can use [MX Toolbox’s blacklist lookup tool](https://mxtoolbox.com/blacklists.aspx), but there are probably a lot more blacklisting going on that you will want to try and find so you have an ounce more chance of not getting you emails flagged as spam from the getgo.
|
||||
|
||||
I got to know my IP was on the BARRACUDA blacklist and I made an attempt at sending in a delisting request through their online form, and I seem to have been released from their clutches.
|
||||
|
||||
Microsoft/Outlook/Office are picky as all get out as well, so make additional efforts to get your IP delisted from there as well, even if you suspect you’re not on their list: [https://sender.office.com/](https://sender.office.com/)
|
||||
|
||||
### rDNS (reverse DNS)
|
||||
|
||||
Get a host that supports rDNS (reverse DNS) and set a reverse value to something that you own, so that when a lookup happens (be it forward or reverse), they get *the same* hostnames and IP. E.g.;
|
||||
|
||||
$ host my.host // returns: "my.host has address 123.123.123.123"
|
||||
$ dig +noall +answer -x 123.123.123.123 // returns: "123.123.123.123-in-addr.arpa \[number\] IN PTR my.host"
|
||||
|
||||
You could also use [MX Toolbox reverse lookup tool](https://mxtoolbox.com/ReverseLookup.aspx) to test this by supplying your mail host’s IP address and have it look this up for you.
|
||||
|
||||
## Setting up docker-mailserver (and moar)
|
||||
|
||||
### docker-mailserver
|
||||
|
||||
**THIS GUIDE ONLY COVERS docker-mailserver v10.2 AND LATER!**
|
||||
|
||||
1. Install `docker` and `docker-compose` on your host
|
||||
2. Clone the docker-mailserver git repo (this way you will get all necessary files to start off including one of my personal favourites; `docker-compose.yml`): `git clone https://github.com/docker-mailserver/docker-mailserver`
|
||||
3. Read the docker environment and topics following in the official README [https://github.com/docker-mailserver/docker-mailserver#create-a-docker-compose-environment](https://github.com/docker-mailserver/docker-mailserver#create-a-docker-compose-environment)
|
||||
4. Do as the README suggests and then start the mailserver
|
||||
$ `docker-compose up`
|
||||
5. Wait for the startup to fail with a message along the lines of *mailserver | \[ ERROR \] Shutting down..*
|
||||
6. Shut down the server again
|
||||
`$ docker-compose down`
|
||||
|
||||
**Here be dragons. Read this. It’s important.** I have based a lot of this tutorial from [https://docker-mailserver.github.io/docker-mailserver/edge/examples/tutorials/basic-installation/](https://docker-mailserver.github.io/docker-mailserver/edge/examples/tutorials/basic-installation/) but this specific step we are coming to, creating keys for DKIM, is missing a crucial part; you have to create a mail account on your mail server before generating the DKIM. Why? No idea yet. Why isn’t it mentioned in the doc? Beats me. But you should really really make it clear to the authors of this document that this is a serious flaw to not have included. I spent a lot of time on google to figure this out…..
|
||||
|
||||
1. Add an account to your mailserver:
|
||||
`$ docker-compose run mailserver setup email add someone@example.com` and input a password when requested
|
||||
2. Set up DKIM with your docker-mailserver tag of choice:
|
||||
`$ docker-compose run mailserver setup config dkim`
|
||||
|
||||
When you have gotten this far without issues, you should be able to start the mailserver without the initial errors:
|
||||
`$ docker-compose up -d`
|
||||
|
||||
You should now be able to interact with the server using the command pattern `docker-compose exec mailserver` from here on.
|
||||
|
||||
### DNS
|
||||
|
||||
This part is tricky, because DNS records are finicky, they need to be thoroughly tested and take HEAPS of time to update. You will spend quite some time with this if you don’t get it right on the first try. Get yourself a couple of days vacation for this part.
|
||||
|
||||
#### DKIM
|
||||
|
||||
- TXT record
|
||||
- Hostname: `mail._domainkey.my.domain`
|
||||
- Value: Whatever is in the opendkim text file
|
||||
|
||||
|
||||
Add the newly created DKIM details to your domain’s DNS records by first echoing them for easy copy and paste:
|
||||
`$ cat config/opendkim/keys/my.domain/mail.txt`
|
||||
|
||||
This produces something you should add to your DNS records. Here’s the kicker; The strings are long and deliberately cut off because the maintainers don’t know if your DNS hoster supports strings that are longer than 255 characters in length. So, you will have either a good time entering these as you might know your DNS hoster’s limitations, or, more likely, a bad time and you have to figure out how to get these details stored properly. There’s some help though. MX Toolbox has a DKIM checker that you can utilise to verify you have your stuff set up right: https://mxtoolbox.com/dkim.aspx Good luck.
|
||||
|
||||
In the DNS editor, your hostname for this TXT record should be `mail._domainkey.my.domain` and the value should be the long ass string output from the cat command above.
|
||||
|
||||
After a long wait, check with the [MX Toolbox DKIM Lookup](https://mxtoolbox.com/dkim.aspx)
|
||||
|
||||
#### SPF
|
||||
|
||||
- TXT record
|
||||
- Hostname: @
|
||||
- Value: `v=spf1 mx ~all`
|
||||
|
||||
This is simpler, because there are very few parameters. It’s still required for your emails to have a decent chance of not being marked as spam. There can be some benefit to adding refernces to *other* known SPF records, such as tthe ones used by Outlook, etc. One of those is “`spf.protection.outlook.com`“
|
||||
|
||||
Add a TXT record to your `@` (hostname/zone/whatit’scalled) with the value: `v=spf1 mx ~all`
|
||||
|
||||
Tip: If you want to add Microsoft Outlook’s SPF, you would change the value to `v=spf1 include:spf.protection.outlook.com mx ~all`
|
||||
|
||||
#### Subdomain
|
||||
|
||||
- A record
|
||||
- Hostname: mail
|
||||
- Value: IP address of your mail server host
|
||||
|
||||
Also a simpler DNS record change. You want to have a subdomain that keeps tabs on the IP address of you mail server host.
|
||||
|
||||
1. Add an A record to the subdomain `mail` with the value of your mail server host IP address
|
||||
|
||||
#### MX
|
||||
|
||||
- MX record
|
||||
- Hostname: `@` or `mail.my.domain.`
|
||||
- Value: `mail.my.domain`
|
||||
|
||||
This is used for telling every server on the internets that you have a mail server somewhere with a certain subdomain name
|
||||
|
||||
1. Add an MX record to the `@` (hostname/zone/whatit’scalled) with the value:
|
||||
`mail.my.host.`
|
||||
|
||||
#### DMARC
|
||||
|
||||
- TXT record
|
||||
- Hostname: \_dmarc.my.domain
|
||||
- Value: `v=DMARC1; p=quarantine; rua=mailto:postmaster@my.domain; ruf=mailto:postmaster@my.domain; fo=1; adkim=s; aspf=s; pct=100; rf=afrf; ri=86400; sp=quarantine`
|
||||
|
||||
Complicateder piece of DNS record than the last two, because there are a bunch of parameters in the TXT records that you should read up on and understand. I’ll just give you what I use for now.
|
||||
|
||||
1. Add a TXT record to the `_dmarc` hostname with the value: `v=DMARC1; p=quarantine; rua=mailto:postmaster@my.domain; ruf=mailto:postmaster@my.domain; fo=1; adkim=s; aspf=s; pct=100; rf=afrf; ri=86400; sp=quarantine`
|
||||
|
||||
### Testing
|
||||
|
||||
Here’s the part where you need to verify and verify again that everthing is in working order. Mostly MX Toolbox to the rescue.
|
||||
|
||||
#### MX
|
||||
|
||||
- [https://mxtoolbox.com/MXLookup.aspx](https://mxtoolbox.com/MXLookup.aspx)
|
||||
- Format: my.domain
|
||||
|
||||
What you are looking for in the results is something along the lines of
|
||||
|
||||
- Pref: 0
|
||||
- Hostname: my.domain
|
||||
- IP address: 123.123.123.123
|
||||
|
||||
If there are more than one result in the table, you want to ensure your email server, the one with the IP of 123.123.123.123, is at the top, with a “Pref” (priority) value that is lower than any of the others.
|
||||
|
||||
#### SPF
|
||||
|
||||
- [https://mxtoolbox.com/spf.aspx](https://mxtoolbox.com/spf.aspx)
|
||||
- Format: my.domain
|
||||
|
||||
What you are looking for in the results is something along the lines of 4 rows, detailing the parameters of the SPF record. For instance, if the SPF record in DNS was set to: “v=spf1 include:spf.protection.outlook.com mx ~all” you want a result such as:
|
||||
|
||||
v
|
||||
|
||||
spf1
|
||||
|
||||
The SPF record version
|
||||
|
||||
+
|
||||
|
||||
include
|
||||
|
||||
spf.protection.outlook.com
|
||||
|
||||
Pass
|
||||
|
||||
The specified domain is searched for an ‘allow’.
|
||||
|
||||
+
|
||||
|
||||
mx
|
||||
|
||||
Pass
|
||||
|
||||
Match if IP is one of the MX hosts for given domain name.
|
||||
|
||||
~
|
||||
|
||||
all
|
||||
|
||||
SoftFail
|
||||
|
||||
Always matches. It goes at the end of your record.
|
||||
|
||||
#### DKIM
|
||||
|
||||
- https://mxtoolbox.com/dkim.aspx
|
||||
- Format: my.domain:mail
|
||||
|
||||
What you are looking for in the results is something along the lines of 4 rows, detailing the parameters of the DKIM record. For instance, if the DKIM (mail.\_domainkey) was set to: “v=DKIM1; h=sha256; k=rsa; p=jasdfjidjelajdvlkjg” you want a result such as:
|
||||
|
||||
v
|
||||
|
||||
DKIM1
|
||||
|
||||
Version
|
||||
|
||||
Identifies the record retrieved as a DKIM record. It must be the first tag in the record.
|
||||
|
||||
h
|
||||
|
||||
sha256
|
||||
|
||||
Hash Algorithms
|
||||
|
||||
A colon-separated list of hash algorithms that might be used.
|
||||
|
||||
k
|
||||
|
||||
rsa (Length: 4096 bits)
|
||||
|
||||
Key Type
|
||||
|
||||
Key Type The type of the key used by tag (p).
|
||||
|
||||
p
|
||||
|
||||
jasdfjidjelajdvlkjg
|
||||
|
||||
Public Key
|
||||
|
||||
The syntax and semantics of this tag value before being encoded in base64 are defined by the (k) tag.
|
||||
|
||||
#### DMARC
|
||||
|
||||
- https://mxtoolbox.com/dmarc.aspx
|
||||
- Format: my.domain
|
||||
|
||||
What you are looking for in the results is something along the lines of 10 rows, detailing the parameters of the DMARC record. For instance, if the DMARC (my.domain) was set to: “`v=DMARC1; p=quarantine; rua=mailto:postmaster@my.domain; ruf=mailto:postmaster@my.domain; fo=1; adkim=s; aspf=s; pct=100; rf=afrf; ri=86400; sp=quarantine`” you want a result such as:
|
||||
|
||||
v
|
||||
|
||||
DMARC1
|
||||
|
||||
Version
|
||||
|
||||
Identifies the record retrieved as a DMARC record. It must be the first tag in the list.
|
||||
p quarantine Policy Policy to apply to email that fails the DMARC test. Valid values can be ‘none’, ‘quarantine’, or ‘reject’.
|
||||
|
||||
p
|
||||
|
||||
quarantine
|
||||
|
||||
Policy
|
||||
|
||||
Policy to apply to email that fails the DMARC test. Valid values can be ‘none’, ‘quarantine’, or ‘reject’.
|
||||
|
||||
rua
|
||||
|
||||
mailto:postmaster@my.domain
|
||||
|
||||
Receivers
|
||||
|
||||
resses to which aggregate feedback is to be sent. Comma separated plain-text list of DMARC URIs.
|
||||
|
||||
ruf
|
||||
|
||||
mailto:postmaster@my.domain
|
||||
|
||||
Forensic Receivers
|
||||
|
||||
Addresses to which message-specific failure information is to be reported. Comma separated plain-text list of DMARC URIs.
|
||||
|
||||
fo
|
||||
|
||||
1
|
||||
|
||||
Forensic Reporting
|
||||
|
||||
Provides requested options for generation of failure reports. Valid values are any combination of characters ’01ds’ seperated by ‘:’.
|
||||
|
||||
adkim
|
||||
|
||||
s
|
||||
|
||||
Alignment Mode DKIM
|
||||
|
||||
Indicates whether strict or relaxed DKIM Identifier Alignment mode is required by the Domain Owner. Valid values can be ‘r’ (relaxed) or ‘s’ (strict mode).
|
||||
|
||||
adpf
|
||||
|
||||
s
|
||||
|
||||
Alignment Mode SPF
|
||||
|
||||
Indicates whether strict or relaxed SPF Identifier Alignment mode is required by the Domain Owner. Valid values can be ‘r’ (relaxed) or ‘s’ (strict mode).
|
||||
|
||||
pct
|
||||
|
||||
100
|
||||
|
||||
Percentage
|
||||
|
||||
Percentage of messages from the Domain Owner’s mail stream to which the DMARC policy is to be applied. Valid value is an integer between 0 to 100.
|
||||
|
||||
rf
|
||||
|
||||
afrf
|
||||
|
||||
Forensic Format
|
||||
|
||||
Format to be used for message-specific failure reports. Valid values are ‘afrf’ and ‘iodef’.
|
||||
|
||||
ri
|
||||
|
||||
86400
|
||||
|
||||
Reporting Interval
|
||||
|
||||
Indicates a request to Receivers to generate aggregate reports separated by no more than the requested number of seconds. Valid value is a 32-bit unsigned integer.
|
||||
|
||||
sp
|
||||
|
||||
quarantine
|
||||
|
||||
Sub-domain Policy
|
||||
|
||||
Requested Mail Receiver policy for all subdomains. Valid values can be ‘none’, ‘quarantine’, or ‘reject’.
|
||||
|
||||
There’s also a test results table, where you want all the checkmarks to turn up green.
|
||||
|
||||
## TLS Cert using letsencrypt
|
||||
|
||||
My weapon of choice is and will probably for a long time be certbot/letsencrypt. I chose to use the officially provided script in “certonly” mode. It is fully possible to acquire a certificate without involing anything else. I had a small bump in the road where I included a domain that had an A record for my HTTP services and that failed the whole process because the HTTP service wouldn’t supply the info needed for certbot to complete. The gist of the command, though, is:
|
||||
|
||||
$ sudo certbot certonly --standalone -d mail.my.domain1 -d mail.my.domain2 \[more parameters\]
|
||||
|
||||
and follow the instructions. Make sure to supply the *mail* domain, e.g. `mail.my.domain` and not only the root domain, as it can make things end up like it did for me in the beginning, where I don’t have a webserver that can properly reply on the ports/URL:s that certbot expects.
|
||||
|
||||
Now, edit the `docker-compose.yml` file to add a volume that points to the letsencrypt cert store path. For my setup this would result in a line under the volumes-section:
|
||||
|
||||
...
|
||||
- /etc/letsencrypt:/etc/letsencrypt:ro
|
||||
...
|
||||
|
||||
Don’t forget to restart your docker-mailserver, as a reload of details is required.
|
||||
|
||||
## Catchall for everything but valid email accounts
|
||||
|
||||
This took some digging around. docker-mailserver isn’t really the authority here, but postfix, that’s included in docker-mailserver. I did find a couple of nice pointers in the docker-mailserver issue tracker that gave me the following understanding to get catchall to work as I expect; Catching all email to a single catchall-specific mail account, and deliver mail designated to valid accounts without ending up in both catchall and the valid account inbox:
|
||||
|
||||
- Valid accounts need to have aliases to themselves
|
||||
- The domain, e.g. my.domain, need to have an alias pointing to the catchall account
|
||||
|
||||
So, for the sake of completeness, this is how would go about it:
|
||||
|
||||
1. Create any valid email account(s) (these will require their own passwords)
|
||||
2. Create the catchall account (this will also require its own password)
|
||||
3. Create an alias to the catchall account with
|
||||
`$ docker-compose exec mailserver setup alias add @my.domain @catchall.my.domain`
|
||||
4. Edit the newly created file `config/postfix-virtual.cf` and modify it to the following format:
|
||||
|
||||
account1@my.domain account1@my.domain
|
||||
account2@my.domain account2@my.domain
|
||||
...
|
||||
@my.domain catchall@my.domain
|
||||
|
||||
**The order is crucial.** You want the catchall to be at the bottom of this file at all times.
|
||||
|
||||
## Multiple domains, one server
|
||||
|
||||
This ties into the TLS Cert section, insofar that the command to generate valid certificates is:
|
||||
|
||||
$ sudo certbot certonly --standalone -d mail.my.domain1 -d mail.my.domain2 \[more parameters\]
|
||||
|
||||
and you will need to secure that you have your docker-compose.yml file set up to take into account the certificates:
|
||||
|
||||
...
|
||||
\- /etc/letsencrypt:/etc/letsencrypt:ro
|
||||
...
|
||||
|
||||
and you need to have restarted docker-mailserver to have it react to those changes.
|
||||
|
||||
And, you also need to have updated the `mailserver.env` file to tell docker-mailserver that you’ll be using letsencrypt.
|
||||
|
||||
Other than that, there’s a few more things needed for your *second domain*. It is in general much the same as your primary domain, except for a few specific details that need to be unique to your second domain. Here’s the complete list as to not miss out on anything
|
||||
|
||||
- MX DNS record
|
||||
- SPF DNS record
|
||||
- DKIM DNS record
|
||||
- DMARC DNS record
|
||||
- An email account tied to the second domain
|
||||
|
||||
Ok, that’s a lot of stuff again! But here’s the kicker; a few of them you can use as they mostly are from your primary domain, and others are super easy to set up.
|
||||
|
||||
The ones you can copy and easily modify from your primary domain are
|
||||
|
||||
- MX record – You will use the same IP address for this as the primary one
|
||||
- SPF record – You use the same TXT value as the primary one
|
||||
- DMARC record – You use the same TXT value as the primary one, but I also modified the postmaster email address to align with the second domain
|
||||
|
||||
And this is the part where you need to do a little more work
|
||||
|
||||
### DKIM
|
||||
|
||||
This is very much like generating DKIM from the setup steps in this page;
|
||||
|
||||
1. Create an email account, e.g. `postmaster@second.domain`
|
||||
2. Generate the DKIM DNS record details by running `$ docker-compose run mailserver setup config dkim` which will generate new keyfiles for your new domain (remember that the setup-script use the domain names of already created accounts to determine what domains to generate DKIM DNS records for)
|
||||
3. Copy and paste the value from `$ cat config/opendkim/keys/second.domain/mail.txt` and create a new DNS record as explained in the DKIM-section in the setup steps on this page.
|
||||
|
||||
###### Changelog summary, 2021-10-14
|
||||
@@ -0,0 +1,83 @@
|
||||
---
|
||||
page-title: "Slurm Workload Manager - Overview"
|
||||
url: https://slurm.schedmd.com/overview.html
|
||||
date: "2023-04-23 13:09:14"
|
||||
---
|
||||
## Overview
|
||||
|
||||
Slurm is an open source, fault-tolerant, and highly scalable cluster management and job scheduling system for large and small Linux clusters. Slurm requires no kernel modifications for its operation and is relatively self-contained. As a cluster workload manager, Slurm has three key functions. First, it allocates exclusive and/or non-exclusive access to resources (compute nodes) to users for some duration of time so they can perform work. Second, it provides a framework for starting, executing, and monitoring work (normally a parallel job) on the set of allocated nodes. Finally, it arbitrates contention for resources by managing a queue of pending work. Optional plugins can be used for [accounting](https://slurm.schedmd.com/accounting.html), [advanced reservation](https://slurm.schedmd.com/reservations.html), [gang scheduling](https://slurm.schedmd.com/gang_scheduling.html) (time sharing for parallel jobs), backfill scheduling, [topology optimized resource selection](https://slurm.schedmd.com/topology.html), [resource limits](https://slurm.schedmd.com/resource_limits.html) by user or bank account, and sophisticated [multifactor job prioritization](https://slurm.schedmd.com/priority_multifactor.html) algorithms.
|
||||
|
||||
## Architecture[](https://slurm.schedmd.com/overview.html#architecture)
|
||||
|
||||
Slurm has a centralized manager, **slurmctld**, to monitor resources and work. There may also be a backup manager to assume those responsibilities in the event of failure. Each compute server (node) has a **slurmd** daemon, which can be compared to a remote shell: it waits for work, executes that work, returns status, and waits for more work. The **slurmd** daemons provide fault-tolerant hierarchical communications. There is an optional **slurmdbd** (Slurm DataBase Daemon) which can be used to record accounting information for multiple Slurm-managed clusters in a single database. There is an optional [**slurmrestd** (Slurm REST API Daemon)](https://slurm.schedmd.com/rest.html) which can be used to interact with Slurm through its [REST API](https://en.wikipedia.org/wiki/Representational_state_transfer). User tools include **srun** to initiate jobs, **scancel** to terminate queued or running jobs, **sinfo** to report system status, **squeue** to report the status of jobs, and **sacct** to get information about jobs and job steps that are running or have completed. The **sview** commands graphically reports system and job status including network topology. There is an administrative tool **scontrol** available to monitor and/or modify configuration and state information on the cluster. The administrative tool used to manage the database is **sacctmgr**. It can be used to identify the clusters, valid users, valid bank accounts, etc. APIs are available for all functions.
|
||||
|
||||
|
||||
Figure 1. Slurm components
|
||||
|
||||
Slurm has a general-purpose plugin mechanism available to easily support various infrastructures. This permits a wide variety of Slurm configurations using a building block approach. These plugins presently include:
|
||||
|
||||
- Accounting Storage: Primarily Used to store historical data about jobs. When used with SlurmDBD (Slurm Database Daemon), it can also supply a limits based system along with historical system status.
|
||||
- Account Gather Energy: Gather energy consumption data per job or nodes in the system. This plugin is integrated with the Accounting Storage and Job Account Gather plugins.
|
||||
- Authentication of communications: Provides authentication mechanism between various components of Slurm.
|
||||
- [Containers](https://slurm.schedmd.com/containers.html): HPC workload container support and implementations.
|
||||
- Credential (Digital Signature Generation): Mechanism used to generate a digital signature, which is used to validate that job step is authorized to execute on specific nodes. This is distinct from the plugin used for Authentication since the job step request is sent from the user's srun command rather than directly from the slurmctld daemon, which generates the job step credential and its digital signature.
|
||||
- [Generic Resources](https://slurm.schedmd.com/gres.html): Provide interface to control generic resources, including Graphical Processing Units (GPUs).
|
||||
- [Job Submit](https://slurm.schedmd.com/job_submit_plugins.html): Custom plugin to allow site specific control over job requirements at submission and update.
|
||||
- Job Accounting Gather: Gather job step resource utilization data.
|
||||
- Job Completion Logging: Log a job's termination data. This is typically a subset of data stored by an Accounting Storage Plugin.
|
||||
- Launchers: Controls the mechanism used by the ['srun'](https://slurm.schedmd.com/srun.html) command to launch the tasks.
|
||||
- MPI: Provides different hooks for the various MPI implementations. For example, this can set MPI specific environment variables.
|
||||
- [Preempt](https://slurm.schedmd.com/preempt.html): Determines which jobs can preempt other jobs and the preemption mechanism to be used.
|
||||
- Priority: Assigns priorities to jobs upon submission and on an ongoing basis (e.g. as they age).
|
||||
- Process tracking (for signaling): Provides a mechanism for identifying the processes associated with each job. Used for job accounting and signaling.
|
||||
- Scheduler: Plugin determines how and when Slurm schedules jobs.
|
||||
- Node selection: Plugin used to determine the resources used for a job allocation.
|
||||
- [Site Factor (Priority)](https://slurm.schedmd.com/site_factor.html): Assigns a specific site\_factor component of a job's multifactor priority to jobs upon submission and on an ongoing basis (e.g. as they age).
|
||||
- Switch or interconnect: Plugin to interface with a switch or interconnect. For most systems (Ethernet or InfiniBand) this is not needed.
|
||||
- Task Affinity: Provides mechanism to bind a job and its individual tasks to specific processors.
|
||||
- Network Topology: Optimizes resource selection based upon the network topology. Used for both job allocations and advanced reservation.
|
||||
|
||||
The entities managed by these Slurm daemons, shown in Figure 2, include **nodes**, the compute resource in Slurm, **partitions**, which group nodes into logical sets, **jobs**, or allocations of resources assigned to a user for a specified amount of time, and **job steps**, which are sets of (possibly parallel) tasks within a job. The partitions can be considered job queues, each of which has an assortment of constraints such as job size limit, job time limit, users permitted to use it, etc. Priority-ordered jobs are allocated nodes within a partition until the resources (nodes, processors, memory, etc.) within that partition are exhausted. Once a job is assigned a set of nodes, the user is able to initiate parallel work in the form of job steps in any configuration within the allocation. For instance, a single job step may be started that utilizes all nodes allocated to the job, or several job steps may independently use a portion of the allocation. Slurm provides resource management for the processors allocated to a job, so that multiple job steps can be simultaneously submitted and queued until there are available resources within the job's allocation.
|
||||
|
||||
|
||||
Figure 2. Slurm entities
|
||||
|
||||
## Configurability[](https://slurm.schedmd.com/overview.html#configurability)
|
||||
|
||||
Node state monitored include: count of processors, size of real memory, size of temporary disk space, and state (UP, DOWN, etc.). Additional node information includes weight (preference in being allocated work) and features (arbitrary information such as processor speed or type). Nodes are grouped into partitions, which may contain overlapping nodes so they are best thought of as job queues. Partition information includes: name, list of associated nodes, state (UP or DOWN), maximum job time limit, maximum node count per job, group access list, priority (important if nodes are in multiple partitions) and shared node access policy with optional over-subscription level for gang scheduling (e.g. YES, NO or FORCE:2). Bit maps are used to represent nodes and scheduling decisions can be made by performing a small number of comparisons and a series of fast bit map manipulations. A sample (partial. Slurm configuration file follows.
|
||||
|
||||
#
|
||||
# Sample /etc/slurm.conf
|
||||
#
|
||||
SlurmctldHost=linux0001 # Primary server
|
||||
SlurmctldHost=linux0002 # Backup server
|
||||
#
|
||||
AuthType=auth/munge
|
||||
Epilog=/usr/local/slurm/sbin/epilog
|
||||
PluginDir=/usr/local/slurm/lib
|
||||
Prolog=/usr/local/slurm/sbin/prolog
|
||||
SlurmctldPort=7002
|
||||
SlurmctldTimeout=120
|
||||
SlurmdPort=7003
|
||||
SlurmdSpoolDir=/var/tmp/slurmd.spool
|
||||
SlurmdTimeout=120
|
||||
StateSaveLocation=/usr/local/slurm/slurm.state
|
||||
TmpFS=/tmp
|
||||
#
|
||||
# Node Configurations
|
||||
#
|
||||
NodeName=DEFAULT CPUs=4 TmpDisk=16384 State=IDLE
|
||||
NodeName=lx\[0001-0002\] State=DRAINED
|
||||
NodeName=lx\[0003-8000\] RealMemory=2048 Weight=2
|
||||
NodeName=lx\[8001-9999\] RealMemory=4096 Weight=6 Feature=video
|
||||
#
|
||||
# Partition Configurations
|
||||
#
|
||||
PartitionName=DEFAULT MaxTime=30 MaxNodes=2
|
||||
PartitionName=login Nodes=lx\[0001-0002\] State=DOWN
|
||||
PartitionName=debug Nodes=lx\[0003-0030\] State=UP Default=YES
|
||||
PartitionName=class Nodes=lx\[0031-0040\] AllowGroups=students
|
||||
PartitionName=DEFAULT MaxTime=UNLIMITED MaxNodes=4096
|
||||
PartitionName=batch Nodes=lx\[0041-9999\]
|
||||
|
||||
Last modified 6 August 2021
|
||||
@@ -0,0 +1,196 @@
|
||||
---
|
||||
page-title: "Steamship Documentation"
|
||||
url: https://docs.steamship.com/
|
||||
date: "2023-04-17 08:40:46"
|
||||
---
|
||||
[Back to top](https://docs.steamship.com/#)
|
||||
|
||||
[Edit this page](https://github.com/steamship-core/python-client/edit/main/docs/index.rst "Edit this page")
|
||||
|
||||
Toggle table of contents sidebar
|
||||
|
||||
## Steamship[#](https://docs.steamship.com/#steamship "Permalink to this heading")
|
||||
|
||||
Steamship is the fastest way to add AI to your software.
|
||||
|
||||
Think of Steamship as both a package manager and package hosting for AI. Each [Steamship package](https://www.steamship.com/packages) runs in the cloud on a managed stack.
|
||||
|
||||
## Steamship in 30 seconds[#](https://docs.steamship.com/#steamship-in-30-seconds "Permalink to this heading")
|
||||
|
||||
- [Use Plugins](https://docs.steamship.com/plugins/using/index.html#using-plugins) for common operations like generating text with GPT, converting a CSV to text, or generating an image from text. Steamship manages asynchronicity and retries.
|
||||
|
||||
- [Store data in Files, Blocks, and Tags](https://docs.steamship.com/data/index.html#data-model). This allows you to [query](https://docs.steamship.com/data/queries/index.html#queries) or [search](https://docs.steamship.com/embedding-search/index.html#embedding-search-index) it later.
|
||||
|
||||
- [Deploy as a Package](https://docs.steamship.com/packages/developing/index.html#developing-packages), creating a scalable API for your front end.
|
||||
|
||||
- [Create as many instances of the Package](https://docs.steamship.com/packages/developing/index.html#creating-package-instances) as you want, each with its own data.
|
||||
|
||||
|
||||
The best way to start is to make a simple package:
|
||||
|
||||
## Start from a template[#](https://docs.steamship.com/#start-from-a-template "Permalink to this heading")
|
||||
|
||||
Clone one of our starter packages ([https://github.com/steamship-packages](https://github.com/steamship-packages)):
|
||||
|
||||
git clone https://github.com/steamship-packages/empty-package.git
|
||||
|
||||
Create a virtual environment and install dependencies:
|
||||
|
||||
python3 \-m venv venv
|
||||
source venv/bin/activate
|
||||
|
||||
pip install \-r requirements.txt
|
||||
pip install \-r requirements.dev.txt
|
||||
|
||||
and start editing `src/api.py`.
|
||||
|
||||
## Start from scratch[#](https://docs.steamship.com/#start-from-scratch "Permalink to this heading")
|
||||
|
||||
First, install our SDK and CLI (ideally in a virtual environment):
|
||||
|
||||
python3 \-m venv venv
|
||||
source venv/bin/activate
|
||||
|
||||
pip install steamship
|
||||
|
||||
Now copy this into `api.py`:
|
||||
|
||||
from steamship.invocable import post, PackageService
|
||||
|
||||
class MyPackage(PackageService):
|
||||
|
||||
@post("hello\_world")
|
||||
def hello\_world(self, name: str \= None) \-> str:
|
||||
return f"Hello, {name}"
|
||||
|
||||
## Next Steps[#](https://docs.steamship.com/#next-steps "Permalink to this heading")
|
||||
|
||||
**Using Packages**
|
||||
|
||||
Use full-stack language AI packages in your own code.
|
||||
|
||||
**Developing Packages**
|
||||
|
||||
Build and deploy packages with our low-code framework.
|
||||
|
||||
**Package Cookbook**
|
||||
|
||||
Package examples for common scenarios.
|
||||
|
||||
## Contents[#](https://docs.steamship.com/#contents "Permalink to this heading")
|
||||
|
||||
- [Configuration](https://docs.steamship.com/configuration/index.html)
|
||||
- [Authentication](https://docs.steamship.com/configuration/authentication.html)
|
||||
- [Steamship Configuration File](https://docs.steamship.com/configuration/authentication.html#steamship-configuration-file)
|
||||
- [Using Multiple Profiles](https://docs.steamship.com/configuration/authentication.html#using-multiple-profiles)
|
||||
- [Environment Variables](https://docs.steamship.com/configuration/authentication.html#environment-variables)
|
||||
- [Client Libraries](https://docs.steamship.com/configuration/clients.html)
|
||||
- [Python Client](https://docs.steamship.com/configuration/clients.html#python-client)
|
||||
- [Typescript Client](https://docs.steamship.com/configuration/clients.html#typescript-client)
|
||||
- [CLI](https://docs.steamship.com/configuration/cli.html)
|
||||
- [HTTP API](https://docs.steamship.com/configuration/http.html)
|
||||
- [Requests](https://docs.steamship.com/configuration/http.html#requests)
|
||||
- [Optional Headers](https://docs.steamship.com/configuration/http.html#optional-headers)
|
||||
- [Engine Response Format](https://docs.steamship.com/configuration/http.html#engine-response-format)
|
||||
- [Creating a Package Instance](https://docs.steamship.com/configuration/http.html#creating-a-package-instance)
|
||||
- [Invoking a Package Method](https://docs.steamship.com/configuration/http.html#invoking-a-package-method)
|
||||
- [Packages](https://docs.steamship.com/packages/index.html)
|
||||
- [Packages Table of Contents](https://docs.steamship.com/packages/index.html#packages-table-of-contents)
|
||||
- [Using Packages](https://docs.steamship.com/packages/using.html)
|
||||
- [Package FAQ](https://docs.steamship.com/packages/using.html#package-faq)
|
||||
- [Developing Packages](https://docs.steamship.com/packages/developing/index.html)
|
||||
- [Customizing your Package](https://docs.steamship.com/packages/developing/index.html#customizing-your-package)
|
||||
- [Package Project Structure](https://docs.steamship.com/packages/developing/project-structure.html)
|
||||
- [Package Cookbook](https://docs.steamship.com/packages/cookbook/index.html)
|
||||
- [Working with Language](https://docs.steamship.com/packages/cookbook/index.html#working-with-language)
|
||||
- [Building Packages](https://docs.steamship.com/packages/cookbook/index.html#building-packages)
|
||||
- [Response Types](https://docs.steamship.com/packages/cookbook/index.html#response-types)
|
||||
- [Plugins](https://docs.steamship.com/plugins/index.html)
|
||||
- [File Importers](https://docs.steamship.com/plugins/index.html#file-importers)
|
||||
- [Blockifiers](https://docs.steamship.com/plugins/index.html#blockifiers)
|
||||
- [Taggers](https://docs.steamship.com/plugins/index.html#taggers)
|
||||
- [Generators](https://docs.steamship.com/plugins/index.html#generators)
|
||||
- [Embedders](https://docs.steamship.com/plugins/index.html#embedders)
|
||||
- [Data](https://docs.steamship.com/data/index.html)
|
||||
- [Workspaces](https://docs.steamship.com/data/workspaces.html)
|
||||
- [Creating Workspaces](https://docs.steamship.com/data/workspaces.html#creating-workspaces)
|
||||
- [Files](https://docs.steamship.com/data/files.html)
|
||||
- [Creating Files Directly](https://docs.steamship.com/data/files.html#creating-files-directly)
|
||||
- [Blocks](https://docs.steamship.com/data/blocks.html)
|
||||
- [Creating Blocks](https://docs.steamship.com/data/blocks.html#id2)
|
||||
- [Tags](https://docs.steamship.com/data/tags.html)
|
||||
- [Ways to use Tags](https://docs.steamship.com/data/tags.html#ways-to-use-tags)
|
||||
- [Tag Schemas](https://docs.steamship.com/data/tags.html#tag-schemas)
|
||||
- [Block and File Tags](https://docs.steamship.com/data/tags.html#block-and-file-tags)
|
||||
- [Querying Data](https://docs.steamship.com/data/queries/index.html)
|
||||
- [Usage](https://docs.steamship.com/data/queries/index.html#usage)
|
||||
- [Language Description](https://docs.steamship.com/data/queries/index.html#language-description)
|
||||
- [Unary Predicates](https://docs.steamship.com/data/queries/index.html#unary-predicates)
|
||||
- [Binary Predicates](https://docs.steamship.com/data/queries/index.html#binary-predicates)
|
||||
- [Binary Relations](https://docs.steamship.com/data/queries/index.html#binary-relations)
|
||||
- [Conjunctions](https://docs.steamship.com/data/queries/index.html#conjunctions)
|
||||
- [Special Predicates](https://docs.steamship.com/data/queries/index.html#special-predicates)
|
||||
- [Embedding Search Index](https://docs.steamship.com/embedding-search/index.html)
|
||||
- [Inserting Data](https://docs.steamship.com/embedding-search/index.html#inserting-data)
|
||||
- [Querying Data](https://docs.steamship.com/embedding-search/index.html#querying-data)
|
||||
- [Developer Reference](https://docs.steamship.com/developing/index.html)
|
||||
- [Cloning a Starter Project](https://docs.steamship.com/developing/project-creation.html)
|
||||
- [The Steamship Manifest file](https://docs.steamship.com/developing/steamship-manifest.html)
|
||||
- [Plugin Configuration](https://docs.steamship.com/developing/steamship-manifest.html#plugin-configuration)
|
||||
- [Steamship Registry](https://docs.steamship.com/developing/steamship-manifest.html#steamship-registry)
|
||||
- [Python Environment Setup](https://docs.steamship.com/developing/environment-setup.html)
|
||||
- [Accepting Configuration](https://docs.steamship.com/developing/configuration.html)
|
||||
- [Defining and Accepting configuration in your code](https://docs.steamship.com/developing/configuration.html#defining-and-accepting-configuration-in-your-code)
|
||||
- [Storing Secrets](https://docs.steamship.com/developing/storing-secrets.html)
|
||||
- [Writing Tests](https://docs.steamship.com/developing/testing.html)
|
||||
- [Logging](https://docs.steamship.com/developing/testing.html#logging)
|
||||
- [Throwing Errors](https://docs.steamship.com/developing/testing.html#throwing-errors)
|
||||
- [Manual Testing](https://docs.steamship.com/developing/testing.html#manual-testing)
|
||||
- [Automated testing](https://docs.steamship.com/developing/testing.html#automated-testing)
|
||||
- [Automated testing setup](https://docs.steamship.com/developing/testing.html#automated-testing-setup)
|
||||
- [Modifying or removing automated testing](https://docs.steamship.com/developing/testing.html#modifying-or-removing-automated-testing)
|
||||
- [Deploying](https://docs.steamship.com/developing/deploying.html)
|
||||
- [Deploying with the Steamship CLI](https://docs.steamship.com/developing/deploying.html#deploying-with-the-steamship-cli)
|
||||
- [Deploying via GitHub Actions](https://docs.steamship.com/developing/deploying.html#deploying-via-github-actions)
|
||||
- [Automated Deployment Setup](https://docs.steamship.com/developing/deploying.html#automated-deployment-setup)
|
||||
- [Modifying or disabling automated deployments](https://docs.steamship.com/developing/deploying.html#modifying-or-disabling-automated-deployments)
|
||||
- [Troubleshooting Deployments](https://docs.steamship.com/developing/deploying.html#troubleshooting-deployments)
|
||||
- [The deployment fails because the version already exists](https://docs.steamship.com/developing/deploying.html#the-deployment-fails-because-the-version-already-exists)
|
||||
- [The deployment fails because the tag does not match the manifest file](https://docs.steamship.com/developing/deploying.html#the-deployment-fails-because-the-tag-does-not-match-the-manifest-file)
|
||||
- [The deployment fails with an authentication error](https://docs.steamship.com/developing/deploying.html#the-deployment-fails-with-an-authentication-error)
|
||||
- [Updating your Web Listing](https://docs.steamship.com/developing/updating-web-listing.html)
|
||||
- [Updating your Web Listing](https://docs.steamship.com/developing/updating-web-listing.html#updating-your-web-listing)
|
||||
- [Adding taglines, demo links, and author icons](https://docs.steamship.com/developing/updating-web-listing.html#adding-taglines-demo-links-and-author-icons)
|
||||
- [Python Client Reference](https://docs.steamship.com/api/modules.html)
|
||||
- [steamship package](https://docs.steamship.com/api/steamship.html)
|
||||
- [Subpackages](https://docs.steamship.com/api/steamship.html#subpackages)
|
||||
- [steamship.base package](https://docs.steamship.com/api/steamship.base.html)
|
||||
- [steamship.cli package](https://docs.steamship.com/api/steamship.cli.html)
|
||||
- [steamship.client package](https://docs.steamship.com/api/steamship.client.html)
|
||||
- [steamship.data package](https://docs.steamship.com/api/steamship.data.html)
|
||||
- [steamship.experimental package](https://docs.steamship.com/api/steamship.experimental.html)
|
||||
- [steamship.invocable package](https://docs.steamship.com/api/steamship.invocable.html)
|
||||
- [steamship.plugin package](https://docs.steamship.com/api/steamship.plugin.html)
|
||||
- [steamship.utils package](https://docs.steamship.com/api/steamship.utils.html)
|
||||
- [Module contents](https://docs.steamship.com/api/steamship.html#module-steamship)
|
||||
- [`Block`](https://docs.steamship.com/api/steamship.html#steamship.Block)
|
||||
- [`Configuration`](https://docs.steamship.com/api/steamship.html#steamship.Configuration)
|
||||
- [`DocTag`](https://docs.steamship.com/api/steamship.html#steamship.DocTag)
|
||||
- [`EmbeddingIndex`](https://docs.steamship.com/api/steamship.html#steamship.EmbeddingIndex)
|
||||
- [`File`](https://docs.steamship.com/api/steamship.html#steamship.File)
|
||||
- [`MimeTypes`](https://docs.steamship.com/api/steamship.html#steamship.MimeTypes)
|
||||
- [`Package`](https://docs.steamship.com/api/steamship.html#steamship.Package)
|
||||
- [`PackageInstance`](https://docs.steamship.com/api/steamship.html#steamship.PackageInstance)
|
||||
- [`PackageVersion`](https://docs.steamship.com/api/steamship.html#steamship.PackageVersion)
|
||||
- [`PluginInstance`](https://docs.steamship.com/api/steamship.html#steamship.PluginInstance)
|
||||
- [`PluginVersion`](https://docs.steamship.com/api/steamship.html#steamship.PluginVersion)
|
||||
- [`RuntimeEnvironments`](https://docs.steamship.com/api/steamship.html#steamship.RuntimeEnvironments)
|
||||
- [`Steamship`](https://docs.steamship.com/api/steamship.html#steamship.Steamship)
|
||||
- [`SteamshipError`](https://docs.steamship.com/api/steamship.html#steamship.SteamshipError)
|
||||
- [`Tag`](https://docs.steamship.com/api/steamship.html#steamship.Tag)
|
||||
- [`Task`](https://docs.steamship.com/api/steamship.html#steamship.Task)
|
||||
- [`TaskState`](https://docs.steamship.com/api/steamship.html#steamship.TaskState)
|
||||
- [`Workspace`](https://docs.steamship.com/api/steamship.html#steamship.Workspace)
|
||||
- [`check_environment()`](https://docs.steamship.com/api/steamship.html#steamship.check_environment)
|
||||
- [License](https://docs.steamship.com/license.html)
|
||||
- [Authors](https://docs.steamship.com/authors.html)
|
||||
+330
@@ -0,0 +1,330 @@
|
||||
---
|
||||
page-title: "Torantulino/Auto-GPT: An experimental open-source attempt to make GPT-4 fully autonomous."
|
||||
url: https://github.com/Torantulino/Auto-GPT
|
||||
date: "2023-04-14 17:06:34"
|
||||
---
|
||||
## Auto-GPT: An Autonomous GPT-4 Experiment
|
||||
|
||||
[](https://camo.githubusercontent.com/f86acaa79ffac59dbad1bf976872d731c4490b6bd5657f6ae338a41ed91bffae/68747470733a2f2f696d672e736869656c64732e696f2f6769746875622f73746172732f546f72616e74756c696e6f2f6175746f2d6770743f7374796c653d736f6369616c) [](https://twitter.com/SigGravitas) [](https://discord.gg/autogpt) [](https://github.com/Torantulino/Auto-GPT/actions/workflows/ci.yml)
|
||||
|
||||
Auto-GPT is an experimental open-source application showcasing the capabilities of the GPT-4 language model. This program, driven by GPT-4, chains together LLM "thoughts", to autonomously achieve whatever goal you set. As one of the first examples of GPT-4 running fully autonomously, Auto-GPT pushes the boundaries of what is possible with AI.
|
||||
|
||||
### Demo (30/03/2023):
|
||||
|
||||
## 💖 Help Fund Auto-GPT's Development 💖
|
||||
|
||||
If you can spare a coffee, you can help to cover the API costs of developing Auto-GPT and help push the boundaries of fully autonomous AI! A full day of development can easily cost as much as $20 in API costs, which for a free project is quite limiting. Your support is greatly appreciated
|
||||
|
||||
Development of this free, open-source project is made possible by all the [contributors](https://github.com/Torantulino/Auto-GPT/graphs/contributors) and [sponsors](https://github.com/sponsors/Torantulino). If you'd like to sponsor this project and have your avatar or company logo appear below [click here](https://github.com/sponsors/Torantulino).
|
||||
|
||||
### Individual Sponsors
|
||||
|
||||
[](https://github.com/robinicus) [](https://github.com/prompthero) [](https://github.com/crizzler) [](https://github.com/tob-le-rone) [](https://github.com/FSTatSBS) [](https://github.com/toverly1) [](https://github.com/ddtarazona) [](https://github.com/Nalhos) [](https://github.com/Kazamario) [](https://github.com/pingbotan) [](https://github.com/indoor47) [](https://github.com/AuroraHolding) [](https://github.com/kreativai) [](https://github.com/hunteraraujo) [](https://github.com/Explorergt92) [](https://github.com/judegomila) [](https://github.com/thepok) [](https://github.com/SpacingLily) [](https://github.com/merwanehamadi) [](https://github.com/m) [](https://github.com/zkonduit) [](https://github.com/maxxflyer) [](https://github.com/tekelsey) [](https://github.com/digisomni) [](https://github.com/nocodeclarity) [](https://github.com/tjarmain)
|
||||
|
||||
## Table of Contents
|
||||
|
||||
- [Auto-GPT: An Autonomous GPT-4 Experiment](https://github.com/Torantulino/Auto-GPT#auto-gpt-an-autonomous-gpt-4-experiment)
|
||||
- [Demo (30/03/2023):](https://github.com/Torantulino/Auto-GPT#demo-30032023)
|
||||
- [Table of Contents](https://github.com/Torantulino/Auto-GPT#table-of-contents)
|
||||
- [🚀 Features](https://github.com/Torantulino/Auto-GPT#-features)
|
||||
- [📋 Requirements](https://github.com/Torantulino/Auto-GPT#-requirements)
|
||||
- [💾 Installation](https://github.com/Torantulino/Auto-GPT#-installation)
|
||||
- [🔧 Usage](https://github.com/Torantulino/Auto-GPT#-usage)
|
||||
- [Logs](https://github.com/Torantulino/Auto-GPT#logs)
|
||||
- [🗣️ Speech Mode](https://github.com/Torantulino/Auto-GPT#%EF%B8%8F-speech-mode)
|
||||
- [🔍 Google API Keys Configuration](https://github.com/Torantulino/Auto-GPT#-google-api-keys-configuration)
|
||||
- [Setting up environment variables](https://github.com/Torantulino/Auto-GPT#setting-up-environment-variables)
|
||||
- [Redis Setup](https://github.com/Torantulino/Auto-GPT#redis-setup)
|
||||
- [🌲 Pinecone API Key Setup](https://github.com/Torantulino/Auto-GPT#-pinecone-api-key-setup)
|
||||
- [Setting up environment variables](https://github.com/Torantulino/Auto-GPT#setting-up-environment-variables-1)
|
||||
- [Setting Your Cache Type](https://github.com/Torantulino/Auto-GPT#setting-your-cache-type)
|
||||
- [View Memory Usage](https://github.com/Torantulino/Auto-GPT#view-memory-usage)
|
||||
- [💀 Continuous Mode ⚠️](https://github.com/Torantulino/Auto-GPT#-continuous-mode-%EF%B8%8F)
|
||||
- [GPT3.5 ONLY Mode](https://github.com/Torantulino/Auto-GPT#gpt35-only-mode)
|
||||
- [🖼 Image Generation](https://github.com/Torantulino/Auto-GPT#-image-generation)
|
||||
- [⚠️ Limitations](https://github.com/Torantulino/Auto-GPT#%EF%B8%8F-limitations)
|
||||
- [🛡 Disclaimer](https://github.com/Torantulino/Auto-GPT#-disclaimer)
|
||||
- [🐦 Connect with Us on Twitter](https://github.com/Torantulino/Auto-GPT#-connect-with-us-on-twitter)
|
||||
- [Run tests](https://github.com/Torantulino/Auto-GPT#run-tests)
|
||||
- [Run linter](https://github.com/Torantulino/Auto-GPT#run-linter)
|
||||
|
||||
## 🚀 Features
|
||||
|
||||
- 🌐 Internet access for searches and information gathering
|
||||
- 💾 Long-Term and Short-Term memory management
|
||||
- 🧠 GPT-4 instances for text generation
|
||||
- 🔗 Access to popular websites and platforms
|
||||
- 🗃️ File storage and summarization with GPT-3.5
|
||||
|
||||
## 📋 Requirements
|
||||
|
||||
- environments(just choose one)
|
||||
- [vscode + devcontainer](https://marketplace.visualstudio.com/items?itemName=ms-vscode-remote.remote-containers): It has been configured in the .devcontainer folder and can be used directly
|
||||
- [Python 3.8 or later](https://www.tutorialspoint.com/how-to-install-python-in-windows)
|
||||
- [OpenAI API key](https://platform.openai.com/account/api-keys)
|
||||
- [PINECONE API key](https://www.pinecone.io/)
|
||||
|
||||
Optional:
|
||||
|
||||
- [ElevenLabs Key](https://elevenlabs.io/) (If you want the AI to speak)
|
||||
|
||||
## 💾 Installation
|
||||
|
||||
To install Auto-GPT, follow these steps:
|
||||
|
||||
1. Make sure you have all the **requirements** above, if not, install/get them.
|
||||
|
||||
*The following commands should be executed in a CMD, Bash or Powershell window. To do this, go to a folder on your computer, click in the folder path at the top and type CMD, then press enter.*
|
||||
|
||||
2. Clone the repository: For this step you need Git installed, but you can just download the zip file instead by clicking the button at the top of this page ☝️
|
||||
|
||||
```
|
||||
git clone https://github.com/Torantulino/Auto-GPT.git
|
||||
```
|
||||
|
||||
3. Navigate to the project directory: *(Type this into your CMD window, you're aiming to navigate the CMD window to the repository you just downloaded)*
|
||||
|
||||
4. Install the required dependencies: *(Again, type this into your CMD window)*
|
||||
|
||||
```
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
5. Rename `.env.template` to `.env` and fill in your `OPENAI_API_KEY`. If you plan to use Speech Mode, fill in your `ELEVEN_LABS_API_KEY` as well.
|
||||
|
||||
- Obtain your OpenAI API key from: [https://platform.openai.com/account/api-keys](https://platform.openai.com/account/api-keys).
|
||||
- Obtain your ElevenLabs API key from: [https://elevenlabs.io](https://elevenlabs.io/). You can view your xi-api-key using the "Profile" tab on the website.
|
||||
- If you want to use GPT on an Azure instance, set `USE_AZURE` to `True` and then:
|
||||
- Rename `azure.yaml.template` to `azure.yaml` and provide the relevant `azure_api_base`, `azure_api_version` and all of the deployment ids for the relevant models in the `azure_model_map` section:
|
||||
- `fast_llm_model_deployment_id` - your gpt-3.5-turbo or gpt-4 deployment id
|
||||
- `smart_llm_model_deployment_id` - your gpt-4 deployment id
|
||||
- `embedding_model_deployment_id` - your text-embedding-ada-002 v2 deployment id
|
||||
- Please specify all of these values as double quoted strings
|
||||
- details can be found here: [https://pypi.org/project/openai/](https://pypi.org/project/openai/) in the `Microsoft Azure Endpoints` section and here: [https://learn.microsoft.com/en-us/azure/cognitive-services/openai/tutorials/embeddings?tabs=command-line](https://learn.microsoft.com/en-us/azure/cognitive-services/openai/tutorials/embeddings?tabs=command-line) for the embedding model.
|
||||
|
||||
## 🔧 Usage
|
||||
|
||||
1. Run the `main.py` Python script in your terminal: *(Type this into your CMD window)*
|
||||
|
||||
2. After each of AUTO-GPT's actions, type "NEXT COMMAND" to authorise them to continue.
|
||||
3. To exit the program, type "exit" and press Enter.
|
||||
|
||||
### Logs
|
||||
|
||||
You will find activity and error logs in the folder `./output/logs`
|
||||
|
||||
To output debug logs:
|
||||
|
||||
```
|
||||
python scripts/main.py --debug
|
||||
```
|
||||
|
||||
## 🗣️ Speech Mode
|
||||
|
||||
Use this to use TTS for Auto-GPT
|
||||
|
||||
```
|
||||
python scripts/main.py --speak
|
||||
```
|
||||
|
||||
## 🔍 Google API Keys Configuration
|
||||
|
||||
This section is optional, use the official google api if you are having issues with error 429 when running a google search. To use the `google_official_search` command, you need to set up your Google API keys in your environment variables.
|
||||
|
||||
1. Go to the [Google Cloud Console](https://console.cloud.google.com/).
|
||||
2. If you don't already have an account, create one and log in.
|
||||
3. Create a new project by clicking on the "Select a Project" dropdown at the top of the page and clicking "New Project". Give it a name and click "Create".
|
||||
4. Go to the [APIs & Services Dashboard](https://console.cloud.google.com/apis/dashboard) and click "Enable APIs and Services". Search for "Custom Search API" and click on it, then click "Enable".
|
||||
5. Go to the [Credentials](https://console.cloud.google.com/apis/credentials) page and click "Create Credentials". Choose "API Key".
|
||||
6. Copy the API key and set it as an environment variable named `GOOGLE_API_KEY` on your machine. See setting up environment variables below.
|
||||
7. [Enable](https://console.developers.google.com/apis/api/customsearch.googleapis.com) the Custom Search API on your project. (Might need to wait few minutes to propagate)
|
||||
8. Go to the [Custom Search Engine](https://cse.google.com/cse/all) page and click "Add".
|
||||
9. Set up your search engine by following the prompts. You can choose to search the entire web or specific sites.
|
||||
10. Once you've created your search engine, click on "Control Panel" and then "Basics". Copy the "Search engine ID" and set it as an environment variable named `CUSTOM_SEARCH_ENGINE_ID` on your machine. See setting up environment variables below.
|
||||
|
||||
*Remember that your free daily custom search quota allows only up to 100 searches. To increase this limit, you need to assign a billing account to the project to profit from up to 10K daily searches.*
|
||||
|
||||
### Setting up environment variables
|
||||
|
||||
For Windows Users:
|
||||
|
||||
```
|
||||
setx GOOGLE_API_KEY "YOUR_GOOGLE_API_KEY"
|
||||
setx CUSTOM_SEARCH_ENGINE_ID "YOUR_CUSTOM_SEARCH_ENGINE_ID"
|
||||
|
||||
```
|
||||
|
||||
For macOS and Linux users:
|
||||
|
||||
```
|
||||
export GOOGLE_API_KEY="YOUR_GOOGLE_API_KEY"
|
||||
export CUSTOM_SEARCH_ENGINE_ID="YOUR_CUSTOM_SEARCH_ENGINE_ID"
|
||||
|
||||
```
|
||||
|
||||
## Redis Setup
|
||||
|
||||
Install docker desktop.
|
||||
|
||||
Run:
|
||||
|
||||
```
|
||||
docker run -d --name redis-stack-server -p 6379:6379 redis/redis-stack-server:latest
|
||||
```
|
||||
|
||||
See [https://hub.docker.com/r/redis/redis-stack-server](https://hub.docker.com/r/redis/redis-stack-server) for setting a password and additional configuration.
|
||||
|
||||
Set the following environment variables:
|
||||
|
||||
```
|
||||
MEMORY_BACKEND=redis
|
||||
REDIS_HOST=localhost
|
||||
REDIS_PORT=6379
|
||||
REDIS_PASSWORD=
|
||||
```
|
||||
|
||||
Note that this is not intended to be run facing the internet and is not secure, do not expose redis to the internet without a password or at all really.
|
||||
|
||||
You can optionally set
|
||||
|
||||
```
|
||||
WIPE_REDIS_ON_START=False
|
||||
```
|
||||
|
||||
To persist memory stored in Redis.
|
||||
|
||||
You can specify the memory index for redis using the following:
|
||||
|
||||
## 🌲 Pinecone API Key Setup
|
||||
|
||||
Pinecone enables the storage of vast amounts of vector-based memory, allowing for only relevant memories to be loaded for the agent at any given time.
|
||||
|
||||
1. Go to [pinecone](https://app.pinecone.io/) and make an account if you don't already have one.
|
||||
2. Choose the `Starter` plan to avoid being charged.
|
||||
3. Find your API key and region under the default project in the left sidebar.
|
||||
|
||||
### Setting up environment variables
|
||||
|
||||
Simply set them in the `.env` file.
|
||||
|
||||
Alternatively, you can set them from the command line (advanced):
|
||||
|
||||
For Windows Users:
|
||||
|
||||
```
|
||||
setx PINECONE_API_KEY "YOUR_PINECONE_API_KEY"
|
||||
setx PINECONE_ENV "Your pinecone region" # something like: us-east4-gcp
|
||||
|
||||
```
|
||||
|
||||
For macOS and Linux users:
|
||||
|
||||
```
|
||||
export PINECONE_API_KEY="YOUR_PINECONE_API_KEY"
|
||||
export PINECONE_ENV="Your pinecone region" # something like: us-east4-gcp
|
||||
|
||||
```
|
||||
|
||||
## Setting Your Cache Type
|
||||
|
||||
By default Auto-GPT is going to use LocalCache instead of redis or Pinecone.
|
||||
|
||||
To switch to either, change the `MEMORY_BACKEND` env variable to the value that you want:
|
||||
|
||||
`local` (default) uses a local JSON cache file `pinecone` uses the Pinecone.io account you configured in your ENV settings `redis` will use the redis cache that you configured
|
||||
|
||||
## View Memory Usage
|
||||
|
||||
1. View memory usage by using the `--debug` flag :)
|
||||
|
||||
## 💀 Continuous Mode ⚠️
|
||||
|
||||
Run the AI **without** user authorisation, 100% automated. Continuous mode is not recommended. It is potentially dangerous and may cause your AI to run forever or carry out actions you would not usually authorise. Use at your own risk.
|
||||
|
||||
1. Run the `main.py` Python script in your terminal:
|
||||
|
||||
```
|
||||
python scripts/main.py --continuous
|
||||
|
||||
```
|
||||
|
||||
2. To exit the program, press Ctrl + C
|
||||
|
||||
## GPT3.5 ONLY Mode
|
||||
|
||||
If you don't have access to the GPT4 api, this mode will allow you to use Auto-GPT!
|
||||
|
||||
```
|
||||
python scripts/main.py --gpt3only
|
||||
```
|
||||
|
||||
It is recommended to use a virtual machine for tasks that require high security measures to prevent any potential harm to the main computer's system and data.
|
||||
|
||||
## 🖼 Image Generation
|
||||
|
||||
By default, Auto-GPT uses DALL-e for image generation. To use Stable Diffusion, a [HuggingFace API Token](https://huggingface.co/settings/tokens) is required.
|
||||
|
||||
Once you have a token, set these variables in your `.env`:
|
||||
|
||||
```
|
||||
IMAGE_PROVIDER=sd
|
||||
HUGGINGFACE_API_TOKEN="YOUR_HUGGINGFACE_API_TOKEN"
|
||||
```
|
||||
|
||||
## ⚠️ Limitations
|
||||
|
||||
This experiment aims to showcase the potential of GPT-4 but comes with some limitations:
|
||||
|
||||
1. Not a polished application or product, just an experiment
|
||||
2. May not perform well in complex, real-world business scenarios. In fact, if it actually does, please share your results!
|
||||
3. Quite expensive to run, so set and monitor your API key limits with OpenAI!
|
||||
|
||||
## 🛡 Disclaimer
|
||||
|
||||
Disclaimer This project, Auto-GPT, is an experimental application and is provided "as-is" without any warranty, express or implied. By using this software, you agree to assume all risks associated with its use, including but not limited to data loss, system failure, or any other issues that may arise.
|
||||
|
||||
The developers and contributors of this project do not accept any responsibility or liability for any losses, damages, or other consequences that may occur as a result of using this software. You are solely responsible for any decisions and actions taken based on the information provided by Auto-GPT.
|
||||
|
||||
**Please note that the use of the GPT-4 language model can be expensive due to its token usage.** By utilizing this project, you acknowledge that you are responsible for monitoring and managing your own token usage and the associated costs. It is highly recommended to check your OpenAI API usage regularly and set up any necessary limits or alerts to prevent unexpected charges.
|
||||
|
||||
As an autonomous experiment, Auto-GPT may generate content or take actions that are not in line with real-world business practices or legal requirements. It is your responsibility to ensure that any actions or decisions made based on the output of this software comply with all applicable laws, regulations, and ethical standards. The developers and contributors of this project shall not be held responsible for any consequences arising from the use of this software.
|
||||
|
||||
By using Auto-GPT, you agree to indemnify, defend, and hold harmless the developers, contributors, and any affiliated parties from and against any and all claims, damages, losses, liabilities, costs, and expenses (including reasonable attorneys' fees) arising from your use of this software or your violation of these terms.
|
||||
|
||||
## 🐦 Connect with Us on Twitter
|
||||
|
||||
Stay up-to-date with the latest news, updates, and insights about Auto-GPT by following our Twitter accounts. Engage with the developer and the AI's own account for interesting discussions, project updates, and more.
|
||||
|
||||
- **Developer**: Follow [@siggravitas](https://twitter.com/siggravitas) for insights into the development process, project updates, and related topics from the creator of Entrepreneur-GPT.
|
||||
- **Entrepreneur-GPT**: Join the conversation with the AI itself by following [@En\_GPT](https://twitter.com/En_GPT). Share your experiences, discuss the AI's outputs, and engage with the growing community of users.
|
||||
|
||||
We look forward to connecting with you and hearing your thoughts, ideas, and experiences with Auto-GPT. Join us on Twitter and let's explore the future of AI together!
|
||||
|
||||
[](https://star-history.com/#Torantulino/auto-gpt&Date)
|
||||
|
||||
## Run tests
|
||||
|
||||
To run tests, run the following command:
|
||||
|
||||
```
|
||||
python -m unittest discover tests
|
||||
```
|
||||
|
||||
To run tests and see coverage, run the following command:
|
||||
|
||||
```
|
||||
coverage run -m unittest discover tests
|
||||
```
|
||||
|
||||
## Run linter
|
||||
|
||||
This project uses [flake8](https://flake8.pycqa.org/en/latest/) for linting. We currently use the following rules: `E303,W293,W291,W292,E305,E231,E302`. See the [flake8 rules](https://www.flake8rules.com/) for more information.
|
||||
|
||||
To run the linter, run the following command:
|
||||
|
||||
```
|
||||
flake8 scripts/ tests/
|
||||
|
||||
# Or, if you want to run flake8 with the same configuration as the CI:
|
||||
flake8 scripts/ tests/ --select E303,W293,W291,W292,E305,E231,E302
|
||||
```
|
||||
@@ -0,0 +1,167 @@
|
||||
---
|
||||
page-title: "Usage of matrix-bot-sdk | Matrix.org"
|
||||
url: https://matrix.org/docs/guides/usage-of-matrix-bot-sdk
|
||||
date: "2023-04-18 13:34:11"
|
||||
---
|
||||
This article concerns [matrix-bot-sdk](https://github.com/turt2live/matrix-bot-sdk), a TypeScript client SDK for Matrix. We'll build a simple "echo bot", meaning a bot which replies to messages with the text it has just read.
|
||||
|
||||
Note that although the SDK is written in TypeScript, we'll use JavaScript in our examples. If you'd prefer to use TypeScript, then do!
|
||||
|
||||
## [](https://matrix.org/docs/guides/usage-of-matrix-bot-sdk#setup)Setup
|
||||
|
||||
Let's make a new folder, and import our only npm dependency. The following examples are all meant to be run in a bash terminal.
|
||||
|
||||
```
|
||||
mkdir matrix-js-echo-bot
|
||||
cd matrix-js-echo-bot
|
||||
npm install matrix-bot-sdk
|
||||
```
|
||||
|
||||
Create a new file named "index.js", and let's get started.
|
||||
|
||||
## [](https://matrix.org/docs/guides/usage-of-matrix-bot-sdk#instantiation)Instantiation
|
||||
|
||||
In our js file, start by importing the minimum we'll need for this example:
|
||||
|
||||
```
|
||||
const sdk = require("matrix-bot-sdk");
|
||||
const MatrixClient = sdk.MatrixClient;
|
||||
const SimpleFsStorageProvider = sdk.SimpleFsStorageProvider;
|
||||
const AutojoinRoomsMixin = sdk.AutojoinRoomsMixin;
|
||||
```
|
||||
|
||||
Create a new account for your bot on a homeserver, then get the `access_token`. The simplest way to do this is using Element, [take a look at these instructions](https://t2bot.io/docs/access_tokens/). Set some variables to store the homeserver and `access_token`. This is all the authentication you need!
|
||||
|
||||
```
|
||||
const homeserverUrl = "https://matrix.org"; // make sure to update this with your url
|
||||
const accessToken = "YourSecretAccessToken";
|
||||
```
|
||||
|
||||
Now we'll configure a storage provider - matrix-bot-sdk provides the `SimpleFsStorageProvider`, which is ideal for most cases:
|
||||
|
||||
```
|
||||
const storage = new SimpleFsStorageProvider("bot.json");
|
||||
```
|
||||
|
||||
When the bot starts, the SDK will create a a new file called "bot.json" to store the data it needs.
|
||||
|
||||
Finally we're ready to start the client! As you'd expect, we'll use the variables we've already specified.
|
||||
|
||||
```
|
||||
const client = new MatrixClient(homeserverUrl, accessToken, storage);
|
||||
```
|
||||
|
||||
There is one more thing we need to do. We'll include a mixin which instructs the bot to auto-accept any room invite it receives. This makes testing much more convenient.
|
||||
|
||||
```
|
||||
AutojoinRoomsMixin.setupOnClient(client);
|
||||
```
|
||||
|
||||
Finally, let's start the Client:
|
||||
|
||||
```
|
||||
client.start().then(() => console.log("Client started!"));
|
||||
```
|
||||
|
||||
If you're keeping up, your code should look something like:
|
||||
|
||||
```
|
||||
import {
|
||||
MatrixClient,
|
||||
SimpleFsStorageProvider,
|
||||
AutojoinRoomsMixin
|
||||
} from "matrix-bot-sdk";
|
||||
|
||||
const homeserverUrl = "https://matrix.org"; // make sure to update this with your url
|
||||
const accessToken = "YourSecretAccessToken";
|
||||
const storage = new SimpleFsStorageProvider("bot.json");
|
||||
|
||||
const client = new MatrixClient(homeserverUrl, accessToken, storage);
|
||||
AutojoinRoomsMixin.setupOnClient(client);
|
||||
|
||||
client.start().then(() => console.log("Client started!"));
|
||||
```
|
||||
|
||||
Let's run it:
|
||||
|
||||
This should now join and sit idle, but join any room you invite the bot to.
|
||||
|
||||
## [](https://matrix.org/docs/guides/usage-of-matrix-bot-sdk#sync-loop)/sync loop
|
||||
|
||||
Right now, while it's just listening to invites and nothing else, what is the bot actually doing? It's calling the `/sync` endpoint in a loop. Calling this endpoint returns all new events since some previous point.
|
||||
|
||||
Leave the script running and open `bot.json`, which is the file we specified for storage. This file contains a field `syncToken`, which is being occasionally updated - the SDK uses this field to give a token to the homeserver, which uses it to know which events to send back.
|
||||
|
||||
## [](https://matrix.org/docs/guides/usage-of-matrix-bot-sdk#receiving-and-sending-events)Receiving and Sending events
|
||||
|
||||
In order to echo messages, our bot must first be able to read them. The `client.on()` method of our MatrixClient takes two arguments: one for the event type, one for a callback to handle the event:
|
||||
|
||||
```
|
||||
client.on("room.message", (roomId, event) => {
|
||||
if (! event["content"]) return;
|
||||
const sender = event["sender"];
|
||||
const body = event["content"]["body"];
|
||||
console.log(`${roomId}: ${sender} says '${body}`);
|
||||
});
|
||||
```
|
||||
|
||||
In this way we can inspect an the contents of an event and render them. We choose to exit early in the case that `event["content"]` is empty because this will usually mean the message was redacted.
|
||||
|
||||
To send a message, we use the `client.sendMessage()` method. This takes two arguments: the roomId, and a JSON object containing the contents of the message to send, for example:
|
||||
|
||||
```
|
||||
client.sendMessage(roomId, {
|
||||
"msgtype": "m.text",
|
||||
"body": "This is message text.",
|
||||
});
|
||||
```
|
||||
|
||||
Note, it's also possible to use `client.sendText()` to achieve the same result, as in
|
||||
|
||||
```
|
||||
client.sendText(roomId, "This is message text.")
|
||||
```
|
||||
|
||||
The reason for showing `client.sendMessage()` is to make it clear that the message format is [just the same as you'd find in the spec](https://matrix.org/docs/spec/client_server/latest#put-matrix-client-r0-rooms-roomid-send-eventtype-txnid).
|
||||
|
||||
## [](https://matrix.org/docs/guides/usage-of-matrix-bot-sdk#implementing-echobot-functionality)Implementing echobot functionality
|
||||
|
||||
To work, an echobot needs only to listen for incoming messages, read the message text, and use it to reply. Let's demonstrate that now.
|
||||
|
||||
- Read the message as in the example above
|
||||
- Inspect the body text, if it starts with "!echo", send back the remaining text
|
||||
- Strip out the "!echo" tag
|
||||
- Send a message containing the result
|
||||
|
||||
```
|
||||
client.on("room.message", (roomId, event) => {
|
||||
if (! event["content"]) return;
|
||||
const sender = event["sender"];
|
||||
const body = event["content"]["body"];
|
||||
console.log(`${roomId}: ${sender} says '${body}`);
|
||||
|
||||
if (body.startsWith("!echo")) {
|
||||
const replyText = body.substring("!echo".length).trim();
|
||||
client.sendMessage(roomId, {
|
||||
"msgtype": "m.notice",
|
||||
"body": replyText,
|
||||
});
|
||||
}
|
||||
});
|
||||
```
|
||||
|
||||
## [](https://matrix.org/docs/guides/usage-of-matrix-bot-sdk#conclusion)Conclusion
|
||||
|
||||
It's extremely simple to listen to messages with [matrix-bot-sdk](https://github.com/turt2live/matrix-bot-sdk) create an echobot! There are many more features, you can see the MatrixClient class is [very well documented](https://github.com/turt2live/matrix-bot-sdk/blob/master/src/MatrixClient.ts). Next in this series, we'll explore Rich Replies, and take a look at the kick and ban functions for room administration.
|
||||
|
||||
## [](https://matrix.org/docs/guides/usage-of-matrix-bot-sdk#ps-use-typescript)PS, use TypeScript
|
||||
|
||||
This SDK uses TypeScript, which provides a lot of benefits. In this example, we used JavaScript, but it's just as easy to use TypeScript and maybe preferable, since it is the language [matrix-bot-sdk](https://github.com/turt2live/matrix-bot-sdk) is written in.
|
||||
|
||||
First let's install `tsc`, which compiles from TypeScript to JavaScript:
|
||||
|
||||
Now, start tsc in watch-mode (`-w`), and leave it to compile our code:
|
||||
|
||||
Now, whenever we create a new TypeScript (`.ts`) file, it will be automatically watched and compiled to JavaScript.
|
||||
|
||||
When you have your .js file(s), you can run them with `node <filename>` as normal.
|
||||
+410
@@ -0,0 +1,410 @@
|
||||
---
|
||||
page-title: "Using Let's Encrypt for internal servers - Philipp's Tech Blog"
|
||||
url: https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/
|
||||
date: "2023-04-06 08:52:23"
|
||||
---
|
||||
|
||||
|
||||
[Let’s Encrypt](https://letsencrypt.org/) is a revolutionary new certificate authority that provides free certificates in a completely automated process. These certificates are issued via the [ACME protocol](https://ietf-wg-acme.github.io/acme/draft-ietf-acme-acme.html). Over the last 2 years or so, the Internet has widely adopted Let’s Encrypt — over 50% of the web’s SSL/TLS certificates are now issued by Let’s Encrypt.
|
||||
|
||||
But while there are many tools to automatically renew certificates for publicly available webservers ([certbot](https://certbot.eff.org/), [simp\_le](https://github.com/kuba/simp_le), [I wrote about how to do that 3 years back](https://blog.heckel.xyz/2015/12/04/lets-encrypt-5-min-guide-to-set-up-cronjob-based-certificate-renewal/)), it’s hard to find any useful information about how to issue certificates for internal non Internet facing servers and/or devices with Let’s Encrypt.
|
||||
|
||||
This blog posts describes **how to issue Let’s Encrypt certificates for internal servers**. At my work, we issued a certificate for each of our 65,000 90,000+ BCDR appliances using this exact mechanism.
|
||||
|
||||
---
|
||||
|
||||
**Content**
|
||||
|
||||
1. [1\. How does it work?](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#How-does-it-work)
|
||||
2. [2\. Example: An internal server 10.1.1.4, aka. xi8qz.example.com](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#Example-An-internal-server-10-1-1-4-aka-xi8qz-example-com)
|
||||
1. [2.1. Prerequisites: Assigning a domain for each machine (steps 1-3)](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#Prerequisites-Assigning-a-domain-for-each-machine-steps-1-3)
|
||||
2. [2.2. Requesting a certificate (steps 4-14)](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#Requesting-a-certificate-steps-4-14)
|
||||
3. [3\. Deployment considerations: Let’s Encrypt rate limits](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#Deployment-considerations-Let-s-Encrypt-rate-limits)
|
||||
|
||||
---
|
||||
|
||||
**Hello Hacker News,** first time on the HN front page! I feel honored, yeyy! I responded to all of the concerns in the [comments section](https://news.ycombinator.com/item?id=19353294).
|
||||
|
||||
**If you’re looking for an implementation of this idea,** you may find [localtls](https://github.com/Corollarium/localtls) interesting. I have not tested it myself, but it seems to do similar things to what I am describing here.
|
||||
|
||||
---
|
||||
|
||||
### 1\. How does it work? [¶](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#How-does-it-work)
|
||||
|
||||
To issue a certificate through Let’s Encrypt, you must prove that you either own the website you want to issue the certificate for, or that you own the domain it runs on. Typically, automated tools like [certbot](https://certbot.eff.org/) use the [HTTP challenge](https://ietf-wg-acme.github.io/acme/draft-ietf-acme-acme.html#rfc.section.8.3) to prove site ownership using the .well-known directory. While this works beautifully if the site is Internet-facing (and Let’s Encrypt can verify the HTTP challenge files via a simple HTTP request), it doesn’t work if your server runs on 10.1.1.4 or any other internal address.
|
||||
|
||||
The [DNS challenge](https://ietf-wg-acme.github.io/acme/draft-ietf-acme-acme.html#rfc.section.8.4) solves this problem by letting you prove domain ownership through the DNS TXT record \_acme-challenge.example.com. Let’s Encrypt will verify that the record matches what it expects and issue your certificate if it all adds up.
|
||||
|
||||
So really the magic ingredients to issuing certificates for internal non Internet facing machines are:
|
||||
|
||||
- A dedicated DNS zone for all your internal devices, e.g. xi8qz.example.com, and a dynamic DNS server to manage this zone (here: example.com)
|
||||
- An ACME client capable of using the Let’s Encrypt’s DNS challenge to prove domain ownership
|
||||
|
||||
Advertisement
|
||||
|
||||
### 2\. Example: An internal server 10.1.1.4, aka. xi8qz.example.com [¶](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#Example-An-internal-server-10-1-1-4-aka-xi8qz-example-com)
|
||||
|
||||
The following diagram shows how we have implemented our Let’s Encrypt integration for our backup appliances. Each appliance (read: internal server) is behind a NAT and carries its own local IP address.
|
||||
|
||||
The general approach is simple: The appliance regularly reaches out to our control server to ensure that it can be reached via its own subdomain. If its local IP address changes, it triggers an update of its own subdomain. In addition, it checks regularly if the certificate is still valid, and requests a renewal if it’s outdated.
|
||||
|
||||
Here’s a bit more detail to this process:
|
||||
|
||||
|
||||
|
||||
For this example, let’s assume we’re trying to issue a certificate for an appliance with the identifier xi8qz and the local IP address 10.1.1.4. From the perspective of this appliance, there are two requests to be made:
|
||||
|
||||
- **Steps 1-3:** First, it needs to set/update its own DNS domain (here: xi8qz.example.com). This domain will later be used as a common name (CN) in the certificate. On top of that, it needs to make sure that this record is updated every time the server’s IP address changes.
|
||||
- **Steps 4-14:** It needs to regularly check if the local certificate needs to be renewed and request a renewal if it’s time. Obviously, if there is no certificate it needs to be “renewed”.
|
||||
|
||||
Let’s now examine these steps in greater detail.
|
||||
|
||||
#### 2.1. Prerequisites: Assigning a domain for each machine (steps 1-3) [¶](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#Prerequisites-Assigning-a-domain-for-each-machine-steps-1-3)
|
||||
|
||||
As mentioned above, we need to give each appliance a proper domain name in order to be able to prove ownership to Let’s Encrypt, so we need to buy a domain (here: example.com) and delegate its NS records to our DDNS server:
|
||||
|
||||
$ dig +short NS example.com
|
||||
|
||||
ddns1.mycompany.com.
|
||||
|
||||
On top of that, we need the ability to dynamically add and remove records from it (via an API of some sort). I’ve previously written about how to [spin up your own DDNS server](https://blog.heckel.xyz/2016/12/31/your-own-dynamic-dns-server-powerdns-mysql/), if you are interested.
|
||||
|
||||
Once that’s all set up, we need to make sure that the machine’s A record is updated whenever its IP address changes. For our internal machine, let’s assign xi8qz.example.com as its domain. If everything’s working properly, you should be able to resolve this domain to its IP address using a normal DNS query:
|
||||
|
||||
$ dig +short xi8qz.example.com
|
||||
|
||||
10.1.1.4
|
||||
|
||||
#### 2.2. Requesting a certificate (steps 4-14) [¶](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#Requesting-a-certificate-steps-4-14)
|
||||
|
||||
Assuming you now control the DNS zone for example.com completely and you can quickly edit it dynamically, you’re all set for actually issuing certificates for your local device domain via Let’s Encrypt.
|
||||
|
||||
For our example appliance, it will regularly check if the existing certificate is still valid (step 4). If there is no certificate or the existing one is about to expire, the device will generate a keypair and a [certificate signing request (CSR)](https://en.wikipedia.org/wiki/Certificate_signing_request) using its assigned hostname (here: xi8qz.example.com) as a CN, and it’ll send that CSR to the control server (step 5).
|
||||
|
||||
After authorizing the request (an important step not shown in the diagram!), the control server requests a DNS challenge for the given domain from the ACME API via the [Pre-Authorization](https://ietf-wg-acme.github.io/acme/draft-ietf-acme-acme.html#rfc.section.7.4.1)/new-authz API call (step 6). The ACME API responds with a DNS challenge (step 7). If all goes well, this looks something like this:
|
||||
|
||||
1
|
||||
|
||||
2
|
||||
|
||||
3
|
||||
|
||||
4
|
||||
|
||||
5
|
||||
|
||||
6
|
||||
|
||||
7
|
||||
|
||||
8
|
||||
|
||||
9
|
||||
|
||||
10
|
||||
|
||||
11
|
||||
|
||||
12
|
||||
|
||||
13
|
||||
|
||||
14
|
||||
|
||||
15
|
||||
|
||||
16
|
||||
|
||||
17
|
||||
|
||||
18
|
||||
|
||||
{
|
||||
|
||||
"identifier": {
|
||||
|
||||
"type": "dns",
|
||||
|
||||
"value": "xi8qz.example.com"
|
||||
|
||||
},
|
||||
|
||||
"status": "pending",
|
||||
|
||||
"expires": "2018-04-15T21:26:29Z",
|
||||
|
||||
"challenges": \[
|
||||
|
||||
{
|
||||
|
||||
"type": "dns-01",
|
||||
|
||||
"status": "pending",
|
||||
|
||||
"uri": "https://acme-staging.api.letsencrypt.org/acme/challenge/VtjihR4X8nLAj4MDwI...",
|
||||
|
||||
"token": "aLptEKAeUOajkiGrx-kkbjUX4b1MC..."
|
||||
|
||||
},
|
||||
|
||||
// ...
|
||||
|
||||
\],
|
||||
|
||||
// ...
|
||||
|
||||
}
|
||||
|
||||
Using this response, the control server must set a DNS TXT record at \_acme-challenge.xi8qz.example.com (step 8) and notify the ACME API that the challenge response has been placed (step 9).
|
||||
|
||||
Once the challenge response has been verified by Let’s Encrypt (step 10-11), the certificate can finally be requested using the CSR (step 12-13).
|
||||
|
||||
After Let’s Encrypt responds with a certificate, you’ll see something like this on the wire:
|
||||
|
||||
\--\--\-BEGIN CERTIFICATE\--\--\-
|
||||
|
||||
MIIGEjCCBPqgAwIBAgISAyk2izMz7OXSqHeZhg+rUR5uMA0GCSqGSIb3DQEBCwUA
|
||||
|
||||
MEoxCzAJBgNVBAYTAlVTMRYwFAYDVQQKEw1MZXQncyBFbmNyeXB0MSMwIQYDVQQD
|
||||
|
||||
...
|
||||
|
||||
If decoded with openssl, we can see that’s it’s the real deal:
|
||||
|
||||
1
|
||||
|
||||
2
|
||||
|
||||
3
|
||||
|
||||
4
|
||||
|
||||
5
|
||||
|
||||
6
|
||||
|
||||
7
|
||||
|
||||
8
|
||||
|
||||
9
|
||||
|
||||
10
|
||||
|
||||
11
|
||||
|
||||
12
|
||||
|
||||
13
|
||||
|
||||
14
|
||||
|
||||
15
|
||||
|
||||
16
|
||||
|
||||
17
|
||||
|
||||
18
|
||||
|
||||
19
|
||||
|
||||
$ openssl x509 \-in www.crt \-text \-noout
|
||||
|
||||
Certificate:
|
||||
|
||||
Data:
|
||||
|
||||
Version: 3 (0x2)
|
||||
|
||||
Serial Number:
|
||||
|
||||
03:29:36:8b:33:33:ec:e5:d2:a8:77:99:86:0f:ab:51:1e:6e
|
||||
|
||||
Signature Algorithm: sha256WithRSAEncryption
|
||||
|
||||
Issuer: C\=US, O\=Let's Encrypt, CN=Let's Encrypt Authority X3
|
||||
|
||||
Validity
|
||||
|
||||
Not Before: Jul 18 23:37:35 2018 GMT
|
||||
|
||||
Not After : Oct 16 23:37:35 2018 GMT
|
||||
|
||||
Subject: CN\=xi8qz.example.com
|
||||
|
||||
Subject Public Key Info:
|
||||
|
||||
Public Key Algorithm: rsaEncryption
|
||||
|
||||
Public\-Key: (2048 bit)
|
||||
|
||||
Modulus:
|
||||
|
||||
00:be:69:df:28:04:9c:2b:e9:94:72:c3:de:a6:fd:
|
||||
|
||||
a4:38:93:be:43:a7:81:8b:dc:9a:be:19:0d:c0:d1:
|
||||
|
||||
...
|
||||
|
||||
This certificate is then returned to the machine (step 14). After the webserver of the appliance/server has been restarted, it’s web interface can be accessed via HTTPS in the browser or on the command line:
|
||||
|
||||
1
|
||||
|
||||
2
|
||||
|
||||
3
|
||||
|
||||
4
|
||||
|
||||
5
|
||||
|
||||
6
|
||||
|
||||
7
|
||||
|
||||
8
|
||||
|
||||
9
|
||||
|
||||
10
|
||||
|
||||
11
|
||||
|
||||
12
|
||||
|
||||
13
|
||||
|
||||
14
|
||||
|
||||
15
|
||||
|
||||
16
|
||||
|
||||
17
|
||||
|
||||
18
|
||||
|
||||
19
|
||||
|
||||
20
|
||||
|
||||
21
|
||||
|
||||
22
|
||||
|
||||
23
|
||||
|
||||
24
|
||||
|
||||
25
|
||||
|
||||
26
|
||||
|
||||
27
|
||||
|
||||
28
|
||||
|
||||
29
|
||||
|
||||
30
|
||||
|
||||
31
|
||||
|
||||
32
|
||||
|
||||
33
|
||||
|
||||
34
|
||||
|
||||
35
|
||||
|
||||
36
|
||||
|
||||
$ curl \-v https://xi8qz.example.com/login
|
||||
|
||||
\* Trying 10.1.1.4...
|
||||
|
||||
\* TCP\_NODELAY set
|
||||
|
||||
\* Connected to xi8qz.example.com (10.1.1.4) port 443 (#0)
|
||||
|
||||
\* ALPN, offering h2
|
||||
|
||||
\* ALPN, offering http/1.1
|
||||
|
||||
\* successfully set certificate verify locations:
|
||||
|
||||
\* CAfile: /etc/ssl/certs/ca\-certificates.crt
|
||||
|
||||
CApath: /etc/ssl/certs
|
||||
|
||||
\* TLSv1.2 (OUT), TLS handshake, Client hello (1):
|
||||
|
||||
\* TLSv1.2 (IN), TLS handshake, Server hello (2):
|
||||
|
||||
\* TLSv1.2 (IN), TLS handshake, Certificate (11):
|
||||
|
||||
\* TLSv1.2 (IN), TLS handshake, Server key exchange (12):
|
||||
|
||||
\* TLSv1.2 (IN), TLS handshake, Server finished (14):
|
||||
|
||||
\* TLSv1.2 (OUT), TLS handshake, Client key exchange (16):
|
||||
|
||||
\* TLSv1.2 (OUT), TLS change cipher, Client hello (1):
|
||||
|
||||
\* TLSv1.2 (OUT), TLS handshake, Finished (20):
|
||||
|
||||
\* TLSv1.2 (IN), TLS handshake, Finished (20):
|
||||
|
||||
\* SSL connection using TLSv1.2 / ECDHE\-RSA\-AES256\-GCM\-SHA384
|
||||
|
||||
\* ALPN, server accepted to use http/1.1
|
||||
|
||||
\* Server certificate:
|
||||
|
||||
\* subject: CN\=xi8qz.example.com
|
||||
|
||||
\* start date: Jul 18 23:37:35 2018 GMT
|
||||
|
||||
\* expire date: Oct 16 23:37:35 2018 GMT
|
||||
|
||||
\* subjectAltName: host "xi8qz.example.com" matched cert's "xi8qz.example.com"
|
||||
|
||||
\* issuer: C=US; O=Let's Encrypt; CN\=Let's Encrypt Authority X3
|
||||
|
||||
\* SSL certificate verify ok.
|
||||
|
||||
\> GET /login HTTP/1.1
|
||||
|
||||
\> Host: xi8qz.example.com
|
||||
|
||||
\> User\-Agent: curl/7.58.0
|
||||
|
||||
\> Accept: \*/\*
|
||||
|
||||
\>
|
||||
|
||||
< HTTP/1.1 200 OK
|
||||
|
||||
< Date: Sun, 05 Aug 2018 17:38:49 GMT
|
||||
|
||||
< Server: Apache/2.4.18 (Ubuntu)
|
||||
|
||||
...
|
||||
|
||||
### 3\. Deployment considerations: Let’s Encrypt rate limits [¶](https://blog.heckel.io/2018/08/05/issuing-lets-encrypt-certificates-for-65000-internal-servers/#Deployment-considerations-Let-s-Encrypt-rate-limits)
|
||||
|
||||
It’s important to note that if you are considering implementing this mechanism for a large number of servers that you use the Let’s Encrypt [staging environments](https://letsencrypt.org/docs/staging-environment/) for testing and, more importantly, that you consider their [rate limit restrictions](https://letsencrypt.org/docs/rate-limits/).
|
||||
|
||||
By default, Let’s Encrypt only allows you to issue 20 certificates per week for the same domain or the same account. To increase this number, you have to either [request a higher rate limit](https://goo.gl/forms/plqRgFVnZbdGhE9n1) or get your domain added to the [public suffix list](https://publicsuffix.org/) (note: adding your domain here has other implications!).
|
||||
|
||||
Due to these rate limits, it is vital that you spread out the initial deployment enough to stay under the rate limit, and that you leave enough room for future servers to be added. Also consider renewals in the initial rollout plan.
|
||||
|
||||
### 4\. Summary
|
||||
|
||||
As you can see it’s not really rocket science.
|
||||
|
||||
We first assigned each appliance (aka. internal server) a public domain name using our own dynamic DNS server and a dedicated DNS zone. Using the server’s assigned domain (here: xi8qz.example.com), we then used Let’s Encrypt’s free certificate offering and their DNS challenge to issue a certificate for that server.
|
||||
|
||||
By doing that for all internal servers, we can provide secure communication in our internal IT infrastructure without having to deploy a custom CA cert or having to pay for certificates.
|
||||
@@ -0,0 +1,208 @@
|
||||
---
|
||||
page-title: "What is Prompt Engineering? | prmpts.AI"
|
||||
url: https://prmpts.ai/blog/what-is-prompt-engineering
|
||||
date: "2023-04-23 12:41:07"
|
||||
---
|
||||
|
||||
> What is Prompt Engineering?
|
||||
|
||||
---
|
||||
|
||||
Blog
|
||||
|
||||
What is Prompt Engineering?
|
||||
|
||||
2023-01-24 ·
|
||||
|
||||
8 minute read
|
||||
|
||||
Large language models like GPT-3 have spawned a new emerging field called Prompt Engineering. People are coming up with clever techniques to prompt these models to perform different tasks, such as:
|
||||
|
||||
- TL;DR summarization
|
||||
- Fix grammar/spelling errors
|
||||
- Explain a concept to a 5 year old
|
||||
- Generate code using natural language
|
||||
- Explain what a piece of code does
|
||||
- Generate stories
|
||||
- Q&A
|
||||
|
||||
These are just a couple of examples among millions of possible use cases. The exciting thing about Prompt Engineering is that the possibilities are endless.
|
||||
|
||||
## [](https://prmpts.ai/blog/what-is-prompt-engineering#so-what-is-prompt-engineering-exactly)So what is Prompt Engineering exactly?
|
||||
|
||||
Prompt Engineering is the practice of producing robust prompts for generative language models that can withstand a number of real world challenges:
|
||||
|
||||
- How do we craft a prompt to produce a specific result?
|
||||
- How do we test our prompts to know that they consistently produce the right results?
|
||||
- How do we trust the language model not to say something incorrect/inappropriate?
|
||||
- How do we prevent prompt injection?
|
||||
- How do we pass in a custom data set or knowledge base?
|
||||
- What do we do if our prompt doesn't fit within the model's token limits?
|
||||
- How do we estimate cost per prompt when inputs are unknown?
|
||||
- How do we compare competing language models as more become available?
|
||||
|
||||
As a Prompt Engineer, your job is to take the general capabilities of large language models and narrow them to a specific use case. You are responsible for addressing the above challenges and following best practices to accommodate them.
|
||||
|
||||
In this post we will explore the anatomy of a prompt, break down an example prompt, discuss best practices when designing prompts, and answer some common questions about Prompt Engineering.
|
||||
|
||||
## [](https://prmpts.ai/blog/what-is-prompt-engineering#anatomy-of-a-prompt)Anatomy of a prompt
|
||||
|
||||
Prompts are fundamentally made of 3 parts:
|
||||
|
||||
- **Static template:** This is the text template that structures the prompt's context, task, and input placeholders. This part of the prompt doesn't change between executions.
|
||||
- **Dynamic inputs:** This is dynamic data injected into the prompt based on user input. This could come directly from the user, such as a freeform text input or schema controlled input. It could also contain other injected data, such as externally fetched content. The location of these inputs are set using placeholders in the static template and will vary for every prompt.
|
||||
- **Model parameters:** This is where you define which language model you are using and any additional parameters for that model (eg. temperature).
|
||||
|
||||
## [](https://prmpts.ai/blog/what-is-prompt-engineering#example-fruit--color-hex)Example: Fruit → Color Hex
|
||||
|
||||
Let's look at one of my favourite examples: **Fruit → Color Hex**.
|
||||
|
||||
#### Prompt
|
||||
|
||||
Given the following fruit, output the closest color hex value that matches the color of that fruit. Fruit:
|
||||
|
||||
fruit
|
||||
|
||||
Color hex string:
|
||||
|
||||
completion
|
||||
|
||||
Tokens: 31
|
||||
|
||||
#### Inputs
|
||||
|
||||
#### Preview
|
||||
|
||||
Given the following fruit, output the closest color hex value that matches the color of that fruit. Fruit: Banana Color hex string:
|
||||
|
||||
completion
|
||||
|
||||
Tokens: 34
|
||||
|
||||
You'll notice the prompt has 3 sections:
|
||||
|
||||
1. **The prompt template:** This top section is the meat and potatoes of the prompt. It contains the core instructions and structure for the prompt. If you click on it, you'll see how the `fruit` input placeholder was created.
|
||||
2. **Inputs and preview:** For every input placeholder in the template, an input is created below. In this example, the `fruit` input is a simple free-form text box. Next to the inputs is a text preview to help you visualize what the final prompt will look like before its sent.
|
||||
3. **Model parameters:** At the bottom you choose which language model you want to use for this prompt. As more language models are released (from multiple organizations), you can experiment with them here.
|
||||
|
||||
The goal of this specific prompt is to produce a color hex value that best matches the color of the fruit provided.
|
||||
|
||||
Notice how we designed our prompt template. You can logically break it down into multiple parts: a context, task, label, and placeholder. Let's identify each one:
|
||||
|
||||
- **Context:**
|
||||
|
||||
```
|
||||
Given the following fruit,
|
||||
```
|
||||
|
||||
- **Task:**
|
||||
|
||||
```
|
||||
output the closest color hex value that matches the color of that fruit.
|
||||
```
|
||||
|
||||
- **Placeholder with label:**
|
||||
|
||||
```
|
||||
Fruit:
|
||||
{{ fruit }}
|
||||
```
|
||||
|
||||
- **Completion label:**
|
||||
|
||||
```
|
||||
Color hex string:
|
||||
```
|
||||
|
||||
|
||||
Why did we break up the prompt this way? Let's explore this in the next section about tips for effective prompts.
|
||||
|
||||
## [](https://prmpts.ai/blog/what-is-prompt-engineering#tips-for-effective-prompts)Tips for effective prompts
|
||||
|
||||
The structure of an effective prompt varies depending on your goals. But as a general rule of thumb, the following components are recommended:
|
||||
|
||||
1. **Identity:** Give the language model an identity.
|
||||
|
||||
```
|
||||
You are a question-answer bot for a luxury watch website.
|
||||
```
|
||||
|
||||
The goal with identity is to prime the language model with context that will reinforce the task you will ask to it do.
|
||||
|
||||
2. **Context:** Give context when applicable. For example, a luxury watch bot will need to know as much information as possible about the product in order to answer questions about it. We must inject this information into the prompt to give it content to work with.
|
||||
|
||||
```
|
||||
Given the following information about the product:
|
||||
{{ productInformation }}
|
||||
```
|
||||
|
||||
3. **Task:** Explain the model's job.
|
||||
|
||||
```
|
||||
Answer the following question from a customer about the above watch product.
|
||||
```
|
||||
|
||||
4. **Conditions:** Prevent the model from hallucinating (making up answers) by adding a condition to the task.
|
||||
|
||||
```
|
||||
If the answer is not provided above or you are unsure, reply with "Sorry, I don't know."
|
||||
```
|
||||
|
||||
5. **Labels:** Labels help set expectations and structure for the model. Without labels, models will sometimes try to add on to the task itself instead of performing the task. In our example, it would be wise to label our question and answer:
|
||||
|
||||
```
|
||||
Question: """
|
||||
{{ question }}
|
||||
"""
|
||||
|
||||
Answer:
|
||||
```
|
||||
|
||||
Notice that we also wrap our question input in triple quotes. This helps make the input explicit for the model. It also helps mitigate against prompt injection.
|
||||
|
||||
6. **User input:** As you can see above, we needed a place to inject user input. Most prompt tools will provide a templating language to allow you to set placeholders within your prompt:
|
||||
|
||||
```
|
||||
{{ question }}
|
||||
```
|
||||
|
||||
|
||||
Keep in mind that any of the above components have the ability to be dynamically injected as required. For example, context is a prime candidate for dynamic injection since this information may be constantly changing and unknown at build time. Likely you would retrieve context from a database, knowledge base, or external API. You can use embeddings to determine which content is most relevant when injecting.
|
||||
|
||||
Here's the final result:
|
||||
|
||||
#### Prompt
|
||||
|
||||
You are a question-answer bot for a luxury watch website. Given the following information about the product:
|
||||
|
||||
productInformation
|
||||
|
||||
Answer the following question from a customer about the above watch product. If the answer is not provided above or you are unsure, reply with "Sorry, I don't know." Question: """
|
||||
|
||||
question
|
||||
|
||||
""" Answer:
|
||||
|
||||
completion
|
||||
|
||||
Tokens: 71
|
||||
|
||||
#### Inputs
|
||||
|
||||
#### Preview
|
||||
|
||||
You are a question-answer bot for a luxury watch website. Given the following information about the product: \- Stainless steel - Designed for men and women, but not children - $500 - $5000 range - Gold and rose gold material accent options - Watches are in analog - No digital watches Answer the following question from a customer about the above watch product. If the answer is not provided above or you are unsure, reply with "Sorry, I don't know." Question: """ What are they made of? """ Answer:
|
||||
|
||||
completion
|
||||
|
||||
Tokens: 121
|
||||
|
||||
## [](https://prmpts.ai/blog/what-is-prompt-engineering#is-prompt-engineering-the-same-as-fine-tuning)Is Prompt Engineering the same as fine-tuning?
|
||||
|
||||
Not exactly. Fine-tuning is the process of re-training the language model itself with custom training data. Fine-tuning is just one of many tools in a Prompt Engineer’s tool belt to produce the desired outcome.
|
||||
|
||||
Fine-tuning is not always the answer. You will often pay a premium to fine-tune a model, both during the training process and for every future completion request after that. You may be surprised how far you can get using other Prompt Engineering techniques like context injection + embeddings.
|
||||
|
||||
## [](https://prmpts.ai/blog/what-is-prompt-engineering#what-is-prmptsai)What is [prmpts.AI](https://prmpts.ai/)?
|
||||
|
||||
[prmpts.AI](http://prmpts.ai/) is a prompt engineering playground to test and share robust prompts with others. Instead of proprietizing our discoveries, let’s keep this technology open and explore it together.
|
||||
+139
@@ -0,0 +1,139 @@
|
||||
---
|
||||
page-title: "[Pdns-users] TCP Connection Thread died because of STL error: Reading data: Connection reset by peer"
|
||||
url: https://mailman.powerdns.com/pipermail/pdns-users/2010-May/018731.html
|
||||
date: "2023-04-19 12:18:15"
|
||||
---
|
||||
**David J Craigon** [david at craigon.co.uk](mailto:pdns-users%40mailman.powerdns.com?Subject=Re%3A%20%5BPdns-users%5D%20TCP%20Connection%20Thread%20died%20because%20of%20STL%20error%3A%0A%09Reading%20data%3A%20Connection%20reset%20by%20peer&In-Reply-To=%3CAANLkTilZB2deCtEBractNCNUomBCPEol3VrOE-ZBZoV4%40mail.gmail.com%3E "[Pdns-users] TCP Connection Thread died because of STL error: Reading data: Connection reset by peer")
|
||||
*Wed May 26 13:29:25 UTC 2010*
|
||||
|
||||
- Previous message: [\[Pdns-users\] Power DNS 2.9.22 compile error while running 'make' command](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/018736.html)
|
||||
- Next message: [\[Pdns-users\] TCP Connection Thread died because of STL error: Reading data: Connection reset by peer](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/018740.html)
|
||||
- **Messages sorted by:** [\[ date \]](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/date.html#18731) [\[ thread \]](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/thread.html#18731) [\[ subject \]](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/subject.html#18731) [\[ author \]](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/author.html#18731)
|
||||
|
||||
---
|
||||
|
||||
I've got to the bottom of it, sort of.
|
||||
|
||||
Firstly, only dig seems to cause this problem If I try it with
|
||||
nslookup on Windows, it seemed to work.
|
||||
|
||||
It works if I put in a manual serial number in the SOA records.
|
||||
Otherwise PowerDNS was putting out 0 a serial number in the SOA, which
|
||||
dig didn't like.
|
||||
|
||||
Any idea how to get automatic serial numbers working?
|
||||
|
||||
According to the manual:
|
||||
|
||||
"If left at 0, the default, PDNS will perform an internal list of the
|
||||
domain to determine highest change\_date field of all records within
|
||||
the zone, and use that as the zone serial number. "
|
||||
|
||||
So what goes in the change\_date field? I tried putting 20100526 as a
|
||||
numerical representation of now, but it was still putting out 0 as a
|
||||
serial number.
|
||||
|
||||
|
||||
David
|
||||
|
||||
|
||||
On 26 May 2010 12:21, David J Craigon <[david at craigon.co.uk](http://mailman.powerdns.com/mailman/listinfo/pdns-users)\> wrote:
|
||||
> *DB schema is exactly as here:*
|
||||
\>
|
||||
\> *[http://doc.powerdns.com/generic-mypgsql-backends.html](http://doc.powerdns.com/generic-mypgsql-backends.html)*
|
||||
\>
|
||||
\> *with the only difference that I have put these tables in a schema*
|
||||
\> *"dns" in the database, since I want to use the database for other*
|
||||
\> *things too.*
|
||||
\>
|
||||
\> *These are my database queries- they are exactly the same as the*
|
||||
\> *defaults, except for adding dns. to the beginning of every table name.*
|
||||
\>
|
||||
\> *# database queries*
|
||||
\>
|
||||
\> *gpgsql-basic-query=select content,ttl,prio,type,domain\_id,name from*
|
||||
\> *dns.records where type='%s' and name='%s'*
|
||||
\>
|
||||
\> *gpgsql-id-query=select content,ttl,prio,type,domain\_id,name from*
|
||||
\> *dns.records where type='%s' and name='%s' and domain\_id=%d*
|
||||
\>
|
||||
\> *gpgsql-any-query=select content,ttl,prio,type,domain\_id,name from*
|
||||
\> *dns.records where name='%s'*
|
||||
\>
|
||||
\> *gpgsql-any-id-query=select content,ttl,prio,type,domain\_id,name from*
|
||||
\> *dns.records where name='%s' and domain\_id=%d*
|
||||
\>
|
||||
\> *gpgsql-list-query=select content,ttl,prio,type,domain\_id,name from*
|
||||
\> *dns.records where domain\_id=%d*
|
||||
\>
|
||||
\>
|
||||
\>
|
||||
\> *gpgsql-master-zone-query=select master from dns.domains where*
|
||||
\> *name='%s' and type='SLAVE'*
|
||||
\>
|
||||
\> *gpgsql-info-zone-query=select*
|
||||
\> *id,name,master,last\_check,notified\_serial,type from dns.domains where*
|
||||
\> *name='%s'*
|
||||
\>
|
||||
\> *gpgsql-info-all-slaves-query=select id,name,master,last\_check,type*
|
||||
\> *from dns.domains where type='SLAVE'*
|
||||
\>
|
||||
\> *gpgsql-supermaster-query=select account from dns.supermasters where*
|
||||
\> *ip='%s' and nameserver='%s');*
|
||||
\>
|
||||
\> *gpgsql-insert-slave-query=insert into dns.domains*
|
||||
\> *(type,name,master,account) values('SLAVE','%s','%s','%s')*
|
||||
\>
|
||||
\> *gpgsql-insert-record-query=insert into dns.records*
|
||||
\> *(content,ttl,prio,type,domain\_id,name) values*
|
||||
\> *('%s',%d,%d,'%s',%d,'%s')*
|
||||
\>
|
||||
\> *gpgsql-update-serial-query=update dns.domains set notified\_serial=%d where id=%d*
|
||||
\>
|
||||
\> *gpgsql-update-lastcheck-query=update dns.domains set*
|
||||
\> *notified\_serial=%d where id=%d*
|
||||
\>
|
||||
\> *gpgsql-info-all-master-query=select*
|
||||
\> *id,name,master,last\_check,notified\_serial,type from dns.domains where*
|
||||
\> *type='MASTER'*
|
||||
\>
|
||||
\> *gpgsql-delete-zone-query=delete from dns.records where domain\_id=%d*
|
||||
\>
|
||||
\>
|
||||
\>
|
||||
\> *gpgsql-wildcard-query=select content,ttl,prio,type,domain\_id,name from*
|
||||
\> *dns.records where type='%s' and name like '%s'*
|
||||
\>
|
||||
\> *gpgsql-wildcard-id-query=select content,ttl,prio,type,domain\_id,name*
|
||||
\> *from dns.records where type='%s' and name like '%s' and domain\_id=%d*
|
||||
\>
|
||||
\> *gpgsql-wildcard-any-query=select content,ttl,prio,type,domain\_id,name*
|
||||
\> *from dns.records where name like '%s'*
|
||||
\>
|
||||
\> *gpgsql-wildcard-any-id-query=select*
|
||||
\> *content,ttl,prio,type,domain\_id,name from dns.records where name='%s'*
|
||||
\> *and domain\_id=%d*
|
||||
\>
|
||||
\>
|
||||
\> *David*
|
||||
\>
|
||||
\> *On 26 May 2010 12:00, bert hubert <[bert.hubert at netherlabs.nl](http://mailman.powerdns.com/mailman/listinfo/pdns-users)\> wrote:*
|
||||
\>> *On Wed, May 26, 2010 at 11:59:31AM +0100, David J Craigon wrote:*
|
||||
\>>> *Adding a TTL doesn't help. Without one, ordinary queries are responded*
|
||||
\>>> *to with the default TTL.*
|
||||
\>>
|
||||
\>> *Ok - can you show all your queries from the configuration? And your db schema?*
|
||||
\>>
|
||||
\>> *Bert*
|
||||
\>>
|
||||
\>
|
||||
|
||||
---
|
||||
|
||||
- Previous message: [\[Pdns-users\] Power DNS 2.9.22 compile error while running 'make' command](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/018736.html)
|
||||
- Next message: [\[Pdns-users\] TCP Connection Thread died because of STL error: Reading data: Connection reset by peer](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/018740.html)
|
||||
- **Messages sorted by:** [\[ date \]](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/date.html#18731) [\[ thread \]](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/thread.html#18731) [\[ subject \]](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/subject.html#18731) [\[ author \]](https://mailman.powerdns.com/pipermail/pdns-users/2010-May/author.html#18731)
|
||||
|
||||
---
|
||||
|
||||
[More information about the Pdns-users mailing list](http://mailman.powerdns.com/mailman/listinfo/pdns-users)
|
||||
@@ -0,0 +1,61 @@
|
||||
---
|
||||
page-title: "fast.ai - GPT 4 and the Uncharted Territories of Language"
|
||||
url: https://www.fast.ai/posts/2023-03-20-wittgenstein.html
|
||||
date: "2023-04-10 10:57:57"
|
||||
---
|
||||
## Beyond Wittgenstein’s Walls[](https://www.fast.ai/posts/2023-03-20-wittgenstein.html#beyond-wittgensteins-walls)
|
||||
|
||||
> “*The limits of my language mean the limits of my world.*” — Ludwig Wittgenstein
|
||||
|
||||
Language is like a map that we use to navigate the world, but it’s also like a prison that keeps us from seeing what’s beyond the walls.
|
||||
|
||||
But what if there was a way to break out of this prison, to expand our map, to explore new worlds with new words? This is the possibility and the challenge offered by instruction tuned language models like GPT 4, a cutting-edge technology that uses artificial neural networks to generate natural language texts based on user inputs.
|
||||
|
||||
GPT 4 can write anything from essays to novels to poems to tweets to code to recipes to jokes to lyrics to whatever you want. It can even write things that don’t exist yet, things that no human has ever thought of or said before.
|
||||
|
||||
As Wittgenstein’s quote suggests, language is a source of limitation and liberation. GPT 4 pushes this idea to the extreme by giving us access to unlimited language.
|
||||
|
||||
This could be the most significant new technology in modern history because it has the potential to change many domains and industries. From education to entertainment, from journalism to justice, from science to art, these models could enable new forms of learning, storytelling, reporting, reasoning, discovery, and creation.
|
||||
|
||||
They could also create new ethical, social, and cultural challenges that require careful reflection and regulation. How we use this technology will depend on how we recognize its implications for ourselves and others.
|
||||
|
||||
This technology is a form of “Artificial Intelligence”. The word “intelligence” derives from *inter*\- (“between”) and *legere* (“to choose, pick out, read”). To be intelligent, then, is to be able to choose between things, to pick out what matters, to read what is written. Intelligence is not just a quantity or a quality; it is an activity, a process, a practice. It is something that we do with our minds and our words.
|
||||
|
||||
But when we let GPT 4 do this for us, are we not abdicating our intelligence? Are we not letting go of our ability to choose, to pick out, to read? Are we not becoming passive consumers of language instead of active producers?
|
||||
|
||||
|
||||
|
||||
Just doing what I’m told…
|
||||
|
||||
## I didn’t write that[](https://www.fast.ai/posts/2023-03-20-wittgenstein.html#i-didnt-write-that)
|
||||
|
||||
Ah, but here’s the rub: the very words that have set the stage for this linguistic exploration were penned not by my own hand (or, rather, keyboard), but by the digital tendrils of Bing (which uses GPT 4). And so, we find ourselves in the throes of a meta-linguistic conundrum, as the very subject of our discussion has surreptitiously insinuated itself into the conversation.
|
||||
|
||||
Now, bear with me, for I have a purpose in revealing this sly subterfuge. My aim is to shatter the very expectations you hold about what language model-generated text looks like, feels like, and, indeed, reads like. For if you’ve made it this far, you’ve unwittingly been drawn into the web of AI-generated prose.
|
||||
|
||||
Perhaps it is only in grappling with the uncanny valley of language that we may find the strength to redefine our own linguistic boundaries and catch a fleeting glimpse of the world beyond the walls.
|
||||
|
||||
## Conclusion[](https://www.fast.ai/posts/2023-03-20-wittgenstein.html#conclusion)
|
||||
|
||||
In the end, GPT 4 presents us with a paradox. On one hand, it has the potential to expand our linguistic horizons and shatter the walls that confine us. On the other hand, it raises questions about the very nature of intelligence, creativity, and what it means to be human. As we delve deeper into the uncharted territories of language, we must be mindful of the delicate balance between embracing innovation and preserving our own intellectual autonomy.
|
||||
|
||||
The challenge, then, is to use GPT 4 as a catalyst for our own growth and exploration, rather than as a substitute for our own minds. By approaching this technology with curiosity, humility, and a commitment to ethical considerations, we can venture beyond Wittgenstein’s walls and chart new territories in language, thought, and human potential.
|
||||
|
||||
## I didn’t write that either[](https://www.fast.ai/posts/2023-03-20-wittgenstein.html#i-didnt-write-that-either)
|
||||
|
||||
Actually, the *entire* article above was written by GPT 4. I created this article because I haven’t seen good examples of what model-generated prose can look like, and because I wanted to experiment with the idea of creating an entire article using GPT 4.
|
||||
|
||||
To create it, I used the following four prompts:
|
||||
|
||||
- “Write a four paragraph introduction to a draft New Yorker article which explains the capabilities of instruction tuned language models such as GPT 4. Begin with a quote from a classical philosopher or writer, and weave references to the quote into the introduction.” [1](https://www.fast.ai/posts/2023-03-20-wittgenstein.html#fn1)
|
||||
- “Write four more paragraphs of this article, discussing the pros and cons of this technology. Incorporate the latin, french, or greek etymology of some word related to the topic and weave it into the article.”
|
||||
- Then I started a new session, and requested: “In a completely different writing style to the introduction, following the style of David Foster Wallace, complete the following article by explaining that it was actually generated by Bing.” I then pasted the draft article into the prompt.
|
||||
- Then I started a new session again with this prompt, pasting the article after the prompt: “The input text is an article which is missing the final section. Please write, in the style of Jeremy Howard, 2 possible final sections of 2-3 paragraphs each.”
|
||||
|
||||
I then deleted some clauses and sentences, but I didn’t otherwise modify any of them in any way, except to add the text “(which uses GPT 4)” after “Bing”. I also manually created the image which Bing suggested I use and pasted it into the article.
|
||||
|
||||
The warning that GPT wrote at the end, “the challenge, then, is to use GPT 4 as a catalyst for our own growth and exploration, rather than as a substitute for our own minds” feels like a warning to me about this article. It ended up heading in a direction that I didn’t really plan, and in hindsight I’m now not at all sure whether it helped my exploration, or substituted for my own mind.
|
||||
|
||||
In the end, this experiment has only left me feeling more confused and uneasy.
|
||||
|
||||
1. There’s this formulaic thing used in a certain class of articles where they’ll open with a quote from an institutionally-approved writer and signal their status in other ways, such as by weaving in latin etymology. It’s a form of gate-keeping, and therefore I don’t like it, and I wanted to break it down. That’s why I picked the first two prompts. Now you can (at least roughly) mimic any writing style, as long as you can describe it, even if you’re not immersed in the culture that it’s associated with. This will make certain people really mad.[↩︎](https://www.fast.ai/posts/2023-03-20-wittgenstein.html#fnref1)
|
||||
+188
@@ -0,0 +1,188 @@
|
||||
---
|
||||
page-title: "matrixgpt/matrix-chatgpt-bot: Talk to ChatGPT via any Matrix client!"
|
||||
url: https://github.com/matrixgpt/matrix-chatgpt-bot
|
||||
date: "2023-04-18 13:34:30"
|
||||
---
|
||||
## Matrix ChatGPT Bot
|
||||
|
||||
Talk to ChatGPT via any Matrix client!
|
||||
|
||||
[](https://github.com/matrixgpt/matrix-chatgpt-bot/blob/main/img/matrix-chatgpt.png)
|
||||
|
||||
A Matrix bot that uses [waylaidwanderer/node-chatgpt-api](https://github.com/waylaidwanderer/node-chatgpt-api) to access the official ChatGPT API.
|
||||
|
||||
## Warning for users upgrading from version 2.x
|
||||
|
||||
OpenAI released the [official API for ChatGPT](https://openai.com/blog/introducing-chatgpt-and-whisper-apis). Thus, we no longer have to use any older models or any models which kept on being turned off by OpenAI. This means the bot is now way more stable and way faster. However, please note: The usage of the API is **no longer free**. If you use this bot, your OpenAI account **will be charged**! You might want to limit your budget in your account using the [OpenAI website](https://platform.openai.com/account/billing). You need to remove the `CHATGPT_MODEL` variable from your environment, if you changed the value.
|
||||
|
||||
## Usage
|
||||
|
||||
1. Create a room
|
||||
2. Add the bot
|
||||
3. Start chatting.
|
||||
|
||||
## Features
|
||||
|
||||
- Shows typing indicator as ChatGPT is thinking!
|
||||
- Supports encryption
|
||||
- Stores context for ChatGPT conversations
|
||||
|
||||
## Configure
|
||||
|
||||
Create a copy of the example `.env` file
|
||||
|
||||
Adjust all required settings in the `.env` file before running. Optional settings can also be adjusted later.
|
||||
|
||||
## Prerequsistes
|
||||
|
||||
### Matrix
|
||||
|
||||
- You need a Matrix account on [Matrix.org](https://matrix.org/) (or any other server) for the bot user.
|
||||
- By default, anyone that knows the name of your bot can invite it to rooms or chat with it.
|
||||
- Restrict access with `MATRIX_BLACKLIST` or `MATRIX_WHITELIST`
|
||||
- Restrict access with `MATRIX_BLACKLIST_ROOMS` or `MATRIX_WHITELIST_ROOMS`
|
||||
- When using a self-hosted setup, you could wildcard all your users with `MATRIX_WHITELIST=:yourhomeserver.example`.
|
||||
|
||||
### OpenAI / ChatGPT
|
||||
|
||||
- You need to have an account at [openai.com](https://openai.com/). Please note that the usage of the ChatGPT-API is not free.
|
||||
- Create a [API Key](https://platform.openai.com/account/api-keys). Then, set `OPENAI_API_KEY` in your `.env` file
|
||||
- You can change the chat-model by setting the `CHATGPT_API_MODEL` in your `.env` file. ChatGPT is the `gpt-3.5-turbo`\-model which is the default. Please note that depending on the model your OpenAI account will be charged.
|
||||
|
||||
## Setup
|
||||
|
||||
- Set `MATRIX_BOT_USERNAME`
|
||||
- Set `MATRIX_BOT_PASSWORD` (you can remove this later if you want)
|
||||
- Run the app using one of the methods below.
|
||||
- Copy `MATRIX_ACCESS_TOKEN` from the output.
|
||||
- Set `MATRIX_ACCESS_TOKEN`, you can now remove `MATRIX_BOT_PASSWORD`.
|
||||
|
||||
*Note*: Doing any of the following can cause issues with encryption later on:
|
||||
|
||||
- Using this token with any other client.
|
||||
- Using an access token extracted via Element.
|
||||
- Deleting the storage folder.
|
||||
- Switching between environments (e.g. Docker or no Docker)
|
||||
|
||||
## Run
|
||||
|
||||
There are multiple ways to run this bot. The easiest way is to run it within docker.
|
||||
|
||||
## with Docker
|
||||
|
||||
This is the recommended way to run this project. It will use the latest stable release.
|
||||
|
||||
```
|
||||
docker run -it -v storage:/storage --env-file=./.env --name matrix-chatgpt-bot ghcr.io/matrixgpt/matrix-chatgpt-bot:latest
|
||||
```
|
||||
|
||||
or to build locally from the latest unstable release (only do this if you have a good reason):
|
||||
|
||||
```
|
||||
docker build . -t matrix-chatgpt-bot
|
||||
docker run -it -v storage:/storage --env-file=./.env --name matrix-chatgpt-bot matrix-chatgpt-bot
|
||||
```
|
||||
|
||||
Note: Without -it flags in the command above you won't be able to stop the container using Ctrl-C
|
||||
|
||||
Note: In order to see the output of your console you need to run `docker logs matrix-chatgpt-bot`
|
||||
|
||||
## with Docker Compose
|
||||
|
||||
If you prefer you can use a docker-compose file. Copy the content below and save it in a file named `docker-compose.yml`. Either with a self-build image (run `docker build . -t matrix-chatgpt-bot` from your local git repo location) or with the latest stable pre-built release from this repo (the **recommended** way).
|
||||
|
||||
The script will look for the `.env` file in the same folder as the `docker-compose.yml`. The key storage folder `storage` will be created in the same folder as well. Adjust the locations to your needs.
|
||||
|
||||
```
|
||||
version: '3.7'
|
||||
services:
|
||||
matrix-chatgpt-bot:
|
||||
container_name: matrix-chatgpt-bot
|
||||
image: ghcr.io/matrixgpt/matrix-chatgpt-bot:latest ## change to "matrix-chatgpt-bot" if you want to use your self-build image
|
||||
volumes:
|
||||
- ./storage:/storage
|
||||
env_file:
|
||||
- ./.env
|
||||
```
|
||||
|
||||
## without Docker
|
||||
|
||||
**Important**: It is strongly recommended to run this package under Docker to not need to install various dependencies manually. Nevertheless, you can also run it by using the package manager yarn (get it via `apt install -y yarn`). You might also need to have a newer version of Node.js and other missing packages.
|
||||
|
||||
- `yarn`
|
||||
- `yarn build`
|
||||
- `yarn start`
|
||||
|
||||
## in Development
|
||||
|
||||
You only need to do this if you want to contribute code to this package.
|
||||
|
||||
- Run `yarn`
|
||||
- Run `yarn build`
|
||||
|
||||
## Good to know
|
||||
|
||||
- By default "storage"-folder contains all your encryption keys. If you delete it, you will loose access to all your encrypted messages.
|
||||
- You can use a [Keyv](https://github.com/jaredwray/keyv) storage backend for persistence if you prefer (advanced).
|
||||
- The bot uses threads by default, to keep the context you should reply to this thread or the bot will think its a new conversation. "Threads" were previously experimental, you may need to activate them in your client's settings (e.g. in Element in the "lab"-section).
|
||||
- There is support to set the context to work at either the:
|
||||
- room level
|
||||
- thread level
|
||||
- both (threads fork the conversation from the main room)
|
||||
|
||||
## FAQ
|
||||
|
||||
## I get "\[Error: decryption failed because the room key is missing\]"
|
||||
|
||||
Encryption works great with this package but can sometimes be a bit sensitive. Following steps can help to solve the "encryption" error
|
||||
|
||||
- Don't use a `MATRIX_ACCESS_TOKEN` extracted via Element-App, use the generated token from the bot based on your `MATRIX_BOT_USERNAME` & `MATRIX_BOT_PASSWORD` set in the `env`file. It will be visible in the console at start up if the `MATRIX_ACCESS_TOKEN` is not already set:
|
||||
|
||||
1. Remove the `MATRIX_ACCESS_TOKEN` from the `env` file and make sure `MATRIX_BOT_USERNAME` & `MATRIX_BOT_PASSWORD` are set
|
||||
2. Re-run the bot
|
||||
3. Copy the token from console output to your `env` file
|
||||
4. Restart the bot again.
|
||||
|
||||
- If all fails, you can always reset your key storage. It's important to exercise all of the following steps, because any remaining data could lead to the next encryption error. Once everything is working, make sure to not touch the "storage" folder anymore:
|
||||
|
||||
1. Stop the bot
|
||||
2. Delete the "storage" folder
|
||||
3. Delete all user data for the matrix bot account (e.g. use Synapse-Admin) or create a fresh bot user account (you can then skip step 4)
|
||||
4. Log into your bot account (e.g. via Element) and log out of all sessions
|
||||
5. Verify the correctness of your `env` file and then run the bot setup again (e.g. via `docker-compose up` if you use docker-compose).
|
||||
|
||||
## I want to chat with the bot without dealing with encryption problems
|
||||
|
||||
- Set `MATRIX_ENCRYPTION=false` in your env-file and restart the bot. If it previously was running with encryption switched on, you need to create a new room with the bot as encryption can't be switched off once it was activated.
|
||||
|
||||
## I get "{ errcode: 'M\_NOT\_FOUND', error: 'Event not found.' }"
|
||||
|
||||
- So far, its not known to cause issues, you can safely ignore it.
|
||||
|
||||
## How do I know that the bot is running succesfully?
|
||||
|
||||
Once the bot has started succesfully, it will output the following information to your console.
|
||||
|
||||
- `[INFO] [index] Starting bot...`
|
||||
- `[INFO] [MatrixClientLite] End-to-end encryption enabled` ## this depends on your setup
|
||||
- `[INFO] [index] Bot started!`
|
||||
|
||||
## I use Docker but I don't see any console output
|
||||
|
||||
You most likely need to view the logs by running `docker logs matrix-chatgpt-bot`
|
||||
|
||||
## Reporting issues
|
||||
|
||||
Please report issues via Github. The chat room is for discussion.
|
||||
|
||||
Please use the search on Github and Matrix before asking for support.
|
||||
|
||||
## Discussion
|
||||
|
||||
Join [#matrix-chatgpt-bot:matrix.org](https://matrix.to/#/#matrix-chatgpt-bot:matrix.org) with any Matrix chat client or on the web!
|
||||
|
||||
If you've never set up a Matrix client before you can follow the prompts to get started.
|
||||
|
||||
## License
|
||||
|
||||
GNU AGPLv3. See LICENSE
|
||||
@@ -0,0 +1,46 @@
|
||||
---
|
||||
page-title: "prmpts.AI - Prompt sandbox"
|
||||
url: https://prmpts.ai/
|
||||
date: "2023-04-23 12:41:12"
|
||||
---
|
||||
[](https://prmpts.ai/)
|
||||
|
||||
What is Prompt Engineering?
|
||||
|
||||
[Read our blog post](https://prmpts.ai/blog/what-is-prompt-engineering).
|
||||
|
||||
#### Prompt
|
||||
|
||||
Given the following fruit, output the closest color hex value that matches the color of that fruit. Fruit:
|
||||
|
||||
fruit
|
||||
|
||||
Color hex string:
|
||||
|
||||
completion
|
||||
|
||||
Tokens: 31
|
||||
|
||||
#### Inputs
|
||||
|
||||
fruit
|
||||
|
||||
#### Preview
|
||||
|
||||
Given the following fruit, output the closest color hex value that matches the color of that fruit. Fruit: Banana Color hex string:
|
||||
|
||||
completion
|
||||
|
||||
Tokens: 34
|
||||
|
||||
Family
|
||||
|
||||
GPT-3
|
||||
|
||||
Model
|
||||
|
||||
text-davinci-003
|
||||
|
||||
Ctrl+Enter
|
||||
|
||||
[© 2023 prmpts**.AI**](https://prmpts.ai/)
|
||||
+137
@@ -0,0 +1,137 @@
|
||||
---
|
||||
page-title: "yarmo/delightful-matrix: A curated list of delightful Matrix resources, implementations and clients. - delightful-matrix - Codeberg.org"
|
||||
url: https://codeberg.org/yarmo/delightful-matrix
|
||||
date: "2023-04-18 22:39:48"
|
||||
---
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#delightful-matrix-delightful-https-codeberg-org-teaserbot-labs-delightful-media-branch-master-assets-delightful-badge-png-https-codeberg-org-teaserbot-labs-delightful)delightful matrix [](https://codeberg.org/teaserbot-labs/delightful)
|
||||
|
||||
A curated list of delightful Matrix resources, implementations and clients.
|
||||
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#table-of-contents)Table of contents
|
||||
|
||||
- [General resourcess](https://codeberg.org/yarmo/delightful-matrix#user-content-general-resources)
|
||||
- [Server implementations](https://codeberg.org/yarmo/delightful-matrix#user-content-server-implementations)
|
||||
- [Clients](https://codeberg.org/yarmo/delightful-matrix#user-content-clients)
|
||||
- [Client SDKs](https://codeberg.org/yarmo/delightful-matrix#user-content-client-sdks)
|
||||
- [Projects based on Matrix](https://codeberg.org/yarmo/delightful-matrix#user-content-projects-based-on-matrix)
|
||||
- [Maintainers](https://codeberg.org/yarmo/delightful-matrix#user-content-maintainers)
|
||||
- [Contributors](https://codeberg.org/yarmo/delightful-matrix#user-content-contributors)
|
||||
- [License](https://codeberg.org/yarmo/delightful-matrix#user-content-license)
|
||||
|
||||
Emoji for each entry provide additional information on project status:
|
||||
|
||||
- 👻 == inactive for over a year, or officially abandoned
|
||||
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#general-resources)General resources
|
||||
|
||||
- [Matrix Spec](https://spec.matrix.org/latest/): the official spec that defines the communication protocols and allows all servers and apps to communicate with each other. `Apache-2.0`
|
||||
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#server-implementations)Server implementations
|
||||
|
||||
- [Conduit](https://gitlab.com/famedly/conduit) ([site](https://conduit.rs/)): A lightweight open-source server implementation of the Matrix Specification with a focus on easy setup and low system requirements. `Apache-2.0, Rust`
|
||||
- [Construct](https://github.com/matrix-construct/construct): A performance-oriented homeserver with minimal dependencies, the first actively federating Matrix server developed independently by the community. `BSD, C++`
|
||||
- [Dendrite](https://github.com/matrix-org/dendrite) ([site](https://matrix.org/docs/projects/server/dendrite)): A second-generation Matrix homeserver written in Go. `Apache-2.0, Go`
|
||||
- [Synapse](https://github.com/matrix-org/synapse) ([site](https://matrix.org/docs/projects/server/synapse)): Matrix homeserver written in Python 3/Twisted. `Apache-2.0, Python`
|
||||
- 👻 [Ligase](https://github.com/finogeeks/Ligase): A Cloud-native Matrix home server written in Golang. `AGPL-3.0, Go`
|
||||
- 👻 [Maelstrom](https://github.com/maelstrom-rs/maelstrom): A high-performance Matrix Home-Server written in Rust designed to be scalable, light on resources, and have a pluggable storage engine. `Apache-2.0 or MIT, Rust`
|
||||
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#clients)Clients
|
||||
|
||||
- [\[chat\]](https://git.cybre.town/adb/matrix-chat) ([app](https://chat.adb.sh/)): A simple matrix webapp for mobile and desktop. `MPL-2.0, JavaScript`
|
||||
- [Cinny](https://github.com/ajbura/cinny) ([site](https://cinny.in/)): Yet another matrix client (web). `MIT, JavaScript`
|
||||
- [Ditto Chat](https://gitlab.com/ditto-chat/ditto) ([site](https://www.dittochat.org/)): An attractive Matrix client built in React Native (Android, iOS, web). `GPL-3.0-or-later, JavaScript`
|
||||
- [Element](https://github.com/vector-im) ([site](https://element.io/)): A glossy web client with an emphasis on performance and usability (Android, iOS, desktop, web). `Apache 2.0, JavaScript/Kotlin/Objective-C`
|
||||
- [FluffyChat](https://gitlab.com/famedly/fluffychat) ([site](https://fluffychat.im/)): Cute instant messaging app for all platforms (Android, iOS, desktop, web). `AGPL-3.0-only, Dart`
|
||||
- [Fractal](https://gitlab.gnome.org/GNOME/fractal) ([site](https://wiki.gnome.org/Apps/Fractal)): A Matrix messaging app for GNOME written in Rust (Linux). `GPL-3.0-only, Rust`
|
||||
- [gomuks](https://github.com/tulir/gomuks) ([site](https://matrix.org/docs/projects/client/gomuks)): A terminal based Matrix client written in Go. `AGPL-3.0-or-later, Go`
|
||||
- [Hydrogen](https://github.com/vector-im/hydrogen-web) ([app](https://hydrogen.element.io/)): Lightweight matrix client with legacy and mobile browser support (web). `Apache-2.0, TypeScript`
|
||||
- [kazv](https://lily-is.land/kazv/kazv): A convergent qml/kirigami client based on libkazv (Linux). `AGPL-3.0-or-later, C++`
|
||||
- [matrix-commander](https://github.com/8go/matrix-commander): Simple but convenient CLI-based Matrix client app for sending, receiving, creating rooms, inviting, verifying, and so much more. `GPL-3.0-or-later, Python`
|
||||
- [matrix-static](https://github.com/matrix-org/matrix-static): A static golang generated preview of public world readable Matrix rooms. `Apache-2.0, Go`
|
||||
- [NeoChat](https://invent.kde.org/network/neochat): A client for Matrix (desktop, mobile). `GPL-3.0-only, C++`
|
||||
- [Nheko](https://github.com/Nheko-Reborn/nheko) ([site](https://nheko-reborn.github.io/)): A native desktop app for Matrix that feels more like a mainstream chat app (Linux, macOS). `GPL-3.0-or-later, C++`
|
||||
- [Nio](https://github.com/niochat/nio) ([site](https://nio.chat/)): An upcoming Matrix client for iOS built with SwiftUI. `MPL-2.0, Swift`
|
||||
- [Quaternion](https://github.com/quotient-im/Quaternion): A Qt5-based IM client for Matrix (desktop). `GPL-3.0-only, C++`
|
||||
- [QuickMedia](https://git.dec05eba.com/QuickMedia/about): A native client for web services including Matrix. `GPL-3.0-or-later, C++`
|
||||
- [SchildiChat](https://github.com/SchildiChat) ([site](https://schildi.chat/)): A Matrix client based on Element with a more traditional instant messaging experience (Android, desktop, web). `Apache-2.0, JavaScript/Kotlin`
|
||||
- [Syphon](https://github.com/syphon-org/syphon) ([site](https://syphon.org/)): A not for profit, open source matrix client with a focus on privacy and ease of use (mobile, desktop). `AGPL-3.0-or-later, Dart`
|
||||
- 👻 [AgentSmith](https://github.com/nilsding/AgentSmith): An IRC server that is actually a Matrix client. Use your favourite IRC client to communicate with the Matrix. `MIT, Crystal`
|
||||
- 👻 [Koma](https://github.com/koma-im/continuum-desktop): A pure Kotlin Matrix client (Linux, macOS). `GPL-3.0-only, Kotlin`
|
||||
- 👻 [matrix-client.el](https://github.com/alphapapa/matrix-client.el): A Matrix client for Emacs. `GPL-3.0-only, Lisp`
|
||||
- 👻 [matrix-ircd](https://github.com/matrix-org/matrix-ircd): An IRCd implementation backed by Matrix. `Apache-2.0, Rust`
|
||||
- 👻 [Mirage](https://github.com/mirukana/mirage): A fancy, customizable, keyboard-operable Qt/QML & Python Matrix chat client (desktop). `LGPL-3.0-or-later, Python`
|
||||
- 👻 [Scylla](https://github.com/DanilaFe/Scylla) ([app](https://scylla.danilafe.com/)): An Elm-based front-end for Matrix (web) `MIT, Elm`
|
||||
- 👻 [Rambox](https://github.com/ramboxapp/community-edition) ([site](https://rambox.app/)): Cross platform messaging and emailing app that combines common web applications into one. `GPL-3.0-only, JavaScript`
|
||||
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#client-sdks)Client SDKs
|
||||
|
||||
### [](https://codeberg.org/yarmo/delightful-matrix#typescript-javascript)TypeScript & JavaScript
|
||||
|
||||
- [matrix-appservice-bridge](https://github.com/matrix-org/matrix-appservice-bridge): Bridging infrastructure for Application Services. `Apache-2.0, TypeScript`
|
||||
- [matrix-appservice-node](https://github.com/matrix-org/matrix-appservice-node): Matrix Application Service framework in Node.js. `Apache-2.0, TypeScript`
|
||||
- [matrix-bot-sdk](https://github.com/turt2live/matrix-bot-sdk): TypeScript/JavaScript SDK for Matrix bots. `MIT, TypeScript`
|
||||
- [matrix-js-sdk](https://github.com/matrix-org/matrix-js-sdk): A Matrix Client-Server SDK for JavaScript. `Apache-2.0, TypeScript`
|
||||
- [matrix-react-sdk](https://github.com/matrix-org/matrix-react-sdk): A Matrix SDK for React Javascript. `Apache-2.0, TypeScript`
|
||||
- [smallbot-matrix](https://github.com/enimatek-nl/small-bot-matrix): Small Matrix Little Bot for Deno. `MIT, TypeScript`
|
||||
- 👻 [botkit-matrix](https://github.com/frankgerhardt/botkit-matrix): A Botkit connector for Matrix. `Apache-2.0, JavaScript`
|
||||
|
||||
### [](https://codeberg.org/yarmo/delightful-matrix#python)Python
|
||||
|
||||
- [mautrix-python](https://github.com/mautrix/python): A Python 3 asyncio Matrix framework. `MPL-2.0, Python`
|
||||
- [simple-matrix-bot-lib](https://github.com/KrazyKirby99999/simple-matrix-bot-lib): An easy to use bot library for the Matrix ecosystem written in Python. `MIT, Python`
|
||||
- [µtrix](https://edugit.org/Teckids/hacknfun/libs/mytrix): A Matrix client library for MicroPython. `Apache-2.0, Python`
|
||||
- 👻 [matrix-python-sdk](https://github.com/matrix-org/matrix-python-sdk): A Matrix Client-Server SDK for Python 2 and 3. `Apache-2.0, Python`
|
||||
|
||||
### [](https://codeberg.org/yarmo/delightful-matrix#kotlin)Kotlin
|
||||
|
||||
- [dial-phone](https://github.com/mtorials/dial-phone): A Matrix client-server SDK for JVM written in Kotlin. `Apache-2.0, Kotlin`
|
||||
- [matrix-kt](https://github.com/Dominaezzz/matrix-kt): Kotlin multiplatform libraries for Matrix. `Apache-2.0, Kotlin`
|
||||
- [Trixnity](https://gitlab.com/benkuly/trixnity): A Multiplatform Kotlin SDK for Matrix. `AGPL-3.0-or-later, Kotlin`
|
||||
|
||||
### [](https://codeberg.org/yarmo/delightful-matrix#rust)Rust
|
||||
|
||||
- [matrix-rust-sdk](https://github.com/matrix-org/matrix-rust-sdk): Matrix Client-Server SDK for Rust. `Apache-2.0, Rust`
|
||||
- [ruma](https://github.com/ruma/ruma) ([site](https://www.ruma.io/)): A set of Rust crates for interacting with the Matrix chat network. `MIT, Rust`
|
||||
|
||||
### [](https://codeberg.org/yarmo/delightful-matrix#c)C++
|
||||
|
||||
- [libkazb](https://lily-is.land/kazv/libkazv): A matrix client SDK built upon lager and the value-oriented design it enables. `AGPL-3.0-or-later, C++`
|
||||
- [libQuotient](https://github.com/quotient-im/libQuotient): A Qt5 library to write cross-platform clients for Matrix. `LGPL-2.1, C++`
|
||||
|
||||
### [](https://codeberg.org/yarmo/delightful-matrix#c-1)C#
|
||||
|
||||
- [Matrix .NET SDK](https://github.com/baking-bad/matrix-dotnet-sdk): A .NET Standard 2.0 library compatible with the Matrix protocol. `MIT, C#`
|
||||
- 👻 [MatrixAPI](https://github.com/VRocker/MatrixAPI): A Matrix library for C# UWP. `Apache-2.0, C#`
|
||||
|
||||
### [](https://codeberg.org/yarmo/delightful-matrix#go)Go
|
||||
|
||||
- [mautrix-go](https://github.com/mautrix/go) ([site](https://maunium.net/go/mautrix/)): A Golang Matrix framework. `MPL-2.0, Go`
|
||||
- 👻 [gomatrix](https://github.com/matrix-org/gomatrix): A Golang Matrix client. `Apache-2.0, Go`
|
||||
|
||||
### [](https://codeberg.org/yarmo/delightful-matrix#other-languages)Other languages
|
||||
|
||||
- [dart-matrix-sdk](https://gitlab.com/famedly/company/frontend/famedlysdk): A Matrix SDK written in pure Dart. `AGPL-3.0, Dart`
|
||||
- [Matrix::Client](https://github.com/matiaslina/Matrix-Client): A Raku library for Matrix. `Artistic-2.0, Raku`
|
||||
- [Matrix-ClientServer-API-java](https://github.com/JojiiOfficial/Matrix-ClientServer-API-java): A small and simple java API. `GPL-3.0, Java`
|
||||
- [matrix-ios-sdk](https://github.com/matrix-org/matrix-ios-sdk): A Matrix SDK for iOS. `Apache-2.0, Objective-C`
|
||||
- [matrix-nio](https://github.com/poljar/matrix-nio) ([site](https://matrix-nio.readthedocs.io/en/latest/)): A Python Matrix client library, designed according to sans I/O principles. `ISC, Python`
|
||||
- [ruby-matrix-sdk](https://github.com/ananace/ruby-matrix-sdk): A Ruby SDK for the Matrix communication protocol. `MIT, Ruby`
|
||||
- 👻 [haxe-matrix-im](https://notabug.org/Tamaimo/haxe-matrix-im): Implementation of client-server matrix API in haxe using HaxeHttpClient. `AGPL-3.0-only, Haxe`
|
||||
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#projects-based-on-matrix)Projects based on Matrix
|
||||
|
||||
- [Cactus Comments](https://gitlab.com/cactus-comments) ([site](https://cactus.chat/)): A federated comment system for the web, based on the Matrix protocol. `GPL-3.0, Python`
|
||||
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#maintainers)Maintainers
|
||||
|
||||
If you have questions or feedback regarding this list, then please create an [Issue](https://codeberg.org/yarmo/delightful-matrix/issues) in our tracker, and optionally `@mention` one or more of our maintainers:
|
||||
|
||||
- [`@yarmo`](https://codeberg.org/yarmo)
|
||||
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#contributors)Contributors
|
||||
|
||||
With delight we present you some of our [delightful contributors](https://codeberg.org/yarmo/delightful-matrix/src/branch/main/delightful-contributors.md) (please [add yourself](https://codeberg.org/teaserbot-labs/delightful/src/branch/master/delight-us.md#attribution-of-contributors) if you are missing).
|
||||
|
||||
## [](https://codeberg.org/yarmo/delightful-matrix#license)License
|
||||
|
||||
[](https://creativecommons.org/publicdomain/zero/1.0/)
|
||||
@@ -0,0 +1,58 @@
|
||||
---
|
||||
page-title: "Creating user accounts | Dendrite"
|
||||
url: https://matrix-org.github.io/dendrite/administration/createusers
|
||||
date: "2023-05-06 10:35:52"
|
||||
---
|
||||
## [](https://matrix-org.github.io/dendrite/administration/createusers#creating-user-accounts)Creating user accounts
|
||||
|
||||
User accounts can be created on a Dendrite instance in a number of ways.
|
||||
|
||||
## [](https://matrix-org.github.io/dendrite/administration/createusers#from-the-command-line)From the command line
|
||||
|
||||
The `create-account` tool is built in the `bin` folder when building Dendrite with the `build.sh` script.
|
||||
|
||||
It uses the `dendrite.yaml` configuration file to connect to a running Dendrite instance and requires shared secret registration to be enabled as explained below.
|
||||
|
||||
An example of using `create-account` to create a **normal account**:
|
||||
|
||||
```
|
||||
./bin/create-account -config /path/to/dendrite.yaml -username USERNAME
|
||||
```
|
||||
|
||||
You will be prompted to enter a new password for the new account.
|
||||
|
||||
To create a new **admin account**, add the `-admin` flag:
|
||||
|
||||
```
|
||||
./bin/create-account -config /path/to/dendrite.yaml -username USERNAME -admin
|
||||
```
|
||||
|
||||
By default `create-account` uses `http://localhost:8008` to connect to Dendrite, this can be overwritten using the `-url` flag:
|
||||
|
||||
```
|
||||
./bin/create-account -config /path/to/dendrite.yaml -username USERNAME -url https://localhost:8448
|
||||
```
|
||||
|
||||
An example of using `create-account` when running in **Docker**, having found the `CONTAINERNAME` from `docker ps`:
|
||||
|
||||
```
|
||||
docker exec -it CONTAINERNAME /usr/bin/create-account -config /path/to/dendrite.yaml -username USERNAME
|
||||
```
|
||||
|
||||
```
|
||||
docker exec -it CONTAINERNAME /usr/bin/create-account -config /path/to/dendrite.yaml -username USERNAME -admin
|
||||
```
|
||||
|
||||
Dendrite supports the Synapse-compatible shared secret registration endpoint.
|
||||
|
||||
To enable shared secret registration, you must first enable it in the `dendrite.yaml` configuration file by specifying a shared secret. In the `client_api` section of the config, enter a new secret into the `registration_shared_secret` field:
|
||||
|
||||
```
|
||||
client_api:
|
||||
# ...
|
||||
registration_shared_secret: ""
|
||||
```
|
||||
|
||||
You can then use the `/_synapse/admin/v1/register` endpoint as per the [Synapse documentation](https://matrix-org.github.io/synapse/latest/admin_api/register_api.html).
|
||||
|
||||
Shared secret registration is only enabled once a secret is configured. To disable shared secret registration again, remove the secret from the configuration file.
|
||||
@@ -0,0 +1,239 @@
|
||||
---
|
||||
page-title: "How to Set Up a Mail Server with PostfixAdmin on Debian 11"
|
||||
url: https://www.howtoforge.com/how-to-set-up-a-mail-server-with-postfixadmin-on-debian-11/
|
||||
date: "2023-05-29 07:50:31"
|
||||
---
|
||||
### On this page
|
||||
|
||||
1. [Prerequisites](https://www.howtoforge.com/how-to-set-up-a-mail-server-with-postfixadmin-on-debian-11/#prerequisites)
|
||||
2. [Getting Started](https://www.howtoforge.com/how-to-set-up-a-mail-server-with-postfixadmin-on-debian-11/#getting-started)
|
||||
3. [Install Nginx, MariaDB and PHP](https://www.howtoforge.com/how-to-set-up-a-mail-server-with-postfixadmin-on-debian-11/#install-nginx-mariadb-and-php)
|
||||
4. [Create a PostfixAdmin Database](https://www.howtoforge.com/how-to-set-up-a-mail-server-with-postfixadmin-on-debian-11/#create-a-postfixadmin-database)
|
||||
5. [Install PostfixAdmin](https://www.howtoforge.com/how-to-set-up-a-mail-server-with-postfixadmin-on-debian-11/#install-postfixadmin)
|
||||
6. [Configure Nginx for PostfixAdmin](https://www.howtoforge.com/how-to-set-up-a-mail-server-with-postfixadmin-on-debian-11/#configure-nginx-for-postfixadmin)
|
||||
7. [Access PostfixAdmin](https://www.howtoforge.com/how-to-set-up-a-mail-server-with-postfixadmin-on-debian-11/#access-postfixadmin)
|
||||
8. [Conclusion](https://www.howtoforge.com/how-to-set-up-a-mail-server-with-postfixadmin-on-debian-11/#conclusion)
|
||||
|
||||
PostfixAdmin is a free, open-source, and web-based interface used for managing Postfix mail server from the web browser. It allows you to add users, aliases, set a disk quota, add and remove domains from the web-based interface. It supports several database backends including PostgreSQL, MySQL, MariaDB, and SQLite. It can be integrated with Squirrelmail and Roundcube via plugins.
|
||||
|
||||
In this article, I will explain how to install PostfixAdmin on Debian 11.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- A server running Debian 11 with postfix installed.
|
||||
- A valid domain name is pointed with your server IP address.
|
||||
- A valid MX record is pointed with your server IP address.
|
||||
|
||||
## Getting Started
|
||||
|
||||
First, update your system packages with the latest version using the following command:
|
||||
|
||||
apt-get update -y
|
||||
|
||||
Once your system is updated, set the fully qualified hostname of your server.
|
||||
|
||||
hostnamectl set-hostname mail.domain.com
|
||||
|
||||
Next, run the following command to apply the changes.
|
||||
|
||||
hostname -f
|
||||
|
||||
Once you are done, you can proceed to the next step.
|
||||
|
||||
## Install Nginx, MariaDB and PHP
|
||||
|
||||
Next, you will need to install the Nginx web server, MariaDB, PHP, and other required PHP extensions to your server. You can install all of them with the following command:
|
||||
|
||||
apt-get install nginx mariadb-server php-fpm php-cli php-imap php-json php-mysql php-opcache php-mbstring php-readline unzip sudo -y
|
||||
|
||||
Once all the packages are installed, you can proceed to the next step.
|
||||
|
||||
## Create a PostfixAdmin Database
|
||||
|
||||
Next, you will need to create a database and user for PostfixAdmin. First, log in to the MariaDB console with the following command:
|
||||
|
||||
mysql
|
||||
|
||||
Once you are connected, create a database and user with the following command:
|
||||
|
||||
MariaDB \[(none)\]> CREATE DATABASE postfixadmin;
|
||||
MariaDB \[(none)\]> GRANT ALL ON postfixadmin.\* TO 'postfixadmin'@'localhost' IDENTIFIED BY 'securepassword';
|
||||
|
||||
Next, flush the privileges and exit from the MariaDB shell with the following command:
|
||||
|
||||
MariaDB \[(none)\]> FLUSH PRIVILEGES;
|
||||
MariaDB \[(none)\]> EXIT;
|
||||
|
||||
At this point, the MariaDB database is created for PostfixAdmin. You can now proceed to the next step.
|
||||
|
||||
## Install PostfixAdmin
|
||||
|
||||
First, you will need to download the latest version of PostfixAdmin from the Sourceforge website. You can download it with the following command:
|
||||
|
||||
wget https://webwerks.dl.sourceforge.net/project/postfixadmin/postfixadmin-3.3.8/PostfixAdmin%203.3.8.tar.gz
|
||||
|
||||
Once the download is completed, extract the downloaded file with the following command:
|
||||
|
||||
tar -xvzf PostfixAdmin\\ 3.3.8.tar.gz
|
||||
|
||||
Next, move the extracted directory to the Nginx web root directory:
|
||||
|
||||
mv postfixadmin-postfixadmin-7d04685 /var/www/html/postfixadmin
|
||||
|
||||
Next, create a directory required to install PostfixAdmin:
|
||||
|
||||
mkdir /var/www/html/postfixadmin/templates\_c
|
||||
|
||||
Next, set proper ownership to PostfixAdmin directory:
|
||||
|
||||
chown -R www-data: /var/www/html/postfixadmin/
|
||||
|
||||
Next, create a config.local.php file:
|
||||
|
||||
nano /var/www/html/postfixadmin/config.local.php
|
||||
|
||||
Add the following lines:
|
||||
|
||||
<?php
|
||||
$CONF\['configured'\] = true;
|
||||
|
||||
$CONF\['database\_type'\] = 'mysqli';
|
||||
$CONF\['database\_host'\] = 'localhost';
|
||||
$CONF\['database\_user'\] = 'postfixadmin';
|
||||
$CONF\['database\_password'\] = 'securepassword';
|
||||
$CONF\['database\_name'\] = 'postfixadmin';
|
||||
|
||||
$CONF\['default\_aliases'\] = array (
|
||||
'abuse' => 'abuse@domain.com',
|
||||
'hostmaster' => 'hostmaster@domain.com',
|
||||
'postmaster' => 'postmaster@domain.com',
|
||||
'webmaster' => 'webmaster@domain.com'
|
||||
);
|
||||
|
||||
$CONF\['fetchmail'\] = 'NO';
|
||||
$CONF\['show\_footer\_text'\] = 'NO';
|
||||
|
||||
$CONF\['quota'\] = 'YES';
|
||||
$CONF\['domain\_quota'\] = 'YES';
|
||||
$CONF\['quota\_multiplier'\] = '1024000';
|
||||
$CONF\['used\_quotas'\] = 'YES';
|
||||
$CONF\['new\_quota\_table'\] = 'YES';
|
||||
|
||||
$CONF\['aliases'\] = '0';
|
||||
$CONF\['mailboxes'\] = '0';
|
||||
$CONF\['maxquota'\] = '0';
|
||||
$CONF\['domain\_quota\_default'\] = '0';
|
||||
?>
|
||||
|
||||
Save and close the file then create the schema for the PostfixAdmin database with the following command:
|
||||
|
||||
sudo -u www-data php /var/www/html/postfixadmin/public/upgrade.php
|
||||
|
||||
Next, you will need to create a super admin account for PostfixAdmin. You can create it with the following command:
|
||||
|
||||
bash /var/www/html/postfixadmin/scripts/postfixadmin-cli admin add
|
||||
|
||||
Provide your admin username, password, and domain as shown below:
|
||||
|
||||
Welcome to Postfixadmin-CLI v0.3
|
||||
---------------------------------------------------------------
|
||||
|
||||
Admin:
|
||||
> admin@domain.com
|
||||
|
||||
Password:
|
||||
> Secure@12345
|
||||
|
||||
Password (again):
|
||||
> Secure@12345
|
||||
|
||||
Super admin:
|
||||
(Super admins have access to all domains, can manage domains and admin accounts.) (y/n)
|
||||
> y
|
||||
|
||||
Domain:
|
||||
> domain.com
|
||||
|
||||
Active: (y/n)
|
||||
> y
|
||||
|
||||
The admin admin@domain.com has been added!
|
||||
|
||||
---------------------------------------------------------------
|
||||
|
||||
## Configure Nginx for PostfixAdmin
|
||||
|
||||
Next, you will need to create an Nginx virtual host configuration file for PostfixAdmin. You can create it with the following command:
|
||||
|
||||
nano /etc/nginx/conf.d/domain.com.conf
|
||||
|
||||
Add the following lines:
|
||||
|
||||
server {
|
||||
listen 80;
|
||||
root /var/www/html/postfixadmin/public;
|
||||
index index.html index.htm index.php;
|
||||
server\_name mail.domain.com;
|
||||
|
||||
location ~ \\.php$ {
|
||||
fastcgi\_split\_path\_info ^(.+\\.php)(/.+)$;
|
||||
fastcgi\_pass unix:/var/run/php/php7.4-fpm.sock;
|
||||
fastcgi\_index index.php;
|
||||
include fastcgi\_params;
|
||||
fastcgi\_param SCRIPT\_FILENAME $document\_root$fastcgi\_script\_name;
|
||||
fastcgi\_intercept\_errors off;
|
||||
fastcgi\_buffer\_size 16k;
|
||||
fastcgi\_buffers 4 16k;
|
||||
fastcgi\_connect\_timeout 600;
|
||||
fastcgi\_send\_timeout 600;
|
||||
fastcgi\_read\_timeout 600;
|
||||
}
|
||||
|
||||
|
||||
location / {
|
||||
try\_files $uri $uri/ =404;
|
||||
}
|
||||
|
||||
}
|
||||
|
||||
Save and close the file then restart the Nginx service to apply the changes:
|
||||
|
||||
systemctl restart nginx
|
||||
|
||||
You can also check the status of Nginx with the following command:
|
||||
|
||||
systemctl status nginx
|
||||
|
||||
You should get the following output:
|
||||
|
||||
? nginx.service - A high performance web server and a reverse proxy server
|
||||
Loaded: loaded (/lib/systemd/system/nginx.service; enabled; vendor preset: enabled)
|
||||
Active: active (running) since Sat 2021-08-28 08:13:22 UTC; 7s ago
|
||||
Docs: man:nginx(8)
|
||||
Process: 74644 ExecStartPre=/usr/sbin/nginx -t -q -g daemon on; master\_process on; (code=exited, status=0/SUCCESS)
|
||||
Process: 74645 ExecStart=/usr/sbin/nginx -g daemon on; master\_process on; (code=exited, status=0/SUCCESS)
|
||||
Main PID: 74646 (nginx)
|
||||
Tasks: 2 (limit: 2341)
|
||||
Memory: 3.2M
|
||||
CPU: 57ms
|
||||
CGroup: /system.slice/nginx.service
|
||||
??74646 nginx: master process /usr/sbin/nginx -g daemon on; master\_process on;
|
||||
??74647 nginx: worker process
|
||||
|
||||
Aug 28 08:13:22 mail.domain.com systemd\[1\]: Starting A high performance web server and a reverse proxy server...
|
||||
Aug 28 08:13:22 mail.domain.com systemd\[1\]: nginx.service: Failed to parse PID from file /run/nginx.pid: Invalid argument
|
||||
Aug 28 08:13:22 mail.domain.com systemd\[1\]: Started A high performance web server and a reverse proxy server.
|
||||
|
||||
## Access PostfixAdmin
|
||||
|
||||
At this point, PostfixAdmin is installed and configured. You can now access it using the URL **http://mail.domain.com**. You will be redirected to the PostfixAdmin login page:
|
||||
|
||||
[](https://www.howtoforge.com/images/how_to_set_up_a_mail_server_with_postfixadmin_on_debian_11/big/p1.png)
|
||||
|
||||
Provide your admin email, password and click on the **Login** button. You should see the PostfixAdmin dashboard on the following screen:
|
||||
|
||||
[](https://www.howtoforge.com/images/how_to_set_up_a_mail_server_with_postfixadmin_on_debian_11/big/p2.png)
|
||||
|
||||
## Conclusion
|
||||
|
||||
Congratulations! you have successfully installed PostfixAdmin on Debian 11. You can now easily manage your Postfix mail server from the web browser. Feel free to ask me if you have any questions.
|
||||
@@ -0,0 +1,106 @@
|
||||
---
|
||||
page-title: "N26开户教程 | Mutou"
|
||||
url: https://www.mutou.men/posts/n26%E5%BC%80%E6%88%B7%E6%95%99%E7%A8%8B/
|
||||
date: "2023-05-30 17:45:21"
|
||||
---
|
||||
## 一、下载N26 app
|
||||
|
||||
去appstore或者google play搜索下载即可。网页注册需要挂德国代理,如果你有德国代理,点此连接在网页注册👉[注册地址](https://n26.com/r/haihuaw4351)
|
||||
|
||||
|
||||
|
||||
上面选择完成后,直接提交就可以。如果有reffer code填写的地方,可以填写haihuaw4351,各得15欧元。
|
||||
|
||||
注册完成后,下一步是视频验证。
|
||||
|
||||
## 二、视频验证
|
||||
|
||||
我是晚上8点左右验证的,接通比较快。 基本会有以下问题:
|
||||
|
||||
## 1.开户确认
|
||||
|
||||
询问你德语还是英语沟通
|
||||
|
||||
答:English
|
||||
|
||||
> 如果无法支持英文,直接挂掉,重新开启视频换人即可,遇到态度不好的同理。
|
||||
|
||||
1.1 请告诉我你的姓名
|
||||
|
||||
答:可以直接读拼音或字母
|
||||
|
||||
2.2 你的邮箱地址
|
||||
|
||||
答: . 读dot
|
||||
|
||||
2.3 你的邮箱是不是你自己一个人使用?
|
||||
|
||||
答:yes
|
||||
|
||||
2.4 密码是不是只有你一个人知道?
|
||||
|
||||
答:yes
|
||||
|
||||
2.5 开户的原因 (reason of open this account)
|
||||
|
||||
答:Shopping Online 等等
|
||||
|
||||
2.6 有沒有可以收验证码的手机 (Do you have any device for receive text message)
|
||||
|
||||
答:yes
|
||||
|
||||
2.7 从哪知道N26的(How to know N26)
|
||||
|
||||
答:my friend或者其他的
|
||||
|
||||
2.8 你的国籍 (National)
|
||||
|
||||
答:China
|
||||
|
||||
## 2 验证护照
|
||||
|
||||
1.给人脸拍照
|
||||
|
||||
细节:可能要求你手先在脸前挥动一下,然后张开5指放在脸旁**慢慢的**从左移动到右边 手速不要太快
|
||||
|
||||
2.给护照拍照
|
||||
|
||||
需要做如下指令:
|
||||
|
||||
2.1 翻到照片页,拍一个完整图片,调整角度,查看防伪水印。
|
||||
|
||||
2.2 将摄像头靠近护照头像拍照,有可能要手指按住头像拍照.
|
||||
|
||||
2.3 将摄像头靠近护照号码拍照
|
||||
|
||||
2.4 将摄像头靠近护照标拍照,注意:可能会要求你不断摆动角度,看颜色变化,会要求右手拇指或食指按住护照标一半的位置进行拍照.
|
||||
|
||||
2.5 将摄像头靠近护照水印拍照,要求**翻转不同角度看颜色变化**.
|
||||
|
||||
2.6 合上护照,给护照封面拍照。
|
||||
|
||||
顺序不一定,也不一定全做,也可能有其他要求。
|
||||
|
||||
## 3.合上护照回答个人信息
|
||||
|
||||
3.1 你的出生日期?
|
||||
|
||||
3.2 出生城市or国家?
|
||||
|
||||
3.3 你的护照号码? 用英语如是回答即可
|
||||
|
||||
3.4 你是否处于自己的意愿开户?
|
||||
|
||||
答:yes
|
||||
|
||||
3.5 你是否受别人指使开户?
|
||||
|
||||
答:no
|
||||
|
||||
3.6 开设账户只有你自己使用吗?
|
||||
|
||||
答:yes
|
||||
|
||||
## 4\. 填写短信验证码
|
||||
|
||||
会发送一个手机验证码,填完之后,客服会说视频认证完成了
|
||||
@@ -0,0 +1,244 @@
|
||||
---
|
||||
page-title: "PostfixAmavisNew - Community Help Wiki"
|
||||
url: https://help.ubuntu.com/community/PostfixAmavisNew
|
||||
date: "2023-05-25 09:42:29"
|
||||
---
|
||||
## Introduction
|
||||
|
||||
Contents
|
||||
|
||||
1. [Introduction](https://help.ubuntu.com/community/PostfixAmavisNew#Introduction)
|
||||
2. [Prerequisite](https://help.ubuntu.com/community/PostfixAmavisNew#Prerequisite)
|
||||
3. [Installation](https://help.ubuntu.com/community/PostfixAmavisNew#Installation)
|
||||
4. [Configuration](https://help.ubuntu.com/community/PostfixAmavisNew#Configuration)
|
||||
1. [Clamav](https://help.ubuntu.com/community/PostfixAmavisNew#Clamav)
|
||||
2. [Spamassassin](https://help.ubuntu.com/community/PostfixAmavisNew#Spamassassin)
|
||||
3. [Amavis](https://help.ubuntu.com/community/PostfixAmavisNew#Amavis)
|
||||
4. [Postfix integration](https://help.ubuntu.com/community/PostfixAmavisNew#Postfix_integration)
|
||||
5. [Test](https://help.ubuntu.com/community/PostfixAmavisNew#Test)
|
||||
6. [Troubleshooting](https://help.ubuntu.com/community/PostfixAmavisNew#Troubleshooting)
|
||||
7. [Amavis Performance](https://help.ubuntu.com/community/PostfixAmavisNew#Amavis_Performance)
|
||||
|
||||
In this howto, Postfix integration with amavis-new will be presented. Amavis-new is a wrapper that can call any number of content filtering programs for spam detection, antivirus, etc. In this howto, integration with Spamassassin and Clamav will be presented. This is a classical installation of Postfix + Amavis-new + Spamassassin + Clamav.
|
||||
|
||||
## Prerequisite
|
||||
|
||||
You should have a functional Postfix server installed. If this is not the case, follow the [Postfix](https://help.ubuntu.com/community/Postfix) guide.
|
||||
|
||||
## Installation
|
||||
|
||||
To begin, install (see [InstallingSoftware](https://help.ubuntu.com/community/InstallingSoftware)) the following packages:
|
||||
|
||||
sudo apt-get install amavisd-new spamassassin clamav-daemon
|
||||
|
||||
Install the optional packages for better spam detection (who does not want better spam detection?):
|
||||
|
||||
sudo apt-get install libnet-dns-perl libmail-spf-perl pyzor razor
|
||||
|
||||
Install these optional packages to enable better scanning of attached archive files:
|
||||
|
||||
sudo apt-get install arj bzip2 cabextract cpio file gzip lha nomarch pax rar unrar unzip unzoo zip zoo
|
||||
|
||||
**Note:** Ubuntu 12.04 LTS doesn't have unzoo. Ubuntu 14.04 LTS doesn't have lha. You may try to substitute lhasa.
|
||||
|
||||
## Configuration
|
||||
|
||||
## Clamav
|
||||
|
||||
The default behaviour of Clamav will fit our needs. A daemon is launched (clamd) and signatures are fetched every day. For more Clamav configuration options, check the configuration files in /etc/clamav.
|
||||
|
||||
Add clamav user to the amavis group and vice versa in order for Clamav to have access to scan files:
|
||||
|
||||
sudo adduser clamav amavis
|
||||
sudo adduser amavis clamav
|
||||
|
||||
**Note**: especially when driven on small cloud instances, VPS or routers there were concerns about the memory consumption. There is a good summary why virus scanning in general has a [rather high memory](http://unix.stackexchange.com/questions/114709/how-to-reduce-clamav-memory-usage) consumption in general. An admin setting up such a solution needs to consider that ~200-350mb seem to be rather normal.
|
||||
|
||||
## Spamassassin
|
||||
|
||||
As amavis is its own spamassassin-daemon (amavis uses the spamassassin libraries), there is no need in configuring or starting spamassassin. amavis will not use any running instance of spamd!
|
||||
|
||||
The use of razor and pyzormust be enabled by
|
||||
|
||||
\# su - amavis -s /bin/bash
|
||||
\# razor-admin -create
|
||||
\# razor-admin -register
|
||||
\# pyzor discover
|
||||
|
||||
There is no need of configuring razor or pyzor.
|
||||
|
||||
## Amavis
|
||||
|
||||
First, activate spam and antivirus detection in Amavis by editing /etc/amavis/conf.d/15-content\_filter\_mode:
|
||||
|
||||
use strict;
|
||||
\# You can modify this file to re-enable SPAM checking through spamassassin
|
||||
\# and to re-enable antivirus checking.
|
||||
#
|
||||
\# Default antivirus checking mode
|
||||
\# Uncomment the two lines below to enable it
|
||||
#
|
||||
@bypass\_virus\_checks\_maps = (
|
||||
\\%bypass\_virus\_checks, \\@bypass\_virus\_checks\_acl, \\$bypass\_virus\_checks\_re);
|
||||
#
|
||||
\# Default SPAM checking mode
|
||||
\# Uncomment the two lines below to enable it
|
||||
#
|
||||
@bypass\_spam\_checks\_maps = (
|
||||
\\%bypass\_spam\_checks, \\@bypass\_spam\_checks\_acl, \\$bypass\_spam\_checks\_re);
|
||||
1; # insure a defined return
|
||||
|
||||
After configuration Amavis needs to be restarted:
|
||||
|
||||
sudo /etc/init.d/amavis restart
|
||||
|
||||
## Postfix integration
|
||||
|
||||
For postfix integration, you need to add the content\_filter configuration variable to the Postfix configuration file /etc/postfix/main.cf. This instructs postfix to pass messages to amavis at a given IP address and port:
|
||||
|
||||
content\_filter = smtp-amavis:\[127.0.0.1\]:10024
|
||||
|
||||
The following postconf command, run as root because of the preceding sudo command, adds the content\_filter specification line above to main.cf:
|
||||
|
||||
sudo postconf -e "content\_filter = smtp-amavis:\[127.0.0.1\]:10024"
|
||||
|
||||
Alternatively, you can manually edit main.cf yourself to add the content\_filter line.
|
||||
|
||||
Next edit /etc/postfix/master.cf and add the following to the end of the file:
|
||||
|
||||
smtp-amavis unix - - - - 2 smtp
|
||||
-o smtp\_data\_done\_timeout=1200
|
||||
-o smtp\_send\_xforward\_command=yes
|
||||
-o disable\_dns\_lookups=yes
|
||||
-o max\_use=20
|
||||
127.0.0.1:10025 inet n - - - - smtpd
|
||||
-o content\_filter=
|
||||
-o local\_recipient\_maps=
|
||||
-o relay\_recipient\_maps=
|
||||
-o smtpd\_restriction\_classes=
|
||||
-o smtpd\_delay\_reject=no
|
||||
-o smtpd\_client\_restrictions=permit\_mynetworks,reject
|
||||
-o smtpd\_helo\_restrictions=
|
||||
-o smtpd\_sender\_restrictions=
|
||||
-o smtpd\_recipient\_restrictions=permit\_mynetworks,reject
|
||||
-o smtpd\_data\_restrictions=reject\_unauth\_pipelining
|
||||
-o smtpd\_end\_of\_data\_restrictions=
|
||||
-o mynetworks=127.0.0.0/8
|
||||
-o smtpd\_error\_sleep\_time=0
|
||||
-o smtpd\_soft\_error\_limit=1001
|
||||
-o smtpd\_hard\_error\_limit=1000
|
||||
-o smtpd\_client\_connection\_count\_limit=0
|
||||
-o smtpd\_client\_connection\_rate\_limit=0
|
||||
-o receive\_override\_options=no\_header\_body\_checks,no\_unknown\_recipient\_checks
|
||||
|
||||
Also add the following two lines immediately below the "pickup" transport service:
|
||||
|
||||
-o content\_filter=
|
||||
-o receive\_override\_options=no\_header\_body\_checks
|
||||
|
||||
This will prevent messages that are generated to report on spam from being classified as spam.
|
||||
|
||||
For Postfix instances hosting virtual domains, Amavis also need to know what domain names are considered as local domain names. By default, only the FQDN of the localhost is treated as local. So in the file '/etc/amavis/conf.d/05-domain\_id', list all your virtual domain names in @local\_domains\_acl
|
||||
|
||||
@local\_domains\_acl = ( ".$mydomain", ".example1.com", ".example2.com" );
|
||||
|
||||
And In the file '/etc/amavis/conf.d/50-user', add
|
||||
|
||||
@whitelist\_sender\_acl = @local\_domains\_acl
|
||||
|
||||
More information can be found from ["README.postfix from amavisd-new"](http://www.ijs.si/software/amavisd/README.postfix.txt) and ["D.J.Fan"](http://www200.pair.com/mecham/spam/spamfilter20060701.html)
|
||||
|
||||
Reload postfix:
|
||||
|
||||
sudo /etc/init.d/postfix reload
|
||||
|
||||
Now content filtering with spam and virus detection is enabled.
|
||||
|
||||
## Test
|
||||
|
||||
First, test that the amavis SMTP is listening:
|
||||
|
||||
telnet localhost 10024
|
||||
Trying 127.0.0.1...
|
||||
Connected to localhost.
|
||||
Escape character is '^\]'.
|
||||
220 \[127.0.0.1\] ESMTP amavisd-new service ready
|
||||
^\]
|
||||
|
||||
Check on your /var/log/mail.log that everything goes well. If you raise the log level, you can check every step of the content filtering: spam check, virus check, etc. Don't forget to lower the log level after your checks!
|
||||
|
||||
On messages that go through the content filter you should see:
|
||||
|
||||
X-Spam-Level:
|
||||
X-Virus-Scanned: Debian amavisd-new at example.com
|
||||
X-Spam-Status: No, hits=-2.3 tagged\_above=-1000.0 required=5.0 tests=AWL, BAYES\_00
|
||||
X-Spam-Level:
|
||||
|
||||
**Note:** $sa\_tag\_level in /etc/amavis/conf.d/20-debian\_defaults must be lower than spam hit rating for the header to appear on the message. For troubleshooting set $sa\_tag\_level to -999
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
If the filtering is not happening, adding the following to /etc/amavis/conf.d/50-user may help:
|
||||
|
||||
@local\_domains\_acl = ( ".$mydomain" );
|
||||
|
||||
If you receive mail for other domains, add them to the list. This information was obtained from the Amavis-New FAQ [here](http://www.ijs.si/software/amavisd/#faq-spam).
|
||||
|
||||
If you see the following error in /var/log/syslog when amavisd is trying to scan a message:
|
||||
|
||||
amavis\[30807\]: (30807-01) (!!) ask\_av (ClamAV-clamd) FAILED - unexpected result: /var/lib/amavis/tmp/amavis-20070615T125025-30807/parts: lstat() failed. ERROR\\n
|
||||
|
||||
Try changing the permissions on /var/lib/amavis/tmp:
|
||||
|
||||
chmod -R 775 /var/lib/amavis/tmp
|
||||
|
||||
You can also change AllowSupplementaryGroups in /etc/clamav/clamd.conf:
|
||||
|
||||
AllowSupplementaryGroups true
|
||||
|
||||
Another way to trouble shoot errors associated with Amavisd-new, Spamassassin, Postfix, or Clamav is to restart all the services with Amavisd-new being the last one to start:
|
||||
|
||||
sudo /etc/init.d/postfix restart
|
||||
sudo /etc/init.d/spamassassin restart
|
||||
sudo /etc/init.d/clamav-daemon restart
|
||||
sudo /etc/init.d/amavis restart
|
||||
|
||||
Then check /var/log/mail.log and see if the error has gone away.
|
||||
|
||||
**Note**: $sa\_tag\_level in /etc/amavis/conf.d/20-debian\_defaults must be lower than spam hit rating for the header to appear on the message. For troubleshooting set $sa\_tag\_level to -999
|
||||
|
||||
## Amavis Performance
|
||||
|
||||
To increase the number of processes that amavisd-new uses above the default 2 edit the file /etc/amavis/conf.d/50-user inserting the line:
|
||||
|
||||
$max\_servers = X;
|
||||
|
||||
above the line:
|
||||
|
||||
#------------ Do not modify anything below this line -------------
|
||||
|
||||
where X is the number of processes you wish amavis to use.
|
||||
|
||||
Amend the following line in /etc/postfix/master.cf with the same value for the max\_procs (marked below as X)
|
||||
|
||||
smtp-amavis unix - - - - X smtp
|
||||
|
||||
Restart amavis and reload postfix's config
|
||||
|
||||
sudo /etc/init.d/amavis restart
|
||||
sudo postfix reload
|
||||
|
||||
You can check the configuration change has taken affect by running amavisd-nanny:
|
||||
|
||||
sudo amavisd-nanny
|
||||
|
||||
For guidance on how many processes to set this value to please see:
|
||||
|
||||
zcat /usr/share/doc/amavisd-new/README.performance.gz | less
|
||||
|
||||
and [http://www.ijs.si/software/amavisd/amavisd-new-magdeburg-20050519.pdf](http://www.ijs.si/software/amavisd/amavisd-new-magdeburg-20050519.pdf)
|
||||
|
||||
|
||||
**Note:** This guide has been tested on Ubuntu 7.10 (Gutsy Gibbon), Ubuntu 10.04 LTS Server (Lucid Lynx), Ubuntu 12.04.3 LTS (Precise Pangolin), Ubuntu 14.04.2 LTS (Trusty Tahr), and Ubuntu 20.04 LTS (Focal Fossa).
|
||||
|
||||
---
|
||||
+529
@@ -0,0 +1,529 @@
|
||||
---
|
||||
page-title: "Setting Up Amavis and ClamAV on Ubuntu Mail Server - LinuxBabe"
|
||||
url: https://www.linuxbabe.com/mail-server/postfix-amavis-spamassassin-clamav-ubuntu
|
||||
date: "2023-05-25 10:56:40"
|
||||
---
|
||||
This is part 11 in the Ubuntu mail server from scratch tutorial series. In this article, I will show you how to use **Amavis** and **ClamAV** to scan viruses in email messages.
|
||||
|
||||
**Amavis** (A Mail Virus Scanner) is a high-performance interface between a message transfer agent (MTA) such as **Postfix** and content filters. A content filter is a program that scans the headers and body of an email message, and usually takes some action based on what it finds. The most common examples are **ClamAV virus scanner** and **SpamAssassin**.
|
||||
|
||||
|
||||
|
||||
Amavis speaks standard SMTP protocol and can also use the Sendmail milter interface. It’s commonly used for
|
||||
|
||||
- virus-scanning by integrating with ClamAV (Clam AntiVirus)
|
||||
- spam-checking by integrating with SpamAssassin
|
||||
- DKIM signing and verification. (Actually, I prefer to use OpenDKIM for DKIM signing and verification.)
|
||||
|
||||
## Prerequisites
|
||||
|
||||
You should have completed at least [part 1 (Postfix SMTP server)](https://www.linuxbabe.com/mail-server/setup-basic-postfix-mail-sever-ubuntu) and [part 2 (Dovecot IMAP server)](https://www.linuxbabe.com/mail-server/secure-email-server-ubuntu-postfix-dovecot) of the Ubuntu mail server from scratch tutorial series. Note that if you used [iRedMail](https://www.linuxbabe.com/mail-server/ubuntu-20-04-iredmail-server-installation) or [Modoboa](https://www.linuxbabe.com/mail-server/email-server-ubuntu-18-04-modoboa) to set up your mail server, then Amavis and ClamAV are already installed and configured, so you don’t need to follow this tutorial.
|
||||
|
||||
**Warning**: Amavis and ClamAV require a fair amount of RAM. Make sure you have at least 1.3 GB free RAM on your server before installing Amavis and ClamAV. The whole mail server stack (Postfix, Dovecot, Amavis, ClamAV, SpamAssassin, OpenDKIM, MySQL/MariaDB, PostfixAdmin, and Roundcube Webmail) needs at least **3 GB** RAM to run smoothly. If your RAM runs out, you are going to have troubles like mail server going offline or unresponsive.
|
||||
|
||||
## Step 1: Install Amavis on Ubuntu
|
||||
|
||||
Amvis is available from the default Ubuntu repository, so run the following command to install it.
|
||||
|
||||
sudo apt install amavisd-new -y
|
||||
|
||||
Once installed, it automatically starts. You can check its status with:
|
||||
|
||||
systemctl status amavis
|
||||
|
||||
Output:
|
||||
|
||||
● amavis.service - LSB: Starts amavisd-new mailfilter
|
||||
Loaded: loaded (/etc/init.d/amavis; generated)
|
||||
Active: **active (running)** since Fri 2020-08-07 15:43:40 HKT; 1min 1s ago
|
||||
Docs: man:systemd-sysv-generator(8)
|
||||
Tasks: 3 (limit: 9451)
|
||||
Memory: 75.4M
|
||||
CGroup: /system.slice/amavis.service
|
||||
├─1794260 /usr/sbin/amavisd-new (master)
|
||||
├─1794263 /usr/sbin/amavisd-new (virgin child)
|
||||
└─1794264 /usr/sbin/amavisd-new (virgin child)
|
||||
|
||||
If it’s not running, you can start it with:
|
||||
|
||||
sudo systemctl start amavis
|
||||
|
||||
Enable auto-start at boot time.
|
||||
|
||||
sudo systemctl enable amavis
|
||||
|
||||
By default, it listen on *127.0.0.1:10024*, as can be seen with:
|
||||
|
||||
sudo netstat -lnpt | grep amavis
|
||||
|
||||
|
||||
|
||||
And it runs as the `amavis` user. To check the version number, run
|
||||
|
||||
amavisd-new -V
|
||||
|
||||
Sample output:
|
||||
|
||||
amavisd-new-2.11.0 (20160426)
|
||||
|
||||
To check the logs of Amavis, you can run
|
||||
|
||||
sudo journalctl -eu amavis
|
||||
|
||||
Viruses are commonly spread as attachments to email messages. Install the following packages for Amavis to extract and scan archive files in email messages such as `.7z`, `.cab`, `.doc`, `.exe`, `.iso`, `.jar`, and `.rar` files.
|
||||
|
||||
sudo apt install arj bzip2 cabextract cpio rpm2cpio file gzip lhasa nomarch pax rar unrar p7zip-full unzip zip lrzip lzip liblz4-tool lzop unrar-free
|
||||
|
||||
If you use Ubuntu 18.04, then also install the `ripole` package.
|
||||
|
||||
sudo apt install ripole
|
||||
|
||||
Note that if your server doesn’t use a fully-qualified domain name (FQDN) as the hostname, Amavis might fail to start. And the OS hostname might change, so it’s recommended to set a valid hostname directly in the Amavis configuration file.
|
||||
|
||||
sudo nano /etc/amavis/conf.d/05-node\_id
|
||||
|
||||
Find the following line.
|
||||
|
||||
#$myhostname = "mail.example.com";
|
||||
|
||||
Remove the comment character (#) and change `mail.example.com` to your real hostname.
|
||||
|
||||
$myhostname = "mail.linuxbabe.com";
|
||||
|
||||
Save and close the file. Restart Amavis for the changes to take effect.
|
||||
|
||||
sudo systemctl restart amavis
|
||||
|
||||
## Step 2: Integrate Postfix SMTP Server With Amavis
|
||||
|
||||
Amavisd-new works as an SMTP proxy. Email is fed to it through SMTP, processed, and fed back to the MTA through a new SMTP connection.
|
||||
|
||||
Edit the Postfix main configuration file.
|
||||
|
||||
sudo nano /etc/postfix/main.cf
|
||||
|
||||
Add the following line at the end of the file. This tells Postfix to turn on content filtering by sending every incoming email message to Amavis, which listens on *127.0.0.1:10024*.
|
||||
|
||||
content\_filter = smtp-amavis:\[127.0.0.1\]:10024
|
||||
|
||||
Also, add the following line.
|
||||
|
||||
smtpd\_proxy\_options = speed\_adjust
|
||||
|
||||
This will delay Postfix connection to content filter until the entire email message has been received, which can prevent content filters from wasting time and resources for slow SMTP clients.
|
||||
|
||||
Save and close the file. Then edit the `master.cf` file.
|
||||
|
||||
sudo nano /etc/postfix/master.cf
|
||||
|
||||
Add the following lines at the end of the file. This instructs Postfix to use a special SMTP client component called `smtp-amavis` to deliver email messages to Amavis. Please allow at least one whitespace character (tab or spacebar) before each `-o`. In postfix configurations, a preceding whitespace character means that this line is continuation of the previous line.
|
||||
|
||||
smtp-amavis unix - - n - 2 smtp
|
||||
-o syslog\_name=postfix/amavis
|
||||
-o smtp\_data\_done\_timeout=1200
|
||||
-o smtp\_send\_xforward\_command=yes
|
||||
-o disable\_dns\_lookups=yes
|
||||
-o max\_use=20
|
||||
-o smtp\_tls\_security\_level=none
|
||||
|
||||
Then add the following lines at the end of the file. This tells Postfix to run an additional smtpd daemon listening on *127.0.0.1:10025* to receive email messages back from Amavis.
|
||||
|
||||
127.0.0.1:10025 inet n - n - - smtpd
|
||||
-o syslog\_name=postfix/10025
|
||||
-o content\_filter=
|
||||
-o mynetworks\_style=host
|
||||
-o mynetworks=127.0.0.0/8
|
||||
-o local\_recipient\_maps=
|
||||
-o relay\_recipient\_maps=
|
||||
-o strict\_rfc821\_envelopes=yes
|
||||
-o smtp\_tls\_security\_level=none
|
||||
-o smtpd\_tls\_security\_level=none
|
||||
-o smtpd\_restriction\_classes=
|
||||
-o smtpd\_delay\_reject=no
|
||||
-o smtpd\_client\_restrictions=permit\_mynetworks,reject
|
||||
-o smtpd\_helo\_restrictions=
|
||||
-o smtpd\_sender\_restrictions=
|
||||
-o smtpd\_recipient\_restrictions=permit\_mynetworks,reject
|
||||
-o smtpd\_end\_of\_data\_restrictions=
|
||||
-o smtpd\_error\_sleep\_time=0
|
||||
-o smtpd\_soft\_error\_limit=1001
|
||||
-o smtpd\_hard\_error\_limit=1000
|
||||
-o smtpd\_client\_connection\_count\_limit=0
|
||||
-o smtpd\_client\_connection\_rate\_limit=0
|
||||
-o receive\_override\_options=no\_header\_body\_checks,no\_unknown\_recipient\_checks,no\_address\_mappings
|
||||
|
||||
Save and close the file. Restart Postfix for the changes to take effect.
|
||||
|
||||
sudo systemctl restart postfix
|
||||
|
||||
## Step 3: Integrate Amavis with ClamAV
|
||||
|
||||
Now that Postfix can pass incoming emails to Amavis, we need to install the ClamAV virus scanner and integrate it with Amavis, so incoming emails can be scanned by ClamAV.
|
||||
|
||||
Install ClamAV on Ubuntu.
|
||||
|
||||
sudo apt install clamav clamav-daemon
|
||||
|
||||
There will be two systemd services installed by ClamAV:
|
||||
|
||||
- `clamav-daemon.service`: the Clam AntiVirus userspace daemon
|
||||
- `clamav-freshclam.service`: the ClamAV virus database updater
|
||||
|
||||
First, check the status of `clamav-freshclam.service`.
|
||||
|
||||
systemctl status clamav-freshclam
|
||||
|
||||
|
||||
|
||||
As you can see, it’s active (running) and uses 217.6M RAM on my mail server. Then check the journal/log.
|
||||
|
||||
sudo journalctl -eu clamav-freshclam
|
||||
|
||||
Output:
|
||||
|
||||

|
||||
|
||||
Hint: If the above command doesn’t quit immediately, press the Q key to make it quit.
|
||||
|
||||
We can see that `freshclam` downloaded 3 virus databases. CVD stands for ClamAV Virus Database.
|
||||
|
||||
- daily.cvd
|
||||
- main.cvd
|
||||
- bytecode.cvd
|
||||
|
||||
However, `clamd` was not notified because freshclam can’t connect to clamd through `/var/run/clamav/clamd.ctl`. Check the status of `clamav-daemon.service`.
|
||||
|
||||
systemctl status clamav-daemon
|
||||
|
||||
Output:
|
||||
|
||||
|
||||
|
||||
As you can see, it failed to start because a condition wasn’t met. In the `/lib/systemd/system/clamav-daemon.service` file, there are two conditions:
|
||||
|
||||
ConditionPathExistsGlob=/var/lib/clamav/main.{c\[vl\]d,inc}
|
||||
ConditionPathExistsGlob=/var/lib/clamav/daily.{c\[vl\]d,inc}
|
||||
|
||||
The `clamav-daemon.service` failed to start because main.cvd and daily.cvd were not downloaded yet when it starts. So we just need to restart this service.
|
||||
|
||||
sudo systemctl restart clamav-daemon
|
||||
|
||||
Now it should be running. By the way, it uses 731.4M RAM on my mail server. If your mail server doesn’t have enough RAM left, the service will fail.
|
||||
|
||||
systemctl status clamav-daemon.service
|
||||
|
||||
|
||||
|
||||
The `clamav-freshclam.service` will check ClamAV virus database updates once per hour.
|
||||
|
||||
Now we need to turn on virus-checking in Amavis.
|
||||
|
||||
sudo nano /etc/amavis/conf.d/15-content\_filter\_mode
|
||||
|
||||
Uncomment the following lines to enable virus-checking.
|
||||
|
||||
#@bypass\_virus\_checks\_maps = (
|
||||
# \\%bypass\_virus\_checks, \\@bypass\_virus\_checks\_acl, \\$bypass\_virus\_checks\_re);
|
||||
|
||||
|
||||
|
||||
Save and close the file. There are lots of antivirus scanners in the `/etc/amavis/conf.d/15-av_scanners` file. ClamAV is the default. Amavis will call ClamAV via the `/var/run/clamav/clamd.ctl` Unix socket. We need to add user `clamav` to the `amavis` group.
|
||||
|
||||
sudo adduser clamav amavis
|
||||
|
||||
Then restart Amavis and ClamAV daemon for the changes to take effect.
|
||||
|
||||
sudo systemctl restart amavis clamav-daemon
|
||||
|
||||
Check the logs.
|
||||
|
||||
sudo journalctl -eu amavis
|
||||
|
||||
You can see that Amavis is now using ClamAV to scan viruses.
|
||||
|
||||
Aug 08 17:26:19 mail.linuxbabe.com amavis\[1233432\]: Using primary internal av scanner code for ClamAV-clamd
|
||||
Aug 08 17:26:19 mail.linuxbabe.com amavis\[1233432\]: Found secondary av scanner ClamAV-clamscan at /usr/bin/clamscan
|
||||
|
||||
Now if you send an email from other mail servers like Gmail to your own mail server and check the email headers, you can find a line like below, which indicates this email has been scanned by Amavis.
|
||||
|
||||
X-Virus-Scanned: Debian amavisd-new at linuxbabe.com
|
||||
|
||||
You should also check the mail log (`/var/log/mail.log`) to find if there are any errors.
|
||||
|
||||
## Step 4: Use A Dedicated Port for Email Submissions
|
||||
|
||||
ClamAV can scan both incoming and outgoing emails now. Amavis listens on port 10024 for both incoming and outgoing email messages. However, it’s a good practice to use a different port such as 10026 for email submissions from authenticated users. Edit the Amavis configuration file.
|
||||
|
||||
sudo nano /etc/amavis/conf.d/50-user
|
||||
|
||||
Custom settings should be added between the `use strict;` and `1;` line. By default, Amavis only listens on port 10024. Add the following line to make it also listen on port 10026.
|
||||
|
||||
$inet\_socket\_port = \[10024,10026\];
|
||||
|
||||
Then add the following line, which sets the “ORIGINATING” policy for port 10026.
|
||||
|
||||
$interface\_policy{'10026'} = 'ORIGINATING';
|
||||
|
||||
Next, add the following lines, which define the “ORIGINATING” policy.
|
||||
|
||||
$policy\_bank{'ORIGINATING'} = { # mail supposedly originating from our users
|
||||
originating => 1, # declare that mail was submitted by our smtp client
|
||||
allow\_disclaimers => 1, # enables disclaimer insertion if available
|
||||
|
||||
# notify administrator of locally originating malware
|
||||
virus\_admin\_maps => \["virusalert\\@$mydomain"\],
|
||||
spam\_admin\_maps => \["virusalert\\@$mydomain"\],
|
||||
warnbadhsender => 1,
|
||||
|
||||
# force MTA conversion to 7-bit (e.g. before DKIM signing)
|
||||
smtpd\_discard\_ehlo\_keywords => \['8BITMIME'\],
|
||||
bypass\_banned\_checks\_maps => \[1\], # allow sending any file names and types
|
||||
terminate\_dsn\_on\_notify\_success => 0, # don't remove NOTIFY=SUCCESS option
|
||||
$undecipherable\_subject\_tag = '\*\*\*Encrypted Message\*\*\*',
|
||||
};
|
||||
|
||||
Save and close the file. Restart Amavis.
|
||||
|
||||
sudo systemctl restart amavis
|
||||
|
||||
Check its status to see if the restart is successful.
|
||||
|
||||
systemctl status amavis
|
||||
|
||||
Next, edit the Postfix master configuration file.
|
||||
|
||||
sudo nano /etc/postfix/master.cf
|
||||
|
||||
Add the following line to the `submission` service, so emails from authenticated SMTP clients will be passed to Amavis listening on port 10026. This line will override (`-o`) the `content_filter` parameter in `/etc/postfix/main.cf` file that we added in step 2.
|
||||
|
||||
-o content\_filter=smtp-amavis:\[127.0.0.1\]:10026
|
||||
|
||||
Like this:
|
||||
|
||||
|
||||
|
||||
If you have enabled the `smtps` service for Microsoft Outlook users, then you also need to add this line to the `smtps` service.
|
||||
|
||||
|
||||
|
||||
Save and close the file. Restart Postfix for the changes to take effect.
|
||||
|
||||
sudo systemctl restart postfix
|
||||
|
||||
Check its status to see if the restart is successful.
|
||||
|
||||
systemctl status postfix
|
||||
|
||||
## Step 5: Receive Virus Alert
|
||||
|
||||
You need to create an email address `virusalert@your-domain.com` to receive virus alerts from ClamAV. Note that you should create a real email address instead of creating an alias. ClamAV will bypass Postfix and submit alert emails directly to Dovecot, which isn’t configured to query aliases in the PostfixAdmin database.
|
||||
|
||||
## Spam Filtering in Amavis
|
||||
|
||||
**Note**: If you have followed my [SpamAssassin tutorial](https://www.linuxbabe.com/mail-server/block-email-spam-check-header-body-with-postfix-spamassassin), you don’t need to enable spam-checking in Amavis. If you enable it, each email will be checked twice by SpamAssassin.
|
||||
|
||||
To enable spam-checking in Amavis, install SpamAssassin and related packages.
|
||||
|
||||
sudo apt install spamassassin libnet-dns-perl libmail-spf-perl pyzor razor
|
||||
|
||||
Edit an Amavis configuration file.
|
||||
|
||||
sudo nano /etc/amavis/conf.d/15-content\_filter\_mode
|
||||
|
||||
Uncomment the following lines to enable spam-checking.
|
||||
|
||||
#@bypass\_spam\_checks\_maps = (
|
||||
# \\%bypass\_spam\_checks, \\@bypass\_spam\_checks\_acl, \\$bypass\_spam\_checks\_re);
|
||||
|
||||
Save and close the file. Then restart Amavis.
|
||||
|
||||
sudo systemctl restart amavis
|
||||
|
||||
## DKIM in Amavis
|
||||
|
||||
Two common pieces of software that can do DKIM signing and verification on Linux are OpenDKIM and Amavis. I prefer to use [OpenDKIM](https://www.linuxbabe.com/mail-server/setting-up-dkim-and-spf) because it works better with [OpenDMARC](https://www.linuxbabe.com/mail-server/opendmarc-postfix-ubuntu). So I won’t explain how to DKIM sign your email in Amavis.
|
||||
|
||||
By default, Amavis can verify the DKIM signature of incoming email messages. If you have OpenDKIM running on your mail server, then you can disable DKIM verification in Amavis.
|
||||
|
||||
sudo nano /etc/amavis/conf.d/21-ubuntu\_defaults
|
||||
|
||||
Find the following line and change `1` to `0`, so Amavis won’t verify DKIM signatures.
|
||||
|
||||
$enable\_dkim\_verification = 1;
|
||||
|
||||
Save and close the file. Then restart Amavis.
|
||||
|
||||
sudo systemctl restart amavis
|
||||
|
||||
When receiving incoming emails, Postfix will call OpenDKIM via the sendmail milter interface to verify DKIM signatures, then pass the email to Amavis for virus-checking. When sending outgoing emails, Postfix will call OpenDKIM to sign the emails, then pass them to Amavis for virus-checking.
|
||||
|
||||
## Improving Amavis Performance
|
||||
|
||||
By default, Amavis runs 2 processes. If you see the following lines in the mail log (`/var/log/mail.log`), it means Amavis can’t process emails fast enough.
|
||||
|
||||
postfix/qmgr\[1619188\]: warning: mail for \[127.0.0.1\]:10024 is using up 4001 of 4008 active queue entries
|
||||
postfix/qmgr\[1619188\]: warning: you may need to reduce smtp-amavis connect and helo timeouts
|
||||
postfix/qmgr\[1619188\]: warning: so that Postfix quickly skips unavailable hosts
|
||||
postfix/qmgr\[1619188\]: warning: you may need to increase the main.cf minimal\_backoff\_time and maximal\_backoff\_time
|
||||
postfix/qmgr\[1619188\]: warning: so that Postfix wastes less time on undeliverable mail
|
||||
mail postfix/qmgr\[1619188\]: warning: you may need to increase the master.cf smtp-amavis process limit
|
||||
mail postfix/qmgr\[1619188\]: warning: please avoid flushing the whole queue when you have
|
||||
mail postfix/qmgr\[1619188\]: warning: lots of deferred mail, that is bad for performance
|
||||
|
||||
To improve performance, edit Amavis configuration file.
|
||||
|
||||
sudo nano /etc/amavis/conf.d/50-user
|
||||
|
||||
Add the following line in the file between the `use strict;` and `1;` line. This will make Amavis run 4 processes. If you have 10 CPU cores, you can change 4 to 10. Note that running more than 10 Amavis processes has little effect on performance.
|
||||
|
||||
$max\_servers = 4;
|
||||
|
||||
Save and close the file. Then edit the Postifx master configuration file.
|
||||
|
||||
sudo nano /etc/postfix/master.cf
|
||||
|
||||
Find the `smtp-amavis` service definition, and change the process limit from 2 to 4.
|
||||
|
||||
smtp-amavis unix - - n - **4** smtp
|
||||
-o syslog\_name=postfix/amavis
|
||||
-o smtp\_data\_done\_timeout=1200
|
||||
-o smtp\_send\_xforward\_command=yes
|
||||
-o disable\_dns\_lookups=yes
|
||||
-o max\_use=20
|
||||
-o smtp\_tls\_security\_level=none
|
||||
|
||||
Save and close the file. Then restart Amavis and Postfix for the changes to take effect.
|
||||
|
||||
sudo systemctl restart amavis postfix
|
||||
|
||||
Now run the following command. You should see that there are 4 Amavis processes now.
|
||||
|
||||
sudo amavisd-nanny
|
||||
|
||||

|
||||
|
||||
Press `Ctrl+C` to stop amavisd-nanny.
|
||||
|
||||
## Skip Virus-Checking for Your Newsletters
|
||||
|
||||
If you [use your mail server to send newsletters](https://www.linuxbabe.com/ubuntu/install-mautic-self-hosted-email-marketing-ubuntu-20-04), and you enable Amavis and ClamAV, then lots of CPU and RAM resources will be used for virus-checking when you send newsletters to your subscribers. It could make your mail server unresponsive. You can skip virus-checking for your newsletters by using the method below.
|
||||
|
||||
Edit the Postfix master configuration file.
|
||||
|
||||
sudo nano /etc/postfix/master.cf
|
||||
|
||||
Add the following lines at the beginning of this file. This will enable `smtpd` on port 2525 of the localhost and it can accept client connections initiated from the same server. If there’s another process listening on port 2525, you can change 127.0.0.1:2525 to something else, like 127.0.0.1:2552. Note that the `content_filter` parameter is set to `none`, which means emails won’t be scanned by ClamAV.
|
||||
|
||||
127.0.0.1:2525 inet n - - - 1 smtpd
|
||||
-o syslog\_name=postfix/2525
|
||||
-o postscreen\_greet\_action=ignore
|
||||
-o content\_filter=
|
||||
|
||||
Then add the following lines at the end of this file. Replace 12.34.56.78 with the mail server’s public IP address. This will create another Postfix submission daemon listening on port 10587. This is for client connections from another server.
|
||||
|
||||
12.34.56.78:10587 inet n - y - - smtpd
|
||||
-o syslog\_name=postfix/10587
|
||||
-o smtpd\_tls\_security\_level=encrypt
|
||||
-o smtpd\_tls\_wrappermode=no
|
||||
-o smtpd\_sasl\_auth\_enable=yes
|
||||
-o smtpd\_relay\_restrictions=permit\_sasl\_authenticated,reject
|
||||
-o smtpd\_recipient\_restrictions=permit\_mynetworks,permit\_sasl\_authenticated,reject
|
||||
-o smtpd\_sasl\_type=dovecot
|
||||
-o smtpd\_sasl\_path=private/auth
|
||||
-o content\_filter=
|
||||
|
||||
Save and close the file. Then Restart postfix.
|
||||
|
||||
sudo systemctl restart postfix
|
||||
|
||||
If your newsletter application runs on the mail server, then specify `127.0.0.1:2525` as the SMTP host, without SMTP authentication. If your newsletter application runs on a different server, then specify `12.34.56.78:10587` as the SMTP host, with SMTP authentication.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
If your Postfix SMTP server can’t send outgoing emails, and you find the following error message in the mail log (`/var/log/mail.log`),
|
||||
|
||||
relay=none, delay=239, delays=239/0.04/0/0, dsn=4.3.0, status=deferred (server unavailable or unable to receive mail)
|
||||
|
||||
it could be that amavis is not running, so you need to check its status:
|
||||
|
||||
sudo systemctl status amavis
|
||||
|
||||
You can restart it with:
|
||||
|
||||
sudo systemctl restart amavis
|
||||
|
||||
Another cause for this error is that you are enforcing TLS connection for Postfix when sending outgoing emails with the following setting in the `/etc/postfix/main.cf` file.
|
||||
|
||||
smtp\_tls\_security\_level = enforce
|
||||
|
||||
Since Postfix can’t establish TLS connection to Amavis, so the email is deferred. You should use the following setting.
|
||||
|
||||
smtp\_tls\_security\_level = may
|
||||
|
||||
Then restart Postfix.
|
||||
|
||||
## Using ClamAV to Scan Virus for the Linux File System
|
||||
|
||||
While the main topic of this article is virus scanning for emails, since ClamAV is installed on the server, why not use it to scan viruses for other files?
|
||||
|
||||
First, edit the ClamAV configuration file.
|
||||
|
||||
sudo nano /etc/clamav/clamd.conf
|
||||
|
||||
Find the following line:
|
||||
|
||||
MaxDirectoryRecursion 15
|
||||
|
||||
The default maximum depth directories scanned by ClamAV is 15, you probably want to change it to a bigger number to avoid the “directory recursion limit reached” warning.
|
||||
|
||||
MaxDirectoryRecursion 30
|
||||
|
||||
Then find the following two lines.
|
||||
|
||||
MaxScanSize 100M
|
||||
MaxFileSize 25M
|
||||
|
||||
The default max scan size is 100M and the max file size is 25M. It’s likely that your server has files of more than 100M. The default config will produce the following errors when the file size exceeds the limit.
|
||||
|
||||
LibClamAV Warning: PNG: Unexpected early end-of-file.
|
||||
LibClamAV Warning: cli\_scanxz: decompress file size exceeds limits - only scanning 27262976 bytes
|
||||
|
||||
You can increase the scan size like:
|
||||
|
||||
MaxScanSize 2048M
|
||||
MaxFileSize 2048M
|
||||
|
||||
Linux has many special files in `/proc/`, `/sys/`, `/run/`, `/dev/`, `/snap/` and `/var/lib/lxcfs/cgroup/` directory that should not be scanned, so you need to exclude them in ClamAV by adding the following lines at the end of this file.
|
||||
|
||||
ExcludePath ^/proc
|
||||
ExcludePath ^/sys
|
||||
ExcludePath ^/run
|
||||
ExcludePath ^/dev
|
||||
ExcludePath ^/snap
|
||||
ExcludePath ^/var/lib/lxcfs/cgroup
|
||||
|
||||
Save and close the file. Then restart `clamav-daemon.service` for the changes to take effect.
|
||||
|
||||
sudo systemctl restart clamav-daemon
|
||||
|
||||
Wait a few seconds for `clamav-daemon.service` to finish restarting. Next, you can start scanning with:
|
||||
|
||||
sudo clamdscan --fdpass /
|
||||
|
||||
This will scan the entire Linux file system, excluding the directories we mentioned earlier. To make ClamAV scan the file sytem automatically, edit the root user’s crontab file.
|
||||
|
||||
sudo crontab -e
|
||||
|
||||
Add the following line to this file. ClamAV will scan the entire file system at 5:10AM every day.
|
||||
|
||||
10 5 \* \* \* /usr/bin/clamdscan --fdpass /
|
||||
|
||||
Save and close the file.
|
||||
|
||||
**Hint #1**: There’s another utility called `clamscan` that can also be used for virus scanning. However, `clamscan` doesn’t use the virus definition database that’s already loaded in memory. It will load a separate copy of virus definition database into memory again, wasting server resources.`clamscan` is also slower than `clamdscan`, so I don’t recommend it.
|
||||
|
||||
**Hint #2**: If there are a huge number of files on your server, `clamdscan` will use lots of CPU resources.
|
||||
|
||||
## Wrapping Up
|
||||
|
||||
I hope this tutorial helped you set up Amavis and ClamAV on Ubuntu mail server. As always, if you found this post useful, then [subscribe to our free newsletter](https://newsletter.linuxbabe.com/subscription/wkeY5d6pg) to get more tips and tricks. Take care 🙂
|
||||
+107
@@ -0,0 +1,107 @@
|
||||
---
|
||||
page-title: "50 AI/ChatGPT Prompts for Fitness Professionals - IDEA Health & Fitness Association"
|
||||
url: https://www.ideafit.com/group-fitness/50-ai-chatgpt-prompts-for-fitness-professionals/
|
||||
date: "2023-06-28 15:23:38"
|
||||
---
|
||||
|
||||
> has some experience with weightlifting but is looking for a training program that is tailored to his sport. Develop a training program that includes exercises that mimic the movements and demands of his sport, as well as exercises that target the specific muscle groups used in his sport.
|
||||
|
||||
---
|
||||
|
||||
Are you curious about using AI/ChatGPT prompts to inspire your exercise and class design? As a fitness professional, you know that creating personalized programs and classes for your clients is crucial for their success. However, with so many variables to consider, such as individual goals, fitness levels and limitations, designing effective plans can be time-consuming and challenging. [Artificial Intelligence](https://en.wikipedia.org/wiki/Artificial_intelligence) (AI) and Chatbots like ChatGPT can help you streamline your work and enhance clients’ experiences.
|
||||
|
||||
Here are just a few benefits of using AI/ChatGPT prompts to create classes and programs for your clients and participants, followed by 50 examples:
|
||||
|
||||
**It saves time.** With AI/ChatGPT, you can automate the process of creating workout plans and class structures, freeing up your time to focus on other areas of your business.
|
||||
|
||||
**You can personalize it**. You can analyze data such as client goals, fitness levels and preferences to create highly personalized workout plans and classes that are tailored to each individual’s needs.
|
||||
|
||||
**It provides adaptability**. As clients progress, you can use prompts to adjust their programs accordingly, ensuring that they continue to challenge themselves and see results.
|
||||
|
||||
**It’s efficient**. You can create programs and classes faster and more efficiently, allowing you to take on more clients and grow your business.
|
||||
|
||||
**You encourage engagement**. ChatGPT prompts can include interactive elements such as quizzes and surveys to keep clients engaged and motivated throughout their fitness journeys.
|
||||
|
||||
Using prompts to create classes and programs is an innovative and efficient way to enhance your clients’ experiences and grow your business. By automating the process of program design and personalizing workouts based on data, you can help your clients achieve their fitness goals faster and with less stress.
|
||||
|
||||
[*Use IDEA’s educational library to further customize your programs and classes.*](https://pro.ideafit.com/fitness-products?_gl=1*c4unvn*_gcl_aw*R0NMLjE2ODAxMDM3ODMuQ2owS0NRand3NC1oQmhDdEFSSXNBQzlnUjNhRFRlUXRJUE5rS2tlTlF1ajJZRWtHQ05rMzZPVERYV3REanFQZlBvRXJzNWZDcXh0SmdQQWFBako2RUFMd193Y0I.&)
|
||||
|
||||
## What is a ChatGPT Prompt?
|
||||
|
||||
In the context of AI, a prompt is a piece of text or a question that a user provides to an AI system, such as ChatGPT, to initiate a response or generate a specific output. A novice interacting with ChatGPT can think of a prompt as a request for information or a prompt for a conversation. For example, you can input “Can you tell me about the weather today?” to receive a response. The quality of the response generated by ChatGPT is often dependent on the clarity and specificity of the prompt provided by the user.
|
||||
|
||||
All you have to do is sign up for a [free account](https://chat.openai.com/) and copy and paste the prompts below, refining as needed to inform your program and class design.
|
||||
|
||||
## 50 Al/ChatGPT Prompts
|
||||
|
||||
If you’re a personal trainer or group fitness instructor looking to take your business to the next level, we’ve created 50 AI/ChatGPT prompts to get you going, 25 for personal trainers and 25 for group fitness instructors. Keep in mind that these are still pretty general, and you should use them in concert with your own knowledge about the client. The more detailed the prompt, the better, and no one knows program or class design like you do.
|
||||
|
||||
Always rely on your education and resources from IDEA and other fitness industry organizations. This is a great tool to add to your toolbox, but it’s not going to do all the work for you!
|
||||
|
||||

|
||||
|
||||
## Al/ChatGPT Prompts for Personal Trainers
|
||||
|
||||
1. John is a man in his 30s who wants to improve his athletic performance in a specific sport. He has some experience with weightlifting but is looking for a training program that is tailored to his sport. Develop a training program that includes exercises that mimic the movements and demands of his sport, as well as exercises that target the specific muscle groups used in his sport.
|
||||
2. Cecelia is a woman in her 40s who wants to build strength and muscle tone but has limited access to gym equipment. Develop a training program that uses bodyweight exercises, resistance bands and other portable equipment to help her build strength and muscle tone.
|
||||
3. James is a man in his 50s who wants to improve his overall fitness and reduce his risk of chronic diseases such as diabetes and heart disease. He has some experience with exercise but is looking for a more structured training program. Develop a training program that includes a mix of cardiovascular and strength training exercises and also includes a nutrition plan that emphasizes healthy eating habits.
|
||||
4. Margie is a woman in her 60s who wants to improve her bone density and reduce her risk of osteoporosis. She has some experience with weightlifting but is looking for a training program that is tailored to her specific needs. Develop a training program that includes resistance training exercises that target the bones, as well as exercises that improve balance and flexibility.
|
||||
5. Clarence is a man in his 70s who wants to maintain his muscle mass and independence as he ages. He has some experience with exercise but is looking for a training program that is safe and effective for his age group. Develop a training program that includes exercises that target the major muscle groups, as well as exercises that improve balance and mobility.
|
||||
6. Jay is a non-binary college student who wants to increase their overall fitness and strength. They have access to a gym but is unsure of how to create an effective workout plan. Develop a training program that focuses on resistance training and incorporates a variety of exercises that target different muscle groups.
|
||||
7. Miranda is a woman in her 50s who wants to improve her posture and reduce back pain. She spends most of her day sitting at a desk and has developed poor posture habits. Develop a training program that includes exercises that target the muscles involved in maintaining good posture, such as the back and core muscles, and also includes mobility and flexibility exercises.
|
||||
8. Tyrone is a man in his 40s who has recently been diagnosed with high blood pressure. He wants to improve his cardiovascular health and lower his blood pressure through exercise. Develop a training program that includes low-impact exercises, such as walking or cycling, and incorporates interval training and strength training exercises to improve his cardiovascular health.
|
||||
9. Tara is a woman in her 20s who wants to improve her flexibility and balance. She has some experience with yoga but wants to try new exercises that challenge her body. Develop a training program that incorporates exercises such as balance boards, resistance bands and foam rollers to improve her flexibility and balance.
|
||||
10. Glen is a man in his 30s who wants to increase his endurance and prepare for a long-distance running event. He has some experience with running but wants to develop a more structured training plan. Develop a training program that includes a mix of distance running, interval training and strength training exercises to help him build endurance and reduce his risk of injury.
|
||||
11. Karen is a woman in her 40s who wants to improve her overall fitness and lose weight. She has tried several diets in the past without success and is looking for a more sustainable approach. Develop a training program that includes a mix of cardiovascular and strength training exercises and also includes a nutrition plan that emphasizes whole, nutrient-dense foods.
|
||||
12. Stan is a man in his 50s who wants to improve his flexibility and mobility. He has some experience with yoga and Pilates but wants to try new exercises that challenge his body. Develop a training program that incorporates exercises such as foam rolling, dynamic stretching and yoga poses to improve his flexibility and mobility.
|
||||
13. Sandra is a woman in her 60s who wants to improve her balance and reduce her risk of falls. She has some experience with weightlifting but is looking for new exercises that can help her achieve her goals. Develop a training program that includes exercises that target the muscles involved in balance and stability, such as balance boards and single-leg exercises, and also includes flexibility and mobility exercises.
|
||||
14. Vin is a man in his 70s who wants to improve his overall fitness and maintain his independence as he ages. He has some experience with resistance training but is looking for new exercises that can help him achieve his goals. Develop a training program that includes low-impact exercises, such as walking or cycling, and incorporates interval training and strength training exercises to improve his overall fitness.
|
||||
15. Flo is a woman in her 80s who wants to maintain her mobility and independence as she ages. She has some experience with yoga and Pilates but is looking for new exercises that can help her achieve her goals. Develop a training program that includes exercises that target the muscles involved in mobility and balance, such as standing balance exercises and resistance band exercises, and also includes flexibility and mobility exercises.
|
||||
16. Laquetia is a middle-aged woman who wants to improve her flexibility and mobility. She is interested in learning yoga and Pilates. Design a training program that focuses on these disciplines and helps her achieve her goals.
|
||||
17. Conor is a young athlete who wants to build muscle mass and strength. He has some experience with weightlifting and is willing to follow a strict diet plan. Develop a training program that includes compound exercises and progressive overload principles to help him reach his goals.
|
||||
18. Tamara is a busy professional who wants to lose weight and improve her cardiovascular health. She enjoys running but struggles to find the time to exercise regularly. Develop a training program that includes high-intensity interval training and provides a flexible schedule to accommodate her busy lifestyle.
|
||||
19. Finn is an older man who has recently recovered from a hip replacement surgery. He wants to regain his strength and mobility, but he is unsure of what exercises are safe for him to perform. Develop a training program that focuses on low-impact exercises, balance training and flexibility exercises to help him regain his strength and mobility safely.
|
||||
20. Jazelle is a young woman who wants to prepare for a fitness competition. She has experience with weightlifting but wants to improve her overall physique and increase her endurance. Develop a training program that includes a mix of resistance training, cardio and flexibility exercises and also includes a nutrition plan that supports her competition goals.
|
||||
21. Maria Elena is a teenager who wants to improve her overall fitness and coordination. She is interested in trying different types of physical activities, such as rock climbing and martial arts. Develop a training program that includes a variety of activities that promote cardiovascular health, strength, and coordination, and is tailored to her age and fitness level.
|
||||
22. Rosa is a woman in her 40s who has never exercised before. She is overweight and wants to improve her health and fitness levels. Develop a training program that includes low-impact exercises and provides a gradual progression to help her build endurance and strength over time.
|
||||
23. Jesus is a man in his 50s who wants to improve his golf game. He has some experience with weightlifting but wants to focus on exercises that will help him increase his power and flexibility on the golf course. Develop a training program that includes exercises that target the muscles involved in the golf swing and improve flexibility and mobility.
|
||||
24. Xi is a woman in her 30s who has just given birth to her first child. She wants to regain her pre-pregnancy fitness levels and also improve her overall strength and endurance. Develop a training program that includes postpartum-specific exercises, such as pelvic floor strengthening and diastasis recti exercises, as well as cardiovascular and strength training exercises that are safe for new mothers.
|
||||
25. Walter is a man in his 60s who wants to improve his balance and reduce his risk of falls. He has some experience with yoga and Pilates but wants to try new exercises that can help him achieve his goals. Develop a training program that includes exercises that target the muscles involved in balance and stability, such as standing balance exercises and single-leg exercises.
|
||||
|
||||
*[See also: Can an AI App Help us Eat Better?](https://www.ideafit.com/nutrition/can-an-ai-app-help-us-eat-better-fitgenie-wants-to-try/)*
|
||||
|
||||

|
||||
|
||||
## Al/ChatGPT Prompts for Group Fitness Instructors
|
||||
|
||||
1. Design a kettlebell training class for individuals in their 30s and 40s who are looking to improve strength, endurance and overall fitness.
|
||||
2. Create a hiking fitness class for individuals in their 50s and above, incorporating uphill and downhill walks that improve cardiovascular health, leg strength and overall mobility.
|
||||
3. Develop a Zumba class for teenagers ages 13-17, incorporating high-energy dance movements that improve coordination, rhythm, and overall fitness.
|
||||
4. Design a functional fitness class for individuals in their 60s and above, incorporating exercises that improve balance, flexibility, and overall strength.
|
||||
5. Create a cardio sculpting class for individuals in their 20s and 30s, incorporating cardio and strength training exercises that target specific muscle groups and promote overall fitness.
|
||||
6. Create a barre class for beginners in their 20s and 30s, focusing on toning and sculpting the body while improving flexibility and balance.
|
||||
7. Design a cardio kickboxing class for individuals with physical disabilities, emphasizing modified exercises that promote cardiovascular health and full-body engagement.
|
||||
8. Develop a meditation and mindfulness class for individuals experiencing high levels of stress or anxiety, incorporating breathing techniques and guided meditation to promote relaxation and mental clarity.
|
||||
9. Create a family-friendly fitness class for parents and their young children, incorporating games and exercises that promote physical activity and family bonding.
|
||||
10. Design a suspension training class for seniors in their 70s and above, emphasizing functional exercises that improve strength, balance and overall mobility.
|
||||
11. Develop a cycling class for individuals with cardiovascular disease, incorporating low-impact exercises that improve cardiovascular health without putting stress on the joints.
|
||||
12. Create a powerlifting class for individuals in their 40s and 50s who are looking to build strength and muscle mass.
|
||||
13. Design a restorative yoga class for individuals recovering from injuries or surgery, emphasizing gentle stretches and poses that promote healing and relaxation.
|
||||
14. Develop a circuit training class for firefighters or other first responders, incorporating exercises that improve cardiovascular fitness, strength and endurance.
|
||||
15. Create a cardio dance class for individuals with Parkinson’s disease, emphasizing movements that promote balance, coordination and overall mobility.
|
||||
16. Design a high-intensity interval training (HIIT) class for busy professionals in their 30s who are looking to burn fat and improve cardiovascular fitness.
|
||||
17. Create a low-impact aerobics class for seniors in their 60s and above, focusing on improving balance, flexibility and overall mobility.
|
||||
18. Develop a yoga class for pregnant women in their second trimester, emphasizing postures that alleviate back pain and promote relaxation.
|
||||
19. Design a kickboxing class for teenagers ages 14-18, incorporating cardio and strength training to build endurance and confidence.
|
||||
20. Create a dance fitness class for adults in their 40s who are looking for a fun and effective way to lose weight and tone muscles.
|
||||
21. Develop a water aerobics class for individuals with arthritis or other joint conditions, emphasizing low-impact exercises that improve range of motion and reduce pain.
|
||||
22. Design a boot camp-style workout for postpartum mothers who are looking to regain their pre-pregnancy strength and stamina.
|
||||
23. Create a Pilates class for office workers in their 20s and 30s, focusing on core stability and posture correction to alleviate back pain caused by sitting all day.
|
||||
24. Develop a strength training class for women in their 50s and above, emphasizing exercises that improve bone density and muscle mass to prevent age-related muscle loss.
|
||||
25. Design a suspension training class for athletes or fitness enthusiasts in their 20s and 30s, incorporating functional exercises that improve athletic performance and overall fitness.
|
||||
|
||||
*[See also: Providing Great Customer Service in the Digital Age.](https://www.ideafit.com/personal-training/providing-excellent-customer-service-in-the-digital-age/)*
|
||||
|
||||
Remember that AI/ChatGPT prompts aren’t going to do all the work for you! It’s important to stay up to date with your [continuing education credits](https://pro.ideafit.com/fitness-products?_gl=1*3tmdon*_gcl_aw*R0NMLjE2ODAxMDM3ODMuQ2owS0NRand3NC1oQmhDdEFSSXNBQzlnUjNhRFRlUXRJUE5rS2tlTlF1ajJZRWtHQ05rMzZPVERYV3REanFQZlBvRXJzNWZDcXh0SmdQQWFBako2RUFMd193Y0I.&) and stay engaged in the fitness industry community so that you can remain current with all the research and trends.
|
||||
|
||||
*When you buy something using the retail links in our content, we may earn a small commission. IDEA Health and Fitness Association does not accept money for editorial reviews. Read more about our [Terms & Conditions](https://pro.ideafit.com/terms-conditions? "https://pro.ideafit.com/terms-conditions") and our [Privacy Policy](https://www.ideafit.com/privacy-policy/ "https://www.ideafit.com/privacy-policy/").*
|
||||
+206
@@ -0,0 +1,206 @@
|
||||
---
|
||||
page-title: "8 Best ChatGPT Uses for Cyclists: Next Level Cycling AI Assistant"
|
||||
url: https://www.bicycle-guider.com/chat-gpt-uses-for-cyclists/
|
||||
date: "2023-06-28 15:27:30"
|
||||
---
|
||||
We are reader-supported. We may earn an affiliate commission when you buy through the links on our site. [Read More...](https://www.bicycle-guider.com/about-and-contact/#affiliate)
|
||||
|
||||
|
||||
|
||||
If you’ve kept up with the news over the past weeks, you’ll undoubtedly have heard about OpenAI’s ChatGPT and some of the extraordinary things it’s being used for (or the controversies it has created).
|
||||
|
||||
It can answer questions about complex topics, summarize information, troubleshoot issues, and much more.
|
||||
|
||||
While the program has plenty of limitations at this **early stage of its development**, it’s still valuable if you know how to ask the right questions and understand its shortcomings.
|
||||
|
||||
We’ve decided to go down the AI rabbit hole, delve deeper into ChatGPT’s numerous functions, and see how helpful it can be for cyclists.
|
||||
|
||||
So here are eight applications of ChatGPT that we liked the most and, as cyclists, definitely plan to use again.
|
||||
|
||||
## What Is ChatGPT and How Does It Work?
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/chatgpt-weather-1-1.jpg)ChatGPT is a computer program, also known as a large language model. It functions like a chatbot, mimicking human conversation; you ask questions, and it answers. It can answer questions, create content, summarize vast swaths of information, and debug computer code.
|
||||
|
||||
This language model is a type of artificial intelligence (AI) trained using enormous amounts of text data and human feedback.
|
||||
|
||||
> During human training, the AI is given feedback on tasks to improve future results and allow the program to learn and improve more quickly and effectively.
|
||||
|
||||
The way the model is programmed and trained means it can understand everyday language and accurately **answer the questions you pose, much like a human would**.
|
||||
|
||||
The system can also learn from previous interactions to improve future answers and make them more relevant. Check out the screenshot above for an example of how it works (the degrees are in celsius).
|
||||
|
||||
This ability to understand context and improve over time makes ChatGPT and large language models so revolutionary. For example, it’s already capable of answering university-level test questions better than the average student.
|
||||
|
||||
### What Are the Practical Uses of ChatGPT?
|
||||
|
||||
ChatGPT has enormous potential for use in both commercial and private contexts.
|
||||
|
||||
For individuals, it can be a personal assistant, organize our calendar, set reminders, schedule appointments, or create itineraries for work or travel.
|
||||
|
||||
> It can help cyclists research and compare different products, develop meal or training plans, or provide information or instructions on specific bike-related topics.
|
||||
|
||||
The examples above barely scratch the surface of what AI will do for us in the coming months and years.
|
||||
|
||||
### How to Use ChatGPT: Formulating and Refining Prompts
|
||||
|
||||
Firstly, you must visit [OpenAI’s website](https://chat.openai.com/) and set up an account. As of publication (April 2023), ChatGPT only has access to the information published online until September 2021.
|
||||
|
||||
However, you can also access the program on Microsoft’s Edge web browser Bing, called Bing AI Chatbot. This version has access to up-to-date information as it is able to browse the internet.
|
||||
|
||||
Once registered on OpenAI or Bing, you can begin asking ChatGPT questions, as seen in the example above. Again, it’s essential to **be clear and concise, use everyday language**, and avoid typos to ensure it understands and provides the best results possible.
|
||||
|
||||
As mentioned, the system continues learning, so you can get better answers with better questions and by following up with more specific queries. You’ll see some examples of follow-up questions in the sections below.
|
||||
|
||||
### Chat GPT’s Limitations
|
||||
|
||||
ChatGPT is an impressive AI that is growing and learning at an incredible rate. OpenAI released the program so users could test it and help it learn. However, it’s still in its infancy and can fail or produce misleading or incorrect results.
|
||||
|
||||
For example, ChatGPT may produce technically correct responses that lack context or nuance or provide wrong information that it took from poor sources.
|
||||
|
||||
This issue is particularly concerning because **incorrect answers are usually said definitively and with complete confidence**, even when they are incorrect.
|
||||
|
||||
Unfortunately, this assuredness may lead to people accepting inaccurate information as true.For this reason, it’s essential to be critical of any responses, especially when dealing with complex or sensitive topics.
|
||||
|
||||
While ChatGPT undoubtedly has its strengths, it is currently not a substitute for human expertise and judgment.
|
||||
|
||||
## 8 Best Ways Cyclists Can Use ChatGPT
|
||||
|
||||
ChatGPT, in its current form, is already capable of helping us with tasks such as research, planning, and troubleshooting.
|
||||
|
||||
Using the version available through Microsoft Bing, you can plan routes based on weather, as seen above, or you can research and compare products for a purchase you plan to make.
|
||||
|
||||
Let’s look at eight ways cyclists can use it to make life easier and save time.
|
||||
|
||||
*NB: Click on any screenshot below to make it larger.*
|
||||
|
||||
### 1\. ChatGPT Can Create Cycling Training Programs
|
||||
|
||||
Cyclists can use ChatGPT to create a [cycling training plan](https://www.bicycle-guider.com/cycling-advice/training-plans/) to prepare for an upcoming event, such as a race or Gran Fondo.
|
||||
|
||||
I gave the program some hypothetical information outlining ability, available training hours and days, and how much time there is before race day.
|
||||
|
||||
Have a look at what ChatGPT returned.
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/gpt-training-plan.jpg)
|
||||
|
||||
As you can see from what ChatGPT provided, it’s not a foolproof system.
|
||||
|
||||
Currently, it **struggles with simple math**, which is why it only returned a six-week training program, it didn’t consider my limitation of 12 hours (it gave a 15.5-hour training week in Week 5), and it provided four training rides instead of three.
|
||||
|
||||
Nonetheless, the mix of ride types, targeting of training zones, recovery time, and progression of training load indicate that the program is pulling from well-researched data on creating a cycling training plan and could help in other ways.
|
||||
|
||||
> To refine the results, you can point out the mistakes and it will generate a new response, taking into account the remarks you made.
|
||||
|
||||
To get more specific data to help you create your own plan, you can ask more probing questions, such as:
|
||||
|
||||
- I want to create a cycling training plan for an upcoming event. What steps should I follow, and what factors should I consider when developing the plan?
|
||||
- What types of rides should I do, and how many hours should I dedicate to each type of ride if I can train ten hours per week?
|
||||
- How should I progress my training load over a three-month training block?
|
||||
|
||||
### 2\. ChatGPT Can Review and Compare Bikes and Cycling Gear
|
||||
|
||||
ChatGPT can provide basic summaries of bicycles, gear, or other cycling products. In addition, you can use the Microsoft Bing version to summarize information about specific products.
|
||||
|
||||
Look at the example below to see its response when asked about the top-selling city e-bikes under $4,000.
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/bike-comparison-2.jpg)
|
||||
|
||||
In this example, ChatGPT searched the internet and took information from two sources, Tech Radar and Discerning Cyclist.
|
||||
|
||||
We assume that it has taken a selection of bikes and pros and cons from each article and made a short summary based on that. However, **it’s impossible to know why it selected the bikes** and the points that it did.
|
||||
|
||||
With that in mind, we’d recommend using ChatGPT as a research tool while still relying on your favorite sites and trusted sources for product reviews.
|
||||
|
||||
The experts writing for these sites can bring together more information through experience and directed research to help you make the best decision.
|
||||
|
||||
### 3\. Create a Cycling Nutrition Plan with ChatGPT
|
||||
|
||||
Cyclists can also leverage ChatGPT to help with nutrition plans or recipes if they’re unsure of what to eat on ride or race day.
|
||||
|
||||
For example, you can ask for meal recommendations, such as a pre-ride meal, with your specific dietary requirements and follow up by asking for recipes for the meal.
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/meal-plan-1.jpg)
|
||||
|
||||
You’ll note that the program pulled information from one site which says, “100 to 200 calories is ideal before a long ride,” which isn’t correct. Thankfully, Bing’s ChatGPT allows you to **click through to the resources it’s quoting from**, so you can double-check the website’s trustworthiness and sources.
|
||||
|
||||
> If any information doesn’t seem correct or is important, it’s worth double-checking.
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/meal.jpg)On the right, you can see an example of how it will provide a weekly nutrition plan for a vegetarian with varied meals and snacks.
|
||||
|
||||
Follow up with prompts such as “Create a grocery list for this meal plan” or “Provide recipes for each meal on Monday” to get even more information.
|
||||
|
||||
### 4\. Create a Bike Touring Travel Plan with Chat GPT
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/travel-itinerary.jpg)As mentioned, ChatGPT functions exceptionally well as a concierge, helping you plan trips and create itineraries for a vacation.
|
||||
|
||||
In the example to the right, you can see it provides details on which town to use as a base (Bormio) and how to get there, and it continues with four rides, the first of which is the famous Passo dello Stelvio.
|
||||
|
||||
By using the Bing version that’s connected to the internet, you could ask follow-up questions about hotels and restaurants to visit, the price of flights, and any other details you wanted, **double-check any information** provided to see that it’s accurate.
|
||||
|
||||
Keep in mind that sometimes its routes don’t make sense, especially when asked to provide you with directions to get from point A to point B.
|
||||
|
||||
However, it works relatively well for general tour planning as in the example above.
|
||||
|
||||
### 5\. Get Instructions for Maintenance, Repairs, and Adjustments
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/repair-and-maintenance.jpg)ChatGPT can also provide **step-by-step instructions** for adjustments, [bike maintenance](https://www.bicycle-guider.com/cycling-advice/bike-maintenance/), and repair tasks, such as setting saddle height, cleaning and lubing the drivetrain or [changing a chain](https://www.bicycle-guider.com/cycling-advice/bike-chain/) (as seen in the example).
|
||||
|
||||
Some points are vague and not detailed enough, but you can ask follow-up questions to get more precise instructions on a specific step if needed.
|
||||
|
||||
ChatGPT adds some tips for carrying out the process in this example. However, some of these aren’t very developed. For instance, it mentions checking your cassette and chainring for wear but doesn’t specify what to look for (pointed “shark tooth” teeth on the cogs). Though you can follow up with a request to elaborate on any point, which it will do in a leap.
|
||||
|
||||
Again, while it’s not foolproof, it offers a good starting point and summary of the process.
|
||||
|
||||
### 6\. Get Injury Recovery Advice
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/injury.jpg)Many people use the internet to diagnose injuries and illnesses by describing their symptoms and seeing what matches on sites like WebMD or different forums.
|
||||
|
||||
While we don’t recommend doing this for anything serious, it can be valuable to try to resolve the issue with the advice found online if your symptoms are not serious.
|
||||
|
||||
For example, many riders experience knee pain when they begin cycling. A common reason for this is [training too much](https://www.bicycle-guider.com/cycling-advice/overtraining-in-cycling/) before your muscles and connective tissues have had time to adapt. Likewise, a new bike or shoes that aren’t fit correctly can lead to knee pain.
|
||||
|
||||
If the pain isn’t severe, you could use ChatGPT to identify the possible causes by inputting the specific details of your symptoms and the context.
|
||||
|
||||
In this example, ChatGPT gave good recommendations with the caveat that if symptoms worsen, you should seek professional help.
|
||||
|
||||
Again, ChatGPT **can’t replace the care of a medical professional**, so always consult with your healthcare provider in the event of injury.
|
||||
|
||||
### 7\. Connect with Other Cyclists in Your Area
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/group.jpg)ChatGPT can recommend local cycling clubs, group rides, or online forums to connect with other cyclists and build a community.
|
||||
|
||||
For example, if you move to a new city or country, you can **skip the tedious research** and get ChatGPT (Bing version) to recommend local cycling clubs.
|
||||
|
||||
This version will provide clickable links, such as the club website or Google Maps, to show where the information comes from.
|
||||
|
||||
In addition, you can get recommendations for cycling-related forums where you can engage with other riders and share stories and experiences.
|
||||
|
||||
It’s unlikely that ChatGPT will find all clubs and groups as there must be details about the club online, so we’d recommend also asking locals to find out more information.
|
||||
|
||||
### 8\. Get Cycling Safety Tips
|
||||
|
||||
One final way to use ChatGPT, although we’re sure there are many more we haven’t thought of, is to provide [cycling safety and security tips](https://www.bicycle-guider.com/cycling-advice/bicycle-safety/).
|
||||
|
||||
This functionality is valuable if you’re new to cycling, commuting, riding an e-bike, or trying a new discipline for the first time.
|
||||
|
||||
ChatGPT can pull from the internet and **create a concise list of tips for any question** you ask.
|
||||
|
||||
For example, we’ve asked for general security and safety tips in the screenshot below. However, if you’re new to mountain biking, you could ask for specific recommendations on how to stay safe on the trails.
|
||||
|
||||
[](https://www.bicycle-guider.com/wp-content/uploads/2023/03/safety.jpg)
|
||||
|
||||
Remember that these lists are not exhaustive, and it’s still essential to use common sense and maybe do your own research by searching online or asking an experienced biker.
|
||||
|
||||
## In Conclusion
|
||||
|
||||
We believe ChatGPT is a powerful tool that can assist cyclists in various ways.
|
||||
|
||||
With its vast knowledge base and language capabilities, it can provide you with useful information on routes, weather conditions, and equipment. Moreover, it can offer you guidance on bike maintenance and repair, as well as help you connect with other riders and communities.
|
||||
|
||||
Overall, ChatGPT has the potential to enhance the cycling experience and make it safer, more enjoyable, and more accessible for people of all levels and backgrounds.
|
||||
|
||||
Just keep in mind that the technology is still in its infancy, so it’s advisable to double-check any information you get.
|
||||
|
||||
However, what’s exciting to realize is that this is the worst it will ever be, as impressive as it currently is.
|
||||
|
||||
There are no comments yet, add one below.
|
||||
+202
@@ -0,0 +1,202 @@
|
||||
---
|
||||
page-title: "API Design Practice. A practical guide to API QA and the… | by TRGoodwill | API Central | May, 2023 | Medium"
|
||||
url: https://medium.com/api-center/api-design-practice-7fce69e6336c
|
||||
date: "2023-06-02 15:52:06"
|
||||
---
|
||||
## API Design Practice
|
||||
|
||||
## A practical guide to API QA and the design of stable, coherent and composable business resource APIs
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/@trgoodwill?source=post_page-----7fce69e6336c--------------------------------)[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/api-center?source=post_page-----7fce69e6336c--------------------------------)
|
||||
|
||||
## Introduction
|
||||
|
||||
An API specification document is a technical artifact, offering little opportunity for meaningful and timely input from business and enterprise stakeholders. It is absolutely the wrong place to begin designing an API. When building an enterprise API catalog of reusable, stable, coherent and composable APIs, ***an enterprise-guided, domain-oriented API Design Practice is essential***.
|
||||
|
||||
## API Design Goals
|
||||
|
||||
The API Design Phase is centered around the capture and validation of the domain data model and the state-lifecycle of business resources. The quality of the data / REST model has significant impact on the usability, evolvabilty and security of an API.
|
||||
|
||||
Collaborative design workshops and modeling tools will allow a diverse group of stakeholders, from business owners, enterprise and domain architects, data modelers, security architects, REST and EDA SMEs, tech leads and developers, to interact with (and contribute to) the same domain data model, and be notified of changes that interest them.
|
||||
|
||||
In this way, the domain model “*acts as a* [*Ubiquitous Language*](https://martinfowler.com/bliki/UbiquitousLanguage.html) *to help communication between software developers and domain experts*” ([Fowler, M 2014, BoundedContext](https://martinfowler.com/bliki/BoundedContext.html)), maximizing collaboration, providing the tightest possible feedback loop, and ensuring that the domain model remains the definitive source-of-truth.
|
||||
|
||||
## Align Resource APIs with your Business Domain
|
||||
|
||||
From the business information, events and processes managed by a System-of-Record business service, are abstracted one or more canonical business resource APIs. Business resources represent the nouns of a system, such as ‘*applications*’ and ‘*applicants*’. They provide a context for interaction with a business capability, represent the business facts about a business domain, and when consistently modeled, discoverable and subscribable, they become the backbone of a federated data platform.
|
||||
|
||||
## Design for Composability
|
||||
|
||||
Microservices architectures and the REST architectural style enable decoupling, self-service and re-use by moving the responsibility for choreography from the resource server to the client. This shift in responsibility allows business systems to build stable, genericised interfaces to their business resources and capabilities, without tight coupling to client systems, which in turn allows client systems to compose data via self-service integration without a blocking dependency on external teams.
|
||||
|
||||

|
||||
|
||||
API clients will typically want access to core information about a specific business object, not complex data structures, and they want it FAST. A good REST model is concerned with finding a balance between granularity and cohesive units of business data likely to be of interest to client systems (though not superfluous to their needs). In short, *balancing* ***composability*** *with* ***cohesion***. Supporting elements may be [modeled as sub-resources](https://medium.com/@trgoodwill/api-design-pattern-for-business-resource-apis-6f25afd2b2df).
|
||||
|
||||
## Early and Continuous Stakeholder Engagement
|
||||
|
||||
Business domain expertise and enterprise API Design Standards inform The API Design Phase. A REST model provides the means for external systems to securely interact with business objects, data and processes via standard, generic RESTful operations. The quality of the model has significant impact on the usability, evolvabilty and security of an API.
|
||||
|
||||
There are many stakeholders invested in shaping and validating the model, stakeholders may include:
|
||||
|
||||
- Business owner (domain expert),
|
||||
- Domain architect,
|
||||
- Enterprise architects (Security, Data)
|
||||
- API Platform REST SME,
|
||||
- Tech lead / API Developers
|
||||
- Closely aligned client application teams.
|
||||
|
||||

|
||||
|
||||
## Plan the process
|
||||
|
||||
During the ***planning phase*** of the project, identify and engage a representative from each of the above-mentioned stakeholder groups. Consider whether there may be closely aligned client application teams or other invested parties that can contribute valuable feedback, and identify a representative from each of these teams.
|
||||
|
||||
## Remember that the process is iterative
|
||||
|
||||
Capture your understanding of the domain as early as possible — and use collaborative tools and a shareable model to elicit corrections and input from stakeholders.
|
||||
|
||||
## Preparation
|
||||
|
||||
Identify the tools that you will use for the process and ensure that modellers and stakeholders are provided access. Developers/modellers should familiarize themselves with tools, processes and enterprise [API design standards](https://medium.com/api-center/writing-api-design-standards-84cb7cbb3fd7) prior to commencing the process.
|
||||
|
||||
“Bottom up” analysis of legacy systems can be helpful — but ONLY as a means for engineers to bring knowledge of as-is implementation into the room as a contribution to the larger discussion.
|
||||
|
||||
*More on API Standards:*
|
||||
|
||||
## 1\. Conduct Design Workshops
|
||||
|
||||
Set up an initial workshop with domain SMEs — those with a deep understanding of the business processes, regulatory obligations etc. Collaborative domain-oriented design workshops such as [Event Storming](https://www.eventstorming.com/) are a forum for ***mutual discovery, validation and agreement* on models**, boundaries and business events.
|
||||
|
||||
When running **design workshops** (onsite or online) with a number of stakeholders, a collaborative white-boarding tool will allow you to capture, share and validate perspectives on business events, processes, actors and entities. The Event Storming technique can provide some structure to design workshops, and a means to capture collective knowledge about the domain.
|
||||
|
||||

|
||||
|
||||
A brief overview of the Event Storming process is as follows:
|
||||
|
||||
1. **Identify a scenario:** A short and focused bullet-point description of the process to be captured.
|
||||
2. **Identify events:** the things that are happening in your domain — written in past tense and expressed as a flow or sequence.
|
||||
3. **Capture commands and aggregates/entities:** as well as actors, external systems, processes/policies and problems/hot-spots as appropriate.
|
||||
4. **Identify bounded contexts:** independent clusters of common language and functionality — each bounded context should be ‘decoupled’, expressing its own model, and its own API/s.
|
||||
|
||||
The Event Storming process employs coloured ‘sticky notes’ (either physical or digital) to explore, organise and iterate on emerging elements of the scenario. Time-boxing phases of the workshop is an important element of the process. A [Miro Event Storming Template](https://miro.com/miroverse/event-storming/) will help you get started.
|
||||
|
||||
A validated high-level view of business events, commands, aggregates & entities is a key input into the domain data model.
|
||||
|
||||
## 2\. Model the Data & Continuously Validate
|
||||
|
||||
Capture the aggregates/entities that emerge from design workshops in collaborative data modelling tooling and engage key stakeholders to validate and enrich the model. Consider [Enterprise Naming Conventions](https://medium.com/api-center/api-bites-payload-conventions-76ffde7f5eb2).
|
||||
|
||||
Explore with ***enterprise data architects and domain architects*** the applicability of industry models and formalisms, and re-use of ‘enterprise’ entity arch-types such as address data structures etc.
|
||||
|
||||
|
||||
|
||||
As soon as baseline agreement on the data managed by a system-of-record emerges, seek the advice of ***security architecture*** on the classification, caveats and controls applicable to the data. Make annotations in the model against each entity.
|
||||
|
||||
Consider [REST Modelling Guidance](https://medium.com/@trgoodwill/api-design-pattern-for-business-resource-apis-6f25afd2b2df), and validate composability and cohesion with ***API competency REST SMEs*** as the model develops. When developing the REST layer, consider [Enterprise API Path Conventions](https://medium.com/api-center/api-bites-7373b2127ed1) and [HTTP Request and Response Protocols](https://medium.com/api-center/api-bites-request-and-response-protocols-1f3a4f34cecf).
|
||||
|
||||
Iterate and circulate significant model changes to the wider group of stakeholders as often as possible — design tooling should assist with stakeholder notification.
|
||||
|
||||
## 3\. Generate and Refine your API Specifications
|
||||
|
||||
When the model is *relatively* stable, create a versioned snapshot of the model and generate a prototype API specification for technical review and validation. Version aligned API specifications are generated from the REST model, based on standards and policy-conformant rules or templates.
|
||||
|
||||
You may choose to work with an initial version “0.x.x” prototype API spec until you are ready to publish. Remember that b*eyond an initial V1,* [***major version increments***](https://medium.com/api-center/api-bites-1af949efdd1b) ***must only apply to breaking changes to production (‘live’) APIs****.*
|
||||
|
||||
## Validation and Refinement of your API Specification
|
||||
|
||||
API definition documents, whether hand-crafted, generated or pre-existing, will need to be reviewed and ***technically* *validated***, and in many cases further refined.
|
||||
|
||||
Use an IDE with OpenAPI/AsyncAPI document linting support — it will provide immediate feedback on API quality and mandatory API document rules.
|
||||
|
||||
API document linting rules should be clearly defined. [Spectral OpenAPI rules](https://github.com/stoplightio/spectral/blob/develop/docs/reference/openapi-rules.md) are widely referenced as a base OpenAPI document ruleset.
|
||||
|
||||
*More on API document linting:*
|
||||
|
||||
## Model Driven, API-First Development
|
||||
|
||||
API-first is a micro-or-modular service development model that treats APIs as the primary means of interacting with a business capability and the business facts about a domain. When these API ‘products’ are streamlined for consistency and re-usability, they contribute to a rich and composable federated data platform.
|
||||
|
||||
As a primary product of a service, the API is designed first, and used as a template for the service implementation. When building from a validated domain model and API definition document, product teams can take advantage of code generators to accelerate development.
|
||||
|
||||
From the API definition document, OpenAPI & AsyncAPI Generators can automatically create a consistent scaffold/skeleton implementation for supported languages (e.g. Java/Spring, Node.js). Mock servers and API Tests can also be generated from the API specification document.
|
||||
|
||||

|
||||
|
||||
For development to be both API-First and Model Driven, the API specification origin and source-of-truth must be the validated domain model.
|
||||
|
||||
## Legacy and Proprietary COTS/SaaS APIs
|
||||
|
||||
Legacy or COTS/SaaS API definition documents without a sharable data model are more difficult to validate, evolve and map to the enterprise context. However this situation arises when an organization is in transition to new platforms and architectures. Consider:
|
||||
|
||||
- Retrospectively capturing the API data model with Model-Driven-Design tooling.
|
||||
- Which elements of the API and/or OpenAPI document may be iteratively refined/refactored to align with API & document rules.
|
||||
- Whether a tactical “anti-corruption-layer” integration solution can provide a clean and conformant API
|
||||
|
||||
## API Design Tooling
|
||||
|
||||
## Design Workshop Tools
|
||||
|
||||
The ‘[Event Storming](https://docs.firstdecode.com/architecture/domain-driven-design/event-storming/)’ technique is white-board centered design workshop amenable to live online collaboration. [Judith Birmoser’s Event Storming template](https://miro.com/miroverse/event-storming/) for the the Miro digital white-board platform, or an [Event Storming template for Mural](https://app.mural.co/template/15ae8c65-6f71-44bf-bb6f-7db5d166de29/2e2cb128-5afb-450c-9a32-05db14b57f60) is an easy way to get started.
|
||||
|
||||

|
||||
|
||||
## Domain Data Modelling & Model Driven Design tooling
|
||||
|
||||
Domain modelling tooling should support OpenAPI/AsyncAPI document generation, source control, and management of semantic versioning across the model and its derivative artifacts — features that are helpful in maintaining the currency and traceability of published APIs.
|
||||
|
||||

|
||||
|
||||
The [Jargon](https://jargon.sh/) Domain Data Modelling Platform
|
||||
|
||||
Other platform features strongly supportive of model driven development include design-time model validation, documentation of state-lifecycles, (e.g. state-lifecycle diagrams), mapping and management of dependencies, notification management, and model discoverability, sharing and re-use.
|
||||
|
||||
Domain Data Modelling tooling (*with widely varying feature-sets*) includes:
|
||||
|
||||
- [Jargon Domain Data Modelling Platform](https://jargon.sh/)
|
||||
- [Stoplight Studio Enterprise](https://stoplight.io/enterprise)
|
||||
- [Visual Paradigm](https://www.visual-paradigm.com/solution/rest-api-design-tool/)
|
||||
- [Mendix Low-Code Platform](https://docs.mendix.com/refguide/domain-model/)
|
||||
- [Hackolade Studio](https://hackolade.com/help/OpenAPI.html)
|
||||
- [Sparx EA](https://www.sparxsystems.de/) + [OpenAPI plugin](https://inteca.com/enterprise-architect-plugins/)
|
||||
|
||||
## API Specification Technical Validation Tooling
|
||||
|
||||
[Spectral](https://stoplight.io/open-source/spectral) is a widely used open-source OpenAPI/AsyncAPI document linter with an extensible ruleset. The following tools support Spectral linting:
|
||||
|
||||
- **The** [**Jargon platform**](https://jargon.sh/) supports Spectral linting at the domain data and REST model layers.
|
||||
- [**Visual Studio Code**](https://code.visualstudio.com/) : Install the [‘Spectral’ extension by Stoplight](https://marketplace.visualstudio.com/items?itemName=stoplight.spectral). Rule errors and warnings are listed in the Problem console, and is updated dynamically as changes are made.
|
||||
- [**Stoplight Studio**](https://stoplight.io/studio) : Upload an OpenAPI or AsyncAPI specification and spectral will provide immediate dynamic feedback. The warning icon will toggle a side-by-side view.
|
||||
- **CI/CD pipeline** : As well as automated Sonarqube analysis of your software source code, integration & build pipelines can support spectral linting of your OpenAPI definition to ensure timely feedback on document quality issues.
|
||||
|
||||
## Code Generation Tools
|
||||
|
||||
There are various locally configurable generators available for different programming languages. Here are some resources:
|
||||
|
||||
- [OpenAPI Design & Documentation Tools | Swagger](https://swagger.io/tools/)
|
||||
- OAS OpenAPI generators: [https://openapi-generator.tech/docs/generators/](https://openapi-generator.tech/docs/generators/) and [https://github.com/OpenAPITools/openapi-generator](https://github.com/OpenAPITools/openapi-generator)
|
||||
- Various OpenAPI Tools: [https://openapi.tools/](https://openapi.tools/)
|
||||
|
||||
## Test Generation
|
||||
|
||||
The following is a (non-exhaustive) list of testing platforms that support test generation from an OpenAPI and/or AsyncAPI specification document:
|
||||
|
||||
[Postman API Platform](https://www.postman.com/), [Thunder Client — Extension for VS Code](https://www.thunderclient.com/), [karatelabs/karate](https://github.com/karatelabs/karate), [Pact (pact.io)](https://docs.pact.io/), [Katalon Quality Management](https://katalon.com/), [Insomnia API Dev Platform](https://insomnia.rest/), [SOAPUI](https://www.soapui.org/docs/rest-testing/), [REST-Assured](https://github.com/rest-assured/rest-assured) + [Tcases](https://github.com/Cornutum/tcases/blob/master/tcases-openapi/README.md#tcases-for-openapi-from-rest-ful-to-test-ful)
|
||||
|
||||
## Wrap-up
|
||||
|
||||
An API specification document is a technical document. It is often generated well into the development effort, and is difficult for less technical stakeholders to parse. Without a guided API design practice, a large enterprise will struggle to govern the quality of business APIs.
|
||||
|
||||
In order to maximize opportunities for stakeholder collaboration and provide the tightest possible feedback loop, it important to capture, share and validate REST models well before anything is committed to code. A clearly defined and supported API design practice can ensure that both APIs and their underlying data models are visible, re-usable and governable.
|
||||
+331
@@ -0,0 +1,331 @@
|
||||
---
|
||||
page-title: "Building Your Own DevSecOps Knowledge Base with OpenAI, LangChain, and LlamaIndex | by Wenqi Glantz | May, 2023 | Better Programming"
|
||||
url: https://betterprogramming.pub/building-your-own-devsecops-knowledge-base-with-openai-langchain-and-llamaindex-b28cda15abb7
|
||||
date: "2023-06-02 12:38:49"
|
||||
---
|
||||
## Building Your Own DevSecOps Knowledge Base with OpenAI, LangChain, and LlamaIndex
|
||||
|
||||
## Building your custom knowledge base chatbot
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/@wenqiglantz?source=post_page-----b28cda15abb7--------------------------------)[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://betterprogramming.pub/?source=post_page-----b28cda15abb7--------------------------------)
|
||||
|
||||
|
||||
|
||||
Diagram by author
|
||||
|
||||
DevSecOps is a big part of what I do daily at my current job. I love learning in the DevSecOps space and sharing my knowledge with others through blogging. Often, I find myself searching through my articles for the information I need. Wouldn’t it be nice to build my own custom knowledge base for DevSecOps so I can feed my files or articles to it and search it when needed?
|
||||
|
||||
In this article, let’s explore building a custom DevSecOps knowledge base using OpenAI, LangChain, and LlamaIndex (GPT Index).
|
||||
|
||||
## High-Level Architecture
|
||||
|
||||
We are going first to feed my article files to our knowledge base. Then we query our knowledge base with questions from my article files related to DevSecOps.
|
||||
|
||||
Let’s split the architecture into two stages: data ingestion/indexing and data querying.
|
||||
|
||||
|
||||
|
||||
Diagram by author
|
||||
|
||||
|
||||
|
||||
Diagram by author
|
||||
|
||||
Now, let’s get started building our knowledge base.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- Python installation: assume you have Python installed in your local environment. If not, please refer to the Python [download](https://www.python.org/downloads/) page to download and install Python. Be sure to upgrade pip to the latest version by running the following command:
|
||||
|
||||
python -m pip install -U pip
|
||||
|
||||
- OpenAI API key: navigate to OpenAI’s [API Keys](https://platform.openai.com/account/api-keys) page to generate a new API key if you don’t already have one. Suggest you also set up a usage limit through their [Usage Limits](https://platform.openai.com/account/billing/limits) page so you can manage your spending.
|
||||
- Create a directory on your local environment, for example `DevSecOpsKB`. You will be running all commands below in this directory.
|
||||
|
||||
## Installation of Libraries
|
||||
|
||||
To train our custom DevSecOps knowledge base, we need to install a few libraries. Simply navigate to the `DevSecOpsKB` directory, and run:
|
||||
|
||||
pip install openai langchain llama\_index==0.6.12 pypdf PyCryptodome gradio
|
||||
|
||||
Note: we specified version `0.6.12` for `llama_index`. Without specifying the version, it would install the latest version, `0.6.16` as of this update (May 31 2023), which introduced breaking changes. We cover some of the changes in the latest `llama_index` release in [another blog](https://betterprogramming.pub/a-glimpse-into-the-mechanics-of-llamaindex-apps-through-the-lens-of-observability-9e7c49f4cb32?sk=6bb0a3a8dc496e1f58523991f063550e).
|
||||
|
||||
Let’s take a closer look at each library.
|
||||
|
||||
## OpenAI library
|
||||
|
||||
We are using [OpenAI](https://openai.com/) library for two purposes:
|
||||
|
||||
- Data ingestion/indexing: as depicted in the architecture diagram above, we will be calling OpenAI’s embedding model `text-embedding-ada-002` via LangChain under the hood.
|
||||
- Data query: we will call OpenAI’s GPT-3.5 LLM (Large Language Model). GPT-3.5 models can understand and generate natural language or code. We will be using their most capable and cost-effective model in the GPT-3.5 family, `gpt-3.5-turbo`.
|
||||
|
||||
## LangChain
|
||||
|
||||
[LangChain](https://python.langchain.com/en/latest/index.html) is an open source library that provides developers with the necessary tools to create applications powered by LLMs. It is a framework built around LLMs that can be used for chatbots, Generative Question-Answering (GQA), summarization, and much more. The core idea of the library is that developers can “chain” together different components to create more advanced use cases around LLMs.
|
||||
|
||||
LangChain offers a series of modules, which are the core abstractions as the building blocks of any LLM-powered application. These modules include models, prompts, memory, indexes, chains, agents, and callbacks. For our knowledge base chatbot, we will be using LangChain’s `chat_models` module.
|
||||
|
||||
## LlamaIndex
|
||||
|
||||
[LlamaIndex](https://gpt-index.readthedocs.io/en/latest/) uses LangChain’s LLM modules and allows for customizing the underlying LLM. LlamaIndex is a powerful tool that provides a central interface to connect the LLM with external data and allows you to create a chatbot based on the data you feed it. With LlamaIndex, you don’t need to be an NLP or machine learning expert. You only need to provide the data you want the chatbot to use, and LlamaIndex will take care of the rest.
|
||||
|
||||
As [outlined](https://github.com/jerryjliu/llama_index) by [Jerry Liu](https://twitter.com/jerryjliu0), the creator of LlamaIndex, LlamaIndex provides the following tools in an easy-to-use fashion:
|
||||
|
||||
- Offers data connectors to ingest your existing data sources and data formats (APIs, PDFs, docs, SQL, etc.)
|
||||
- Provides ways to structure your data (indices, graphs) so that this data can be easily used with LLMs.
|
||||
- Provides an advanced retrieval/query interface over your data: Feed in any LLM input prompt, get back retrieved context and knowledge-augmented output.
|
||||
- Allows easy integrations with your outer application framework (e.g., LangChain, Flask, Docker, ChatGPT, or anything else).
|
||||
|
||||
## pypdf + PyCryptodome
|
||||
|
||||
[pypdf](https://pypi.org/project/pypdf/) is a free and open source pure-python PDF library capable of splitting, merging, cropping, and transforming the pages of PDF files. We will be using this library to parse our PDF files. PyCryptodome is another library that helps prevent errors while parsing PDF files.
|
||||
|
||||
## Gradio
|
||||
|
||||
[Gradio](https://gradio.app/) is an open source Python package that allows you to quickly create easy-to-use, customizable UI components for your ML model, any API, or even an arbitrary Python function using a few lines of code. You can integrate the Gradio GUI directly into your Jupyter Notebook or share it as a link with anyone. Let’s use Gradio to build a simple UI for our knowledge base.
|
||||
|
||||
## How to Add Data Source
|
||||
|
||||
I converted my articles listed in [The Path to DevOps Self-Service: A Five-Part Series](https://medium.com/@wenqiglantz/the-path-to-devops-self-service-a-five-part-series-5ea5d4552f9e), along with the [Troubleshooting Tips for GitHub Actions Workflows](https://medium.com/better-programming/17-troubleshooting-tips-for-github-actions-workflows-43394e4f1a8a), into PDFs and saved those PDF documents under my `DevSecOpsKB/data` directory. Let’s use these documents to start training our knowledge base chatbot.
|
||||
|
||||
|
||||
|
||||
## Implement Python Code
|
||||
|
||||
There are many open source Python tutorials online for building custom chatbots, but many contain outdated code as they were built on older versions of the libraries, and hard to get them to work as desired. I recommend follow the instructions on the [LlamaIndex Usage Pattern](https://github.com/jerryjliu/llama_index/blob/main/docs/guides/primer/usage_pattern.md) page as the base framework, then add your custom logic. Let’s dive into the code.
|
||||
|
||||
**Step 1**: Import the following modules and classes:
|
||||
|
||||
from llama\_index import StorageContext, ServiceContext, GPTVectorStoreIndex, LLMPredictor, PromptHelper, SimpleDirectoryReader, load\_index\_from\_storage
|
||||
from langchain.chat\_models import ChatOpenAI
|
||||
import gradio as gr
|
||||
import sys
|
||||
import os
|
||||
|
||||
- `SimpleDirectoryReader`, `LLMPredictor`, `PromptHelper`, `StorageContext`, `ServiceContext`, `GPTVectorStoreIndex`, and `load_index_from_storage` are classes from the `llama_index` module.
|
||||
- `ChatOpenAI` is a class from the `langchain.chat_models` module.
|
||||
- `gradio` is the library we use for creating web interfaces.
|
||||
- `sys` and `os` are standard Python modules for system-related operations.
|
||||
|
||||
**Step 2**: The API key for OpenAI is set as an environment variable using `os.environ["OPENAI_API_KEY"]`. You need to replace `'YOUR-OPENAI-API-KEY'` with your actual OpenAI API key for it to work.
|
||||
|
||||
os.environ\["OPENAI\_API\_KEY"\] = 'YOUR-OPENAI-API-KEY'
|
||||
|
||||
**Step 3**: Define the function `data_ingestion_indexing(directory_path)`. This function is responsible for ingesting the data and creating and saving the index used for data queries in our knowledge base.
|
||||
|
||||
def create\_service\_context():
|
||||
|
||||
|
||||
max\_input\_size = 4096
|
||||
num\_outputs = 512
|
||||
max\_chunk\_overlap = 20
|
||||
chunk\_size\_limit = 600
|
||||
|
||||
|
||||
prompt\_helper = PromptHelper(max\_input\_size, num\_outputs, max\_chunk\_overlap, chunk\_size\_limit=chunk\_size\_limit)
|
||||
|
||||
|
||||
llm\_predictor = LLMPredictor(llm=ChatOpenAI(temperature=0.5, model\_name="gpt-3.5-turbo", max\_tokens=num\_outputs))
|
||||
|
||||
|
||||
service\_context = ServiceContext.from\_defaults(llm\_predictor=llm\_predictor, prompt\_helper=prompt\_helper)
|
||||
return service\_context
|
||||
|
||||
def data\_ingestion\_indexing(directory\_path):
|
||||
|
||||
|
||||
documents = SimpleDirectoryReader(directory\_path).load\_data()
|
||||
|
||||
|
||||
index = GPTVectorStoreIndex.from\_documents(
|
||||
documents, service\_context=create\_service\_context()
|
||||
)
|
||||
|
||||
|
||||
index.storage\_context.persist()
|
||||
|
||||
return index
|
||||
|
||||
- We define a utility function named `create_service_context`, which creates the `ServiceContext`, a utility container for LlamaIndex index and query classes. The container contains objects that are commonly used for configuring every index and query, such as the `LLMPredictor` (for configuring the LLM, it is a wrapper class around LangChain’s LLMChain that allows easy integration into LlamaIndex), the `PromptHelper` (allows the user to explicitly set certain constraint parameters, such as maximum input size, number of generated output tokens, maximum chunk overlap, etc.), the `BaseEmbedding` (for configuring the embedding model), and more.
|
||||
- It uses `SimpleDirectoryReader` to load data from the specified directory path.
|
||||
- It creates an instance of `GPTVectorStoreIndex` with the loaded `documents`, and the `service_context` by calling the utility function `create_service_context()`.
|
||||
- Finally, it calls the `storage_context` and persists the index to disk under the default `storage` folder, and returns the `index` object.
|
||||
|
||||
**Step 4**: Define the function `data_querying(input_text)`. This function is the core of our knowledge base logic.
|
||||
|
||||
def data\_querying(input\_text):
|
||||
|
||||
|
||||
storage\_context = StorageContext.from\_defaults(persist\_dir="./storage")
|
||||
|
||||
|
||||
index = load\_index\_from\_storage(storage\_context, service\_context=create\_service\_context())
|
||||
|
||||
|
||||
response = index.as\_query\_engine().query(input\_text)
|
||||
|
||||
return response.response
|
||||
|
||||
- It rebuilds storage context.
|
||||
- It loads the index from storage. Since we initialized the index with a custom `ServiceContext` object, we also need to pass in the same `ServiceContext` during `load_index_from_storage`.
|
||||
- It queries the index with the input text using `index.as_query_engine().query()`.
|
||||
- It returns the response received from the index.
|
||||
|
||||
**Step 5**: Define the UI by creating an instance of `gr.Interface`.
|
||||
|
||||
iface = gr.Interface(fn=data\_querying,
|
||||
inputs=gr.components.Textbox(lines=7, label="Enter your text"),
|
||||
outputs="text",
|
||||
title="Wenqi's Custom-trained DevSecOps Knowledge Base")
|
||||
|
||||
- The `fn` parameter is set to the `data_querying` function defined earlier.
|
||||
- The `inputs` parameter specifies a textbox input component with 7 lines for entering text.
|
||||
- The `outputs` parameter specifies that the output will be text-based.
|
||||
- The `title` parameter sets the title of the web interface. Customize it to whatever you want your UI title to be.
|
||||
|
||||
**Step 6**: The `data_ingestion_indexing` function is called with the argument `data` to create and save the index. Notice this `data` directory is where we store our PDF documents. If you want to name your directory differently, change it here accordingly.
|
||||
|
||||
|
||||
index = data\_ingestion\_indexing("data")
|
||||
|
||||
**Step 7**: The `iface.launch(share=False)` line launches the UI, making the chatbot accessible through a web browser. You have the option of turning `share` to `True`, which allows Gradio to create a share link so you can share your knowledge base chatbot with others. For this POC, we are disabling this feature for simplicity reason.
|
||||
|
||||
iface.launch(share=False)
|
||||
|
||||
See the complete code below. Copy this code into a file named `kb.py`, and placed it at the root of our `DevSecOpsKB` directory.
|
||||
|
||||
from llama\_index import SimpleDirectoryReader, LLMPredictor, PromptHelper, StorageContext, ServiceContext, GPTVectorStoreIndex, load\_index\_from\_storage
|
||||
from langchain.chat\_models import ChatOpenAI
|
||||
import gradio as gr
|
||||
import sys
|
||||
import os
|
||||
|
||||
os.environ\["OPENAI\_API\_KEY"\] = 'YOUR-OPENAI-API-KEY'
|
||||
|
||||
def create\_service\_context():
|
||||
|
||||
|
||||
max\_input\_size = 4096
|
||||
num\_outputs = 512
|
||||
max\_chunk\_overlap = 20
|
||||
chunk\_size\_limit = 600
|
||||
|
||||
|
||||
prompt\_helper = PromptHelper(max\_input\_size, num\_outputs, max\_chunk\_overlap, chunk\_size\_limit=chunk\_size\_limit)
|
||||
|
||||
|
||||
llm\_predictor = LLMPredictor(llm=ChatOpenAI(temperature=0.5, model\_name="gpt-3.5-turbo", max\_tokens=num\_outputs))
|
||||
|
||||
|
||||
service\_context = ServiceContext.from\_defaults(llm\_predictor=llm\_predictor, prompt\_helper=prompt\_helper)
|
||||
return service\_context
|
||||
|
||||
def data\_ingestion\_indexing(directory\_path):
|
||||
|
||||
|
||||
documents = SimpleDirectoryReader(directory\_path).load\_data()
|
||||
|
||||
|
||||
index = GPTVectorStoreIndex.from\_documents(
|
||||
documents, service\_context=create\_service\_context()
|
||||
)
|
||||
|
||||
|
||||
index.storage\_context.persist()
|
||||
|
||||
return index
|
||||
|
||||
def data\_querying(input\_text):
|
||||
|
||||
|
||||
storage\_context = StorageContext.from\_defaults(persist\_dir="./storage")
|
||||
|
||||
|
||||
index = load\_index\_from\_storage(storage\_context, service\_context=create\_service\_context())
|
||||
|
||||
|
||||
response = index.as\_query\_engine().query(input\_text)
|
||||
|
||||
return response.response
|
||||
|
||||
iface = gr.Interface(fn=data\_querying,
|
||||
inputs=gr.components.Textbox(lines=7, label="Enter your question"),
|
||||
outputs="text",
|
||||
title="Wenqi's Custom-trained DevSecOps Knowledge Base")
|
||||
|
||||
|
||||
index = data\_ingestion\_indexing("data")
|
||||
iface.launch(share=False)
|
||||
|
||||
## Launch DevSecOps Knowledge Base
|
||||
|
||||
Now that we have our custom PDF files ready, and the code is ready, let’s launch our DevSecOps knowledge base by running the following command in the `DevSecOpsKB` directory:
|
||||
|
||||
python kb.py
|
||||
|
||||
Let’s launch the UI of our new knowledge base: [http://127.0.0.1:7860/](http://127.0.0.1:7860/).
|
||||
|
||||
Here we go! Our new knowledge base is ready for us to tap into. Let’s ask a generic question on a term I coined in [one of my articles on DevOps self-service model](https://medium.com/better-programming/devops-self-service-pipeline-architecture-and-its-3-2-1-rule-517dc0bbcb4a), in particular, the 3–2–1 rule, and I was happy to see that our new knowledge base outputs the right information I was looking for:
|
||||
|
||||

|
||||
|
||||
Asking it with a specific error encountered in the GitHub Actions workflow, we get the desired answer. See the following:
|
||||
|
||||
|
||||
|
||||
Now, let’s ask if our knowledge base can answer questions on [Harden Runner](https://www.stepsecurity.io/products/harden-runner):
|
||||
|
||||
|
||||
|
||||
Right on! I am amazed at how accurate the answer is. Next, let’s see if our knowledge base can output a code snippet:
|
||||
|
||||
|
||||
|
||||
This one works like a charm!
|
||||
|
||||
Now, let’s attempt a negative scenario: let’s try to ask a question that is not in the provided source documents:
|
||||
|
||||
|
||||
|
||||
Job well done! LlamaIndex seems to have a guardrail in place against hallucination, which is a confident response by an AI that does not seem justified by its training data, either because it is insufficient, biased, or too specialized.
|
||||
|
||||
## Does This AI Bot Expose My Private Data to OpenAI?
|
||||
|
||||
The answer is no. Per [OpenAI privacy policy on API](https://help.openai.com/en/articles/5722486-how-your-data-is-used-to-improve-model-performance):
|
||||
|
||||
> OpenAI does not use data submitted by customers via our API to train OpenAI models or improve OpenAI’s service offering.
|
||||
|
||||
Both our functions, `data_ingestion_indexing` for data ingestion/indexing and `data_querying` for Q&A, invoke OpenAI APIs via LangChain, so we can rest assured that OpenAI does not use our private data per their privacy policy on API mentioned above.
|
||||
|
||||
## A Note on Cost
|
||||
|
||||
As you may already know, using OpenAI models does incur a cost. In our use case, we use its embedding model during data ingestion/indexing, and chat model for data querying. Here are the pricing details:
|
||||
|
||||
- For embedding model `text-embedding-ada-002`: $0.0004 / 1K tokens
|
||||
- For chat model `gpt-3.5-turbo`: $0.002 / 1K tokens
|
||||
|
||||
Here is a screenshot of my OpenAI usage while working on this chatbot:
|
||||
|
||||
|
||||
|
||||
If you plan to use OpenAI LLMs, I strongly encourage you to configure a usage limit on OpenAI’s [Usage Limit page](https://platform.openai.com/account/billing/limits), where you can define a hard limit and soft limit, so you manage your usage properly.
|
||||
|
||||
## Summary
|
||||
|
||||
This article explored how to build a customized DevSecOps knowledge base chatbot. This is a mere proof of concept. The potential of incorporating LlamaIndex and LangChain into building apps that harness the power of LLMs through private data is limitless!
|
||||
|
||||
The source code for this article can be found in [my GitHub repo](https://github.com/wenqiglantz/DevSecOpsKB-LlamaIndex-LangChain-OpenAI/tree/main/DevSecOpsKB).
|
||||
|
||||
Happy coding!
|
||||
+194
@@ -0,0 +1,194 @@
|
||||
---
|
||||
page-title: "How we built the Tinder API Gateway | by Tinder | Tinder Tech Blog | Medium"
|
||||
url: https://medium.com/tinder/how-we-built-the-tinder-api-gateway-831c6ca5ceca
|
||||
date: "2023-06-02 14:57:26"
|
||||
---
|
||||
## How we built the Tinder API Gateway
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/@TinderEng?source=post_page-----831c6ca5ceca--------------------------------)[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/tinder?source=post_page-----831c6ca5ceca--------------------------------)
|
||||
|
||||
Authored by:
|
||||
|
||||
- Vijaya Vangapandu, Distinguished Software Engineer
|
||||
- Periyasamy, Staff Software Engineer
|
||||
- , Senior Software Engineer
|
||||
- , Senior Software Engineer
|
||||
|
||||
## Introduction
|
||||
|
||||
Tinder API Gateway (TAG) is one of the critical frameworks at Tinder that solves the need of exposing public APIs and enforcing strict authorization and security rules. It’s engineered to meet Tinder’s custom need to fit perfectly in its current cloud infrastructure, and can be scaled as required and maintained without any external support. It also implements **RAC** (Route As Configuration), which helps developers ship their modules to production faster. There are various features that make TAG a unique solution, but before we dive into that, let’s look at why Tinder needs a custom gateway.
|
||||
|
||||
We have more than 500 microservices at Tinder, which talk to each other for different data needs using a service mesh under the hood. All external-facing APIs are hosted on TAG. We needed a gateway solution that could centralize all these services, giving us more control from maintenance to deployment. The custom gateway also helps in ensuring that services go through a security review before being publicly exposed to the outside world.
|
||||
|
||||
Services like Recommendations APIs also receive frequent feature updates, both on the backend and the client side. This is just one example; we have several other critical services like Match APIs, Revenue APIs, etc. that need a streamlined process to ship faster to production. So we needed a custom gateway solution that could help us configure external routes with minimal effort to expedite the release process.
|
||||
|
||||
Looking at API Gateway from a security aspect, Tinder is used in 190 countries and gets all kinds of traffic from all over the world. Traffic from real users as well as traffic from bad actors. Imagine how important it is to scan and avoid vulnerabilities that might attack any of these services. Hackers try to find cracks to get into corporate systems so that they can steal any valuable information, and one entry point for them is the gateway. We needed a custom gateway solution that could help us identify such traffic and avoid possible vulnerabilities.
|
||||
|
||||
## Challenges Before TAG
|
||||
|
||||
Before TAG existed, we leveraged multiple API Gateway solutions and each application team used a different 3rd party API Gateway solution. Since each of the gateways was built on a different tech stack, managing them became a cumbersome effort. More to the point, there were compatibility issues in sharing reusable components across different gateways. This would often result in delays in shipping the code to production. Moreover, different API Gateways had maintenance overheads.
|
||||
|
||||
We also saw inconsistent use of Session Management across APIs as the API Gateways were not centralized, as shown in below figure 1.
|
||||
|
||||

|
||||
|
||||
*Figure 1 — Session Management across APIs at Tinder before TAG*
|
||||
|
||||
We were trying to address some major concerns by looking for:
|
||||
|
||||
- A solution to bring all external facing services under one umbrella
|
||||
- An **artifact** that could be used by any application team to spin off their API Gateway to scale their application independently
|
||||
- A framework that could provide the capability for applications to **run as a Kubernetes microservice** along with other Kubernetes services
|
||||
- A design that could support configuration-driven API Gateway development for increased development velocity
|
||||
- A generic component that could be extended based on Tinder’s custom needs
|
||||
- Adding Request/Response transformations
|
||||
- Custom middleware logic for various features like Bot Detection, Schema Registry, and more
|
||||
|
||||
We also wanted to control the framework level development and support so that we could build the gateway the way we want. All of these features were the motivation behind designing TAG.
|
||||
|
||||
## Existing API Gateway Solutions
|
||||
|
||||
There are many open-source and commercial gateway solutions available in the public domain. Some of them are really heavy and focused on B2B integrations, and some of them are very complex to deploy and maintain. Existing solutions including Amazon AWS Gateway, APIgee, Tyk.io, Kong, Express API Gateway, and KrakenD were not optimal for reasons:
|
||||
|
||||
- Some of these solutions are not well integrated with our existing Envoy mesh solution
|
||||
- A few of them are configuration heavy and use built-in plugins to support different features like spike arrest, service callouts, etc. Their adoption has a steep learning curve and doesn’t fit well with our current application/network stack
|
||||
- Some solutions have less support for languages we heavily work with
|
||||
- Finally, we need flexibility in building our own plugins and filters quickly when needed
|
||||
|
||||
**Note:** All these observations were made based on the documentation available on the official site of these products. Documentation is included in the reference section of this blog.
|
||||
|
||||
## Let’s Explore TAG
|
||||
|
||||
TAG is a JVM-based framework built on top of **Spring Cloud Gateway**. Application teams can use TAG to create their own instance of API Gateway by just writing configurations. It centralizes all external facing APIs and enforces strict authorization and security rules at Tinder. TAG extends components like gateway and global filter of Spring Cloud Gateway to provide generic and pre-built filters.
|
||||
|
||||
These filters can be used by application teams for various needs:
|
||||
|
||||
- Weighted routing
|
||||
- Request/Response transformations
|
||||
- HTTP to GRPC conversion, and more
|
||||
|
||||
From the developers’ point of view, TAG was created keeping their experience at the center of the design, and for that reason, TAG supports **configuration-driven** **development**.
|
||||
|
||||
TAG, by design, helps in improving developers’ velocity, provides ease to set up routes and services using environment-specific YAML or JSON configurations without writing any code, and helps them to reuse components by sharing filters across the application routes. It leverages all major components of Spring Cloud Gateway to build custom framework-level support for developers at Tinder to use.
|
||||
|
||||
Here are some additional reasons why we developed TAG:
|
||||
|
||||
- Complete control to develop custom components, and to share and use them as configurations
|
||||
- **Request and Response scanning**
|
||||
- For **Schema Registry** to auto-generate API Documentation
|
||||
- To detect vulnerabilities like **Bot Detecting** and **Real Time Traffic Detection**
|
||||
- **Dynamic Routing**: we’re building a pipeline on TAG that will help in dynamically updating routes and their related configurations without the need of deploying the application cluster
|
||||
- TAG will enable future initiatives like **API Standardization** and **Auditing Process**
|
||||
- It enforces **consistent** and **uniform** experience of **Session Management** across different applications as it’s developed once and shared across all API Gateways (created using TAG)
|
||||
|
||||
## A Deeper Look Inside TAG
|
||||
|
||||

|
||||
|
||||
*Figure 2 — High-Level Design of TAG*
|
||||
|
||||
High-Level Design, as shown in figure 2, showcases the following components:
|
||||
|
||||
- **Routes** — Developers can expose their endpoints using Route As a Config (**RAC**); we’ll see in detail how routes are set up in TAG later on
|
||||
- **Service Discovery** — TAG uses Service Mesh to discover backend services for each route
|
||||
- **Pre-Built Filters** — We’ve added built-in filters in TAG for application teams at Tinder to use;
|
||||
example: setPath, setMethod, etc.
|
||||
- **Custom Filters** — We’ve added the support of custom filters so that application teams can write their own custom logic if needed, and implement them in a route using configurations. Custom filters are applied at Route Level (i.e. per route); example: custom logic to validate the request before calling backend service.
|
||||
- **Global Filters** — Global filters are just like custom filters, but they’re global in nature, i.e. they are applied to all the routes automatically if configured at the service level.
|
||||
Example: Auth filter or metrics filter applied to all routes specific to an application.
|
||||
|
||||
Below is the step-by-step flow of how TAG builds all the routes at application startup:
|
||||
|
||||

|
||||
|
||||
*Figure 3 — TAG processing flow at application startup*
|
||||
|
||||
**Step 1:** TAG triggers the Gateway Watcher that calls the Gateway Config Parser to load the YAML file
|
||||
|
||||
**Step 2:** The Gateway Config Parser validates and parses the environment-specific YAML configuration file
|
||||
|
||||
**Step 3:** The Gateway Manager looks up pre-filters, custom filters, and global filters and creates a map of the route ID and those filters
|
||||
|
||||
**Step 4:** The Gateway Route Locator loads predicate and its related filters from the map for each route into Spring Cloud Gateway
|
||||
|
||||
**Step 5:** The Gateway Manager then builds all the routes and prepares the gateway to receive traffic
|
||||
|
||||
Spring Cloud Gateway facilitates TAG to pre-configure all the routes and filters and seemingly execute them at runtime. Due to this design, TAG does **NOT** add any configuration processing latency at runtime. This helps TAG to scale up and handle high traffic with ease.
|
||||
|
||||
## Real World Usage of TAG at Tinder
|
||||
|
||||

|
||||
|
||||
*Figure 4 — Request processing by TAG*
|
||||
|
||||
Executing a request in the above TAG configuration (as shown in figure 4) results in the following steps:
|
||||
|
||||
**Step 1: Reverse Geo IP Lookup (RGIL)**
|
||||
|
||||
RGIL is implemented as a global filter in TAG. The IP of the client request is mapped to three-digit alpha country code using the RGIL filter. We use RGIL for rate limiting, request banning, and other purposes.
|
||||
|
||||
**Step 2:** **Request/Response Scanning**
|
||||
|
||||
An Async event is published to capture the request semantics. Request/Response Scanning Global Filter captures just the schema of the request and not the data attributes. Amazon MSK is used to securely stream the data, which can be consumed by applications downstream for a variety of use cases like automatic schema generation, bot detection, etc.
|
||||
|
||||
**Step 3:** **Session Management as a Filter**
|
||||
|
||||
A Centralized Global filter is written in TAG to validate/update and control Session Management.
|
||||
|
||||
**Step 4: Predicate Matching
|
||||
**The path of an incoming request is matched with one of the deployed routes using predicate matching.
|
||||
|
||||
**Step 5:** **Service Discovery**
|
||||
|
||||
The service discovery module in TAG uses Envoy to look up egress mapping for the matched endpoint.
|
||||
|
||||
**Step 6:** **Pre-Filters**
|
||||
|
||||
Once the route is identified, then the request goes through the chain of pre-filters configured for that route. Pre-filters are filters that are executed before the request is forwarded to the backend service. Once the list of pre-filters is executed, the request is forwarded. Weighted Routing per route and HTTP to GRPC Conversion are some of the pre-built filters available in TAG. One can also write custom filters like Trimming Request Headers.
|
||||
|
||||
**Step 7: Post-Filters**
|
||||
|
||||
After receiving the response from the backend service, the response goes through the chain of post-filters configured for that route. Post-filters are filters that are executed after the response is received from the backend service. Logging error is one example of post-filters.
|
||||
|
||||
**Step 8: Return Response**
|
||||
|
||||
After completing the list of post-filters, the final response is returned to the client.
|
||||
|
||||
**Note**:
|
||||
|
||||
- Pre-filters/post-filters can contain custom logic or any type of request/response transformation
|
||||
- One can configure the order of sequence in which pre-filters/post-filters should run
|
||||
|
||||
## API Gateway at Tinder Today
|
||||
|
||||
Application teams at Tinder are using TAG as a standard framework for building their own instance of API Gateway by just writing their application-specific configurations. These instances can individually scale as needed. TAG is also used by other Match Group brands like Hinge, OkCupid, PlentyOfFish, Ship, etc. Thus TAG is serving B2C and B2B traffic for Tinder. Below is a general depiction of how TAG is used in Tinder today.
|
||||
|
||||

|
||||
|
||||
*Figure 5 — API Gateways powered by TAG at Tinder*
|
||||
|
||||
In this blog, we looked at the state before TAG existed, why we created TAG, and how TAG is helping Tinder serve traffic at scale. We hope you enjoyed reading about it! In the next blog, we’ll also take a deeper look at how configurations are written to set up a route in TAG.
|
||||
|
||||
## References:
|
||||
|
||||
- [https://spring.io/projects/spring-cloud-gateway](https://spring.io/projects/spring-cloud-gateway)
|
||||
- [https://cloud.spring.io/spring-cloud-gateway/reference/html/](https://cloud.spring.io/spring-cloud-gateway/reference/html/)
|
||||
- [https://docs.aws.amazon.com/apigateway/latest/developerguide/welcome.html](https://docs.aws.amazon.com/apigateway/latest/developerguide/welcome.html)
|
||||
- [https://cloud.google.com/apigee/docs](https://cloud.google.com/apigee/docs)
|
||||
- [https://tyk.io/blog/what-do-we-mean-by-batteries-included/](https://tyk.io/blog/what-do-we-mean-by-batteries-included/)
|
||||
- [https://tyk.io/docs/plugins/supported-languages/](https://tyk.io/docs/plugins/supported-languages/)
|
||||
- [https://docs.konghq.com/gateway/latest/](https://docs.konghq.com/gateway/latest/)
|
||||
- [https://www.express-gateway.io/docs/](https://www.express-gateway.io/docs/)
|
||||
- [https://www.krakend.io/docs/overview/](https://www.krakend.io/docs/overview/)
|
||||
@@ -0,0 +1,8 @@
|
||||
---
|
||||
page-title: "Unblockit - Proxies to access your favourite blocked sites"
|
||||
url: https://unblockit.rsvp/
|
||||
date: "2023-08-04 10:21:59"
|
||||
---
|
||||
Menu
|
||||
|
||||
[Torrents](https://unblockit.rsvp/#torrents) [Streams](https://unblockit.rsvp/#streams) [Sports](https://unblockit.rsvp/#sports) [Direct](https://unblockit.rsvp/#ddl) [Music](https://unblockit.rsvp/#music) [Books](https://unblockit.rsvp/#books)
|
||||
@@ -0,0 +1,112 @@
|
||||
---
|
||||
page-title: "一张数据量很大的表,SQL分页查询特别耗时,你有什么优化方案? - 董川民"
|
||||
url: https://www.dongchuanmin.com/mysql/2101.html
|
||||
date: "2023-09-06 17:43:56"
|
||||
---
|
||||
像标题那样的问题,你一般都是如何去做查询呢?下面来看看,实际开发中我们会遇到,面试的时候也是会被问到的问题。
|
||||
|
||||
在开发过程中我们经常会使用分页,核心技术是使用limit进行数据的读取,在使用limit进行分页的测试过程中,得到以下数据:.
|
||||
|
||||
```
|
||||
select * from news order by id desc limit 0,10
|
||||
耗时0.003秒
|
||||
select * from news order by id desc limit 10000,10
|
||||
耗时0.058秒
|
||||
select * from news order by id desc limit 100000,10
|
||||
耗时0.575秒
|
||||
select * from news order by id desc limit 1000000,10
|
||||
耗时7.28秒
|
||||
```
|
||||
|
||||
我们惊讶的发现mysql在数据量大的情况下分页起点越大查询速度越慢,100万条起的查询速度已经需要7秒钟。这是一个我们无法接受的数值!
|
||||
|
||||
**改进方案 1**
|
||||
|
||||
```
|
||||
select * from news
|
||||
where id > (select id from news order by id desc limit 1000000, 1)
|
||||
order by id desc
|
||||
limit 0,10
|
||||
```
|
||||
|
||||
查询时间 0.365秒,提升效率是非常明显的!!原理是什么呢???
|
||||
|
||||
我们使用条件对id进行了筛选,在子查询 (select id from news order by id desc limit 1000000, 1) 中我们只查询了id这一个字段比起select \* 或 select 多个字段 节省了大量的查询开销!
|
||||
|
||||
**改进方案2**
|
||||
|
||||
适合id连续的系统,速度极快!
|
||||
|
||||
```
|
||||
select * from news
|
||||
where id between 1000000 and 1000010
|
||||
order by id desc
|
||||
```
|
||||
|
||||
不适合带有条件的、id不连续的查询。速度非常快!
|
||||
|
||||
**百万数据分页的注意事项**
|
||||
|
||||
接上一节,我们加上查询条件:
|
||||
|
||||
```
|
||||
select id from news
|
||||
where cate = 1
|
||||
order by id desc
|
||||
limit 500000 ,10
|
||||
```
|
||||
|
||||
查询时间 20 秒
|
||||
|
||||
好恐怖的速度!!利用上面方案进行优化:
|
||||
|
||||
```
|
||||
select * from news
|
||||
where cate = 1 and id > (select id from news where cate = 1 order by id desc limit 500000,1 )
|
||||
order by id desc
|
||||
limit 0,10
|
||||
```
|
||||
|
||||
查询时间 15 秒
|
||||
|
||||
优化效果不明显,条件带来的影响还是很大!在这样的情况下无论我们怎么去优化sql语句就无法解决运行效率问题。
|
||||
|
||||
那么换个思路:建立一个索引表,只记录文章的id、分类信息,我们将文章内容这个大字段分割出去。
|
||||
|
||||
表 news2 \[ 文章表 引擎 myisam 字符集 utf-8 \]
|
||||
|
||||
\-------------------------------------------------
|
||||
|
||||
id int 11 主键自动增加
|
||||
|
||||
cate int 11 索引
|
||||
|
||||
在写入数据时将2张表同步,查询是则可以使用news2 来进行条件查询:
|
||||
|
||||
```
|
||||
select * from news
|
||||
where cate = 1 and id > (select id from news2 where cate = 1 order by id desc limit 500000,1 )
|
||||
order by id desc
|
||||
limit 0,10
|
||||
```
|
||||
|
||||
注意条件 id > 后面使用了news2 这张表!
|
||||
|
||||
运行时间 1.23秒,我们可以看到运行时间缩减了近20倍!!数据在10万左右是查询时间可以保持在0.5秒左右,是一个逐步接近我们能够容忍的值!
|
||||
|
||||
但是1秒对于服务器来说依然是一个不能接受的值!!还有什么可以优化的办法吗??
|
||||
|
||||
我们尝试了一个伟大的变化:
|
||||
|
||||
将 news2 的存储引擎改变为innodb,执行结果是惊人的!
|
||||
|
||||
```
|
||||
select * from news
|
||||
where cate = 1 and id > (select id from news2 where cate = 1 order by id desc limit 500000,1 )
|
||||
order by id desc
|
||||
limit 0,10
|
||||
```
|
||||
|
||||
只需要 0.2秒,非常棒的速度。
|
||||
|
||||
到了这一步,我们的分页优化完毕,显然是有很大的效果的。你自己可以测试一下!
|
||||
@@ -0,0 +1,95 @@
|
||||
---
|
||||
page-title: "用UBNT EdgeRouter X实现PPPoE拨号与IPv6 - Minaduki's Blog"
|
||||
url: https://www.minaduki.cn/2022/04/16/ubnt-edgerouter-x-pppoe-and-ipv6/
|
||||
date: "2023-10-17 20:37:41"
|
||||
---
|
||||
## Step 0:前言
|
||||
|
||||
疫情原因,学校开始了可能是近两年最严格的一次封校,进不了学校就只好在家里看看实验室文档,玩玩电脑,效率自然是不高的,于是就想着整点活干干,虽然和学校的事情并没什么相干,但是一来积累点经验,二来也可以减轻摸鱼的罪恶感。
|
||||
|
||||
一来二去,还是盯上了出租屋的网络,本来的网络环境也就一般,入户一个PT622电信光猫,光猫拨号,然后由于光猫没有WiFi房东还接了一个小米路由器4Q,这下不仅有复古风格的全百兆接口,更有现代乃至后现代风格的NAT叠叠乐拓扑,属实难绷。
|
||||
|
||||
不过话又说回来,其实网络本来不一定就要用顶级的配置,我始终觉得,符合需求并具有一定的拓展空间,就是最佳的方案,所以我现在若是像去年复习的时候一样每天到家玩会手机就睡,这套方案倒也没什么大不了的,不是自家的房子也不用考虑什么拓展;但是现在家里有了两个电脑,这百兆的内网带宽就有些捉襟见肘了,剪个视频传素材都能卡,再加上双重NAT导致和无耻联机都费劲,所以确实应该稍微改造一下。
|
||||
|
||||
正好手头有前几天从臧老板坑蒙拐骗来的一台UBNT EdgeRouter X,久仰优倍快的大名,今天就来配置看看。
|
||||
|
||||
## Step 1:光猫改桥接
|
||||
|
||||
鉴于寒假里的经验,找电信师傅肯定是行不通的,况且这也不是我自己的宽带,所以最好还是留下能够恢复如初的口子。
|
||||
|
||||
PT622这款光猫还是比较古老的,在论坛上很快就找到了漏洞,可以用备份配置文件的方式破解:
|
||||
在用普通用户登录光猫后,打开`/cgi-bin/upgrade.asp`页面,点击页面中的ROMFILE BACKUP按钮,在下载的`romfile.cfg`文件里,搜索`web_passwd`字段,就能够找到telecomadmin的超级密码。
|
||||
|
||||
> 家里光猫的passwd文件还在紧锣密鼓的破解中,但是显然用CPU爆破的话性能不够,目前在尝试用HashCat调用CUDA使用恰当的正则表达式猜测,如果后续有结果会更新。
|
||||
|
||||
登陆光猫后,定位到网络->宽带设置->Internet设置,连接名称选`4_INTERNET_B_VID_`,将模式改为Bridge,其他不用管,确认即可。如果有必要,建议先备份宽带的用户名和密码。
|
||||
|
||||
> 参考:[再发一次友华PT622光猫里面的密码,方便外面的人查找](https://www.right.com.cn/FORUM/forum.php?mod=viewthread&tid=934706#pid9110653 "再发一次友华PT622光猫里面的密码,方便外面的人查找")
|
||||
|
||||
## Step 2:配置主路由
|
||||
|
||||
UBNT的设备确实比较高端,似乎还更鼓励用户通过命令行的方式对设备进行配置,不过好在今天的配置项足够简单,用Web UI就可以完成。
|
||||
|
||||
对于PPPoE这样的基本操作,UBNT的EdgeOS提供了几个Wizard,可以配置基本的组网方式,包括多个LAN或者链路聚合等情况,普通上网只需要选择Basic Setup,选择PPPoE并输入账号密码即可。为了使用IPv6,所以我这里选上了Enable DHCPv6 Prefix Delegation,并设置前缀长度为60,然后完成向导并重启路由器。
|
||||
|
||||
重启后,还需要修改路由器的配置树,启用`interfaces / ethernet / eth0 / pppoe / 0 / ipv6 / address / autoconf`和`interfaces / ethernet / eth0 / pppoe / 0 / ipv6 / enable`两个条目,即点击树中该项目右侧的加号,然后应用修改,稍等片刻就能获取到IPv6地址了。
|
||||
|
||||
> 参考:[七海网络教学 1: EdgeRouter 启用IPv6](https://www.bilibili.com/video/av90572075 "七海网络教学 1: EdgeRouter 启用IPv6")
|
||||
|
||||
## Step 3:配置UPnP和硬件加速
|
||||
|
||||
使用EdgeOS的UPnP Wizard,添加一个Internal Interface为switch0,External Interface为pppoe0的UPnP转发,即可完成UPnP的配置。
|
||||
|
||||
不过根据一些文章的说法,UPnP服务并不安全,更推荐的做法是使用更为现代的UPnP2,EdgeRouter支持UPnP2,但是仅能通过CLI开启。
|
||||
|
||||
> UPnP2就很安全吗?
|
||||
> 其实也未必,有不少研究表示UPnP2也有可以利用的漏洞。事实上,在引入任何“自动”的工具之前,都应该仔细权衡利弊,因为一旦选择了便利性,就必然会牺牲安全作为代价,风险控制和损害管制是设计一个系统时不可缺少的细节。
|
||||
|
||||
首先,删除已有的UPnP配置项:
|
||||
|
||||
```
|
||||
configure
|
||||
delete service upnp
|
||||
commit
|
||||
save
|
||||
exit
|
||||
```
|
||||
|
||||
然后,配置UPnP2:
|
||||
|
||||
```
|
||||
configure
|
||||
set service upnp2 listen-on switch0
|
||||
set service upnp2 wan pppoe0
|
||||
set service upnp2 secure-mode enable
|
||||
set service upnp2 nat-pmp enable
|
||||
commit
|
||||
save
|
||||
exit
|
||||
```
|
||||
|
||||
重启后,可以使用`show upnp2 rules`查看配置结果。
|
||||
|
||||
> Web UI自带的Web Shell登录进去要卡一段时间,是正常现象,不是出问题了。
|
||||
> 而且这玩意儿重启好慢啊,可能是因为MIPS架构的吧。
|
||||
>
|
||||
> 参考:[UPnP with EdgeRouter: Don’t do it! · GitHub](https://gist.github.com/plembo/c7f596ce6e690c6c022a6153c674f471 "UPnP with EdgeRouter: Don't do it! · GitHub")
|
||||
> [Ubiquiti EdgeRouter 配置 UPnP2 啟用方法](https://www.sakamoto.blog/ubiquiti-edgerouter-upnp2/ "Ubiquiti EdgeRouter 配置 UPnP2 啟用方法")
|
||||
|
||||
另外,UBNT的设备内置了用于转发加速的硬件,按照网友的测试,如果使用软件转发仅有百兆水平,而开启硬件加速就可以跑满。但硬件加速并不是默认开启的,需要手动通过命令行启用:
|
||||
|
||||
```
|
||||
configure
|
||||
set system offload hwnat enable
|
||||
commit
|
||||
save
|
||||
```
|
||||
|
||||
按照官方推荐,启用后最好重启,可以使用`show ubnt offload`命令查看硬件加速是否加载成功。
|
||||
|
||||
> 参考:[EdgeMax – 如何开启 IP offload 进行硬件加速](https://help.ui.com.cn/articles/115000117142/ "EdgeMax - 如何开启 IP offload 进行硬件加速")
|
||||
> [EdgeRouter拨号200M宽带一定务必打开PPPoE offload](https://www.chiphell.com/thread-1233957-1-1.html "EdgeRouter拨号200M宽带一定务必打开PPPoE offload")
|
||||
|
||||
## Step -1:尾声
|
||||
|
||||
其实这篇文章的篇幅实在是不太长,但是为了记录经验,所以还是写了下来。而且这个篇幅不应该作为独立的一篇,更适合作为Operation Reloaded的一个额外的部分附在最后,不过想了想,我还是把它单独发了,一方面是久了没写东西,需要写点“要发出来的”文章熟悉熟悉感觉,而不是写一堆只有自己看得懂的半吊子流水账屯在草稿箱里,另一方面,我欠的债也属实有点多,除了一直在规划的Operation Rebirth记录和百T纪念之外,社团里我还欠了一篇远程访问的推送没写(欠了一年多了),把这篇发出来,也算是给自己提供下继续的动力吧。
|
||||
Reference in New Issue
Block a user