refactor(vault): Phase 2 — root directory cleanup and clipper migration
- Remove dead services: .scripts/memory/, compose.yml, initdb/, specs/
- Remove root散件: package-lock.json, install.sh, LICENSE, FIRST_RUN,
  .failed_images.txt, .upgrade-checklist.md, 未命名*.md, Untitled Kanban.md
- Move chinese-to-english-mapping.csv → .scripts/
- Migrate 00_Inbox/Clippings/ → 04_Archive/Inbox-Clippings/
- Fix self-nesting bug: 2024/11/2023/ → 2023/ (73 files relocated)
- Fix verifier false-positive on its own regex patterns
This commit is contained in:
 windyboy
@@ -1,49 +0,0 @@
|
||||
---
|
||||
page-title: "GOPROXY.IO - A Global Proxy for Go Modules"
|
||||
url: https://goproxy.io/
|
||||
date: "2025-01-10 12:18:47"
|
||||
---
|
||||
|
||||
> $env:GOPROXY \= "https://goproxy.io,direct"
|
||||
|
||||
---
|
||||
|
||||
**Bash (Linux or macOS)**
|
||||
|
||||
```
|
||||
# Set the GOPROXY environment variable
|
||||
export GOPROXY=https://goproxy.io,direct
|
||||
# Set environment variable allow bypassing the proxy for specified repos (optional)
|
||||
export GOPRIVATE=git.mycompany.com,github.com/my/private
|
||||
```
|
||||
|
||||
**PowerShell (Windows)**
|
||||
|
||||
```
|
||||
# Set the GOPROXY environment variable
|
||||
$env:GOPROXY = "https://goproxy.io,direct"
|
||||
# Set environment variable allow bypassing the proxy for specified repos (optional)
|
||||
$env:GOPRIVATE = "git.mycompany.com,github.com/my/private"
|
||||
```
|
||||
|
||||
Now, when you build your applications, `Go` will fetch dependencies via goproxy.io. You can also permanently export the `GOPROXY` environment in `~/.bashrc` or `~/.profile` file. If Go version < 1.13, we recommend you [update to the latest version](https://go.dev/dl/). See more information in the [documention](https://goproxy.io/docs/getting-started.html).
|
||||
|
||||
#### Fast
|
||||
|
||||
Global proxy servers, including Las Vegas, Hong Kong etc.
|
||||
|
||||
#### Reliable
|
||||
|
||||
Enterprise monitor and alert system. Promise 99.99% uptime SLA.
|
||||
|
||||
#### Open Source
|
||||
|
||||
One of most active go modules proxy projects.
|
||||
|
||||
#### Checksum Database
|
||||
|
||||
Support sum.golang.org proxy.
|
||||
|
||||
### Who are using goproxy.io
|
||||
|
||||

|
||||
-80
@@ -1,80 +0,0 @@
|
||||
---
|
||||
page-title: "How to Find all Files Containing Specific Text (string) on Linux - GeeksforGeeks"
|
||||
url: https://www.geeksforgeeks.org/how-to-find-all-files-containing-specific-text-string-on-linux/
|
||||
date: "2025-01-03 20:38:40"
|
||||
---
|
||||
## How to Find all Files Containing Specific Text (string) on Linux
|
||||
|
||||
Last Updated : 31 Jul, 2023
|
||||
|
||||
Suppose you are looking for a file in Linux, but you have forgotten its name. You only remember the contents of the file. How will you find the file in this case? Well, there are some useful methods that will help you find a file containing a specific text (or string) in Linux. The string needs to be specified by the user. So, let’s take a look at the methods:
|
||||
|
||||
## Methods to Find All Files Containing Specific Text (string) on Linux
|
||||
|
||||
### Method 1: grep command
|
||||
|
||||
[grep command](https://www.geeksforgeeks.org/grep-command-in-unixlinux/) in Linux that is used to search for files containing a specific text or string. By default, it shows us the lines in the files that contain the particular text. If we append the -l option to it, the command will show us all the files that contain the particular text.
|
||||
|
||||
****Example:****
|
||||
|
||||
Suppose, we have a directory that contains two files named file1.txt and file2.txt.
|
||||
|
||||
****Contents of file1.txt:****
|
||||
|
||||
This line contains text.
|
||||
|
||||
****Contents of file2.txt:****
|
||||
|
||||
You should learn Data Structures & Algorithms.
|
||||
|
||||
Now, we will use the grep command with the -l option to search for text in given files located inside the current directory. See the following example:
|
||||
|
||||

|
||||
|
||||
It can be clearly said from the above example that the grep command has successfully found the given string in file1.txt. As a result, it displayed the file name on the screen.
|
||||
|
||||
We can also use the -i option to tell grep to ignore the case. Look at the following example:
|
||||
|
||||

|
||||
|
||||
Above, we have first used the previous command, but the given string is Text. Because file1.txt contains text, not Text, it is not taken into consideration. Here, the search operation is performed keeping the case in mind. Then, we used the -i option. As a result, the case is ignored and the given string matches with the one that file1.txt contains. Hence, the file name is displayed on the screen.
|
||||
|
||||
Another variation is to use the -r option. It suggests grep to search for the given string in the current directory and its subdirectories recursively. Look at the below example:
|
||||
|
||||

|
||||
|
||||
file1.txt and file2.txt are located in the files folder, not in the current directory, i.e. desktop. So, if we don’t use the -r option, no files with matching strings will be found because they don’t exist in the current directory. But we used the -r option and also omitted the file names. As a result, grep searches for matching strings in not only the current directory but also in its subdirectories as well. Hence, file1.txt is found and displayed on the screen.
|
||||
|
||||
### Method 2: The combination of find and grep command
|
||||
|
||||
[find](https://www.geeksforgeeks.org/find-command-in-linux-with-examples/) is another useful command in Linux. We will combine find with the -type f option to search for files and the -exec option to apply to grep on the files that are found. Look at the following example:
|
||||
|
||||

|
||||
|
||||
Clearly, the search operation finds file1.txt as it contains the matching string. Hence, the file name is displayed on the screen.
|
||||
|
||||
### Method 3: Find files containing specific text with mc
|
||||
|
||||
We can also search for files using Midnight Commander (mc). Open the application and press Alt + Shift + ? to open the Find File dialogue box. You will see a Starting box at the top. In the box, type the path where the files exist. Then, under the content box, type the string you want to search. In our case, we searched for text in the Files directory:
|
||||
|
||||

|
||||
|
||||
It can be clearly seen below that the search operation has successfully found file1.txt, which contains the matching string.
|
||||
|
||||

|
||||
|
||||
### Method 4: ripgrep command
|
||||
|
||||
ripgrep (written as rg) is a command that can be used as an alternative to the grep command. The implementation is below:
|
||||
|
||||

|
||||
|
||||
file1.txt is found and hence, the file name is displayed on the screen.
|
||||
|
||||
### Method 5: ack command
|
||||
|
||||
Yet another command we can use is the ack command. Here is the implementation:
|
||||
|
||||

|
||||
|
||||
file1.txt is successfully found and displayed on the screen.
|
||||
@@ -1,193 +0,0 @@
|
||||
---
|
||||
page-title: "Windows 10 Virtualization with KVM - Funtoo"
|
||||
url: https://www.funtoo.org/Windows_10_Virtualization_with_KVM
|
||||
date: "2025-01-08 13:43:29"
|
||||
---
|
||||
|
||||
> https://www.microsoft.com/en-us/software-download/windows10ISO
|
||||
|
||||
---
|
||||
|
||||
Support Funtoo!
|
||||
|
||||
*Get an **awesome** Funtoo container and support Funtoo!* See [Funtoo Containers](https://www.funtoo.org/Funtoo_Containers "Funtoo Containers") for more information.
|
||||
|
||||
This page describes how to set up Funtoo Linux to run Windows 10 Home/Professional 64-bit within a KVM virtual machine. KVM is suitable for running Windows 10 for general desktop application use. It does not provide 3D support, but offers a nice, high-performance virtualization solution for day-to-day productivity applications. It is also very easy to set up.
|
||||
|
||||
Warning
|
||||
|
||||
While this page provides a good introduction to how to run Windows 10 with Linux KVM, some parts of these instructions are specific to [Funtoo Linux](https://www.funtoo.org/Welcome "Welcome"). They may need to be adapted somewhat for other Linux distributions. But we are happy to have this page be a good general resource for Windows 10 under KVM for all Linux distros. If you have adaptations to the docs for other Linux distributions, please feel free leaving the steps at [the talk page](https://www.funtoo.org/Windows_10_Virtualization_with_KVM/Talk "Windows 10 Virtualization with KVM/Talk") and we'll consider adding them.
|
||||
|
||||
## Introduction
|
||||
|
||||
KVM is a hardware-accelerated full-machine hypervisor and virtualization solution included as part of kernel 2.6.20 and later. It allows you to create and start hardware-accelerated virtual machines under Linux using the QEMU tools.
|
||||
|
||||
[](https://www.funtoo.org/File:Windows7virt.png "Windows 7 Professional 32-bit running within qemu-kvm")
|
||||
|
||||
### KVM Setup
|
||||
|
||||
You will need KVM to be set up on the machine that will be running the virtual machine. This can be a local Linux system, or if you are using SPICE (see [SPICE](https://www.funtoo.org/Windows_10_Virtualization_with_KVM#SPICE_.28Accelerated_Remote_Connection.29)), a local or remote system. See the SPICE section for tweaks that you will need to make to these instructions if you plan to run Windows 10 on a Funtoo Linux system that you will connect to remotely.
|
||||
|
||||
Follow these steps for the system that will be running the virtual machine.
|
||||
|
||||
If you are using an automatically-built kernel, it is likely that kernel support for KVM is already available.
|
||||
|
||||
If you build your kernel from scratch, please see [the KVM page](https://www.funtoo.org/KVM "KVM") for detailed instructions on how to enable KVM. These instructions also cover the process of emerging qemu, which is also necessary. [Do this first, as described on the KVM page](https://www.funtoo.org/KVM "KVM") -- then come back here.
|
||||
|
||||
Important
|
||||
|
||||
Before using KVM, be sure that your user account is in the kvm group so that qemu can access /dev/kvm. You will need to use a command such as vigr as root to do this, and then log out and log back in for this to take effect.
|
||||
|
||||
Prior to using KVM, modprobe the appropriate accelerated driver for Intel or AMD, as root:
|
||||
|
||||
root # modprobe kvm\_intel
|
||||
|
||||
### Windows 10 ISO Images
|
||||
|
||||
In this tutorial, we are going to install Windows 10 Home, 64-bit Edition. Microsoft provides a free download of the ISO DVD image, but this does require a valid license key for installation. You can download the ISO at the following location:
|
||||
|
||||
[https://www.microsoft.com/en-us/software-download/windows10ISO](https://www.microsoft.com/en-us/software-download/windows10ISO)
|
||||
|
||||
Note
|
||||
|
||||
Windows 10 is a free download but requires a valid license key for installation.
|
||||
|
||||
In addition, it's highly recommended that you download "VirtIO" drivers produced by Red Hat. These drivers are installed under Windows and significantly improve Windows 10 network and disk performance. You want to download the ISO file (not the ZIP file) at the following location:
|
||||
|
||||
[https://fedorapeople.org/groups/virt/virtio-win/direct-downloads/latest-virtio/](https://fedorapeople.org/groups/virt/virtio-win/direct-downloads/latest-virtio/)
|
||||
|
||||
Note
|
||||
|
||||
At the time of this writing, the latest version of the virtio ISO is `virtio-win-0.1.149.iso`
|
||||
|
||||
### Create Raw Disk
|
||||
|
||||
In this tutorial, we are going to create a 30GB raw disk image for Windows 10. Raw disk images offer better performance than the commonly-used QCOW2 format. Do this as a regular user:
|
||||
|
||||
user $ cd
|
||||
user $ mkdir vm
|
||||
user $ cd vm
|
||||
user $ qemu-img create -f raw win10.img 30G
|
||||
|
||||
We now have an empty virtual disk image called `win10.img` in our home directory.
|
||||
|
||||
### QEMU script
|
||||
|
||||
Now, we'll create the following script to start our virtual machine and begin Windows 10 installation. Note that this script assumes that the two ISO files downloaded earlier were placed in the `vm` directory we created. Adjust paths as necessary if that is not the case. Also be sure to adjust the following parts of the script:
|
||||
|
||||
- Adjust the name of VIRTIMG to match the exact name of the VirtIO ISO image you downloaded earlier
|
||||
- Adjust the smp option to use the number of CPU cores and threads (if your system has hyperthreading) of your Linux system's CPU.
|
||||
- Adjust memory allocated to the VM to be a fraction of your system's RAM (currently 6GB via `-m 6144` setting)
|
||||
|
||||
Use your favorite text editor to create the following script. Name it something like `vm.sh`:
|
||||
|
||||
(bash source code)
|
||||
|
||||
#!/bin/sh
|
||||
WINIMG\=~/vm/Win10\_1803\_English\_x64.iso
|
||||
VIRTIMG\=~/vm/virtio-win-0.1.149.iso
|
||||
qemu-system-x86\_64 --enable-kvm -drive driver\=raw,file\=~/vm/win10.img,if\=virtio -m 6144 \\
|
||||
-net nic,model\=virtio -net user -cdrom ${WINIMG} \\
|
||||
-drive file\=${VIRTIMG},index\=3,media\=cdrom \\
|
||||
-rtc base\=localtime,clock\=host -smp cores\=4,threads\=8 \\
|
||||
-usb -device usb-tablet \\
|
||||
-net user,smb\=$HOME
|
||||
|
||||
Now, make the script executable:
|
||||
|
||||
user $ chmod +x vm.sh
|
||||
|
||||
Here is a brief summary of what the script does. It starts the qemu-kvm program and instructs it to use KVM to accelerate virtualization. The display will be shown locally, in a window. If you are using the SPICE method, described later in this document, no window will appear, and you will be able to connect remotely to your running virtual machine.
|
||||
|
||||
The system disk is the 30GB raw image you created, and we tell QEMU to use "virtio" mode for this disk, as well as "virtio" for network access. This will require that we install special drivers during installation to access the disk and enable networking, but will give us better performance.
|
||||
|
||||
To assist us in installing the VirtIO drivers, we have configured the system with two DVD drives -- the first holds the Windows 10 installation media, and the second contains the VirtIO driver ISO that we will need to access during Windows 10 installation.
|
||||
|
||||
The `-usb -device usb-tablet` option will cause our mouse and keyboard interaction with our virtual environment to be intuitive and easy to use.
|
||||
|
||||
Important
|
||||
|
||||
For optimal performance, adjust the script so that the \-smp option specifies the exact number of cores and threads on your system -- on non-HyperThreading systems (AMD and some Intel), simply remove the ,threads=X option entirely and just specify cores. Also ensure that the \-m option provides enough RAM for Windows 10, without eating up all your system's RAM. On a 4GB Linux system, use 1536. For an 8GB system, 2048 is safe. 6144 is ideal if you have 16GB+ of Linux RAM.
|
||||
|
||||
### Installation of Windows 10
|
||||
|
||||
To begin installation, run the script:
|
||||
|
||||
user $ ./vm.sh
|
||||
|
||||
The Windows 10 ISO image will boot and installation will begin. Everything should proceed as expected for a Windows 10 installation until the point where you need to select a destination disk.
|
||||
|
||||
[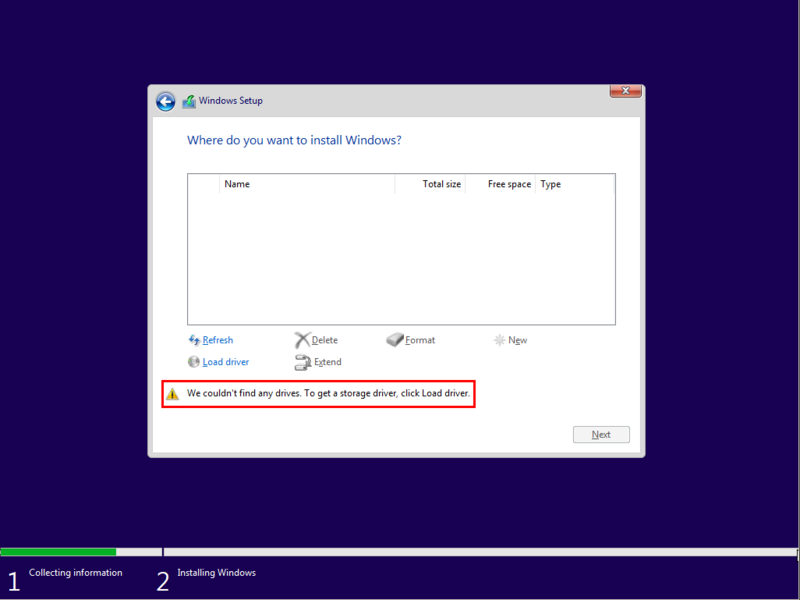](https://www.funtoo.org/File:Win10_install_no_drives.png "Win10 install no drives")
|
||||
|
||||
Since we are using the virtio driver, we will need to manually load this driver so that the 30GB disk image is visible for installation. To do this, you will see an option to manually install a driver. Select this option, and navigate to the Red Hat virtio ISO (available under your Windows VM) and to the `E:\viostor\w10\amd64` directory.
|
||||
|
||||
[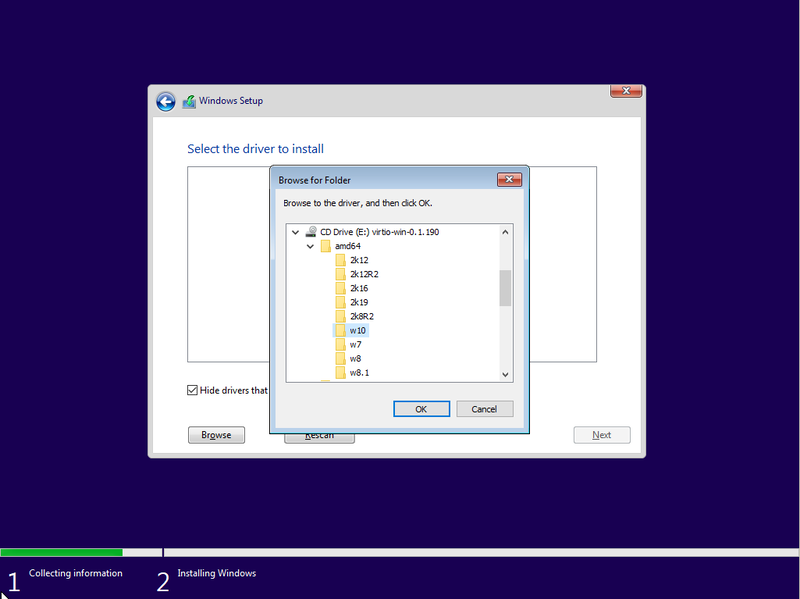](https://www.funtoo.org/File:Win10_install_manually_install_driver.png "Win10 install manually install driver")
|
||||
|
||||
After selecting this directory, the Windows 10 installer will spend a minute or two configuring the driver, after which you should be able to see 30 GB of free storage available for Windows installation.
|
||||
|
||||
[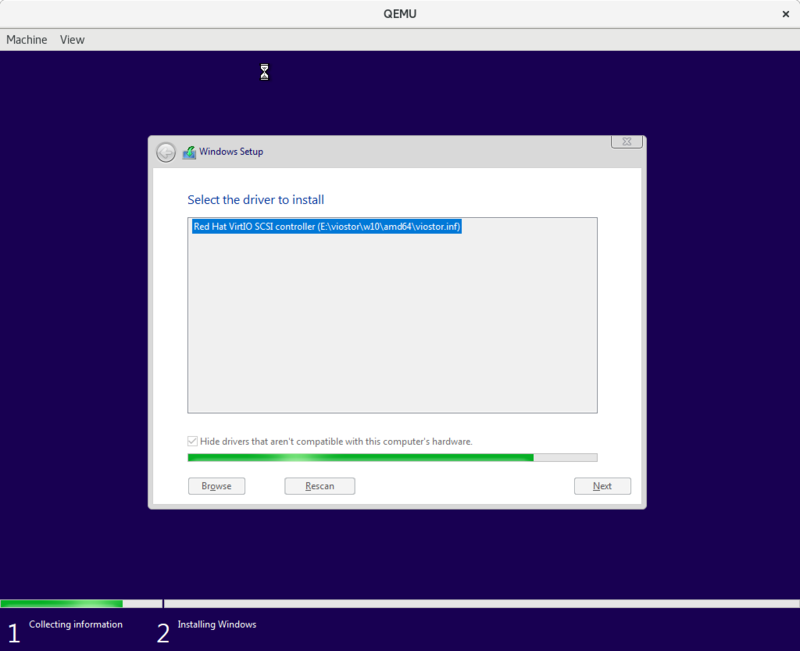](https://www.funtoo.org/File:Windows-setup.png "Windows 10 - Installing virtio storage driver")
|
||||
|
||||
Proceed with the installation process as normal.
|
||||
|
||||
### Installation of Network Drivers
|
||||
|
||||
Once Windows 10 installation has completed, you will notice that although Windows is installed, no network or sound is available. We will not cover enabling sound in this document, as sound support in qemu is choppy by default (whether using alsa or pulseaudio) and really deserves its own document for proper configuration since it's so tricky to get perfect. But networking is essential, and we will want to your VM on the network.
|
||||
|
||||
To do this, open Device Manager in Windows and select the network adapter, and right-click on it and choose `Update Driver`. Then navigate to the virtio CD, path `E:\NetKVM\w10\amd64` and install the driver. Your network will now be enabled.
|
||||
|
||||
### Accessing Files on your Linux System
|
||||
|
||||
Our `vm.sh` by default enables built-in Samba support to allow easy access to files in your home directory. To enable this capability, type `\\10.0.2.4\qemu` in the Windows 10 search bar, and hit Enter. Windows should prompt you to create a network drive to this path. Do so, mapping it to drive Z, and click OK. You should now be able to access your Linux home directory as drive Z.
|
||||
|
||||
In newer versions of windows, guest authentication fallback for file shares is blocked according to [https://support.microsoft.com/en-us/help/4046019/guest-access-in-smb2-disabled-by-default-in-windows-10-and-windows-ser](https://support.microsoft.com/en-us/help/4046019/guest-access-in-smb2-disabled-by-default-in-windows-10-and-windows-ser) .
|
||||
|
||||
From the support link, this can be bypassed by navigating to the following group policy setting and enabling it.
|
||||
|
||||
`Computer Configuration\Administrative Templates\Network\Lanman Workstation`
|
||||
|
||||
`"Enable insecure guest logons"`
|
||||
|
||||
## SPICE (Accelerated Remote Connection)
|
||||
|
||||
SPICE is a new technology that has been incorporated into QEMU, which allows the virtual machine to run on one system, and allows you to use `spicy`, the SPICE client, to connect to your remote virtual machine. In real-world use, you can run a SPICE server (via QEMU) and client on the same machine if you like, or have them on the same local area network, or have server and client connect over an Internet connection. Here are some important facts about SPICE:
|
||||
|
||||
- SPICE provides accelerated, optimized video updates over the network, similar to VNC
|
||||
- QEMU can be configured to run a SPICE server, which you can connect to via `spicy`, the SPICE client. The SPICE client renders to a local window on your system.
|
||||
- SPICE allows easy copying and pasting across operating systems -- for example, you can copy something in GNOME, paste it into the `spicy` window and have it appear on your Windows 10 system.
|
||||
|
||||
### SPICE Setup
|
||||
|
||||
To set up SPICE, you need to perform the following changes to the "standard" steps described in this document:
|
||||
|
||||
1. Emerge QEMU with the `spice` USE variable on the system that will be running the Windows 10 virtual machine.
|
||||
2. Emerge `app-emulation/virt-viewer` on the system that you will be using to connect to your remote Windows 10 virtual machine.
|
||||
3. In the `vm.sh` script, remove the existing `-vga vmware` `qemu-kvm` option, and add these options: `-vga qxl -device virtio-serial-pci -spice port=5900,password=mypass -device virtserialport,chardev=spicechannel0,name=com.redhat.spice.0 -chardev spicevmc,id=spicechannel0,name=vdagent`
|
||||
4. Run `vm.sh` as described in the next section on your remote server (your Windows 10 system will now boot, but you can't see the virtual machine display) and then connect to it by running the following command on your local system:
|
||||
|
||||
root # spicy -h remotehost -p 5900 -w mypass
|
||||
|
||||
The SPICE client window will appear locally and allow you to interact with your Windows 10 system.
|
||||
|
||||
Note
|
||||
|
||||
Browse all our available articles below. Use the search field to search for topics and keywords in real-time.
|
||||
|
||||
Show entries
|
||||
|
||||
Search:
|
||||
|
||||
| | Article | Subtitle |
|
||||
| --- | --- | --- |
|
||||
| | Article | Subtitle |
|
||||
| | [Awk by Example, Part 1](https://www.funtoo.org/Awk_by_Example,_Part_1 "Awk by Example, Part 1") | An intro to the great language with the strange name |
|
||||
| | [Awk by Example, Part 2](https://www.funtoo.org/Awk_by_Example,_Part_2 "Awk by Example, Part 2") | Records, loops, and arrays |
|
||||
| | [Awk by Example, Part 3](https://www.funtoo.org/Awk_by_Example,_Part_3 "Awk by Example, Part 3") | String functions and ... checkbooks? |
|
||||
| | [Bash by Example, Part 1](https://www.funtoo.org/Bash_by_Example,_Part_1 "Bash by Example, Part 1") | Fundamental programming in the Bourne again shell (bash) |
|
||||
| | [Bash by Example, Part 2](https://www.funtoo.org/Bash_by_Example,_Part_2 "Bash by Example, Part 2") | More bash programming fundamentals |
|
||||
| | [Bash by Example, Part 3](https://www.funtoo.org/Bash_by_Example,_Part_3 "Bash by Example, Part 3") | Exploring the ebuild system |
|
||||
| | [BTRFS Fun](https://www.funtoo.org/BTRFS_Fun "BTRFS Fun") | |
|
||||
| | [Funtoo Filesystem Guide, Part 1](https://www.funtoo.org/Funtoo_Filesystem_Guide,_Part_1 "Funtoo Filesystem Guide, Part 1") | Journaling and ReiserFS |
|
||||
| | [Funtoo Filesystem Guide, Part 2](https://www.funtoo.org/Funtoo_Filesystem_Guide,_Part_2 "Funtoo Filesystem Guide, Part 2") | Using ReiserFS and Linux |
|
||||
| | [Funtoo Filesystem Guide, Part 3](https://www.funtoo.org/Funtoo_Filesystem_Guide,_Part_3 "Funtoo Filesystem Guide, Part 3") | Tmpfs and Bind Mounts |
|
||||
|
||||
Showing 1 to 10 of 45 entries
|
||||
@@ -1,331 +0,0 @@
|
||||
---
|
||||
page-title: "iDvel/rime-ice: Rime 配置:雾凇拼音 | 长期维护的简体词库"
|
||||
url: https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E4%B8%9C%E9%A3%8E%E7%A0%B4-plum
|
||||
date: "2025-01-15 10:07:31"
|
||||
---
|
||||
## 雾凇拼音
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E9%9B%BE%E5%87%87%E6%8B%BC%E9%9F%B3)
|
||||
|
||||
[GPL-3.0-only](https://spdx.org/licenses/GPL-3.0-only.html)
|
||||
|
||||
[](https://github.com/iDvel/rime-ice/blob/main/others/demo.webp)
|
||||
|
||||
功能齐全,词库体验良好,长期更新修订。
|
||||
|
||||
[Rime Input Method Engine / 中州韵输入法引擎](https://rime.im/) 是一个跨平台的输入法算法框架。
|
||||
|
||||
这里是 Rime 的一份配置仓库,用户需要下载各平台对应的前端,并将此配置应用到配置目录。
|
||||
|
||||
雾凇拼音提供了一套开箱即用的完整配置,包含输入方案(全拼、常见双拼)、长期维护的开源词库及各项扩展功能。
|
||||
|
||||
详细介绍:[Rime 配置:雾凇拼音](https://dvel.me/posts/rime-ice/)
|
||||
|
||||
[常见问题](https://github.com/iDvel/rime-ice/issues/133)
|
||||
|
||||
[更新日志](https://github.com/iDvel/rime-ice/blob/main/others/CHANGELOG.md)
|
||||
|
||||
## 基本套路
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E5%9F%BA%E6%9C%AC%E5%A5%97%E8%B7%AF)
|
||||
|
||||
- 简体 | 全拼 | 双拼
|
||||
- 主要功能
|
||||
- 轻量的英文输入,支持中英混输
|
||||
- [优化英文输入体验](https://dvel.me/posts/make-rime-en-better/)
|
||||
- 拆字反查(uU+拼音),拆字辅码(拼音+\`+拆字辅码)
|
||||
- 自整理的 Emoji
|
||||
- 以词定字(左右中括号:\[、\])
|
||||
- 长词优先
|
||||
- Unicode(U+Unicode 码位)
|
||||
- 数字、人民币大写(R+数字)
|
||||
- 日期、时间、星期(详见方案 `/date_translator` 节点)
|
||||
- 农历(转写:N+八位数字;获取当前农历:全拼nl,双拼lunar)
|
||||
- 简易计算器(cC+算式)
|
||||
- 常见错音错字提示
|
||||
- 置顶候选项(详见方案 `/pin_cand_filter` 节点)
|
||||
- 所有标点符号直接上屏
|
||||
- 特殊符号、字符输入(全拼v+首字母缩写;双拼V+首字母缩写)
|
||||
- 拼音纠错(模糊音)
|
||||
- 更多默认未启用的功能请参考 `lua/` 及方案注释
|
||||
- 简体字表、词库
|
||||
- [通用规范汉字表](https://github.com/iDvel/The-Table-of-General-Standard-Chinese-Characters)(by 中华人民共和国教育部)8K 常用汉字
|
||||
- [Unihan 字库](https://www.unicode.org/Public/)(by Unicode lnc | [UNICODE LICENSE V3](https://www.unicode.org/license.txt))40K 大字库, **默认未启用**
|
||||
- [现代汉语常用词表](https://zh.wikipedia.org/wiki/%E7%8E%B0%E4%BB%A3%E6%B1%89%E8%AF%AD%E5%B8%B8%E7%94%A8%E8%AF%8D%E8%A1%A8)(by 中国国家语言文字工作委员会)
|
||||
- [华宇野风词库](http://bbs.pinyin.thunisoft.com/forum.php?mod=viewthread&tid=30049)(by 野风)
|
||||
- [简化字八股文](https://github.com/rime/rime-essay-simp)(by rime | [LGPL](https://github.com/rime/rime-essay-simp/blob/master/LICENSE))
|
||||
- [清华大学开源词库](https://github.com/thunlp/THUOCL)(by THUNLP | [MIT](https://github.com/thunlp/THUOCL/blob/master/LICENSE))
|
||||
- [腾讯词向量](https://ai.tencent.com/ailab/nlp/en/download.html)(@Huandeep [整理](https://github.com/iDvel/rime-ice/issues/24) | by Tencent AI Lab | [CC BY 3.0](https://creativecommons.org/licenses/by/3.0/))
|
||||
- 词库修订
|
||||
- 校对大量异形词、错别字、错误注音
|
||||
- 全词库完成注音
|
||||
- 同义多音字注音
|
||||
- 参考
|
||||
- 《现代汉语词典》
|
||||
- 《同义词词林》
|
||||
- 《新华成语大词典》
|
||||
- [校对标准论坛](http://www.jiaodui.com/bbs/)
|
||||
- Rime、Squirrel、Weasel 常用配置项的详尽注释
|
||||
|
||||
## 长期维护词库
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E9%95%BF%E6%9C%9F%E7%BB%B4%E6%8A%A4%E8%AF%8D%E5%BA%93)
|
||||
|
||||
因为没有找到一份比较好的词库,干脆自己维护一个。综合了几个不错的词库,精心调教了很多。
|
||||
|
||||
主要维护的词库:
|
||||
|
||||
- `8105` 字表。
|
||||
- `base` 基础词库。
|
||||
- `ext` 扩展词库,小词库。
|
||||
- `tencent` 扩展词库,大词库。
|
||||
- Emoji
|
||||
|
||||
维护内容主要是异形词、错别字的校对,错误注音的修正,缺失的常用词汇的增添,词频的调整。
|
||||
|
||||
欢迎在词库方面提 issue [#666](https://github.com/iDvel/rime-ice/issues/666) ,我会及时更新修正。
|
||||
|
||||
## 使用说明
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E4%BD%BF%E7%94%A8%E8%AF%B4%E6%98%8E)
|
||||
|
||||
### 选择和安装 RIME 前端
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E9%80%89%E6%8B%A9%E5%92%8C%E5%AE%89%E8%A3%85-rime-%E5%89%8D%E7%AB%AF)
|
||||
|
||||
要使用雾凇拼音默认提供的所有功能,请保证
|
||||
|
||||
- 您的 RIME 前端提供的 librime 版本 ≥ 1.8.5 且
|
||||
- 含有 librime-lua 依赖
|
||||
|
||||
以下是主流平台上的一些 RIME 前端安装建议。部分信息具有时效性,请以当下具体情况为准:
|
||||
|
||||
| 系统 | RIME 前端 | 雾凇拼音版本要求 | 备注 |
|
||||
| --- | --- | --- | --- |
|
||||
| Android | [fcitx5-android](https://github.com/fcitx5-android/fcitx5-android/releases) + plugin.rime(小企鹅输入法) | ≥ 0.0.8 | 暂不支持九宫格 |
|
||||
| Android | [Trime](https://github.com/osfans/trime)(同文输入法) | ≥ 3.2.11 | |
|
||||
| iOS | [Hamster](https://apps.apple.com/cn/app/%E4%BB%93%E8%BE%93%E5%85%A5%E6%B3%95/id6446617683)(仓输入法) | N/A | 闭源;有内购 |
|
||||
| Linux | ibus + [ibus-rime](https://github.com/rime/ibus-rime) | librime ≥ 1.8.5 且装有 librime-lua | 部分发行版需手动安装 librime-lua |
|
||||
| Linux | fcitx5 + [fcitx5-rime](https://github.com/fcitx/fcitx5-rime) | librime ≥ 1.8.5 且装有 librime-lua | 部分发行版需手动安装 librime-lua |
|
||||
| macOS | [Squirrel](https://github.com/rime/squirrel)(鼠须管) | ≥ 1.0.0 | 0.16.0 - 0.18.0 版本请参考[🔗](https://github.com/iDvel/rime-ice/issues/1062) |
|
||||
| macOS | [fcitx5-macos](https://github.com/fcitx-contrib/fcitx5-macos) | N/A | 支持[卷轴模式](https://github.com/iDvel/rime-ice/issues/941) |
|
||||
| Windows | [Weasel](https://github.com/rime/weasel)(小狼毫) | ≥ 0.15.0 | 0.14.3 可手动更新 [rime.dll](https://github.com/iDvel/rime-ice/issues/197)(但不支持彩色 emoji)
|
||||
Weasel 当下有兼容性问题,建议安装其他输入法备用 |
|
||||
|
||||
Linux 依赖问题的具体解释请参考 [#840](https://github.com/iDvel/rime-ice/issues/840)。
|
||||
|
||||
雾凇拼音的部分配置可能要求更高的 librime 或者客户端版本,这些功能已在具体配置文件中注明。
|
||||
|
||||
以下安装方式,选择其一:
|
||||
|
||||
- [手动安装](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E4%BD%BF%E7%94%A8%E8%AF%B4%E6%98%8E)
|
||||
- [Git 安装](https://github.com/iDvel/rime-ice?tab=readme-ov-file#git-%E5%AE%89%E8%A3%85)
|
||||
- [东风破 plum](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E4%B8%9C%E9%A3%8E%E7%A0%B4-plum)
|
||||
- [自动部署脚本](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E8%87%AA%E5%8A%A8%E9%83%A8%E7%BD%B2%E8%84%9A%E6%9C%AC)
|
||||
- [仓输入法](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E4%BB%93%E8%BE%93%E5%85%A5%E6%B3%95-hamster)
|
||||
- [Arch Linux](https://github.com/iDvel/rime-ice?tab=readme-ov-file#arch-linux)(AUR)
|
||||
|
||||
### 手动安装
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E6%89%8B%E5%8A%A8%E5%AE%89%E8%A3%85)
|
||||
|
||||
您可以将仓库打包下载,将所有文件复制粘贴到 RIME 前端的配置目录,重新部署。
|
||||
|
||||
只需要使用或者更新词库的话,可以手动粘贴覆盖 `cn_dicts` `en_dicts` `opencc` 三个文件夹。
|
||||
|
||||
Note
|
||||
|
||||
雾凇拼音中多个文件可能与其他方案同名冲突,如果是新手想一键安装,建议备份原先配置,**清空配置目录**再导入。
|
||||
|
||||
Note
|
||||
|
||||
单独使用词库注意事项:`rime_ice.dict.yaml` 下面包含了大写字母,这和配置有些许绑定,可以直接删除,详细说明:[#356](https://github.com/iDvel/rime-ice/issues/356)
|
||||
|
||||
您也可以前往 [Release](https://github.com/iDvel/rime-ice/releases) 界面,下载特定版本的词典文件(具体描述见 Release 说明),覆盖配置目录的对应文件。
|
||||
|
||||
### Git 安装
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#git-%E5%AE%89%E8%A3%85)
|
||||
|
||||
您如果熟悉 git 常用操作,可以使用 git clone 命令将本仓库克隆到对应前端的用户目录。由于本库提交历史较多且更改频繁,添加 `--depth` 参数可以显著减少传输体积。
|
||||
|
||||
git clone https://github.com/iDvel/rime-ice.git Rime --depth 1
|
||||
|
||||
# 更新
|
||||
cd Rime
|
||||
git pull
|
||||
|
||||
通过 checkout 命令,您也可以实现更新部分文件的效果。
|
||||
|
||||
### 东风破 [plum](https://github.com/rime/plum)
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E4%B8%9C%E9%A3%8E%E7%A0%B4-plum)
|
||||
|
||||
选择配方(`others/recipes/*.recipe.yaml`)来进行安装或更新。
|
||||
|
||||
/plum/ 简易安装和使用教程
|
||||
|
||||
---
|
||||
|
||||
安装 plum(仅需要执行一次)
|
||||
|
||||
# 请先安装 git 和 bash,并加入环境变量
|
||||
# 请确保和 github.com 的连接稳定
|
||||
cd ~
|
||||
git clone https://github.com/rime/plum.git plum
|
||||
# 卸载 plum 只需要删除 ~/plum 文件夹即可
|
||||
|
||||
更新 plum
|
||||
|
||||
cd ~/plum
|
||||
bash rime-install plum
|
||||
|
||||
使用 plum 安装「雾凇拼音」方案的韵书(recipe)
|
||||
|
||||
cd ~/plum
|
||||
bash rime-install iDvel/rime-ice:others/recipes/full
|
||||
|
||||
指定 RIME 前端为 fcitx5-rime
|
||||
|
||||
cd ~/plum
|
||||
rime\_frontend=fcitx5-rime bash rime-install iDvel/rime-ice:others/recipes/full
|
||||
|
||||
使用 plum 更新「雾凇拼音」的词库文件
|
||||
|
||||
cd ~/plum
|
||||
bash rime-install iDvel/rime-ice:others/recipes/all\_dicts
|
||||
|
||||
---
|
||||
|
||||
词库配方只是更新具体词库文件,并不更新 `rime_ice.dict.yaml` 和 `melt_eng.dict.yaml`,因为用户可能会挂载其他词库。如果更新后部署时报错,可能是增、删、改了文件名,需要检查上面两个文件和词库的对应关系。
|
||||
|
||||
℞ 安装或更新全部文件
|
||||
|
||||
```
|
||||
bash rime-install iDvel/rime-ice:others/recipes/full
|
||||
```
|
||||
|
||||
℞ 安装或更新所有词库文件(包含下面三个)
|
||||
|
||||
```
|
||||
bash rime-install iDvel/rime-ice:others/recipes/all_dicts
|
||||
```
|
||||
|
||||
℞ 安装或更新拼音词库文件( `cn_dicts/` 目录内所有文件)
|
||||
|
||||
```
|
||||
bash rime-install iDvel/rime-ice:others/recipes/cn_dicts
|
||||
```
|
||||
|
||||
℞ 安装或更新英文词库文件( `en_dicts/` 目录内所有文件)
|
||||
|
||||
```
|
||||
bash rime-install iDvel/rime-ice:others/recipes/en_dicts
|
||||
```
|
||||
|
||||
℞ 安装或更新 opencc ( `opencc/` 目录内所有文件)
|
||||
|
||||
```
|
||||
bash rime-install iDvel/rime-ice:others/recipes/opencc
|
||||
```
|
||||
|
||||
下面这个配方会在 `radical_pinyin.custom.yaml` 和 `melt_eng.custom.yaml` 里将 `speller/algebra` 修改为对应的双拼拼写,选择一个自己使用的双拼作为参数。
|
||||
|
||||
℞ 双拼补丁
|
||||
|
||||
```
|
||||
bash rime-install iDvel/rime-ice:others/recipes/config:schema=flypy
|
||||
bash rime-install iDvel/rime-ice:others/recipes/config:schema=double_pinyin
|
||||
bash rime-install iDvel/rime-ice:others/recipes/config:schema=mspy
|
||||
bash rime-install iDvel/rime-ice:others/recipes/config:schema=sogou
|
||||
bash rime-install iDvel/rime-ice:others/recipes/config:schema=abc
|
||||
bash rime-install iDvel/rime-ice:others/recipes/config:schema=ziguang
|
||||
```
|
||||
|
||||
℞ 下载特定版本的配置
|
||||
|
||||
在仓库后加 `@tag` 即可,例如:
|
||||
|
||||
bash rime-install iDvel/rime-ice@2024.05.21:others/recipes/full
|
||||
|
||||
### 仓输入法 [Hamster](https://github.com/imfuxiao/Hamster)
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E4%BB%93%E8%BE%93%E5%85%A5%E6%B3%95-hamster)
|
||||
|
||||
参考 [如何导入"雾凇拼音输入方案"](https://github.com/imfuxiao/Hamster/wiki/%E5%A6%82%E4%BD%95%E5%AF%BC%E5%85%A5%22%E9%9B%BE%E6%B7%9E%E6%8B%BC%E9%9F%B3%E8%BE%93%E5%85%A5%E6%96%B9%E6%A1%88%22)
|
||||
|
||||
仓输入法目前已内置雾凇拼音,也可以通过【输入方案设置 - 右上角加号 - 方案下载 - 覆盖并部署】来更新雾凇拼音。
|
||||
|
||||
使用九宫格,需要同时启用九宫格方案(输入方案设置)和九宫格布局(键盘设置 - 键盘布局 - 中文 9 键)。
|
||||
|
||||
### 自动部署脚本
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E8%87%AA%E5%8A%A8%E9%83%A8%E7%BD%B2%E8%84%9A%E6%9C%AC)
|
||||
|
||||
[Mark24Code/rime-auto-deploy](https://github.com/Mark24Code/rime-auto-deploy) 一个自动部署脚本,集成了雾凇拼音,帮助无痛快速安装、部署 Rime 输入法(中州韵、小狼毫,鼠须管)以及部署配置。
|
||||
|
||||
### Arch Linux
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#arch-linux)
|
||||
|
||||
使用 AUR helper 安装 [rime-ice-git](https://aur.archlinux.org/packages/rime-ice-git) 包即可。
|
||||
|
||||
# paru 默认会每次重新评估 pkgver,所以有新的提交时 paru 会自动更新,
|
||||
# yay 默认未开启此功能,可以通过此命令开启
|
||||
# yay -Y --devel --save
|
||||
|
||||
paru -S rime-ice-git
|
||||
# yay -S rime-ice-git
|
||||
|
||||
推荐使用[补丁](https://github.com/rime/home/wiki/Configuration#%E8%A3%9C%E9%9D%AA)的方式启用。
|
||||
|
||||
参考下面的配置示例,修改对应输入法框架用户目录(见下)中的 `default.custom.yaml` 文件
|
||||
|
||||
- iBus 为 `$HOME/.config/ibus/rime/`
|
||||
- Fcitx5 为 `$HOME/.local/share/fcitx5/rime/`
|
||||
|
||||
default.custom.yaml
|
||||
|
||||
patch:
|
||||
# 仅使用「雾凇拼音」的默认配置,配置此行即可
|
||||
\_\_include: rime\_ice\_suggestion:/
|
||||
# 以下根据自己所需自行定义,仅做参考。
|
||||
# 针对对应处方的定制条目,请使用 <recipe>.custom.yaml 中配置,例如 rime\_ice.custom.yaml
|
||||
\_\_patch:
|
||||
key\_binder/bindings/+:
|
||||
# 开启逗号句号翻页
|
||||
- { when: paging, accept: comma, send: Page\_Up }
|
||||
- { when: has\_menu, accept: period, send: Page\_Down }
|
||||
|
||||
## 感谢 ❤️
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E6%84%9F%E8%B0%A2-%EF%B8%8F)
|
||||
|
||||
特别感谢上文已经提及的词库、词典的作者、贡献者及整理者;特别感谢以及下列词库、方案、脚本的作者及贡献者(提及的均为 GitHub id):
|
||||
|
||||
- @mozillazg 开发的汉字转拼音工具和数据库(MIT)
|
||||
- [melt\_eng](https://github.com/tumuyan/rime-melt)(@tumuyan | [Apache 2.0](https://github.com/tumuyan/rime-melt/blob/master/LICENSE)) :提供了部分(约 1000 条)英文词汇以及原始英文方案参考;
|
||||
- [部件拆字方案](https://github.com/mirtlecn/rime-radical-pinyin)(@mirtlecn | [GPL 3.0](https://github.com/mirtlecn/rime-radical-pinyin/blob/master/LICENSE)):提供的拆字反查和候选筛选插件;
|
||||
- [长词优先插件](https://github.com/tumuyan/rime-melt/blob/master/lua/melt.lua)(@tumuyan | [Apache 2.0](https://github.com/tumuyan/rime-melt/blob/master/LICENSE))
|
||||
- [Unicode 插件](https://github.com/shewer/librime-lua-script/blob/main/lua/component/unicode.lua)(@shewer | [MIT](https://github.com/shewer/librime-lua-script/blob/main/lua/component/unicode.lua))
|
||||
- [数字、人民币大写插件](https://github.com/yanhuacuo/98wubi/blob/master/lua/number.lua)(@98wubi)
|
||||
- [农历插件](https://github.com/boomker/rime-fast-xhup)(@boomker | [LGPL 3.0](https://github.com/boomker/rime-fast-xhup/blob/master/LICENSE))
|
||||
- 未能在此处详述的、在本库源码注释中提及的项目及作者给予的帮助和参考
|
||||
|
||||
感谢 [@Huandeep](https://github.com/Huandeep) 整理的多个词库。
|
||||
|
||||
感谢 [@Mirtle](https://github.com/mirtlecn) 完善的多个功能。
|
||||
|
||||
感谢所有贡献者。
|
||||
|
||||
Thanks to JetBrains for the OSS development license.
|
||||
|
||||
[](https://jb.gg/OpenSourceSupport)
|
||||
|
||||
## 赞助 ☕
|
||||
|
||||
[](https://github.com/iDvel/rime-ice?tab=readme-ov-file#%E8%B5%9E%E5%8A%A9-)
|
||||
|
||||
如果觉得项目不错,可以请 Dvel 吃个煎饼馃子。
|
||||
|
||||
[](https://github.com/iDvel/rime-ice/blob/main/others/sponsor.webp)
|
||||
File diff suppressed because it is too large
Load Diff
-83
@@ -1,83 +0,0 @@
|
||||
---
|
||||
title: "AI Agent Systems: Architectures, Applications, and Evaluation"
|
||||
source: "https://arxiv.org/abs/2601.01743v1"
|
||||
author:
|
||||
- "[[Bin Xu]]"
|
||||
published:
|
||||
created: 2026-01-07
|
||||
description: "Abstract page for arXiv paper 2601.01743v1: AI Agent Systems: Architectures, Applications, and Evaluation"
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://arxiv.org/abs/2601.01743v1
|
||||
> Title: AI Agent Systems: Architectures, Applications, and Evaluation
|
||||
> Clipped:
|
||||
|
||||
页面已保存到 Trilium。 [在 Trilium 中打开。](https://arxiv.org/abs/)
|
||||
|
||||
\[Submitted on 5 Jan 2026\]
|
||||
|
||||
## Title:AI Agent Systems: Architectures, Applications, and Evaluation
|
||||
|
||||
Authors:
|
||||
|
||||
[View PDF](https://arxiv.org/pdf/2601.01743v1) [HTML (experimental)](https://arxiv.org/html/2601.01743v1)
|
||||
|
||||
> Abstract:AI agents -- systems that combine foundation models with reasoning, planning, memory, and tool use -- are rapidly becoming a practical interface between natural-language intent and real-world computation. This survey synthesizes the emerging landscape of AI agent architectures across: (i) deliberation and reasoning (e.g., chain-of-thought-style decomposition, self-reflection and verification, and constraint-aware decision making), (ii) planning and control (from reactive policies to hierarchical and multi-step planners), and (iii) tool calling and environment interaction (retrieval, code execution, APIs, and multimodal perception). We organize prior work into a unified taxonomy spanning agent components (policy/LLM core, memory, world models, planners, tool routers, and critics), orchestration patterns (single-agent vs.\\ multi-agent; centralized vs.\\ decentralized coordination), and deployment settings (offline analysis vs.\\ online interactive assistance; safety-critical vs.\\ open-ended tasks). We discuss key design trade-offs -- latency vs.\\ accuracy, autonomy vs.\\ controllability, and capability vs.\\ reliability -- and highlight how evaluation is complicated by non-determinism, long-horizon credit assignment, tool and environment variability, and hidden costs such as retries and context growth. Finally, we summarize measurement and benchmarking practices (task suites, human preference and utility metrics, success under constraints, robustness and security) and identify open challenges including verification and guardrails for tool actions, scalable memory and context management, interpretability of agent decisions, and reproducible evaluation under realistic workloads.
|
||||
|
||||
| Subjects: | Artificial Intelligence (cs.AI) |
|
||||
| --- | --- |
|
||||
| Cite as: | [arXiv:2601.01743](https://arxiv.org/abs/2601.01743) \[cs.AI\] |
|
||||
| | (or [arXiv:2601.01743v1](https://arxiv.org/abs/2601.01743v1) \[cs.AI\] for this version) |
|
||||
| | [https://doi.org/10.48550/arXiv.2601.01743](https://doi.org/10.48550/arXiv.2601.01743) arXiv-issued DOI via DataCite (pending registration) |
|
||||
|
||||
## Submission history
|
||||
|
||||
From: Bin Xu \[[view email](https://arxiv.org/show-email/97a5ff94/2601.01743)\]
|
||||
**\[v1\]** Mon, 5 Jan 2026 02:38:40 UTC (47,415 KB)
|
||||
|
||||
## Bibliographic and Citation Tools
|
||||
|
||||
Bibliographic Explorer *([What is the Explorer?](https://info.arxiv.org/labs/showcase.html#arxiv-bibliographic-explorer))*
|
||||
|
||||
Connected Papers *([What is Connected Papers?](https://www.connectedpapers.com/about))*
|
||||
|
||||
Litmaps *([What is Litmaps?](https://www.litmaps.co/))*
|
||||
|
||||
scite Smart Citations *([What are Smart Citations?](https://www.scite.ai/))*
|
||||
|
||||
## Code, Data and Media Associated with this Article
|
||||
|
||||
alphaXiv *([What is alphaXiv?](https://alphaxiv.org/))*
|
||||
|
||||
CatalyzeX Code Finder for Papers *([What is CatalyzeX?](https://www.catalyzex.com/))*
|
||||
|
||||
DagsHub *([What is DagsHub?](https://dagshub.com/))*
|
||||
|
||||
Gotit.pub *([What is GotitPub?](http://gotit.pub/faq))*
|
||||
|
||||
Hugging Face *([What is Huggingface?](https://huggingface.co/huggingface))*
|
||||
|
||||
Papers with Code *([What is Papers with Code?](https://paperswithcode.com/))*
|
||||
|
||||
ScienceCast *([What is ScienceCast?](https://sciencecast.org/welcome))*
|
||||
|
||||
## Demos
|
||||
|
||||
Replicate *([What is Replicate?](https://replicate.com/docs/arxiv/about))*
|
||||
|
||||
Hugging Face Spaces *([What is Spaces?](https://huggingface.co/docs/hub/spaces))*
|
||||
|
||||
TXYZ.AI *([What is TXYZ.AI?](https://txyz.ai/))*
|
||||
|
||||
## arXivLabs: experimental projects with community collaborators
|
||||
|
||||
arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website.
|
||||
|
||||
Both individuals and organizations that work with arXivLabs have embraced and accepted our values of openness, community, excellence, and user data privacy. arXiv is committed to these values and only works with partners that adhere to them.
|
||||
|
||||
Have an idea for a project that will add value for arXiv's community? [**Learn more about arXivLabs**](https://info.arxiv.org/labs/index.html).
|
||||
|
||||
[Which authors of this paper are endorsers?](https://arxiv.org/auth/show-endorsers/2601.01743) | [Disable MathJax](https://arxiv.org/abs/) ([What is MathJax?](https://info.arxiv.org/help/mathjax.html))
|
||||
@@ -1,150 +0,0 @@
|
||||
---
|
||||
title: "How I use Obsidian"
|
||||
source: "https://stephango.com/vault"
|
||||
author:
|
||||
- "[[Steph Ango]]"
|
||||
published:
|
||||
created: 2026-01-05
|
||||
description: "My personal Obsidian vault template. A bottom-up approach to note-taking and organizing things I am interested in."
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://stephango.com/vault
|
||||
> Title: How I use Obsidian
|
||||
> Clipped:
|
||||
|
||||
I use [Obsidian](https://stephango.com/obsidian) to think, take notes, write essays, and publish this site. This is my bottom-up approach to note-taking and organizing things I am interested in. It embraces chaos and laziness to create emergent structure.
|
||||
|
||||
In Obsidian, a “vault” is simply a folder of files. This is important because it adheres to my [file over app](https://stephango.com/file-over-app) philosophy. If you want to create digital artifacts that last, they must be files you can control, in formats that are easy to retrieve and read. Obsidian gives you that freedom.
|
||||
|
||||
The following is in no way dogmatic, just one example of how you can use Obsidian. Take the parts you like.
|
||||
|
||||
## Vault template
|
||||
|
||||
1. [Download my vault](https://github.com/kepano/kepano-obsidian/archive/refs/heads/main.zip) or clone it from [the Github repo](https://github.com/kepano/kepano-obsidian).
|
||||
2. Unzip the `.zip` file to a folder of your choosing.
|
||||
3. In Obsidian open the folder as a vault.
|
||||
- My theme [Minimal](https://stephango.com/minimal) with the [Flexoki](https://stephango.com/flexoki) color scheme.
|
||||
- [Obsidian Web Clipper](https://stephango.com/obsidian-web-clipper) to save articles and pages from the web, see my [clipper templates](https://github.com/kepano/clipper-templates) for specific sites I clip from.
|
||||
- [Obsidian Sync](https://obsidian.md/sync) to sync notes between my desktop, phone and tablet.
|
||||
- [Obsidian Bases](https://help.obsidian.md/bases) to view notes by category.
|
||||
- [Obsidian Maps](https://help.obsidian.md/bases/views/map) for maps used in some of my templates.
|
||||
|
||||
## Personal rules
|
||||
|
||||
Rules I follow in my personal vault:
|
||||
|
||||
- Avoid splitting content into multiple vaults.
|
||||
- Avoid folders for organization.
|
||||
- Avoid non-standard Markdown.
|
||||
- Always pluralize categories and tags.
|
||||
- Use internal links profusely.
|
||||
- Use `YYYY-MM-DD` dates everywhere.
|
||||
- Use the 7-point scale for ratings.
|
||||
- Keep [a single to-do list](https://stephango.com/todos) per week.
|
||||
|
||||
Having a [consistent style](https://stephango.com/style) collapses hundreds of future decisions into one, and gives me focus. For example, I always pluralize tags so I never have to wonder what to name new tags. Choose rules that feel comfortable to you and write them down. Make your own style guide. You can always change your rules later.
|
||||
|
||||
## Folders and organization
|
||||
|
||||
I use very few folders. I avoid folders because many of my entries belong to more than one area of thought. My system is oriented towards speed and laziness. I don’t want the overhead of having to consider where something should go.
|
||||
|
||||
I do not use nested sub-folders. I do not use the file explorer much for navigation. I mostly navigate using the quick switcher, backlinks, or links within a note.
|
||||
|
||||
My notes are primarily organized using the `categories` property. Categories display an overview of related notes, using the [bases](https://help.obsidian.md/bases) feature in Obsidian.
|
||||
|
||||
**Most of my notes are in the root of the vault**, not a folder. This where I write about my personal world: journal entries, essays, [evergreen](https://stephango.com/evergreen-notes) notes, and other personal notes. If a note is in the root, I know it’s something I wrote, or relates directly to me.
|
||||
|
||||
Two reference folders I use:
|
||||
|
||||
- **References** where I write about things that exist outside my world. Books, movies, places, people, podcasts, etc. Always named using the title e.g. `Book title.md` or `Movie title.md`.
|
||||
- **Clippings** where I save things other people wrote, mostly essays and articles.
|
||||
|
||||
Three admin folders exist so that their contents don’t show up in the file navigation:
|
||||
|
||||
- **Attachments** for images, audio, videos, PDFs, etc.
|
||||
- **Daily** for my daily notes, all named `YYYY-MM-DD.md`. I do not write anything in daily notes, they exist solely to be linked to from other entries.
|
||||
- **Templates** for templates.
|
||||
|
||||
Two folders are present in the downloadable version of my vault for the sake of clarity. In my personal vault, these notes would be in the root, not a folder.
|
||||
|
||||
- **Categories** contains top-level overviews of notes per category (e.g. Books, Movies, Podcasts, etc).
|
||||
- **Notes** contains example notes.
|
||||
|
||||
## Links
|
||||
|
||||
I use internal links profusely throughout my notes. I try to always link the first mention of something. My journal entries are often a stream of consciousness cataloging recent events, finding connections between things. Often the link is *unresolved*, meaning that the note for that link isn’t created yet. Unresolved links are important because they are breadcrumbs for future connections between things.
|
||||
|
||||
A journal entry in the **root** of my vault might look something like this:
|
||||
|
||||
```
|
||||
I went to see the movie [[Perfect Days]] with [[Aisha]] at [[Vidiots]] and had Filipino food at [[Little Ongpin]]. I loved this quote from Perfect Days: [[Next time is next time, now is now]]. It reminds me of the essay ...
|
||||
```
|
||||
|
||||
The movie, movie theater, and restaurant each link to entries in my **References** folder. In these reference notes I capture properties, my rating, and thoughts about that thing. I use [Web Clipper](https://stephango.com/obsidian-web-clipper) to help populate properties from databases like IMDB. The quote was meaningful to me, so it became an [evergreen note](https://stephango.com/evergreen-notes) in my root folder. The essay I mention is in my **Clippings** folder, because I didn’t write it myself.
|
||||
|
||||
This heavy linking style becomes more useful as time goes on, because I can trace how ideas emerged, and the branching paths these ideas created.
|
||||
|
||||
## Fractal journaling and random revisit
|
||||
|
||||
Fractal journaling and randomization are how I tame the wilderness that a knowledge base can grow into.
|
||||
|
||||
Throughout the day I use Obsidian’s *unique note* hotkey to write individual thoughts as they come up. This shortcut automatically creates a note with the prefix `YYYY-MM-DD HHmm` to which I may add a title that describes the idea.
|
||||
|
||||
Every few days I review these journal fragments and compile the salient thoughts. I then review those reviews monthly, and review the monthly reviews yearly (using [this template](https://stephango.com/40-questions)). The result is a fractal web of my life that I can zoom in and out of at varying degrees of detail. I can trace back where individual thoughts came from, and how they bubbled up into bigger themes.
|
||||
|
||||
Every few months I set aside time for a “random revisit”. I use the *random note* hotkey to quickly travel randomly through my vault. I often use the local graph at shallow depth to see related notes. This helps me revisit old ideas, create missing links, and find inspiration in past thoughts. It’s also an opportunity to do maintenance, like fix formatting based on new rules in my personal style guide.
|
||||
|
||||
People have asked me if this could be automated with language models but I do not care to do so. I enjoy this process. Doing this maintenance helps me understand my own patterns. [Don’t delegate understanding](https://stephango.com/understand).
|
||||
|
||||
## Properties and templates
|
||||
|
||||
Almost every note I create starts from a [template](https://github.com/kepano/kepano-obsidian/tree/main/Templates). I use templates heavily because they allow me to lazily add information that will help me find the note later. I have a template for every category with [properties](https://help.obsidian.md/properties) at the top, to capture data such as:
|
||||
|
||||
- **Dates** — created, start, end, published
|
||||
- **People** — author, director, artist, cast, host, guests
|
||||
- **Themes** — grouping by genre, type, topic, related notes
|
||||
- **Locations** — neighborhood, city, coordinates
|
||||
- **Ratings** — more on this below
|
||||
|
||||
A few rules I follow for properties:
|
||||
|
||||
- Property names and values should aim to be reusable across categories. This allows me to find things across categories, e.g. `genre` is shared across all media types, which means I can see an archive of *Sci-fi* books, movies and shows in one place.
|
||||
- Templates should aim to be composable, e.g. *Person* and *Author* are two different templates that can be added to the same note.
|
||||
- Short property names are faster to type, e.g. `start` instead of `start‑date`.
|
||||
- Default to `list` type properties instead of `text` if there is any chance it might contain more than one link or value in the future.
|
||||
|
||||
The [.obsidian/types.json](https://github.com/kepano/kepano-obsidian/blob/main/.obsidian/types.json) file lists which properties are assigned to which types (i.e. `date`, `number`, `text`, etc).
|
||||
|
||||
## Rating system
|
||||
|
||||
Anything with a `rating` uses an integer from 1 to 7:
|
||||
|
||||
- 7 — **Perfect**, must try, life-changing, go out of your way to seek this out
|
||||
- 6 — **Excellent**, worth repeating
|
||||
- 5 — **Good**, don’t go out of your way, but enjoyable
|
||||
- 4 — **Passable**, works in a pinch
|
||||
- 3 — **Bad**, don’t do this if you can
|
||||
- 2 — **Atrocious**, actively avoid, repulsive
|
||||
- 1 — **Evil**, life-changing in a bad way
|
||||
|
||||
Why this scale? I like rating out of 7 better than 4 or 5 because I need more granularity at the top, for the good experiences, and 10 is too granular.
|
||||
|
||||
## Publishing to the web
|
||||
|
||||
This site is written, edited, and published directly from Obsidian. To do this, I break one of my rules listed above — I have a separate vault for my site. I use a *static site generator* called [Jekyll](https://jekyllrb.com/) to automatically compile my notes into a website and convert them from Markdown to HTML.
|
||||
|
||||
My publishing flow is easy to use, but a bit technical to set up. This is because I like to have full control over every aspect of my site’s layout. If you don’t need full control you might consider [Obsidian Publish](https://obsidian.md/publish) which is more user-friendly, and what I use for my [Minimal documentation site](https://minimal.guide/publish/download).
|
||||
|
||||
For this site, I push notes from Obsidian to a GitHub repo using the [Obsidian Git](https://obsidian.md/plugins?id=obsidian-git) plugin. The notes are then automatically compiled using [Jekyll](https://jekyllrb.com/) with my web host [Netlify](https://www.netlify.com/). I also use my [Permalink Opener](https://stephango.com/permalink-opener) plugin to quickly open notes in the browser so I can compare the draft and live versions.
|
||||
|
||||
The color palette is [Flexoki](https://stephango.com/flexoki), which I created for this site. My Jekyll template is not public, but you can get similar results from [this template](https://github.com/maximevaillancourt/digital-garden-jekyll-template) by Maxime Vaillancourt. There are also many alternatives to Jekyll you can use to compile your site such as [Quartz](https://quartz.jzhao.xyz/), [Astro](https://astro.build/), [Eleventy](https://www.11ty.dev/), and [Hugo](https://gohugo.io/).
|
||||
|
||||
- [File over app](https://stephango.com/file-over-app)
|
||||
- [Concise explanations accelerate progress](https://stephango.com/concise)
|
||||
- [Evergreen notes turn ideas into objects that you can manipulate](https://stephango.com/evergreen-notes)
|
||||
- [40 questions to ask yourself every year](https://stephango.com/40-questions)
|
||||
- [40 questions to ask yourself every decade](https://stephango.com/40-questions-decade)
|
||||
- [How I do my to-dos](https://stephango.com/todos)
|
||||
-181
@@ -1,181 +0,0 @@
|
||||
---
|
||||
title: "Understanding Spec-Driven-Development: Kiro, spec-kit, and Tessl"
|
||||
source: "https://martinfowler.com/articles/exploring-gen-ai/sdd-3-tools.html"
|
||||
author:
|
||||
- "[[Birgitta BöckelerBirgitta is a Distinguished Engineer and AI-assisted delivery expert at Thoughtworks. She has over 20 years of experience as a software developer]]"
|
||||
- "[[architect and technical leader.]]"
|
||||
published:
|
||||
created: 2026-01-21
|
||||
description: "Notes from my Thoughtworks colleagues on AI-assisted software delivery"
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://martinfowler.com/articles/exploring-gen-ai/sdd-3-tools.html
|
||||
> Title: Understanding Spec-Driven-Development: Kiro, spec-kit, and Tessl
|
||||
> Clipped:
|
||||
|
||||
I’ve been trying to understand one of the latest AI coding buzzword: Spec-driven development (SDD). I looked at three of the tools that label themselves as SDD tools and tried to untangle what it means, as of now.
|
||||
|
||||
## Definition
|
||||
|
||||
Like with many emerging terms in this fast-paced space, the definition of “spec-driven development” (SDD) is still in flux. Here’s what I can gather from how I have seen it used so far: Spec-driven development means writing a “spec” before writing code with AI (“documentation first”). The spec becomes the source of truth for the human and the AI.
|
||||
|
||||
[GitHub](https://github.com/github/spec-kit/blob/main/spec-driven.md): “In this new world, *maintaining software means evolving specifications*. \[…\] The lingua franca of development moves to a higher level, and code is the last-mile approach.”
|
||||
|
||||
[Tessl](https://docs.tessl.io/introduction-to-tessl/concepts): “A development approach where *specs — not code — are the primary artifact*. Specs describe intent in structured, testable language, and agents generate code to match them.”
|
||||
|
||||
After looking over the usages of the term, and some of the tools that claim to be implementing SDD, it seems to me that in reality, there are multiple implementation levels to it:
|
||||
|
||||
1. **Spec-first**: A well thought-out spec is written first, and then used in the AI-assisted development workflow for the task at hand.
|
||||
2. **Spec-anchored**: The spec is kept even after the task is complete, to continue using it for evolution and maintenance of the respective feature.
|
||||
3. **Spec-as-source**: The spec is the main source file over time, and only the spec is edited by the human, the human never touches the code.
|
||||
|
||||
All SDD approaches and definitions I’ve found are spec-first, but not all strive to be spec-anchored or spec-as-source. And often it’s left vague or totally open what the spec maintenance strategy over time is meant to be.
|
||||
|
||||
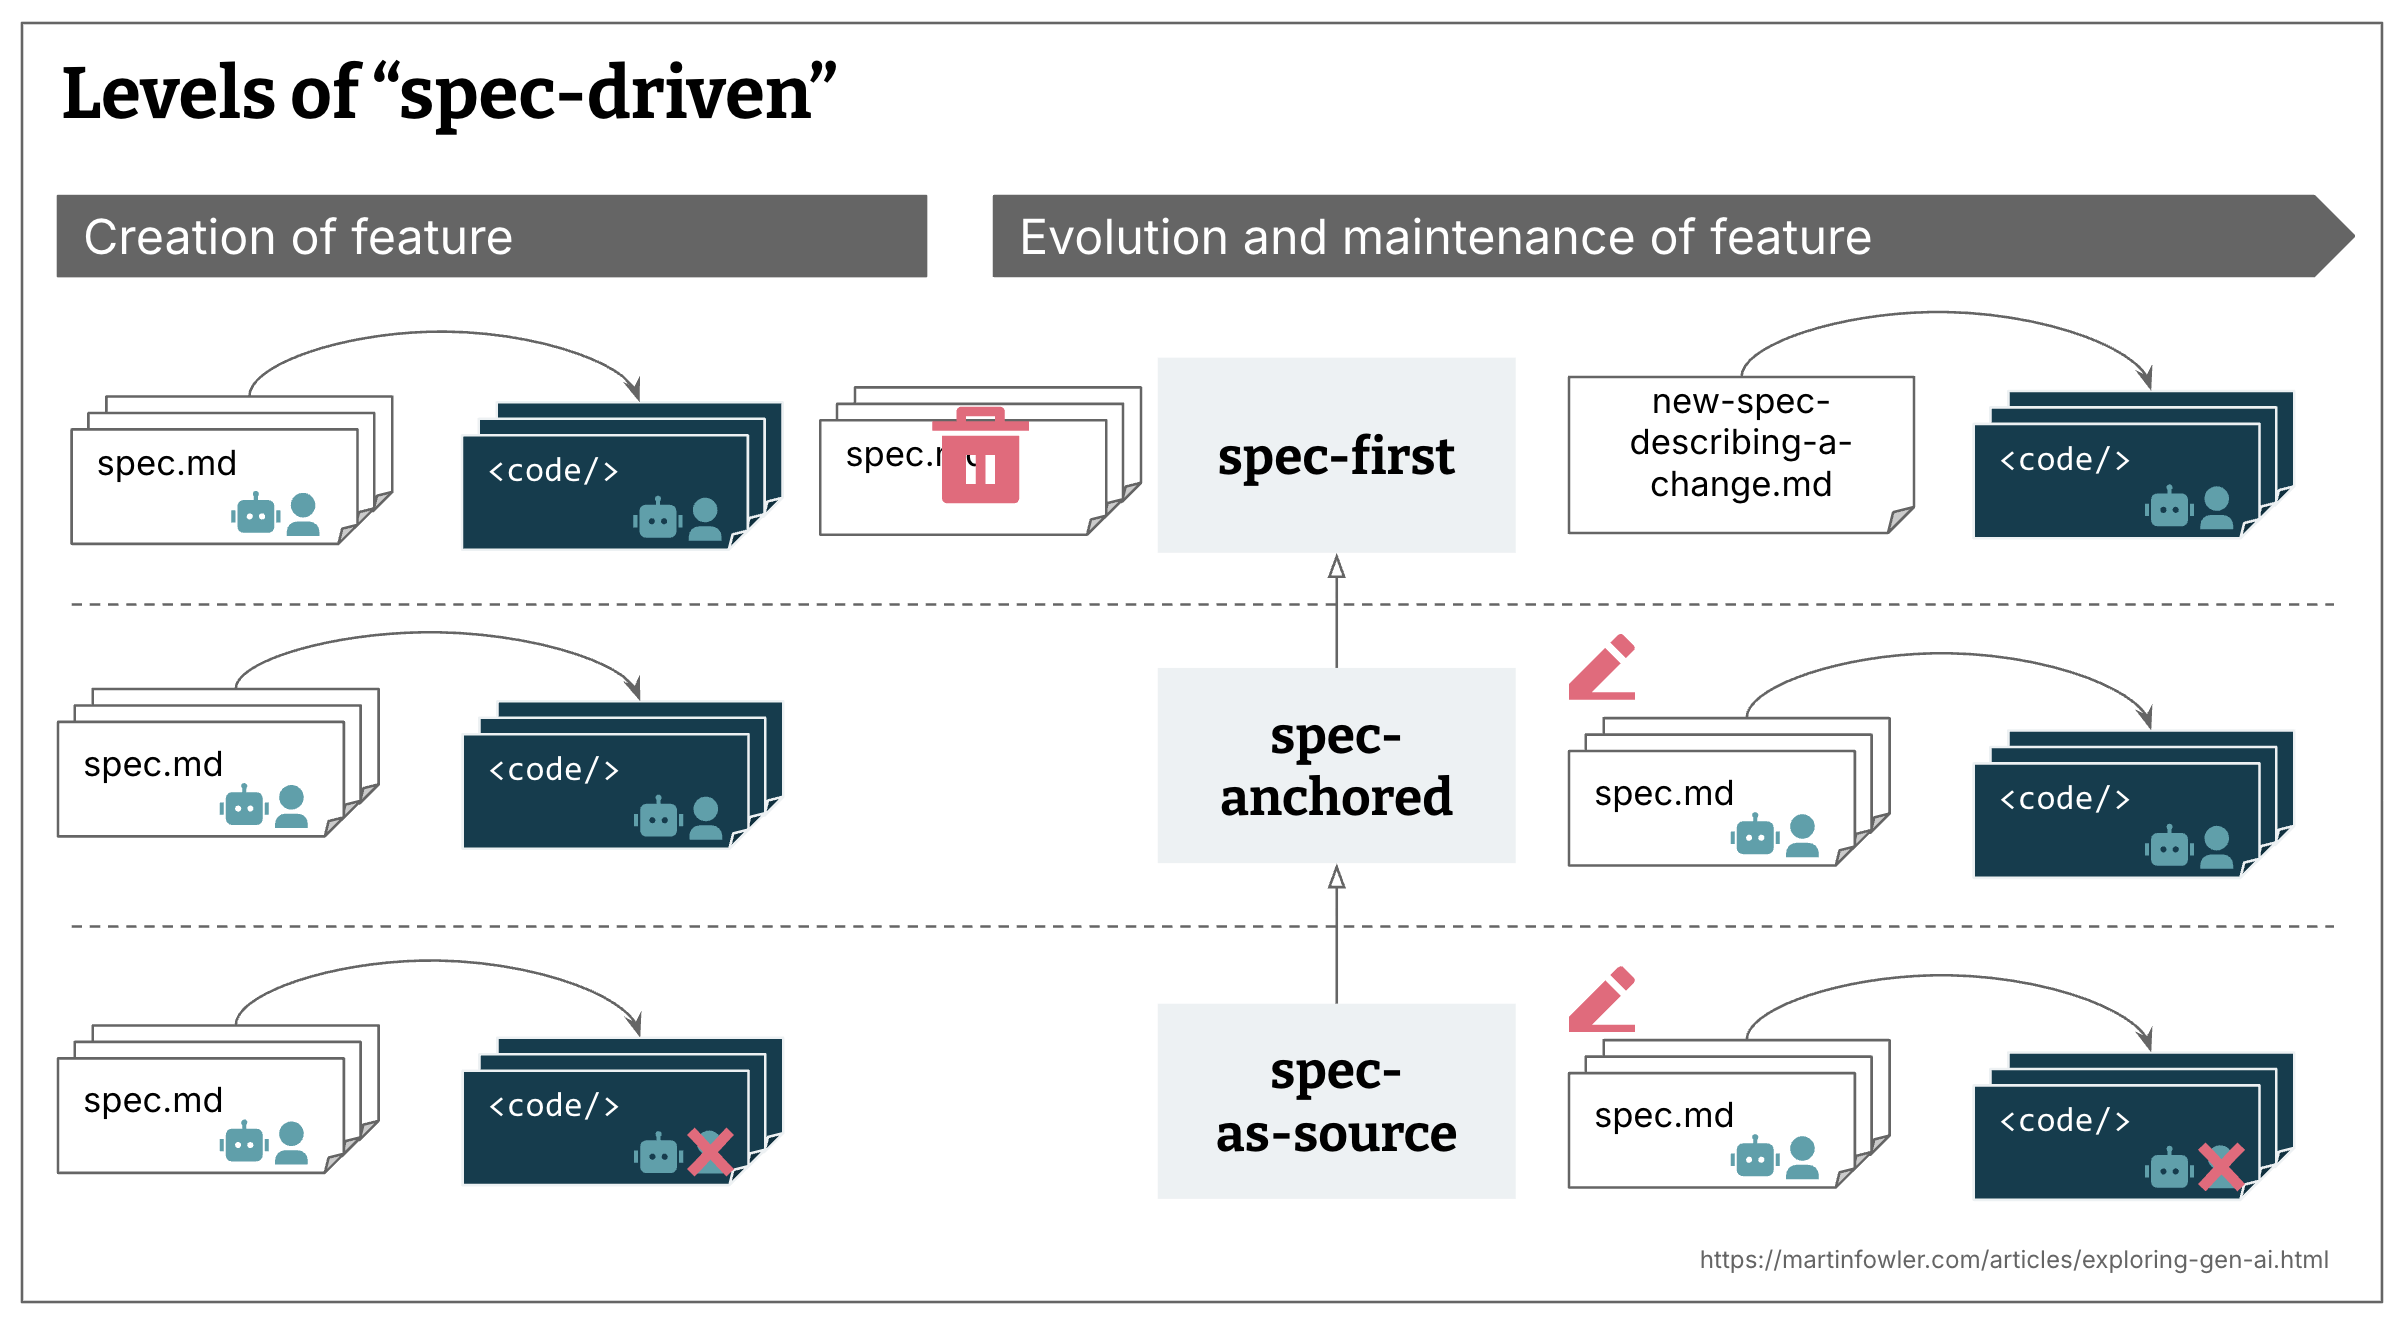
|
||||
|
||||
## What is a spec?
|
||||
|
||||
The key question in terms of definitions of course is: What is a spec? There doesn’t seem to be a general definition, the closest I’ve seen to a consistent definition is the comparison of a spec to a “Product Requirements Document”.
|
||||
|
||||
The term is quite overloaded at the moment, here is my attempt at defining what a spec is:
|
||||
|
||||
A spec is a structured, behavior-oriented artifact - or a set of related artifacts - written in natural language that expresses software functionality and serves as guidance to AI coding agents. Each variant of spec-driven development defines their approach to a spec’s structure, level of detail, and how these artifacts are organized within a project.
|
||||
|
||||
There is a useful difference to be made I think between specs and the more general context documents for a codebase. That general context are things like rules files, or high level descriptions of the product and the codebase. Some tools call this context a [**memory bank**](https://docs.cline.bot/prompting/cline-memory-bank), so that’s what I will use here. These files are relevant across all AI coding sessions in the codebase, whereas specs only relevant to the tasks that actually create or change that particular functionality.
|
||||
|
||||
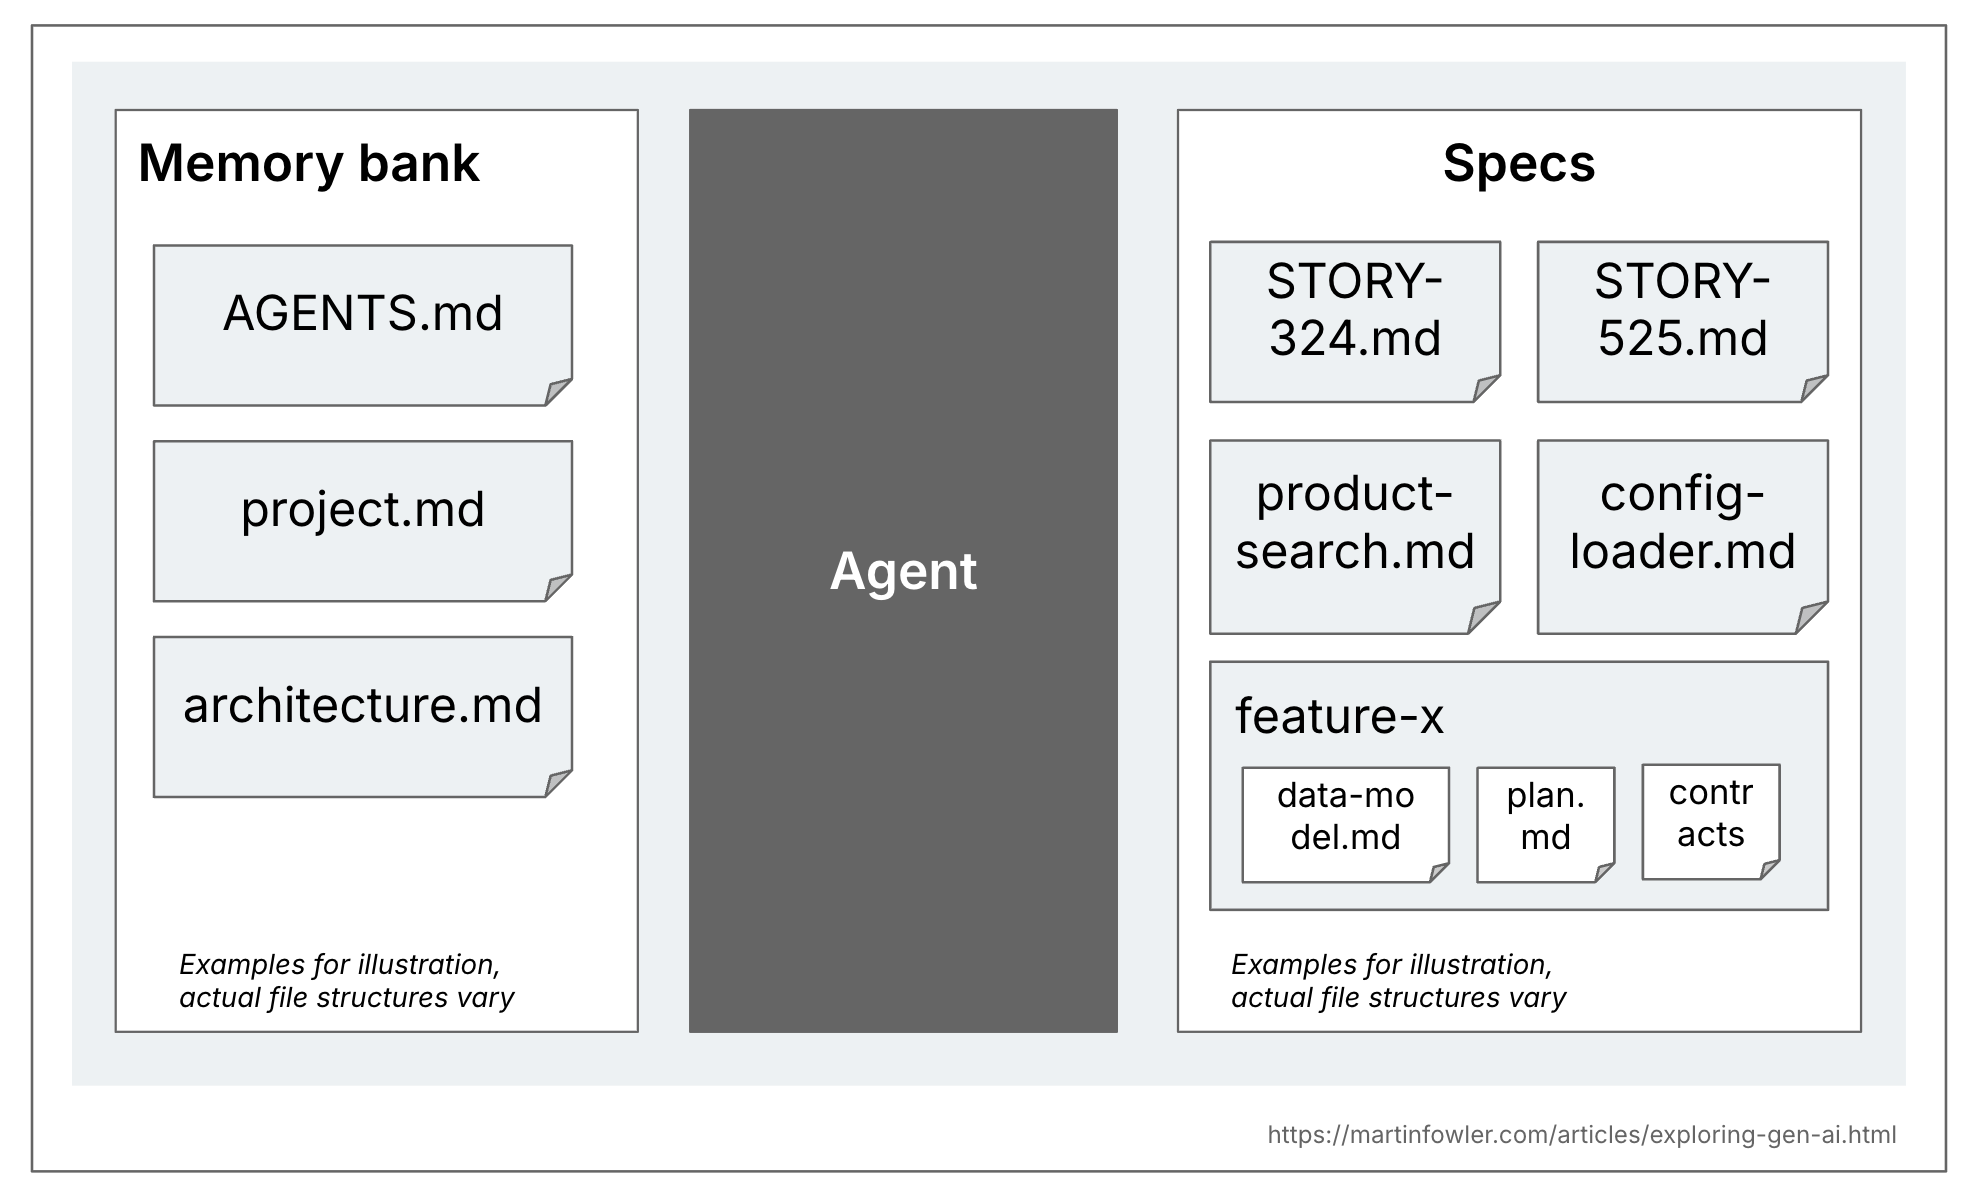
|
||||
|
||||
## The challenge with evaluating SDD tools
|
||||
|
||||
It turns out to be quite time-consuming to evaluate SDD tools and approaches in a way that gets close to real usage. You would have to try them out with different sizes of problems, greenfield, brownfield, and really take the time to review and revise the intermediate artifacts with more than just a cursory glance. Because as [GitHub’s blog post about spec-kit](https://github.blog/ai-and-ml/generative-ai/spec-driven-development-with-ai-get-started-with-a-new-open-source-toolkit/) says: “Crucially, your role isn’t just to steer. It’s to verify. At each phase, you reflect and refine.”
|
||||
|
||||
For two of the three tools I tried it also seems to be even more work to introduce them into an existing codebase, therefore making it even harder to evaluate their usefulness for brownfield codebases. Until I hear usage reports from people using them for a period of time on a “real” codebase, I still have a lot of open questions about how this works in real life.
|
||||
|
||||
That being said - let’s get into three of these tools. I will share a description of how they work first (or rather how I think they work), and will keep my observations and questions for the end. Note that these tools are very fast evolving, so they might have already changed since I used them in September.
|
||||
|
||||
## Kiro
|
||||
|
||||
[Kiro](https://kiro.dev/) is the simplest (or most lightweight) one of the three I tried. It seems to be mostly spec-first, all the examples I have found use it for a task, or a user story, with no mention of how to use the requirements document in a spec-anchored way over time, across multiple tasks.
|
||||
|
||||
**Workflow:** Requirements → Design → Tasks
|
||||
|
||||
Each workflow step is represented by one markdown document, and Kiro guides you through those 3 workflow steps inside of its VS Code based distribution.
|
||||
|
||||
**Requirements:** Structured as a list of requirements, where each requirement represents a “User Story” (in “As a…” format) with acceptance criteria (in “GIVEN… WHEN… THEN…” format)
|
||||
|
||||
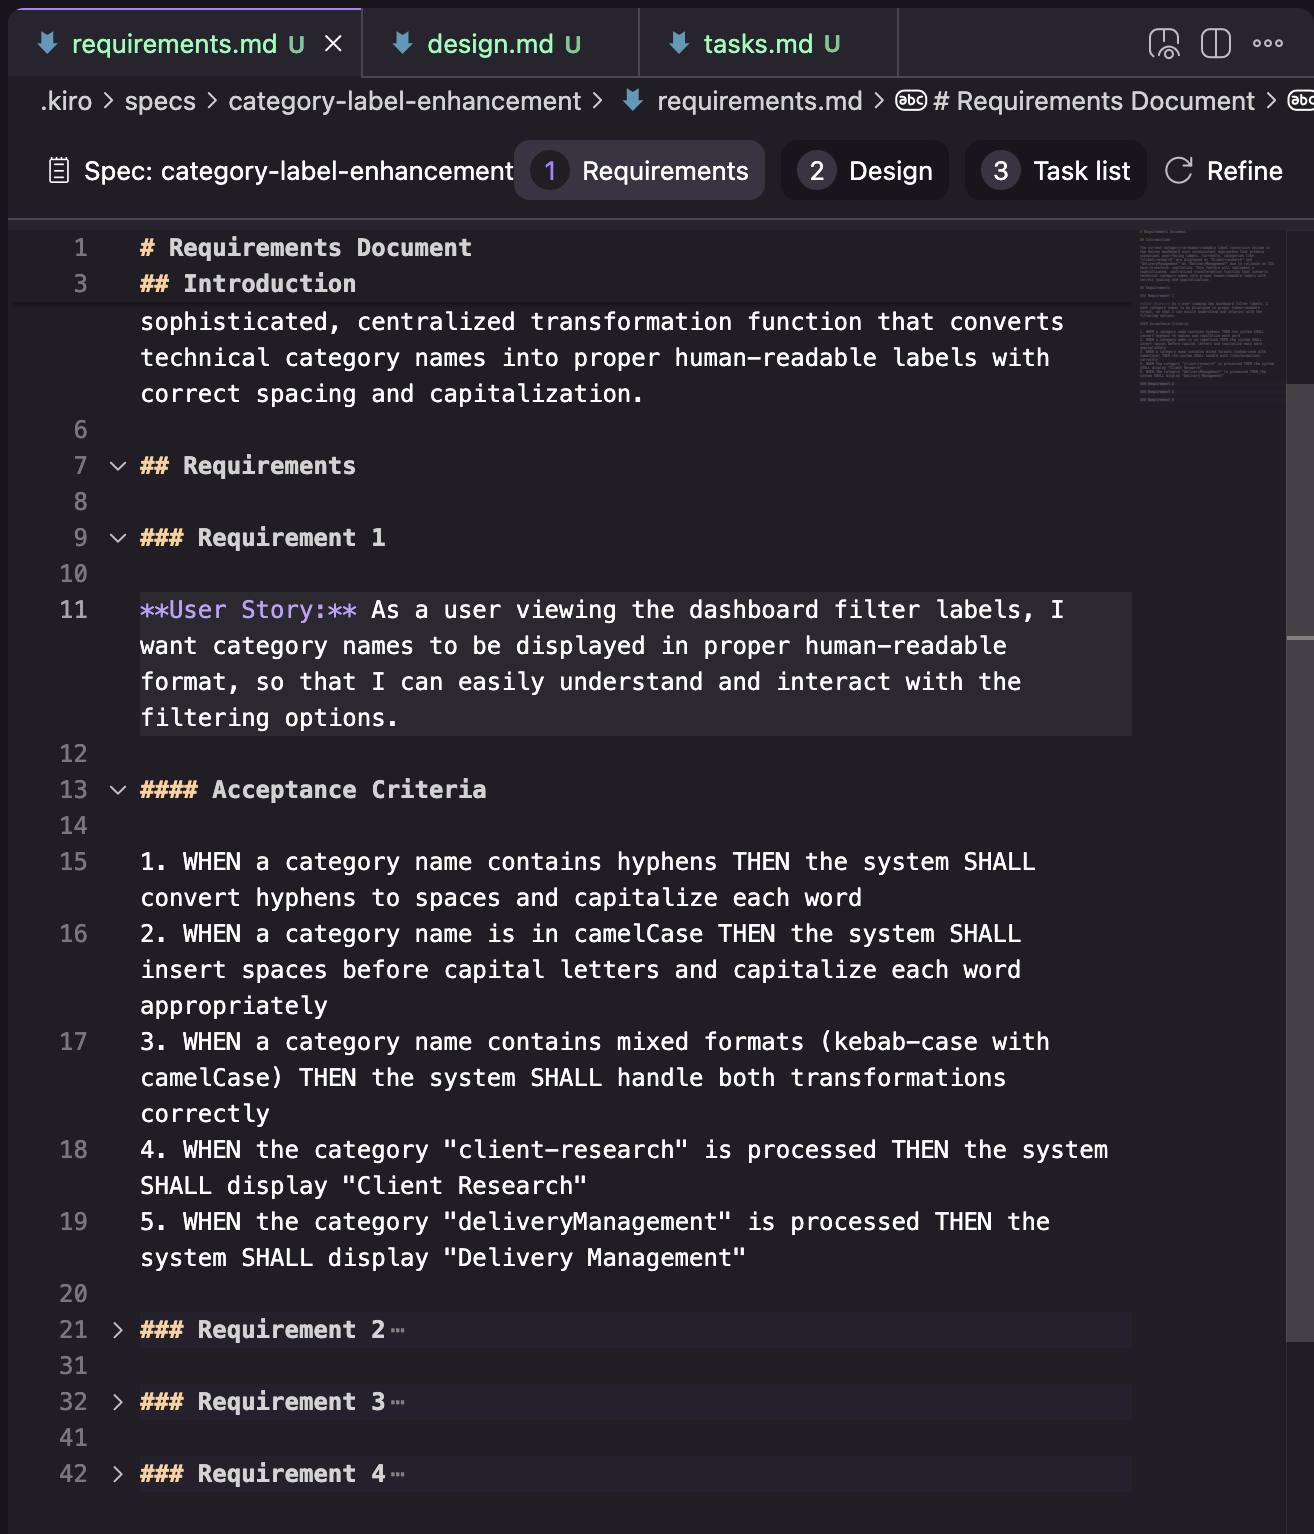
|
||||
|
||||
**Design:** In my attempt, the design document consisted of the sections seen in the screenshot below. I only have the results of one of my attempts still, so I’m not sure if this is a consistent structure, or if it changes depending on the task.
|
||||
|
||||
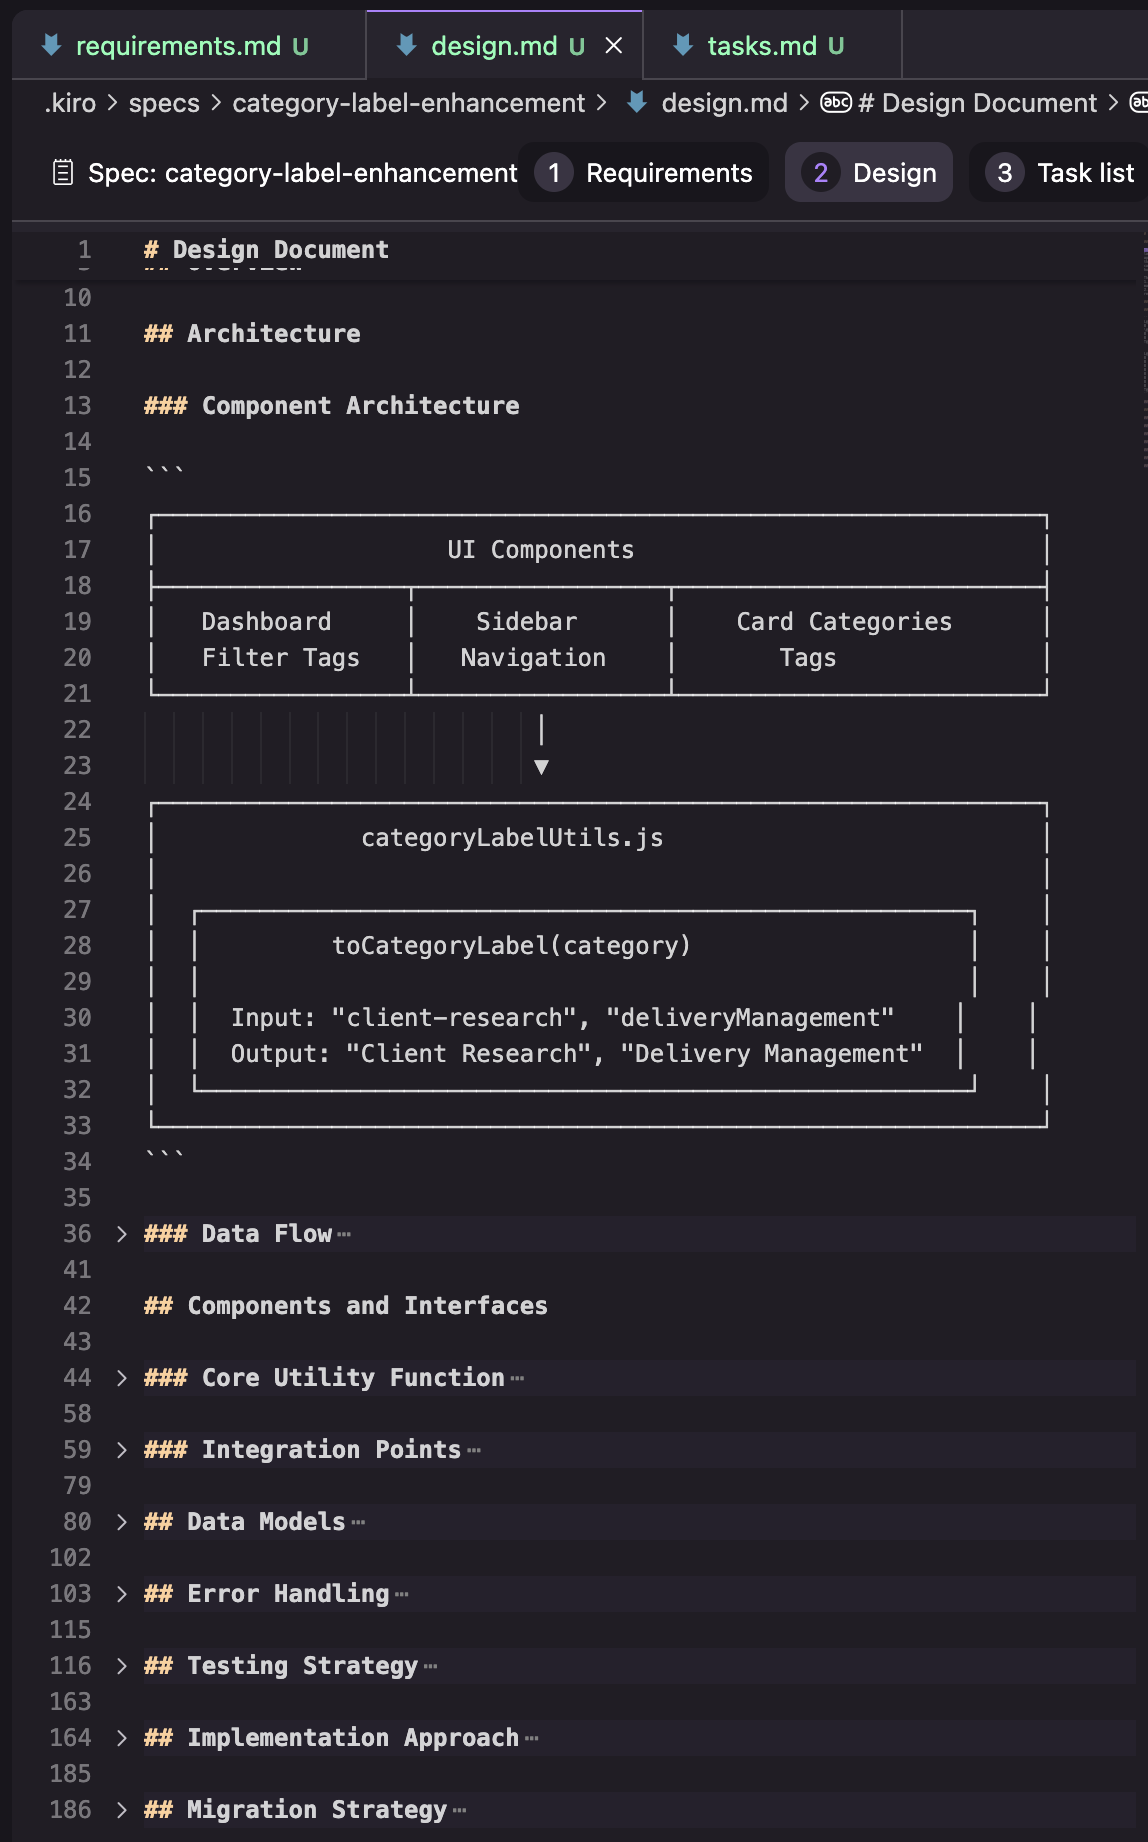
|
||||
|
||||
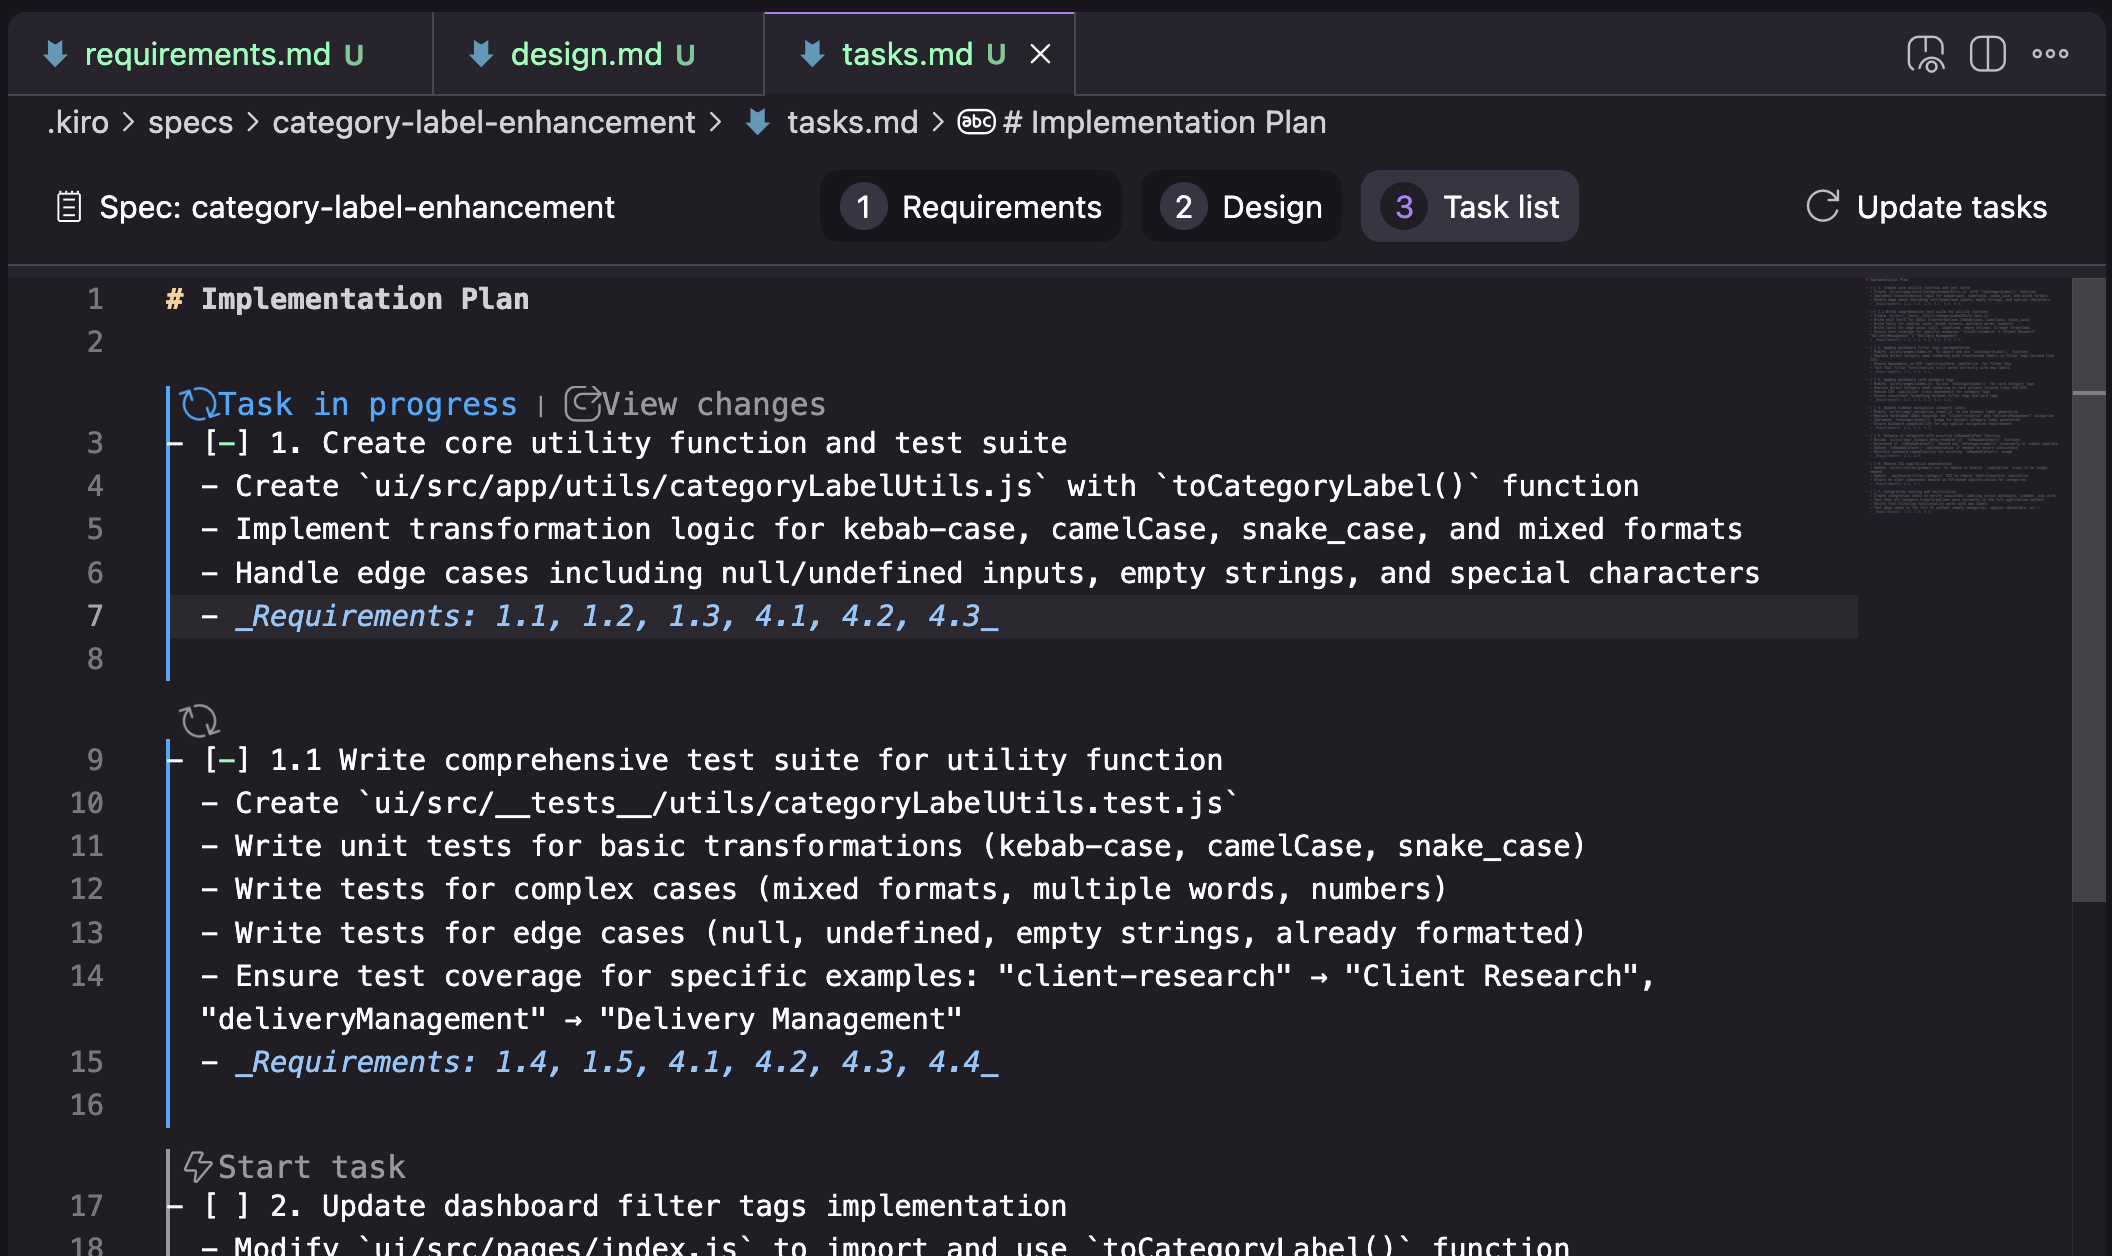
**Tasks:** A list of tasks that trace back to the requirement numbers, and that get some extra UI elements to run tasks one by one, and review changes per task.
|
||||
|
||||
|
||||
|
||||
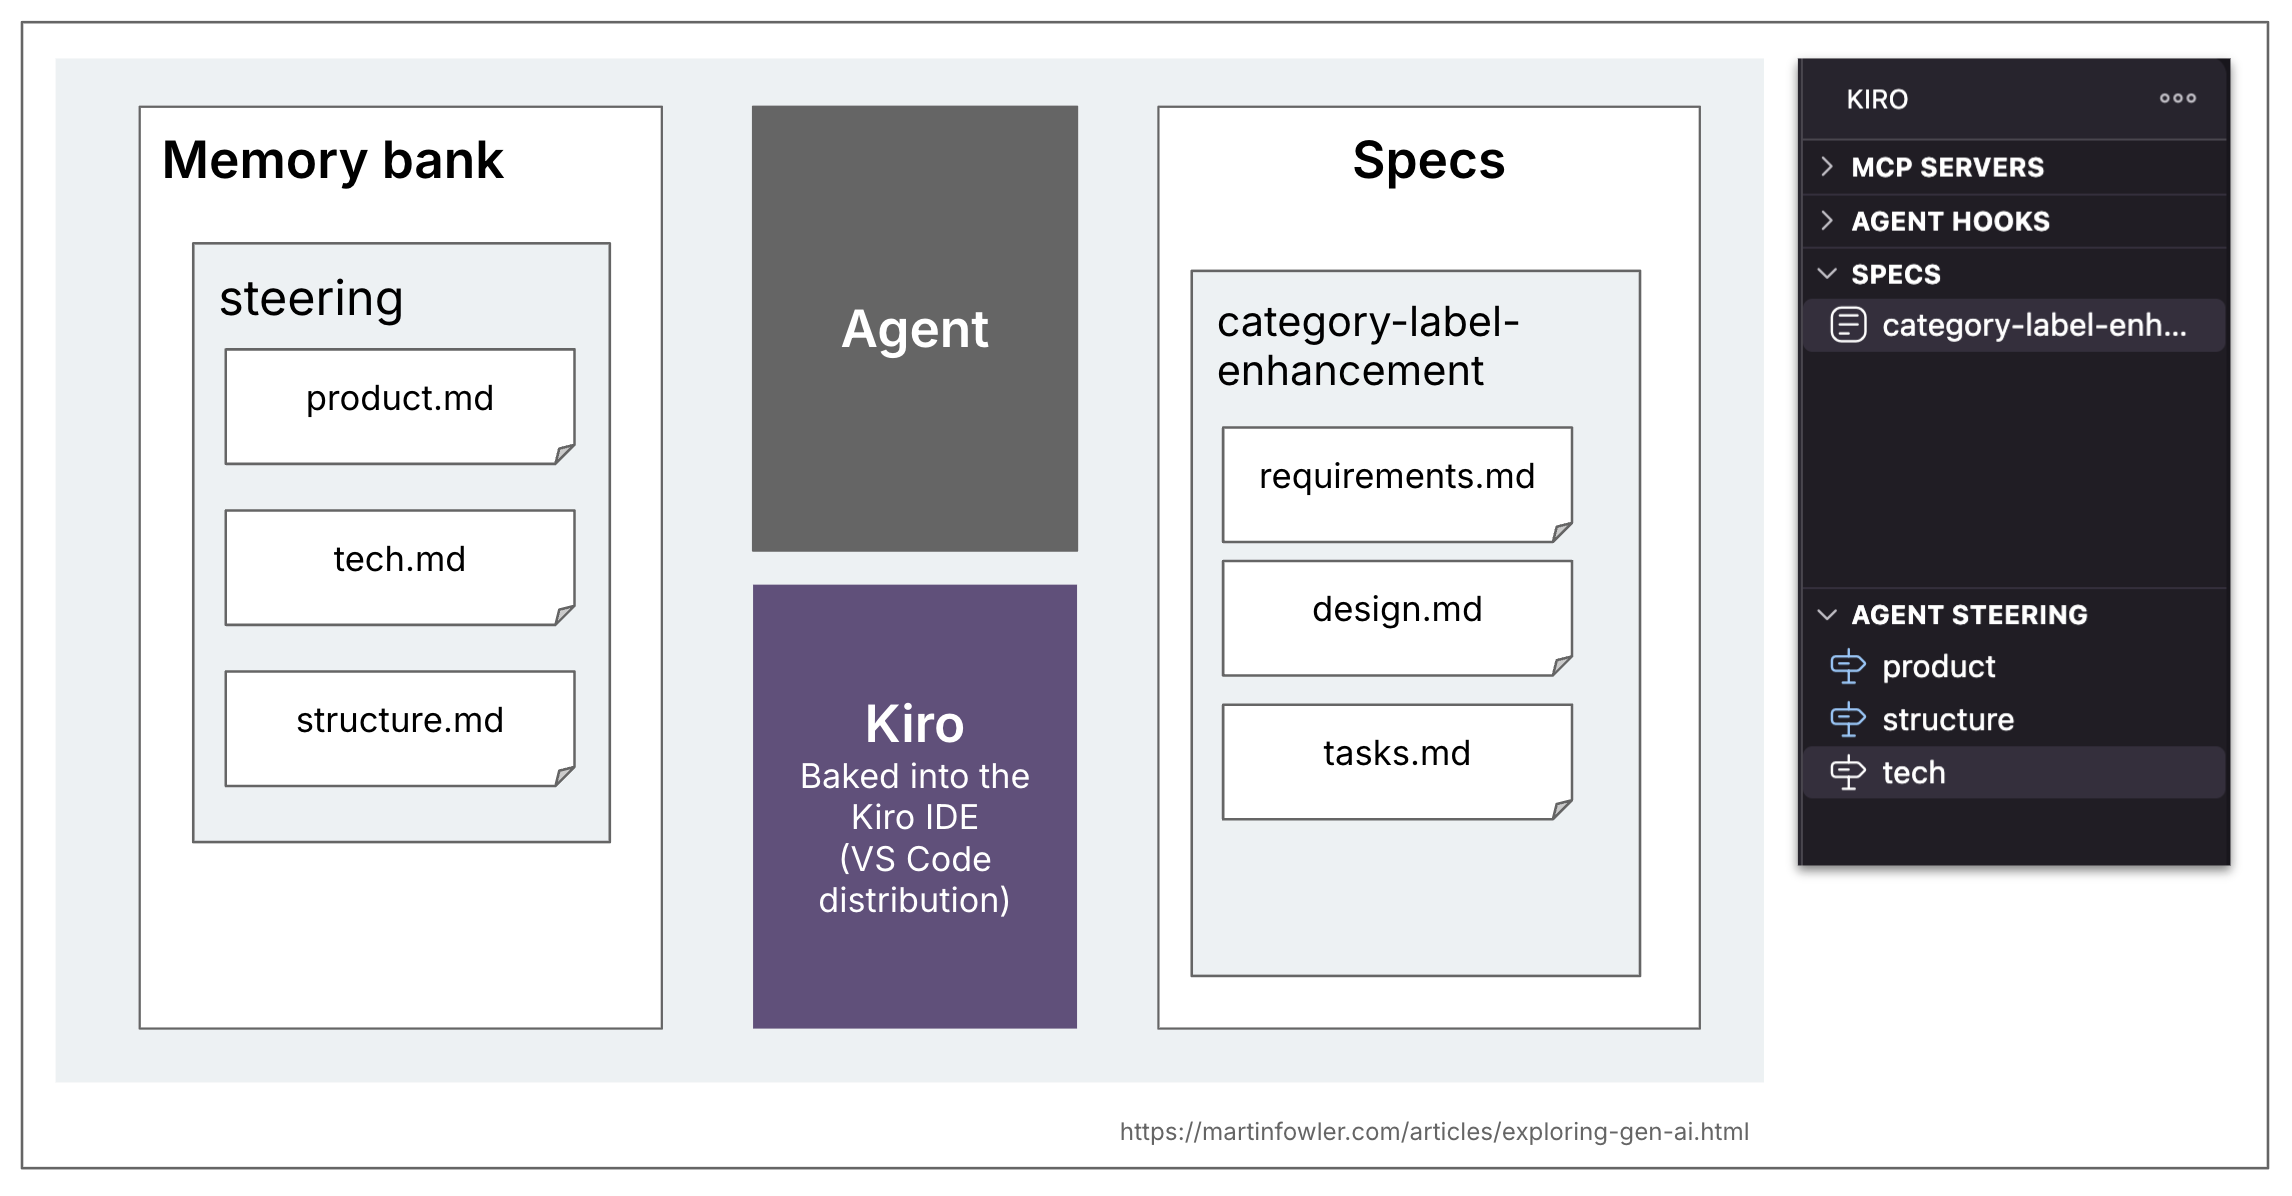
Kiro also has the concept of a memory bank, they call it “steering”. Its contents are flexible, and their workflow doesn’t seem to rely on any specific files being there (I made my usage attempts before I even discovered the steering section). The default topology created by Kiro when you ask it to generate steering documents is product.md, structure.md, tech.md.
|
||||
|
||||
|
||||
|
||||
## Spec-kit
|
||||
|
||||
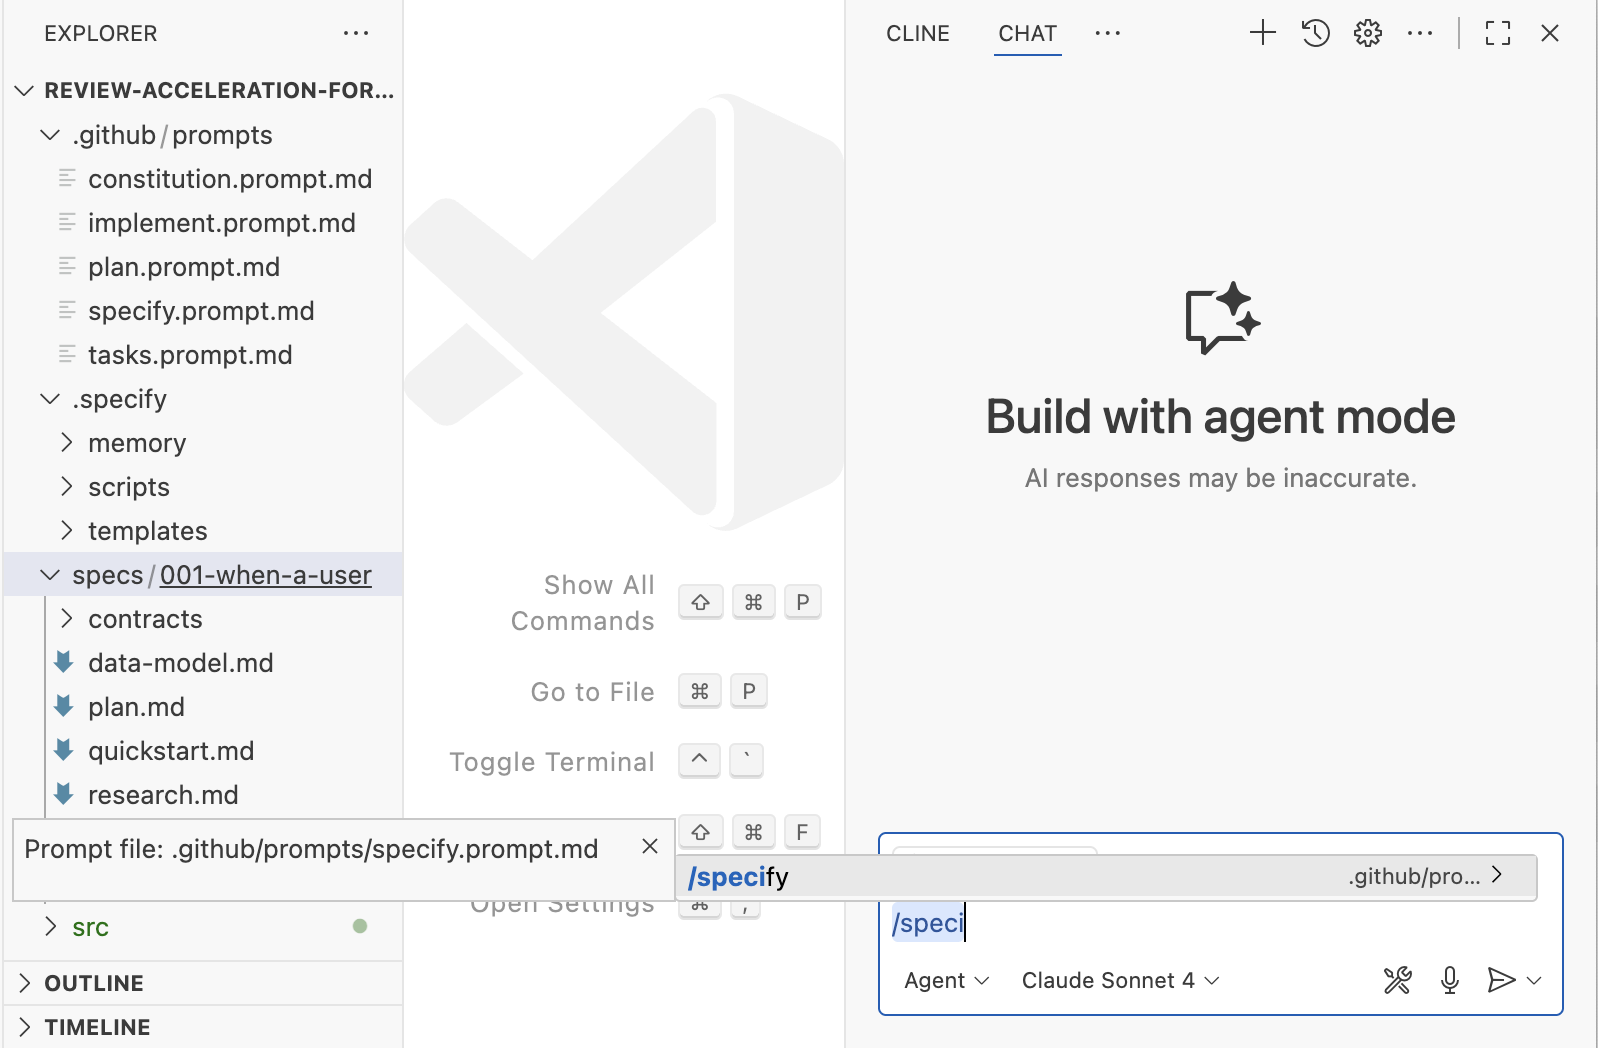
[Spec-kit](https://github.com/github/spec-kit) is GitHub’s version of SDD. It is distributed as a CLI that can create workspace setups for a wide range of common coding assistants. Once that structure is set up, you interact with spec-kit via slash commands in your coding assistant. Because all of its artifacts are put right into your workspace, this is the most customizable one of the three tools discussed here.
|
||||
|
||||
|
||||
|
||||
**Workflow:** Constitution → 𝄆 Specify → Plan → Tasks 𝄇
|
||||
|
||||
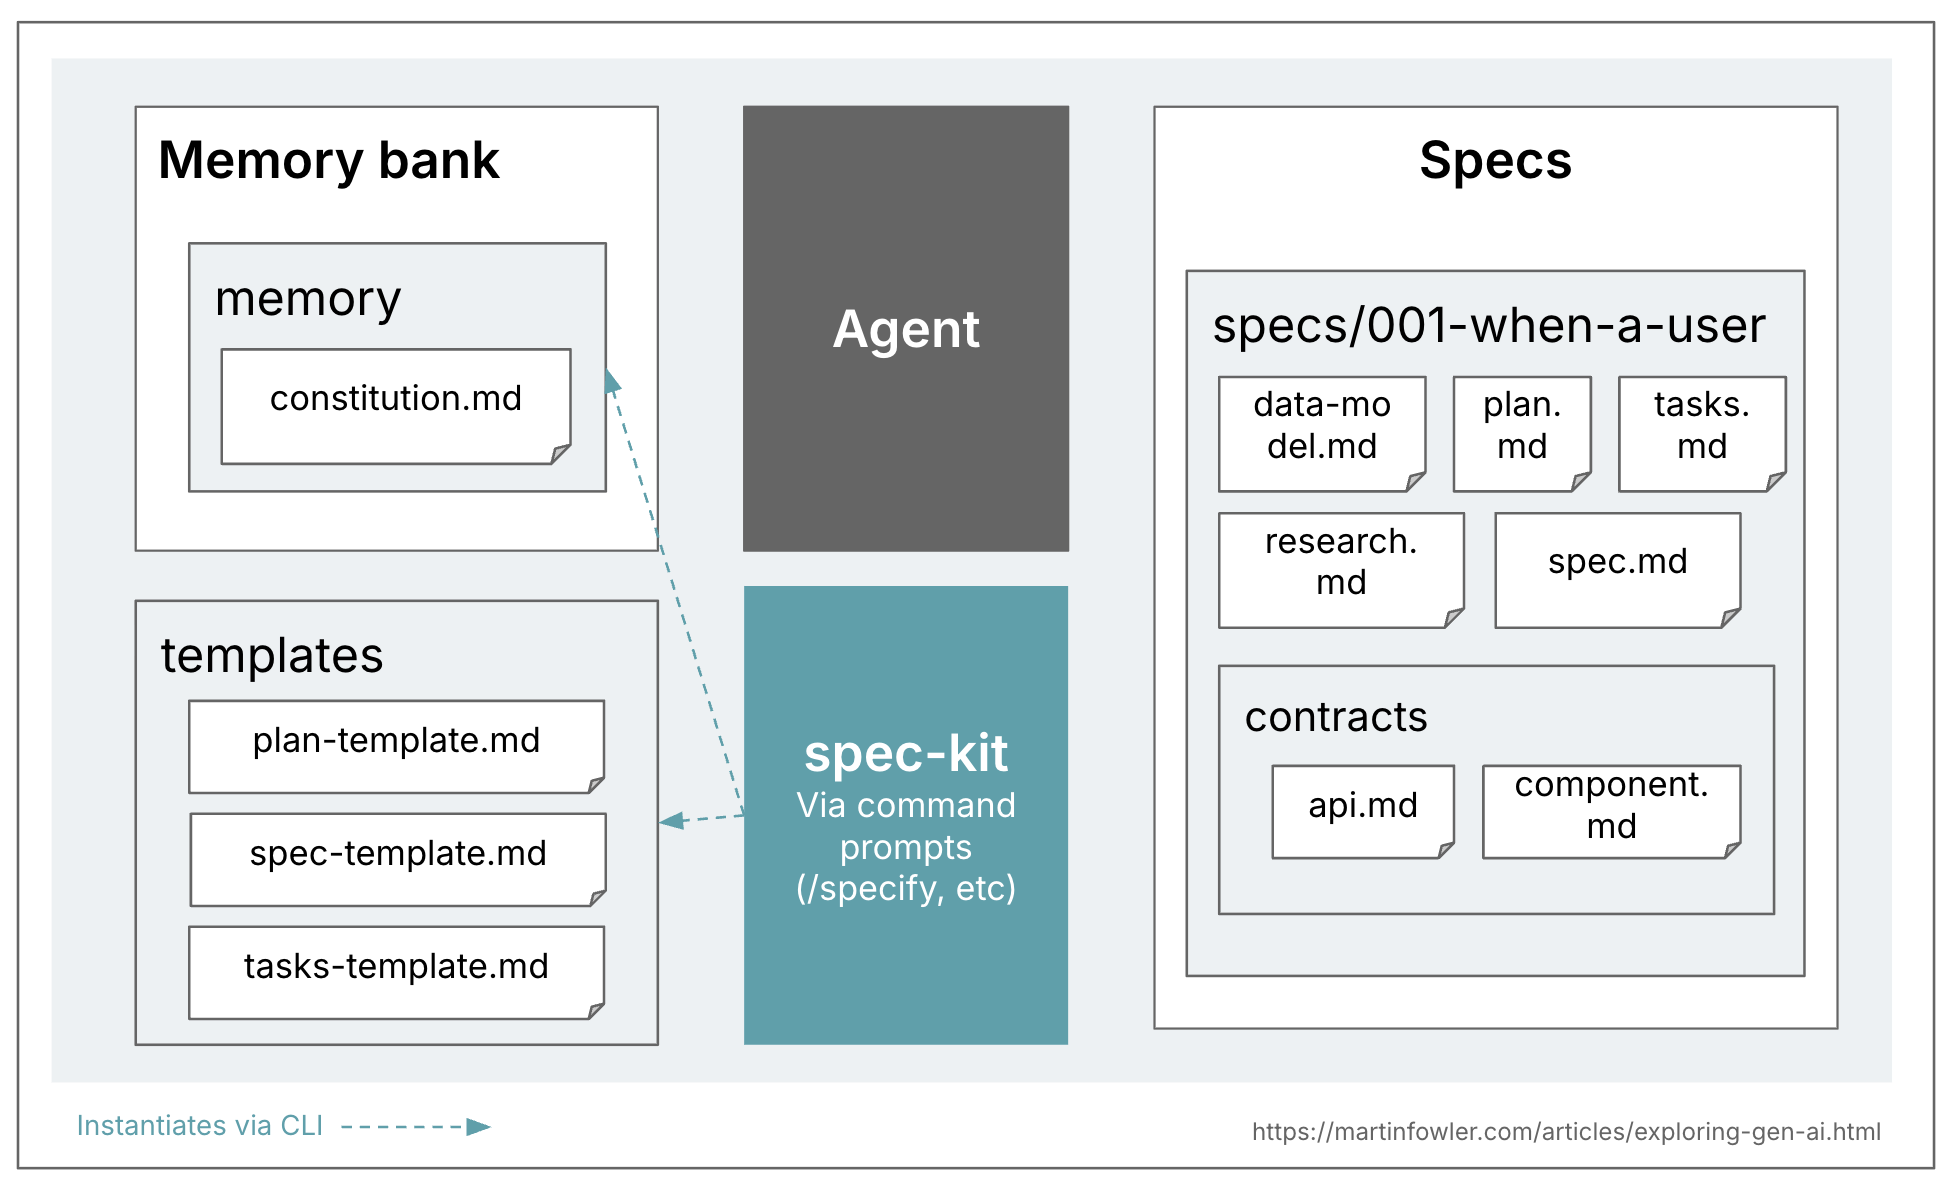
Spec-kit’s memory bank concept is a prerequisite for the spec-driven approach. They call it a [**constitution**](https://github.com/github/spec-kit/blob/main/spec-driven.md#the-constitutional-foundation-enforcing-architectural-discipline). The constitution is supposed to contain the high level principles that are “immutable” and should always be applied, to every change. It’s basically a very powerful rules file that is heavily used by the workflow.
|
||||
|
||||
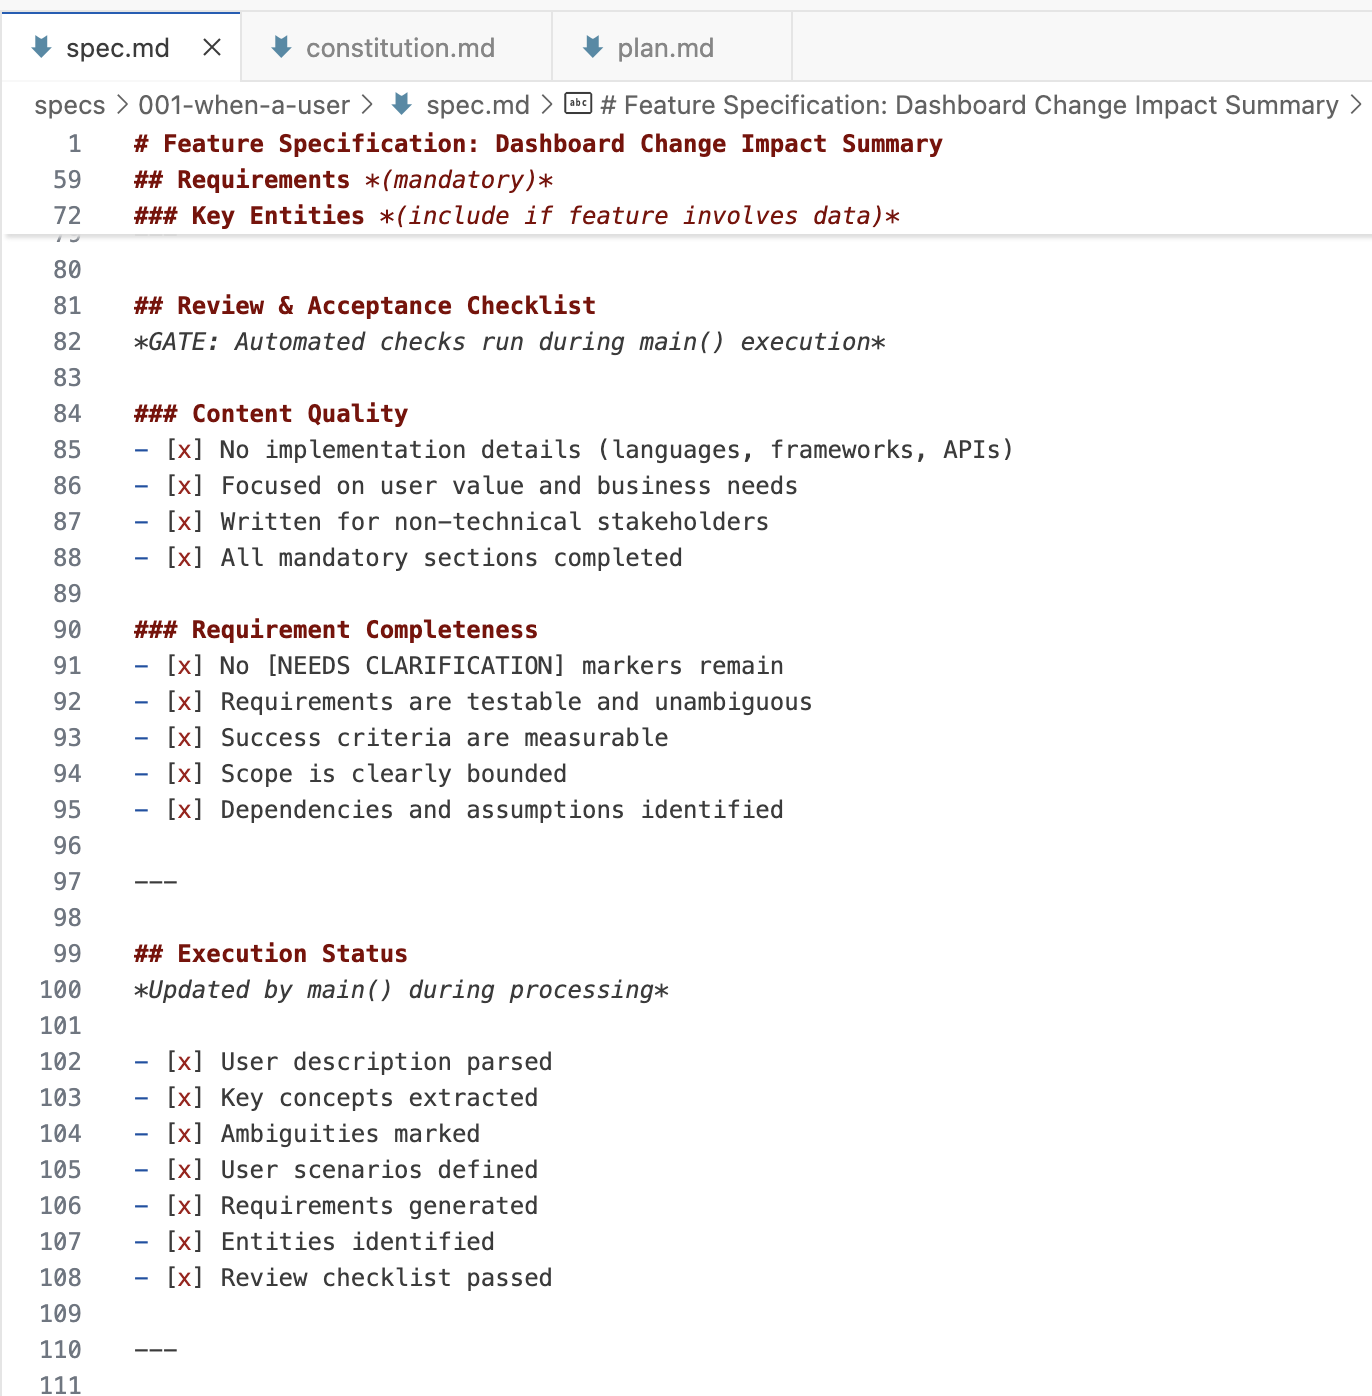
In each of the workflow steps (specify, plan, tasks), spec-kit instantiates a set of files and prompts with the help of a bash script and some templates. The workflow then makes heavy use of checklists inside of the files, to track necessary user clarifications, constitution violations, research tasks, etc. They are like a “definition of done” for each workflow step (though interpreted by AI, so there is no 100% guarantee that they will be respected).
|
||||
|
||||
|
||||
|
||||
Below is an overview to illustrate the file topology I saw in spec-kit. Note how one spec is made up of many files.
|
||||
|
||||
|
||||
|
||||
At first glance, GitHub seems to be [aspiring to a spec-anchored approach](https://github.blog/ai-and-ml/generative-ai/spec-driven-development-with-ai-get-started-with-a-new-open-source-toolkit/) (“That’s why we’re rethinking specifications — not as static documents, but as living, executable artifacts that evolve with the project. Specs become the shared source of truth. When something doesn’t make sense, you go back to the spec; when a project grows complex, you refine it; when tasks feel too large, you break them down.”) However, spec-kit creates a branch for every spec that gets created, which seems to indicate that they see a spec as a living artifact for the lifetime of a change request, not the lifetime of a feature. [This community discussion](https://github.com/github/spec-kit/discussions/152) is talking about this confusion. It makes me think that spec-kit is still what I would call spec-first only, not spec-anchored over time.
|
||||
|
||||
## Tessl Framework
|
||||
|
||||
*(Still in private beta)*
|
||||
|
||||
Like spec-kit, the [Tessl Framework](https://docs.tessl.io/introduction-to-tessl/quick-start-guide-tessl-framework) is distributed as a CLI that can create all the workspace and config structure for a variety of coding assistants. The CLI command also doubles as an MCP server.
|
||||
|
||||
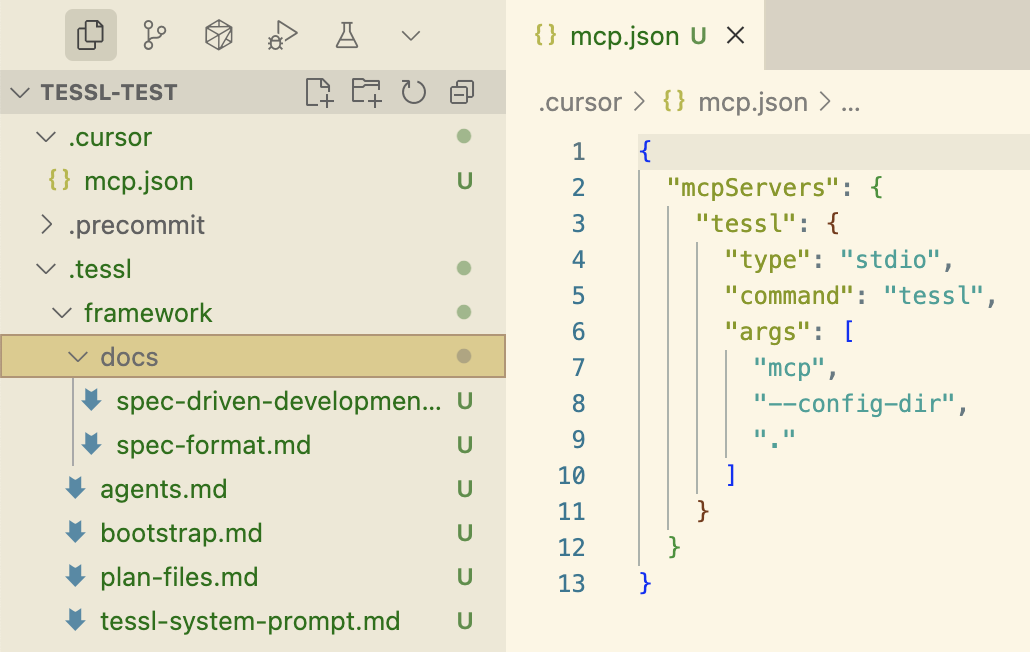
|
||||
|
||||
Tessl is the only one of these three tools that explicitly aspires to a spec-anchored approach, and is even exploring the spec-as-source level of SDD. A Tessl spec can serve as the main artifact that is being maintained and edited, with the code even marked with a comment at the top saying `// GENERATED FROM SPEC - DO NOT EDIT`. This is currently a 1:1 mapping between spec and code files, i.e. one spec translates into one file in the codebase. But Tessl is still in beta and they are experimenting with different versions of this, so I can imagine that this approach could also be taken on a level where one spec maps to a code component with multiple files. It remains to be seen what the alpha product will support. (The Tessl team themselves see their framework as something that is more in the future than their current public product, the Tessl Registry.)
|
||||
|
||||
Here is an example of a spec that I had the Tessl CLI reverse engineer (`tessl document --code ...js`) from a JavaScript file in an existing codebase:
|
||||
|
||||
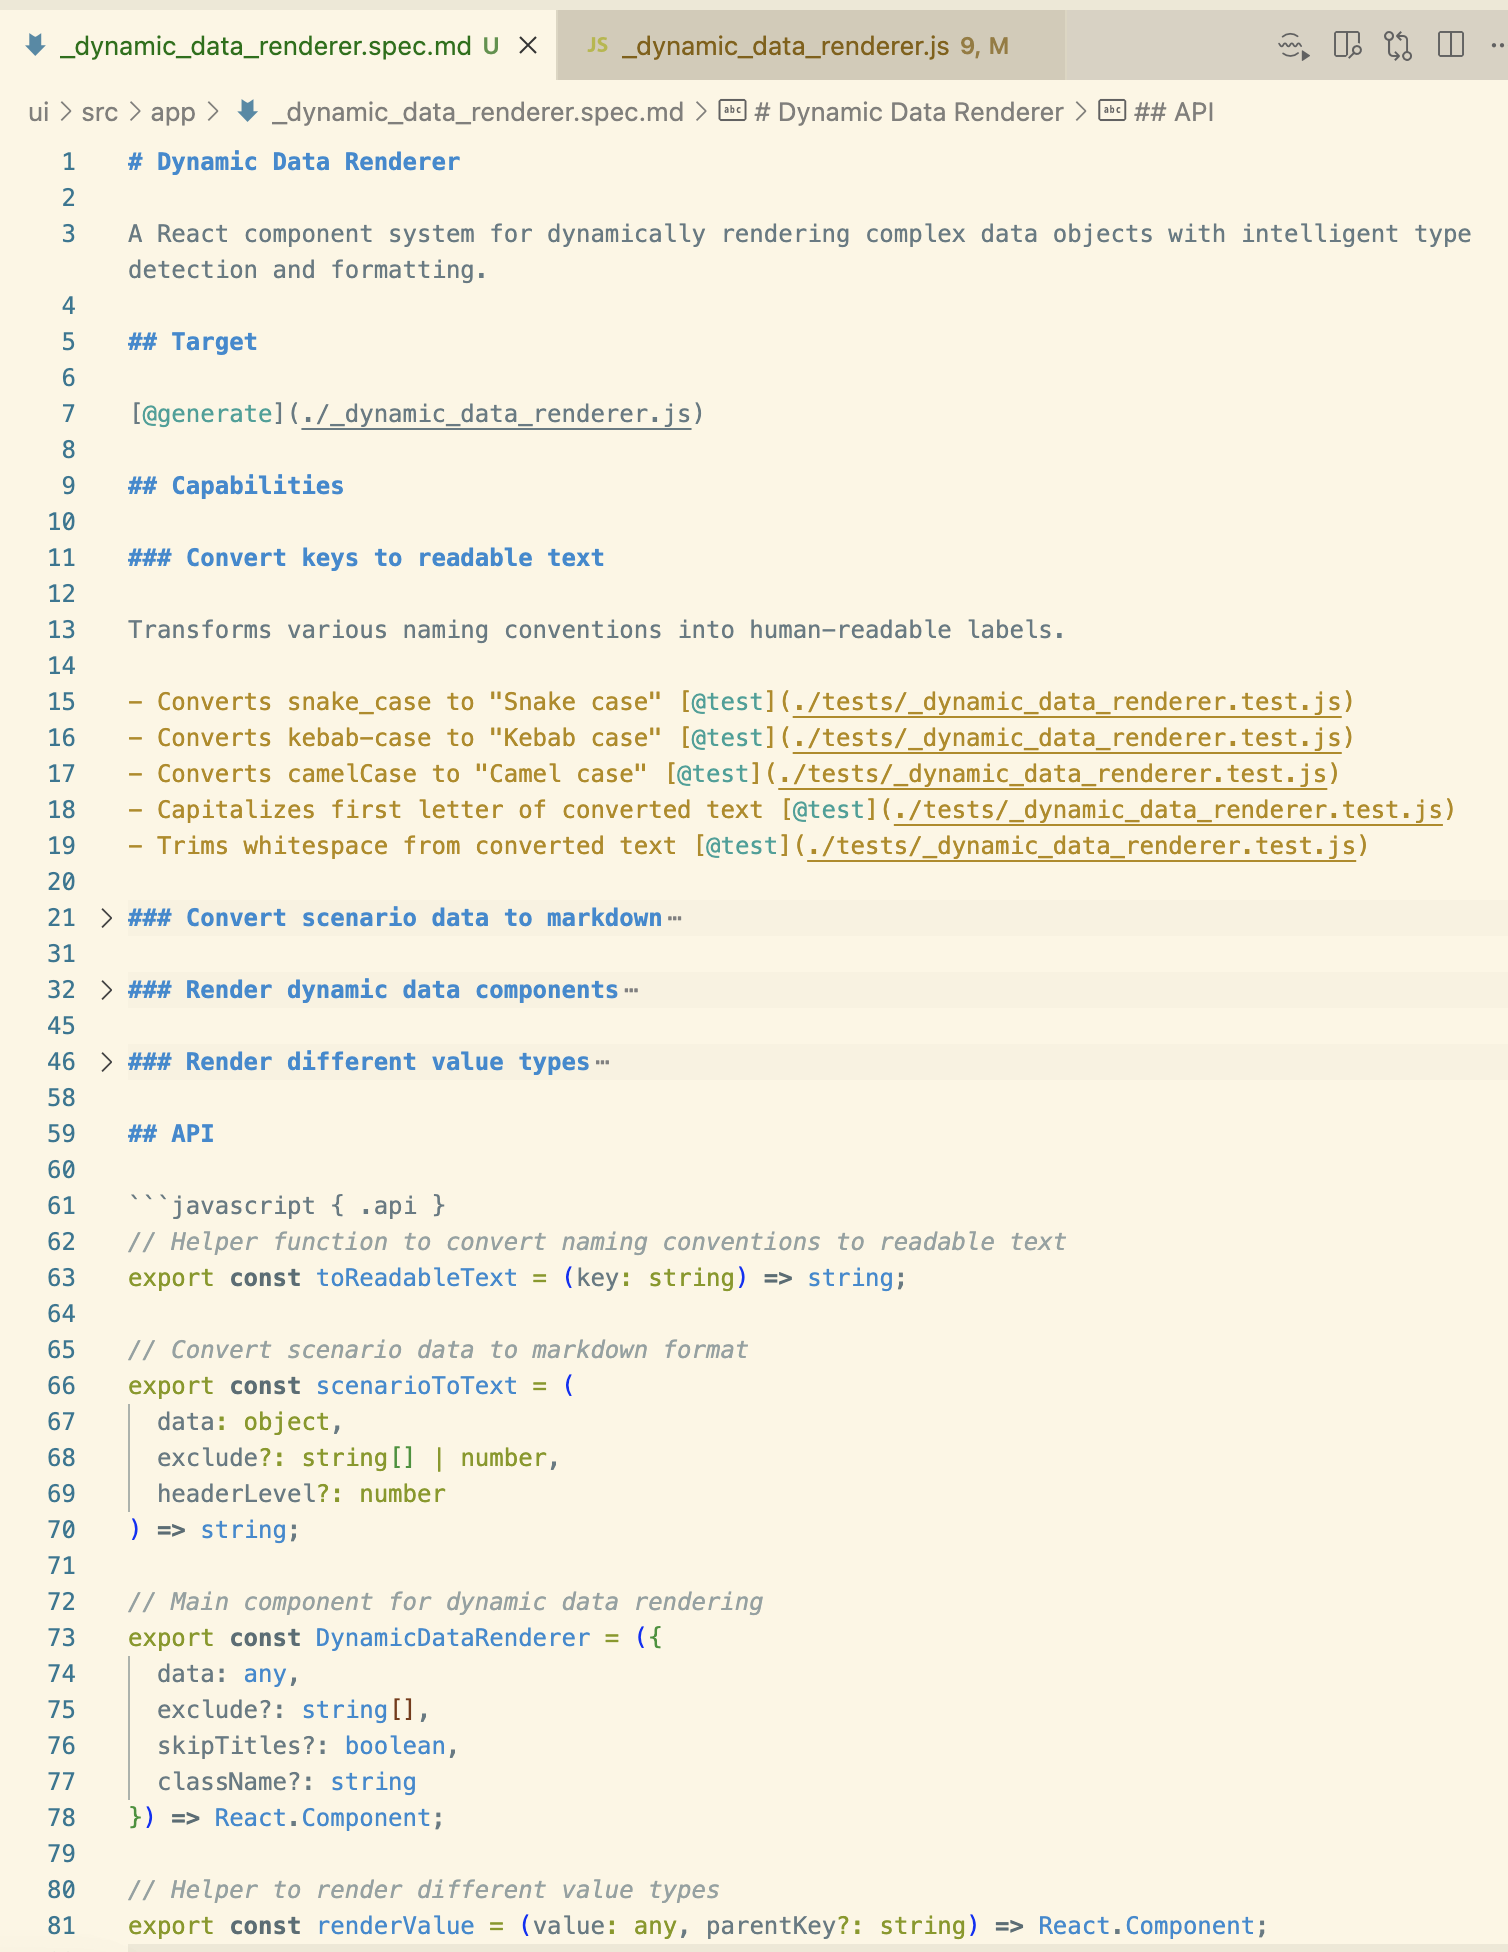
|
||||
|
||||
Tags like `@generate` or `@test` seem to tell Tessl what to generate. The API section shows the idea of defining at least the interfaces that get exposed to other parts of the codebase in the spec, presumably to make sure that these more crucial parts of the generated component are fully under the control of the maintainer. Running `tessl build` for this spec generates the corresponding JavaScript code file.
|
||||
|
||||
Putting the specs for spec-as-source at a quite low abstraction level, per code file, probably reduces amount of steps and interpretations the LLM has to do, and therefore the chance of errors. Even at this low abstraction level I have seen the non-determinism in action though, when I generated code multiple times from the same spec. It was an interesting exercise to iterate on the spec and make it more and more specific to increase the repeatability of the code generation. That process reminded me of some of the pitfalls and challenges of writing an unambiguous and complete specification.
|
||||
|
||||
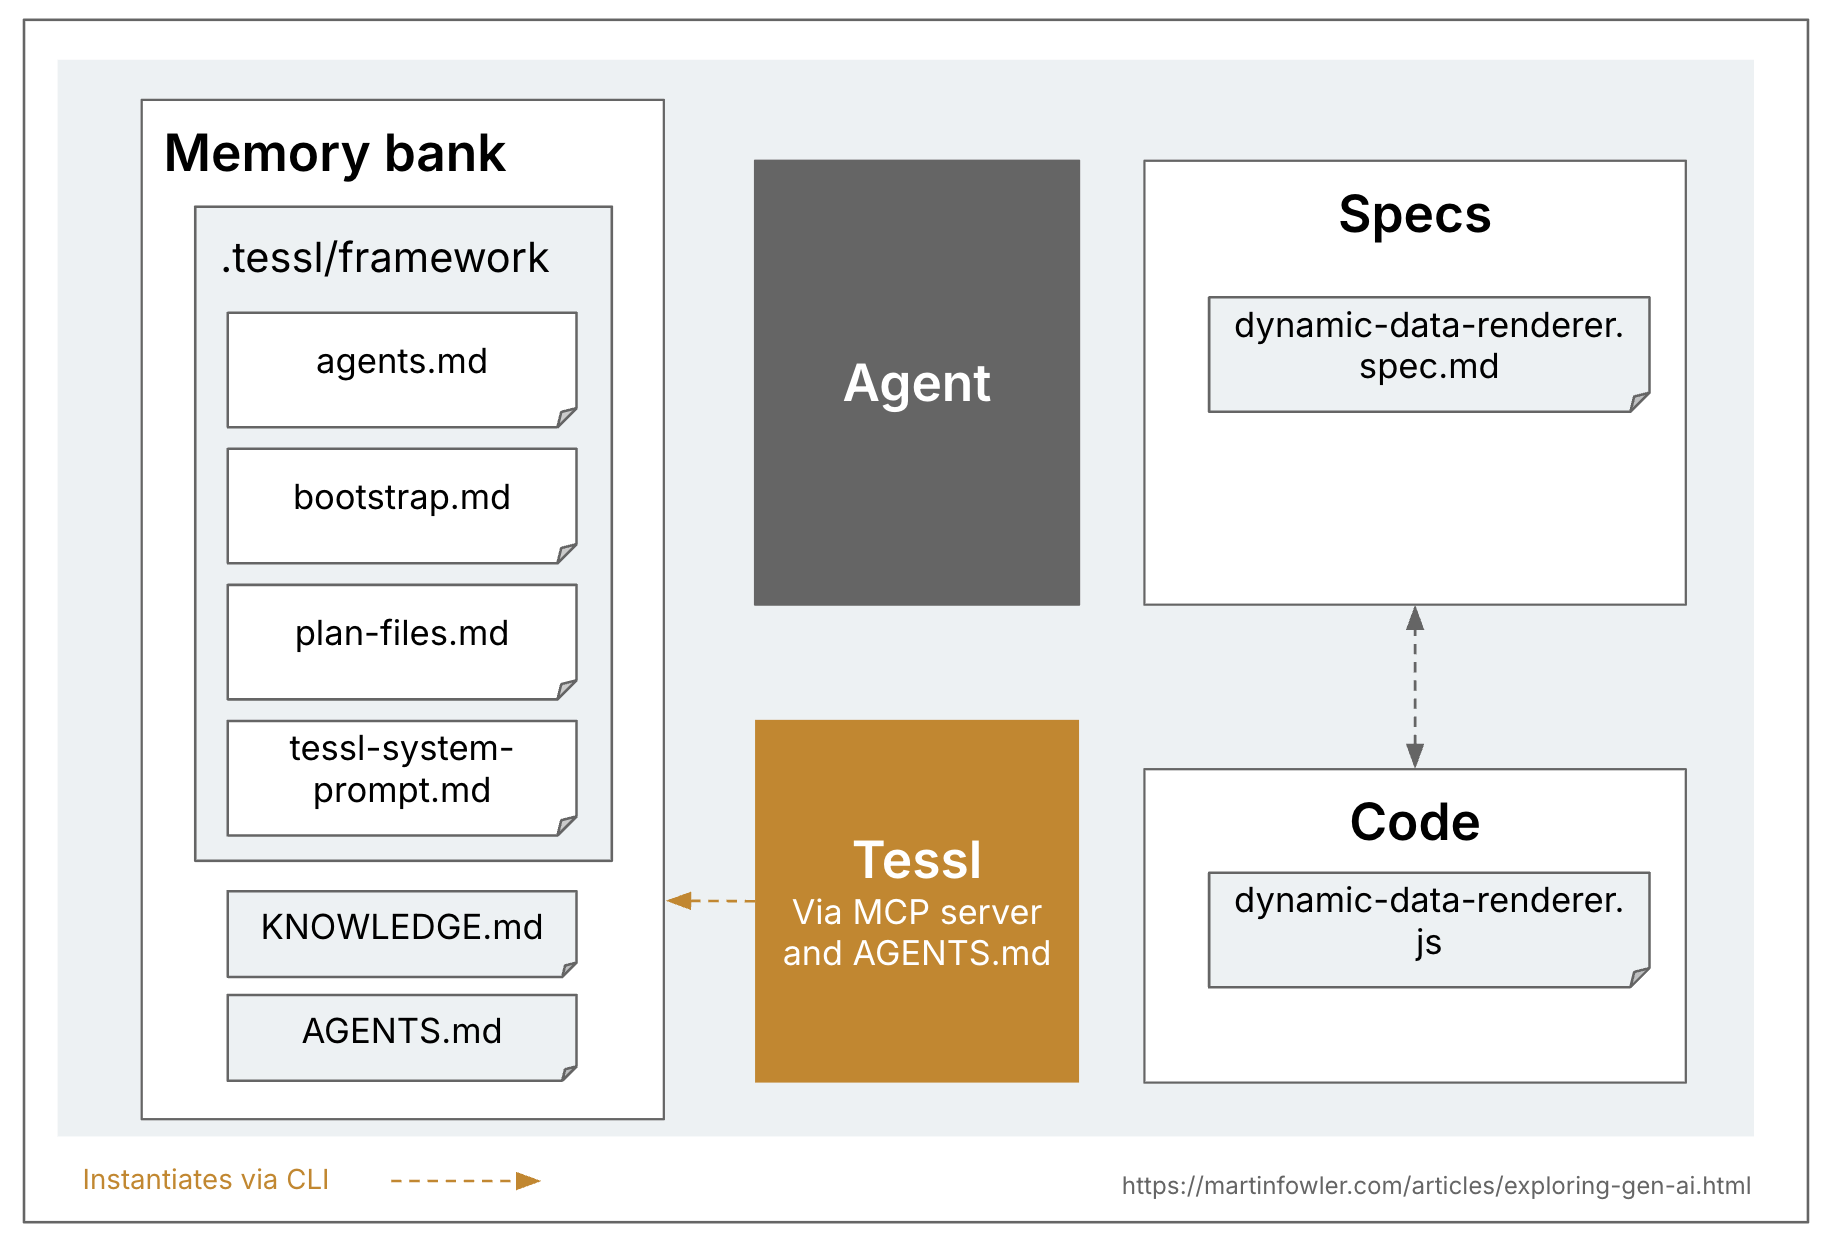
|
||||
|
||||
## Observations and questions
|
||||
|
||||
These three tools are all labelling themselves as implementations of spec-driven development, but they are quite different from each other. So that’s the first thing to keep in mind when talking about SDD, it is not just one thing.
|
||||
|
||||
### One workflow to fit all sizes?
|
||||
|
||||
Kiro and spec-kit provide one opinionated workflow each, but I’m quite sure that neither of them is suitable for the majority of real life coding problems. In particular, it’s not quite clear to me how they would cater to enough different problem sizes to be generally applicable.
|
||||
|
||||
When I asked Kiro to fix a small bug ([it was the same one I used in the past to try Codex](https://martinfowler.com/articles/exploring-gen-ai/autonomous-agents-codex-example.html)), it quickly became clear that the workflow was like using a sledgehammer to crack a nut. The requirements document turned this small bug into 4 “user stories” with a total of 16 acceptance criteria, including gems like “User story: As a developer, I want the transformation function to handle edge cases gracefully, so that the system remains robust when new category formats are introduced.”
|
||||
|
||||
I had a similar challenge when I used spec-kit, I wasn’t quite sure what size of problem to use it for. Available tutorials are usually based on creating an application from scratch, because that’s easiest for a tutorial. One of the use cases I ended up trying was a feature that would be a 3-5 point story on one of my past teams. The feature depended on a lot of code that was already there, it was supposed to build an overview modal that summarised a bunch of data from an existing dashboard. With the amount of steps spec-kit took, and the amount of markdown files it created for me to review, this again felt like overkill for the size of the problem. It was a bigger problem than the one I used with Kiro, but also a much more elaborate workflow. I never even finished the full implementation, but I think in the same time it took me to run and review the spec-kit results I could have implemented the feature with “plain” AI-assisted coding, and I would have felt much more in control.
|
||||
|
||||
An effective SDD tool would at the very least have to provide flexibility for a few different core workflows, for different sizes and types of changes.
|
||||
|
||||
### Reviewing markdown over reviewing code?
|
||||
|
||||
As just mentioned, and as you can see in the description of the tool above, spec-kit created a LOT of markdown files for me to review. They were repetitive, both with each other, and with the code that already existed. Some contained code already. Overall they were just very verbose and tedious to review. In Kiro it was a little easier, as you only get 3 files, and it’s more intuitive to understand the mental model of “requirements > design > tasks”. However, as mentioned, Kiro also was way too verbose for the small bug I was asking it to fix.
|
||||
|
||||
To be honest, I’d rather review code than all these markdown files. An effective SDD tool would have to provide a very good spec review experience.
|
||||
|
||||
### False sense of control?
|
||||
|
||||
Even with all of these files and templates and prompts and workflows and checklists, I frequently saw the agent ultimately not follow all the instructions. Yes, the context windows are now larger, which is often mentioned as one of the enablers of spec-driven development. But just because the windows are larger, doesn’t mean that AI will properly pick up on everything that’s in there.
|
||||
|
||||
For example: Spec-kit has a research step somewhere during planning, and it did a lot of research on the existing code and what’s already there, which was great because I asked it to add a feature that built on top of existing code. But ultimately the agent ignored the notes that these were descriptions of existing classes, it just took them as a new specification and generated them all over again, creating duplicates. But I didn’t only see examples of ignoring instructions, I also saw the agent go way overboard because it was too eagerly following instructions (e.g. one of the constitution articles).
|
||||
|
||||
The past has shown that the best way for us to stay in control of what we’re building are small, iterative steps, so I’m very skeptical that lots of up-front spec design is a good idea, especially when it’s overly verbose. An effective SDD tool would have to cater to an iterative approach, but small work packages almost seem counter to the idea of SDD.
|
||||
|
||||
### How to effectively separate functional from technical spec?
|
||||
|
||||
It is a common idea in SDD to be intentional about the separation between functional spec and technical implementation. The underlying aspiration I guess is that ultimately, we could have AI fill in all the solutioning and details, and switch to different tech stacks with the same spec.
|
||||
|
||||
In reality, when I was trying spec-kit, I frequently got confused when to stay on the functional level, and when it was time to add technical details. The tutorial and documentation also weren’t quite consistent with it, there seem to be different interpretations of what “purely functional” really means. And when I think back on the many, many user stories I’ve read in my career that weren’t properly separating requirements from implementation, I don’t think we have a good track record as a profession to do this well.
|
||||
|
||||
### Who is the target user?
|
||||
|
||||
Many of the demos and tutorials for spec-driven development tools include things like defining product and feature goals, they even incorporate terms like “user story”. The idea here might be to use AI as an enabler for cross-skilling, and have developers participate more heavily in requirements analysis? Or have developers pair with product people when they work on this workflow? None of this is made explicit though, it’s presented as a given that a developer would do all this analysis.
|
||||
|
||||
In which case I would ask myself again, what problem size and type is SDD meant for? Probably not for large features that are still very unclear, as surely that would require more specialist product and requirements skills, and lots of other steps like research and stakeholder involvement?
|
||||
|
||||
|
||||
|
||||
### Spec-anchored and spec-as-source: Are we learning from the past?
|
||||
|
||||
While many people draw analogies between SDD and TDD or BDD, I think another important parallel to look at for spec-as-source in particular is MDD (model-driven development). I worked on a few projects at the beginning of my career that heavily used MDD, and I kept being reminded about that when I was trying out the Tessl Framework. The models in MDD were basically the specs, albeit not in natural language, but expressed in e.g. custom UML or a textual DSL. We built custom code generators to turn those specs into code.
|
||||
|
||||
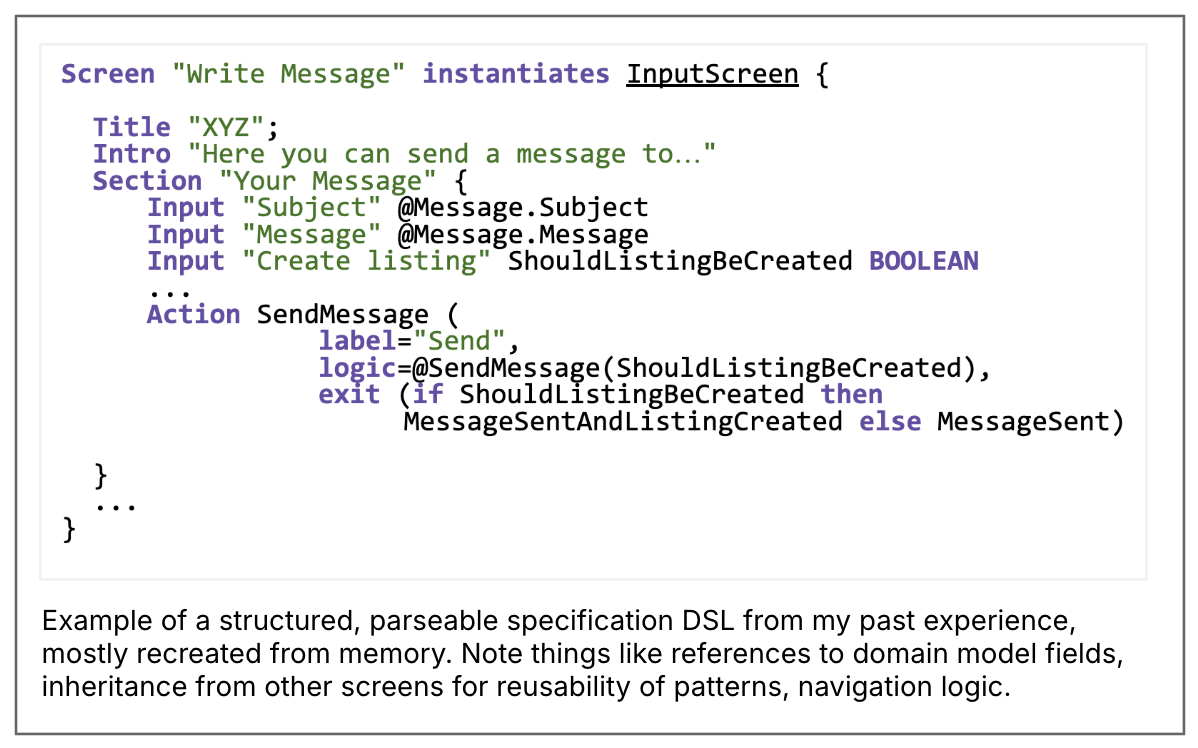
|
||||
|
||||
Ultimately, MDD never took off for business applications, it sits at an awkward abstraction level and just creates too much overhead and constraints. But LLMs take some of the overhead and constraints of MDD away, so there is a new hope that we can now finally focus on writing specs and just generate code from them. With LLMs, we are not constrained by a predefined and parseable spec language anymore, and we don’t have to build elaborate code generators. The price for that is LLMs’ non-determinism of course. And the parseable structure also had upsides that we’re losing now: We could provide the spec author with a lot of tool support to write valid, complete and consistent specs. I wonder if spec-as-source, and even spec-anchoring, might end up with the downsides of both MDD and LLMs: Inflexibility *and* non-determinism.
|
||||
|
||||
To be clear, I’m not nostalgic about my MDD experience in the past and saying “we might as well bring that back”. But we should look to code-from-spec attempts in the past to learn from them when we explore spec-driven today.
|
||||
|
||||
## Conclusions
|
||||
|
||||
In my personal usage of AI-assisted coding, I also often spend time on carefully crafting some form of spec first to give to the coding agent. So the general principle of spec-first is definitely valuable in many situations, and the different approaches of how to structure that spec are very sought after. They are among the top most frequently asked questions I hear at the moment from practitioners: “How do I structure my memory bank?”, “How do I write a good specification and design document for AI?”.
|
||||
|
||||
But the term “spec-driven development” isn’t very well defined yet, and it’s already [semantically diffused](https://martinfowler.com/bliki/SemanticDiffusion.html). I’ve even recently heard people use “spec” basically as a synonym for “detailed prompt”.
|
||||
|
||||
Regarding the tools I’ve tried, I have listed many of my questions about their real world usefulness here. I wonder if some of them are trying to feed AI agents with our existing workflows too literally, ultimately amplifying existing challenges like review overload and hallucinations. Especially with the more elaborate approaches that create lots of files, I can’t help but think of the German compound word “Verschlimmbesserung”: Are we making something worse in the attempt of making it better?
|
||||
-164
@@ -1,164 +0,0 @@
|
||||
---
|
||||
title: "VectifyAI/PageIndex: 📑 PageIndex: Document Index for Vectorless, Reasoning-based RAG"
|
||||
source: "https://github.com/VectifyAI/PageIndex"
|
||||
author:
|
||||
- "[[rejojer]]"
|
||||
published:
|
||||
created: 2026-01-20
|
||||
description: "📑 PageIndex: Document Index for Vectorless, Reasoning-based RAG - VectifyAI/PageIndex"
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://github.com/VectifyAI/PageIndex
|
||||
> Title: VectifyAI/PageIndex: 📑 PageIndex: Document Index for Vectorless, Reasoning-based RAG
|
||||
> Clipped:
|
||||
|
||||
**[PageIndex](https://github.com/VectifyAI/PageIndex)** Public
|
||||
|
||||
📑 PageIndex: Document Index for Vectorless, Reasoning-based RAG
|
||||
|
||||
[pageindex.ai](https://pageindex.ai/ "https://pageindex.ai")
|
||||
|
||||
[MIT license](https://github.com/VectifyAI/PageIndex/blob/main/LICENSE)
|
||||
|
||||
[Open in github.dev](https://github.dev/) [Open in a new github.dev tab](https://github.dev/) [Open in codespace](https://github.com/codespaces/new/VectifyAI/PageIndex?resume=1)
|
||||
|
||||
[](https://vectify.ai/pageindex)
|
||||
|
||||
|
||||
[](https://trendshift.io/repositories/14736)
|
||||
|
||||
**Reasoning-based RAG ◦ No Vector DB ◦ No Chunking ◦ Human-like Retrieval**
|
||||
|
||||
**🔥 Releases:**
|
||||
|
||||
- [**PageIndex Chat**](https://chat.pageindex.ai/): The first human-like document-analysis agent [platform](https://chat.pageindex.ai/) built for professional long documents. Can also be integrated via [MCP](https://pageindex.ai/mcp) or [API](https://docs.pageindex.ai/quickstart) (beta).
|
||||
|
||||
**📝 Articles:**
|
||||
|
||||
- [**PageIndex Framework**](https://pageindex.ai/blog/pageindex-intro): Introduces the PageIndex framework — an *agentic, in-context* *tree index* that enables LLMs to perform *reasoning-based*, *human-like retrieval* over long documents, without vector DB or chunking.
|
||||
|
||||
**🧪 Cookbooks:**
|
||||
|
||||
- [Vectorless RAG](https://docs.pageindex.ai/cookbook/vectorless-rag-pageindex): A minimal, hands-on example of reasoning-based RAG using PageIndex. No vectors, no chunking, and human-like retrieval.
|
||||
- [Vision-based Vectorless RAG](https://docs.pageindex.ai/cookbook/vision-rag-pageindex): OCR-free, vision-only RAG with PageIndex's reasoning-native retrieval workflow that works directly over PDF page images.
|
||||
|
||||
---
|
||||
|
||||
Are you frustrated with vector database retrieval accuracy for long professional documents? Traditional vector-based RAG relies on semantic *similarity* rather than true *relevance*. But **similarity ≠ relevance** — what we truly need in retrieval is **relevance**, and that requires **reasoning**. When working with professional documents that demand domain expertise and multi-step reasoning, similarity search often falls short.
|
||||
|
||||
Inspired by AlphaGo, we propose **[PageIndex](https://vectify.ai/pageindex)** — a **vectorless**, **reasoning-based RAG** system that builds a **hierarchical tree index** from long documents and uses LLMs to **reason** *over that index* for **agentic, context-aware retrieval**. It simulates how *human experts* navigate and extract knowledge from complex documents through *tree search*, enabling LLMs to *think* and *reason* their way to the most relevant document sections. PageIndex performs retrieval in two steps:
|
||||
|
||||
1. Generate a “Table-of-Contents” **tree structure index** of documents
|
||||
2. Perform reasoning-based retrieval through **tree search**
|
||||
|
||||
[](https://pageindex.ai/blog/pageindex-intro "The PageIndex Framework")
|
||||
|
||||
### 🎯 Features
|
||||
|
||||
Compared to traditional vector-based RAG, **PageIndex** features:
|
||||
|
||||
- **No Vector DB**: Uses document structure and LLM reasoning for retrieval, instead of vector similarity search.
|
||||
- **No Chunking**: Documents are organized into natural sections, not artificial chunks.
|
||||
- **Human-like Retrieval**: Simulates how human experts navigate and extract knowledge from complex documents.
|
||||
- **Better Explainability and Traceability**: Retrieval is based on reasoning — traceable and interpretable, with page and section references. No more opaque, approximate vector search (“vibe retrieval”).
|
||||
|
||||
PageIndex powers a reasoning-based RAG system that achieved **state-of-the-art** [98.7% accuracy](https://github.com/VectifyAI/Mafin2.5-FinanceBench) on FinanceBench, demonstrating superior performance over vector-based RAG solutions in professional document analysis (see our [blog post](https://vectify.ai/blog/Mafin2.5) for details).
|
||||
|
||||
To learn more, please see a detailed introduction of the [PageIndex framework](https://pageindex.ai/blog/pageindex-intro). Check out this GitHub repo for open-source code, and the [cookbooks](https://docs.pageindex.ai/cookbook), [tutorials](https://docs.pageindex.ai/tutorials), and [blog](https://pageindex.ai/blog) for additional usage guides and examples.
|
||||
|
||||
The PageIndex service is available as a ChatGPT-style [chat platform](https://chat.pageindex.ai/), or can be integrated via [MCP](https://pageindex.ai/mcp) or [API](https://docs.pageindex.ai/quickstart).
|
||||
|
||||
- Self-host — run locally with this open-source repo.
|
||||
- Cloud Service — try instantly with our [Chat Platform](https://chat.pageindex.ai/), or integrate with [MCP](https://pageindex.ai/mcp) or [API](https://docs.pageindex.ai/quickstart).
|
||||
- *Enterprise* — private or on-prem deployment. [Contact us](https://ii2abc2jejf.typeform.com/to/tK3AXl8T) or [book a demo](https://calendly.com/pageindex/meet) for more details.
|
||||
- Try the [**Vectorless RAG**](https://github.com/VectifyAI/PageIndex/blob/main/cookbook/pageindex_RAG_simple.ipynb) notebook — a *minimal*, hands-on example of reasoning-based RAG using PageIndex.
|
||||
- Experiment with [*Vision-based Vectorless RAG*](https://github.com/VectifyAI/PageIndex/blob/main/cookbook/vision_RAG_pageindex.ipynb) — no OCR; a minimal, reasoning-native RAG pipeline that works directly over page images.
|
||||
|
||||
---
|
||||
|
||||
PageIndex can transform lengthy PDF documents into a semantic **tree structure**, similar to a *"table of contents"* but optimized for use with Large Language Models (LLMs). It's ideal for: financial reports, regulatory filings, academic textbooks, legal or technical manuals, and any document that exceeds LLM context limits.
|
||||
|
||||
Below is an example PageIndex tree structure. Also see more example [documents](https://github.com/VectifyAI/PageIndex/tree/main/tests/pdfs) and generated [tree structures](https://github.com/VectifyAI/PageIndex/tree/main/tests/results).
|
||||
|
||||
You can generate the PageIndex tree structure with this open-source repo, or use our [API](https://docs.pageindex.ai/quickstart)
|
||||
|
||||
---
|
||||
|
||||
You can follow these steps to generate a PageIndex tree from a PDF document.
|
||||
|
||||
```
|
||||
pip3 install --upgrade -r requirements.txt
|
||||
```
|
||||
|
||||
Create a `.env` file in the root directory and add your API key:
|
||||
|
||||
```
|
||||
CHATGPT_API_KEY=your_openai_key_here
|
||||
```
|
||||
```
|
||||
python3 run_pageindex.py --pdf_path /path/to/your/document.pdf
|
||||
```
|
||||
**Optional parameters**
|
||||
You can customize the processing with additional optional arguments:
|
||||
|
||||
```
|
||||
--model OpenAI model to use (default: gpt-4o-2024-11-20)
|
||||
--toc-check-pages Pages to check for table of contents (default: 20)
|
||||
--max-pages-per-node Max pages per node (default: 10)
|
||||
--max-tokens-per-node Max tokens per node (default: 20000)
|
||||
--if-add-node-id Add node ID (yes/no, default: yes)
|
||||
--if-add-node-summary Add node summary (yes/no, default: yes)
|
||||
--if-add-doc-description Add doc description (yes/no, default: yes)
|
||||
```
|
||||
|
||||
**Markdown support**
|
||||
We also provide markdown support for PageIndex. You can use the \`-md\_path\` flag to generate a tree structure for a markdown file.
|
||||
```
|
||||
python3 run_pageindex.py --md_path /path/to/your/document.md
|
||||
```
|
||||
|
||||
> Note: in this function, we use "#" to determine node heading and their levels. For example, "##" is level 2, "###" is level 3, etc. Make sure your markdown file is formatted correctly. If your Markdown file was converted from a PDF or HTML, we don't recommend using this function, since most existing conversion tools cannot preserve the original hierarchy. Instead, use our [PageIndex OCR](https://pageindex.ai/blog/ocr), which is designed to preserve the original hierarchy, to convert the PDF to a markdown file and then use this function.
|
||||
|
||||
---
|
||||
|
||||
[Mafin 2.5](https://vectify.ai/mafin) is a reasoning-based RAG system for financial document analysis, powered by **PageIndex**. It achieved a state-of-the-art [**98.7% accuracy**](https://vectify.ai/blog/Mafin2.5) on the [FinanceBench](https://arxiv.org/abs/2311.11944) benchmark, significantly outperforming traditional vector-based RAG systems.
|
||||
|
||||
PageIndex's hierarchical indexing and reasoning-driven retrieval enable precise navigation and extraction of relevant context from complex financial reports, such as SEC filings and earnings disclosures.
|
||||
|
||||
Explore the full [benchmark results](https://github.com/VectifyAI/Mafin2.5-FinanceBench) and our [blog post](https://vectify.ai/blog/Mafin2.5) for detailed comparisons and performance metrics.
|
||||
|
||||
[](https://github.com/VectifyAI/Mafin2.5-FinanceBench)
|
||||
|
||||
---
|
||||
|
||||
## 🧭 Resources
|
||||
|
||||
- 🧪 [Cookbooks](https://docs.pageindex.ai/cookbook/vectorless-rag-pageindex): hands-on, runnable examples and advanced use cases.
|
||||
- 📖 [Tutorials](https://docs.pageindex.ai/doc-search): practical guides and strategies, including *Document Search* and *Tree Search*.
|
||||
- 📝 [Blog](https://pageindex.ai/blog): technical articles, research insights, and product updates.
|
||||
- 🔌 [MCP setup](https://pageindex.ai/mcp#quick-setup) & [API docs](https://docs.pageindex.ai/quickstart): integration details and configuration options.
|
||||
|
||||
---
|
||||
|
||||
Leave us a star 🌟 if you like our project. Thank you!
|
||||
|
||||
[](https://private-user-images.githubusercontent.com/13518252/481667856-eae4ff38-48ae-4a7c-b19f-eab81201d794.gif?jwt=eyJ0eXAiOiJKV1QiLCJhbGciOiJIUzI1NiJ9.eyJpc3MiOiJnaXRodWIuY29tIiwiYXVkIjoicmF3LmdpdGh1YnVzZXJjb250ZW50LmNvbSIsImtleSI6ImtleTUiLCJleHAiOjE3Njg4NzI2MzYsIm5iZiI6MTc2ODg3MjMzNiwicGF0aCI6Ii8xMzUxODI1Mi80ODE2Njc4NTYtZWFlNGZmMzgtNDhhZS00YTdjLWIxOWYtZWFiODEyMDFkNzk0LmdpZj9YLUFtei1BbGdvcml0aG09QVdTNC1ITUFDLVNIQTI1NiZYLUFtei1DcmVkZW50aWFsPUFLSUFWQ09EWUxTQTUzUFFLNFpBJTJGMjAyNjAxMjAlMkZ1cy1lYXN0LTElMkZzMyUyRmF3czRfcmVxdWVzdCZYLUFtei1EYXRlPTIwMjYwMTIwVDAxMjUzNlomWC1BbXotRXhwaXJlcz0zMDAmWC1BbXotU2lnbmF0dXJlPWEyNzA4ZDQxMmI2MjhiOGVkODU3MTMxOWFhNTE0Mjg4MzdkOWI3N2Q4ZmY4MTY2MDk3NDZlZjE1YzcwNWJlZjkmWC1BbXotU2lnbmVkSGVhZGVycz1ob3N0In0.pSfTU0Lp63eIF6U3IbkEbdIwr2_U4ZL708xLqslt8uQ)
|
||||
|
||||
---
|
||||
|
||||
© 2025 [Vectify AI](https://vectify.ai/)
|
||||
|
||||
## Releases
|
||||
|
||||
No releases published
|
||||
|
||||
## Packages
|
||||
|
||||
No packages published
|
||||
|
||||
## Languages
|
||||
|
||||
- [Python 100.0%](https://github.com/VectifyAI/PageIndex/search?l=python)
|
||||
@@ -1,124 +0,0 @@
|
||||
---
|
||||
title: "Welcome to LessWrong! — LessWrong"
|
||||
source: "https://www.lesswrong.com/posts/bJ2haLkcGeLtTWaD5/welcome-to-lesswrong"
|
||||
author:
|
||||
- "[[Ruby]]"
|
||||
published: 2019-06-15
|
||||
created: 2026-01-16
|
||||
description: "The road to wisdom? Well, it's plainand simple to express: • Errand errand err againbut lessand lessand less. • – Piet Hein …"
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://www.lesswrong.com/posts/bJ2haLkcGeLtTWaD5/welcome-to-lesswrong
|
||||
> Title: Welcome to LessWrong! — LessWrong
|
||||
> Clipped:
|
||||
|
||||
| *The road to wisdom? Well, it's plain 通往智慧的道路?好吧,它显而易见* *and simple to express: 且易于表达:* *Err 犯错* *and err 以及犯错的智慧* *and err again 并再次犯错* *but **less** 但更少* *and **less** 越来越少* *and **less**.越少越好* – Piet Hein – 彼得·海恩 |
|
||||
| --- |
|
||||
|
||||
LessWrong is an online forum and community dedicated to improving human reasoning and decision-making. We seek to hold true beliefs and to be effective at accomplishing our goals. Each day, we aim to be less wrong about the world than the day before.
|
||||
LessWrong 是一个致力于提升人类推理与决策能力的在线论坛和社区。我们力求持有正确的信念,并高效实现目标。每一天,我们都努力让自己对世界的认识比前一天更少错误。
|
||||
|
||||
*See also our* [*New User's Guide*](https://www.lesswrong.com/posts/LbbrnRvc9QwjJeics/new-user-s-guide-to-lesswrong)
|
||||
也可参见我们的新用户指南*.*
|
||||
|
||||
## Training Rationality 训练理性
|
||||
|
||||
Rationality has a number of definitions [^1] on LessWrong, but perhaps the most canonical is that the more rational you are, the more likely your reasoning leads you to have accurate beliefs, and by extension, allows you to make decisions that most effectively advance your goals.
|
||||
在 LessWrong 上,理性有多种定义 <sup><span><a href="https://www.lesswrong.com/posts/bJ2haLkcGeLtTWaD5/#fnajdy57uko9d">[1]</a></span></sup> ,但或许最经典的诠释是:你的理性程度越高,你的推理过程就越有可能助你获得准确的信念,进而让你能够做出最有效推动目标达成的决策。
|
||||
|
||||
LessWrong contains a lot of content on this topic. How minds work (both human, artificial, and theoretical ideal), how to reason better, and how to have discussions that are productive. We're very big fans of [Bayes Theorem](https://www.lesswrong.com/w/bayes_rule?l=1zq) and other theories of normatively correct reasoning [^2].
|
||||
LessWrong 包含大量关于此主题的内容,涉及心智如何运作(包括人类心智、人工心智以及理论上的理想心智)、如何更好地推理,以及如何进行富有成效的讨论。我们非常推崇贝叶斯定理和其他规范性正确推理理论。
|
||||
|
||||
To get started improving your Rationality, we recommend reading the background-knowledge text of LessWrong, [Rationality: A-Z](https://www.lesswrong.com/rationality) (aka "The Sequences") or at least [selected highlights](https://www.lesswrong.com/highlights) from it. After that, looking through the Rationality section of the [Concepts Portal](https://www.lesswrong.com/concepts) is a good thing to do.
|
||||
要开始提升你的理性思维,我们建议先阅读 LessWrong 的背景知识文本《理性:从 A 到 Z》(又称“The Sequences”),或者至少阅读其中的精选亮点部分。之后,浏览概念门户的理性部分是很好的下一步。
|
||||
|
||||
## Applying Rationality 运用理性
|
||||
|
||||
You might value Rationality for its own sake, however, many people want to be better reasoners so they can have more accurate beliefs about topics they care about, and make better decisions.
|
||||
您可能因理性本身的价值而珍视它,然而,许多人希望成为更出色的推理者,以便能在他们关心的话题上拥有更准确的信念,并做出更明智的决策。
|
||||
|
||||
Using LessWrong-style reasoning, contributors to LessWrong have written essays on an immense variety of topics on LessWrong, each time approaching the topic with a desire to know what's actually true (not just what's convenient or pleasant to believe), being deliberate about processing the evidence, and avoiding common pitfalls of human reason.
|
||||
在 LessWrong,投稿者运用 LessWrong 风格的推理,针对极其多样的主题撰写了大量文章。每一次探讨主题时,他们都怀有探究真实(而非仅仅相信便捷或令人愉悦的观点)的渴望,审慎地处理证据,并避开人类推理中常见的陷阱。
|
||||
|
||||
Check out the [Concepts Portal](https://www.lesswrong.com/concepts) to find essays on topics such as [artificial intelligence](https://www.lesswrong.com/w/ai), [history](https://www.lesswrong.com/w/history), [philosophy of science](https://www.lesswrong.com/w/practice-and-philosophy-of-science), [language](https://www.lesswrong.com/w/philosophy-of-language), [psychology](https://www.lesswrong.com/w/psychology), [biology](https://www.lesswrong.com/w/biology), [morality](https://www.lesswrong.com/w/ethics-and-morality), [culture](https://www.lesswrong.com/w/social-and-cultural-dynamics), [self-care](https://www.lesswrong.com/w/well-being), [economics](https://www.lesswrong.com/w/economics), [game theory](https://www.lesswrong.com/w/game-theory), [productivity](https://www.lesswrong.com/w/productivity), [art](https://www.lesswrong.com/w/art), [nutrition](https://www.lesswrong.com/w/nutrition), [relationships](https://www.lesswrong.com/w/relationships-interpersonal) and hundreds of other topics broad and narrow.
|
||||
查阅概念门户,探索人工智能、历史、科学哲学、语言、心理学、生物学、道德、文化、自我关怀、经济学、博弈论、生产力、艺术、营养、人际关系以及数百种主题广泛或专精的文章。
|
||||
|
||||
## LessWrong and Artificial Intelligence"少错"社区与人工智能
|
||||
|
||||
For several reasons, LessWrong is a website and community with a strong interest in AI and specifically causing powerful AI systems to be safe and beneficial.
|
||||
出于多种原因,LessWrong 作为一个网站及社群,对人工智能领域抱有浓厚兴趣,尤其关注如何确保强大的人工智能系统安全且有益。
|
||||
|
||||
- AI is a field concerned with how minds and intelligence works, overlapping a lot with rationality.
|
||||
人工智能这一领域探讨意识与智能的运行机制,与理性思维研究存在大量交集。
|
||||
- Historically, LessWrong was seeded by the writings of Eliezer Yudkowsky, an artificial intelligence researcher.
|
||||
回溯历史,LessWrong 最初源自人工智能研究者埃利泽·尤德考斯基的系列著作。
|
||||
- Many members of the LessWrong community are heavily motivated by trying to improve the world as much as possible, and these people were convinced many years ago that AI was a very big deal for the future of humanity. Since then LessWrong has hosted a lot of discussion of AI Alignment/AI Safety, and that's only accelerated recently with further AI capabilities developments.
|
||||
LessWrong 社区中的许多成员都深受改善世界的强烈动机驱动,这些人多年前就已确信人工智能将对人类的未来产生深远影响。自那时起,LessWrong 便承载了大量关于人工智能对齐与安全性的讨论,而随着近期人工智能能力的进一步发展,这一讨论趋势正在加速。
|
||||
- LessWrong is also integrated with the [Alignment Forum](https://www.alignmentforum.org/about)
|
||||
LessWrong 还与 Alignment Forum 紧密集成。
|
||||
- The LessWrong team who maintain and develop the site are predominantly motivated by trying to cause powerful AI outcomes to be good.
|
||||
维护和开发此网站的 LessWrong 团队,主要动力源于努力促使强大的人工智能带来积极成果。
|
||||
|
||||
If you want to see more or less AI content, you can adjust your Frontpage Tag Filters according to taste [^3].
|
||||
若您希望调整人工智能相关内容的显示频率,可根据个人喜好通过首页标签筛选功能进行设置 <sup><span><a href="https://www.lesswrong.com/posts/bJ2haLkcGeLtTWaD5/#fnq85givw8h9">[3]</a></span></sup> 。
|
||||
|
||||
## Getting Started on LessWrong开启 LessWrong 之旅
|
||||
|
||||
The [New User's Guide](https://www.lesswrong.com/posts/LbbrnRvc9QwjJeics/new-user-s-guide-to-lesswrong) is a great place to start.
|
||||
《新手指南》是极佳的入门起点。
|
||||
|
||||
The core background text of LessWrong is the collection of essays, [Rationality: A-Z](https://www.lesswrong.com/rationality) (aka "The Sequences"). Reading these will help you understand the mindset and philosophy that defines the site. Those looking for a quick introduction can start with [The Sequences Highlights](https://www.lesswrong.com/highlights)
|
||||
LessWrong 的核心背景文本是文集《理性:从 A 到 Z》(亦称“序列系列”)。阅读这些文章将帮助您理解定义本网站思维方式与哲学理念。寻求快速入门者可先阅读《序列精选》
|
||||
|
||||
Other top writings include [The Codex](https://www.lesswrong.com/codex) (writings by Scott Alexander) and [Harry Potter & The Methods of Rationality](https://www.lesswrong.com/hpmor). Also see the [Library Page](https://www.lesswrong.com/library) for many curated collections of posts and the [Concepts Portal.](https://www.lesswrong.com/concepts)
|
||||
其他重要作品包括《秘典集》(斯科特·亚历山大文集)与《哈利波特与理性之道》。您亦可通过文库页查阅众多精选文章合集,或浏览概念门户获取系统知识。
|
||||
|
||||
Also, feel free to introduce yourself in the monthly [open and welcome thread](https://www.lesswrong.com/w/open-threads?sortedBy=new)!
|
||||
也欢迎你随时在每月开放欢迎贴中自我介绍!
|
||||
|
||||
Lastly, we do recommend that new contributors (posters or commenters) take time to familiarize themselves with the sites norms and culture to maximize the chances that your contributions are well-received.
|
||||
最后,我们确实建议新贡献者(无论是发布文章还是评论)花时间熟悉本站的规范和文化,这样能最大限度地让你的贡献受到欢迎。
|
||||
|
||||
Thanks for your interest!
|
||||
感谢你的关注!
|
||||
|
||||
\- The LW Team
|
||||
\- LW 团队
|
||||
|
||||
- [**LessWrong FAQ LessWrong 常见问题**](https://www.lesswrong.com/posts/2rWKkWuPrgTMpLRbp/lesswrong-faq)
|
||||
- [**A Brief History of LessWrong
|
||||
LessWrong 简史**](https://www.lesswrong.com/posts/S69ogAGXcc9EQjpcZ/a-brief-history-of-lesswrong)
|
||||
- [**Team 团队**](https://www.lesswrong.com/posts/aG74jJkiPccqdkK3c/the-lesswrong-team-page-under-construction)
|
||||
- [**LessWrong Concepts LessWrong 概念**](https://www.lesswrong.com/concepts)
|
||||
|
||||
x
|
||||
|
||||
[^1]: Definitions of Rationality as used on LessWrong include:
|
||||
LessWrong 中使用的理性定义包括:
|
||||
|
||||
\- Rationality is thinking in ways that systematically arrive at truth.
|
||||
\- 理性是系统性地抵达真理的思维方式。
|
||||
|
||||
\- Rationality is thinking in ways that cause you to systematically achieve your goals.
|
||||
\- 理性是系统性地帮助你达成目标的思维方式。
|
||||
|
||||
\- Rationality is trying to do better on purpose.
|
||||
\- 理性意味着要有意为之,力求做得更好。
|
||||
|
||||
\- Rationality is reasoning well even in the face of massive uncertainty.
|
||||
\- 理性意味着即便面对巨大的不确定性,仍能进行良好的推理。
|
||||
|
||||
\- Rationality is making good decisions even when it’s hard.
|
||||
\- 理性意味着即便在艰难时刻,也能做出明智的决策。
|
||||
|
||||
\-Rationality is being self-aware, understanding how your own mind works, and applying this knowledge to thinking better.
|
||||
\- 理性意味着保持自我觉察,理解自身心智的运作方式,并运用这些知识来更好地思考。
|
||||
|
||||
[^2]: There are in fact laws of thought no less ironclad than the law of physics \[[source](https://www.lesswrong.com/posts/QkX2bAkwG2EpGvNug/the-second-law-of-thermodynamics-and-engines-of-cognition)\].
|
||||
事实上,思维的法则与物理定律同样牢不可破【来源】。
|
||||
|
||||
[^3]: Hover your mouse over the tags to be able to adjust their weighting in your Latest Posts feed.
|
||||
将鼠标悬停在标签上,即可在“最新帖子”动态中调整其权重。
|
||||
@@ -1,64 +0,0 @@
|
||||
---
|
||||
title: "YAGNI Principle in Software Development"
|
||||
source: "https://www.geeksforgeeks.org/software-engineering/what-is-yagni-principle-you-arent-gonna-need-it/"
|
||||
author:
|
||||
- "[[GeeksforGeeks]]"
|
||||
published: 2024-02-20
|
||||
created: 2026-01-22
|
||||
description: "Your All-in-One Learning Portal: GeeksforGeeks is a comprehensive educational platform that empowers learners across domains-spanning computer science and programming, school education, upskilling, commerce, software tools, competitive exams, and more."
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://www.geeksforgeeks.org/software-engineering/what-is-yagni-principle-you-arent-gonna-need-it/
|
||||
> Title: YAGNI Principle in Software Development
|
||||
> Clipped:
|
||||
|
||||
页面已保存到 Trilium。 [在 Trilium 中打开。](https://www.geeksforgeeks.org/software-engineering/what-is-yagni-principle-you-arent-gonna-need-it/)
|
||||
|
||||
Last Updated: 27 Aug, 2025
|
||||
|
||||
****"YAGNI"**** stands for ****"You Aren't Gonna Need It".**** It is a principle in software development that suggests developers should only implement features that are necessary for the current requirements and not add any additional functionality that might be needed in the future.
|
||||
|
||||
- This principle is based on the idea that adding unnecessary features can lead to increased complexity, longer development times, and potentially more bugs.
|
||||
- The YAGNI principle is closely related to the ****"**** [****KISS****](https://www.geeksforgeeks.org/software-engineering/kiss-principle-in-software-development/) ****"**** principle ("Keep It Simple, Stupid"), which advocates for simplicity in design and avoiding unnecessary complexity. Both principles encourage developers to focus on delivering the simplest solution that meets current requirements, rather than trying to anticipate and accommodate potential future needs.
|
||||
|
||||
### Why a developer should follow the YAGNI principle?
|
||||
|
||||
The developer should follow YAGNI principles for the following reasons:
|
||||
|
||||
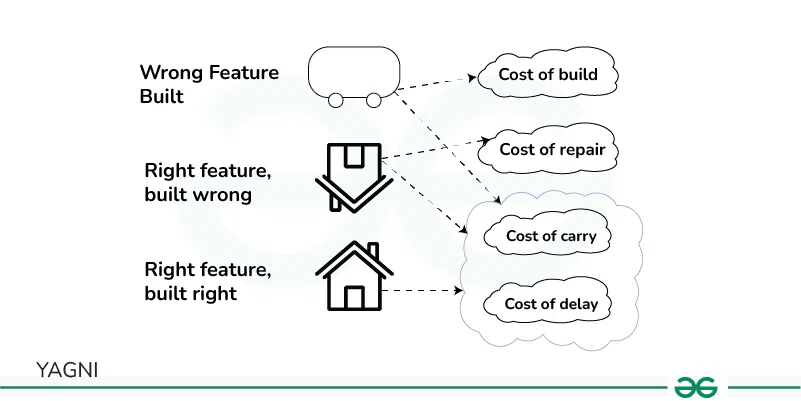
|
||||
- ****Cost of Building:**** The cost of build is the amount of time, effort, and resources spent on creating a feature or solution. It includes everything from planning and coding to testing.
|
||||
- ****Cost of Delay:**** The cost of delay is the missed opportunity or economic impact of not delivering a feature or solution promptly.
|
||||
- ****Cost of Carry:**** When a feature adds complexity, it can make it harder to work on other parts of the software, leading to additional time and effort.
|
||||
- ****Cost of Repair:**** The cost of repair, also known as technical debt, is the ongoing cost associated with fixing mistakes, bugs, or poor choices made during the development of a feature.
|
||||
|
||||
### Steps to follow YAGNI Principle
|
||||
|
||||
To use YAGNI as a developer, it's like having a practical guide to keep your work focused and efficient.
|
||||
|
||||
|
||||
|
||||
YAGNI Principal for Developers
|
||||
|
||||
****1\. Get the Necessary Requirements**** : All the things your project needs and sort them into "must-haves" and "can wait."
|
||||
|
||||
****2\. Discuss with Your Team:**** After that, it's time to talk with your team. Share your plans and goals with them. This makes sure everyone is on the same page and understands what needs to be done.
|
||||
|
||||
****3\. Analyze a Simple Plan for the Solution:**** Now, when it comes to planning the actual work, keep it simple. Break down your big goals into smaller tasks. This helps you avoid getting overwhelmed and ensures you're focusing on what really matters.
|
||||
|
||||
****4\. Refuse If It Doesn't Fit for the Solution:**** Sometimes, your team might come up with new ideas or want to add extra things. While these ideas might be cool, you've got to be ready to say "no" unless it's a tiny improvement. Saying "no" can be tough, but it keeps you from getting off track and missing deadlines.
|
||||
|
||||
****5\. Have a Record of Your Progress:**** Keep a record of what you've done. It's like keeping score in a game. This helps you see how far you've come and if you're heading in the right direction.
|
||||
|
||||
### Advantages of Applying YAGNI
|
||||
|
||||
- ****Reduced Development Time****: By avoiding the development of unused features, teams can focus on current requirements and accelerate the delivery of functional software.
|
||||
- ****Improved Maintainability:**** Simpler, more focused codebases are easier to understand and maintain over time.
|
||||
- ****Increased Flexibility:**** The ability to defer decisions until later provides more clarity and allows for more informed design choices as requirements become clearer.
|
||||
- ****Fewer Bugs:**** Less complex code with fewer speculative features is less prone to bugs, leading to a higher quality product
|
||||
|
||||
Overall, YAGNI complements other software development principles by focusing on delivering the simplest solution that meets the current requirements and avoiding unnecessary functionality.
|
||||
|
||||
Article Tags:
|
||||
-1773
File diff suppressed because it is too large
Load Diff
-151
File diff suppressed because one or more lines are too long
-626
@@ -1,626 +0,0 @@
|
||||
---
|
||||
title: "github/spec-kit: 💫 Toolkit to help you get started with Spec-Driven Development"
|
||||
source: "https://github.com/github/spec-kit"
|
||||
author:
|
||||
- "[[localden]]"
|
||||
published:
|
||||
created: 2026-01-21
|
||||
description: "💫 Toolkit to help you get started with Spec-Driven Development - github/spec-kit"
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://github.com/github/spec-kit
|
||||
> Title: github/spec-kit: 💫 Toolkit to help you get started with Spec-Driven Development
|
||||
> Clipped:
|
||||
|
||||
**[spec-kit](https://github.com/github/spec-kit)** Public
|
||||
|
||||
💫 Toolkit to help you get started with Spec-Driven Development
|
||||
|
||||
[MIT license](https://github.com/github/spec-kit/blob/main/LICENSE)
|
||||
|
||||
[Code of conduct](https://github.com/github/spec-kit/blob/main/CODE_OF_CONDUCT.md)
|
||||
|
||||
[Contributing](https://github.com/github/spec-kit/blob/main/CONTRIBUTING.md)
|
||||
|
||||
[Security policy](https://github.com/github/spec-kit/blob/main/SECURITY.md)
|
||||
|
||||
[63.9k stars](https://github.com/github/spec-kit/stargazers) [5.5k forks](https://github.com/github/spec-kit/forks) [443 watching](https://github.com/github/spec-kit/watchers) [Branches](https://github.com/github/spec-kit/branches) [Tags](https://github.com/github/spec-kit/tags) [Activity](https://github.com/github/spec-kit/activity) [Custom properties](https://github.com/github/spec-kit/custom-properties)
|
||||
|
||||
Public repository
|
||||
|
||||
[Open in github.dev](https://github.dev/) [Open in a new github.dev tab](https://github.dev/) [Open in codespace](https://github.com/codespaces/new/github/spec-kit?resume=1)
|
||||
|
||||
<table><thead><tr><th colspan="2"><span>Name</span></th><th colspan="1"><span>Name</span></th><th><p><span>Last commit message</span></p></th><th colspan="1"><p><span>Last commit date</span></p></th></tr></thead><tbody><tr><td colspan="3"><p><span><a href="https://github.com/github/spec-kit/commit/9111699cd27879e3e6301651a03e502ecb6dd65d">Merge pull request</a> <a href="https://github.com/github/spec-kit/pull/1288">#1288</a> <a href="https://github.com/github/spec-kit/commit/9111699cd27879e3e6301651a03e502ecb6dd65d">from github/localden/updates</a></span></p><p><span><a href="https://github.com/github/spec-kit/commit/9111699cd27879e3e6301651a03e502ecb6dd65d">9111699</a> ·</span></p><p><a href="https://github.com/github/spec-kit/commits/main/"><span><span><span>528 Commits</span></span></span></a></p></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/tree/main/.devcontainer">.devcontainer</a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/tree/main/.devcontainer">.devcontainer</a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/71c2c63d555ea5b86e1498f6e572023bc01ff98d">chore: replace <code>bun</code> by <code>node/npm</code> in the <code>devcontainer</code> (as many CLI…</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/tree/main/.github">.github</a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/tree/main/.github">.github</a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/8d552e6d116801a2b3cac203405a0a469257ac2c">feat:qoder agent</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/tree/main/docs">docs</a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/tree/main/docs">docs</a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/0049b1cdc2f9ba12def39a042872b0b1b6a09704">Update Markdown formatting</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/tree/main/media">media</a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/tree/main/media">media</a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/f892b9e1cb21d3cd971c98cebea3270d7d167d7c">fix: broken media files</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/tree/main/memory">memory</a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/tree/main/memory">memory</a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/36ff7e6505ae49eee73a01c2d3dd31752f73ad5d">Update files</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/tree/main/scripts">scripts</a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/tree/main/scripts">scripts</a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/6c3d698959bd9a8b50588f93c1bffb517fc6d5a0">Merge pull request</a> <a href="https://github.com/github/spec-kit/pull/1237">#1237</a> <a href="https://github.com/github/spec-kit/commit/6c3d698959bd9a8b50588f93c1bffb517fc6d5a0">from Mearman/fix/branch-number-collision-bug</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/tree/main/src/specify_cli"><span>src/</span> <span>specify_cli</span></a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/tree/main/src/specify_cli"><span>src/</span> <span>specify_cli</span></a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/ad3bb1a5fed2f8a8e5a569b9927a784691cee501">resolve confilct and add qoder agent</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/tree/main/templates">templates</a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/tree/main/templates">templates</a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/0049b1cdc2f9ba12def39a042872b0b1b6a09704">Update Markdown formatting</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/blob/main/.gitattributes">.gitattributes</a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/blob/main/.gitattributes">.gitattributes</a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/36ff7e6505ae49eee73a01c2d3dd31752f73ad5d">Update files</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/github/spec-kit/blob/main/.gitignore">.gitignore</a></p></td><td colspan="1"><p><a href="https://github.com/github/spec-kit/blob/main/.gitignore">.gitignore</a></p></td><td><p><a href="https://github.com/github/spec-kit/commit/392dbf20c4a6589cf2df6b8627e6beac2773e878">docs: Add comprehensive upgrading guide for Spec Kit</a></p></td><td></td></tr><tr><td colspan="3"></td></tr></tbody></table>
|
||||
|
||||
[](https://github.com/github/spec-kit/blob/main/media/logo_large.webp)
|
||||
|
||||
**An open source toolkit that allows you to focus on product scenarios and predictable outcomes instead of vibe coding every piece from scratch.**
|
||||
|
||||
---
|
||||
|
||||
- [🤔 What is Spec-Driven Development?](https://github.com/github/#-what-is-spec-driven-development)
|
||||
- [⚡ Get Started](https://github.com/github/#-get-started)
|
||||
- [📽️ Video Overview](https://github.com/github/#%EF%B8%8F-video-overview)
|
||||
- [🤖 Supported AI Agents](https://github.com/github/#-supported-ai-agents)
|
||||
- [🔧 Specify CLI Reference](https://github.com/github/#-specify-cli-reference)
|
||||
- [📚 Core Philosophy](https://github.com/github/#-core-philosophy)
|
||||
- [🌟 Development Phases](https://github.com/github/#-development-phases)
|
||||
- [🎯 Experimental Goals](https://github.com/github/#-experimental-goals)
|
||||
- [🔧 Prerequisites](https://github.com/github/#-prerequisites)
|
||||
- [📖 Learn More](https://github.com/github/#-learn-more)
|
||||
- [📋 Detailed Process](https://github.com/github/#-detailed-process)
|
||||
- [🔍 Troubleshooting](https://github.com/github/#-troubleshooting)
|
||||
- [👥 Maintainers](https://github.com/github/#-maintainers)
|
||||
- [💬 Support](https://github.com/github/#-support)
|
||||
- [🙏 Acknowledgements](https://github.com/github/#-acknowledgements)
|
||||
- [📄 License](https://github.com/github/#-license)
|
||||
|
||||
Spec-Driven Development **flips the script** on traditional software development. For decades, code has been king — specifications were just scaffolding we built and discarded once the "real work" of coding began. Spec-Driven Development changes this: **specifications become executable**, directly generating working implementations rather than just guiding them.
|
||||
|
||||
Choose your preferred installation method:
|
||||
|
||||
Install once and use everywhere:
|
||||
|
||||
```
|
||||
uv tool install specify-cli --from git+https://github.com/github/spec-kit.git
|
||||
```
|
||||
|
||||
Then use the tool directly:
|
||||
|
||||
```
|
||||
# Create new project
|
||||
specify init <PROJECT_NAME>
|
||||
|
||||
# Or initialize in existing project
|
||||
specify init . --ai claude
|
||||
# or
|
||||
specify init --here --ai claude
|
||||
|
||||
# Check installed tools
|
||||
specify check
|
||||
```
|
||||
|
||||
To upgrade Specify, see the [Upgrade Guide](https://github.com/github/spec-kit/blob/main/docs/upgrade.md) for detailed instructions. Quick upgrade:
|
||||
|
||||
```
|
||||
uv tool install specify-cli --force --from git+https://github.com/github/spec-kit.git
|
||||
```
|
||||
|
||||
Run directly without installing:
|
||||
|
||||
```
|
||||
uvx --from git+https://github.com/github/spec-kit.git specify init <PROJECT_NAME>
|
||||
```
|
||||
|
||||
**Benefits of persistent installation:**
|
||||
|
||||
- Tool stays installed and available in PATH
|
||||
- No need to create shell aliases
|
||||
- Better tool management with `uv tool list`, `uv tool upgrade`, `uv tool uninstall`
|
||||
- Cleaner shell configuration
|
||||
|
||||
Launch your AI assistant in the project directory. The `/speckit.*` commands are available in the assistant.
|
||||
|
||||
Use the **`/speckit.constitution`** command to create your project's governing principles and development guidelines that will guide all subsequent development.
|
||||
|
||||
```
|
||||
/speckit.constitution Create principles focused on code quality, testing standards, user experience consistency, and performance requirements
|
||||
```
|
||||
|
||||
Use the **`/speckit.specify`** command to describe what you want to build. Focus on the **what** and **why**, not the tech stack.
|
||||
|
||||
```
|
||||
/speckit.specify Build an application that can help me organize my photos in separate photo albums. Albums are grouped by date and can be re-organized by dragging and dropping on the main page. Albums are never in other nested albums. Within each album, photos are previewed in a tile-like interface.
|
||||
```
|
||||
|
||||
Use the **`/speckit.plan`** command to provide your tech stack and architecture choices.
|
||||
|
||||
```
|
||||
/speckit.plan The application uses Vite with minimal number of libraries. Use vanilla HTML, CSS, and JavaScript as much as possible. Images are not uploaded anywhere and metadata is stored in a local SQLite database.
|
||||
```
|
||||
|
||||
Use **`/speckit.tasks`** to create an actionable task list from your implementation plan.
|
||||
|
||||
```
|
||||
/speckit.tasks
|
||||
```
|
||||
|
||||
Use **`/speckit.implement`** to execute all tasks and build your feature according to the plan.
|
||||
|
||||
```
|
||||
/speckit.implement
|
||||
```
|
||||
|
||||
For detailed step-by-step instructions, see our [comprehensive guide](https://github.com/github/spec-kit/blob/main/spec-driven.md).
|
||||
|
||||
Want to see Spec Kit in action? Watch our [video overview](https://www.youtube.com/watch?v=a9eR1xsfvHg&pp=0gcJCckJAYcqIYzv)!
|
||||
|
||||
[](https://www.youtube.com/watch?v=a9eR1xsfvHg&pp=0gcJCckJAYcqIYzv)
|
||||
|
||||
| Agent | Support | Notes |
|
||||
| --- | --- | --- |
|
||||
| [Qoder CLI](https://qoder.com/cli) | ✅ | |
|
||||
| [Amazon Q Developer CLI](https://aws.amazon.com/developer/learning/q-developer-cli/) | ⚠️ | Amazon Q Developer CLI [does not support](https://github.com/aws/amazon-q-developer-cli/issues/3064) custom arguments for slash commands. |
|
||||
| [Amp](https://ampcode.com/) | ✅ | |
|
||||
| [Auggie CLI](https://docs.augmentcode.com/cli/overview) | ✅ | |
|
||||
| [Claude Code](https://www.anthropic.com/claude-code) | ✅ | |
|
||||
| [CodeBuddy CLI](https://www.codebuddy.ai/cli) | ✅ | |
|
||||
| [Codex CLI](https://github.com/openai/codex) | ✅ | |
|
||||
| [Cursor](https://cursor.sh/) | ✅ | |
|
||||
| [Gemini CLI](https://github.com/google-gemini/gemini-cli) | ✅ | |
|
||||
| [GitHub Copilot](https://code.visualstudio.com/) | ✅ | |
|
||||
| [IBM Bob](https://www.ibm.com/products/bob) | ✅ | IDE-based agent with slash command support |
|
||||
| [Jules](https://jules.google.com/) | ✅ | |
|
||||
| [Kilo Code](https://github.com/Kilo-Org/kilocode) | ✅ | |
|
||||
| [opencode](https://opencode.ai/) | ✅ | |
|
||||
| [Qwen Code](https://github.com/QwenLM/qwen-code) | ✅ | |
|
||||
| [Roo Code](https://roocode.com/) | ✅ | |
|
||||
| [SHAI (OVHcloud)](https://github.com/ovh/shai) | ✅ | |
|
||||
| [Windsurf](https://windsurf.com/) | ✅ | |
|
||||
|
||||
The `specify` command supports the following options:
|
||||
|
||||
### Commands
|
||||
|
||||
| Command | Description |
|
||||
| --- | --- |
|
||||
| `init` | Initialize a new Specify project from the latest template |
|
||||
| `check` | Check for installed tools (`git`, `claude`, `gemini`, `code` / `code-insiders`, `cursor-agent`, `windsurf`, `qwen`, `opencode`, `codex`, `shai`, `qoder`) |
|
||||
|
||||
| Argument/Option | Type | Description |
|
||||
| --- | --- | --- |
|
||||
| `<project-name>` | Argument | Name for your new project directory (optional if using `--here`, or use `.` for current directory) |
|
||||
| `--ai` | Option | AI assistant to use: `claude`, `gemini`, `copilot`, `cursor-agent`, `qwen`, `opencode`, `codex`, `windsurf`, `kilocode`, `auggie`, `roo`, `codebuddy`, `amp`, `shai`, `q`, `bob`, or `qoder` |
|
||||
| `--script` | Option | Script variant to use: `sh` (bash/zsh) or `ps` (PowerShell) |
|
||||
| `--ignore-agent-tools` | Flag | Skip checks for AI agent tools like Claude Code |
|
||||
| `--no-git` | Flag | Skip git repository initialization |
|
||||
| `--here` | Flag | Initialize project in the current directory instead of creating a new one |
|
||||
| `--force` | Flag | Force merge/overwrite when initializing in current directory (skip confirmation) |
|
||||
| `--skip-tls` | Flag | Skip SSL/TLS verification (not recommended) |
|
||||
| `--debug` | Flag | Enable detailed debug output for troubleshooting |
|
||||
| `--github-token` | Option | GitHub token for API requests (or set GH\_TOKEN/GITHUB\_TOKEN env variable) |
|
||||
|
||||
### Examples
|
||||
|
||||
```
|
||||
# Basic project initialization
|
||||
specify init my-project
|
||||
|
||||
# Initialize with specific AI assistant
|
||||
specify init my-project --ai claude
|
||||
|
||||
# Initialize with Cursor support
|
||||
specify init my-project --ai cursor-agent
|
||||
|
||||
# Initialize with Qoder support
|
||||
specify init my-project --ai qoder
|
||||
|
||||
# Initialize with Windsurf support
|
||||
specify init my-project --ai windsurf
|
||||
|
||||
# Initialize with Amp support
|
||||
specify init my-project --ai amp
|
||||
|
||||
# Initialize with SHAI support
|
||||
specify init my-project --ai shai
|
||||
|
||||
# Initialize with IBM Bob support
|
||||
specify init my-project --ai bob
|
||||
|
||||
# Initialize with PowerShell scripts (Windows/cross-platform)
|
||||
specify init my-project --ai copilot --script ps
|
||||
|
||||
# Initialize in current directory
|
||||
specify init . --ai copilot
|
||||
# or use the --here flag
|
||||
specify init --here --ai copilot
|
||||
|
||||
# Force merge into current (non-empty) directory without confirmation
|
||||
specify init . --force --ai copilot
|
||||
# or
|
||||
specify init --here --force --ai copilot
|
||||
|
||||
# Skip git initialization
|
||||
specify init my-project --ai gemini --no-git
|
||||
|
||||
# Enable debug output for troubleshooting
|
||||
specify init my-project --ai claude --debug
|
||||
|
||||
# Use GitHub token for API requests (helpful for corporate environments)
|
||||
specify init my-project --ai claude --github-token ghp_your_token_here
|
||||
|
||||
# Check system requirements
|
||||
specify check
|
||||
```
|
||||
|
||||
After running `specify init`, your AI coding agent will have access to these slash commands for structured development:
|
||||
|
||||
#### Core Commands
|
||||
|
||||
Essential commands for the Spec-Driven Development workflow:
|
||||
|
||||
| Command | Description |
|
||||
| --- | --- |
|
||||
| `/speckit.constitution` | Create or update project governing principles and development guidelines |
|
||||
| `/speckit.specify` | Define what you want to build (requirements and user stories) |
|
||||
| `/speckit.plan` | Create technical implementation plans with your chosen tech stack |
|
||||
| `/speckit.tasks` | Generate actionable task lists for implementation |
|
||||
| `/speckit.implement` | Execute all tasks to build the feature according to the plan |
|
||||
|
||||
#### Optional Commands
|
||||
|
||||
Additional commands for enhanced quality and validation:
|
||||
|
||||
| Command | Description |
|
||||
| --- | --- |
|
||||
| `/speckit.clarify` | Clarify underspecified areas (recommended before `/speckit.plan`; formerly `/quizme`) |
|
||||
| `/speckit.analyze` | Cross-artifact consistency & coverage analysis (run after `/speckit.tasks`, before `/speckit.implement`) |
|
||||
| `/speckit.checklist` | Generate custom quality checklists that validate requirements completeness, clarity, and consistency (like "unit tests for English") |
|
||||
|
||||
### Environment Variables
|
||||
|
||||
| Variable | Description |
|
||||
| --- | --- |
|
||||
| `SPECIFY_FEATURE` | Override feature detection for non-Git repositories. Set to the feature directory name (e.g., `001-photo-albums`) to work on a specific feature when not using Git branches. \*\*Must be set in the context of the agent you're working with prior to using `/speckit.plan` or follow-up commands. |
|
||||
|
||||
Spec-Driven Development is a structured process that emphasizes:
|
||||
|
||||
- **Intent-driven development** where specifications define the " *what* " before the " *how* "
|
||||
- **Rich specification creation** using guardrails and organizational principles
|
||||
- **Multi-step refinement** rather than one-shot code generation from prompts
|
||||
- **Heavy reliance** on advanced AI model capabilities for specification interpretation
|
||||
|
||||
| Phase | Focus | Key Activities |
|
||||
| --- | --- | --- |
|
||||
| **0-to-1 Development** ("Greenfield") | Generate from scratch | - Start with high-level requirements - Generate specifications - Plan implementation steps - Build production-ready applications |
|
||||
| **Creative Exploration** | Parallel implementations | - Explore diverse solutions - Support multiple technology stacks & architectures - Experiment with UX patterns |
|
||||
| **Iterative Enhancement** ("Brownfield") | Brownfield modernization | - Add features iteratively - Modernize legacy systems - Adapt processes |
|
||||
|
||||
Our research and experimentation focus on:
|
||||
|
||||
### Technology independence
|
||||
|
||||
- Create applications using diverse technology stacks
|
||||
- Validate the hypothesis that Spec-Driven Development is a process not tied to specific technologies, programming languages, or frameworks
|
||||
|
||||
### Enterprise constraints
|
||||
|
||||
- Demonstrate mission-critical application development
|
||||
- Incorporate organizational constraints (cloud providers, tech stacks, engineering practices)
|
||||
- Support enterprise design systems and compliance requirements
|
||||
|
||||
### User-centric development
|
||||
|
||||
- Build applications for different user cohorts and preferences
|
||||
- Support various development approaches (from vibe-coding to AI-native development)
|
||||
- Validate the concept of parallel implementation exploration
|
||||
- Provide robust iterative feature development workflows
|
||||
- Extend processes to handle upgrades and modernization tasks
|
||||
|
||||
## 🔧 Prerequisites
|
||||
|
||||
- **Linux/macOS/Windows**
|
||||
- [Supported](https://github.com/github/#-supported-ai-agents) AI coding agent.
|
||||
- [uv](https://docs.astral.sh/uv/) for package management
|
||||
- [Python 3.11+](https://www.python.org/downloads/)
|
||||
- [Git](https://git-scm.com/downloads)
|
||||
|
||||
If you encounter issues with an agent, please open an issue so we can refine the integration.
|
||||
|
||||
- **[Complete Spec-Driven Development Methodology](https://github.com/github/spec-kit/blob/main/spec-driven.md)** - Deep dive into the full process
|
||||
- **[Detailed Walkthrough](https://github.com/github/#-detailed-process)** - Step-by-step implementation guide
|
||||
|
||||
---
|
||||
|
||||
Click to expand the detailed step-by-step walkthrough
|
||||
|
||||
You can use the Specify CLI to bootstrap your project, which will bring in the required artifacts in your environment. Run:
|
||||
|
||||
```
|
||||
specify init <project_name>
|
||||
```
|
||||
|
||||
Or initialize in the current directory:
|
||||
|
||||
```
|
||||
specify init .
|
||||
# or use the --here flag
|
||||
specify init --here
|
||||
# Skip confirmation when the directory already has files
|
||||
specify init . --force
|
||||
# or
|
||||
specify init --here --force
|
||||
```
|
||||
|
||||
[](https://github.com/github/spec-kit/blob/main/media/specify_cli.gif)
|
||||
|
||||
You will be prompted to select the AI agent you are using. You can also proactively specify it directly in the terminal:
|
||||
|
||||
```
|
||||
specify init <project_name> --ai claude
|
||||
specify init <project_name> --ai gemini
|
||||
specify init <project_name> --ai copilot
|
||||
|
||||
# Or in current directory:
|
||||
specify init . --ai claude
|
||||
specify init . --ai codex
|
||||
|
||||
# or use --here flag
|
||||
specify init --here --ai claude
|
||||
specify init --here --ai codex
|
||||
|
||||
# Force merge into a non-empty current directory
|
||||
specify init . --force --ai claude
|
||||
|
||||
# or
|
||||
specify init --here --force --ai claude
|
||||
```
|
||||
|
||||
The CLI will check if you have Claude Code, Gemini CLI, Cursor CLI, Qwen CLI, opencode, Codex CLI, Qoder CLI, or Amazon Q Developer CLI installed. If you do not, or you prefer to get the templates without checking for the right tools, use `--ignore-agent-tools` with your command:
|
||||
|
||||
```
|
||||
specify init <project_name> --ai claude --ignore-agent-tools
|
||||
```
|
||||
|
||||
Go to the project folder and run your AI agent. In our example, we're using `claude`.
|
||||
|
||||
[](https://github.com/github/spec-kit/blob/main/media/bootstrap-claude-code.gif)
|
||||
|
||||
You will know that things are configured correctly if you see the `/speckit.constitution`, `/speckit.specify`, `/speckit.plan`, `/speckit.tasks`, and `/speckit.implement` commands available.
|
||||
|
||||
The first step should be establishing your project's governing principles using the `/speckit.constitution` command. This helps ensure consistent decision-making throughout all subsequent development phases:
|
||||
|
||||
```
|
||||
/speckit.constitution Create principles focused on code quality, testing standards, user experience consistency, and performance requirements. Include governance for how these principles should guide technical decisions and implementation choices.
|
||||
```
|
||||
|
||||
This step creates or updates the `.specify/memory/constitution.md` file with your project's foundational guidelines that the AI agent will reference during specification, planning, and implementation phases.
|
||||
|
||||
With your project principles established, you can now create the functional specifications. Use the `/speckit.specify` command and then provide the concrete requirements for the project you want to develop.
|
||||
|
||||
> \[!IMPORTANT\] Be as explicit as possible about *what* you are trying to build and *why*. **Do not focus on the tech stack at this point**.
|
||||
|
||||
An example prompt:
|
||||
|
||||
```
|
||||
Develop Taskify, a team productivity platform. It should allow users to create projects, add team members,
|
||||
assign tasks, comment and move tasks between boards in Kanban style. In this initial phase for this feature,
|
||||
let's call it "Create Taskify," let's have multiple users but the users will be declared ahead of time, predefined.
|
||||
I want five users in two different categories, one product manager and four engineers. Let's create three
|
||||
different sample projects. Let's have the standard Kanban columns for the status of each task, such as "To Do,"
|
||||
"In Progress," "In Review," and "Done." There will be no login for this application as this is just the very
|
||||
first testing thing to ensure that our basic features are set up. For each task in the UI for a task card,
|
||||
you should be able to change the current status of the task between the different columns in the Kanban work board.
|
||||
You should be able to leave an unlimited number of comments for a particular card. You should be able to, from that task
|
||||
card, assign one of the valid users. When you first launch Taskify, it's going to give you a list of the five users to pick
|
||||
from. There will be no password required. When you click on a user, you go into the main view, which displays the list of
|
||||
projects. When you click on a project, you open the Kanban board for that project. You're going to see the columns.
|
||||
You'll be able to drag and drop cards back and forth between different columns. You will see any cards that are
|
||||
assigned to you, the currently logged in user, in a different color from all the other ones, so you can quickly
|
||||
see yours. You can edit any comments that you make, but you can't edit comments that other people made. You can
|
||||
delete any comments that you made, but you can't delete comments anybody else made.
|
||||
```
|
||||
|
||||
After this prompt is entered, you should see Claude Code kick off the planning and spec drafting process. Claude Code will also trigger some of the built-in scripts to set up the repository.
|
||||
|
||||
Once this step is completed, you should have a new branch created (e.g., `001-create-taskify`), as well as a new specification in the `specs/001-create-taskify` directory.
|
||||
|
||||
The produced specification should contain a set of user stories and functional requirements, as defined in the template.
|
||||
|
||||
At this stage, your project folder contents should resemble the following:
|
||||
|
||||
```
|
||||
└── .specify
|
||||
├── memory
|
||||
│ └── constitution.md
|
||||
├── scripts
|
||||
│ ├── check-prerequisites.sh
|
||||
│ ├── common.sh
|
||||
│ ├── create-new-feature.sh
|
||||
│ ├── setup-plan.sh
|
||||
│ └── update-claude-md.sh
|
||||
├── specs
|
||||
│ └── 001-create-taskify
|
||||
│ └── spec.md
|
||||
└── templates
|
||||
├── plan-template.md
|
||||
├── spec-template.md
|
||||
└── tasks-template.md
|
||||
```
|
||||
|
||||
With the baseline specification created, you can go ahead and clarify any of the requirements that were not captured properly within the first shot attempt.
|
||||
|
||||
You should run the structured clarification workflow **before** creating a technical plan to reduce rework downstream.
|
||||
|
||||
Preferred order:
|
||||
|
||||
1. Use `/speckit.clarify` (structured) – sequential, coverage-based questioning that records answers in a Clarifications section.
|
||||
2. Optionally follow up with ad-hoc free-form refinement if something still feels vague.
|
||||
|
||||
If you intentionally want to skip clarification (e.g., spike or exploratory prototype), explicitly state that so the agent doesn't block on missing clarifications.
|
||||
|
||||
Example free-form refinement prompt (after `/speckit.clarify` if still needed):
|
||||
|
||||
```
|
||||
For each sample project or project that you create there should be a variable number of tasks between 5 and 15
|
||||
tasks for each one randomly distributed into different states of completion. Make sure that there's at least
|
||||
one task in each stage of completion.
|
||||
```
|
||||
|
||||
You should also ask Claude Code to validate the **Review & Acceptance Checklist**, checking off the things that are validated/pass the requirements, and leave the ones that are not unchecked. The following prompt can be used:
|
||||
|
||||
```
|
||||
Read the review and acceptance checklist, and check off each item in the checklist if the feature spec meets the criteria. Leave it empty if it does not.
|
||||
```
|
||||
|
||||
It's important to use the interaction with Claude Code as an opportunity to clarify and ask questions around the specification - **do not treat its first attempt as final**.
|
||||
|
||||
You can now be specific about the tech stack and other technical requirements. You can use the `/speckit.plan` command that is built into the project template with a prompt like this:
|
||||
|
||||
```
|
||||
We are going to generate this using .NET Aspire, using Postgres as the database. The frontend should use
|
||||
Blazor server with drag-and-drop task boards, real-time updates. There should be a REST API created with a projects API,
|
||||
tasks API, and a notifications API.
|
||||
```
|
||||
|
||||
The output of this step will include a number of implementation detail documents, with your directory tree resembling this:
|
||||
|
||||
```
|
||||
.
|
||||
├── CLAUDE.md
|
||||
├── memory
|
||||
│ └── constitution.md
|
||||
├── scripts
|
||||
│ ├── check-prerequisites.sh
|
||||
│ ├── common.sh
|
||||
│ ├── create-new-feature.sh
|
||||
│ ├── setup-plan.sh
|
||||
│ └── update-claude-md.sh
|
||||
├── specs
|
||||
│ └── 001-create-taskify
|
||||
│ ├── contracts
|
||||
│ │ ├── api-spec.json
|
||||
│ │ └── signalr-spec.md
|
||||
│ ├── data-model.md
|
||||
│ ├── plan.md
|
||||
│ ├── quickstart.md
|
||||
│ ├── research.md
|
||||
│ └── spec.md
|
||||
└── templates
|
||||
├── CLAUDE-template.md
|
||||
├── plan-template.md
|
||||
├── spec-template.md
|
||||
└── tasks-template.md
|
||||
```
|
||||
|
||||
Check the `research.md` document to ensure that the right tech stack is used, based on your instructions. You can ask Claude Code to refine it if any of the components stand out, or even have it check the locally-installed version of the platform/framework you want to use (e.g.,.NET).
|
||||
|
||||
Additionally, you might want to ask Claude Code to research details about the chosen tech stack if it's something that is rapidly changing (e.g.,.NET Aspire, JS frameworks), with a prompt like this:
|
||||
|
||||
```
|
||||
I want you to go through the implementation plan and implementation details, looking for areas that could
|
||||
benefit from additional research as .NET Aspire is a rapidly changing library. For those areas that you identify that
|
||||
require further research, I want you to update the research document with additional details about the specific
|
||||
versions that we are going to be using in this Taskify application and spawn parallel research tasks to clarify
|
||||
any details using research from the web.
|
||||
```
|
||||
|
||||
During this process, you might find that Claude Code gets stuck researching the wrong thing - you can help nudge it in the right direction with a prompt like this:
|
||||
|
||||
```
|
||||
I think we need to break this down into a series of steps. First, identify a list of tasks
|
||||
that you would need to do during implementation that you're not sure of or would benefit
|
||||
from further research. Write down a list of those tasks. And then for each one of these tasks,
|
||||
I want you to spin up a separate research task so that the net results is we are researching
|
||||
all of those very specific tasks in parallel. What I saw you doing was it looks like you were
|
||||
researching .NET Aspire in general and I don't think that's gonna do much for us in this case.
|
||||
That's way too untargeted research. The research needs to help you solve a specific targeted question.
|
||||
```
|
||||
|
||||
> \[!NOTE\] Claude Code might be over-eager and add components that you did not ask for. Ask it to clarify the rationale and the source of the change.
|
||||
|
||||
With the plan in place, you should have Claude Code run through it to make sure that there are no missing pieces. You can use a prompt like this:
|
||||
|
||||
```
|
||||
Now I want you to go and audit the implementation plan and the implementation detail files.
|
||||
Read through it with an eye on determining whether or not there is a sequence of tasks that you need
|
||||
to be doing that are obvious from reading this. Because I don't know if there's enough here. For example,
|
||||
when I look at the core implementation, it would be useful to reference the appropriate places in the implementation
|
||||
details where it can find the information as it walks through each step in the core implementation or in the refinement.
|
||||
```
|
||||
|
||||
This helps refine the implementation plan and helps you avoid potential blind spots that Claude Code missed in its planning cycle. Once the initial refinement pass is complete, ask Claude Code to go through the checklist once more before you can get to the implementation.
|
||||
|
||||
You can also ask Claude Code (if you have the [GitHub CLI](https://docs.github.com/en/github-cli/github-cli) installed) to go ahead and create a pull request from your current branch to `main` with a detailed description, to make sure that the effort is properly tracked.
|
||||
|
||||
> \[!NOTE\] Before you have the agent implement it, it's also worth prompting Claude Code to cross-check the details to see if there are any over-engineered pieces (remember - it can be over-eager). If over-engineered components or decisions exist, you can ask Claude Code to resolve them. Ensure that Claude Code follows the [constitution](https://github.com/github/spec-kit/blob/main/base/memory/constitution.md) as the foundational piece that it must adhere to when establishing the plan.
|
||||
|
||||
With the implementation plan validated, you can now break down the plan into specific, actionable tasks that can be executed in the correct order. Use the `/speckit.tasks` command to automatically generate a detailed task breakdown from your implementation plan:
|
||||
|
||||
```
|
||||
/speckit.tasks
|
||||
```
|
||||
|
||||
This step creates a `tasks.md` file in your feature specification directory that contains:
|
||||
|
||||
- **Task breakdown organized by user story** - Each user story becomes a separate implementation phase with its own set of tasks
|
||||
- **Dependency management** - Tasks are ordered to respect dependencies between components (e.g., models before services, services before endpoints)
|
||||
- **Parallel execution markers** - Tasks that can run in parallel are marked with `[P]` to optimize development workflow
|
||||
- **File path specifications** - Each task includes the exact file paths where implementation should occur
|
||||
- **Test-driven development structure** - If tests are requested, test tasks are included and ordered to be written before implementation
|
||||
- **Checkpoint validation** - Each user story phase includes checkpoints to validate independent functionality
|
||||
|
||||
The generated tasks.md provides a clear roadmap for the `/speckit.implement` command, ensuring systematic implementation that maintains code quality and allows for incremental delivery of user stories.
|
||||
|
||||
Once ready, use the `/speckit.implement` command to execute your implementation plan:
|
||||
|
||||
```
|
||||
/speckit.implement
|
||||
```
|
||||
|
||||
The `/speckit.implement` command will:
|
||||
|
||||
- Validate that all prerequisites are in place (constitution, spec, plan, and tasks)
|
||||
- Parse the task breakdown from `tasks.md`
|
||||
- Execute tasks in the correct order, respecting dependencies and parallel execution markers
|
||||
- Follow the TDD approach defined in your task plan
|
||||
- Provide progress updates and handle errors appropriately
|
||||
|
||||
> \[!IMPORTANT\] The AI agent will execute local CLI commands (such as `dotnet`, `npm`, etc.) - make sure you have the required tools installed on your machine.
|
||||
|
||||
Once the implementation is complete, test the application and resolve any runtime errors that may not be visible in CLI logs (e.g., browser console errors). You can copy and paste such errors back to your AI agent for resolution.
|
||||
|
||||
---
|
||||
|
||||
## 🔍 Troubleshooting
|
||||
|
||||
If you're having issues with Git authentication on Linux, you can install Git Credential Manager:
|
||||
|
||||
```
|
||||
#!/usr/bin/env bash
|
||||
set -e
|
||||
echo "Downloading Git Credential Manager v2.6.1..."
|
||||
wget https://github.com/git-ecosystem/git-credential-manager/releases/download/v2.6.1/gcm-linux_amd64.2.6.1.deb
|
||||
echo "Installing Git Credential Manager..."
|
||||
sudo dpkg -i gcm-linux_amd64.2.6.1.deb
|
||||
echo "Configuring Git to use GCM..."
|
||||
git config --global credential.helper manager
|
||||
echo "Cleaning up..."
|
||||
rm gcm-linux_amd64.2.6.1.deb
|
||||
```
|
||||
|
||||
## 👥 Maintainers
|
||||
|
||||
- Den Delimarsky ([@localden](https://github.com/localden))
|
||||
- John Lam ([@jflam](https://github.com/jflam))
|
||||
|
||||
## 💬 Support
|
||||
|
||||
For support, please open a [GitHub issue](https://github.com/github/spec-kit/issues/new). We welcome bug reports, feature requests, and questions about using Spec-Driven Development.
|
||||
|
||||
## 🙏 Acknowledgements
|
||||
|
||||
This project is heavily influenced by and based on the work and research of [John Lam](https://github.com/jflam).
|
||||
|
||||
## 📄 License
|
||||
|
||||
This project is licensed under the terms of the MIT open source license. Please refer to the [LICENSE](https://github.com/github/spec-kit/blob/main/LICENSE) file for the full terms.
|
||||
|
||||
## Releases 90
|
||||
|
||||
[\+ 89 releases](https://github.com/github/spec-kit/releases)
|
||||
|
||||
## Deployments 14
|
||||
|
||||
- [github-pages](https://github.com/github/spec-kit/deployments/github-pages)
|
||||
|
||||
[\+ 13 deployments](https://github.com/github/spec-kit/deployments)
|
||||
|
||||
## Languages
|
||||
|
||||
- [Python 37.5%](https://github.com/github/spec-kit/search?l=python)
|
||||
- [Shell 34.9%](https://github.com/github/spec-kit/search?l=shell)
|
||||
- [PowerShell 27.6%](https://github.com/github/spec-kit/search?l=powershell)
|
||||
@@ -1,81 +0,0 @@
|
||||
---
|
||||
title: "kepano/obsidian-skills: Claude Skills for Obsidian"
|
||||
source: "https://github.com/kepano/obsidian-skills"
|
||||
author:
|
||||
- "[[kepano]]"
|
||||
published:
|
||||
created: 2026-01-07
|
||||
description: "Claude Skills for Obsidian. Contribute to kepano/obsidian-skills development by creating an account on GitHub."
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://github.com/kepano/obsidian-skills
|
||||
> Title: kepano/obsidian-skills: Claude Skills for Obsidian
|
||||
> Clipped:
|
||||
|
||||
**[obsidian-skills](https://github.com/kepano/obsidian-skills)** Public
|
||||
|
||||
Claude Skills for Obsidian
|
||||
|
||||
[MIT license](https://github.com/kepano/obsidian-skills/blob/main/LICENSE)
|
||||
|
||||
[Open in github.dev](https://github.dev/) [Open in a new github.dev tab](https://github.dev/) [Open in codespace](https://github.com/codespaces/new/kepano/obsidian-skills?resume=1)
|
||||
|
||||
<table><thead><tr><th colspan="2"><span>Name</span></th><th colspan="1"><span>Name</span></th><th><p><span>Last commit message</span></p></th><th colspan="1"><p><span>Last commit date</span></p></th></tr></thead><tbody><tr><td colspan="3"><p><span><a href="https://github.com/kepano/obsidian-skills/commit/2b9846224fa277993e23c8c8eb35c185571e3551">2b98462</a> ·</span></p><p><a href="https://github.com/kepano/obsidian-skills/commits/main/"><span><span><span>13 Commits</span></span></span></a></p></td></tr><tr><td colspan="2"><p><a href="https://github.com/kepano/obsidian-skills/tree/main/.claude-plugin">.claude-plugin</a></p></td><td colspan="1"><p><a href="https://github.com/kepano/obsidian-skills/tree/main/.claude-plugin">.claude-plugin</a></p></td><td><p><a href="https://github.com/kepano/obsidian-skills/commit/2b9846224fa277993e23c8c8eb35c185571e3551">Update plugin.json</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/kepano/obsidian-skills/tree/main/skills">skills</a></p></td><td colspan="1"><p><a href="https://github.com/kepano/obsidian-skills/tree/main/skills">skills</a></p></td><td><p><a href="https://github.com/kepano/obsidian-skills/commit/9eab9ad2bf8e2839b991bb8ef592a7f65ceee4af">feat: convert to Claude Code plugin structure</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/kepano/obsidian-skills/blob/main/LICENSE">LICENSE</a></p></td><td colspan="1"><p><a href="https://github.com/kepano/obsidian-skills/blob/main/LICENSE">LICENSE</a></p></td><td><p><a href="https://github.com/kepano/obsidian-skills/commit/6aa10512d87abb8c5fdf3b5705029854b893d667">license</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/kepano/obsidian-skills/blob/main/README.md">README.md</a></p></td><td colspan="1"><p><a href="https://github.com/kepano/obsidian-skills/blob/main/README.md">README.md</a></p></td><td><p><a href="https://github.com/kepano/obsidian-skills/commit/6d8941875cd9f58431a2f7d47fbacc94ca87f5ea">Update README.md</a></p></td><td></td></tr><tr><td colspan="3"></td></tr></tbody></table>
|
||||
|
||||
Claude Code skills for creating and editing Obsidian vault files.
|
||||
|
||||
## Skills included
|
||||
|
||||
| Skill | Description | File Types |
|
||||
| --- | --- | --- |
|
||||
| [obsidian-markdown](https://github.com/kepano/obsidian-skills/blob/main/skills/obsidian-markdown) | Obsidian Flavored Markdown with wikilinks, embeds, callouts, and properties | `.md` |
|
||||
| [obsidian-bases](https://github.com/kepano/obsidian-skills/blob/main/skills/obsidian-bases) | Database-like views with filters, formulas, and summaries | `.base` |
|
||||
| [json-canvas](https://github.com/kepano/obsidian-skills/blob/main/skills/json-canvas) | Infinite canvas with nodes, edges, and groups | `.canvas` |
|
||||
|
||||
## Installation
|
||||
|
||||
Install directly from the Obsidian marketplace:
|
||||
|
||||
```
|
||||
claude plugin add obsidian@kepano
|
||||
claude plugin install obsidian@kepano
|
||||
```
|
||||
|
||||
### Manual installation
|
||||
|
||||
Clone or copy this repository into your project's `.claude/plugins/` directory:
|
||||
|
||||
```
|
||||
# Option 1: Clone into plugins directory
|
||||
mkdir -p .claude/plugins
|
||||
git clone https://github.com/obsidianmd/obsidian-skills.git .claude/plugins/obsidian
|
||||
|
||||
# Option 2: Add as git submodule
|
||||
git submodule add https://github.com/obsidianmd/obsidian-skills.git .claude/plugins/obsidian
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
Once installed, Claude Code will automatically use these skills when working with Obsidian files. The skills provide:
|
||||
|
||||
- **Syntax guidance** for Obsidian-specific features (wikilinks, callouts, embeds)
|
||||
- **Schema documentation** for `.base` and `.canvas` file formats
|
||||
- **Best practices** for structuring notes and databases
|
||||
- **Complete function references** for Bases formulas
|
||||
|
||||
## Documentation
|
||||
|
||||
- [Obsidian Flavored Markdown](https://help.obsidian.md/obsidian-flavored-markdown)
|
||||
- [Obsidian Bases](https://help.obsidian.md/bases)
|
||||
- [JSON Canvas Spec](https://jsoncanvas.org/)
|
||||
|
||||
## Releases
|
||||
|
||||
No releases published
|
||||
|
||||
## Packages
|
||||
|
||||
No packages published
|
||||
-533
@@ -1,533 +0,0 @@
|
||||
---
|
||||
title: "tobi/qmd: mini cli search engine for your docs, knowledge bases, meeting notes, whatever. Tracking current sota approaches while being all local"
|
||||
source: "https://github.com/tobi/qmd"
|
||||
author:
|
||||
- "[[Agents]]"
|
||||
- "[[dgilperez]]"
|
||||
published:
|
||||
created: 2026-02-02
|
||||
description: "mini cli search engine for your docs, knowledge bases, meeting notes, whatever. Tracking current sota approaches while being all local - tobi/qmd"
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://github.com/tobi/qmd
|
||||
> Title: tobi/qmd: mini cli search engine for your docs, knowledge bases, meeting notes, whatever. Tracking current sota approaches while being all local
|
||||
> Clipped:
|
||||
|
||||
**[qmd](https://github.com/tobi/qmd)** Public
|
||||
|
||||
mini cli search engine for your docs, knowledge bases, meeting notes, whatever. Tracking current sota approaches while being all local
|
||||
|
||||
[Open in github.dev](https://github.dev/) [Open in a new github.dev tab](https://github.dev/) [Open in codespace](https://github.com/codespaces/new/tobi/qmd?resume=1)
|
||||
|
||||
<table><thead><tr><th colspan="2"><span>Name</span></th><th colspan="1"><span>Name</span></th><th><p><span>Last commit message</span></p></th><th colspan="1"><p><span>Last commit date</span></p></th></tr></thead><tbody><tr><td colspan="3"><p><span><a href="https://github.com/tobi/qmd/commit/47b705409eb1427e574ce82c16e1860b216869ed">fix: BM25 score normalization - use Math.abs instead of Math.max (</a><a href="https://github.com/tobi/qmd/pull/76">#76</a><a href="https://github.com/tobi/qmd/commit/47b705409eb1427e574ce82c16e1860b216869ed">)</a></span></p><p><span><a href="https://github.com/tobi/qmd/commit/47b705409eb1427e574ce82c16e1860b216869ed">47b7054</a> ·</span></p><p><a href="https://github.com/tobi/qmd/commits/main/"><span><span><span>172 Commits</span></span></span></a></p></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/tree/main/finetune">finetune</a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/tree/main/finetune">finetune</a></p></td><td></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/tree/main/skills/qmd"><span>skills/</span> <span>qmd</span></a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/tree/main/skills/qmd"><span>skills/</span> <span>qmd</span></a></p></td><td><p><a href="https://github.com/tobi/qmd/commit/f6a987a642fccd2a3c6585811fdf92b6b61be2e2">Add skills.sh integration for AI agent discovery (</a><a href="https://github.com/tobi/qmd/pull/64">#64</a><a href="https://github.com/tobi/qmd/commit/f6a987a642fccd2a3c6585811fdf92b6b61be2e2">)</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/tree/main/src">src</a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/tree/main/src">src</a></p></td><td><p><a href="https://github.com/tobi/qmd/commit/47b705409eb1427e574ce82c16e1860b216869ed">fix: BM25 score normalization - use Math.abs instead of Math.max (</a><a href="https://github.com/tobi/qmd/pull/76">#76</a><a href="https://github.com/tobi/qmd/commit/47b705409eb1427e574ce82c16e1860b216869ed">)</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/tree/main/test">test</a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/tree/main/test">test</a></p></td><td><p><a href="https://github.com/tobi/qmd/commit/431f6e505ba2fc53f196da03b0580f3f7be59269">Fix qmd embed crash and resolve all TypeScript errors</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/blob/main/.gitattributes">.gitattributes</a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/blob/main/.gitattributes">.gitattributes</a></p></td><td><p><a href="https://github.com/tobi/qmd/commit/99aee7190387483079358cf50b4cd152e607c2c3">Update get and multi-get commands for virtual paths</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/blob/main/.gitignore">.gitignore</a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/blob/main/.gitignore">.gitignore</a></p></td><td><p><a href="https://github.com/tobi/qmd/commit/533f0eed372f03a07d46569ba3fcbca0b1d8cf4e">docs: add finetune CLAUDE.md and update training workflow</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/blob/main/CLAUDE.md">CLAUDE.md</a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/blob/main/CLAUDE.md">CLAUDE.md</a></p></td><td><p><a href="https://github.com/tobi/qmd/commit/17c201ea8173e90962bfb64c4d3758f48cefb224">fix: correct QMD acronym to Query Markup Documents</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/blob/main/README.md">README.md</a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/blob/main/README.md">README.md</a></p></td><td><p><a href="https://github.com/tobi/qmd/commit/17c201ea8173e90962bfb64c4d3758f48cefb224">fix: correct QMD acronym to Query Markup Documents</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/blob/main/bun.lock">bun.lock</a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/blob/main/bun.lock">bun.lock</a></p></td><td><p><a href="https://github.com/tobi/qmd/commit/c85889df12d59a090e21bbe41a02144a7e251191">fixes</a></p></td><td></td></tr><tr><td colspan="2"><p><a href="https://github.com/tobi/qmd/blob/main/example-index.yml">example-index.yml</a></p></td><td colspan="1"><p><a href="https://github.com/tobi/qmd/blob/main/example-index.yml">example-index.yml</a></p></td><td><p><a href="https://github.com/tobi/qmd/commit/c85889df12d59a090e21bbe41a02144a7e251191">fixes</a></p></td><td></td></tr><tr><td colspan="3"></td></tr></tbody></table>
|
||||
|
||||
An on-device search engine for everything you need to remember. Index your markdown notes, meeting transcripts, documentation, and knowledge bases. Search with keywords or natural language. Ideal for your agentic flows.
|
||||
|
||||
QMD combines BM25 full-text search, vector semantic search, and LLM re-ranking—all running locally via node-llama-cpp with GGUF models.
|
||||
|
||||
## Quick Start
|
||||
|
||||
```
|
||||
# Install globally
|
||||
bun install -g https://github.com/tobi/qmd
|
||||
|
||||
# Create collections for your notes, docs, and meeting transcripts
|
||||
qmd collection add ~/notes --name notes
|
||||
qmd collection add ~/Documents/meetings --name meetings
|
||||
qmd collection add ~/work/docs --name docs
|
||||
|
||||
# Add context to help with search results
|
||||
qmd context add qmd://notes "Personal notes and ideas"
|
||||
qmd context add qmd://meetings "Meeting transcripts and notes"
|
||||
qmd context add qmd://docs "Work documentation"
|
||||
|
||||
# Generate embeddings for semantic search
|
||||
qmd embed
|
||||
|
||||
# Search across everything
|
||||
qmd search "project timeline" # Fast keyword search
|
||||
qmd vsearch "how to deploy" # Semantic search
|
||||
qmd query "quarterly planning process" # Hybrid + reranking (best quality)
|
||||
|
||||
# Get a specific document
|
||||
qmd get "meetings/2024-01-15.md"
|
||||
|
||||
# Get a document by docid (shown in search results)
|
||||
qmd get "#abc123"
|
||||
|
||||
# Get multiple documents by glob pattern
|
||||
qmd multi-get "journals/2025-05*.md"
|
||||
|
||||
# Search within a specific collection
|
||||
qmd search "API" -c notes
|
||||
|
||||
# Export all matches for an agent
|
||||
qmd search "API" --all --files --min-score 0.3
|
||||
```
|
||||
|
||||
QMD's `--json` and `--files` output formats are designed for agentic workflows:
|
||||
|
||||
```
|
||||
# Get structured results for an LLM
|
||||
qmd search "authentication" --json -n 10
|
||||
|
||||
# List all relevant files above a threshold
|
||||
qmd query "error handling" --all --files --min-score 0.4
|
||||
|
||||
# Retrieve full document content
|
||||
qmd get "docs/api-reference.md" --full
|
||||
```
|
||||
|
||||
### MCP Server
|
||||
|
||||
Although the tool works perfectly fine when you just tell your agent to use it on the command line, it also exposes an MCP (Model Context Protocol) server for tighter integration.
|
||||
|
||||
**Tools exposed:**
|
||||
|
||||
- `qmd_search` - Fast BM25 keyword search (supports collection filter)
|
||||
- `qmd_vsearch` - Semantic vector search (supports collection filter)
|
||||
- `qmd_query` - Hybrid search with reranking (supports collection filter)
|
||||
- `qmd_get` - Retrieve document by path or docid (with fuzzy matching suggestions)
|
||||
- `qmd_multi_get` - Retrieve multiple documents by glob pattern, list, or docids
|
||||
- `qmd_status` - Index health and collection info
|
||||
|
||||
**Claude Desktop configuration** (`~/Library/Application Support/Claude/claude_desktop_config.json`):
|
||||
|
||||
```
|
||||
{
|
||||
"mcpServers": {
|
||||
"qmd": {
|
||||
"command": "qmd",
|
||||
"args": ["mcp"]
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Claude Code configuration** (`~/.claude/settings.json`):
|
||||
|
||||
```
|
||||
{
|
||||
"mcpServers": {
|
||||
"qmd": {
|
||||
"command": "qmd",
|
||||
"args": ["mcp"]
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Architecture
|
||||
|
||||
```
|
||||
┌─────────────────────────────────────────────────────────────────────────────┐
|
||||
│ QMD Hybrid Search Pipeline │
|
||||
└─────────────────────────────────────────────────────────────────────────────┘
|
||||
|
||||
┌─────────────────┐
|
||||
│ User Query │
|
||||
└────────┬────────┘
|
||||
│
|
||||
┌──────────────┴──────────────┐
|
||||
▼ ▼
|
||||
┌────────────────┐ ┌────────────────┐
|
||||
│ Query Expansion│ │ Original Query│
|
||||
│ (fine-tuned) │ │ (×2 weight) │
|
||||
└───────┬────────┘ └───────┬────────┘
|
||||
│ │
|
||||
│ 2 alternative queries │
|
||||
└──────────────┬──────────────┘
|
||||
│
|
||||
┌───────────────────────┼───────────────────────┐
|
||||
▼ ▼ ▼
|
||||
┌─────────────────┐ ┌─────────────────┐ ┌─────────────────┐
|
||||
│ Original Query │ │ Expanded Query 1│ │ Expanded Query 2│
|
||||
└────────┬────────┘ └────────┬────────┘ └────────┬────────┘
|
||||
│ │ │
|
||||
┌───────┴───────┐ ┌───────┴───────┐ ┌───────┴───────┐
|
||||
▼ ▼ ▼ ▼ ▼ ▼
|
||||
┌───────┐ ┌───────┐ ┌───────┐ ┌───────┐ ┌───────┐ ┌───────┐
|
||||
│ BM25 │ │Vector │ │ BM25 │ │Vector │ │ BM25 │ │Vector │
|
||||
│(FTS5) │ │Search │ │(FTS5) │ │Search │ │(FTS5) │ │Search │
|
||||
└───┬───┘ └───┬───┘ └───┬───┘ └───┬───┘ └───┬───┘ └───┬───┘
|
||||
│ │ │ │ │ │
|
||||
└───────┬───────┘ └──────┬──────┘ └──────┬──────┘
|
||||
│ │ │
|
||||
└────────────────────────┼───────────────────────┘
|
||||
│
|
||||
▼
|
||||
┌───────────────────────┐
|
||||
│ RRF Fusion + Bonus │
|
||||
│ Original query: ×2 │
|
||||
│ Top-rank bonus: +0.05│
|
||||
│ Top 30 Kept │
|
||||
└───────────┬───────────┘
|
||||
│
|
||||
▼
|
||||
┌───────────────────────┐
|
||||
│ LLM Re-ranking │
|
||||
│ (qwen3-reranker) │
|
||||
│ Yes/No + logprobs │
|
||||
└───────────┬───────────┘
|
||||
│
|
||||
▼
|
||||
┌───────────────────────┐
|
||||
│ Position-Aware Blend │
|
||||
│ Top 1-3: 75% RRF │
|
||||
│ Top 4-10: 60% RRF │
|
||||
│ Top 11+: 40% RRF │
|
||||
└───────────────────────┘
|
||||
```
|
||||
|
||||
### Search Backends
|
||||
|
||||
| Backend | Raw Score | Conversion | Range |
|
||||
| --- | --- | --- | --- |
|
||||
| **FTS (BM25)** | SQLite FTS5 BM25 | `Math.abs(score)` | 0 to ~25+ |
|
||||
| **Vector** | Cosine distance | `1 / (1 + distance)` | 0.0 to 1.0 |
|
||||
| **Reranker** | LLM 0-10 rating | `score / 10` | 0.0 to 1.0 |
|
||||
|
||||
### Fusion Strategy
|
||||
|
||||
The `query` command uses **Reciprocal Rank Fusion (RRF)** with position-aware blending:
|
||||
|
||||
1. **Query Expansion**: Original query (×2 for weighting) + 1 LLM variation
|
||||
2. **Parallel Retrieval**: Each query searches both FTS and vector indexes
|
||||
3. **RRF Fusion**: Combine all result lists using `score = Σ(1/(k+rank+1))` where k=60
|
||||
4. **Top-Rank Bonus**: Documents ranking #1 in any list get +0.05, #2-3 get +0.02
|
||||
5. **Top-K Selection**: Take top 30 candidates for reranking
|
||||
6. **Re-ranking**: LLM scores each document (yes/no with logprobs confidence)
|
||||
7. **Position-Aware Blending**:
|
||||
- RRF rank 1-3: 75% retrieval, 25% reranker (preserves exact matches)
|
||||
- RRF rank 4-10: 60% retrieval, 40% reranker
|
||||
- RRF rank 11+: 40% retrieval, 60% reranker (trust reranker more)
|
||||
|
||||
**Why this approach**: Pure RRF can dilute exact matches when expanded queries don't match. The top-rank bonus preserves documents that score #1 for the original query. Position-aware blending prevents the reranker from destroying high-confidence retrieval results.
|
||||
|
||||
### Score Interpretation
|
||||
|
||||
| Score | Meaning |
|
||||
| --- | --- |
|
||||
| 0.8 - 1.0 | Highly relevant |
|
||||
| 0.5 - 0.8 | Moderately relevant |
|
||||
| 0.2 - 0.5 | Somewhat relevant |
|
||||
| 0.0 - 0.2 | Low relevance |
|
||||
|
||||
## Requirements
|
||||
|
||||
### System Requirements
|
||||
|
||||
- **Bun** >= 1.0.0
|
||||
- **macOS**: Homebrew SQLite (for extension support)
|
||||
```
|
||||
brew install sqlite
|
||||
```
|
||||
|
||||
QMD uses three local GGUF models (auto-downloaded on first use):
|
||||
|
||||
| Model | Purpose | Size |
|
||||
| --- | --- | --- |
|
||||
| `embeddinggemma-300M-Q8_0` | Vector embeddings | ~300MB |
|
||||
| `qwen3-reranker-0.6b-q8_0` | Re-ranking | ~640MB |
|
||||
| `qmd-query-expansion-1.7B-q4_k_m` | Query expansion (fine-tuned) | ~1.1GB |
|
||||
|
||||
Models are downloaded from HuggingFace and cached in `~/.cache/qmd/models/`.
|
||||
|
||||
## Installation
|
||||
|
||||
```
|
||||
bun install -g github:tobi/qmd
|
||||
```
|
||||
|
||||
Make sure `~/.bun/bin` is in your PATH.
|
||||
|
||||
### Development
|
||||
|
||||
```
|
||||
git clone https://github.com/tobi/qmd
|
||||
cd qmd
|
||||
bun install
|
||||
bun link
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Collection Management
|
||||
|
||||
```
|
||||
# Create a collection from current directory
|
||||
qmd collection add . --name myproject
|
||||
|
||||
# Create a collection with explicit path and custom glob mask
|
||||
qmd collection add ~/Documents/notes --name notes --mask "**/*.md"
|
||||
|
||||
# List all collections
|
||||
qmd collection list
|
||||
|
||||
# Remove a collection
|
||||
qmd collection remove myproject
|
||||
|
||||
# Rename a collection
|
||||
qmd collection rename myproject my-project
|
||||
|
||||
# List files in a collection
|
||||
qmd ls notes
|
||||
qmd ls notes/subfolder
|
||||
```
|
||||
```
|
||||
# Embed all indexed documents (800 tokens/chunk, 15% overlap)
|
||||
qmd embed
|
||||
|
||||
# Force re-embed everything
|
||||
qmd embed -f
|
||||
```
|
||||
|
||||
### Context Management
|
||||
|
||||
Context adds descriptive metadata to collections and paths, helping search understand your content.
|
||||
|
||||
### Search Commands
|
||||
|
||||
```
|
||||
┌──────────────────────────────────────────────────────────────────┐
|
||||
│ Search Modes │
|
||||
├──────────┬───────────────────────────────────────────────────────┤
|
||||
│ search │ BM25 full-text search only │
|
||||
│ vsearch │ Vector semantic search only │
|
||||
│ query │ Hybrid: FTS + Vector + Query Expansion + Re-ranking │
|
||||
└──────────┴───────────────────────────────────────────────────────┘
|
||||
```
|
||||
|
||||
### Options
|
||||
|
||||
```
|
||||
# Search options
|
||||
-n <num> # Number of results (default: 5, or 20 for --files/--json)
|
||||
-c, --collection # Restrict search to a specific collection
|
||||
--all # Return all matches (use with --min-score to filter)
|
||||
--min-score <num> # Minimum score threshold (default: 0)
|
||||
--full # Show full document content
|
||||
--line-numbers # Add line numbers to output
|
||||
--index <name> # Use named index
|
||||
|
||||
# Output formats (for search and multi-get)
|
||||
--files # Output: docid,score,filepath,context
|
||||
--json # JSON output with snippets
|
||||
--csv # CSV output
|
||||
--md # Markdown output
|
||||
--xml # XML output
|
||||
|
||||
# Get options
|
||||
qmd get <file>[:line] # Get document, optionally starting at line
|
||||
-l <num> # Maximum lines to return
|
||||
--from <num> # Start from line number
|
||||
|
||||
# Multi-get options
|
||||
-l <num> # Maximum lines per file
|
||||
--max-bytes <num> # Skip files larger than N bytes (default: 10KB)
|
||||
```
|
||||
|
||||
### Output Format
|
||||
|
||||
Default output is colorized CLI format (respects `NO_COLOR` env):
|
||||
|
||||
```
|
||||
docs/guide.md:42 #a1b2c3
|
||||
Title: Software Craftsmanship
|
||||
Context: Work documentation
|
||||
Score: 93%
|
||||
|
||||
This section covers the **craftsmanship** of building
|
||||
quality software with attention to detail.
|
||||
See also: engineering principles
|
||||
|
||||
notes/meeting.md:15 #d4e5f6
|
||||
Title: Q4 Planning
|
||||
Context: Personal notes and ideas
|
||||
Score: 67%
|
||||
|
||||
Discussion about code quality and craftsmanship
|
||||
in the development process.
|
||||
```
|
||||
|
||||
- **Path**: Collection-relative path (e.g., `docs/guide.md`)
|
||||
- **Docid**: Short hash identifier (e.g., `#a1b2c3`) - use with `qmd get #a1b2c3`
|
||||
- **Title**: Extracted from document (first heading or filename)
|
||||
- **Context**: Path context if configured via `qmd context add`
|
||||
- **Score**: Color-coded (green >70%, yellow >40%, dim otherwise)
|
||||
- **Snippet**: Context around match with query terms highlighted
|
||||
|
||||
### Examples
|
||||
|
||||
```
|
||||
# Get 10 results with minimum score 0.3
|
||||
qmd query -n 10 --min-score 0.3 "API design patterns"
|
||||
|
||||
# Output as markdown for LLM context
|
||||
qmd search --md --full "error handling"
|
||||
|
||||
# JSON output for scripting
|
||||
qmd query --json "quarterly reports"
|
||||
|
||||
# Use separate index for different knowledge base
|
||||
qmd --index work search "quarterly reports"
|
||||
```
|
||||
|
||||
### Index Maintenance
|
||||
|
||||
```
|
||||
# Show index status and collections with contexts
|
||||
qmd status
|
||||
|
||||
# Re-index all collections
|
||||
qmd update
|
||||
|
||||
# Re-index with git pull first (for remote repos)
|
||||
qmd update --pull
|
||||
|
||||
# Get document by filepath (with fuzzy matching suggestions)
|
||||
qmd get notes/meeting.md
|
||||
|
||||
# Get document by docid (from search results)
|
||||
qmd get "#abc123"
|
||||
|
||||
# Get document starting at line 50, max 100 lines
|
||||
qmd get notes/meeting.md:50 -l 100
|
||||
|
||||
# Get multiple documents by glob pattern
|
||||
qmd multi-get "journals/2025-05*.md"
|
||||
|
||||
# Get multiple documents by comma-separated list (supports docids)
|
||||
qmd multi-get "doc1.md, doc2.md, #abc123"
|
||||
|
||||
# Limit multi-get to files under 20KB
|
||||
qmd multi-get "docs/*.md" --max-bytes 20480
|
||||
|
||||
# Output multi-get as JSON for agent processing
|
||||
qmd multi-get "docs/*.md" --json
|
||||
|
||||
# Clean up cache and orphaned data
|
||||
qmd cleanup
|
||||
```
|
||||
|
||||
## Data Storage
|
||||
|
||||
Index stored in: `~/.cache/qmd/index.sqlite`
|
||||
|
||||
### Schema
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Default | Description |
|
||||
| --- | --- | --- |
|
||||
| `XDG_CACHE_HOME` | `~/.cache` | Cache directory location |
|
||||
|
||||
### Indexing Flow
|
||||
|
||||
```
|
||||
Collection ──► Glob Pattern ──► Markdown Files ──► Parse Title ──► Hash Content
|
||||
│ │ │
|
||||
│ │ ▼
|
||||
│ │ Generate docid
|
||||
│ │ (6-char hash)
|
||||
│ │ │
|
||||
└──────────────────────────────────────────────────►└──► Store in SQLite
|
||||
│
|
||||
▼
|
||||
FTS5 Index
|
||||
```
|
||||
|
||||
### Embedding Flow
|
||||
|
||||
Documents are chunked into 800-token pieces with 15% overlap:
|
||||
|
||||
```
|
||||
Document ──► Chunk (800 tokens) ──► Format each chunk ──► node-llama-cpp ──► Store Vectors
|
||||
│ "title | text" embedBatch()
|
||||
│
|
||||
└─► Chunks stored with:
|
||||
- hash: document hash
|
||||
- seq: chunk sequence (0, 1, 2...)
|
||||
- pos: character position in original
|
||||
```
|
||||
|
||||
```
|
||||
Query ──► LLM Expansion ──► [Original, Variant 1, Variant 2]
|
||||
│
|
||||
┌─────────┴─────────┐
|
||||
▼ ▼
|
||||
For each query: FTS (BM25)
|
||||
│ │
|
||||
▼ ▼
|
||||
Vector Search Ranked List
|
||||
│
|
||||
▼
|
||||
Ranked List
|
||||
│
|
||||
└─────────┬─────────┘
|
||||
▼
|
||||
RRF Fusion (k=60)
|
||||
Original query ×2 weight
|
||||
Top-rank bonus: +0.05/#1, +0.02/#2-3
|
||||
│
|
||||
▼
|
||||
Top 30 candidates
|
||||
│
|
||||
▼
|
||||
LLM Re-ranking
|
||||
(yes/no + logprob confidence)
|
||||
│
|
||||
▼
|
||||
Position-Aware Blend
|
||||
Rank 1-3: 75% RRF / 25% reranker
|
||||
Rank 4-10: 60% RRF / 40% reranker
|
||||
Rank 11+: 40% RRF / 60% reranker
|
||||
│
|
||||
▼
|
||||
Final Results
|
||||
```
|
||||
|
||||
## Model Configuration
|
||||
|
||||
Models are configured in `src/llm.ts` as HuggingFace URIs:
|
||||
|
||||
```
|
||||
const DEFAULT_EMBED_MODEL = "hf:ggml-org/embeddinggemma-300M-GGUF/embeddinggemma-300M-Q8_0.gguf";
|
||||
const DEFAULT_RERANK_MODEL = "hf:ggml-org/Qwen3-Reranker-0.6B-Q8_0-GGUF/qwen3-reranker-0.6b-q8_0.gguf";
|
||||
const DEFAULT_GENERATE_MODEL = "hf:tobil/qmd-query-expansion-1.7B-gguf/qmd-query-expansion-1.7B-q4_k_m.gguf";
|
||||
```
|
||||
|
||||
```
|
||||
// For queries
|
||||
"task: search result | query: {query}"
|
||||
|
||||
// For documents
|
||||
"title: {title} | text: {content}"
|
||||
```
|
||||
|
||||
### Qwen3-Reranker
|
||||
|
||||
Uses node-llama-cpp's `createRankingContext()` and `rankAndSort()` API for cross-encoder reranking. Returns documents sorted by relevance score (0.0 - 1.0).
|
||||
|
||||
Used for generating query variations via `LlamaChatSession`.
|
||||
|
||||
## License
|
||||
|
||||
MIT
|
||||
|
||||
## Releases
|
||||
|
||||
No releases published
|
||||
|
||||
## Packages
|
||||
|
||||
No packages published
|
||||
|
||||
## Languages
|
||||
|
||||
- [TypeScript 65.8%](https://github.com/tobi/qmd/search?l=typescript)
|
||||
- [Python 33.5%](https://github.com/tobi/qmd/search?l=python)
|
||||
- Other 0.7%
|
||||
-46
@@ -1,46 +0,0 @@
|
||||
---
|
||||
title: "Astrobotic Breaks Records for Hot Firing Rotating Detonation Rocket Engine (RDRE)"
|
||||
source: "https://www.youtube.com/watch?v=DjnC8KvakKk"
|
||||
author:
|
||||
- "[[Astrobotic]]"
|
||||
published: 2026-04-23
|
||||
created: 2026-04-26
|
||||
description: "Astrobotic today announced the successful hot fire test of its Chakram rotating detonation rocket engine (RDRE) at NASA’s Marshall Space Flight Center in Huntsville, Alabama. Two Chakram engine protot"
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://www.youtube.com/watch?v=DjnC8KvakKk
|
||||
> Title: Astrobotic Breaks Records for Hot Firing Rotating Detonation Rocket Engine (RDRE)
|
||||
> Clipped:
|
||||
|
||||

|
||||
|
||||
Astrobotic today announced the successful hot fire test of its Chakram rotating detonation rocket engine (RDRE) at NASA’s Marshall Space Flight Center in Huntsville, Alabama. Two Chakram engine prototypes completed eight successful hot-fire tests, accumulating more than 470 seconds of total run time without any discernible damage to the engine hardware. The campaign included a 300-second continuous burn, which is now believed to have set the record for longest duration hot firing of an RDRE engine to date. During testing, each engine produced more than 4,000 pounds of thrust, making Chakram one of the most powerful RDREs ever demonstrated.
|
||||
|
||||
## Transcript
|
||||
|
||||
**0:01** · Astrobotic just successfully hotfired a 4,000lb rotating detonation engine. That puts it squarely in the category of one of the largest rotating detonation engines ever fired. That's not just within small businesses. That's not just in the United States. That's in human history. This is one of the most powerful embodiment of this technology that has ever been created and demonstrated. On each of these tests, we generate over 4,000 lbs of thrust. Uh we achieve steadystate combustion in all of our longduration tests and all of our initial signs are extremely positive.
|
||||
|
||||
**0:34** · We've got a lot of math to do. We've got a lot of analysis to do, but everything we've seen so far indicates that this engine performed as well as we possibly could have hoped for. One of the things that differentiates what we're doing is uh a lot of the rotating detonation engine demonstrations that have been done to date have all been at relatively small scale. So in a lot of cases we're talking a couple hundred pounds of force. Some of them have been, you know, have been incrementally creeping upwards. But to really enable some of these next generation systems, we have to go bigger. And that's exactly what we did.
|
||||
|
||||
**1:03** · Considering what we did this with, this is a small team working across multiple offices on a very modest budget. We think that, you know, not only is this engine efficient, our team is really efficient. And they put in so many hours. Uh so to see this pay off the way it did and to achieve such a historic milestone on our first try uh that was just incredible.
|
||||
|
||||
**1:26** · This is uh a model uh of our Chakram RDRE. This is actually exactly lifelike.
|
||||
|
||||
**1:32** · This is very representative of what we actually fired. So we fired two thrust chambers. It doesn't look like a conventional rocket engine. There's no giant bell on it. It's it's quite small.
|
||||
|
||||
**1:42** · You've got an aerospike nozzle coming out the back here. And all of these are designed to propagate these detonation waves. And so what you get to make these RDREs work is you have these supersonic detonation waves that travel in circles around the outer part of this rocket engine. And in fact, we didn't have just one of these supersonic waves. We had three detonation waves chasing each other around the outside of this. And that's what allows for this very efficient, very rapid combustion to enable these these high thrust applications.
|
||||
|
||||
**2:10** · There's a number of different opportunities uh for infusion of Chakram into some of our existing systems and as we look ahead that's where this gets really exciting is having a rocket engine is one thing.
|
||||
|
||||
**2:22** · What you do with that rocket engine is really what matters. We're excited about developing this technology but we're not developing it just for the sake of of science projects and advancing the state-of-the-art. We're looking at ways to introduce this into our existing product lines. Whether that's our next generation Zogdor vertical takeoff and landing reusable rocket which will be able to get uh affordable space access uh and rapid reuse. So takeoff and land.
|
||||
|
||||
**2:45** · But by introducing this into a future Zogdor variant, we think we can get much higher performance and potentially take more payload up higher or faster. Uh it allows us to just do more because we have more uh more efficient combustion.
|
||||
|
||||
**2:59** · I think most people who are familiar with Astrobotic know about our lunar lander line and we're certainly interested in looking at ways to introduce this to our lander architecture. There's a number of different opportunities potentially for that, but uh that's certainly something we're exploring.
|
||||
|
||||
**3:15** · What What do I have next to me? Um Kitty, this is like this is amazing.
|
||||
|
||||
**3:22** · Okay.
|
||||
@@ -1,208 +0,0 @@
|
||||
---
|
||||
title: "This New Method Just Killed RAM Limitations"
|
||||
source: "https://www.youtube.com/watch?v=erV_8yrGMA8"
|
||||
author:
|
||||
- "[[AI News & Strategy Daily | Nate B Jones]]"
|
||||
published: 2026-04-11
|
||||
created: 2026-04-17
|
||||
description: "Full Story w/ Prompts: https://natesnewsletter.substack.com/p/your-gpus-just-got-6x-more-valuable?r=1z4sm5&utm_campaign=post&utm_medium=web&showWelcomeOnShare=true___________________What's really ha"
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://www.youtube.com/watch?v=erV_8yrGMA8
|
||||
> Title: This New Method Just Killed RAM Limitations
|
||||
> Clipped:
|
||||
|
||||

|
||||
|
||||
Full Story w/ Prompts: https://natesnewsletter.substack.com/p/your-gpus-just-got-6x-more-valuable?r=1z4sm5&utm\_campaign=post&utm\_medium=web&showWelcomeOnShare=true
|
||||
\_\_\_\_\_\_\_\_\_\_\_\_\_\_\_\_\_\_\_
|
||||
What's really happening inside AI memory — and why it's the bottleneck threatening every LLM deployment at scale?
|
||||
|
||||
The common story is that we just need more chips — but the reality is more interesting: a new Google paper may have just changed the math without touching the hardware.
|
||||
|
||||
In this video, I share the inside scoop on TurboQuant, Google's lossless KV cache compression breakthrough:
|
||||
|
||||
• Why the AI memory crisis is structural, not temporary
|
||||
• How TurboQuant achieves 6x compression with zero data loss
|
||||
• What lossless KV cache optimization means for LLM architecture
|
||||
• Where Google, NVIDIA, and enterprises each stand to win or lose
|
||||
|
||||
The operators and builders who start treating memory as a years-long constraint — and take control of their own context layers now — will hold a real structural advantage as this rolls toward production.
|
||||
|
||||
Chapters
|
||||
00:00 Introduction: TurboQuant and the Memory Problem
|
||||
01:15 The AI Memory Crisis, Explained
|
||||
03:00 Why Memory Supply Is Structurally Constrained
|
||||
05:00 Demand Explosion: Agents and Token Consumption
|
||||
06:30 How Traditional Compression Fails
|
||||
08:00 TurboQuant Part One: PolarQuant Rotation
|
||||
09:30 TurboQuant Part Two: QJL Error Correction
|
||||
11:00 Test Results Across Real LLM Tasks
|
||||
12:30 Why TurboQuant Isn't in Production Yet 14:00 What Is the KV Cache?
|
||||
15:30 Percepta: Embedding Compute Inside an LLM
|
||||
17:00 Strategic Implications: Google, NVIDIA, Enterprises
|
||||
18:30 Five Angles Attacking the Memory Problem
|
||||
20:00 Sovereign Memory: Your Takeaway
|
||||
|
||||
Subscribe for daily AI strategy and news. For deeper playbooks and analysis: https://natesnewsletter.substack.com/
|
||||
|
||||
Listen to this video as a podcast.
|
||||
\- Spotify: https://open.spotify.com/show/0gkFdjd1wptEKJKLu9LbZ4
|
||||
\- Apple Podcasts: https://podcasts.apple.com/us/podcast/ai-news-strategy-daily-with-nate-b-jones/id1877109372
|
||||
|
||||
## Transcript
|
||||
|
||||
### Introduction: TurboQuant and the Memory Problem
|
||||
|
||||
**0:00** · Google just published one of the most important breakthroughs of the year.
|
||||
|
||||
**0:03** · It's called TurboQuant. And it has everything to do with how we use memory in LLMs. Not just in agents, not just in applications, but like the core LLM architecture becoming more memory efficient. And that is a huge deal because right now one of the biggest crises in the industry is the fact that intelligence and demand for intelligence are scaling way way faster than memory.
|
||||
|
||||
**0:24** · And if you're hearing this and you're thinking TurboQuant, this sounds like Silicon Valley the television show.
|
||||
|
||||
**0:30** · You're absolutely right. In fact, that's what most of the newspapers said. They said Turboquant is the new Pied Piper.
|
||||
|
||||
**0:34** · They were kidding around because in the television show Silicon Valley, the little startup Pied Piper actually makes a compression algorithm that saves a ton of hard disk space and memory and that's how they're valued and that's like their whole startup thesis. In this case, I would argue it's even more valuable because TurboQuant compresses the way LLMs handle processing of text in a way that is lossless. And that's a big big deal. So, Pi Piper compressed video files and Turbo Quant compresses the memory that LLM use to think called the key value cache or the KV cache.
|
||||
|
||||
**1:07** · It's the thing that determines how much an AI can hold in its head at a time. And what TurboQuant showed is that they can do a six times memory reduction in the KV cache and up to an 8x speed up on chip without losing even one bit of data.
|
||||
|
||||
### The AI Memory Crisis, Explained
|
||||
|
||||
**1:25** · That's the the biggest news in the world, right? Like that is a huge deal from an AI perspective because it means that the structural economics of the memory crisis that we've been walking into for the last couple of years may actually be addressable. Now, just to give you the 30 secondond view of the memory crisis, supply is structurally constrained. HBM, high bandwidth memory, is getting harder and harder and harder to make. Partly that's because there's so much demand for it.
|
||||
|
||||
**1:49** · And partly because it's literally harder to make because the conflict in Iran means that there's less helium and more expensive power prices, both of which impact the ability to make memory. And so, for multiple reasons, memory is very hard to make right now. On top of that, demand is exploding because agents happened.
|
||||
|
||||
**2:06** · And that means that the average conversation length or the average token usage for a particular interaction went from how long it takes you to have a chat to a thousandx that because agents can burn so many tokens. It's not unusual for agents to burn 100 million tokens, even a billion tokens. Now that means there's more and more demand for exactly the working memory that this Google paper addresses. And just to underline how big a deal this is, token consumption is already reaching 25 billion tokens a year for enterprises with AI native workers. That's that's a year per engineer just to be clear, not for the enterprise as a whole.
|
||||
|
||||
**2:38** · And also memory prices are soaring. Memory prices are multiple hundreds of percent up which is increasing the bill of materials and costs for everything that we use for computing including our personal computers. And the squeeze is relentless. Like we are looking at a situation where for the next half decade this is going to be difficult because bringing more fabrication units online is not easy. So that's the problem space. That's why everyone's stressed about memory. In the middle of this turbo quant looks like a possible way out. Now, I grant you it's a working paper. It's not yet in production systems.
|
||||
|
||||
### Why Memory Supply Is Structurally Constrained
|
||||
|
||||
**3:07** · I don't want to overpromise, but it's worth understanding how it works because it starts to paint a picture for how we can use memory more efficiently. And that's a big deal.
|
||||
|
||||
**3:17** · Look, traditional methods for compressing AI memory are really, really problematic. I want to go through a couple and then explain without math why Turbo Quant is so much better. So if you wanted to compress AI memory before Turbo Quant came out, something that you could do would be called vector quantization, which is a fancy way of saying that you can compress data, but then you need to add data to make sure the data is easily retrievable. So you add something called quantization constants, which sort of somewhat defeats the purpose of the compression because you're adding more data back in after you press it.
|
||||
|
||||
**3:47** · And that overhead actually literally adds one to two extra bits per number that you compress. And it sort of defeats some of the purpose of the compression. It's like packing a suitcase by folding everything tightly, but you have to carry a separate bag with the folding instructions, right?
|
||||
|
||||
**4:01** · That would be sort of silly, but that's a little bit like what vector quantization does. Turboqu Quant makes things easier. So, TurboQuant eliminates that overhead, the packing instruction, so to speak, in a couple of stages.
|
||||
|
||||
**4:12** · First, Polar Quant rotates the data into a standard coordinate system. So what I mean by that is that the data structure becomes predictable enough that you don't need special normalization to read it per block going through the LLM transformer head. So think of it as converting go three blocks east and four blocks north into go five blocks at a 37 degree angle. Both of those are technically the same thing, but one is a shorter way to say it. And so the radius captures the signal strength and the angles capture the meaning.
|
||||
|
||||
**4:44** · And it's a a more efficient way to pack up that data.
|
||||
|
||||
**4:48** · in this analogy because the angles capture all of that data. You don't need to carry the extra bag of folding instructions and it's just a clean, lossless, more efficient way to carry data. But we're not done there because the second technique is what makes this really brilliant. Even if you compress it and you make sure that you like carefully represent all of the original data in a slightly smaller form, it's still possible for tiny errors to creep in.
|
||||
|
||||
### Demand Explosion: Agents and Token Consumption
|
||||
|
||||
**5:10** · And if you're an LLM and you want to be not tolerant of tiny errors, then that's unacceptable because you actually have to do long running steps over many many layers of context and it's really really important to get it exactly right. Let's say in our example that three blocks east and four blocks north translated to 37°. It's actually 36 and a half. It's not 37, but it's close enough for most purposes. Well, Google went farther. Google didn't just say this is close enough for most purposes.
|
||||
|
||||
**5:36** · It's almost perfect. They also added a second technique called QJL or if you want to have a tongue twister, quantized Johnson Linden Strauss. Say that five times fast. That's basically a fancy name for a process that takes the tiny residual error that 36 12 versus 35 degrees or whatever it is. And it corrects it and it corrects it efficiently using just a single bit, a mathematical error checker that eliminates the bias and attention scores. And the combination leads to net net zero overhead and a perfect compression.
|
||||
|
||||
**6:10** · And so the result is eye opening. So where you have a KV cache that might have 16 or 30 bits in it for a key value, you can compress that up to 10x from 32 down to three bits of value without any loss. And that was tested across a variety of fields that we care about for LLM. So if you're wondering, is this just theoretical? I mean, yes, it's a paper, but it was tested. So it was tested across question answering, it was tested across code generation, it was tested across summarization, and it was tested critically across needle in a haststack retrieval.
|
||||
|
||||
### How Traditional Compression Fails
|
||||
|
||||
**6:40** · So if you have a big piece of context and you do this compression on it, can the LLM still find a specific tiny word or phrase in that gigantic context? And so they ran and threw a 100,000 traditional tokens at this compression system and TurboQuant compressed it. And then they said, "Okay, now can you find this tiny little phrase that we've put into this 100,000 tokens?" And it could. And the beautiful thing about this is that it's what we call a data oblivious algorithm.
|
||||
|
||||
**7:10** · So it's not specific to a specific data set. It's not specific to a specific large language model. It's actually a mathematical property we're working with here, which makes it more easy to translate. Now, if you're wondering, okay, this sounds great. Why don't we all have it? The answer is that rolling something to production takes time, and it's important to understand how it actually works. I'm going to give you an example of that. Here's why this matters and why we need to think beyond the spec sheet to make sure we get this right.
|
||||
|
||||
**7:33** · When you compress the KV cache by 6x or 8x or 10x, however big the number ends up being in production, you don't just save memory, you change the way concurrency math works on a chip. In other words, you change the number of simultaneous users that a single GPU can serve. And this is the number that determines whether the inference workloads that you're running end up being profitable for you with your GPU investment or not.
|
||||
|
||||
**7:55** · But one of the things that's interesting is if the concurrency number gets high, you may have to change the way your enterprise deployments work, the way your firmware works on top of the chips to enable more concurrency on a single chip because chips typically have concurrency limits that they may have put in place before.
|
||||
|
||||
### TurboQuant Part One: PolarQuant Rotation
|
||||
|
||||
**8:16** · In fact, certainly put in place. chips have concurrency limits typically that have been put in place long before Turbo Quant came out and that you may have to think about how you address when you want to take advantage of this. And so one of the things I want to call out is that whenever you try and production scale something, you have to think about the whole stack. And especially if you're thinking about something as near to the metal as memory use in a KV cache, you have to think about all of the implications for the stack before you can roll it out.
|
||||
|
||||
**8:44** · And that's why as much fun as this is, there's still work to be done before this is fully available for production. And so you might say, Nate, well, why are we talking about this? It's just theory.
|
||||
|
||||
**8:54** · Well, the answer is even if it's theory today, this is still the fastest possible path for us to solve this problem. And the reason why is that it can move at the speed of software. It doesn't necessarily have to move at the speed of hardware. Because if you're trying to fix these fab timelines, I talked about the issues with making HBM.
|
||||
|
||||
**9:11** · It's a half a decade timeline, right? If you're trying to address how demand works in the system, I'm sorry, but demand is just exploding for AI and that's not going anywhere. So that's an immovable force that's getting bigger and bigger all the time. In that world, software is sort of our only way through the memory problem. Now, if you're wondering what is a KV cache, I'm going to explain it really simply. KV cache is the memory for the language model. So it's the model's working memory while it does computation across a prompt. So every token the model has ever seen gets stored as a key value pair or in the KV cache.
|
||||
|
||||
### TurboQuant Part Two: QJL Error Correction
|
||||
|
||||
**9:43** · And the model computes over all of those pairs for every token generated. And so the KV cache is what lets a model connect token number 89,031 to token number 2354 in your giant prompt. It's what allows the model to hold a conversation, to follow an argument, to track a codebase. It's super super important. And so if model weights are effectively the processor that allows you to do the computing, the KV cache is like a hard drive. It's like RAM. It allows you to remember things.
|
||||
|
||||
**10:12** · And so if you were to invent a piece of software that effectively an algorithm that effectively compresses and makes the hard drive you already have potentially six, seven, eight times more efficient. That's a really really big deal. And I think that one of the things I want to call out is that this TurboQuant paper is happening in the context of a larger set of innovations that are around the core architecture of LLMs that we should be paying attention to. I'll give you one more example. This is from a company called Percepa, which is figuring out how to embed a computer inside a large language model.
|
||||
|
||||
**10:46** · Now, one of the things I want to call out for people who are like, "But an LLM is a computer." The answer is actually no.
|
||||
|
||||
**10:52** · It's not a computer. The LLM is a neural network architecture and it's inherently probabilistic. And so it does not compute in the classical sense normally.
|
||||
|
||||
### Test Results Across Real LLM Tasks
|
||||
|
||||
**11:03** · And so when you see great results where like the LLM does math these days, what you're really seeing is the LM calling a tool and using a tool like Python to do the math. And that's how that works. But that may not be how that works in the future. So what they figured out is they could get the model to deterministically solve a Sudoku puzzle by actually computing the answer logically step by step with 100% accuracy over a lengthy number of steps. We're talking a million plus steps at 33,000 tokens a second which is very very fast.
|
||||
|
||||
**11:34** · If you want to get into the details, what they did is they compiled a web assembly interpreter directly into the weight matrix of a standard PyTorch transform. Not as an external tool call, not as a code interpreter sandbox that was running alongside the model that it could use, but actually they compiled the computer inside the weights of the model. And so the model can execute C programs through a forward pass step by step and emits a stack trace as tokens. For the nerds out there, that's how they did it. And the implications of having a computer in your LLM are really interesting.
|
||||
|
||||
**12:05** · Not because again all of our LLMs will immediately have this, the production piece comes out here too. But because if you look at the combination of the memory piece where Google's pushing, the computer piece that Percepa is pushing, you start to see a changing capability envelope. What happens in 6 months or 8 months if our LLMs can now run native
|
||||
|
||||
**12:26** · compute inside the LLM weights as something they can invoke when they need to run particular programs and they don't need a tool call and what happens if that is also something that is super efficient because the KV cache has been compressed six or eight times and now you can do more. What you're looking at if you start to chain together some of these insights we're having at the cutting edge is a world of a stepchanging capability, right? A world where it's not the LLM itself getting smarter that makes the LLM better. It's the fact that the LLM architecture is changing.
|
||||
|
||||
### Why TurboQuant Isn't in Production Yet What Is the KV Cache?
|
||||
|
||||
**12:57** · And so the LM is much better at memory, holds way more memory without effort, seemingly holds six, seven, 8x more memory without working too hard, and also at the same time, oh by the way, doesn't have to call tools to do computing anymore. That is looking a lot like a revolutionary change in architecture that we may start to see in the second half of 2026 as it starts to roll toward production systems. This is how innovation works, right? You have a transformer architecture. There are a trillion dollars being poured into making this whole system better. And people are like constantly banging their heads on the wall figuring out how do we improve this?
|
||||
|
||||
**13:29** · These two breakthroughs that I'm talking about are not the only ones, but I've picked them because they highlight where the industry is going as a whole. The industry is thinking about how you can make true computing possible and a more flexible architecture that doesn't require all of this tool calling. The industry is thinking about how you can efficiently solve memory.
|
||||
|
||||
**13:47** · And when you put those two together, you get a capability breakthrough. That is a big big deal. Now let's imagine a world where we start to see this breakthrough architecture. Just walk back with me and look at the strategic implication for a second. Google wins twice in this world.
|
||||
|
||||
**14:01** · They wrote TurboQuant and they also run Gemini. And Google has explicitly stated that the KV cache is a bottleneck for Gemini. They've had trouble securing HPM high bandwidth memory. And so if they can actually get Turbo Quan implemented in Gemini, they effectively have a compounding cost advantage on top of their TPU stack and they are able to start to roll this out faster than anybody else because they had the breakthrough themselves originally. This also frees them from some of the competitive dynamic around acquiring memory which is going to be a structural advantage for them long term.
|
||||
|
||||
**14:32** · Now for Nvidia, the narrative gets complicated.
|
||||
|
||||
**14:35** · Jensen spent GTC arguing that Vera Rubin's 500x memory increase solves the inference bottleneck. And Turbo Quant effectively says, "Why not just compress the cash and you get 6x more out of the GPUs you already have?" Well, Nvidia makes money selling chips. They kind of want you to buy more chips to solve that problem. If Nvidia ends up selling fewer chips because compression works really well, they've got a problem. Now, so far that hasn't been the case because the world needs so much AI and is demanding so much AI that no matter what we do, Jensen keeps selling more chips.
|
||||
|
||||
**15:04** · But it is something that complexifies Nvidia's narrative a little bit as we start to move into a world where memory becomes more of a software fungeible constraint.
|
||||
|
||||
**15:14** · The other thing I want to call out is that middleware continues to not win here. So middleware is sitting on top of these foundation models. And if you're looking at where you acrew value, the foundation models are where you can acrue value. That's where the KV cache is being optimized. That's where the tool sets and tool calling capabilities are being optimized. And if you're sitting on top of these models, they may or may not pass their margins on to you.
|
||||
|
||||
### Percepta: Embedding Compute Inside an LLM
|
||||
|
||||
**15:33** · Certainly, they won't pass full margins on to you and you may still continue to get squeezed even as the foundation models reap the gains of these kinds of efficiencies. Enterprises on the other hand are in a really good spot because what enterprises can do is they can start to say, "Hey, we want more for our existing chips. How can we get more out of our existing chips? Can we use something like TurboQuant and actually implement the memory in a way that works?" Now, one thing I want to call out here is you might walk away thinking TurboQuant is the only answer.
|
||||
|
||||
**16:00** · TurboQuant is the only breakthrough on memory. And that is not true. There are other forces out there, other breakthroughs, other research papers out there on me. And so really what makes this whole memory conversation powerful, it's it's that it's not a single paper.
|
||||
|
||||
**16:12** · It's actually the breadth of the attack on the memory problem as a whole. So smart people are hitting this from at least five distinct angles and I want to outline them briefly so you understand the broader landscape. Quantization is how TurboQuant does it, right? They're representing the same vectors in the memory space in fewer bits. And that's the core insight, right? And before TurboQuant did this, KV demonstrated two-bit asymmetric quantization. If you want to get nerdy, zip cache has an approach here as well. So quantization is a stable vector of attack across at least three different research areas.
|
||||
|
||||
**16:41** · Eviction and sparity is actually a completely different strategy from Turboquan. Instead of compressing everything and throwing away the tokens that don't matter, H2O, which is uh Oracle's heavy hitter, keeps only the tokens that attention scores the highest and evicts the rest. Uh, Snap KV has an approach here where it does something similar during decoding. Streaming LLM keeps this sliding window of recent tokens plus a few attention sync tokens.
|
||||
|
||||
### Strategic Implications: Google, NVIDIA, Enterprises
|
||||
|
||||
**17:04** · So, essentially, eviction and sparity means we can pick the tokens that matter and keep those. It's not going to be lossless like Turboquant, but it is in production and it does help some. And there's there's three or four angles there as well. Architectural redesign.
|
||||
|
||||
**17:18** · Uh this attacks the problem at a model level. Deepseek v2 did this the first time. They introduced multi head latent attention which for the nerds projects keys and values into a lower dimensional latent space during training and then shrinks the KV cache footprint by design rather than after the fact. And there's been other work done here too, right?
|
||||
|
||||
**17:37** · Hybrid architectures like IBM's Granite 4.0, uh Nvidia's Neotronh.
|
||||
|
||||
**17:42** · These replace most of the quadratic attention mechanism, which is how LLMs traditionally work with uh what would we would call like a linear time state space model solution. In other words, it makes the memory problem smaller by definition because it's not quadratic attention. And these require training from scratch, right? You have to just train them from from the the get-go. And that limits immediate adoption, but it represents another direction the architecture is heading to make memory more efficient. A fourth approach is offloading and taring, right? It keeps the full cache, but it shifts it around strategically.
|
||||
|
||||
**18:13** · So, shadow KV will store compressed keys on a GPU and offload those values to a CPU, which allows you to achieve much larger batch sizes and uh very high throughput on the right chip. And it treats GPU memory and CPU memory as effectively a hierarchy, right? You can have RAM and solid state memory on your machine in the same way you have like GPUs and CPUs. Flex Gen is also going after this uh and they take it even further with really aggressive offloading to a disk for throughput optimized not latency optimized workload. So this is where you want like high throughput. You don't care how long it takes.
|
||||
|
||||
### Five Angles Attacking the Memory Problem
|
||||
|
||||
**18:44** · And so that's a way to get memory off of the model's immediate KV cache but still make it accessible to the model. Attention optimization uh is the fifth and final approach we'll talk about. It makes the computation itself cheaper without shrinking down the data.
|
||||
|
||||
**18:59** · So flash attention is an example of how companies are attacking this problem, right? Uh flash attention restructures how attention which is what LLMs do reads and writes GPU memory to minimize input output reads and writes which in theory improves performance dramatically on NVIDIA chips. Percept has been in this business for a while. Uh Perceptor's whole KVach also goes after this. It uses two-dimensional attention heads to reduce attention complexity, which by the way, the two-dimensional attention heads are what made that millionstep computation that we talked about earlier with percepta possible.
|
||||
|
||||
**19:32** · So, they've been working on this for a while. The point here is not that any of these is quote unquote the answer. I don't believe in a silver bullet. The point is there are now dozens of research groups and companies attacking the memory problem as a software problem or attacking it algorithmically from multiple directions. And the results are going to compound as we continue to innovate. And this represents one of our most efficient ways to solve one of the biggest problems in AI and really in computing in society today. Memory is something that is blocking us on harvesting a lot of the value of AI.
|
||||
|
||||
### Sovereign Memory: Your Takeaway
|
||||
|
||||
**20:01** · And it's something that I think we don't even realize because we can't even imagine a world where LLMs actually have excellent memory over a long term. Like we're excited that we have fragments of memory in chat GPT right now. We're excited that that that maybe Claude has a little bit of memory that it can remember us with and and maybe we can adjust that or edit that or maybe we can tell it to use an MCP server. Great.
|
||||
|
||||
**20:22** · Memory is such a big deal that we can't imagine a world where the LM just is ambiently aware and has persistent memory over a long period of time. But that's where we're investing and that's where we're going. That is the long-term vision. And the reason I made this video today is because the breakthroughs that we have, including Turboon, which I think is a huge deal, are going to enable us to start to build toward that world and ultimately build really interesting customer experiences, really interesting business experiences, unlock a world that feels more Star Trekian than the world we have today, more like there's just ambient compute and memory everywhere. But we have to build our way there.
|
||||
|
||||
**20:54** · We have to innovate our way there. And it is extremely difficult to do that in a world where it's getting harder and harder to make memory in, which is the world we live in today. I hope this little tour, slightly nerdy down memory lane has been helpful for you. Uh, and I hope you have a sense of where the industry is going on solving some of these really complex problems.
|
||||
|
||||
**21:12** · The biggest takeaway for you if you're looking like what do I do and how can I apply this is pretty simple. Make sure that you have a plan for how you want to handle your own memory and context layer. There is going to be personal memory and context layer stuff out there. I've recommended like you should have an open source one because then no company owns it. Uh that's why I launched uh open brain as an open source protocol. But regardless, you should think of memory as a long-term constraint in your life and in the life of your company if you have one uh or if you work at a company.
|
||||
|
||||
**21:42** · And you should be treating it that way. Treat it as something that is a yearslong problem.
|
||||
|
||||
**21:47** · And you want to make sure that what you are storing is something that you control, that you're okay with, and that you can retrieve aically. That's really important because the alternative is some company deciding for you. And then in that world, if the LMS get better at memory, it's just easier for you because you can throw more at them and it's fine and you don't have to worry about it. If you take anything away, it's what I would call sovereign memory. You should own your memory. You should decide what your memory does. Somebody else should own it for you. All right, best of luck and uh thank you Google for making a really cool breakthrough and uh allowing me to reference Silicon Valley, which is like the best Silicon Valley TV show.
|
||||
|
||||
**22:20** · Chips.
|
||||
@@ -1,113 +0,0 @@
|
||||
---
|
||||
title: "How to Setup"
|
||||
source: "https://wsldl-pg.github.io/ArchW-docs/How-to-Setup/"
|
||||
author:
|
||||
published:
|
||||
created: 2026-08-23
|
||||
description: "A ArchWSL for documentation"
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://wsldl-pg.github.io/ArchW-docs/How-to-Setup/
|
||||
> Title: How to Setup
|
||||
> Clipped:
|
||||
|
||||
## How to Set Up ArchWSL
|
||||
|
||||
## Requirements
|
||||
|
||||
- Windows 10 1709 Fall Creators Update 64bit or later.
|
||||
- Windows Subsystem for Linux feature is enabled.
|
||||
|
||||
## Installation Instructions
|
||||
|
||||
There are three ways to install ArchWSL.
|
||||
|
||||
### Method 1: zip file
|
||||
|
||||
1. [Download](https://github.com/yuk7/ArchWSL/releases/latest) the installer zip.
|
||||
2. Extract all files in zip file to the same directory. Please extract to a folder that you have write permission. For example, `C:\Program Files` cannot be used since the rootfs cannot be modified there.
|
||||
3. Run `Arch.exe` to extract the rootfs and register to WSL
|
||||
|
||||
As a side note, the executable name is what is used as the WSL instance name. If you rename it, you can have multiple installs.
|
||||
|
||||
### Method 2: appx package
|
||||
|
||||
1. [Download the `.appx` and `.cer`](https://github.com/yuk7/ArchWSL/releases/latest)
|
||||
2. Install `.cer` to the “Trusted Root Certificate Store” of the local machine. For details, please refer to the [Install Certificate page](https://wsldl-pg.github.io/ArchW-docs/Install-Certificate/). You will need administrator privileges to install the certificate.
|
||||
3. Install the `.appx`
|
||||
|
||||
### Method 3: online installer
|
||||
|
||||
1. [Download `Arch_Online.zip`](https://github.com/yuk7/ArchWSL/releases/latest)
|
||||
2. Extract all files in zip file to the same directory.
|
||||
3. Run `Arch.exe` to download rootfs and register to WSL
|
||||
|
||||
This zip file is doesn’t include rootfs (~200 MB), hence its zip file is very small (~2 MB), but rootfs is donwloaded in the first run.
|
||||
|
||||
## Setup after install
|
||||
|
||||
### If you are a WSL1 user, you must change the glibc package. Please see Known issues.
|
||||
|
||||
### Setting the root password
|
||||
|
||||
```shell
|
||||
>Arch.exe
|
||||
[root@PC-NAME]# passwd
|
||||
```
|
||||
|
||||
### Set up the default user
|
||||
|
||||
Please see ArchWiki [Sudo](https://wiki.archlinux.org/index.php/Sudo#Example_entries) and [User and groups](https://wiki.archlinux.org/index.php/Users_and_groups) pages.
|
||||
|
||||
```shell
|
||||
>Arch.exe
|
||||
[root@PC-NAME]# echo "%wheel ALL=(ALL) ALL" > /etc/sudoers.d/wheel
|
||||
(setup sudoers file.)
|
||||
|
||||
[root@PC-NAME]# useradd -m -G wheel -s /bin/bash {username}
|
||||
(add user)
|
||||
|
||||
[root@PC-NAME]# passwd {username}
|
||||
(set default user password)
|
||||
|
||||
[root@PC-NAME]# exit
|
||||
|
||||
>Arch.exe config --default-user {username}
|
||||
(setting to default user)
|
||||
```
|
||||
|
||||
If the default user has not been changed ([issue #7](https://github.com/yuk7/ArchWSL/issues/7)), please reboot the computer or alternatively, restart the LxssManager in an Admin command prompt.
|
||||
|
||||
To restart the `LxssManager`, run this:
|
||||
|
||||
```batch
|
||||
net stop lxssmanager && net start lxssmanager
|
||||
```
|
||||
|
||||
### Initialize keyring
|
||||
|
||||
Please excute these commands to initialize the keyring. (This step is necessary to use pacman.)
|
||||
|
||||
```shell
|
||||
>Arch.exe
|
||||
[user@PC-NAME]$ sudo pacman-key --init
|
||||
|
||||
[user@PC-NAME]$ sudo pacman-key --populate
|
||||
|
||||
[user@PC-NAME]$ sudo pacman -Sy archlinux-keyring
|
||||
|
||||
[user@PC-NAME]$ sudo pacman -Su
|
||||
```
|
||||
|
||||
### Install patched glibc (need in WSL1)
|
||||
|
||||
Arch’s glibc is built for Linux kernel 4.4 and above and does not work with WSL1.
|
||||
|
||||
WSL1 users **should** always follow the steps in [Known issues](https://wsldl-pg.github.io/ArchW-docs/Known-issues/#wsl1--wsl2).
|
||||
|
||||
### Install systemctl alternative (Optional)
|
||||
|
||||
WSL does not have support for systemd however, there are several solutions. Please see [Known issues](https://wsldl-pg.github.io/ArchW-docs/Known-issues/#systemdsystemctl).
|
||||
@@ -1,389 +0,0 @@
|
||||
---
|
||||
title: "万字长文|Web出海第一步,从选需求到关键词研究,教你选出第一个赚美刀的方向"
|
||||
source: "https://x.com/momo_peggy/status/2099415429831876747"
|
||||
author:
|
||||
- "[[@momo_peggy]]"
|
||||
published: 2026-09-14
|
||||
created: 2026-09-21
|
||||
description: "大家好,我是夏林果~!好么,上回那篇Web出海的完整闭环流程写完,很多准备做出海的小伙伴关注了我,跟我说已经开始采购域名了,这家伙,大家这执行力很棒啊!夏林果的出海日记@momo_peggy·9月8日今天开始,来讲讲我最熟悉的Web出海业务,小白友好~! 文章万字长文|从 0 到..."
|
||||
tags:
|
||||
- "clippings"
|
||||
- "webclipper"
|
||||
---
|
||||
> [!info] Source
|
||||
> URL: https://x.com/momo_peggy/status/2099415429831876747
|
||||
> Title: 万字长文|Web出海第一步,从选需求到关键词研究,教你选出第一个赚美刀的方向
|
||||
> Clipped:
|
||||
|
||||

|
||||
|
||||
大家好,我是夏林果~!
|
||||
|
||||
好么,上回那篇Web出海的完整闭环流程写完,很多准备做出海的小伙伴关注了我,跟我说已经开始采购域名了,这家伙,大家这执行力很棒啊!
|
||||
|
||||
> 9月8日
|
||||
>
|
||||
> 今天开始,来讲讲我最熟悉的Web出海业务,小白友好~!
|
||||
|
||||
我知道你很急,但你先别急,我建议你不要急着注册域名,也不要让ai开始写代码。先花点时间确认你要做个什么站,解决什么问题,赚谁口袋里的钱
|
||||
|
||||
所以这一篇开始讲第一步:**怎么从一个想法开始,找到真实需求,再把它变成用户会搜索的关键词,从而确认好赚美刀的方向。**
|
||||
|
||||
这篇第一步的流程,是我认为最重要的,最核心的,如果你是想做Web出海的小白,看看这篇吧(文章有点长,你可以收藏了回头用的时候再看hhh)
|
||||
|
||||

|
||||
|
||||
## 一、Web 出海的第一步是找好需求
|
||||
|
||||
**为什么 Web 出海第一步是找好需求**
|
||||
|
||||
这一步最最最最重要!!你得找能产生收益的需求~选不好后面全完犊子!
|
||||
|
||||
新手最常见的情况是,想到一个自认为很妙的产品,然后马上开始自嗨式开发了。做了几周,功能越来越多,页面越来越复杂,最后鼓捣上线了。结果过了三个月没什么流量,更没有用户付费,这时才开始怀疑是不是推广做得不够好。
|
||||
|
||||
但很多时候,问题根本不在推广,而在一开始就没有确认:谁会用,为什么现在就要用,他会去哪里寻找解决办法。
|
||||
|
||||
比如,我高中同学之前打算给宠物主人做个社交类的网站,类似于宠物主人版的人人网。我听完其实心里觉得有点不靠谱,这个功能太大了,太泛了,你有自信做的比脸书和ins还牛吗。费心费力做出来,最后可能连一个真正愿意用的人都没有。
|
||||
|
||||
所以我现在更愿意先问另一组问题:**海外用户正在为什么问题花时间、花钱?** 这个问题是不是反复出现?他们现在怎么解决?现有方案到底差在哪里?
|
||||
|
||||
**好需求如何定义**
|
||||
|
||||
是不是好需求方向,看四个点:
|
||||
|
||||
- **问题是否具体**:能不能说清楚是谁,在什么场景下,要完成什么动作?哪怕是一个小问题都行
|
||||
- **问题是否重复**:是偶尔发生的一次意外,还是用户每周、每天都会遇到?
|
||||
- **用户是否在找办法**:他有没有搜索、提问、比较工具,或者已经找人帮忙?
|
||||
- **有没有付费理由**:解决它能不能省时间、少出错、赚到钱,或者避免一笔损失?
|
||||
|
||||
别妄想给所有人做一个万能工具,用户不明确,问题不具体,关键词发散,竞品又多。你很难知道第一版到底该做什么。
|
||||
|
||||
反之,你可以选择**做一个精细垂直的小工具,解决一个小问题**,比如“帮独立卖家在发货前自动检查地址格式”,用户、场景和动作就清楚多了。接下来要查的也很具体:这类卖家多久遇到一次?现在怎么处理?是自己忍着,还是找人帮忙,或者已经在买别的工具?
|
||||
|
||||
## 二、怎么找到一个好的需求
|
||||
|
||||
这个过程我一般分成三个动作:捞、筛、掂(怎么那么像厨子呢hhh)
|
||||
|
||||

|
||||
|
||||
**第一步:捞,把需求的线索先捞上来**
|
||||
|
||||
从哪捞?海底捞吗?当然不是了,怎么就惦记吃呢hhh
|
||||
|
||||
我给你找了6种可以捞需求线索的方向,往下看吧兄弟~⬇️⬇️⬇️
|
||||
|
||||
**1️⃣用户表达:他们正在怎么说**
|
||||
|
||||
先听用户怎么在平台去吐槽,甚至去骂,这个来源又可以分成两种:
|
||||
|
||||
- **社交媒体和社区**:看 Reddit 的行业小板块、X、Facebook 群组、LinkedIn、Discord、Indie Hackers 等。这里更容易看到用户日常抱怨、经验分享和临时解决方案。
|
||||
- **论坛和问答**:看 Quora、Stack Overflow,以及各种垂直论坛。这里的问题通常更具体,能看到用户卡在了哪一步、尝试过什么办法。
|
||||
|
||||

|
||||
|
||||
**2️⃣用户反馈:现有产品哪里没有接住**
|
||||
|
||||
如果已经有竞品,甚至有付费的竞品,说明这个需求起码已经被市场验证可行,这时候就去看它的低星评价。G2、Capterra、App Store、Chrome Web Store,以及竞品自己的评论区都可以看。
|
||||
|
||||
不要只看评分,重点看用户原本想完成什么,产品在哪一步没有满足。但一条差评只代表一个人的经历。把相似评价多找几条,看它到底是偶发问题,还是很多人都在遇到。当然了,光看可不行啊,你得上手试试,看看用户说的是真是假,有没有可能这些吐槽已经被竞品解决了呢。
|
||||
|
||||
**3️⃣产品市场:这个领域已经有什么**
|
||||
|
||||
**导航站和综合目录**,比如 Product Hunt、AlternativeTo、SaaSHub、BetaList、Uneed,以及各种行业工具目录,适合用来建立一个领域的产品地图。
|
||||
|
||||
你可以记录产品服务谁、解决什么问题、怎么分类、怎么收费,以及用户正在寻找哪些替代品。它们只能帮你看市场上有哪些产品,不能直接证明产品有流量或销量。被目录收录,最多说明它出现过,不能说明用户真的在用,更不能说明它卖得好,有可能就是花钱做外链了。
|
||||
|
||||
4️⃣**付费行为:用户已经为哪些事情花钱**
|
||||
|
||||
可以分成两类看:
|
||||
|
||||
- **服务交易平台**:Upwork、Fiverr、Freelancer、Contra、PeoplePerHour。这里能看到用户愿意花钱请人完成什么任务,以及他们如何描述需求、预算大概在哪个范围。
|
||||
- **招聘平台**:LinkedIn Jobs、Indeed、Wellfound、Remote OK。这里能看到企业愿意长期花工资让人做什么重复劳动,以及这个岗位需要哪些固定能力。
|
||||
|
||||
这两类信息要分开理解。服务平台说明有人愿意为一次任务付钱,招聘平台说明企业愿意长期为一类工作付费。它们都不能直接推出用户会买软件,你还要看这项工作是不是重复、能不能标准化,以及人工流程里有没有一段可以被工具替代。
|
||||
|
||||
**5️⃣搜索行为:用户有没有主动找解决办法**
|
||||
|
||||
Google 的自动联想、相关搜索和搜索结果,也值得顺手看一眼。这里先做轻量观察,不需要马上展开完整关键词研究。
|
||||
|
||||

|
||||
|
||||
你可以先记下用户使用的原词,以及搜索结果到底是工具、教程、论坛还是产品对比。这样能帮助你判断:用户是在了解问题,还是想马上完成一个动作。
|
||||
|
||||
正式的搜索量、CPC、KD 分析放到后面的关键词研究部分。前面只需要确认这个问题有没有被用户用搜索表达。
|
||||
|
||||
**6️⃣亲身体验:你自己在哪里被卡住**
|
||||
|
||||
这个最常见吧,你在使用海外产品时遇到的卡点,也可以成为线索。比如操作很绕、某个功能缺失、价格不透明、导出麻烦,或者一个简单任务需要反复手动完成。
|
||||
|
||||
但个人体验只能作为起点,不能直接当成市场结论。把它记下来,再去用户讨论、竞品评价和搜索结果里找印证。你过去工作里如果出现过要是有人做了某个工具,我们马上就买这样的表达,也值得先记录,再验证。
|
||||
|
||||
你不需要把这些来源全部逛一遍。新手可以先选一个用户表达的地方,再选一个能观察付费行为的地方,最后用搜索结果做一次交叉验证。**至少有两类证据对得上,再进入下一步;不要因为某个平台上出现一个热门帖子,就马上开始做产品。**
|
||||
|
||||
**第二步:筛,伪需求你不要过来啊!**
|
||||
|
||||
这步你得把每条线索重新过一遍,主要看三个点:问题够不够具体,是否反复发生,遇到它的人是不是一群相对清楚的人。
|
||||
|
||||
- **第一道:数次数,而且要跨地方数。** 同一个抱怨在不同地方出现,比一个帖子里有很多点赞更有参考价值。比如 Reddit 有人在讨论,竞品差评区有人提到,论坛里也有人问,三个地方各出现一次,往往比单个平台刷屏更可靠。
|
||||
- **第二道:分清用户是在发泄,还是在找办法。** 光骂现有产品,可能只是情绪。骂完以后还在问有没有替代品、大家正在用什么、有没有更快的做法,这就不一样了。后面这类人已经开始找答案,离一个可被解决的需求更近。
|
||||
- **第三道:看是谁在骂。** 如果抱怨的人都是小会计、独立卖家、摄影师,或者某一类具体用户,后面就比较好验证具体场景。
|
||||
|
||||

|
||||
|
||||
**第三步:掂,确认它有没有变现机会**
|
||||
|
||||
这里要看的,是它有没有付费理由,市场上有没有空隙,以及你自己能不能做出来、推广出去。
|
||||
|
||||
- **第一关:看市场上有没有人真金白银在付。** 打开竞品定价页,看同行如何收费,免费版和付费版的边界在哪里,哪些功能被放在付费墙后面。这能告诉你市场里已经存在什么收费方式,但不要把定价页当成销量证明。
|
||||
- **第二关:看这个赛道有没有现实的切入口。** 用候选关键词搜索前几页结果,把排名靠前的产品列出来,简单看它们的域名经营时间、网站权重、引荐域名数量、内容规模和产品质量。如果前几页几乎都是经营多年的强品牌,且外部链接和内容积累明显领先,新手就要谨慎,不要只因为有搜索量就冲进去。
|
||||
- **第三关:先做一次最低限度的功能对齐。** 不需要马上做完整竞品调研,但要把首页排名靠前的产品打开,走一遍它们的核心流程:用户怎么进入,怎么完成任务,最后拿到什么结果。把这个流程拆成几个基础功能,再问自己:这些功能我能不能做?第一版能不能至少完成同样的核心任务?
|
||||
- **第四关:问用户的行为,不要问意愿。** 找到前面发帖抱怨、留下差评的人,尝试和他们交流。比如上一次遇到这个问题时,你是怎么处理的?花了多少时间和钱?最后怎么解决?现在还会遇到吗?用户能讲出具体过程,说明他真的经历过。
|
||||
- **第五关:重新掂一遍问题本身。** 重点问四件事:做错了有没有后果,用户烦不烦,这个问题是不是隔三差五就来一次,用户有没有已经到处找办法。能帮用户省时间、赚钱、减少错误或降低麻烦的需求,通常比纯娱乐需求更容易找到付费理由。
|
||||
- **第六关:算一算成本。** 用 AI、现成接口或无代码工具,能不能先做出一个可用版本?单个用户的服务成本是多少?未来可能的定价和成本之间有没有利润空间?同时写出这批用户可能聚集的三个地方。暂时说不出来,不代表需求一定不存在,但说明你的获客路径还没有出现,需要继续查。
|
||||
- **第七关:掂自己能不能接得住。** 你能不能做出至少不输给竞品的基础体验?能不能理解这批用户?能不能持续处理客服、反馈和后续需求?有些方向看起来有钱,但你没有能力或兴趣长期服务,最后也很难做成。
|
||||
|
||||
行了,这三步你看完,需求也就基本选择的差不多了。
|
||||
|
||||
## 三、选好需求后做关键词研究
|
||||
|
||||
**为什么选好需求后还要做关键词研究**
|
||||
|
||||
需求确认之后,你得琢磨琢磨,用户在谷歌是怎么去搜的。对 Web 工具来说,关键词研究是在继续追问三件事:
|
||||
|
||||
- **用户会怎么说:** 他会在搜索框里输入什么词?
|
||||
- **他搜这个词想做什么:** 是了解问题、比较方案,还是马上使用工具?
|
||||
- **这个词值不值得做:** 有没有足够的需求、商业价值和进入机会?
|
||||
|
||||
它至少会影响后面的产品决策:
|
||||
|
||||
- 决定你的首页应该围绕什么词和什么动作来写;
|
||||
- 决定你要做工具页、产品页,还是先做教程和对比内容;
|
||||
- 决定你是依靠搜索获客,还是要换成社媒、社区或其他渠道。
|
||||
|
||||
比如“做一个去水印工具”是产品想法,不是关键词。用户可能搜索 image watermark remover,也可能搜索 remove watermark from photo。这两个词看起来相近,背后的用户表达和搜索结果却可能不一样。
|
||||
|
||||
所以,关键词研究最后要回答的不是“哪个词搜索量最高”,而是:**用户真的在搜什么,我应该用什么页面接住他,以及这个词有没有机会给产品带来用户和收入。**
|
||||
|
||||

|
||||
|
||||
**关键词研究怎么做**
|
||||
|
||||
你可以先把这件事记成一条很简单的路线:**先把用户可能搜索的词找出来,再弄清楚每个词背后的意图,最后从里面选出第一批真正值得做的核心词。**
|
||||
|
||||
**第一步:从需求里提炼核心词,再把词池扩展开**
|
||||
|
||||
核心词,就是你对这个需求最直接、最基础的几种叫法。不要一开始就追求“最准确的词”,先把用户可能使用的表达收回来。
|
||||
|
||||
可以从四个方向列核心词:
|
||||
|
||||
- **产品词:** 用户可能直接搜索的工具或产品名称;
|
||||
- **动作词:** 用户想完成的动作,比如 translate、remove、convert、generate;
|
||||
- **场景词:** 用户在什么场景下使用,比如 academic paper、online、for students;
|
||||
- **用户原话:** Reddit、论坛、差评和客服沟通里出现过的自然表达。
|
||||
|
||||
以 PDF Translator 为例,第一批核心词可以先从 pdf translator、translate pdf、online pdf translation 这些核心表达开始。像“扫描件翻译”“论文翻译”属于后面扩展出来的场景词,不要一开始就把词池做得很散。
|
||||
|
||||
- 看 Google 搜索框的自动联想和底部相关搜索。
|
||||
- 看竞品首页、标题、描述和产品功能中反复出现的表达。竞品已经在用的词,至少说明这个词和市场有关系,但不代表你可以直接照抄。
|
||||
- 看 Reddit、论坛、问答和用户评价中的原话。工具给你的是数据,用户原话能告诉你他们真实怎么描述问题。
|
||||
- 用 Ahrefs、Semrush、Google Keyword Planner 等工具扩展相关词;预算有限,可以先用 Google 自动联想、Google Trends 和 Keyword Planner。
|
||||
- 让 AI 帮你发散,但只把它当成候选词生成器。AI 可以帮你把说法想宽,最后能不能留下,要回到真实搜索数据和 Google 首页结果。
|
||||
|
||||
英文市场可以这样问 AI:
|
||||
|
||||
```text
|
||||
你是一名 SEO 关键词研究员。
|
||||
我要做一个工具网站:[一句话描述这个工具给谁用、解决什么问题]。请想象一个真实用户,他正被 [这个工具解决的问题] 困扰,正在谷歌上搜索解决办法。
|
||||
列出 20 个他真正会敲进谷歌的英文关键词短语。
|
||||
每个关键词标注搜索意图:想直接用工具、想找教程、还是在比较产品。最后按“关键词—搜索意图”的清单输出。
|
||||
```
|
||||
|
||||
如果你想看小语种市场,不要让 AI 把英文清单逐词翻译过去。可以这样问:
|
||||
|
||||
```text
|
||||
现在把同样的事再做一遍,换成 [德语] 市场。
|
||||
列出 20 个母语者遇到同样问题时,真正会敲进谷歌的 [德语] 关键词短语。
|
||||
不要把英文清单逐词翻译过去,要按当地人的真实搜法来想。
|
||||
每个关键词标注搜索意图,结果用 [德语] 输出,并按“关键词—搜索意图”的清单排列。
|
||||
```
|
||||
|
||||
小语种最容易踩的坑,是把英文逐词翻译成当地语言,但当地人根本不这么搜。AI 和翻译工具可以帮你列候选词,最后一定要回到目标国家的搜索结果,最好再找母语者确认。这个后面我单独写一篇怎么找小语种的关键词。
|
||||
|
||||
**第二步:判断搜索意图,并把相近的词归到一起**
|
||||
|
||||
拿到一批候选词之后,先别急着看数字。先判断用户搜索这个词时到底想做什么。常见的搜索意图可以简单分成四类:
|
||||
|
||||
- **信息型:** 想了解、学习或解决一个问题,比如 how to translate a pdf;
|
||||
- **商业调研型:** 想比较工具或方案,比如 best pdf translator;
|
||||
- **交易型:** 想直接完成动作,比如 pdf translator online;
|
||||
- **导航型:** 想找某个已经知道的品牌或网站。
|
||||
|
||||
判断意图最简单的办法,就是把词放进 Google,看首页结果。是工具页多,还是教程、论坛和对比文章多?Google 首页已经告诉你这个词背后的主要需求。
|
||||
|
||||

|
||||
|
||||
接下来要做关键词分组。不要把每个词都当成一个独立页面,也不要为了凑词给同一个需求写十篇差不多的文章。
|
||||
|
||||
- 搜索意图和 Google 首页结果高度相似的词,可以归为一组;
|
||||
- 一组词选一个主关键词,其余作为相关词自然覆盖;
|
||||
- 如果两个词的首页结果完全不同,说明它们可能是两个不同主题,需要分别判断。
|
||||
|
||||
比如 pdf translator 和 online pdf translator 的搜索结果可能高度重叠,可以先作为一个工具页主题;而 how to translate a pdf 更像教程意图,可以单独做内容页,再把用户引导到工具页。
|
||||
|
||||
**第三步:从候选词里选出真正要做的核心词**
|
||||
|
||||
好词其实可以先用一句话理解:**用户搜完确实想完成一个动作,搜索量或流量潜力够用,KD 没超过你的红线,而且你的产品能直接接住这个需求。**
|
||||
|
||||
确定了什么叫好词之后,再用数据做粗筛。对我自己做 Web 工具来说,我会先用一条比较直接的标准:**优先看搜索量或流量潜力在 10K 以上、KD 不超过 60,而且搜索结果里确实有工具或产品页的词。**
|
||||
|
||||
这不是 Google 的规则,而是用来帮自己快速缩小范围的工作门槛,一般会用semrush看:
|
||||
|
||||
- **搜索量 / 流量潜力:** 先看这个词有没有足够大的搜索入口。搜索量低于 10K,我通常先放到后面;如果新手觉得门槛太高,可以先从 1K 以上的词练手。
|
||||
- **KD:** 看竞争难度。KD 大于 60,我通常先不考虑;新手可以优先找 KD 30—50 的词。
|
||||
|
||||

|
||||
|
||||
- **CPC:** 看广告主是否愿意为这类点击付费。CPC 越高,商业价值通常越明显,但它只是参考,不能单独证明能赚钱。
|
||||
- **搜索结果:** 如果首页主要是工具、产品页或落地页,说明用户有直接完成动作的需求;如果全是教程和论坛,商业价值通常要打折。
|
||||
|
||||
## 四、小白跟练实操案例:PDF Translator
|
||||
|
||||
前面讲的是方法,下面把这个方法真正走一遍。PDF Translator 这个方向是我先拿到的一个具体想法,接下来要做的不是马上开发,而是按照前面的流程去确认:它到底是不是一个值得做的需求。
|
||||
|
||||
**第一步:捞,收集 PDF Translator 的需求线索**
|
||||
|
||||
我自己在处理外语论文、报告或说明书时,遇到过一个很直接的卡点:想把 PDF 翻译成自己能读的语言,但复制、分段翻译、对照原文和重新排版都很麻烦。
|
||||
|
||||
所以后来我基本用Dechecker的pdf translator的功能去翻译,因为可以保留文档的布局格式,不会乱码,也不会串行,主要是我觉得还算便宜,文档很大也不用等非常久,但我还是想自己做一个
|
||||
|
||||

|
||||
|
||||
[dechecker.ai](https://dechecker.ai/)
|
||||
|
||||
后来我在 Reddit 上继续搜,发现这不是我一个人的问题。有人在问怎么翻译整份 PDF,有人在问扫描版 PDF 怎么处理,也有人抱怨翻译完以后标题、表格和原来的版式全乱了。
|
||||
|
||||

|
||||
|
||||
这时我开始认真看 PDF Translator 这个方向。自己的卡点只能算第一条线索,Reddit 上的重复讨论说明问题可能普遍存在,现有产品没有形成完整体验,则说明市场里可能有缺口了。
|
||||
|
||||
**第二步:筛,确认问题是否反复出现**
|
||||
|
||||
接下来要确认的其实是同一件事:用户是不是经常遇到这个问题,而且已经为解决它付出了时间或金钱。
|
||||
|
||||
我把 Reddit 上的讨论、现有产品的低星评价和用户正在使用的替代方案放在一起看。看大家是不是在描述相似的过程:上传失败,扫描件识别不了,翻译后格式混乱,表格和公式不能处理,或者只能复制文字后分段翻译。再看他们现在怎么解决。有的人复制粘贴,有的人购买通用翻译工具,有的人请人处理,还有的人在不同工具之间来回切换。这些行为说明用户已经在付出成本。
|
||||
|
||||
从这些讨论和评价里,还能整理出几个核心痛点:比如 PDF 不能直接复制,扫描件需要识别;翻译后标题、表格和页码容易乱;专业术语前后不一致;用户最终想要的是一份可以继续阅读、下载和复查的文件,而不是网页里零散的翻译结果。
|
||||
|
||||
**第三步:掂,判断这个需求有没有机会做**
|
||||
|
||||
**先把用户场景和服务闭环梳理出来**
|
||||
|
||||
确认问题可能存在之后,我会把用户从进入网站到拿到结果的流程写出来。假设一个用户拿到一篇外语论文:
|
||||
|
||||
1. 他搜索 PDF 翻译工具,进入网站。
|
||||
2. 上传 PDF,先看到支持的文件大小、页数和语言。
|
||||
3. 选择原语言和目标语言,开始处理文件。
|
||||
4. 系统识别 PDF 内容,再进行翻译,同时尽量保留标题、段落和页码关系。
|
||||
5. 用户预览结果,发现某一段或某个术语有问题,可以单独重新处理。
|
||||
6. 用户下载结果,或者复制内容回到自己的笔记和文档里。
|
||||
7. 用户提交反馈,告诉产品哪一页有问题、哪个术语不准确。
|
||||
|
||||
这样梳理下来,PDF Translator 提供的就不只是一个翻译接口,而是一条完整服务流程:**上传文件,识别内容,翻译内容,保留基本结构,预览结果,下载文件,再收集反馈。**
|
||||
|
||||
第一版先处理常见的文字型 PDF,让用户完成上传、翻译、预览和下载。扫描件 OCR、复杂表格、公式、双栏论文的完美还原,可以作为后续功能,不要一开始全部塞进去。
|
||||
|
||||
然后问自己一个很现实的问题:第一版能不能把这条基础闭环做出来?不要求一开始比竞品更快、更便宜,也不要求马上覆盖所有复杂 PDF,但至少要能完成同一个核心任务。如果连基础功能都接不住,需求再真实也还不能进入开发。
|
||||
|
||||
**再评估技术、竞品和进入机会**
|
||||
|
||||
需求看起来成立,还要继续判断能不能做。技术上,PDF Translator 至少涉及文本提取、扫描件 OCR、翻译接口、上下文处理、排版还原、文件生成和大文件处理。第一版如果只做文字型 PDF,技术难度是可控的;如果一开始就要求扫描件、复杂表格和论文双栏排版全部还原,成本会快速上升。
|
||||
|
||||
如果市场上已经有产品,但它们都只是顺手提供一个翻译入口,没有把识别、翻译、预览、下载和反馈做成完整体验,说明可能存在切入口。这个切入口还要结合关键词竞争判断,不能只凭“竞品体验不好”就开始开发。至于怎么系统拆功能、分析用户评价和寻找比竞品更好的位置,放到下一篇竞品调研里展开。
|
||||
|
||||
|
||||
|
||||
**第四步:开始关键词研究,确认有没有搜索入口**
|
||||
|
||||
**从需求里提炼种子词,再扩展候选词**
|
||||
|
||||
前面已经确认,用户想把外语 PDF 变成可以阅读、下载和复查的文件。所以这次不从“我还能想到哪些词”开始,而是先从产品动作和用户表达里提炼种子词。
|
||||
|
||||
第一批核心词先定为:
|
||||
|
||||
- pdf translator
|
||||
- translate pdf
|
||||
- pdf translation
|
||||
- online pdf translator
|
||||
|
||||

|
||||
|
||||
这几个词都直接对应“找 PDF 翻译工具”这个动作。再把它们放进 Google 自动联想、关键词工具和竞品页面里扩展,可能会出现 translate scanned pdf、translate academic paper pdf 这类场景词。
|
||||
|
||||
但这一轮先不把痛点词和长尾词全部纳入,目的是先验证这个产品最核心的搜索入口:用户是否会直接搜索“PDF 翻译工具”。
|
||||
|
||||
**判断搜索意图,并把相近的词归组**
|
||||
|
||||
这几个核心词的搜索意图不完全一样:
|
||||
|
||||
- pdf translator:更像是在找一个可以直接使用的工具;
|
||||
- online pdf translator:同样偏向在线工具,行动意图更强;
|
||||
- translate pdf:可能是找工具,也可能是找具体操作方法;
|
||||
- pdf translation:表达更宽,可能是在了解服务,也可能是在找工具。
|
||||
|
||||
最终不能只靠词面判断,还要看 Google 首页。如果 pdf translator 和 online pdf translator 的首页结果高度重叠,可以先归到同一个工具页主题;如果 translate pdf 的首页主要是教程,就要考虑它是否更适合用教程页承接,再把用户引导到工具。
|
||||
|
||||
这一轮先把核心工具词作为主线,场景词和教程词留到后续内容规划,不让第一版产品方向发散。
|
||||
|
||||
**从候选词里选出真正要做的核心词**
|
||||
|
||||
前两步已经把候选词找出来、按搜索意图分好组了。现在只做一件事:从里面选出 PDF Translator 第一版真正要做的核心词。
|
||||
|
||||
对这个工具,我会先用一个很直观的粗筛标准:**搜索量或流量潜力尽量在 10K 以上,KD 不超过 60,搜索结果里还要有用户可以直接使用的 PDF 翻译工具。** 新手不必照搬 10K,可以先从 3K 以上、KD 30—50 的词练手。
|
||||
|
||||
然后逐个核对:
|
||||
|
||||
- pdf translator 和 online pdf translator 的搜索结果是否高度重叠,能不能合并到同一个工具页;
|
||||
- translate pdf 是否更多是教程结果,如果是,就不要强行把它当成工具页的唯一核心词;
|
||||
- CPC 有没有显示出商业价值,排名靠前的页面有没有同时从相关词获得流量;
|
||||
- Google 首页是不是已经被强品牌占满,还是存在小站、功能缺口和用户吐槽。
|
||||
|
||||
这样筛完,PDF Translator 第一版就可以先围绕能直接接住工具需求的核心词做首页,其他教程词和场景词再作为后续内容入口,而不是一开始把所有词都做进去。
|
||||
|
||||
**复盘,判断能不能进入下一步**
|
||||
|
||||
到这里,我仍然不会直接说“PDF Translator 可以做”。更准确的说法是:它已经从一个产品想法,变成了一条可以继续验证的需求线索。
|
||||
|
||||
目前得到的是:
|
||||
|
||||
- 需求来源:自己处理外语 PDF 时遇到的卡点,以及 Reddit 上反复出现的类似问题
|
||||
- 用户场景:学生、研究人员和专业从业者,需要把外语 PDF 翻译成可阅读、可下载的文件
|
||||
- 验证证据:用户讨论、竞品差评、替代方案、付费成本和技术可行性需要互相印证
|
||||
- 基础功能对齐:至少确认竞品能完成上传、识别、翻译、预览和下载,自己也能做出第一版核心闭环
|
||||
- 产品闭环:上传、识别、翻译、保留基本结构、预览、下载、反馈
|
||||
- 核心关键词:先验证 pdf translator、translate pdf、pdf translation、online pdf translator
|
||||
|
||||
这才是从需求到关键词的完整过程:先发现一个具体任务,再确认它是否重复、用户是否在找办法、有没有付费理由,最后看它有没有搜索入口。中间任何一环证据不足,都不能急着进入开发。
|
||||
|
||||
## 五、复盘:从需求线索到关键词,完整流程是什么
|
||||
|
||||
这篇文章真正想讲的,不是怎么找一个听起来很酷的点子,而是怎么在动手开发之前,把一个方向逐层验证清楚。
|
||||
|
||||

|
||||
|
||||
整条路线可以压缩成五步:
|
||||
|
||||
1. **捞线索:** 从自己的卡点、用户讨论、竞品差评和付费行为里,找到一个真实发生的问题。
|
||||
2. **筛需求:** 确认这个问题是不是反复出现,用户有没有主动找办法,并且已经付出时间或金钱成本。
|
||||
3. **掂可行性:** 说清楚用户场景和服务闭环,走一遍竞品的基础流程,确认自己能不能做出不低于基础水平的版本。
|
||||
4. **查关键词:** 从需求里提炼种子词,判断搜索意图,再结合搜索量、流量潜力、CPC、KD、趋势和商业潜力排优先级。
|
||||
5. **做出判断:** 把需求、用户、基础功能、关键词和技术成本放在一起,判断这条方向是否值得进入下一轮。
|
||||
|
||||
所以,最后要回答清楚的不是一个问题,而是六个:**谁有问题?问题有多频繁?他们现在怎么解决?竞品的基础功能是什么?我能不能先做到同等水平?用户能不能通过搜索找到我?**
|
||||
|
||||
## 下一篇:研究竞品,知己知彼
|
||||
|
||||
这一篇只是完成了基础判断:需求是不是真实,用户有没有成本,产品能不能做,关键词有没有搜索入口。
|
||||
|
||||
下一篇我会**教你如何做竞品调研,并找到自己的机会点**
|
||||
|
||||
竞品调研的目的,不是找一个产品照着做,而是看清楚这个市场已经怎么服务用户、怎么收钱,以及还留下了什么空位。所以下一篇我们继续讲~!当然了,不会太快,我需要好好打磨内容。
|
||||
Reference in New Issue
Block a user