vault backup: 2026-01-05 14:26:17
This commit is contained in:
 windyboy
@@ -0,0 +1,181 @@
|
||||
---
|
||||
page-title: "配置实例 | 达梦技术文档"
|
||||
url: https://eco.dameng.com/document/dm/zh-cn/start/dm-instance-linux.html
|
||||
date: "2024-09-05 08:35:28"
|
||||
---
|
||||
## 一、前言
|
||||
|
||||
DM 数据库在 Linux 环境支持命令行配置实例以及图形化配置实例,本章节将分别进行介绍。
|
||||
|
||||
## 二、命令行方式初始化实例
|
||||
|
||||
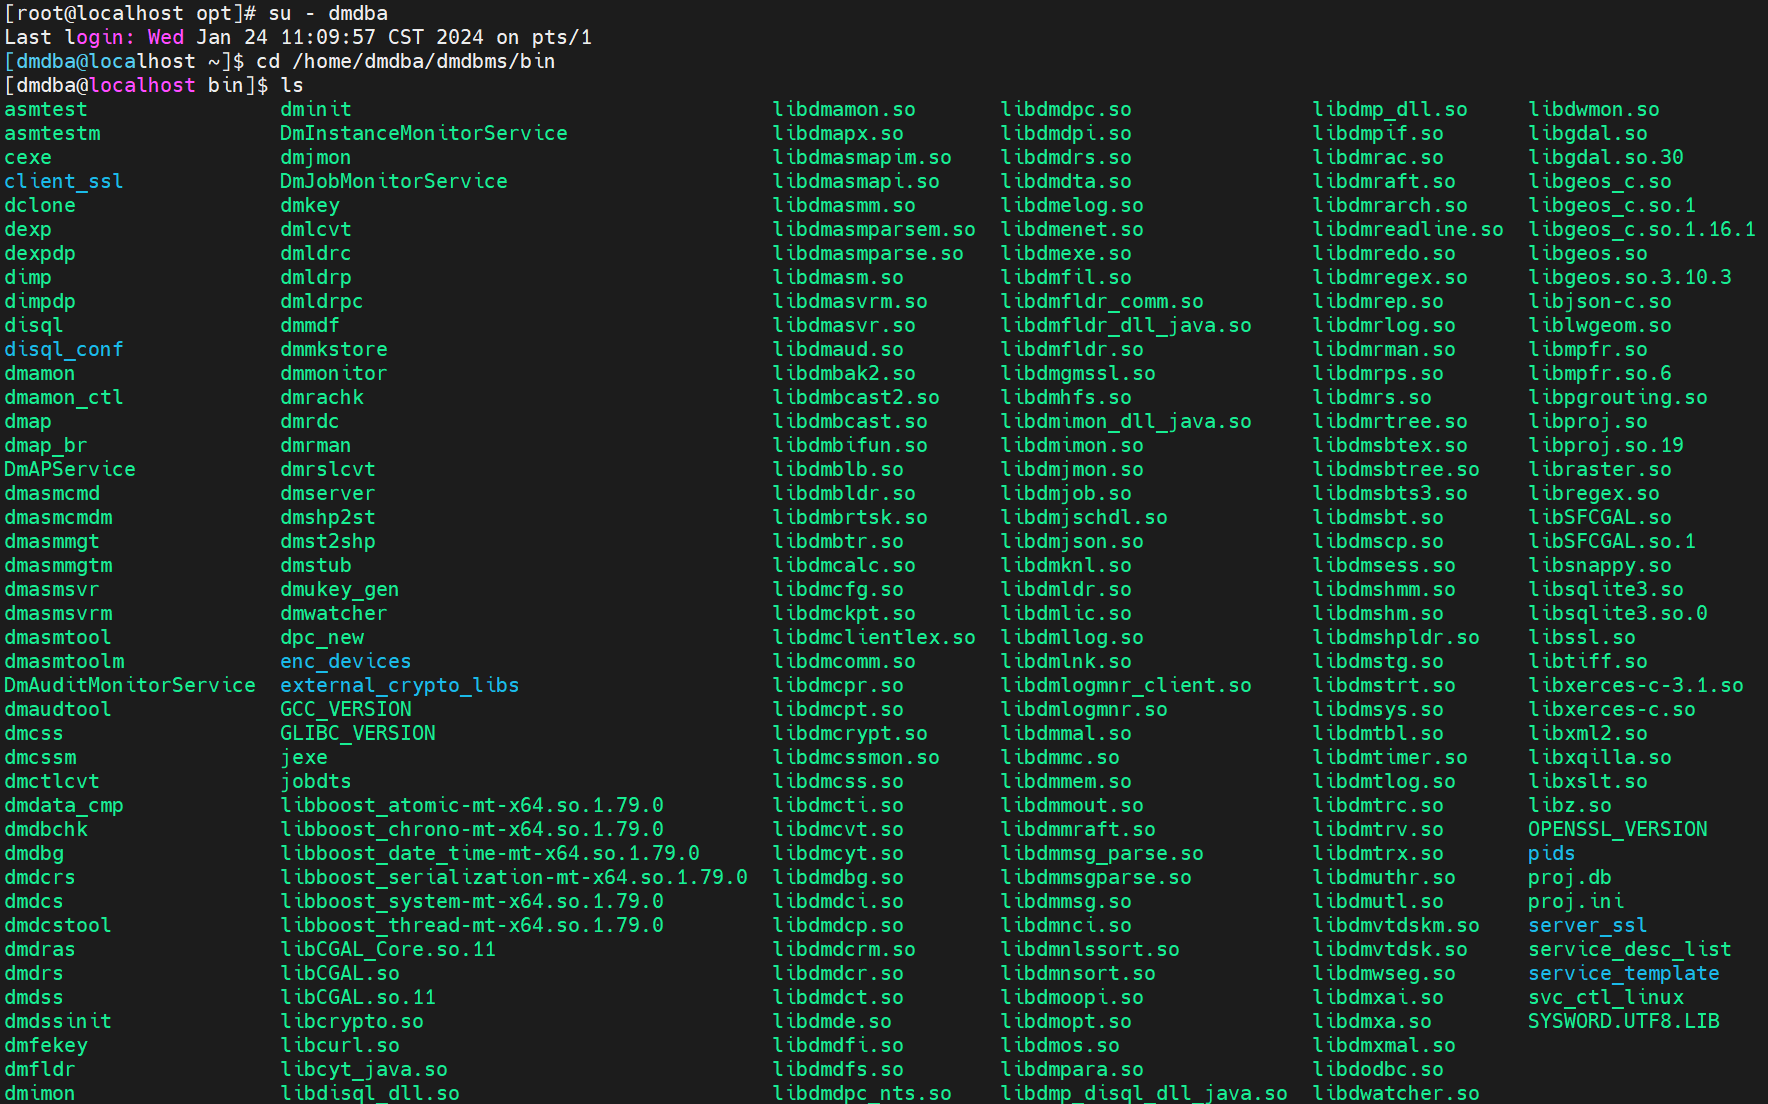
使用 dmdba 用户配置实例,进入到 DM 数据库安装目录下的 bin 目录中。
|
||||
|
||||
Copy`su - dmdba cd /home/dmdba/dmdbms/bin`
|
||||
|
||||
|
||||
|
||||
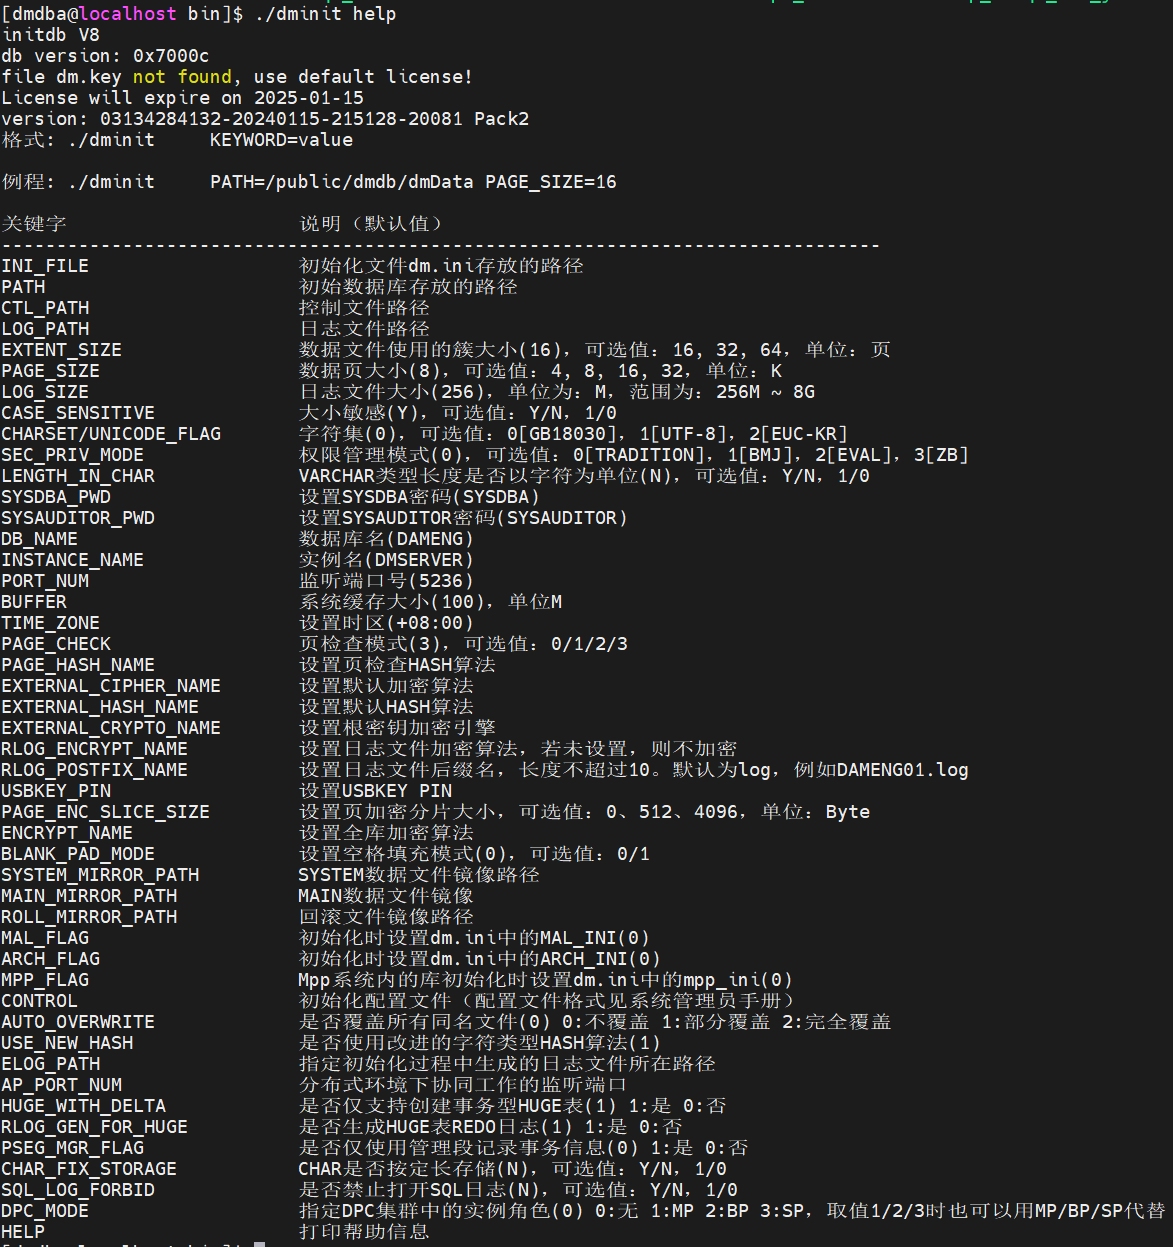
使用 dminit 命令初始化实例,dminit 命令可设置多种参数,可执行如下命令查看可配置参数。
|
||||
|
||||
Copy`./dminit help`
|
||||
|
||||
|
||||
|
||||
需要注意的是 **页大小 (page\_size)、簇大小 (extent\_size)、大小写敏感 (case\_sensitive)、字符集 (charset) 、空格填充模式 (BLANK\_PAD\_MODE) 、页检查模式(PAGE CHECK)** 等部分参数,**一旦确定无法修改**,在初始化实例时确认需求后谨慎设置。
|
||||
|
||||
部分参数解释如下:
|
||||
|
||||
- page\_size:数据文件使用的页大小。取值范围 4、8、16、32,单位:KB。缺省值为 8。可选参数。选择的页大小越大,则 DM 支持的元组长度也越大,但同时空间利用率可能下降。数据库创建成功后无法再修改页大小,可通过系统函数 SF\_GET\_PAGE\_SIZE()获取系统的页大小。
|
||||
- extent\_size:数据文件使用的簇大小,即每次分配新的段空间时连续的页数。取值范围 16、32、64。单位:页数。缺省值为 16。可选参数。数据库创建成功后无法再修改簇大小,可通过系统函数 SF\_GET\_EXTENT\_SIZE()获取系统的簇大小。
|
||||
- case\_sensitive: 标识符大小写敏感。当大小写敏感时,小写的标识符应用""括起,否则被系统自动转换为大写;当大小写不敏感时,系统不会转换标识符的大小写,系统比较函数会将大写字母全部转为小写字母再进行比较。取值:Y、y、1 表示敏感;N、n、0 表示不敏感。缺省值为 Y。可选参数。此参数在数据库创建成功后无法修改,可通过系统函数 SF\_GET\_CASE\_SENSITIVE\_FLAG()或 CASE\_SENSITIVE()查询设置的参数置。
|
||||
- charset:字符集选项。取值范围 0、1、2。0 代表 GB18030,1 代表 UTF-8,2 代表韩文字符集 EUC-KR。缺省值为 0。可选参数。此参数在数据库创建成功后无法修改,可通过系统函数 SF\_GET\_UNICODE\_FLAG()或 UNICODE()查询设置的参数置。
|
||||
- BLANK\_PAD\_MODE:设置字符串比较时,结尾空格填充模式是否兼容 ORACLE。1:兼容;0:不兼容。缺省值为 0。可选参数。此参数在数据库创建成功后无法修改,可通过查询 V$PARAMETER 中的 BLANK\_PAD\_MODE 参数名查看此参数的设置值。
|
||||
- PAGE\_CHECK:PAGE\_CHECK 为页检查模式。取值范围 0、1、2、3。0:禁用页校验;1:开启页校验并使用 CRC 校验;2:开启页校验并使用指定的 HASH 算法进行校验;3:开启页校验并使用快速 CRC 校验。缺省值为 3。可选参数。在数据库创建成功后无法修改。
|
||||
|
||||
更多 dminit 参数解释可参考达梦数据库安装目录下 doc 目录中《DM8\_dminit 使用手册》。
|
||||
|
||||
> **建议**
|
||||
>
|
||||
> 在实际使用中,初始化时建议提前设置好 COMPATIBLE\_MODE 的参数值,便于更好的兼容其他数据库。参数说明:是否兼容其他数据库模式。0:不兼容,1:兼容 SQL92 标准,2:部分兼容 ORACLE,3:部分兼容 MS SQL SERVER,4:部分兼容 MYSQL,5:兼容 DM6,6:部分兼容 TERADATA,7:部分兼容 POSTGRES。
|
||||
|
||||
可以使用默认参数初始化实例,需要附加实例存放路径。此处以初始化实例到 /dmdata/data 目录下为例(执行初始化命令前,需要使用 root 用户授予 /dmdata/data 目录相应权限,可以参考[修改目录权限](https://eco.dameng.com/document/dm/zh-cn/start/install-dm-linux-prepare#%E7%9B%AE%E5%BD%95%E8%A7%84%E5%88%92)),初始化命令如下:
|
||||
|
||||
Copy`./dminit path=/dmdata/data`
|
||||
|
||||
也可以自定义初始化实例的参数,参考如下示例:
|
||||
|
||||
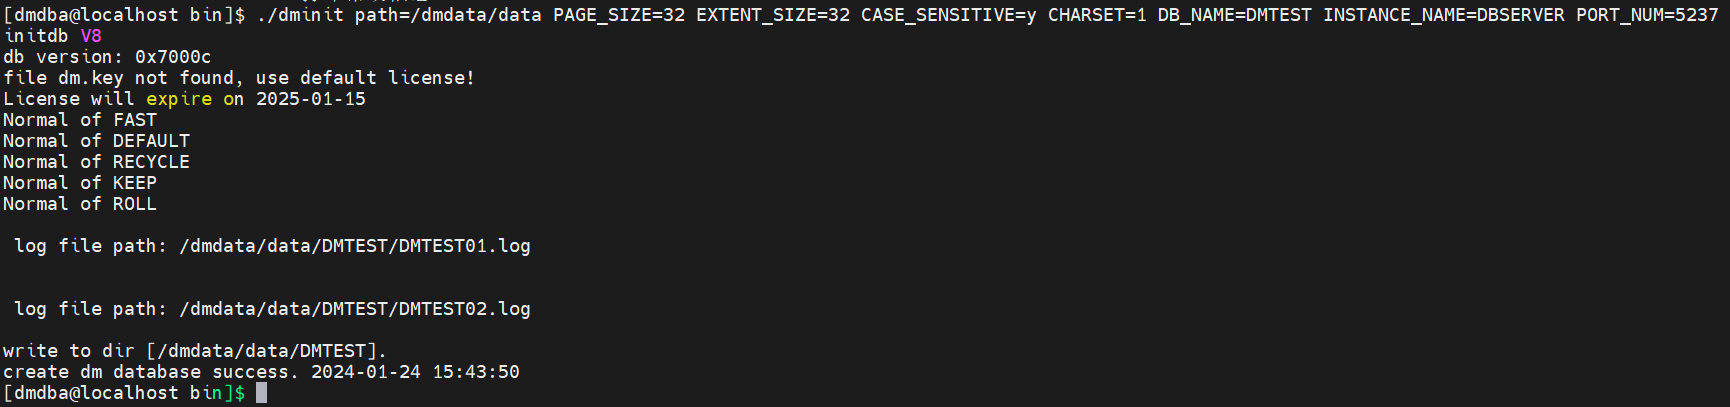
以下命令设置页大小为 32 KB,簇大小为 32 KB,大小写敏感,字符集为 utf\_8,数据库名为 DMTEST,实例名为 DBSERVER,端口为 5237。
|
||||
|
||||
Copy`./dminit path=/dmdata/data PAGE_SIZE=32 EXTENT_SIZE=32 CASE_SENSITIVE=y CHARSET=1 DB_NAME=DMTEST INSTANCE_NAME=DBSERVER PORT_NUM=5237`
|
||||
|
||||
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 如果此处自定义了初始化参数,在后面的注册服务和启动数据库等步骤中,请按实际的自定义参数进行操作。
|
||||
|
||||
## 三、图形化配置实例
|
||||
|
||||
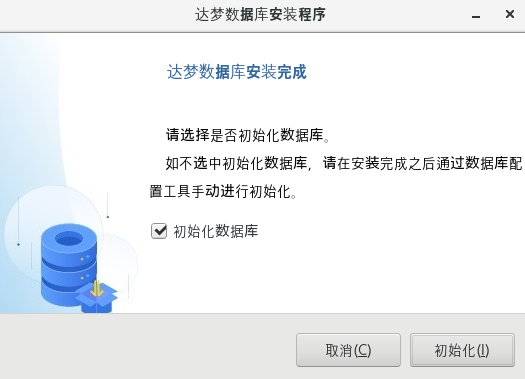
使用图形化界面安装数据库安装完成后,会弹出选择是否初始化数据库页面,选择【初始化】。
|
||||
|
||||
|
||||
|
||||
点击初始化后会弹出数据库配置助手,通过数据库配置助手便可以配置数据库。
|
||||
|
||||
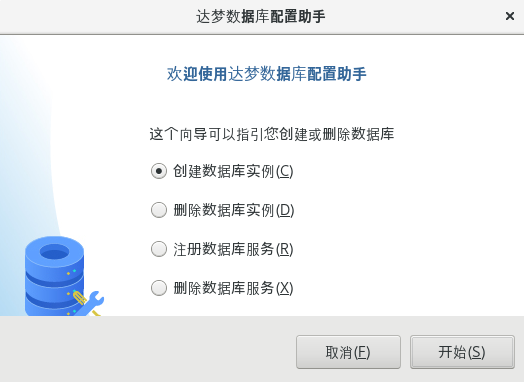
|
||||
|
||||
### 3.1 手动打开配置助手
|
||||
|
||||
若需要主动打开配置助手,可使用 dmdba 用户配置实例,进入到 DM 数据库安装目录下的 tool 目录中,使用 `./dbca.sh` 命令打开数据库配置助手。
|
||||
|
||||
启用图形界面前需要通过如下方法将图形界面权限放开:
|
||||
|
||||
Copy`[root@localhost mnt]# xhost + access control disabled, clients can connect from any host [root@localhost mnt]# echo $DISPLAY [root@localhost mnt]# su - dmdba Last login: 四 1月 25 16:41:51 CST 2024 on pts/1 [dmdba@localhost ~]$ export DISPLAY=:0.0`
|
||||
|
||||
进入 DM 安装目录下的 tool 目录,使用如下命令打开 DM 数据库配置助手,如下所示:
|
||||
|
||||
Copy`[dmdba@localhost ~]$ cd /home/dmdba/dmdbms/tool/ [dmdba@localhost tool]$ ll [dmdba@localhost tool]$ ./dbca.sh`
|
||||
|
||||
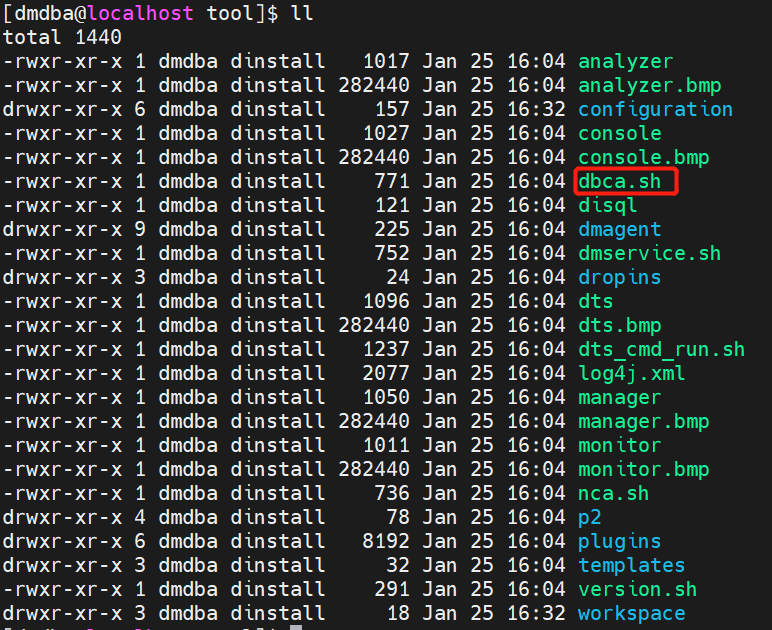
|
||||
|
||||
选择创建数据库实例,点击【开始】。
|
||||
|
||||

|
||||
|
||||
### 3.2 创建数据库模板
|
||||
|
||||
进入创建数据库页面的创建数据库模版页签,此处可以根据实际需求选择合适的数据库模板,一般建议选择【一般用途】其它保持默认即可,如下图所示:
|
||||
|
||||
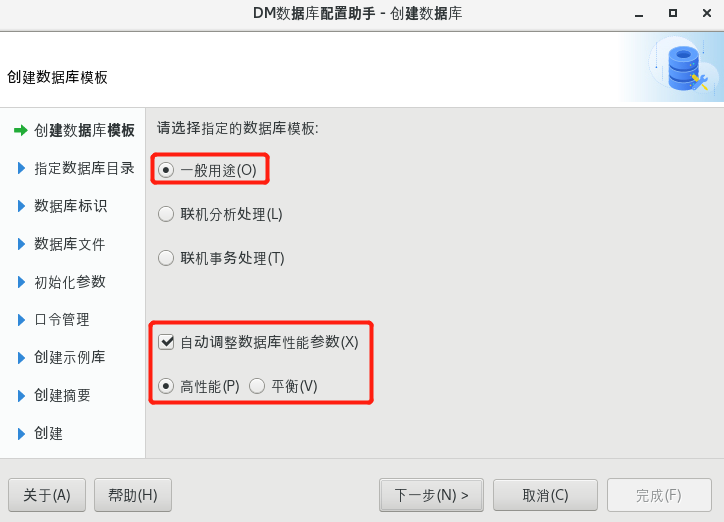
|
||||
|
||||
### 3.3 选择数据库实例目录
|
||||
|
||||
本例中数据库安装路径为 /dmdba/data,如下图所示:
|
||||
|
||||
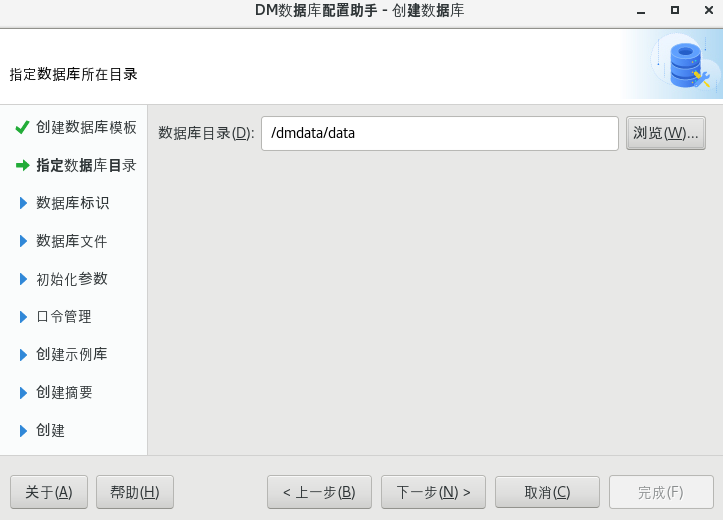
|
||||
|
||||
### 3.4 输入数据库标识
|
||||
|
||||
可自定义输入或保持默认数据库名称、实例名、端口号等参数,如下图所示:
|
||||
|
||||
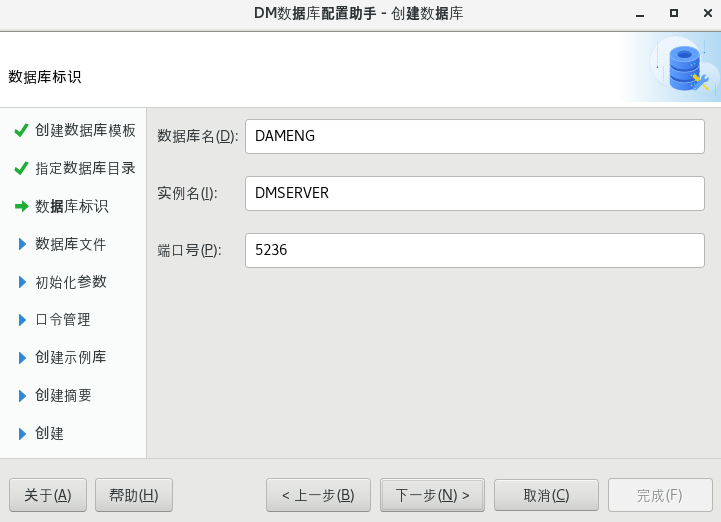
|
||||
|
||||
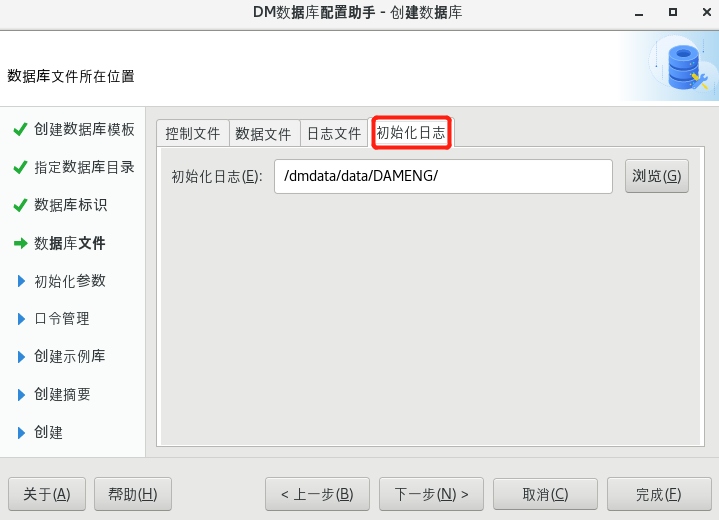
### 3.5 数据库文件所在位置
|
||||
|
||||
此处可选择自定义或保持默认配置路径,如下图所示:
|
||||
|
||||
控制文件:
|
||||
|
||||
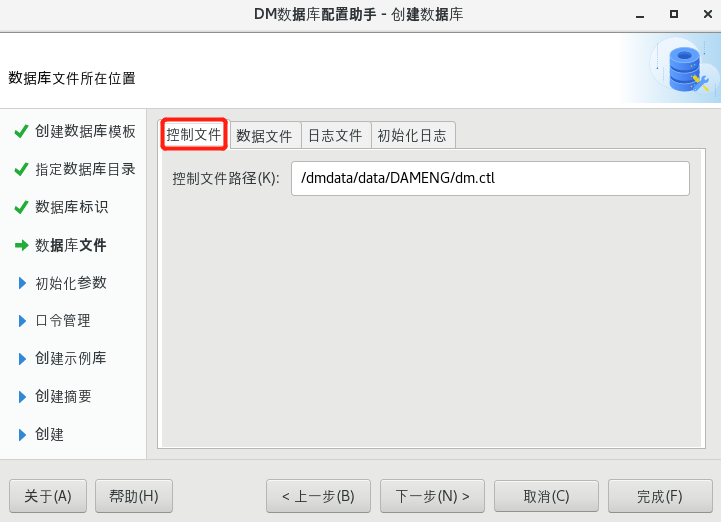
|
||||
|
||||
数据文件:
|
||||
|
||||
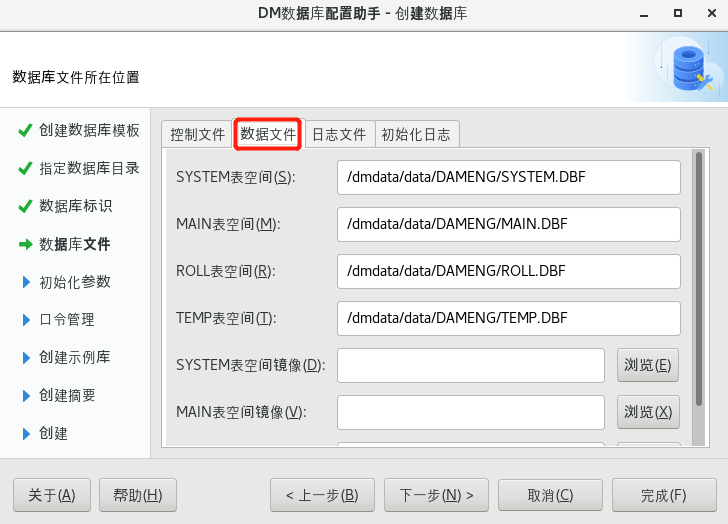
|
||||
|
||||
redo 日志文件:
|
||||
|
||||
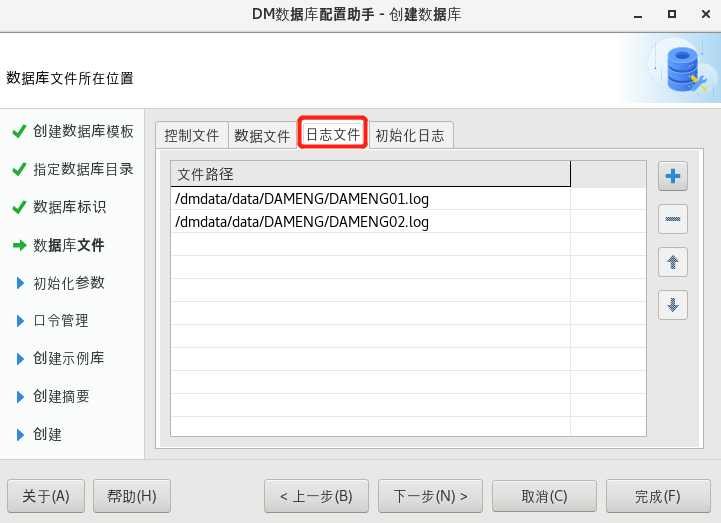
|
||||
|
||||
初始化日志:
|
||||
|
||||
|
||||
|
||||
用户可通过选择或输入确定数据库控制文件、数据文件、日志文件、初始化日志等文件的所在位置,并可通过右侧功能按钮,对文件进行添加或删除。
|
||||
|
||||
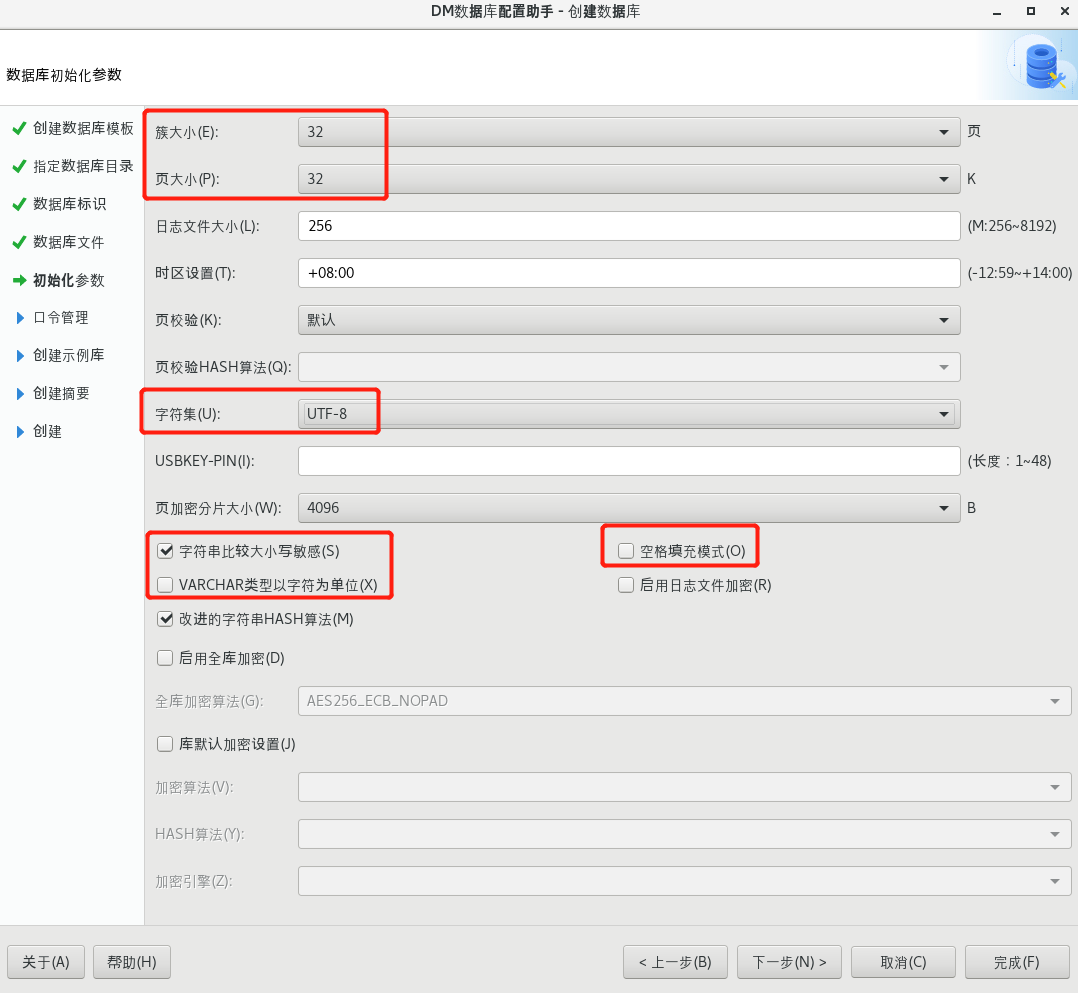
### 3.6 数据库初始化参数
|
||||
|
||||
此处配置可根据实际需求进行配置,如下图所示:
|
||||
|
||||
|
||||
|
||||
需要注意的是**页大小 、簇大小 、大小写敏感 、字符集 、空格填充模式**等部分参数, **一旦确定无法修改** ,需谨慎设置。
|
||||
|
||||
常见参数说明:
|
||||
|
||||
1. 数据文件使用的簇大小:默认值 16,可选值: 16、 32、 64,单位:页。
|
||||
2. 数据页大小:默认值 8,可选值: 4、 8、 16、 32,单位: KB。
|
||||
3. 日志文件大小:默认值 256,单位为: MB,范围为: 64 MB~2 GB。
|
||||
4. 大小敏感:默认值 Y,可选值: Y/N, 1/0。
|
||||
5. 字符集:默认值 0,可选值: 0\[GB18030\], 1\[UTF-8\], 2\[EUC-KR\]。
|
||||
|
||||
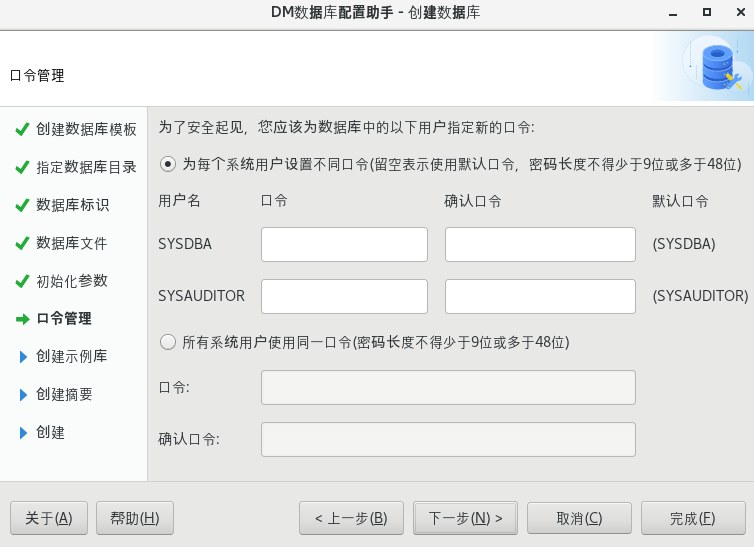
### 3.7 口令管理
|
||||
|
||||
此处选择默认配置即可,**默认口令与登录名一致**,如下图所示:
|
||||
|
||||
|
||||
|
||||
用户可输入 SYSDBA,SYSAUDITOR 的密码,对默认口令进行更改,如果安装版本为安全版,将会增加 SYSSSO 用户的密码修改。
|
||||
|
||||
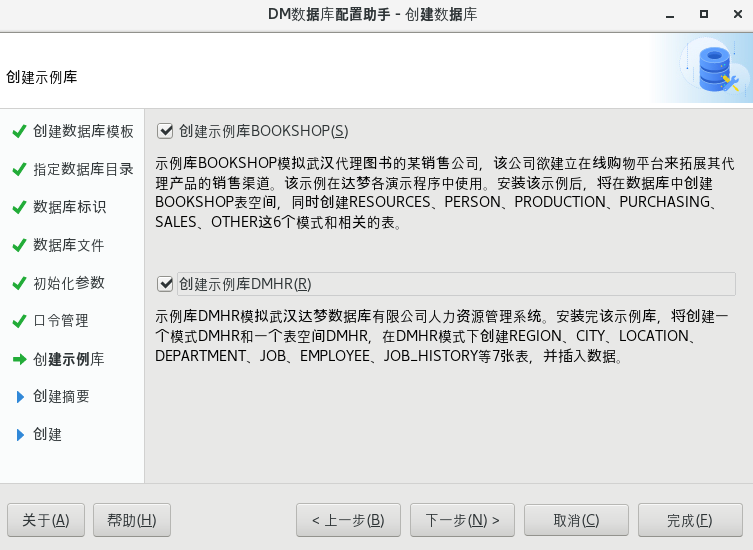
### 3.8 选择创建示例库
|
||||
|
||||
此处建议勾选创建示例库 `BOOKSHOP` 或 `DMHR`,作为测试环境,如下图所示:
|
||||
|
||||
|
||||
|
||||
### 3.9 创建数据库摘要
|
||||
|
||||
在安装数据库之前,将显示用户通过数据库配置工具设置的相关参数。点击【完成】进行数据库实例的初始化工作,如下图所示:
|
||||
|
||||
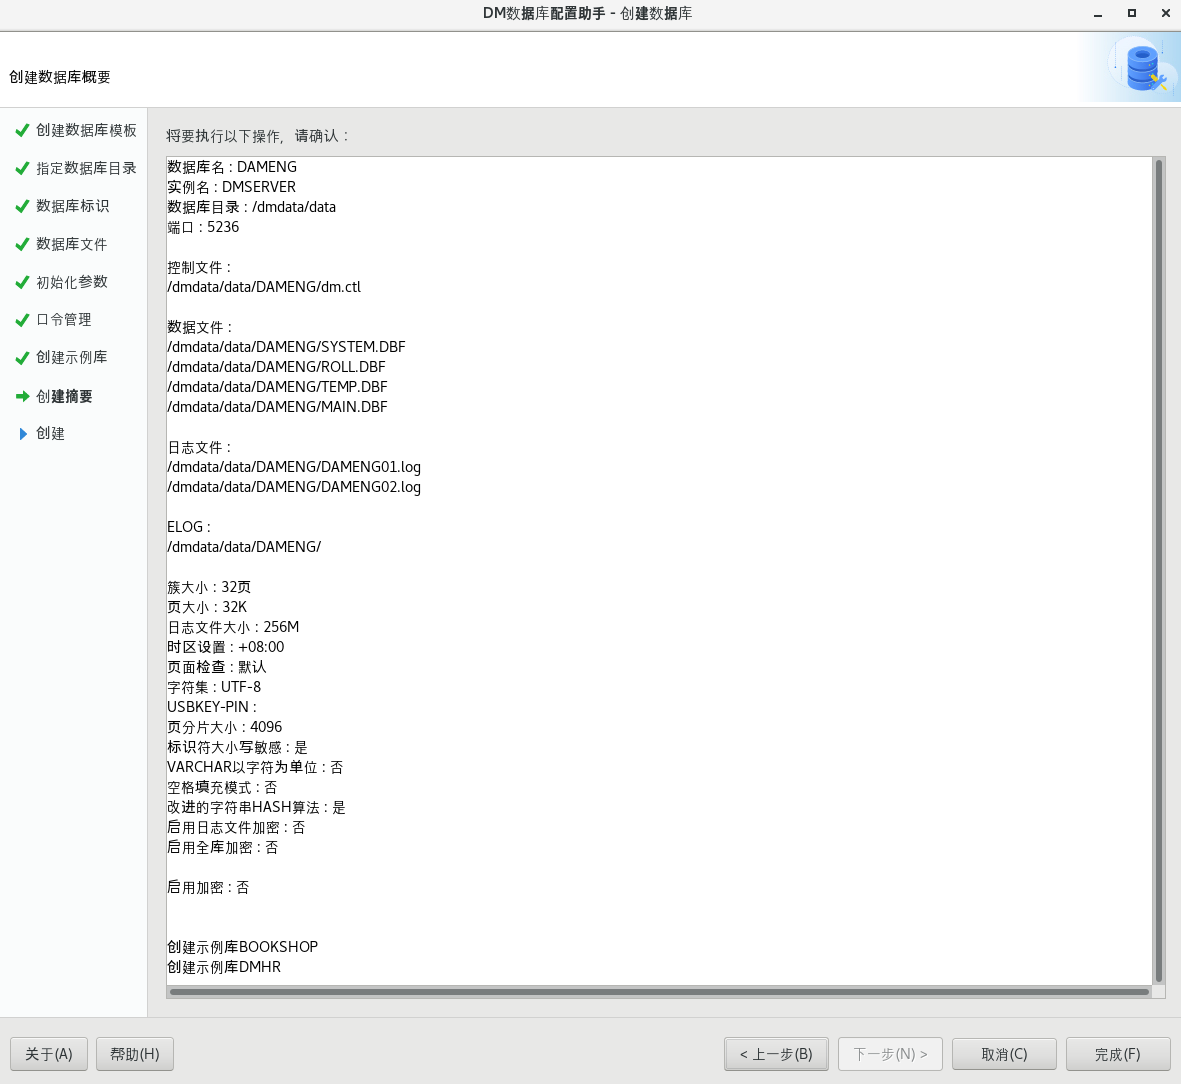
|
||||
|
||||
### 3.10 创建实例
|
||||
|
||||
点击【完成】,创建完成数据库实例后,按下图按提示执行脚本完成实例配置。
|
||||
|
||||
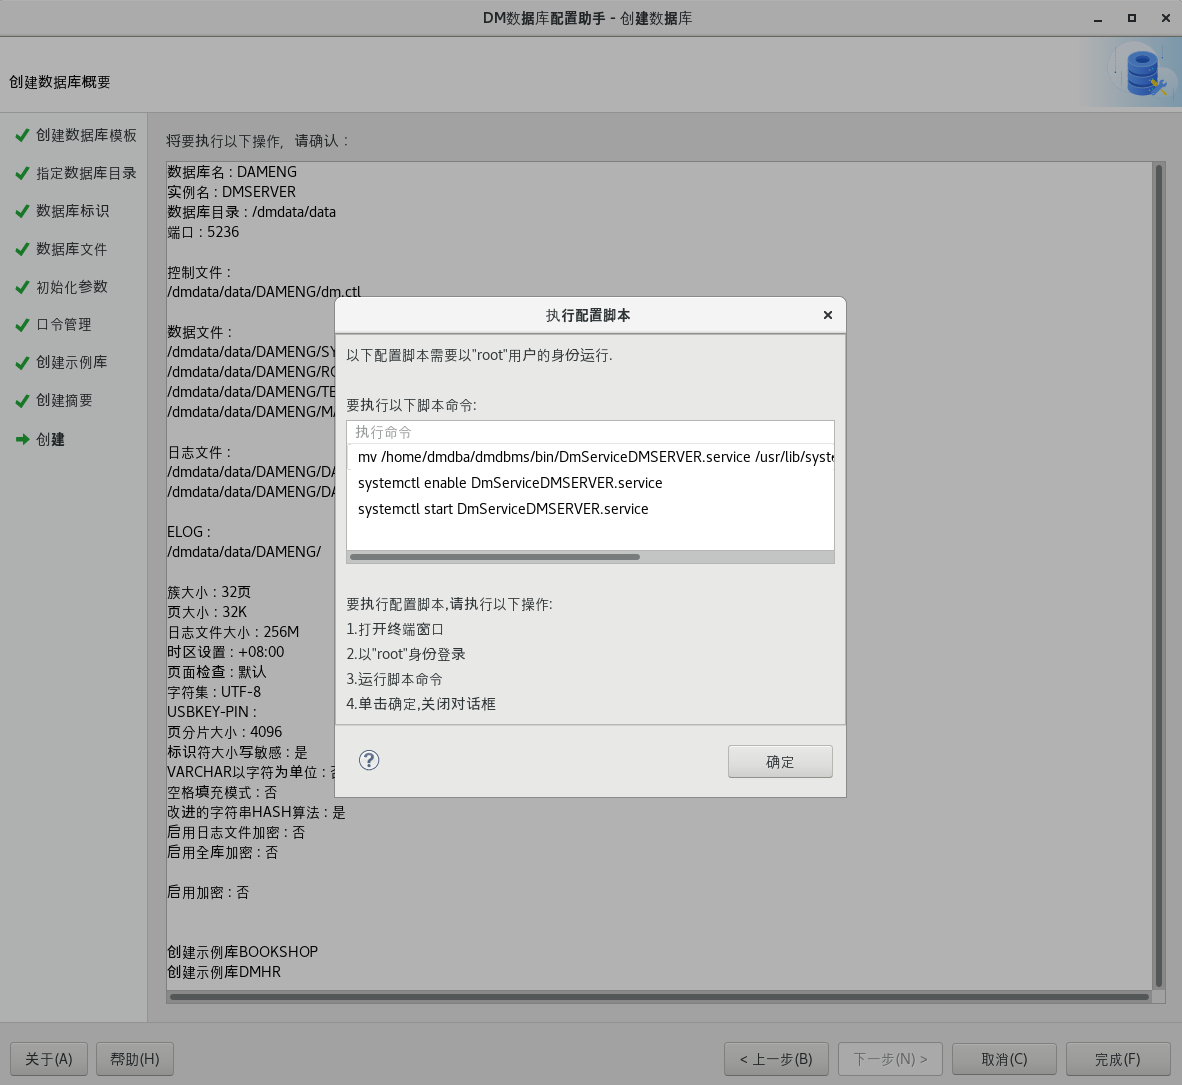
|
||||
|
||||

|
||||
|
||||
执行完成后会提示参数修改完成。
|
||||
|
||||
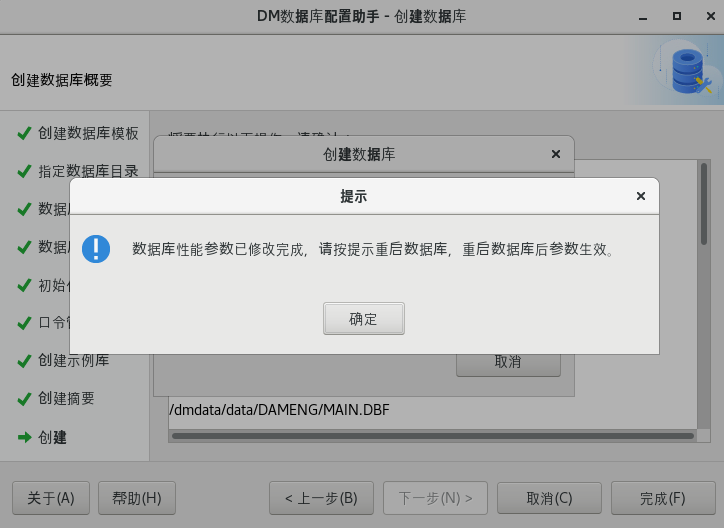
|
||||
|
||||
以 root 用户执行提示的脚本重启数据库使自动优化的参数生效。
|
||||
|
||||
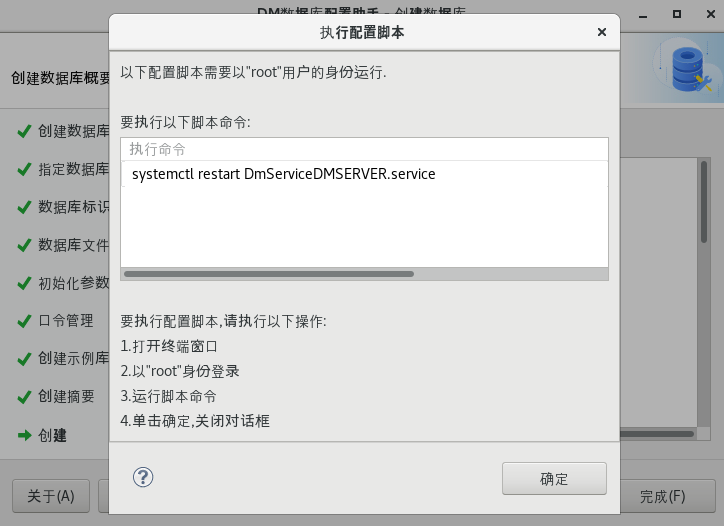
|
||||
|
||||
创建实例完成。
|
||||
|
||||
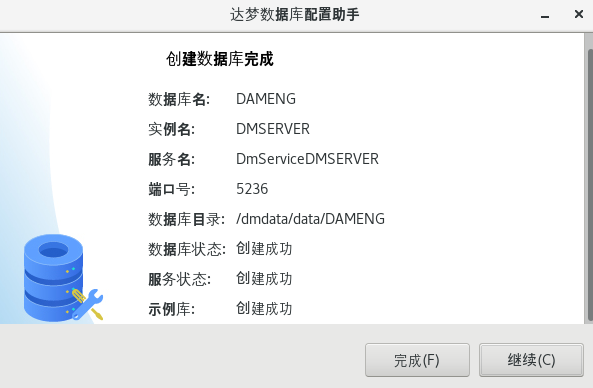
|
||||
|
||||
至此达梦数据库就可以开始使用了。
|
||||
@@ -0,0 +1,128 @@
|
||||
---
|
||||
page-title: "数据库安装 | 达梦技术文档"
|
||||
url: https://eco.dameng.com/document/dm/zh-cn/start/dm-install-linux.html
|
||||
date: "2024-09-05 08:31:28"
|
||||
---
|
||||
## 一、前言
|
||||
|
||||
DM 数据库在 Linux 环境下支持**命令行安装**和**图形化安装**,本章节将分别进行详细介绍。
|
||||
|
||||
## 二、挂载镜像
|
||||
|
||||
切换到 root 用户,将 DM 数据库的 iso 安装包保存在任意位置,例如 /opt 目录下,执行如下命令挂载镜像:
|
||||
|
||||
Copy`cd /opt mount -o loop dm8_20240116_x86_rh7_64.iso /mnt`
|
||||
|
||||

|
||||
|
||||
## 三、命令行安装
|
||||
|
||||
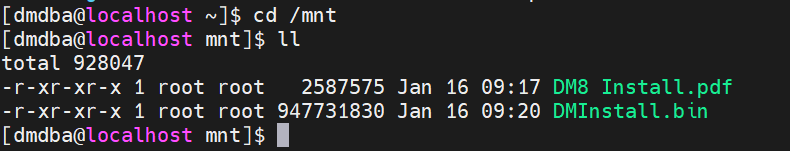
切换至 dmdba 用户下,在 /mnt 目录下使用命令行安装数据库程序,依次执行以下命令安装 DM 数据库。
|
||||
|
||||
Copy`su - dmdba cd /mnt`
|
||||
|
||||
|
||||
|
||||
执行如下命令进行安装。
|
||||
|
||||
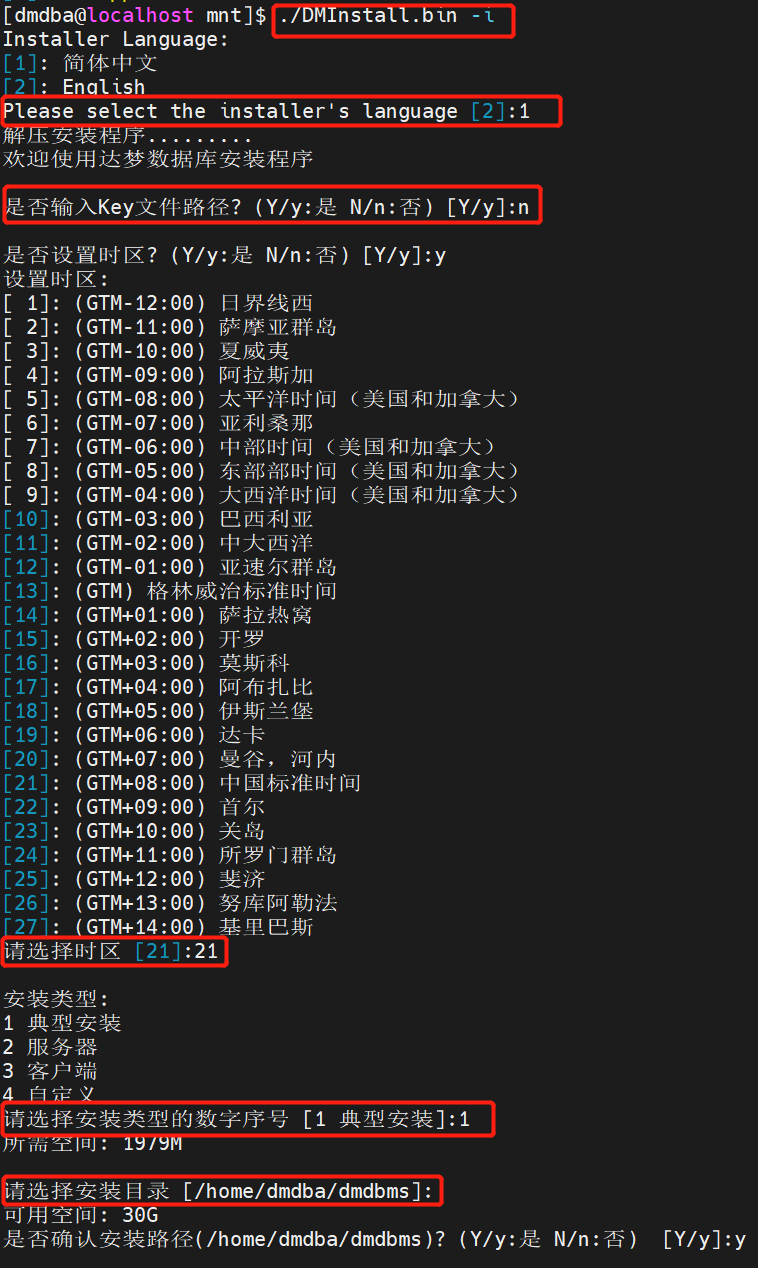
Copy`./DMInstall.bin -i`
|
||||
|
||||
按需求选择安装语言,没有 key 文件选择 "n",时区按需求选择一般选择 “21”,安装类型选择“1”,安装目录按实际情况配置,这里示例使用默认安装位置。
|
||||
|
||||
|
||||
|
||||
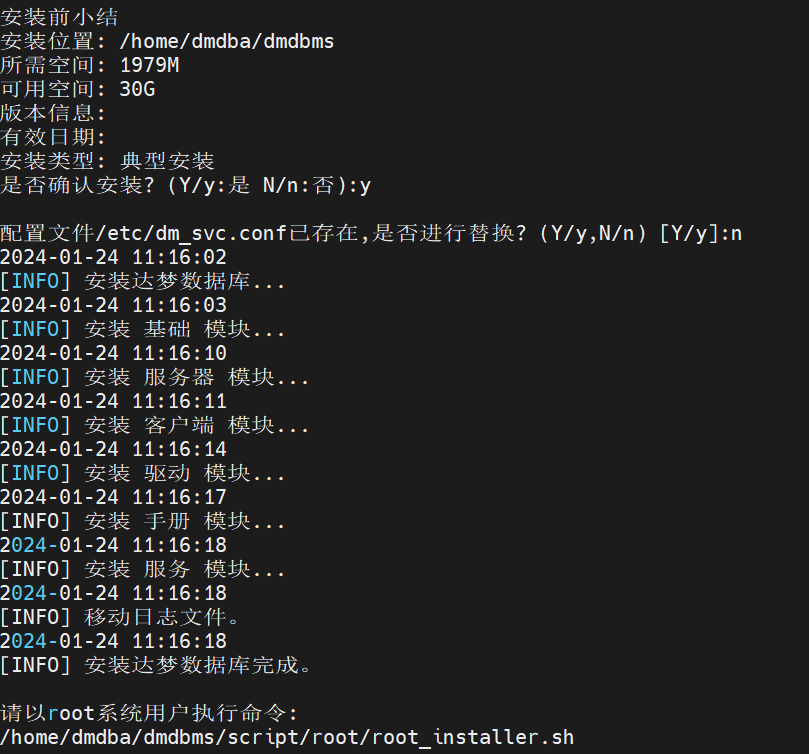
数据库安装大概 1~2 分钟,数据库安装完成后,显示如下界面。
|
||||
|
||||
|
||||
|
||||
数据库安装完成后,需要切换至 root 用户执行上图中的命令 `/home/dmdba/dmdbms/script/root/root_installer.sh` 创建 DmAPService,否则会影响数据库备份。
|
||||
|
||||

|
||||
|
||||
数据库安装完成后还需注册实例才能使用数据库,注册实例可参考[配置实例](https://eco.dameng.com/document/dm/zh-cn/start/dm-instance-linux)章节。
|
||||
|
||||
## 四、图形化安装
|
||||
|
||||
启用图形化安装界面前需要通过如下命令将图形界面权限放开:
|
||||
|
||||
Copy`[root@localhost mnt]# xhost + access control disabled, clients can connect from any host [root@localhost mnt]# echo $DISPLAY [root@localhost mnt]# su - dmdba Last login: 四 1月 25 16:41:51 CST 2024 on pts/1 [dmdba@localhost ~]$ export DISPLAY=:0.0`
|
||||
|
||||
切换到 dmdba 用户,进入 /mnt 目录下,执行命令开始图形化安装。
|
||||
|
||||
Copy`[dmdba@localhost ~]$ cd /mnt [dmdba@localhost mnt]$ ./DM DM8 Install.pdf DMInstall.bin [dmdba@localhost mnt]$ ./DMInstall.bin`
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 该方法为本地调用图形化界面,如果希望通过其它机器调用该图形化界面需设置 export DISPLAY=调用图形化机器的IP:0.0,例如,数据库安装机器 IP 为 10.10.12.25,需要在 IP 为 192.132.32.12 的机器上调用图形化界面,需要设置 export DISPLAY=192.132.32.12:0.0
|
||||
|
||||
若初始化图形界面失败,当前监视器窗口不支持图形界面,请进入安装文件所在文件夹并使用"./DMInstall.bin -i"进行命令行安装。
|
||||
|
||||
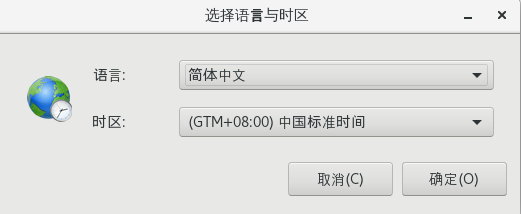
图形化界面启动成功后,将弹出【选择语言与时区】页面,默认为简体中文和中国标准时间。
|
||||
|
||||
|
||||
|
||||
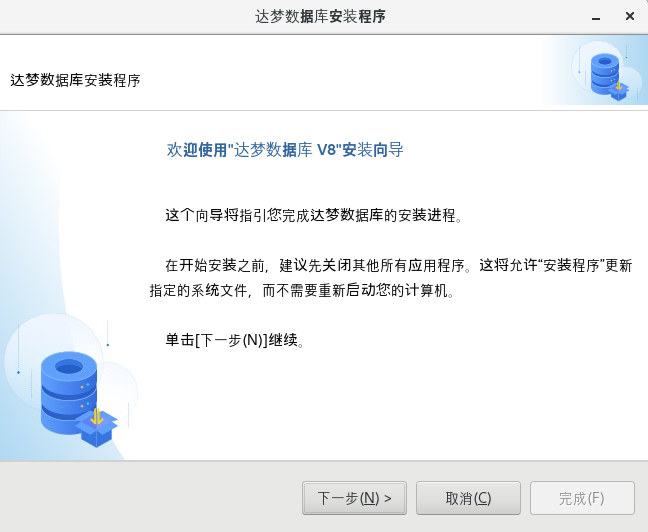
点击【确定】后,弹出 DM 数据库安装程序。
|
||||
|
||||
|
||||
|
||||
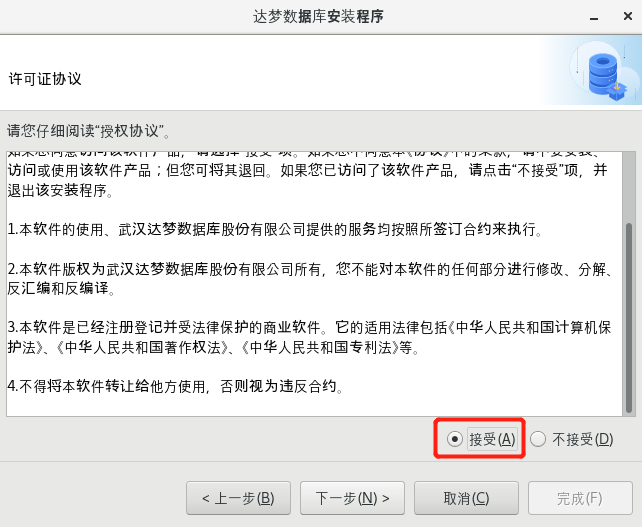
点击【下一步】后,为许可证协议页面,选择【接受】。
|
||||
|
||||
|
||||
|
||||
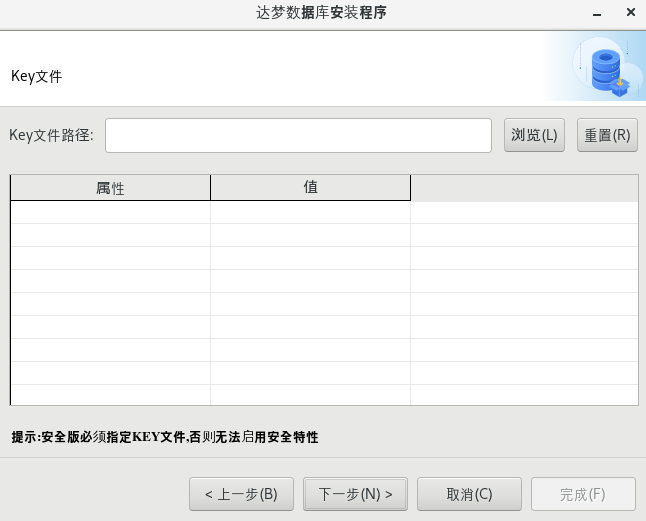
点击【下一步】后,弹出 key 文件页面,点击【浏览】选择【key 文件】,若**没有 key 文件**可以直接点击【下一步】,跳过该步骤。
|
||||
|
||||
|
||||
|
||||
点击【下一步】后,弹出选择组件页面,建议选择**典型安装**,也可根据需要,选择服务器安装、客户端安装和自定义安装。
|
||||
|
||||
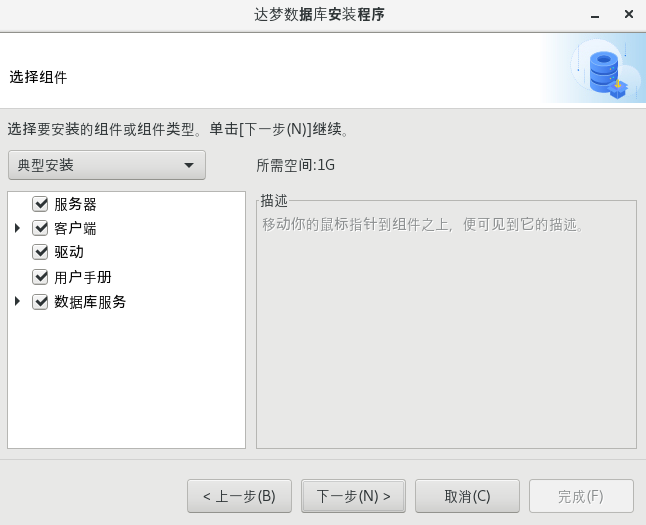
|
||||
|
||||
点击【下一步】后,弹出选择安装位置页面,可点击【浏览】选择安装位置,也可安装在默认路径下。
|
||||
|
||||
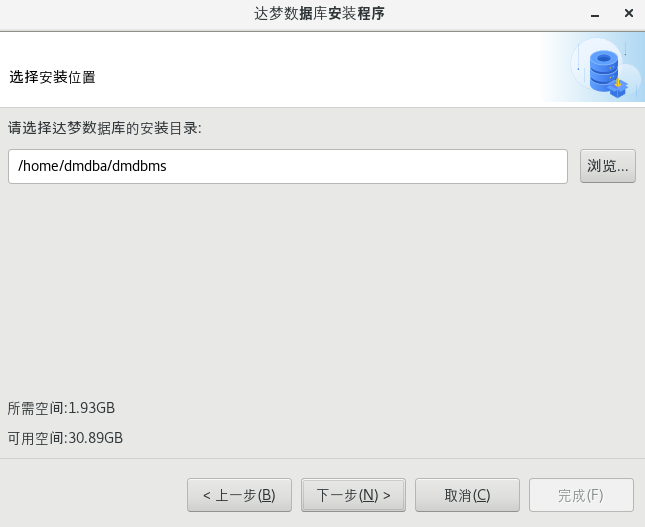
|
||||
|
||||
点击【下一步】后,弹出确认安装信息页面,检查安装信息是否准确,确认无误后点击【安装】。
|
||||
|
||||
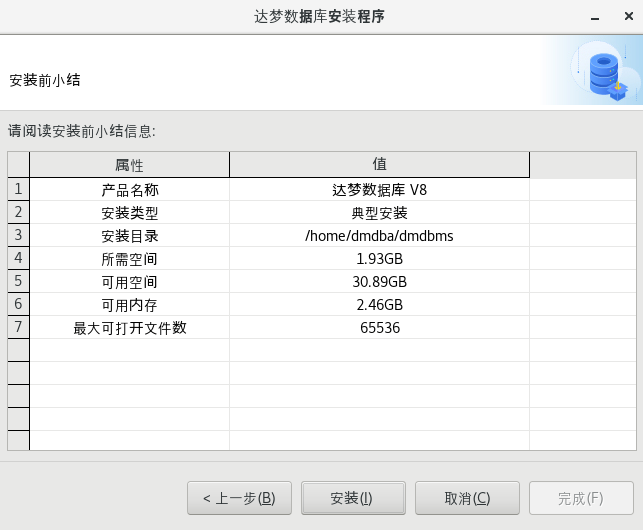
|
||||
|
||||
点击【安装】后,等待 1~2 分钟即可安装完成,安装完成后弹出执行配置脚本页面,按照页面要求执行该脚本即可。
|
||||
|
||||
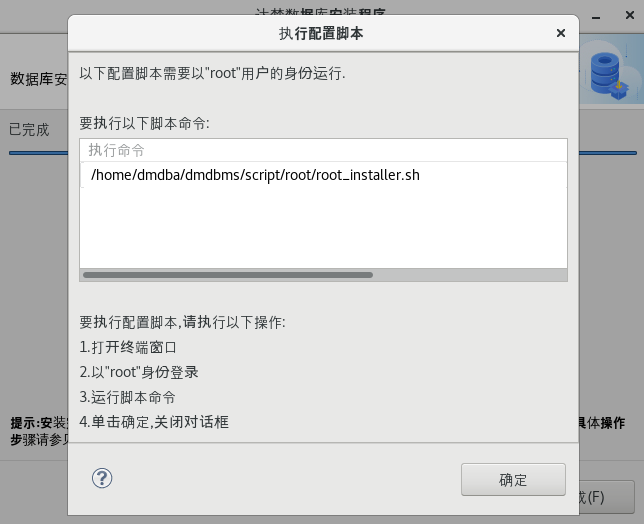
|
||||
|
||||
重新打开一个终端,切换到 root 用户,执行弹出页面中的脚本。
|
||||
|
||||

|
||||
|
||||
脚本执行完成后,点击执行配置脚本页面中的【完成】,弹出提示框,提示是否关闭窗口,选择是,提示数据库安装完成,再点击【完成】按钮,完成数据库安装。
|
||||
|
||||

|
||||
|
||||
## 五、配置环境变量
|
||||
|
||||
切换到 root 用户进入 dmdba 用户的根目录下,配置对应的环境变量。DM\_HOME 变量和动态链接库文件的加载路径在程序安装成功后会自动导入。命令如下:
|
||||
|
||||
Copy`export PATH=$PATH:$DM_HOME/bin:$DM_HOME/tool`
|
||||
|
||||
编辑 .bash\_profile,使其最终效果如下图所示:
|
||||
|
||||
Copy`cd /home/dmdba/`
|
||||
|
||||
Copy`vim .bash_profile`
|
||||
|
||||
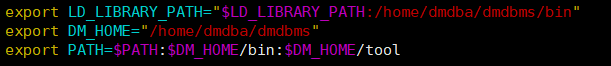
|
||||
|
||||
切换至 dmdba 用户下,执行以下命令,使环境变量生效。
|
||||
|
||||
Copy`su - dmdba`
|
||||
|
||||
Copy`source .bash_profile`
|
||||
|
||||
若需要主动打开配置助手,可使用 dmdba 用户配置实例,进入到 DM 数据库安装目录下的 tool 目录中,使用 `./dbca.sh` 命令打开数据库配置助手。
|
||||
|
||||
启用图形界面前需要通过如下方法将图形界面权限放开:
|
||||
|
||||
Copy`[root@localhost mnt]# xhost + access control disabled, clients can connect from any host [root@localhost mnt]# echo $DISPLAY [root@localhost mnt]# su - dmdba Last login: 四 1月 25 16:41:51 CST 2024 on pts/1 [dmdba@localhost ~]$ export DISPLAY=:0.0`
|
||||
|
||||
进入 DM 安装目录下的 tool 目录,使用如下命令打开 DM 服务查看器,如下所示:
|
||||
|
||||
Copy`[dmdba@localhost ~]$ cd /home/dmdba/dmdbms/tool/ [dmdba@localhost tool]$ ll [dmdba@localhost tool]$ ./dbca.sh`
|
||||
@@ -0,0 +1,124 @@
|
||||
---
|
||||
page-title: "Docker安装 | 达梦技术文档"
|
||||
url: https://eco.dameng.com/document/dm/zh-cn/start/dm-install-docker.html
|
||||
date: "2024-09-05 08:37:13"
|
||||
---
|
||||
## 一、安装前准备
|
||||
|
||||
| 软硬件 | 版本 |
|
||||
| --- | --- |
|
||||
| 终端 | X86-64 架构 |
|
||||
| Docker | 2024 年 4 月版 |
|
||||
|
||||
## 二、下载 Docker 安装包
|
||||
|
||||
请在达梦数据库官网下载 [Docker 安装包](https://eco.dameng.com/download/)。
|
||||
|
||||
## 三、导入安装包
|
||||
|
||||
拷贝安装包到 /opt 目录下,执行以下命令导入安装包:
|
||||
|
||||
Copy`docker load -i dm8_20240422_x86_rh6_64_rq_std_8.1.3.100_pack2.tar`
|
||||
|
||||
结果显示如下:
|
||||
|
||||
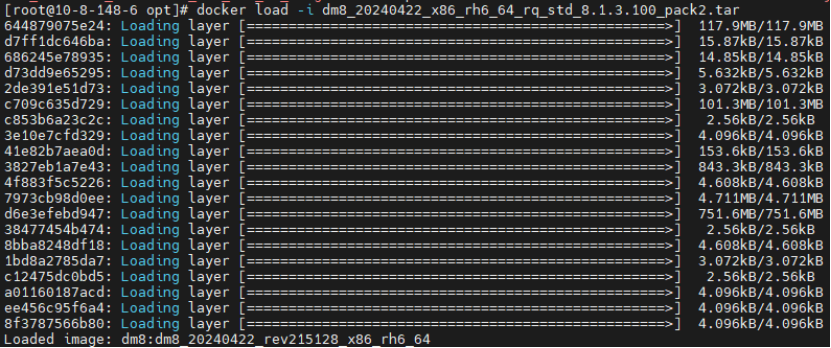
|
||||
|
||||
导入完成后,可以使用 `docker images` 查看导入的镜像。结果显示如下:
|
||||
|
||||

|
||||
|
||||
## 四、启动容器
|
||||
|
||||
镜像导入后,使用 `docker run` 启动容器,启动命令如下:
|
||||
|
||||
Copy`docker run -d -p 30236:5236 --restart=always --name=dm8_test --privileged=true -e LD_LIBRARY_PATH=/opt/dmdbms/bin -e PAGE_SIZE=16 -e EXTENT_SIZE=32 -e LOG_SIZE=1024 -e UNICODE_FLAG=1 -e INSTANCE_NAME=dm8_test -v /opt/data:/opt/dmdbms/data dm8:dm8_20240422_rev215128_x86_rh6_64`
|
||||
|
||||

|
||||
|
||||
容器运行相关参数说明:
|
||||
|
||||
| 参数名 | 参数描述 |
|
||||
| --- | --- |
|
||||
| \-d | \-detach 的简写,在后台运行容器,并且打印容器 id。 |
|
||||
| \-p | 指定容器端口映射,比如 -p 30236:5236 是将容器里数据库的 5236 端口映射到宿主机 30236 端口,外部就可以通过宿主机 ip 和 30236 端口访问容器里的数据库服务。 |
|
||||
| \--restart | 指定容器的重启策略,默认为 always,表示在容器退出时总是重启容器。 |
|
||||
| \--name | 指定容器的名称。 |
|
||||
| \--privileged | 指定容器是否在特权模式下运行。 |
|
||||
| \-v | 指定在容器创建的时候将宿主机目录挂载到容器内目录,默认为/home/mnt/disks |
|
||||
|
||||
使用 -e 命令指定数据库初始化参数时,需要注意的是目前只支持预设以下九个 DM 参数。
|
||||
|
||||
| 参数名 | 参数描述 | 备注 |
|
||||
| --- | --- | --- |
|
||||
| PAGE\_SIZE | 页大小,可选值 4/8/16/32,默认值:8 | 设置后不可修改 |
|
||||
| EXTENT\_SIZE | 簇大小,可选值 16/32/64,默认值:16 | 设置后不可修改 |
|
||||
| CASE\_SENSITIVE | 1:大小写敏感;0:大小写不敏感,默认值:1 | 设置后不可修改 |
|
||||
| UNICODE\_FLAG | 字符集选项;0:GB18030;1:UTF-8;2:EUC-KR,默认值:0 | 设置后不可修改 |
|
||||
| INSTANCE\_NAME | 初始化数据库实例名字,默认值:DAMENG | 可修改 |
|
||||
| SYSDBA\_PWD | 初始化实例时设置 SYSDBA 的密码,默认值:SYSDBA001 | 可修改 |
|
||||
| BLANK\_PAD\_MODE | 空格填充模式,默认值:0 | 设置后不可修改 |
|
||||
| LOG\_SIZE | 日志文件大小,单位为:M,默认值:256 | 可修改 |
|
||||
| BUFFER | 系统缓存大小,单位为:M,默认值:1000 | 可修改 |
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 1.SYSDBA\_PWD 预设的时候,密码长度为 9~48 个字符,docker 版本使用暂不支持特殊字符为密码。
|
||||
> 2.-e 设置的时候 初始化参数必须使用大写,不可使用小写。
|
||||
|
||||
通过以下命令可以查看 Docker 镜像中数据库初始化的参数。
|
||||
|
||||
Copy`docker inspect dm8_test`
|
||||
|
||||
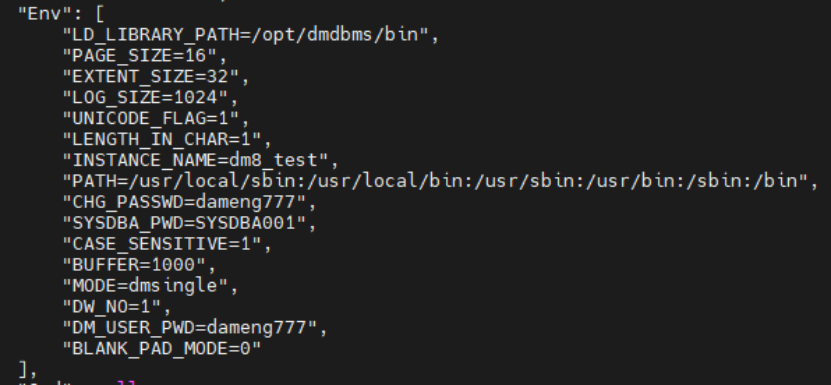
|
||||
|
||||
找到 Env 项可以看到在数据库初始化时设置的参数值,包括页大小(PAGE\_SIZE)、簇大小(EXTENT\_SIZE)、字符集(UNICODE\_FLAG)、默认密码(SYSDBA\_PWD)等。更多数据库初始化实例参数解释可参考达梦数据库安装目录下 doc 目录中《DM8\_dminit 使用手册》。
|
||||
|
||||
容器启动完成后,使用命令 `docker ps` 查看镜像的启动情况,结果显示如下:
|
||||
|
||||

|
||||
|
||||
启动完成后,可通过日志检查启动情况,命令如下:
|
||||
|
||||
Copy`docker logs -f dm8_test 或 docker logs -f a1d3053287b2`
|
||||
|
||||
结果显示如下:
|
||||
|
||||
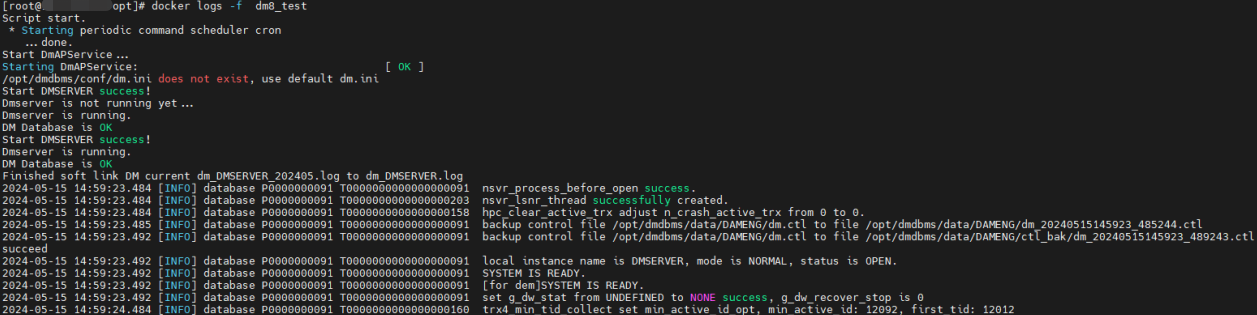
|
||||
|
||||
## 五、启动/停止数据库
|
||||
|
||||
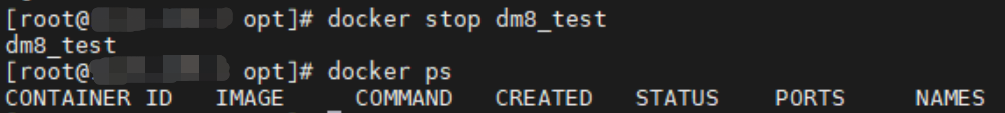
停止数据库命令如下:
|
||||
|
||||
Copy`docker stop dm8_test`
|
||||
|
||||
|
||||
|
||||
启动数据库命令如下:
|
||||
|
||||
Copy`docker start dm8_test`
|
||||
|
||||

|
||||
|
||||
重启命令如下:
|
||||
|
||||
Copy`docker restart dm8_test`
|
||||
|
||||

|
||||
|
||||
## 六、进入 DM8 容器连接数据库
|
||||
|
||||
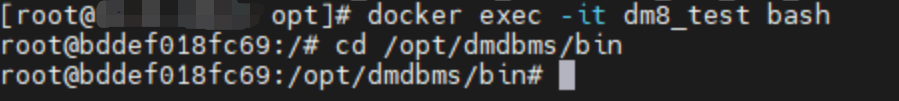
通过以下命令进入容器:
|
||||
|
||||
Copy`docker exec -it dm8_test bash`
|
||||
|
||||
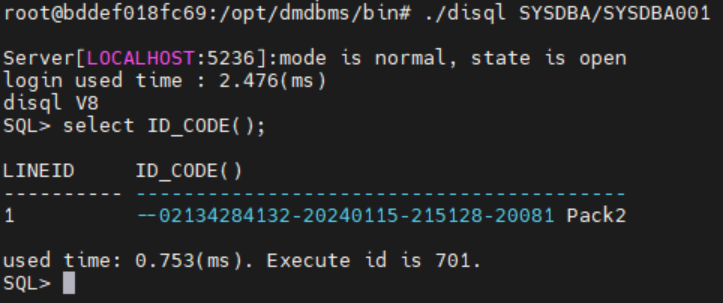
连接数据库:
|
||||
|
||||
Copy`./disql SYSDBA/SYSDBA001`
|
||||
|
||||
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 1.如果使用 docker 容器里面的 disql,进入容器后,先执行 source /etc/profile 防止中文乱码。
|
||||
> 2.新版本 Docker 镜像中数据库默认用户名/密码为 SYSDBA/SYSDBA001。
|
||||
+164
@@ -0,0 +1,164 @@
|
||||
---
|
||||
page-title: "How to Upgrade Ubuntu from 20.04 to 22.04 (Step by Step)"
|
||||
url: https://cloudinfrastructureservices.co.uk/how-to-upgrade-ubuntu-from-20-04-to-22-04-step-by-step/
|
||||
date: "2024-09-11 15:27:35"
|
||||
---
|
||||
How to Upgrade Ubuntu from 20.04 to 22.04 (Step by Step). In this post, we show you how to upgrade Ubuntu from 20.04 to 22.04.
|
||||
|
||||
[Ubuntu 22.04 LTS](https://releases.ubuntu.com/jammy) also called Jammy Jellyfish was released on April 21, 2022, by [Canonical](https://canonical.com/). It is also long term support version and supported until April 2027. Ubuntu 22.04 comes with a new enhancement, a number of software packages, and some powerful features that make your life easier.
|
||||
|
||||
- PHP 8.1.2
|
||||
|
||||
- Python 3.10.4
|
||||
|
||||
- [MySQL](https://cloudinfrastructureservices.co.uk/how-to-setup-mysql-server-phpmyadmin-on-linux-in-azure-aws-gcp/) 8.0.28
|
||||
|
||||
- OpenSSL 3.0
|
||||
|
||||
- Linux kernel v5.15.0-25 & MESA 22
|
||||
|
||||
- Ruby 3.0
|
||||
|
||||
- [PostgreSQL](https://cloudinfrastructureservices.co.uk/how-to-setup-install-postgresql-server-on-azure-aws-gcp/) 14.2
|
||||
|
||||
## New Features in Ubuntu 22.04
|
||||
|
||||
Ubuntu 22.04 comes with many useful features and changes. Some of them are listed below:
|
||||
|
||||
- **GNOME 42** – Ubuntu 22.04 comes with the latest [GNOME 42](https://release.gnome.org/42/) version with a user-friendly interface and several customize options. It also comes with a new screenshot tool for both video recording of desktop and screencast.
|
||||
|
||||
- **Dock Mode** – This feature allows you to change the size of the dock as per your need. Also use it with auto hide feature.
|
||||
|
||||
- **Multitasking Setting** – With this new feature, you don’t need any GNOME tweak tool to access this setting. You can easily enable hot corners using this feature.
|
||||
|
||||
- **Desktop Icons** – In this feature, the position of the new desktop icons is now in the bottom right corner.
|
||||
|
||||
- **Control Mounted Device** – This feature allows you to control the behaviour of mounted drives in the dock. Show or hide the mounted device as per your requirement.
|
||||
|
||||
- **Multimonitor settings** – This feature only supports two monitor setup only. It allows you to get the option to join displays, mirror them or use only one of them.
|
||||
|
||||
- **Raspberry Pi Support** – Ubuntu 22.04 desktop version is now supported on Raspberry Pi devices. However, it can work only on 8 GB [Raspberry Pi](https://www.raspberrypi.org/) version.
|
||||
|
||||
- **Native RDP support** – Ubuntu 22.04 comes with Remina software pre-installed. Use this tool to connect Windows system via [RDP protocol](https://cloudinfrastructureservices.co.uk/how-does-remote-desktop-protocol-work-rdp-protocol-explained/).
|
||||
|
||||
## Types of Upgrade
|
||||
|
||||
There are two methods to upgrade to Ubuntu 22.04 version. The clean upgrade method and inline upgrade method.
|
||||
|
||||
### Clean Upgrade
|
||||
|
||||
In this method, you will need to download the Ubuntu 22.04 [ISO](https://www.iso.org/home.html) image from their official download page, then boot your system from the ISO. Following that you need to format your existing installation and then install the newer version of Ubuntu on your system. Advice: this method is not suitable, because you need to backup all your configuration file and reinstall all necessary software on the new system.
|
||||
|
||||
### Inline Upgrade
|
||||
|
||||
In this method, you upgrade your existing system without losing any configuration files and reinstalling applications. Perform an [inline upgrade](https://cloudinfrastructureservices.co.uk/ubuntu-vs-linux-whats-the-difference/) via GUI or CLI method. This method downloads and installs all packages and a new releases of the operating system on the same system. Compared to a clean upgrade, this method is the fasted method to perform the upgrade.
|
||||
|
||||
## How to Upgrade Ubuntu from 20.04 to 22.04 (Step by Step)
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/How-to-Upgrade-Ubuntu-from-20.04-to-22.04-Step-by-Step.png)
|
||||
|
||||
In this section we navigate you through steps how to upgrade from Ubuntu 20.04 to Ubuntu 22.04.
|
||||
|
||||
### Prerequisites
|
||||
|
||||
Before you start with the system upgrade process, please check the following requirements. If anything missing from the below list, you must implement it before the upgrade process.
|
||||
|
||||
- A root user or a user with sudo privileges is configured on your server with [SSH access](https://cloudinfrastructureservices.co.uk/vpn-vs-ssh-whats-the-difference/).
|
||||
|
||||
- Minimum 20 GB of free disk space available on your system.
|
||||
|
||||
- Fast and stable internet connection to perform the upgrade.
|
||||
|
||||
- Close all running applications.
|
||||
|
||||
### Backup Your Important Data
|
||||
|
||||
Before upgrading your system, it is always recommended to backup your files and directory and place them in a safe location. So if your upgrade process failed then you don’t worry about losing your data. If your server is hosted on the [VPS](https://www.ibm.com/in-en/topics/vps) or VM then create a [snapshot](https://snapshot.org/) of your VM to VPS. So that you can restore it easily in the event of a failed upgrade.
|
||||
|
||||
### Update and Upgrade Existing Packages
|
||||
|
||||
First, get a list of all packages that needs upgrade using the following command.
|
||||
|
||||
Next, update the system package cache using the following command.
|
||||
|
||||
Now, upgrade all the packages to the latest version with the following command.
|
||||
|
||||
This will take some time to upgrade all the packages to the latest version. After the successful upgrade, restart your system to use the latest kernel that comes with the new upgrade.
|
||||
|
||||
Next, remove all unwanted packages, dependencies and cache with the following command.
|
||||
|
||||
Once you are done, please proceed to the next step.
|
||||
|
||||
### Verify the Existing Server Version
|
||||
|
||||
You also need to verify your existing server version. Easily upgrade it to the newer version. First, get a list of all upgradable packages using the following command.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/check-ubuntu-20.04-version.png)
|
||||
|
||||
### Allow Port 1022 Through UFW
|
||||
|
||||
By default, [SSH](https://www.ucl.ac.uk/isd/what-ssh-and-how-do-i-use-it) uses port 22. However, during the upgrade process, Ubuntu starts the SSH service on port 1022. Connect to your server via SSH if anything goes wrong.
|
||||
|
||||
If you are using the [UFW](https://help.ubuntu.com/community/UFW) [firewall](https://cloudinfrastructureservices.co.uk/top-15-best-open-source-firewalls-for-linux-windows/) and upgrading your server via SSH connection then you will also need to allow port 1022 via UFW. Allow port 1022 with the following command.
|
||||
|
||||
Then, reload the UFW firewall to apply the changes.
|
||||
|
||||
Once you are done proceed to the next step.
|
||||
|
||||
## Upgrade Ubuntu 20.04 to Ubuntu 22.04
|
||||
|
||||
First, install the update-manger-core package on your system with the following command.
|
||||
|
||||
```
|
||||
apt install ubuntu-release-upgrader-core -y
|
||||
```
|
||||
|
||||
Then, start the upgrade process with the following command.
|
||||
|
||||
If there is not any latest version available then you should see the following screen.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/error-getting-upgrade-release.png)
|
||||
|
||||
Otherwise, you will be notified that an additional SSH service will be started on port 1022. Simply type Y and press ENTER to proceed.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/ssh-service-notice.png)
|
||||
|
||||
Type **Y** and press the **Enter** key to continue. You should see another message. Just press the **Enter** key. You will see the installation summary.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/installation-summary.png)
|
||||
|
||||
Type **Y** and press the **Enter** key to start downloading packages needed for the upgrade. After some time, you will be prompted “if you would like your server’s services to be restarted automatically throughout the upgrade”
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/restart-service-notice.png)
|
||||
|
||||
Type **Y** and press the **Enter** key to continue the upgrade. You will be asked to select the keyboard.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/select-keyboard.png)
|
||||
|
||||
Select your country of origin for the keyboard and press the **Enter** key. You will be asked to select the keyboard layout.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/select-keyboard-layout.png)
|
||||
|
||||
Choose your keyboard layout and press the Enter key. You will be asked “whether you wish to preserve these or replace them with the new configuration files included with Ubuntu 22.04”
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/keep-current-configuration.png)
|
||||
|
||||
Select your preferred option and press the **Enter** key. You will be asked to remove the obsolete packages from your server.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/remove-obsolete-packages.png)
|
||||
|
||||
Type **Y** and press the **Enter** key to confirm. Once the upgrade process is complete successfully, you will be asked to reboot your system on see the following screen.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/reboot-the-system.png)
|
||||
|
||||
Just, type **Y** and press the **Enter** key to restart your system.
|
||||
|
||||
At this point, your server is upgraded from Ubuntu 20.04 to Ubuntu 22.04. Now verify the upgraded system version. Run the following command to verify the newer version.
|
||||
|
||||
You should see the following screen.
|
||||
|
||||
[](https://net.cloudinfrastructureservices.co.uk/wp-content/uploads/2023/03/verify-ubuntu-upgrade.png)
|
||||
|
||||
## How to Upgrade Ubuntu from 20.04 to 22.04 (Step by Step) Conclusion
|
||||
|
||||
Congratulations! Your Ubuntu is now upgraded to Ubuntu 22.04. Explore and enjoy new features that come with Ubuntu. Also, investigate your application configuration file and services whether all are working fine or not.
|
||||
@@ -0,0 +1,110 @@
|
||||
---
|
||||
page-title: "麒麟V10(arm64/aarch64)离线安装docker – Jason's Blog"
|
||||
url: http://www.884358.com/kylinos-docker/
|
||||
date: "2024-09-25 13:43:43"
|
||||
---
|
||||
[跳至正文](http://www.884358.com/kylinos-docker/#content)
|
||||
|
||||
## 下载docker离线包
|
||||
|
||||
下载地址:[https://download.docker.com/linux/static/stable/](https://download.docker.com/linux/static/stable/ "https://download.docker.com/linux/static/stable/")
|
||||
选择系统架构对应的文件目录:`aarch64`
|
||||
|
||||
我目前使用的docker版本是:`docker-24.0.7.tgz`
|
||||
|
||||
## 安装docker
|
||||
|
||||
1. `# 解压 docker 到当前目录`
|
||||
2. `tar -xvf docker-24.0.7.tgz`
|
||||
|
||||
4. `# 将 docker 文件移动到 /usr/bin 目录下`
|
||||
5. `cp -p docker/* /usr/bin`
|
||||
|
||||
## 准备 docker.service系统配置文件
|
||||
|
||||
1. `vi docker.service`
|
||||
|
||||
docker.service文件内容:
|
||||
|
||||
1. `docker.service`
|
||||
|
||||
3. `[Unit]`
|
||||
4. `Description=Docker Application Container Engine`
|
||||
5. `Documentation=https://docs.docker.com`
|
||||
6. `After=network-online.target firewalld.service`
|
||||
7. `Wants=network-online.target`
|
||||
|
||||
9. `[Service]`
|
||||
10. `Type=notify`
|
||||
11. `# the default is not to use systemd for cgroups because the delegate issues still`
|
||||
12. `# exists and systemd currently does not support the cgroup feature set required`
|
||||
13. `# for containers run by docker`
|
||||
14. `ExecStart=/usr/bin/dockerd`
|
||||
15. `ExecReload=/bin/kill -s HUP $MAINPID`
|
||||
16. `# Having non-zero Limit*s causes performance problems due to accounting overhead`
|
||||
17. `# in the kernel. We recommend using cgroups to do container-local accounting.`
|
||||
18. `LimitNOFILE=infinity`
|
||||
19. `LimitNPROC=infinity`
|
||||
20. `LimitCORE=infinity`
|
||||
21. `# Uncomment TasksMax if your systemd version supports it.`
|
||||
22. `# Only systemd 226 and above support this version.`
|
||||
23. `#TasksMax=infinity`
|
||||
24. `TimeoutStartSec=0`
|
||||
25. `# set delegate yes so that systemd does not reset the cgroups of docker containers`
|
||||
26. `Delegate=yes`
|
||||
27. `# kill only the docker process, not all processes in the cgroup`
|
||||
28. `KillMode=process`
|
||||
29. `# restart the docker process if it exits prematurely`
|
||||
30. `Restart=on-failure`
|
||||
31. `StartLimitBurst=3`
|
||||
32. `StartLimitInterval=60s`
|
||||
|
||||
34. `[Install]`
|
||||
35. `WantedBy=multi-user.target`
|
||||
|
||||
## 将 docker.service 移到 /etc/systemd/system/ 目录
|
||||
|
||||
1. `cp docker.service /etc/systemd/system/`
|
||||
2. `# 设置 docker.service 文件权限`
|
||||
3. `chmod +x /etc/systemd/system/docker.service`
|
||||
|
||||
## 启动docker
|
||||
|
||||
1. `# 重新加载配置文件`
|
||||
2. `systemctl daemon-reload`
|
||||
|
||||
4. `# 启动docker`
|
||||
5. `systemctl start docker`
|
||||
|
||||
7. `# 设置 docker 开机自启`
|
||||
8. `systemctl enable docker.service`
|
||||
|
||||
## 验证安装是否成功
|
||||
|
||||
1. `docker -v`
|
||||
|
||||
## 国内加速
|
||||
|
||||
参考http://www.884358.com/docker-cmds/#guo\_nei\_jia\_su
|
||||
|
||||
## 安装docker-compose
|
||||
|
||||
### 下载
|
||||
|
||||
下载地址:
|
||||
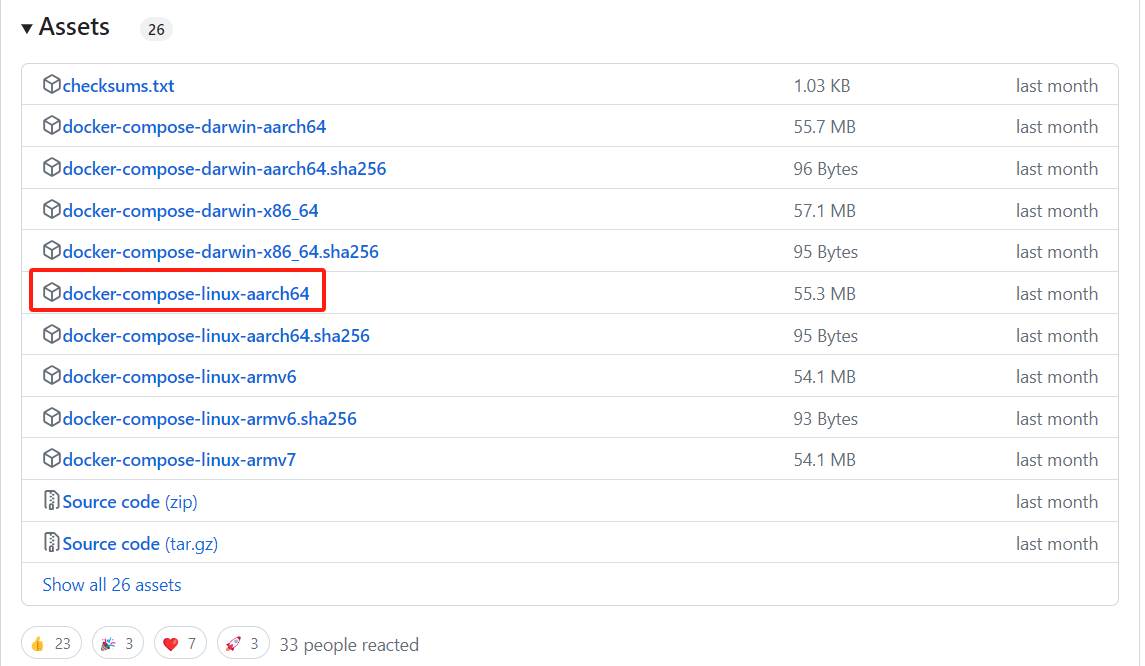
https://github.com/docker/compose/releases
|
||||
选择对应系统架构的离线安装包
|
||||
|
||||
|
||||
### 安装
|
||||
|
||||
1. `# 将 docker-compose 文件复制到 /usr/local/bin/ 目录下,并重命名为 docker-compose`
|
||||
2. `cp docker-compose-linux-aarch64 /usr/local/bin/docker-compose`
|
||||
3. `# 设置 docker-compose 文件权限`
|
||||
4. `chmod +x /usr/local/bin/docker-compose`
|
||||
|
||||
### 验证
|
||||
|
||||
1. `docker-compose -v`
|
||||
|
||||
参考:https://blog.csdn.net/qq\_23845083/article/details/130768859
|
||||
@@ -0,0 +1,212 @@
|
||||
---
|
||||
page-title: "Linux安装达梦数据库DM8 - sowler - 博客园"
|
||||
url: https://www.cnblogs.com/sowler/p/17693658.html
|
||||
date: "2024-09-05 11:19:58"
|
||||
---
|
||||
1、简介描述
|
||||
|
||||
DM8是达梦公司在总结DM系列产品研发与应用经验的基础上,坚持开放创新、简洁实用的理念,推出的新一代自研数据库。DM8吸收借鉴当前先进新技术思想与主流数据库产品的优点,融合了分布式、弹性计算与云计算的优势,对灵活性、易用性、可靠性、高安全性等方面进行了大规模改进,多样化架构充分满足不同场景需求,支持超大规模并发事务处理和事务-分析混合型业务处理,动态分配计算资源,实现更精细化的资源利用、更低成本的投入。一个数据库,满足用户多种需求,让用户能更加专注于业务发展。
|
||||
|
||||
2、下载DM8
|
||||
|
||||
达梦官网
|
||||
|
||||
找到数据库,下载DM8
|
||||
|
||||
https://www.dameng.com/list\_103.html
|
||||
|
||||
下载的时候需要选择安装操作系统,Linux操作系统就是X86,查看当前Linux版本信息
|
||||
|
||||
选择相对应的版本进行下载。下载成功是一个压缩包。
|
||||
|
||||

|
||||
|
||||
3、上传文件到Linux
|
||||
|
||||
将下载的压缩包解压并上传的/opt下面,我这里上传到:
|
||||
|
||||
4、安装DM8
|
||||
|
||||
官网可以找到达梦技术文档,根据文档步骤进行安装就没有问题。文档的安装步骤很详细。文档地址:
|
||||
|
||||
https://eco.dameng.com/document/dm/zh-cn/start/install-dm-linux-prepare.html
|
||||
|
||||
下面记录本人自己按照文档安装相关步骤及遇到的问题解决:
|
||||
|
||||
首先创建用户所在的组,命令如下:
|
||||
|
||||
创建Linux用户,命令如下:
|
||||
|
||||
useradd -g dinstall -m -d /home/dmdba -s /bin/bash dmdba
|
||||
|
||||
修改用户密码,命令如下:
|
||||
|
||||
修改系统配置,修改一下系统限制,否则之后在安装时可能报错:
|
||||
|
||||

|
||||
|
||||
vi /etc/security/limits.conf
|
||||
|
||||
dmdba hard nofile 65536
|
||||
dmdba soft nofile 65536
|
||||
dmdba hard stack 32768
|
||||
dmdba soft stack 16384
|
||||
|
||||

|
||||
|
||||
修改成功后,切换到 dmdba 用户,查看是否生效
|
||||
|
||||
查看配置:
|
||||
|
||||
如果已生效则切换的root用户挂载镜像,否则需要在dmdba设置参数临时生效:
|
||||
|
||||
挂载镜像:切换root用户进入上传的镜像目录下执行:
|
||||
|
||||
mount -o loop ./dm8\_20230418\_x86\_rh6\_64.iso /mnt
|
||||
|
||||
镜像挂载成功后,新建安装目录:dm8,本人安装在/usr/local下面(可以根据需要安装到其他位置),进入/usr/local目录:
|
||||
|
||||
将新建的安装路径目录权限的用户修改为 dmdba,用户组修改为 dinstall。命令如下:
|
||||
|
||||
chown dmdba:dinstall -R /dm8/
|
||||
|
||||
给安装路径下的文件设置 755 权限。命令如下:
|
||||
|
||||
下面开始正式安装,需要切换至 dmdba 用户下安装:
|
||||
|
||||
进入镜像挂载目录:cd /mnt/ 执行:
|
||||
|
||||

|
||||
|
||||
选择语言,安装中文语言选择C 、英文选择E。输入成功后回车下一步:
|
||||
|
||||

|
||||
|
||||
由于目前还没有购买授权密钥,key路径选择不配置。需要设置一下时区中国标准时间:21,回车下一步:
|
||||
|
||||

|
||||
|
||||
选择典型安装,配置数据库安装路径为上面新建的目录,设置完成后确认安装:
|
||||
|
||||

|
||||
|
||||
数据库安装完成后,需要切换至 root 用户执行上图中的命令进入/dm8/script/root/root\_installer.sh创建 DmAPService,否则会影响数据库备份。
|
||||
|
||||

|
||||
|
||||
5、配置环境变量
|
||||
|
||||
进入cd /home/dmdba/目录下面编辑文件 .bash\_profile
|
||||
|
||||

|
||||
|
||||
切换至 dmdba 用户下,执行以下命令,使环境变量生效。
|
||||
|
||||
su - dmdba
|
||||
|
||||
source .bash\_profile
|
||||
|
||||
6、配置实例
|
||||
|
||||
dminit 命令可设置多种参数,可执行如下命令查看可配置参数。
|
||||
|
||||
注意:页大小 (page\_size)、簇大小 (extent\_size)、大小写敏感 (case\_sensitive)、字符集 (charset) 这四个参数,一旦确定无法修改,需谨慎设置。如果需要更改只能删除实例在新建一个新的实例重新配置。
|
||||
|
||||
自定义初始化实例的参数,参考如下示例:
|
||||
|
||||
./dminit path=/usr/local/dm8/data PAGE\_SIZE=32 EXTENT\_SIZE=32 CASE\_SENSITIVE=y LENGTH\_IN\_CHAR=y CHARSET=1 DB\_NAME=DMDB INSTANCE\_NAME=DBSERVER PORT\_NUM=5236
|
||||
|
||||
以上命令设置页大小为 32 KB,簇大小为 32 KB,大小写敏感,VARCHAR类型以字符为单位,字符集为 utf\_8,数据库名为 DMDB,实例名为 DBSERVER,端口为 5236
|
||||
|
||||
相关参数说明:
|
||||
|
||||
PAGE\_SIZE:数据页大小(8),可选值:4, 8, 16, 32,单位:K
|
||||
EXTENT\_SIZE:数据文件使用的簇大小(16),可选值:16, 32, 64,单位:页
|
||||
CASE\_SENSITIVE:大小敏感(Y),可选值:Y/N,1/0
|
||||
LENGTH\_IN\_CHAR:VARCHAR类型以字符为单位
|
||||
charset 字符集选项。0 代表 GB18030;1 代表 UTF-8;2 代表韩文字符集 EUC-KR;取值 0、1 或 2 之一。默认值为 0。
|
||||
DMDB:数据库名
|
||||
INSTANCE\_NAME:实例名
|
||||
PORT\_NUM:端口默认端口 5236 ,初始化时设置 dm.ini 中的监听端口号,默认 5236 。服务器配置此参数,有效值范围(1024~65534),发起连接端的端口在1024~65535之间随机分配。可选参数。
|
||||
|
||||

|
||||
|
||||
7、注册服务
|
||||
|
||||
注册服务需使用 root 用户进行注册
|
||||
|
||||
进入安装目录cd /usr/local/dm8/script/root 执行命令:
|
||||
|
||||
./dm\_service\_installer.sh -t dmserver -dm\_ini /usr/local/dm8/data/DMDB/dm.ini -p DMSERVER
|
||||
|
||||
\-t 指定服务类型为dmserver -dm\_ini 指定配置文件路径 -p 指定服务名称
|
||||
|
||||

|
||||
|
||||
顺便写一下卸载服务命令:
|
||||
|
||||
./dm\_service\_uninstaller.sh -t dmserver -dm\_ini /usr/local/dm8/data/DMDB/dm.ini -p DMSERVER
|
||||
|
||||
执行脚本不一样,后面的参数和创建时是一样的。
|
||||
|
||||
8、通过服务启动、停止数据库
|
||||
|
||||
服务注册成功后,启动数据库,如下所示:
|
||||
|
||||
systemctl start DmServiceDMSERVER.service
|
||||
|
||||
停止数据库,如下所示:
|
||||
|
||||
systemctl stop DmServiceDMSERVER.service
|
||||
|
||||
重启数据库,如下所示:
|
||||
|
||||
systemctl restart DmServiceDMSERVER.service
|
||||
|
||||
查看数据库服务状态,如下所示:
|
||||
|
||||
systemctl status DmServiceDMSERVER.service
|
||||
|
||||

|
||||
|
||||
9、进入测试登录:
|
||||
|
||||
初始用户名:SYSDBA,密码:SYSDBA
|
||||
|
||||
进入成功,查看达梦数据库库名:
|
||||
|
||||
select name,create\_time from v$database;
|
||||
|
||||
查看数据库授权信息:
|
||||
|
||||
达梦数据库试用期限为一年,官网定期更新安装包版本期限。EXPIRED\_DATE字段信息显示过期时间:
|
||||
|
||||
select EXPIRED\_DATE from v$license;
|
||||
|
||||
一定要在截止前把数据库迁移或备份,然后官网下载最新安装包重新安装,再恢复数据。
|
||||
|
||||
刷新授权 执行:
|
||||
|
||||
将试用授权或正式光盘授权中的key文件重命名为dm.key,放到达梦数据库安装路径的bin路径中,替换原来的dm.key(建议将原来的改名备份下),最好是将给755权限,给dmdba:dinstall的用户和组权限。然后重启数据库服务,数据库会自动识别到新的授权。
|
||||
|
||||
10、连接工具:
|
||||
|
||||
连接工具可以使用官网下载的安装包进行只安装客户端工具,官网提供了多种工具。每一个工具都有不通的作用。可以自行了解。
|
||||
|
||||

|
||||
|
||||
下面介绍一个连接工具,页面简洁方便:DBeaver
|
||||
|
||||
DBeaver下载:https://dbeaver.io/download/
|
||||
|
||||
使用DBeaver连接需要配置相关驱动,官网连接驱动下载地址:
|
||||
|
||||
https://eco.dameng.com/document/dm/zh-cn/app-dev/java-MyBatis-Plus-frame.html
|
||||
|
||||
windows连接DM数据库配置:
|
||||
|
||||
https://zhuanlan.zhihu.com/p/615526878
|
||||
|
||||
mac连接DM数据库配置:
|
||||
|
||||
https://blog.csdn.net/u011019141/article/details/131111164
|
||||
@@ -0,0 +1,268 @@
|
||||
---
|
||||
page-title: "OpenXPKI - The Open Source Trustcenter Solution"
|
||||
url: https://www.openxpki.org/
|
||||
date: "2024-09-08 23:31:57"
|
||||
---
|
||||

|
||||
|
||||
## PKI Made in Germany
|
||||
|
||||
OpenXPKI is an enterprise-grade PKI/Trustcenter software for customizable and scaleable management of X.509v3 certificates, known for its flexibility, web-based management interface, workflow support, and active Open Source community.
|
||||
|
||||
Established in 2009, it has grown and improved over the years, with installations serving several hundreds of thousands of certificates below dozens of issuing CAs on a single installation.
|
||||
|
||||
While running the core functionality as an Open Source project, the team behind the project offers consulting, setup and operational support as well as several add-on modules for integrating certificate management into existing ITSM infrastructures.
|
||||
|
||||
|
||||
|
||||
## Certificate Lifecycle
|
||||
|
||||
Utilize customizable workflows that seamlessly guide your users through the certificate request, renewal, and revocation processes.
|
||||
|
||||
|
||||
|
||||
## Automation
|
||||
|
||||
Enable full automation of certificate distribution with industry-standard interfaces and a flexible custom API.
|
||||
|
||||
|
||||
|
||||
## Reporting
|
||||
|
||||
Stay informed about the status of your certificates at all times through our comprehensive reporting and alerting framework.
|
||||
|
||||
## OpenXPKI at a Glance
|
||||
|
||||
### Modern WebUI
|
||||
|
||||
The Ember.js based web frontend runs in all major browsers and provides easy access to the system for users, operators and administrators.
|
||||
|
||||
### Automation
|
||||
|
||||
In addition to the standard enrollment protocols SCEP, EST, SimpleCMC and ACME, a powerful REST-like API with OpenAPI support is also included.
|
||||
|
||||
### Configuration
|
||||
|
||||
Full system configuration is held in YAML files. An overlay mechanism allows easy management of environment-specific differences.
|
||||
|
||||
### Flexible Crypto Layer
|
||||
|
||||
Crypto operations are based on the renowned OpenSSL toolkit and can utilize almost any compatible Hardware Security Module (HSM).
|
||||
|
||||
### Multiple Backends
|
||||
|
||||
Operate your CA signing keys on a remote system or even delegate certificate issuance to an external CA like Digicert, Sectigo or SwissSign.
|
||||
|
||||
### SubCAs and Rollover
|
||||
|
||||
Run multiple separate CAs within a single installation and enjoy a fully-automated rollover of CA generations as a standard operational task.
|
||||
|
||||
### Integration
|
||||
|
||||
A generic API allows for easy integration with existing CMDB and ITSM systems to automate request validation, approvals and notifications.
|
||||
|
||||
### User Management
|
||||
|
||||
Seamlessly integrate your existing identity and access management using SAML, OAuth, LDAP or webserver-based SSO solutions.
|
||||
|
||||
### Workflow Driven
|
||||
|
||||
Processes are driven by workflows defined as part of the customer configuration, allowing for easy adaptation to project-specific needs.
|
||||
|
||||
### Easy Deployment
|
||||
|
||||
Deployment is as easy as installing the software using your distribution's package manager, copying and adjusting the sample configuration, loading your key material and you're ready to go!
|
||||
|
||||
### Free Open Source
|
||||
|
||||
The fully-functional software with an extensive example configuration is provided under the Apache License with friendly support via mailing list.
|
||||
|
||||
### Enterprise Ready
|
||||
|
||||
Consulting, configuration, packaging and operational support with SLA are available directly from the core developers via White Rabbit Security GmbH.
|
||||
|
||||
---
|
||||
|
||||
## OpenXPKI Mission: Empowering continuous PKI operation.
|
||||
|
||||
OpenXPKI is an enterprise grade PKI and Trustcenter software which focuses strongly on Registration Authority (RA) functionality and supporting truly continuous PKI operation in professional PKI environments of any scale and complexity. Maintained by a seasoned team of PKI experts, it offers unmatched flexibility and configurability. Rooted in a vision outlined in the [original architecture whitepaper](https://www.openxpki.org/download/OpenXPKI-Architecture-Overview.pdf), the project constantly evolves to meet modern PKI needs. Unique approaches tackle common challenges faced in professional environments, emphasizing technical abstraction over local customizations. While the [OpenXPKI Community Edition](https://github.com/openxpki/openxpki) is true Open Source, the [Enterprise Edition](https://www.whiterabbitsecurity.com/produkte/openxpki/) provides additional features, commercial support and consulting services offered by [White Rabbit Security GmbH](https://www.whiterabbitsecurity.com/).
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Enterprise Ready: Mature, standard compliant, and future-proof.
|
||||
|
||||
OpenXPKI is built upon a highly stable and mature code base, continuously maintained and upgraded by the OpenXPKI development team at White Rabbit Security GmbH. The project prioritizes adherence to open standards for seamless integration with other infrastructure components.
|
||||
|
||||
The OpenXPKI team is committed to making OpenXPKI the optimal choice for a future-proof PKI. The project remains aligned with current trends in PKI and cryptography, following up on the latest developments in the ongoing standardization of Post Quantum Cryptography. OpenXPKI is poised to provide robust support for Post Quantum Cryptography algorithms and protocols, ensuring its relevance and security for the next decades of cryptographic advancements.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Certificate Lifecycle Management: Getting back into power.
|
||||
|
||||
OpenXPKI provides robust features for managing the lifecycle of certificates, equipping PKI Registration Officers with a comprehensive toolkit for their tasks. The capabilities span from powerful GUI functions for information retrieval and metadata management to overseeing the certificate request processes.
|
||||
|
||||
This extends to automation and policy enforcement features for enrollment interfaces (SCEP, EST, ACME and OpenXPKIRPC). Custom metadata, alongside standard information like contact email addresses, can be defined and managed through the GUI, providing flexibility in grouping or querying certificates. Fully automatic end entity certificate renewal is supported across all enrollment interfaces, contingent on support by the end entities.
|
||||
|
||||
For distributed certificate management, White Rabbit Security offers CertNanny Enterprise Edition, a commercial multi-platform client-side agent that integrates seamlessly with OpenXPKI.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## PKI Realms: Run multiple logical CAs in one OpenXPKI instance.
|
||||
|
||||
OpenXPKI supports hosting multiple PKI Realms in a single instance. Each PKI Realm manages a distinct namespace of end-entity certificates and may include zero, one, or many Issuing CAs for certificate issuance within that namespace. A PKI Realm defines profiles, workflows and policies for certificate management, ensuring complete separation from other PKI Realms.
|
||||
|
||||
The actual certificate issuance can be done directly on the local system using either software keys or utilizing an HSM. It is also possible to set up OpenXPKI with the RA and CA operating on separate systems or even delegate the issuance process to an external CA. The OpenXPKI Enterprise Edition offers extensions that seamlessly integrate with DigiCert, Sectigo, and SwissSign. This enables you to efficiently manage both your browser-trusted certificates and internal certificates on a unified platform, complete with comprehensive reporting and automation capabilities.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Seamless Issuing CA Rollover: Effortless Certificate Authority rotation.
|
||||
|
||||
CA Rollovers should be easy. In fact, why even restart your PKI for that? In a PKI Realm, multiple Issuing CAs can be configured to issue certificates. OpenXPKI's core automatically selects the appropriate Issuing CA certificate for issuance based on criteria such as the highest NotBefore date. Older Issuing CA certificates are retained in passive mode and used for issuing CRLs post-rollover. This ensures seamless CA rollovers without system downtime or administrative intervention. While the mechanism defaults to automatic rollovers, administrators can also set specific dates or execute rollovers manually. As an Issuing CA's certificate nears expiration, the system automatically issues a final long-lived CRL for a smooth retirement process.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Workflow Engine: Efficiently model and execute key management processes.
|
||||
|
||||
OpenXPKI's core system offers a toolbox of simple, stateless cryptographic functions. Complex or stateful operations are modeled as workflows, ranging from one-shot reporting tasks to long-lived processes requiring manual interactions. Workflow instances can be interrupted and reinstantiated. The system includes common workflows for tasks like manual certificate requests, revocation requests, automatic enrollment, CRL issuance, and reporting. These can be modified or extended to meet specific project needs, or entirely new workflows can be modeled for non-standard requirements.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Generic Web Frontend: Intuitive interface for workflow management.
|
||||
|
||||
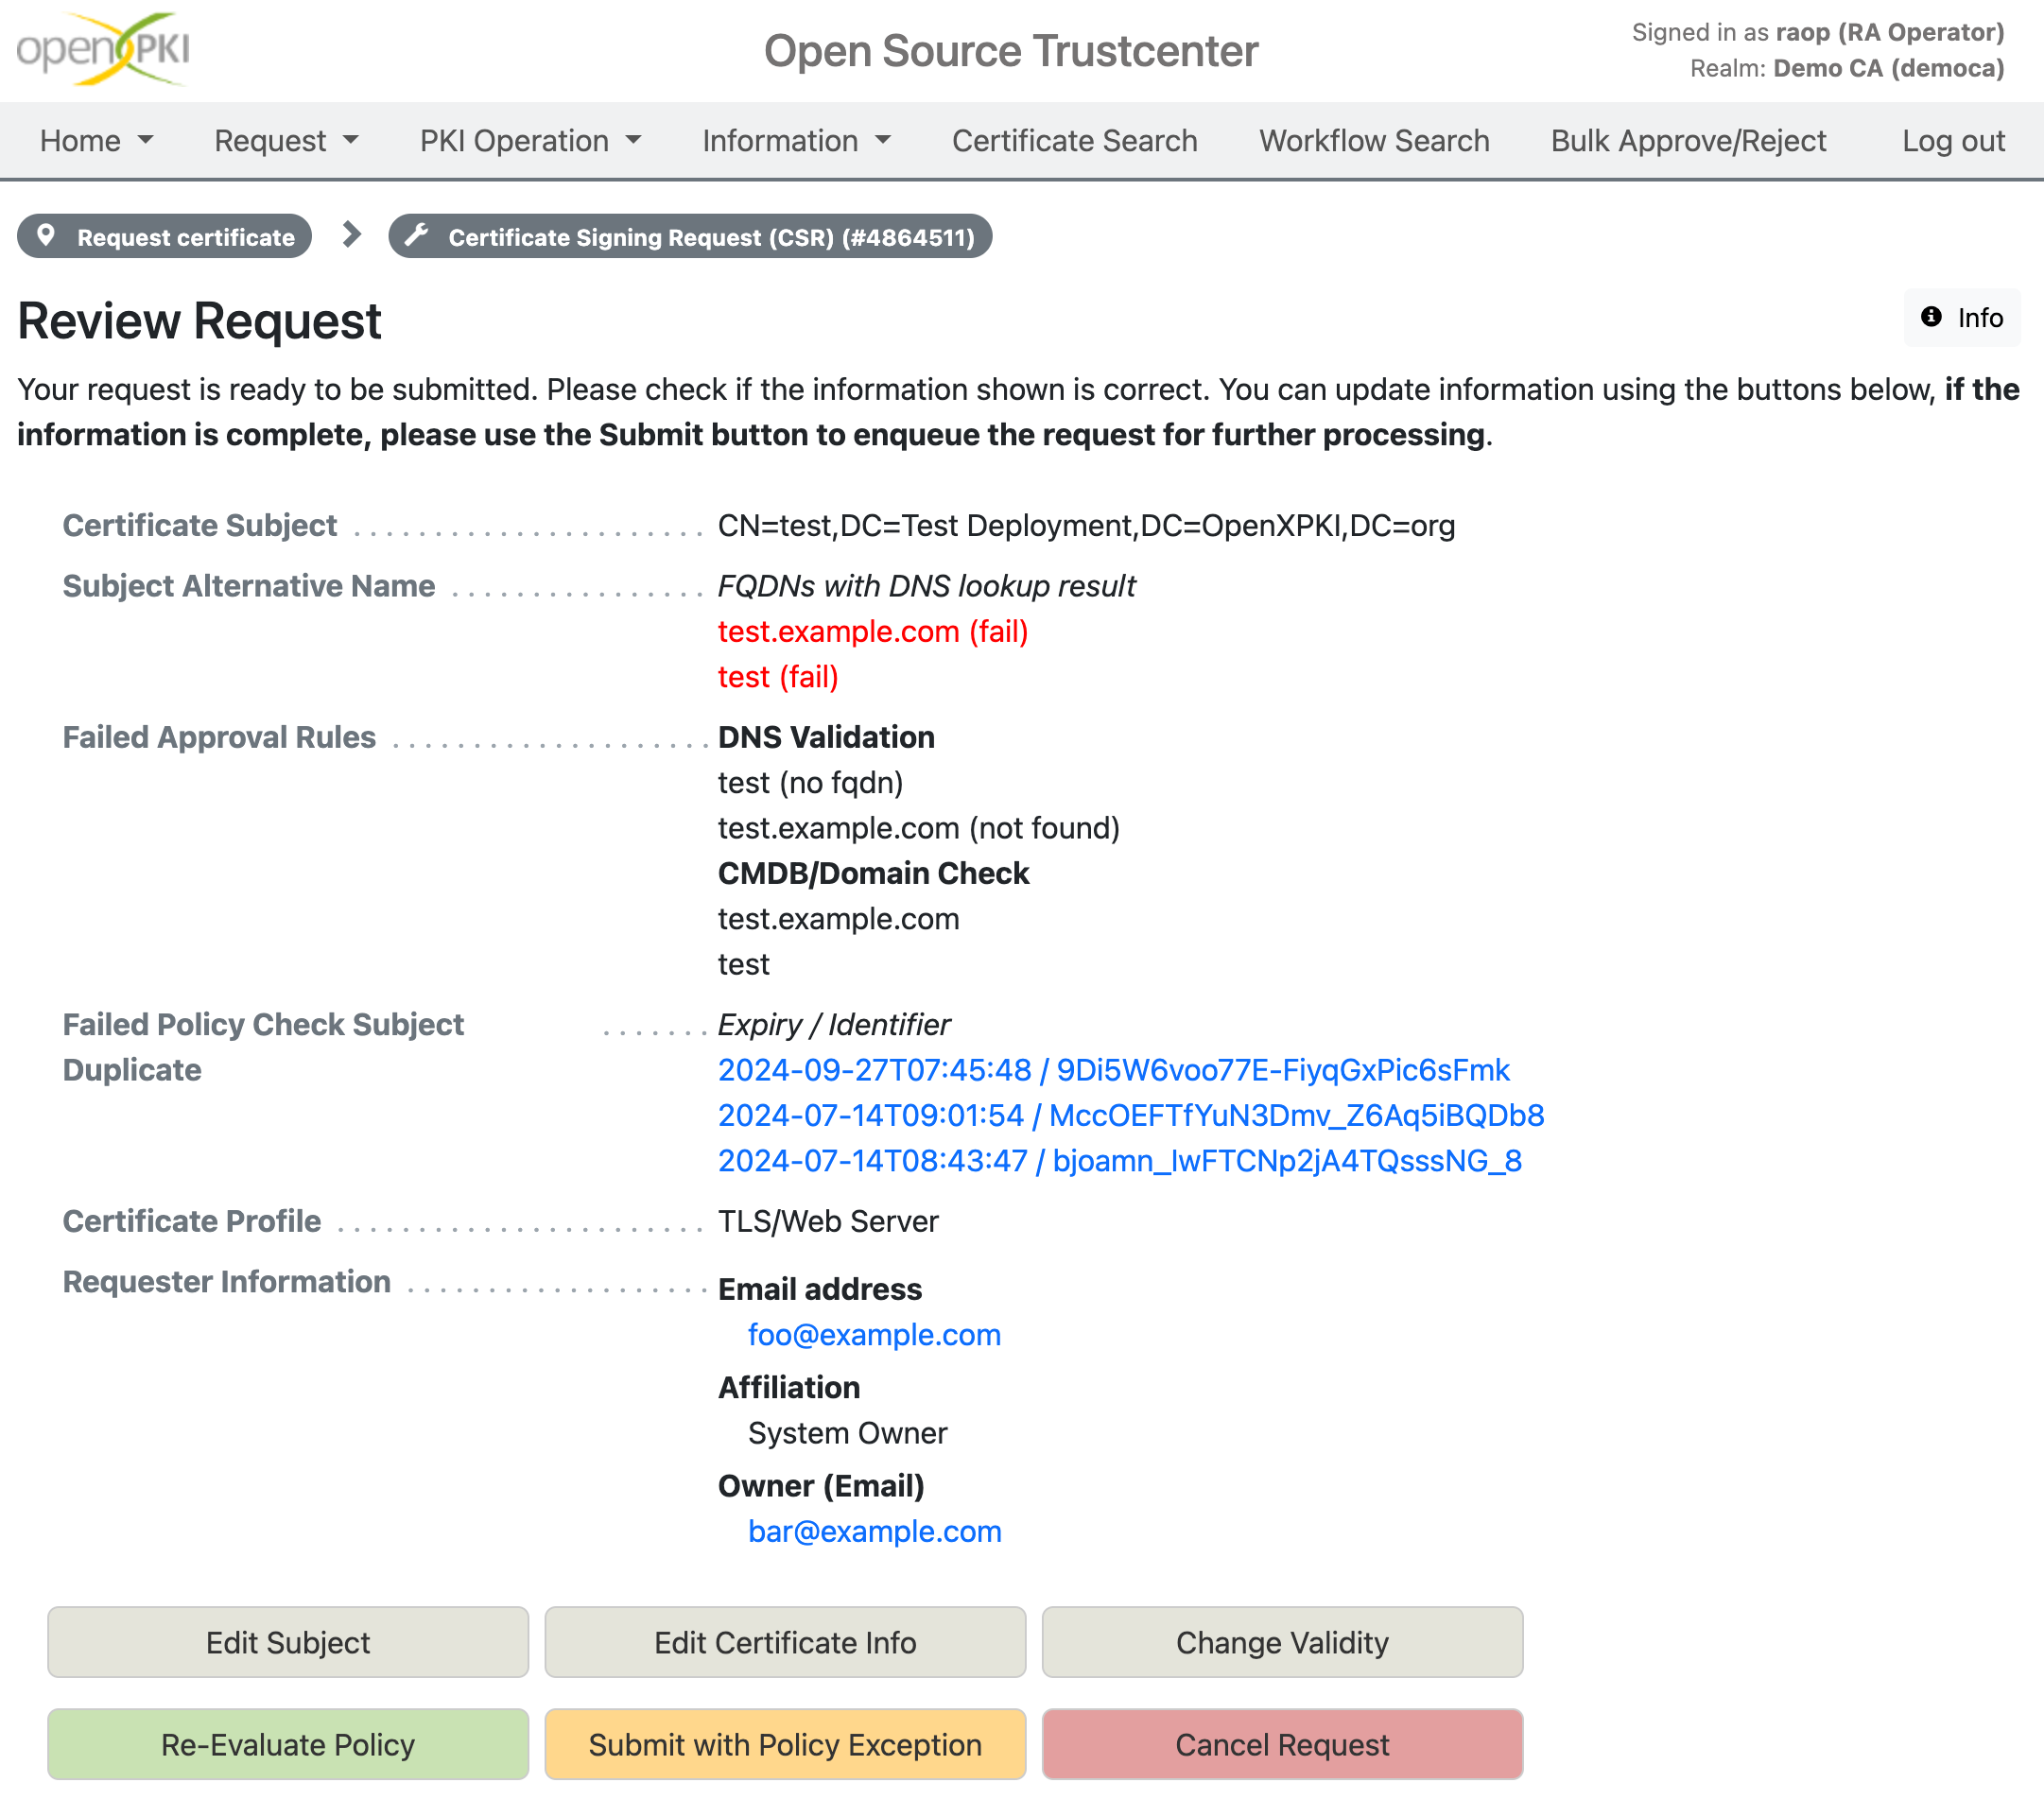
OpenXPKI boasts a robust and versatile web frontend which empowers users and administrators to interact seamlessly with the system. Access the workflow catalog, instantiate new workflows, and manage existing instances. The frontend dynamically renders the workflow's properties and current state based on its workflow definition and internal status. Defining a workflow in OpenXPKI's configuration automatically provides a suitable web-based frontend.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Infrastructure Key Protection: Enhanced security with Hardware Security Modules.
|
||||
|
||||
OpenXPKI supports Hardware Security Modules (HSMs) for robust infrastructure key protection through the PKCS#11 interface. Leveraging HSMs enhances the overall security posture of the system by providing a dedicated hardware-based solution for cryptographic key management.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Reporting: Efficiently collect and provide statistical data.
|
||||
|
||||
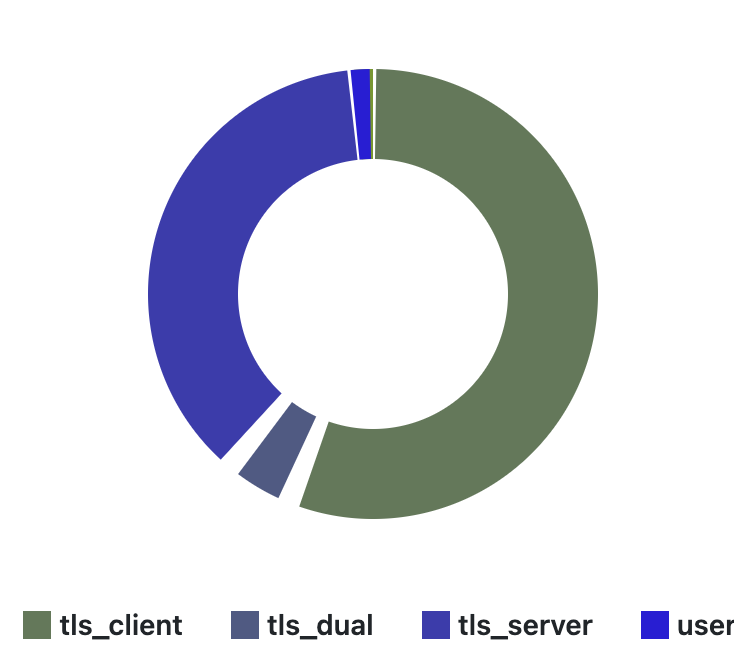
OpenXPKI features customizable reporting functions, implemented as one-shot workflows. These functions collect statistical data and provide meaningful Key Performance Indicators for the managed PKI Realms and generate downloadable CSV files containing the gathered information. This capability streamlines the process of obtaining and analyzing key statistical insights from the PKI environment.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Flexible Configuration: Manage system state auditably and verifiably.
|
||||
|
||||
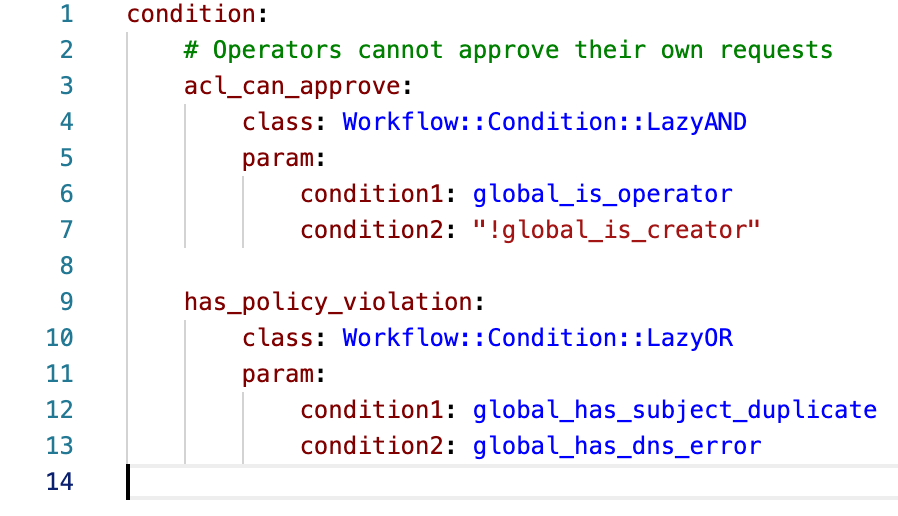
OpenXPKI's is configured through a hierarchy of YAML-format configuration files. As the entire configuration is strictly file-based, the use of a revision control system like Git for a PKI instance configuration facilitates easy management, enabling an auditable and verifiable representation of the complete system state. This approach allows test and development systems to share exactly the same configuration as the production system, with any necessary differences isolated in a single local overlay file.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Automation: Highly configurable certificate enrollment interfaces.
|
||||
|
||||
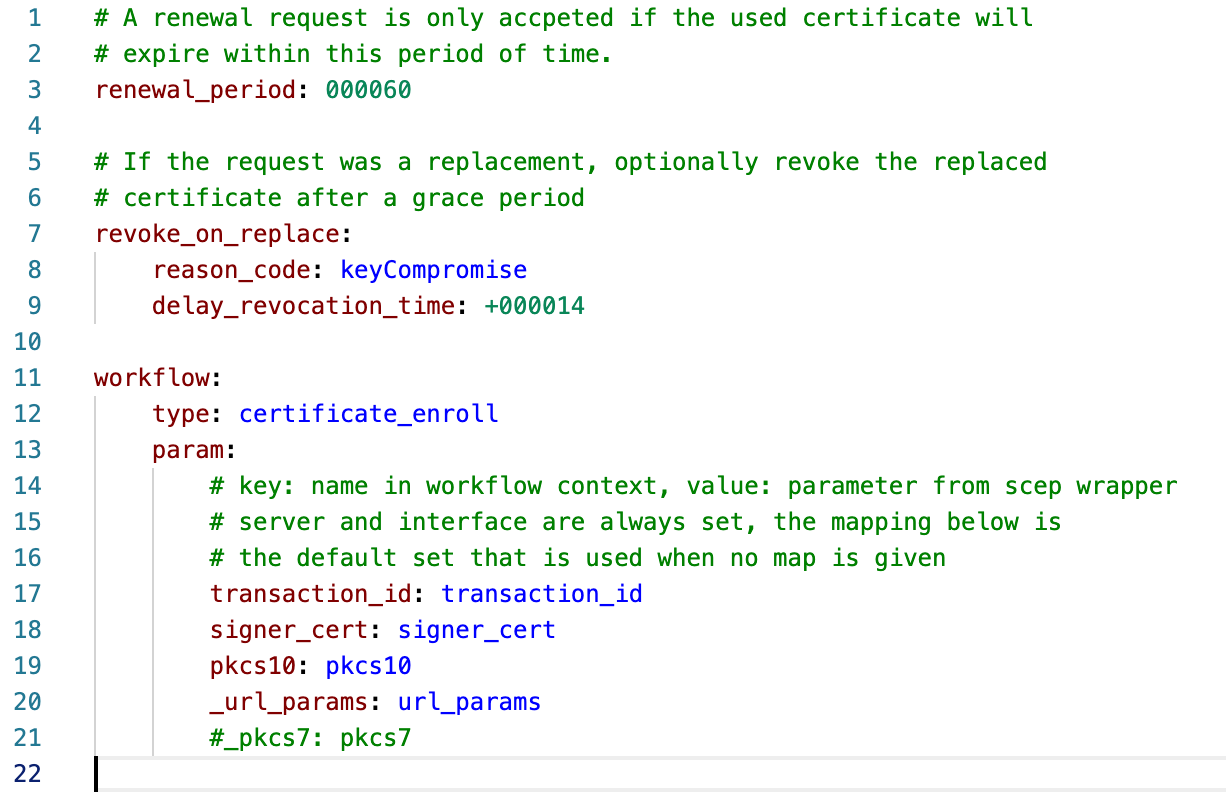
OpenXPKI's enrollment interfaces are highly flexible and configurable. They support automatic renewal based on the previous certificate's existing key and seamlessly integrate external authentication and authorization sources via the [Connector](https://www.openxpki.org/#connector) interface.
|
||||
|
||||
Following OpenXPKI's "zero, one, or many" paradigm, you can define an arbitrary number of enrollment interfaces of any type within a PKI Realm. This allows the support of individual enrollment modes for different client groups. Standard enrollment interfaces, such as SCEP, EST, and ACME, are fully supported, providing a comprehensive solution for various enrollment scenarios.
|
||||
|
||||
In conjunction with client-side tools such as CertNanny Enterprise Edition, organizations can automate request and renewal of certificates.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Connectors: Accessing external data resources.
|
||||
|
||||
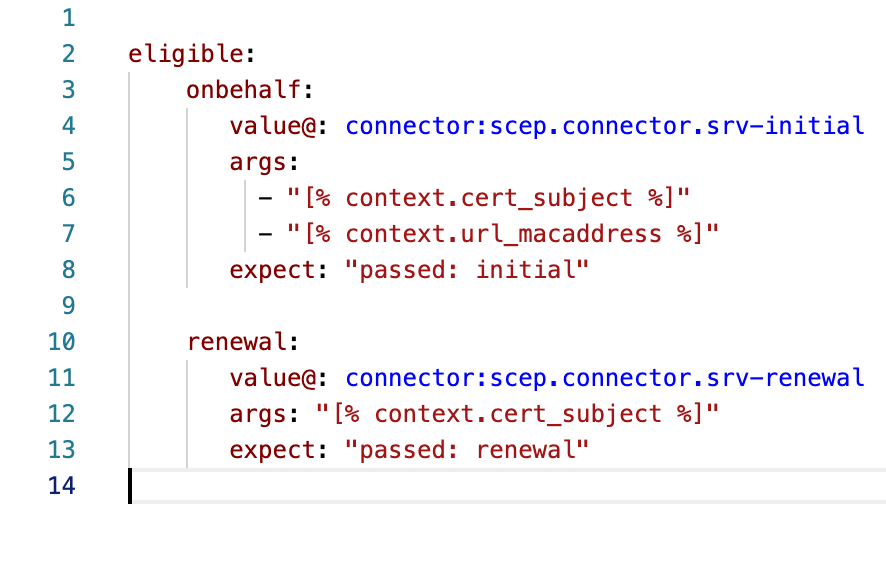
OpenXPKI introduces the powerful concept of a [Connector](http://search.cpan.org/~mrscotty/Connector/lib/Connector.pm), implementing an abstract key/value tuple interface. Configurable anywhere in the OpenXPKI configuration tree, a Connector specifies its implementation class and potential static parameters. The system, based on the provided key, resolves the implementation class, executes the query at runtime, and returns the result.
|
||||
|
||||
Connectors can replace literal configuration values throughout the entire OpenXPKI configuration, allowing for unmatched flexibility when accessing external resources. Connectors are available for various data sources such as flat files, LDAP directories, SQL databases, and web services. OpenXPKI leverages Connectors extensively, allowing attachment of external data sources for authentication, authorization, or publishing CRLs and certificates. This flexibility enables customization and seamless integration with surrounding infrastructure at a level unmatched by many competitors.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Credential Protection: Avoiding sensitive data in configuration files.
|
||||
|
||||
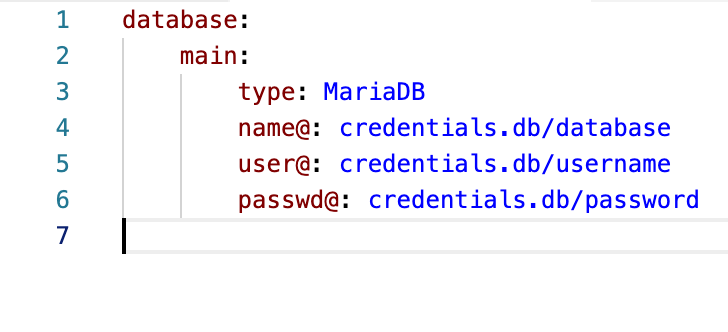
OpenXPKI allows exclusion of sensitive information, like database passwords, from (usually version-controlled) configuration files. This is achieved by either using local overlay files, or, even better, by leveraging the companion tool [KeyNanny](https://github.com/certnanny/KeyNanny). The native integration of KeyNanny, facilitated through a KeyNanny Connector, ensures secure handling of sensitive data, enhancing the overall security posture of the OpenXPKI configuration.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Expose Any Workflow: Generic RPC interface.
|
||||
|
||||
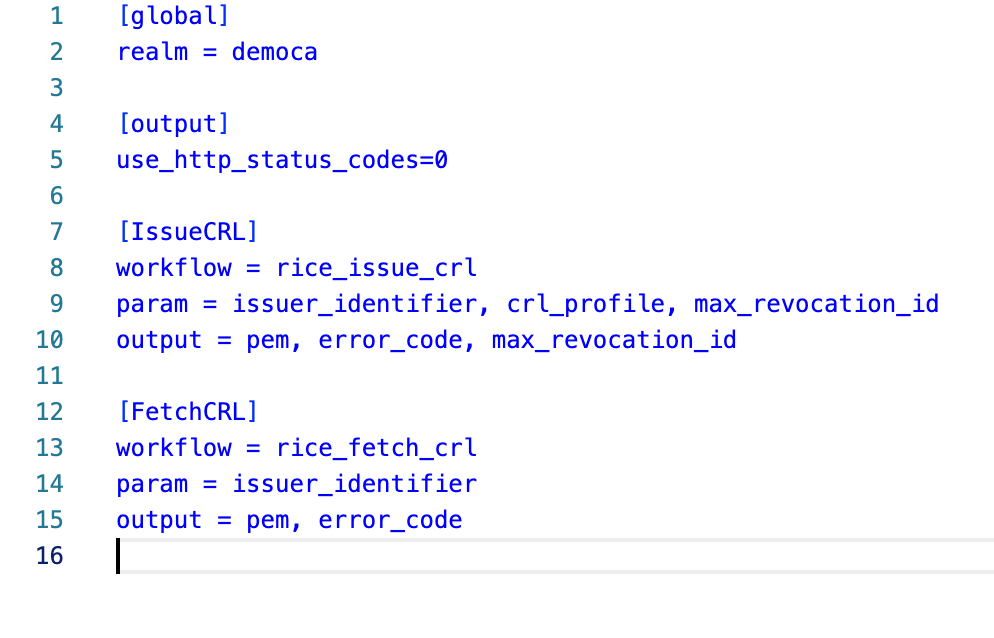
The RPC interface in OpenXPKI enables the exposure of any workflow via an RPC endpoint. Within each PKI Realm, you can define an arbitrary number of RPC API endpoints accessible through HTTP/HTTPS GET/POST requests, depending on the web server configuration. Each RPC interface can be linked to a distinct workflow for efficient RPC call processing. This allows controlled exposure of business logic implemented the Workflow Engine of OpenXPKI to consumers while leveraging the powerful key management features provided by the OpenXPKI core.
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Command Line Driven Operating: Auditable, reproducible runtime administration.
|
||||
|
||||
OpenXPKI's operational tasks are executed via the command line using a set of provided command line tools. Administrators can perform PKI tasks in a textual form, enabling the exact description of administrative actions in change task descriptions or scripts.
|
||||
|
||||
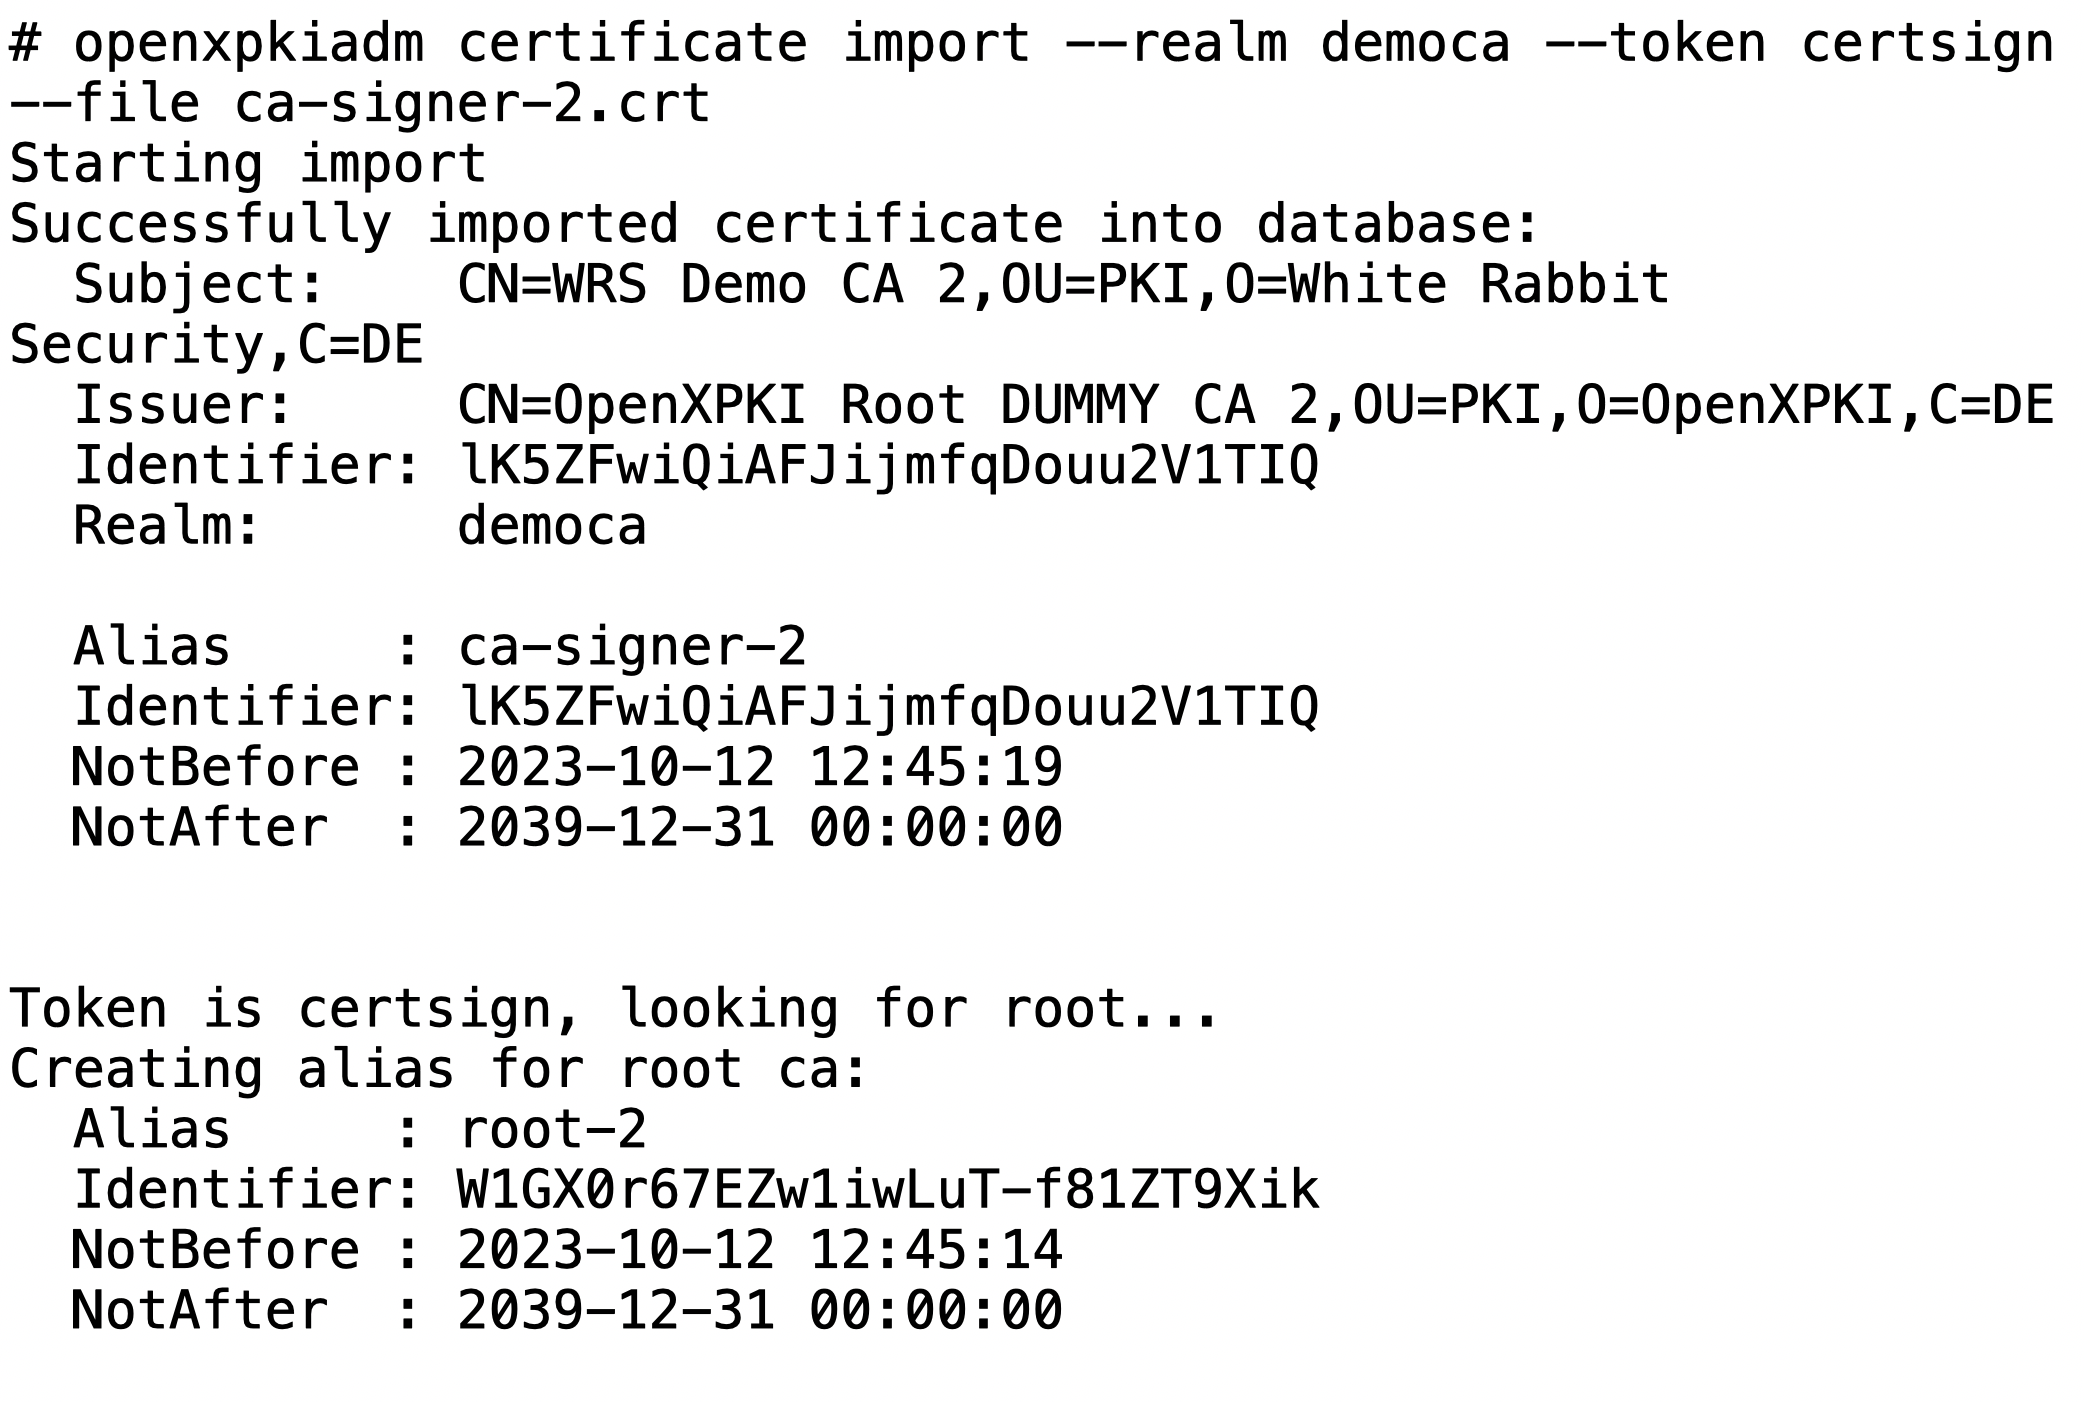
For instance, the import of a new Issuing CA certificate can be seamlessly conducted online without interrupting the OpenXPKI system. When configured properly, the system can automatically determine the correct private key for a specific CA certificate, even referencing the correct HSM-protected key when applicable. This capability facilitates performing Issuing CA rollovers without downtime and without altering the configuration, allowing the description or scripting of PKI operational tasks for ITIL-compliant change processes.
|
||||
|
||||
|
||||
|
||||
## OpenXPKI Resources
|
||||
|
||||
## Documentation
|
||||
|
||||
Documentation for OpenXPKI Community Edition is [available online via Read the Docs](https://openxpki.readthedocs.io/en/latest/). For first steps see the [quickstart manual](https://openxpki.readthedocs.io/en/latest/quickstart.html). You should also check the comments in the configuration and the man pages of the application for more details.
|
||||
|
||||
OpenXPKI Enterprise Edition comes with extensive documentation in PDF format, covering all aspects of the software in detail.
|
||||
|
||||
## Packages
|
||||
|
||||
Debian packages for the Community Edition are available from our [Debian 12 "Bookworm" package repository](https://packages.openxpki.org/v3/bookworm). A [FreeBSD Port of OpenXPKI](https://www.freshports.org/security/p5-openxpki/) exists which is not maintained by the OpenXPKI core development team, but by an independent maintainer.
|
||||
|
||||
OpenXPKI Enterprise Edition is available packaged for RedHat Enterprise Linux (RHEL), SuSE Linux Enterprise Server (SLES) and Ubuntu Server LTS.
|
||||
|
||||
## Support
|
||||
|
||||
Sharing problems and solutions with OpenXPKI Community Edition fosters the Open Source idea, and the OpenXPKI core team is committed to assist users with problems or questions that may arise with OpenXPKI Community Edition.
|
||||
|
||||
For general support questions please use the [OpenXPKI Users Mailing List](https://lists.sourceforge.net/lists/listinfo/openxpki-users) hosted by sourceforge.net. **Please do not create issues on the Github Issue Tracker for support questions.**
|
||||
|
||||
## Professional Services
|
||||
|
||||
The OpenXPKI team consists of cryptographic key management experts with vast experience designing and implementing numerous different PKIs of all scale.
|
||||
|
||||
Feel free to [reach out to the core developers](mailto:openxpki@whiterabbitsecurity.com) at [White Rabbit Security](https://www.whiterabbitsecurity.com/) for more information on OpenXPKI Enterprise Edition, professional services, and our various commercial support options.
|
||||
|
||||
## OpenXPKI Editions, Support and Service Options Overview
|
||||
|
||||
- Comprehensive, fully functional code base
|
||||
- Debian packages
|
||||
- Example configuration
|
||||
- Online documentation
|
||||
- Support via mailing list
|
||||
- 100% free
|
||||
|
||||
- RHEL/SLES/Ubuntu packages
|
||||
- Custom-built configuration
|
||||
- Powerful extension modules available (e.g., multi-tenancy, adapters to external/public CAs, full ITSM integration , GDPR compliant data retention)
|
||||
- Extensive product documentation in PDF format
|
||||
- Individual support with SLAs
|
||||
|
||||
- Health monitoring
|
||||
- Logging and reporting
|
||||
- Level-2 helpdesk
|
||||
- Full operation support
|
||||
- Cloud or OnPremise
|
||||
- Flexible licensing
|
||||
- HSM management
|
||||
- SLAs available
|
||||
@@ -0,0 +1,98 @@
|
||||
---
|
||||
page-title: "安装前准备 | 达梦技术文档"
|
||||
url: https://eco.dameng.com/document/dm/zh-cn/start/install-dm-linux-prepare.html
|
||||
date: "2024-09-05 08:31:52"
|
||||
---
|
||||
## 一、前言
|
||||
|
||||
用户在安装 DM 数据库之前需要检查或修改操作系统的配置,以保证 DM 数据库能够正确安装和运行。
|
||||
|
||||
本文演示环境如下:
|
||||
|
||||
| 操作系统 | CPU | 数据库 |
|
||||
| --- | --- | --- |
|
||||
| CentOS7 | x86\_64 架构 | dm8\_20240116\_x86\_rh7\_64 |
|
||||
|
||||
**信创环境安装部署也可以参考此篇文章,但需注意 CPU 和操作系统对应的 DM 数据库版本。**
|
||||
|
||||
## 二、新建 dmdba 用户
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 安装前必须创建 dmdba 用户,禁止使用 root 用户安装数据库。
|
||||
|
||||
1. 创建用户所在的组,命令如下:
|
||||
|
||||
Copy`groupadd dinstall -g 2001`
|
||||
|
||||
2. 创建用户,命令如下:
|
||||
|
||||
Copy`useradd -G dinstall -m -d /home/dmdba -s /bin/bash -u 2001 dmdba`
|
||||
|
||||
3. 修改用户密码,命令如下:
|
||||
|
||||
Copy`passwd dmdba`
|
||||
|
||||
## 三、修改文件打开最大数
|
||||
|
||||
在 Linux、Solaris、AIX 和 HP-UNIX 等系统中,操作系统默认会对程序使用资源进行限制。如果不取消对应的限制,则数据库的性能将会受到影响。
|
||||
|
||||
永久修改和临时修改。
|
||||
|
||||
- 重启服务器后永久生效。
|
||||
|
||||
使用 root 用户打开 `/etc/security/limits.conf` 文件进行修改,命令如下:
|
||||
|
||||
Copy`vi /etc/security/limits.conf`
|
||||
|
||||
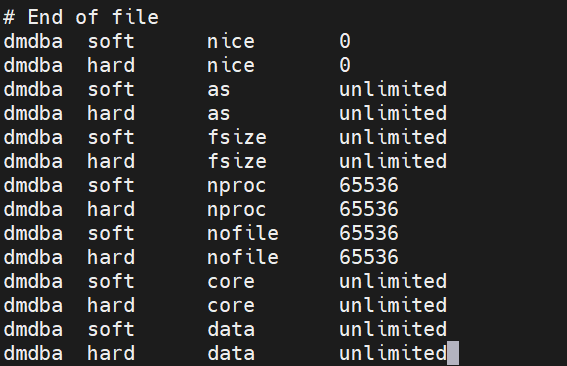
在最后需要添加如下配置:
|
||||
|
||||
Copy`dmdba soft nice 0 dmdba hard nice 0 dmdba soft as unlimited dmdba hard as unlimited dmdba soft fsize unlimited dmdba hard fsize unlimited dmdba soft nproc 65536 dmdba hard nproc 65536 dmdba soft nofile 65536 dmdba hard nofile 65536 dmdba soft core unlimited dmdba hard core unlimited dmdba soft data unlimited dmdba hard data unlimited`
|
||||
|
||||
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 修改配置文件后重启服务器生效。
|
||||
|
||||
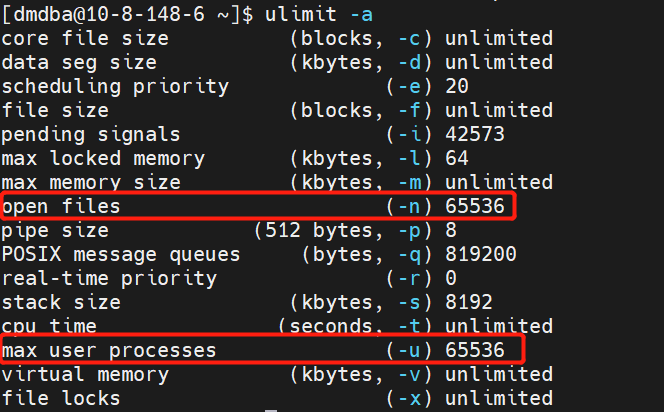
切换到 dmdba 用户,查看是否生效,命令如下:
|
||||
|
||||
Copy`su - dmdba`
|
||||
|
||||
Copy`ulimit -a`
|
||||
|
||||
参数配置已生效。
|
||||
|
||||
|
||||
|
||||
- 设置参数临时生效
|
||||
|
||||
可使用 dmdba 用户执行如下命令,使设置临时生效:
|
||||
|
||||
Copy`ulimit -n 65536 ulimit -u 65536`
|
||||
|
||||
> **建议**
|
||||
>
|
||||
> 使用永久修改方式进行配置。
|
||||
|
||||
## 四、目录规划
|
||||
|
||||
1.可根据实际需求规划安装目录,本示例使用默认配置 DM 数据库安装在 /home/dmdba 文件夹下。
|
||||
|
||||
2.规划创建实例保存目录、归档保存目录、备份保存目录。
|
||||
|
||||
Copy`##实例保存目录 mkdir -p /dmdata/data ##归档保存目录 mkdir -p /dmdata/arch ##备份保存目录 mkdir -p /dmdata/dmbak`
|
||||
|
||||
> **注意**
|
||||
>
|
||||
> 使用 root 用户建立文件夹,待 dmdba 用户建立完成后需将文件所有者更改为 dmdba 用户,否则无法安装到该目录下
|
||||
|
||||
## 五、修改目录权限
|
||||
|
||||
将新建的路径目录权限的用户修改为 dmdba,用户组修改为 dinstall。命令如下:
|
||||
|
||||
Copy`chown -R dmdba:dinstall /dmdata/data chown -R dmdba:dinstall /dmdata/arch chown -R dmdba:dinstall /dmdata/dmbak`
|
||||
|
||||
给路径下的文件设置 755 权限。命令如下:
|
||||
|
||||
Copy`chmod -R 755 /dmdata/data chmod -R 755 /dmdata/arch chmod -R 755 /dmdata/dmbak`
|
||||
+267
@@ -0,0 +1,267 @@
|
||||
---
|
||||
page-title: "Setting Up Elasticsearch and Kibana Single-Node with Docker Compose | by Karthik S | Medium"
|
||||
url: https://karthiksdevopsengineer.medium.com/setting-up-elasticsearch-and-kibana-single-node-with-docker-compose-329776fa3aee
|
||||
date: "2024-09-27 10:53:26"
|
||||
---
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://karthiksdevopsengineer.medium.com/?source=post_page-----329776fa3aee--------------------------------)
|
||||
|
||||

|
||||
|
||||
Setting up Elasticsearch and Kibana on a single-node cluster can be a straightforward process with Docker Compose. In this guide, we’ll walk through the steps to get your Elasticsearch and Kibana instances up and running smoothly.
|
||||
|
||||
## Hardware Prerequisites
|
||||
|
||||
According to the Elastic Cloud Enterprise documentation, here are the hardware requirements for running Elasticsearch and Kibana
|
||||
|
||||
- **CPU**: A minimum of 2 CPU cores is recommended, but the actual requirement depends on your workload. More CPU cores may be required for intensive tasks or larger datasets.
|
||||
- **RAM**: Elastic recommends a minimum of 8GB of RAM for Elasticsearch, but 16GB or more is recommended for production use, especially when running both Elasticsearch and Kibana on the same machine.
|
||||
- **Storage**: SSD storage is recommended for better performance, especially for production use. The amount of storage required depends on your data volume and retention policies.
|
||||
|
||||
For more detailed hardware requirements and recommendations, refer to the [Elastic Cloud Enterprise documentation](https://www.elastic.co/guide/en/cloud-enterprise/current/ece-hardware-prereq.html#ece-hardware-prereq).
|
||||
|
||||
## Software Prerequisites
|
||||
|
||||
Before getting started, make sure you have Docker installed on your system. You can download and install Docker from the [official website](https://docs.docker.com/engine/install/).
|
||||
|
||||
## Setting Up Instructions
|
||||
|
||||
In this guide, I will perform these operations with the following specifications.
|
||||
|
||||
- **OS**: Ubuntu 22.04
|
||||
- **RAM**: 8GB
|
||||
- **Storage**: 30GB SSD
|
||||
|
||||
## 1\. Adjust Kernel Settings
|
||||
|
||||
The `vm.max_map_count` kernel setting must be set to at least `262144`
|
||||
|
||||
How you set `vm.max_map_count` depends on your platform. For [more information](https://www.elastic.co/guide/en/elasticsearch/reference/current/docker.html#_set_vm_max_map_count_to_at_least_262144)
|
||||
|
||||
I’m using the Linux operating system, so I will set `vm.max_map_count` using as follows
|
||||
|
||||
Open the ‘**/etc/sysctl.conf**’ file in a text editor with root privileges. You can use the following command
|
||||
|
||||
sudo nano /etc/sysctl.conf
|
||||
|
||||
Navigate to the end of the file or search for the line containing `vm.max_map_count`, If the line exists, modify it to set the desired value
|
||||
|
||||
vm.max\_map\_count\=262144
|
||||
|
||||
If the line doesn’t exist, add it at the end of the file
|
||||
|
||||
|
||||
vm.max\_map\_count\=262144
|
||||
|
||||
Save the file and exit the text editor. Apply the changes by running the following command
|
||||
|
||||
sudo sysctl -p
|
||||
|
||||
This command reloads the sysctl settings from the configuration file. Now, the value of `vm.max_map_count` should be updated to **262144**.
|
||||
|
||||
## 2\. Prepare Environment Variables
|
||||
|
||||
Create or navigate to an empty directory for the project.
|
||||
|
||||
Inside this directory, create a `.env` file and set up the necessary environment variables.
|
||||
|
||||
Copy the following content and paste it into the `.env` file.
|
||||
|
||||
|
||||
ELASTIC\_PASSWORD=
|
||||
|
||||
|
||||
KIBANA\_PASSWORD=
|
||||
|
||||
|
||||
STACK\_VERSION={version}
|
||||
|
||||
|
||||
CLUSTER\_NAME=docker-cluster
|
||||
|
||||
|
||||
LICENSE=basic
|
||||
|
||||
|
||||
ES\_PORT=9200
|
||||
|
||||
|
||||
KIBANA\_PORT=5601
|
||||
|
||||
|
||||
MEM\_LIMIT=2147483648
|
||||
|
||||
In the `.env` file, specify a password for the `ELASTIC_PASSWORD` and `KIBANA_PASSWORD` variables.
|
||||
|
||||
The passwords must be alphanumeric and can’t contain special characters, such as `!` or `@`. The bash script included in the `compose.yml` file only works with alphanumeric characters. Example:
|
||||
|
||||
|
||||
ELASTIC\_PASSWORD=Secure123
|
||||
|
||||
|
||||
KIBANA\_PASSWORD=Secure123
|
||||
|
||||
...
|
||||
|
||||
In the `.env` file, set `STACK_VERSION` to the Elastic Stack version. Example:
|
||||
|
||||
...
|
||||
|
||||
\# Version of Elastic products
|
||||
STACK\_VERSION=8.13.2
|
||||
|
||||
...
|
||||
|
||||
## 3\. Create Docker Compose Configuration
|
||||
|
||||
Now, create a `compose.yml` file in the same directory and copy the following content and paste it into the `compose.yml` file.
|
||||
|
||||
version: "2.2"
|
||||
|
||||
services:
|
||||
setup:
|
||||
image: docker.elastic.co/elasticsearch/elasticsearch:${STACK\_VERSION}
|
||||
volumes:
|
||||
- certs:/usr/share/elasticsearch/config/certs
|
||||
user: "0"
|
||||
command: >
|
||||
bash -c '
|
||||
if \[ x${ELASTIC\_PASSWORD} == x \]; then
|
||||
echo "Set the ELASTIC\_PASSWORD environment variable in the .env file";
|
||||
exit 1;
|
||||
elif \[ x${KIBANA\_PASSWORD} == x \]; then
|
||||
echo "Set the KIBANA\_PASSWORD environment variable in the .env file";
|
||||
exit 1;
|
||||
fi;
|
||||
if \[ ! -f config/certs/ca.zip \]; then
|
||||
echo "Creating CA";
|
||||
bin/elasticsearch-certutil ca --silent --pem -out config/certs/ca.zip;
|
||||
unzip config/certs/ca.zip -d config/certs;
|
||||
fi;
|
||||
if \[ ! -f config/certs/certs.zip \]; then
|
||||
echo "Creating certs";
|
||||
echo -ne \\
|
||||
"instances:\\n"\\
|
||||
" - name: es01\\n"\\
|
||||
" dns:\\n"\\
|
||||
" - es01\\n"\\
|
||||
" - localhost\\n"\\
|
||||
" ip:\\n"\\
|
||||
" - 127.0.0.1\\n"\\
|
||||
> config/certs/instances.yml;
|
||||
bin/elasticsearch-certutil cert --silent --pem -out config/certs/certs.zip --in config/certs/instances.yml --ca-cert config/certs/ca/ca.crt --ca-key config/certs/ca/ca.key;
|
||||
unzip config/certs/certs.zip -d config/certs;
|
||||
fi;
|
||||
echo "Setting file permissions"
|
||||
chown -R root:root config/certs;
|
||||
find . -type d -exec chmod 750 \\{\\} \\;;
|
||||
find . -type f -exec chmod 640 \\{\\} \\;;
|
||||
echo "Waiting for Elasticsearch availability";
|
||||
until curl -s --cacert config/certs/ca/ca.crt https://es01:9200 | grep -q "missing authentication credentials"; do sleep 30; done;
|
||||
echo "Setting kibana\_system password";
|
||||
until curl -s -X POST --cacert config/certs/ca/ca.crt -u "elastic:${ELASTIC\_PASSWORD}" -H "Content-Type: application/json" https://es01:9200/\_security/user/kibana\_system/\_password -d "{\\"password\\":\\"${KIBANA\_PASSWORD}\\"}" | grep -q "^{}"; do sleep 10; done;
|
||||
echo "All done!";
|
||||
'
|
||||
healthcheck:
|
||||
test: \["CMD-SHELL", "\[ -f config/certs/es01/es01.crt \]"\]
|
||||
interval: 1s
|
||||
timeout: 5s
|
||||
retries: 120
|
||||
|
||||
es01:
|
||||
image: docker.elastic.co/elasticsearch/elasticsearch:${STACK\_VERSION}
|
||||
volumes:
|
||||
- certs:/usr/share/elasticsearch/config/certs
|
||||
- esdata:/usr/share/elasticsearch/data
|
||||
ports:
|
||||
- ${ES\_PORT}:9200
|
||||
environment:
|
||||
- node.name=es01
|
||||
- cluster.name=${CLUSTER\_NAME}
|
||||
- discovery.type=single-node
|
||||
- ELASTIC\_PASSWORD=${ELASTIC\_PASSWORD}
|
||||
- bootstrap.memory\_lock=true
|
||||
- xpack.security.enabled=true
|
||||
- xpack.security.http.ssl.enabled=true
|
||||
- xpack.security.http.ssl.key=certs/es01/es01.key
|
||||
- xpack.security.http.ssl.certificate=certs/es01/es01.crt
|
||||
- xpack.security.http.ssl.certificate\_authorities=certs/ca/ca.crt
|
||||
- xpack.security.transport.ssl.enabled=true
|
||||
- xpack.security.transport.ssl.key=certs/es01/es01.key
|
||||
- xpack.security.transport.ssl.certificate=certs/es01/es01.crt
|
||||
- xpack.security.transport.ssl.certificate\_authorities=certs/ca/ca.crt
|
||||
- xpack.security.transport.ssl.verification\_mode=certificate
|
||||
- xpack.license.self\_generated.type=${LICENSE}
|
||||
mem\_limit: ${MEM\_LIMIT}
|
||||
ulimits:
|
||||
memlock:
|
||||
soft: -1
|
||||
hard: -1
|
||||
healthcheck:
|
||||
test:
|
||||
\[
|
||||
"CMD-SHELL",
|
||||
"curl -s --cacert config/certs/ca/ca.crt https://localhost:9200 | grep -q 'missing authentication credentials'",
|
||||
\]
|
||||
interval: 10s
|
||||
timeout: 10s
|
||||
retries: 120
|
||||
|
||||
kibana:
|
||||
depends\_on:
|
||||
es01:
|
||||
condition: service\_healthy
|
||||
image: docker.elastic.co/kibana/kibana:${STACK\_VERSION}
|
||||
volumes:
|
||||
- certs:/usr/share/kibana/config/certs
|
||||
- kibanadata:/usr/share/kibana/data
|
||||
ports:
|
||||
- ${KIBANA\_PORT}:5601
|
||||
environment:
|
||||
- SERVERNAME=kibana
|
||||
- ELASTICSEARCH\_HOSTS=https://es01:9200
|
||||
- ELASTICSEARCH\_USERNAME=kibana\_system
|
||||
- ELASTICSEARCH\_PASSWORD=${KIBANA\_PASSWORD}
|
||||
- ELASTICSEARCH\_SSL\_CERTIFICATEAUTHORITIES=config/certs/ca/ca.crt
|
||||
- SERVER\_PUBLICBASEURL=http://localhost:5601
|
||||
mem\_limit: ${MEM\_LIMIT}
|
||||
healthcheck:
|
||||
test:
|
||||
\[
|
||||
"CMD-SHELL",
|
||||
"curl -s -I http://localhost:5601 | grep -q 'HTTP/1.1 302 Found'",
|
||||
\]
|
||||
interval: 10s
|
||||
timeout: 10s
|
||||
retries: 120
|
||||
|
||||
volumes:
|
||||
certs:
|
||||
driver: local
|
||||
esdata:
|
||||
driver: local
|
||||
kibanadata:
|
||||
driver: local
|
||||
|
||||
## 4\. Start Docker Compose
|
||||
|
||||
Now you can start Elasticsearch and Kibana using Docker Compose. Run the following command from your project directory
|
||||
|
||||
docker compose up -d
|
||||
|
||||
**5\. Access Elasticsearch and Kibana**
|
||||
|
||||
Once Docker Compose has started the services, you can access Elasticsearch at `https://<localhost or serverip>:9200` and Kibana at `http://<localhost or serverip>:5601` in your web browser.
|
||||
|
||||
Log in to Elasticsearch or Kibana as the `elastic` user and the password is the one you set earlier in the `.env` file.
|
||||
|
||||
## Conclusion
|
||||
|
||||
You’ve successfully set up Elasticsearch and Kibana on a single-node using Docker Compose.
|
||||
|
||||
**Reference** [https://www.elastic.co/guide/en/elasticsearch/reference/current/docker.html](https://www.elastic.co/guide/en/elasticsearch/reference/current/docker.html)
|
||||
+188
@@ -0,0 +1,188 @@
|
||||
---
|
||||
page-title: "Step-by-Step Guide: Setting Up OpenXPKI for Secure Digital Certificates in Linux | by Riski Ilyas | Medium"
|
||||
url: https://medium.com/@riskiilyas03/step-by-step-guide-setting-up-openxpki-for-secure-digital-certificates-in-linux-107b06b2c0c1
|
||||
date: "2024-09-09 15:16:40"
|
||||
---
|
||||
|
||||
> openxpki
|
||||
|
||||
---
|
||||
|
||||
## Step-by-Step Guide: Setting Up OpenXPKI for Secure Digital Certificates in Linux
|
||||
|
||||
[
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
](https://medium.com/@riskiilyas03?source=post_page-----107b06b2c0c1--------------------------------)
|
||||
|
||||

|
||||
|
||||
source: [https://github.com/openxpki](https://github.com/openxpki)
|
||||
|
||||
In the ever-evolving landscape of digital security, the need for robust Public Key Infrastructure (PKI) solutions has become paramount. OpenXPKI, a versatile and open-source PKI software, offers a powerful framework for managing digital certificates and ensuring the secure exchange of information in a networked environment.
|
||||
|
||||
This article serves as your gateway to understanding and harnessing the capabilities of OpenXPKI. Whether you’re looking to establish a Certificate Authority (CA), manage registration processes as a Registration Authority (RA), or simply utilize digital certificates as a common user, we’ve got you covered. In the following sections, we’ll provide a step-by-step guide on installing and using OpenXPKI in various roles.
|
||||
|
||||
## Why OpenXPKI?
|
||||
|
||||
OpenXPKI combines flexibility and security, making it an ideal choice for organizations seeking a reliable PKI solution. With features tailored for Certificate Authorities, Registration Authorities, and end users, OpenXPKI streamlines the often complex processes involved in managing digital certificates.
|
||||
|
||||
From securing communications to enabling digital signatures and authentication, OpenXPKI empowers you to build a robust and trustworthy infrastructure. Whether you’re a system administrator, security professional, or a curious enthusiast, this guide will walk you through the process of setting up and utilizing OpenXPKI in a manner that suits your specific needs.
|
||||
|
||||
So, let’s embark on this journey into the realm of OpenXPKI, demystifying its installation and usage for Certificate Authorities, Registration Authorities, and common users alike.
|
||||
|
||||
## Docker Installation
|
||||
|
||||
To simplify the installation process and ensure compatibility across various environments, we’ll guide you through setting up OpenXPKI on a Linux system using Docker containers. Docker provides a convenient way to package applications and their dependencies, allowing for seamless deployment and scalability. Let’s dive into the world of OpenXPKI and set the stage for a secure and efficient Public Key Infrastructure.
|
||||
|
||||
First and foremost, ensure that Docker, Docker Compose, and Make are installed on your local machine. If you haven’t installed these components yet, follow the steps provided below.
|
||||
|
||||
1. Install Docker
|
||||
|
||||
sudo apt update
|
||||
sudo apt install -y apt-transport-https ca-certificates curl software-properties-common
|
||||
curl -fsSL https://download.docker.com/linux/ubuntu/gpg | sudo gpg --dearmor -o /usr/share/keyrings/docker-archive-keyring.gpg
|
||||
echo "deb \[signed-by=/usr/share/keyrings/docker-archive-keyring.gpg\] https://download.docker.com/linux/ubuntu $(lsb\_release -cs) stable" | sudo tee /etc/apt/sources.list.d/docker.list > /dev/null
|
||||
sudo apt update
|
||||
sudo apt install -y docker-ce docker-ce-cli containerd.io
|
||||
sudo usermod -aG docker $USER
|
||||
docker --version
|
||||
|
||||

|
||||
|
||||
Finished Installing Docker
|
||||
|
||||
2\. Install Docker-Compose
|
||||
|
||||
sudo apt update
|
||||
sudo curl -L "https://github.com/docker/compose/releases/latest/download/docker-compose-$(uname -s)\-$(uname -m)" -o /usr/local/bin/docker-compose
|
||||
sudo chmod +x /usr/local/bin/docker-compose
|
||||
docker-compose --version
|
||||
|
||||

|
||||
|
||||
Finished Installing Docker-Compose
|
||||
|
||||
3\. Install Make
|
||||
|
||||
sudo apt update
|
||||
sudo apt install make
|
||||
make --version
|
||||
|
||||

|
||||
|
||||
Finished Installing Make
|
||||
|
||||
With Docker, Docker Compose, and Make successfully installed on your local machine, you are now ready to proceed with the installation of OpenXPKI. The following steps will guide you through the process, ensuring a smooth setup for your Certificate Authority (CA), Registration Authority (RA), and common user roles. Let’s embark on this journey into implementing OpenXPKI for your secure and efficient Public Key Infrastructure.
|
||||
|
||||
## OpenXPKI Installation
|
||||
|
||||
After installing Docker, Docker-Compose, & Make, we can continue to Install OpenXPKI. The first step is to clone the OpenXPKI Docker Image Repository. You can copy below command to clone the Docker Image.
|
||||
|
||||
git clone https://github.com/openxpki/openxpki-docker.git
|
||||
|
||||
After cloning the Repository, you can change the directory to the Cloned Docker Repository.
|
||||
|
||||
cd openxpki-docker
|
||||
|
||||

|
||||
|
||||
Change to the Repository Directory
|
||||
|
||||
Now you are inside the Docker Directory. The next step is to clone the Config Repository. You can copy the command below:
|
||||
|
||||
git clone https://github.com/openxpki/openxpki-config.git \\
|
||||
--single-branch --branch=community
|
||||
|
||||
Next, to avoid the server to crash when the database is not available, you should copy the configuration into the local.yaml . You can copy the command below
|
||||
|
||||
cp contrib/wait\_on\_init.yaml openxpki-config/config.d/system/local.yaml
|
||||
|
||||
Now, to run the docker-compose. Use below make command to start
|
||||
|
||||
make compose
|
||||
|
||||

|
||||
|
||||
Starting the Web Server with Docker Compose
|
||||
|
||||
The Web-Server is now started, to Open the OpenXPKI Web, you can access [https://localhost:8443/](https://localhost:8443/)
|
||||
|
||||

|
||||
|
||||
Login Page of OpenXPKI
|
||||
|
||||
## Using OpenXPKI as Certificate Authority (CA)
|
||||
|
||||
OpenXPKI provides some Demo Accounts for CA, RA, & Common Users. Now we are going to use Demo Account for CA. Therefore, choose **Test Accounts** in the Authentication Method. Then Click **Login**
|
||||
|
||||

|
||||
|
||||
Login using Test Account
|
||||
|
||||
In the Login form, use **caop** as the username and **openxpki** for the default password. Then click **Login**
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
Now you already Logged in as Certificate Authority (CA), you can do some authority like Certifficate Issuance, Certificate Revocation, Certificate Renewal, Policy Enforcement, etc.
|
||||
|
||||
## Using OpenXPKI as Registration Authority (RA)
|
||||
|
||||
To use OpenXPKI as Registration Authority (RA), you can log in with the same option which is Test Account. Then, you can fill **raop** for the username and **openxpki** for the password. Click **Login** after that.
|
||||
|
||||

|
||||
|
||||
Now you are Logged in as Registration Authority (RA), you can do things like managing User Enrollment, Certificate Request Approval, Certificate Request Revocation, etc
|
||||
|
||||

|
||||
|
||||
To manage Certificate Request, you can click **Home ->My Task**. Here you can approve or revoke any certificate requests from the users.
|
||||
|
||||

|
||||
|
||||
## Using OpenXPKI as Common User
|
||||
|
||||
To use as Common User, The first thing to do is to Log in as Test User, then you can log in as Alice. Therefore, you can fill the username with **alice** and the password with **openxpki** as the default password.
|
||||
|
||||

|
||||
|
||||
Now, you are already Logged in as Alice. The next step is to request a certificate. You can click **Request certificate** menu.
|
||||
|
||||

|
||||
|
||||
Then you can choose **OCSP Responder** for the Certificate Profile. Next, click **Continue**
|
||||
|
||||

|
||||
|
||||
After clicking **Continue,** choose **Generate Key on PKI** to request the certificate.
|
||||
|
||||

|
||||
|
||||
Next, you can customize the Key Algorithm and Key Length. Otherwise, you can just click **Continue.**
|
||||
|
||||

|
||||
|
||||
Next, fill in your own Hostname, for example we can put **alice.my.id**. Then, click **Continue**
|
||||
|
||||

|
||||
|
||||
Next, You can also customize the certificate Info and also add Comment on it. Or you can also use the Default Info and click **Continue**
|
||||
|
||||

|
||||
|
||||
Next, it will show your certificate info and you can edit, submit, or cancel the request. To Proceed the request, click **Submit request**
|
||||
|
||||

|
||||
|
||||
Lastly, retype the Password that already given to the **Password Confirmation** Form
|
||||
|
||||

|
||||
|
||||
Finally, you have already create a Certificate Request! Now, you can log in as Registration User (RA) to approve or revoke the request.
|
||||
|
||||
In conclusion, OpenXPKI emerges as a versatile and indispensable tool in the realm of digital security, offering a robust framework for managing Public Key Infrastructure. Through the installation guide and insights into the roles of Certificate Authority (CA), Registration Authority (RA), and common users, you’ve gained a comprehensive understanding of how OpenXPKI fortifies the security landscape. As a CA, it facilitates precise certificate issuance and management, while the RA ensures a seamless enrollment process. Together, they establish a secure foundation for cryptographic operations. By navigating OpenXPKI, you’ve not only acquired the skills to safeguard information and authenticate users but also laid the groundwork for a resilient and trustworthy digital infrastructure within your organization.
|
||||
+297
@@ -0,0 +1,297 @@
|
||||
---
|
||||
page-title: "elasticdump/elasticsearch-dump - Docker Image | Docker Hub"
|
||||
url: https://hub.docker.com/r/elasticdump/elasticsearch-dump
|
||||
date: "2024-09-26 11:11:29"
|
||||
---
|
||||
Tools for moving and saving indices.
|
||||
|
||||
Elasticdump works by sending an `input` to an `output`. Both can be either an elasticsearch URL or a File.
|
||||
|
||||
If Elasticsearch is not being served from the root directory the `--input-index` and `--output-index` are required. If they are not provided, the additional sub-directories will be parsed for index and type.
|
||||
|
||||
If you prefer using docker to use elasticdump, you can download this project from docker hub:
|
||||
|
||||
The file format generated by this tool is line-delimited JSON files. The dump file itself is not valid JSON, but each line is. We do this so that dumpfiles can be streamed and appended without worrying about whole-file parser integrity.
|
||||
|
||||
```
|
||||
elasticdump: Import and export tools for elasticsearch
|
||||
version: %%version%%
|
||||
|
||||
Usage: elasticdump --input SOURCE --output DESTINATION [OPTIONS]
|
||||
|
||||
--input
|
||||
Source location (required)
|
||||
--input-index
|
||||
Source index and type
|
||||
(default: all, example: index/type)
|
||||
--output
|
||||
Destination location (required)
|
||||
--output-index
|
||||
Destination index and type
|
||||
(default: all, example: index/type)
|
||||
--overwrite
|
||||
Overwrite output file if it exists
|
||||
(default: false)
|
||||
--limit
|
||||
How many objects to move in batch per operation
|
||||
limit is approximate for file streams
|
||||
(default: 100)
|
||||
--size
|
||||
How many objects to retrieve
|
||||
(default: -1 -> no limit)
|
||||
--concurrency
|
||||
The maximum number of requests the can be made concurrently to a specified transport.
|
||||
(default: 1)
|
||||
--concurrencyInterval
|
||||
The length of time in milliseconds in which up to <intervalCap> requests can be made
|
||||
before the interval request count resets. Must be finite.
|
||||
(default: 5000)
|
||||
--intervalCap
|
||||
The maximum number of transport requests that can be made within a given <concurrencyInterval>.
|
||||
(default: 5)
|
||||
--carryoverConcurrencyCount
|
||||
If true, any incomplete requests from a <concurrencyInterval> will be carried over to
|
||||
the next interval, effectively reducing the number of new requests that can be created
|
||||
in that next interval. If false, up to <intervalCap> requests can be created in the
|
||||
next interval regardless of the number of incomplete requests from the previous interval.
|
||||
(default: true)
|
||||
--throttleInterval
|
||||
Delay in milliseconds between getting data from an inputTransport and sending it to an
|
||||
outputTransport.
|
||||
(default: 1)
|
||||
--debug
|
||||
Display the elasticsearch commands being used
|
||||
(default: false)
|
||||
--quiet
|
||||
Suppress all messages except for errors
|
||||
(default: false)
|
||||
--type
|
||||
What are we exporting?
|
||||
(default: data, options: [settings, analyzer, data, mapping, policy, alias, template, component_template, index_template])
|
||||
--filterSystemTemplates
|
||||
Whether to remove metrics-*-* and logs-*-* system templates
|
||||
(default: true])
|
||||
--templateRegex
|
||||
Regex used to filter templates before passing to the output transport
|
||||
(default: ((metrics|logs|\\..+)(-.+)?)
|
||||
--delete
|
||||
Delete documents one-by-one from the input as they are
|
||||
moved. Will not delete the source index
|
||||
(default: false)
|
||||
--searchBody
|
||||
Preform a partial extract based on search results
|
||||
when ES is the input, default values are
|
||||
if ES > 5
|
||||
`'{"query": { "match_all": {} }, "stored_fields": ["*"], "_source": true }'`
|
||||
else
|
||||
`'{"query": { "match_all": {} }, "fields": ["*"], "_source": true }'`
|
||||
[As of 6.68.0] If the searchBody is preceded by a @ symbol, elasticdump will perform a file lookup
|
||||
in the location specified. NB: File must contain valid JSON
|
||||
--searchWithTemplate
|
||||
Enable to use Search Template when using --searchBody
|
||||
If using Search Template then searchBody has to consist of "id" field and "params" objects
|
||||
If "size" field is defined within Search Template, it will be overridden by --size parameter
|
||||
See https://www.elastic.co/guide/en/elasticsearch/reference/current/search-template.html for
|
||||
further information
|
||||
(default: false)
|
||||
--searchBodyTemplate
|
||||
A method/function which can be called to the searchBody
|
||||
doc.searchBody = { query: { match_all: {} }, stored_fields: [], _source: true };
|
||||
May be used multiple times.
|
||||
Additionally, searchBodyTemplate may be performed by a module. See [searchBody Template](#search-template) below.
|
||||
--headers
|
||||
Add custom headers to Elastisearch requests (helpful when
|
||||
your Elasticsearch instance sits behind a proxy)
|
||||
(default: '{"User-Agent": "elasticdump"}')
|
||||
Type/direction based headers are supported .i.e. input-headers/output-headers
|
||||
(these will only be added based on the current flow type input/output)
|
||||
--params
|
||||
Add custom parameters to Elastisearch requests uri. Helpful when you for example
|
||||
want to use elasticsearch preference
|
||||
|
||||
--input-params is a specific params extension that can be used when fetching data with the scroll api
|
||||
--output-params is a specific params extension that can be used when indexing data with the bulk index api
|
||||
NB : These were added to avoid param pollution problems which occur when an input param is used in an output source
|
||||
(default: null)
|
||||
--sourceOnly
|
||||
Output only the json contained within the document _source
|
||||
Normal: {"_index":"","_type":"","_id":"", "_source":{SOURCE}}
|
||||
sourceOnly: {SOURCE}
|
||||
(default: false)
|
||||
--ignore-errors
|
||||
Will continue the read/write loop on write error
|
||||
(default: false)
|
||||
--scrollId
|
||||
The last scroll Id returned from elasticsearch.
|
||||
This will allow dumps to be resumed used the last scroll Id &
|
||||
`scrollTime` has not expired.
|
||||
--scrollTime
|
||||
Time the nodes will hold the requested search in order.
|
||||
(default: 10m)
|
||||
|
||||
--scroll-with-post
|
||||
Use a HTTP POST method to perform scrolling instead of the default GET
|
||||
(default: false)
|
||||
|
||||
--maxSockets
|
||||
How many simultaneous HTTP requests can we process make?
|
||||
(default:
|
||||
5 [node <= v0.10.x] /
|
||||
Infinity [node >= v0.11.x] )
|
||||
--timeout
|
||||
Integer containing the number of milliseconds to wait for
|
||||
a request to respond before aborting the request. Passed
|
||||
directly to the request library. Mostly used when you don't
|
||||
care too much if you lose some data when importing
|
||||
but rather have speed.
|
||||
--offset
|
||||
Integer containing the number of rows you wish to skip
|
||||
ahead from the input transport. When importing a large
|
||||
index, things can go wrong, be it connectivity, crashes,
|
||||
someone forgets to `screen`, etc. This allows you
|
||||
to start the dump again from the last known line written
|
||||
(as logged by the `offset` in the output). Please be
|
||||
advised that since no sorting is specified when the
|
||||
dump is initially created, there's no real way to
|
||||
guarantee that the skipped rows have already been
|
||||
written/parsed. This is more of an option for when
|
||||
you want to get most data as possible in the index
|
||||
without concern for losing some rows in the process,
|
||||
similar to the `timeout` option.
|
||||
(default: 0)
|
||||
--noRefresh
|
||||
Disable input index refresh.
|
||||
Positive:
|
||||
1. Much increase index speed
|
||||
2. Much less hardware requirements
|
||||
Negative:
|
||||
1. Recently added data may not be indexed
|
||||
Recommended using with big data indexing,
|
||||
where speed and system health in a higher priority
|
||||
than recently added data.
|
||||
--inputTransport
|
||||
Provide a custom js file to use as the input transport
|
||||
--outputTransport
|
||||
Provide a custom js file to use as the output transport
|
||||
--toLog
|
||||
When using a custom outputTransport, should log lines
|
||||
be appended to the output stream?
|
||||
(default: true, except for `$`)
|
||||
--transform
|
||||
A method/function which can be called to modify documents
|
||||
before writing to a destination. A global variable 'doc'
|
||||
is available.
|
||||
Example script for computing a new field 'f2' as doubled
|
||||
value of field 'f1':
|
||||
doc._source["f2"] = doc._source.f1 * 2;
|
||||
May be used multiple times.
|
||||
Additionally, transform may be performed by a module. See [Module Transform](#module-transform) below.
|
||||
--awsChain
|
||||
Use [standard](https://aws.amazon.com/blogs/security/a-new-and-standardized-way-to-manage-credentials-in-the-aws-sdks/) location and ordering for resolving credentials including environment variables, config files, EC2 and ECS metadata locations
|
||||
_Recommended option for use with AWS_
|
||||
Use [standard](https://aws.amazon.com/blogs/security/a-new-and-standardized-way-to-manage-credentials-in-the-aws-sdks/)
|
||||
location and ordering for resolving credentials including environment variables,
|
||||
config files, EC2 and ECS metadata locations _Recommended option for use with AWS_
|
||||
--awsAccessKeyId
|
||||
--awsSecretAccessKey
|
||||
When using Amazon Elasticsearch Service protected by
|
||||
AWS Identity and Access Management (IAM), provide
|
||||
your Access Key ID and Secret Access Key.
|
||||
--sessionToken can also be optionally provided if using temporary credentials
|
||||
--awsIniFileProfile
|
||||
Alternative to --awsAccessKeyId and --awsSecretAccessKey,
|
||||
loads credentials from a specified profile in aws ini file.
|
||||
For greater flexibility, consider using --awsChain
|
||||
and setting AWS_PROFILE and AWS_CONFIG_FILE
|
||||
environment variables to override defaults if needed
|
||||
--awsIniFileName
|
||||
Override the default aws ini file name when using --awsIniFileProfile
|
||||
Filename is relative to ~/.aws/
|
||||
(default: config)
|
||||
--awsService
|
||||
Sets the AWS service that the signature will be generated for
|
||||
(default: calculated from hostname or host)
|
||||
--awsRegion
|
||||
Sets the AWS region that the signature will be generated for
|
||||
(default: calculated from hostname or host)
|
||||
--awsUrlRegex
|
||||
Overrides the default regular expression that is used to validate AWS urls that should be signed
|
||||
(default: ^https?:\/\/.*\.amazonaws\.com.*$)
|
||||
--support-big-int
|
||||
Support big integer numbers
|
||||
--big-int-fields
|
||||
Sepcifies a comma-seperated list of fields that should be checked for big-int support
|
||||
(default '')
|
||||
--retryAttempts
|
||||
Integer indicating the number of times a request should be automatically re-attempted before failing
|
||||
when a connection fails with one of the following errors `ECONNRESET`, `ENOTFOUND`, `ESOCKETTIMEDOUT`,
|
||||
ETIMEDOUT`, `ECONNREFUSED`, `EHOSTUNREACH`, `EPIPE`, `EAI_AGAIN`
|
||||
(default: 0)
|
||||
|
||||
--retryDelay
|
||||
Integer indicating the back-off/break period between retry attempts (milliseconds)
|
||||
(default : 5000)
|
||||
--parseExtraFields
|
||||
Comma-separated list of meta-fields to be parsed
|
||||
--maxRows
|
||||
supports file splitting. Files are split by the number of rows specified
|
||||
--fileSize
|
||||
supports file splitting. This value must be a string supported by the **bytes** module.
|
||||
The following abbreviations must be used to signify size in terms of units
|
||||
b for bytes
|
||||
kb for kilobytes
|
||||
mb for megabytes
|
||||
gb for gigabytes
|
||||
tb for terabytes
|
||||
|
||||
e.g. 10mb / 1gb / 1tb
|
||||
Partitioning helps to alleviate overflow/out of memory exceptions by efficiently segmenting files
|
||||
into smaller chunks that then be merged if needs be.
|
||||
--fsCompress
|
||||
gzip data before sending output to file.
|
||||
On import the command is used to inflate a gzipped file
|
||||
--s3AccessKeyId
|
||||
AWS access key ID
|
||||
--s3SecretAccessKey
|
||||
AWS secret access key
|
||||
--s3Region
|
||||
AWS region
|
||||
--s3Endpoint
|
||||
AWS endpoint can be used for AWS compatible backends such as
|
||||
OpenStack Swift and OpenStack Ceph
|
||||
--s3SSLEnabled
|
||||
Use SSL to connect to AWS [default true]
|
||||
|
||||
--s3ForcePathStyle Force path style URLs for S3 objects [default false]
|
||||
|
||||
--s3Compress
|
||||
gzip data before sending to s3
|
||||
--s3ServerSideEncryption
|
||||
Enables encrypted uploads
|
||||
--s3SSEKMSKeyId
|
||||
KMS Id to be used with aws:kms uploads
|
||||
--s3ACL
|
||||
S3 ACL: private | public-read | public-read-write | authenticated-read | aws-exec-read |
|
||||
bucket-owner-read | bucket-owner-full-control [default private]
|
||||
--s3StorageClass
|
||||
Set the Storage Class used for s3
|
||||
(default: STANDARD)
|
||||
--s3Options
|
||||
Set all s3 parameters shown here https://docs.aws.amazon.com/AWSJavaScriptSDK/latest/AWS/S3.html#createMultipartUpload-property
|
||||
A escaped JSON string or file can be supplied. File location must be prefixed with the @ symbol
|
||||
(default: null)
|
||||
--s3Configs
|
||||
Set all s3 constructor configurations
|
||||
A escaped JSON string or file can be supplied. File location must be prefixed with the @ symbol
|
||||
(default: null)
|
||||
--retryDelayBase
|
||||
The base number of milliseconds to use in the exponential backoff for operation retries. (s3)
|
||||
--customBackoff
|
||||
Activate custom customBackoff function. (s3)
|
||||
--tlsAuth
|
||||
Enable TLS X509 client authentication
|
||||
--cert, --input-cert, --output-cert
|
||||
Client certificate file. Use --cert if source and destination are identical.
|
||||
Otherwise, use the one prefixed with --input or --output as needed.
|
||||
--key, --input-key, --o
|
||||
```
|
||||
Reference in New Issue
Block a user